Share
Embed
Transcript
30 slides
-
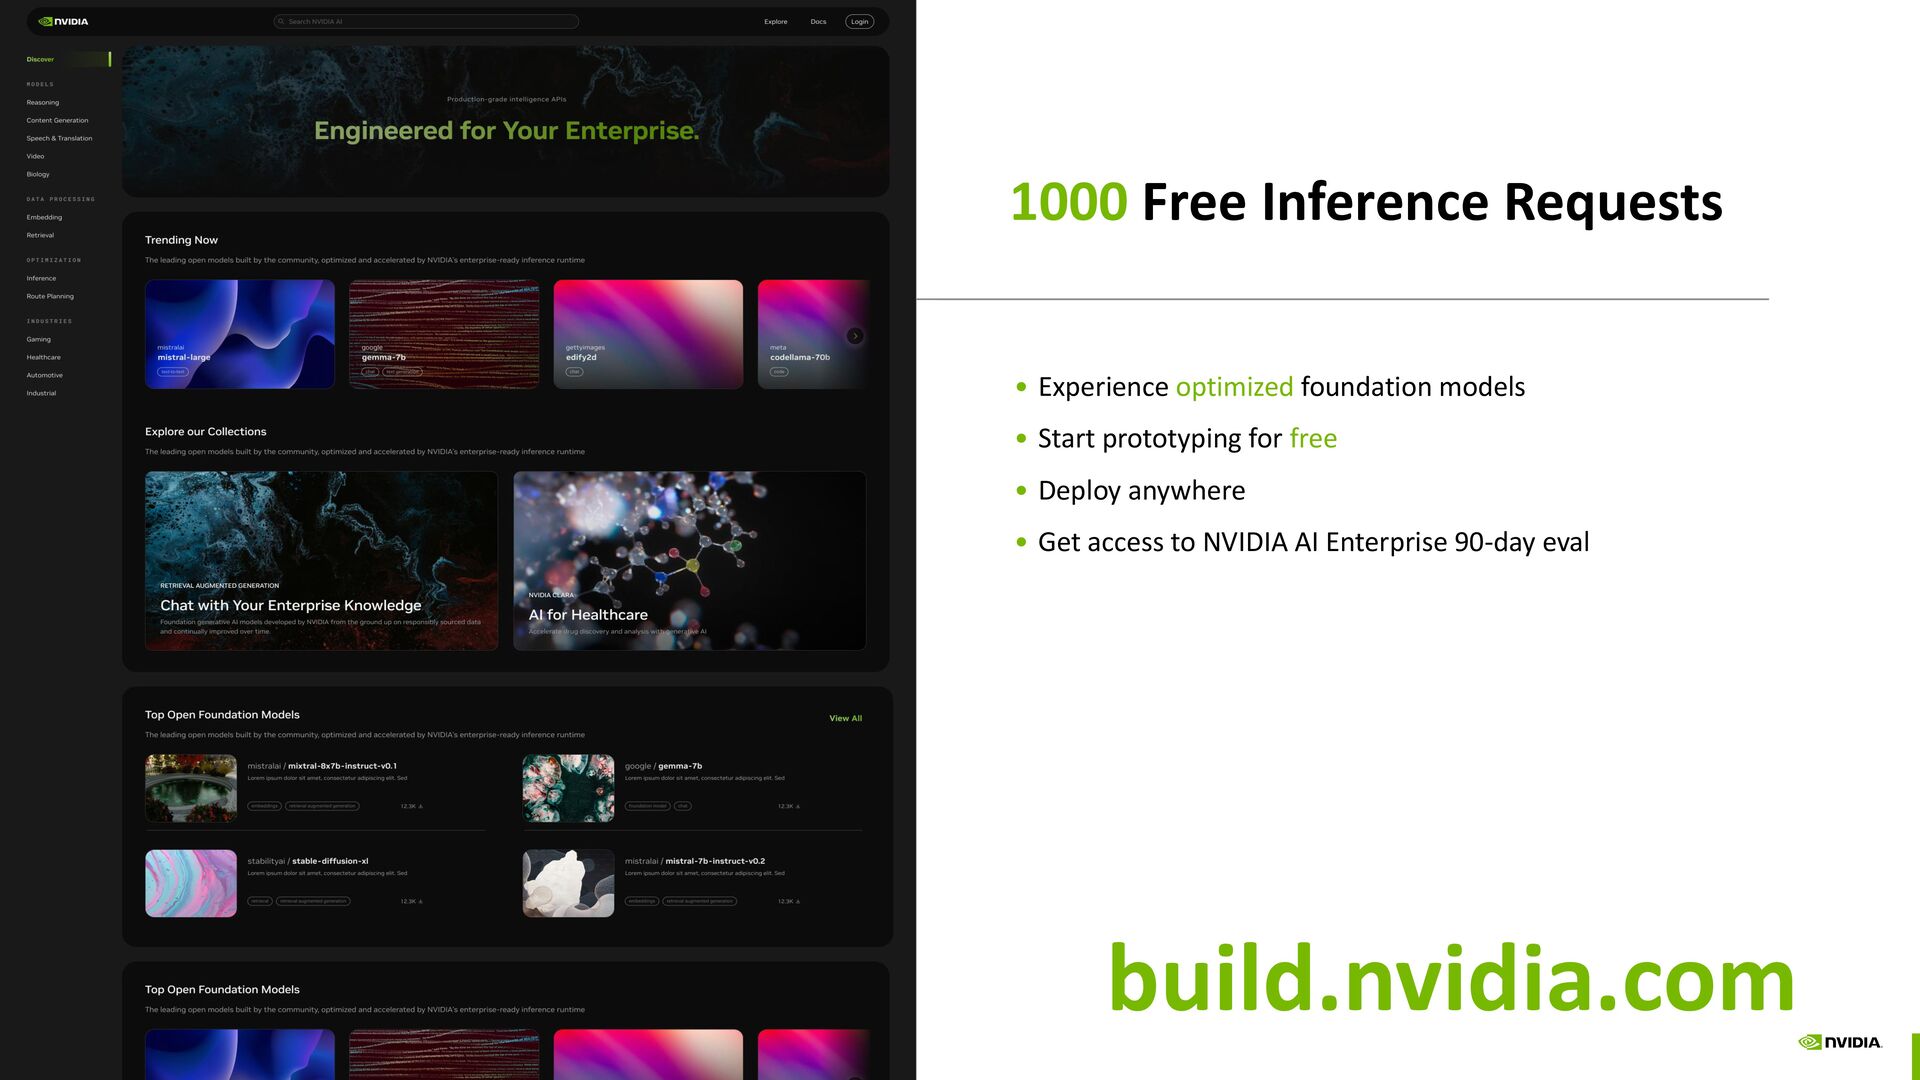
1000 Free Inference Requests • Experience optimized foundation models •
Start prototyping for free • Deploy anywhere • Get access to NVIDIA AI Enterprise 90-day eval build.nvidia.com -
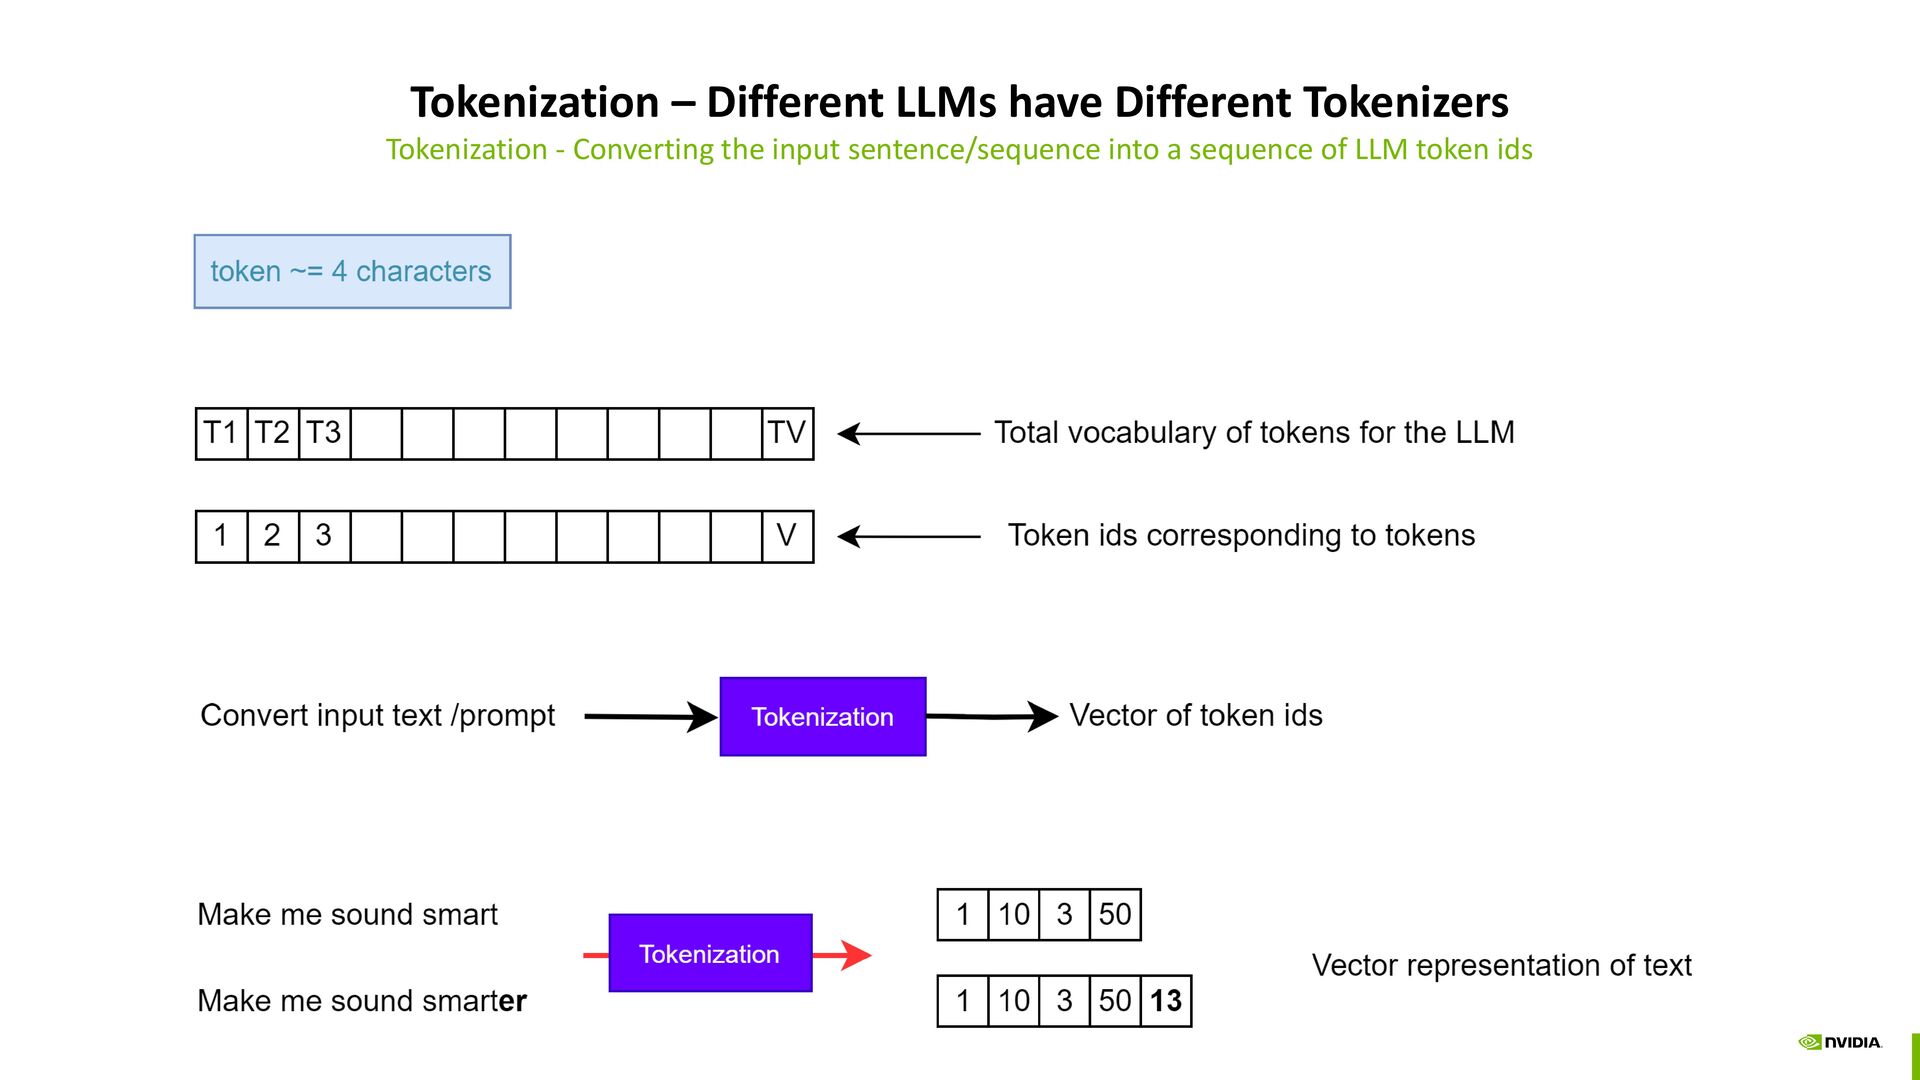
Tokenization – Different LLMs have Different Tokenizers Tokenization - Converting
the input sentence/sequence into a sequence of LLM token ids -
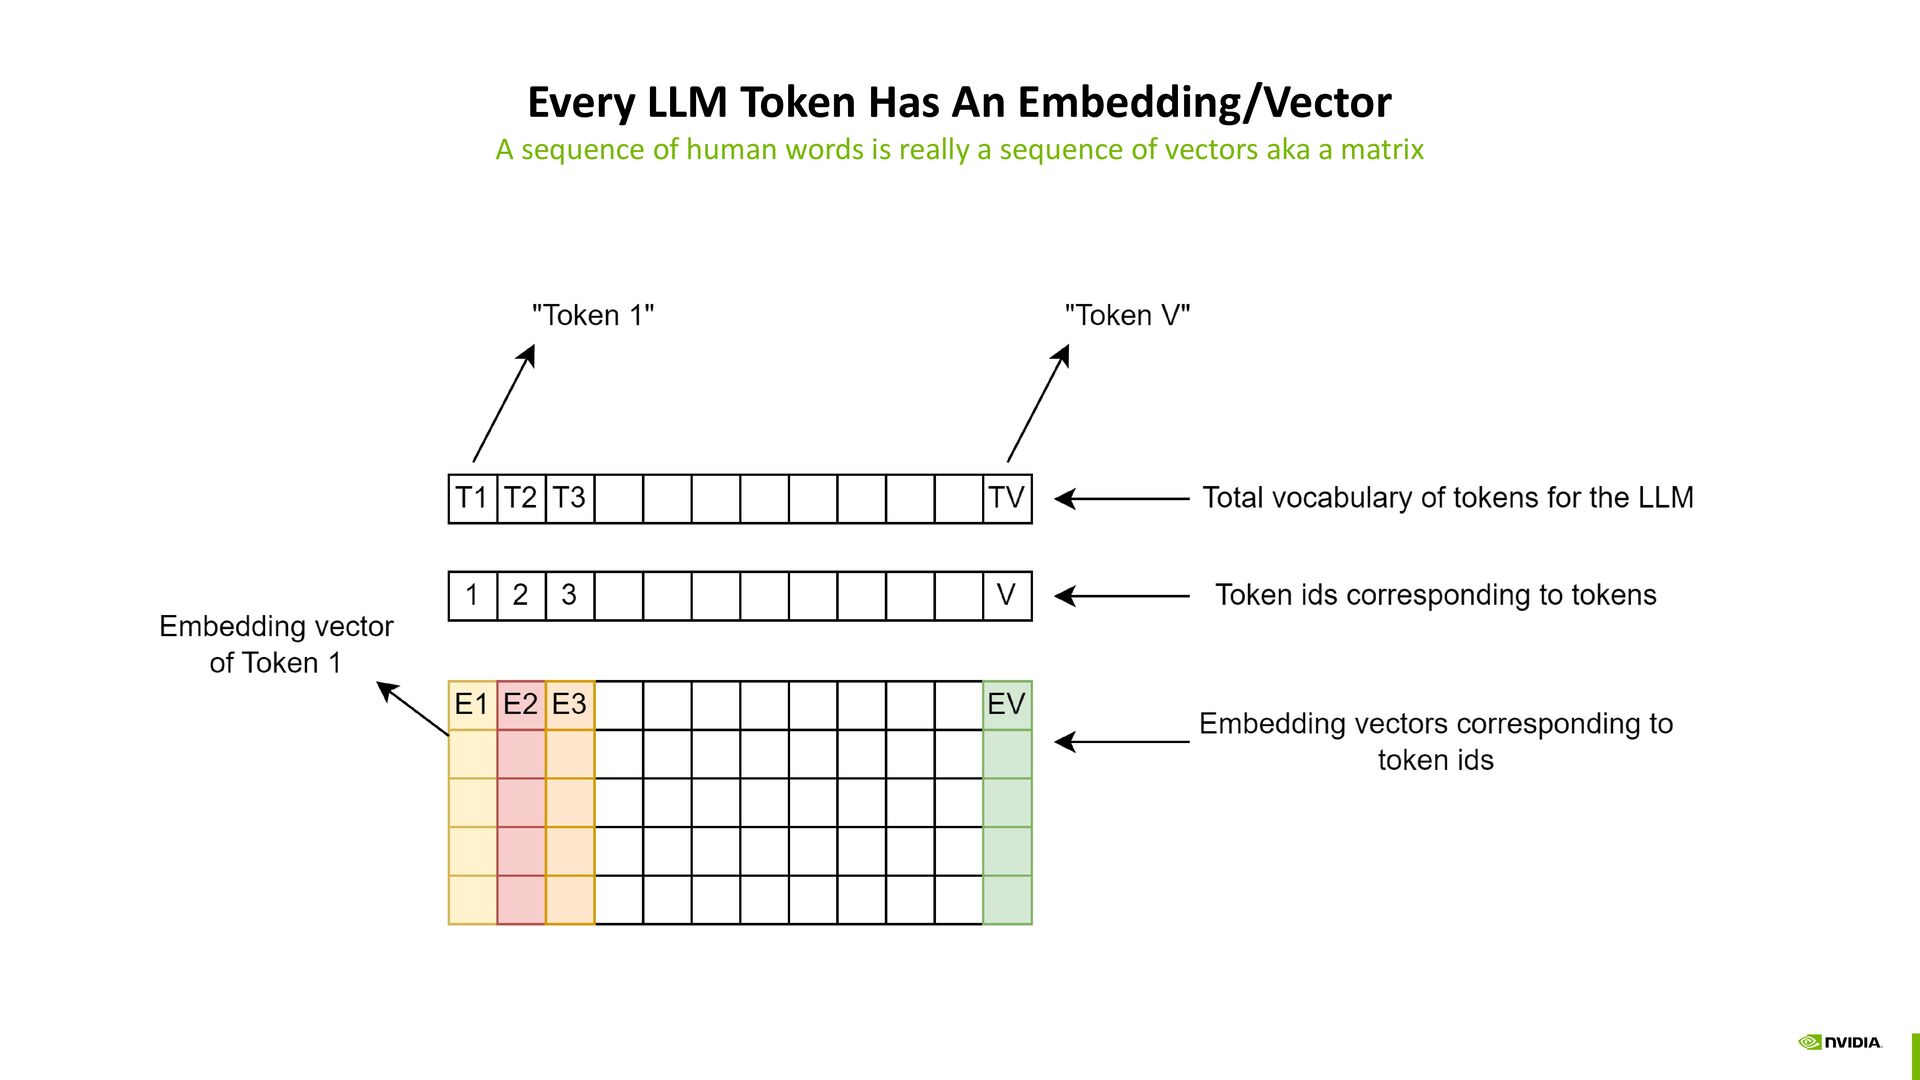
Every LLM Token Has An Embedding/Vector A sequence of human
words is really a sequence of vectors aka a matrix -
Matrix Representation of an Input Prompt Tokenization - Converting the
input sentence/sequence into a sequence of LLM token ids -
An input prompt to an LLM is stored as a
matrix on the GPU The larger the prompt the larger the matrix on the GPU gpu accelerated -
How LLMs Make Sense Of Tokens Using Attention Convert text
to token-ids -> token embeddings -> compute attention on the entire input sequence Many details of the model inference lifecycle are omitted for brevity such as mlps, layer-norms, decoding, etc -
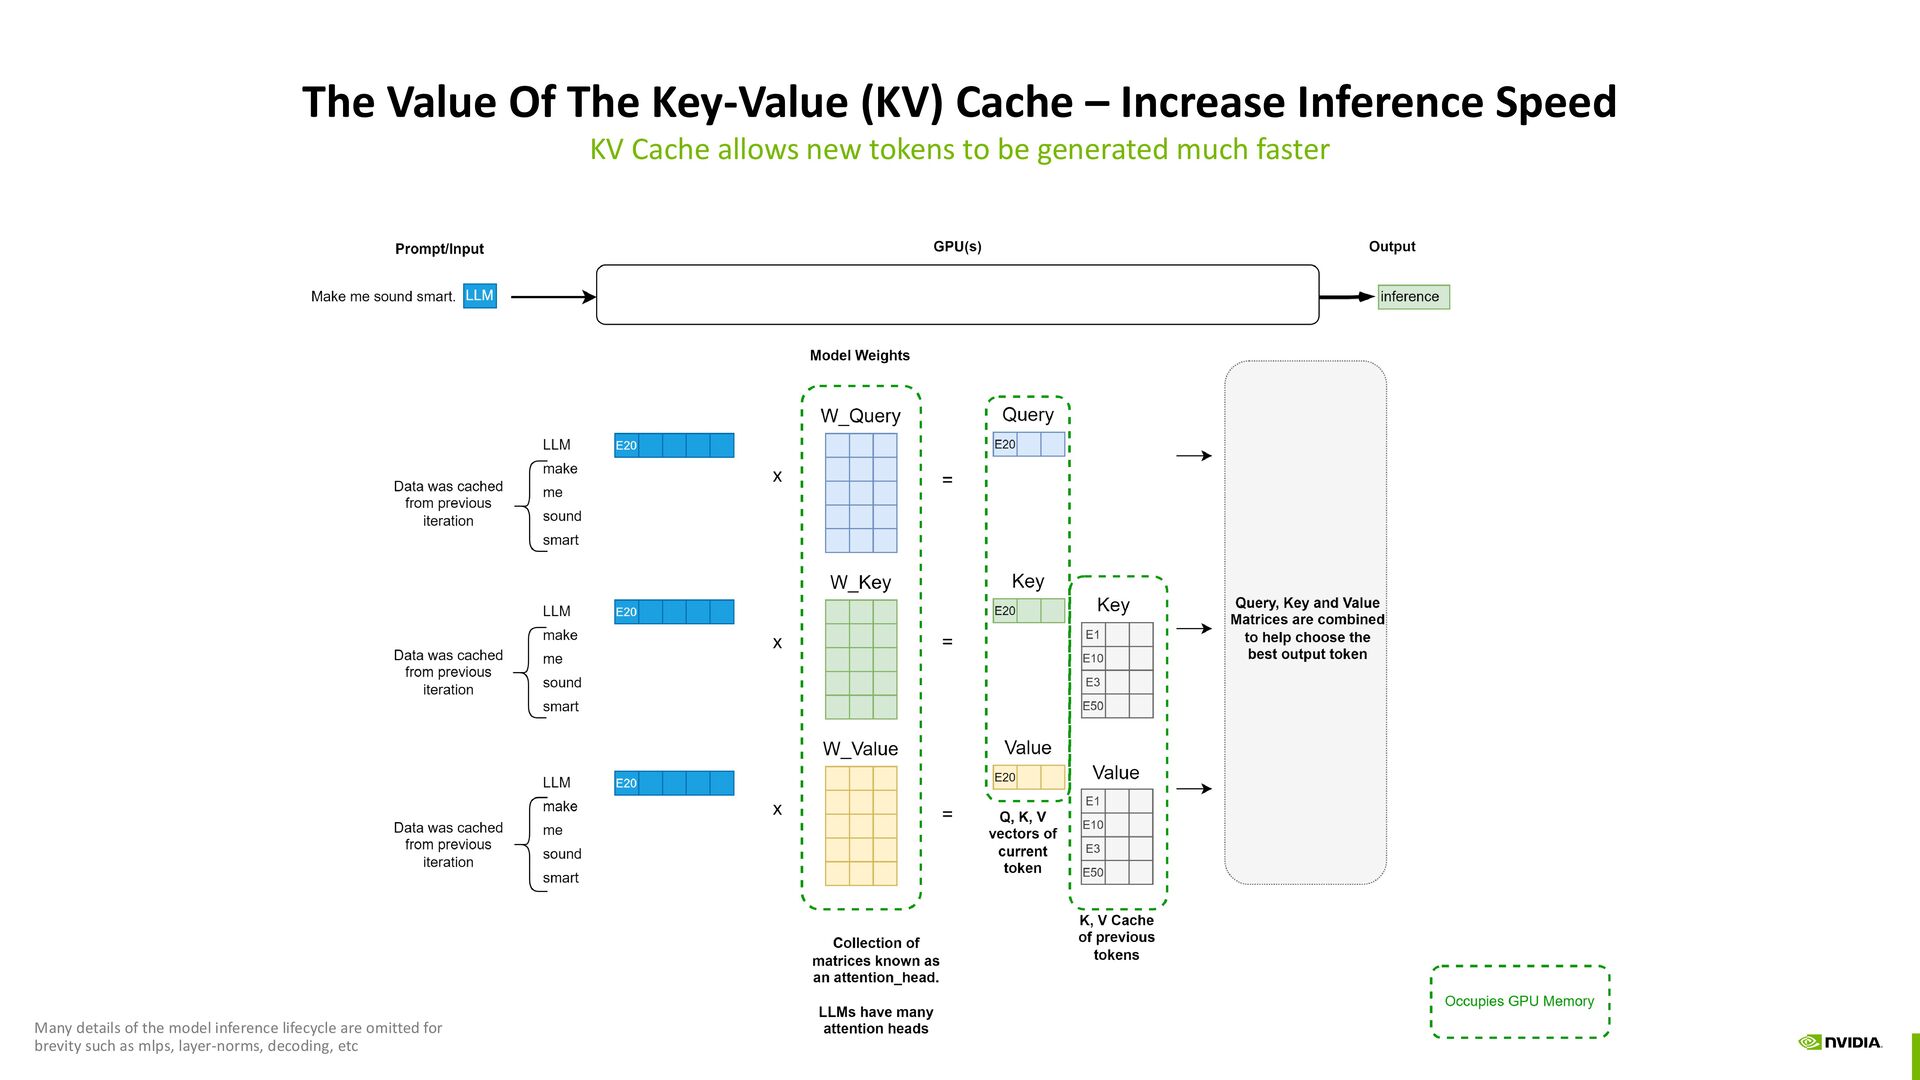
The Value Of The Key-Value (KV) Cache – Increase Inference
Speed KV Cache allows new tokens to be generated much faster Many details of the model inference lifecycle are omitted for brevity such as mlps, layer-norms, decoding, etc -
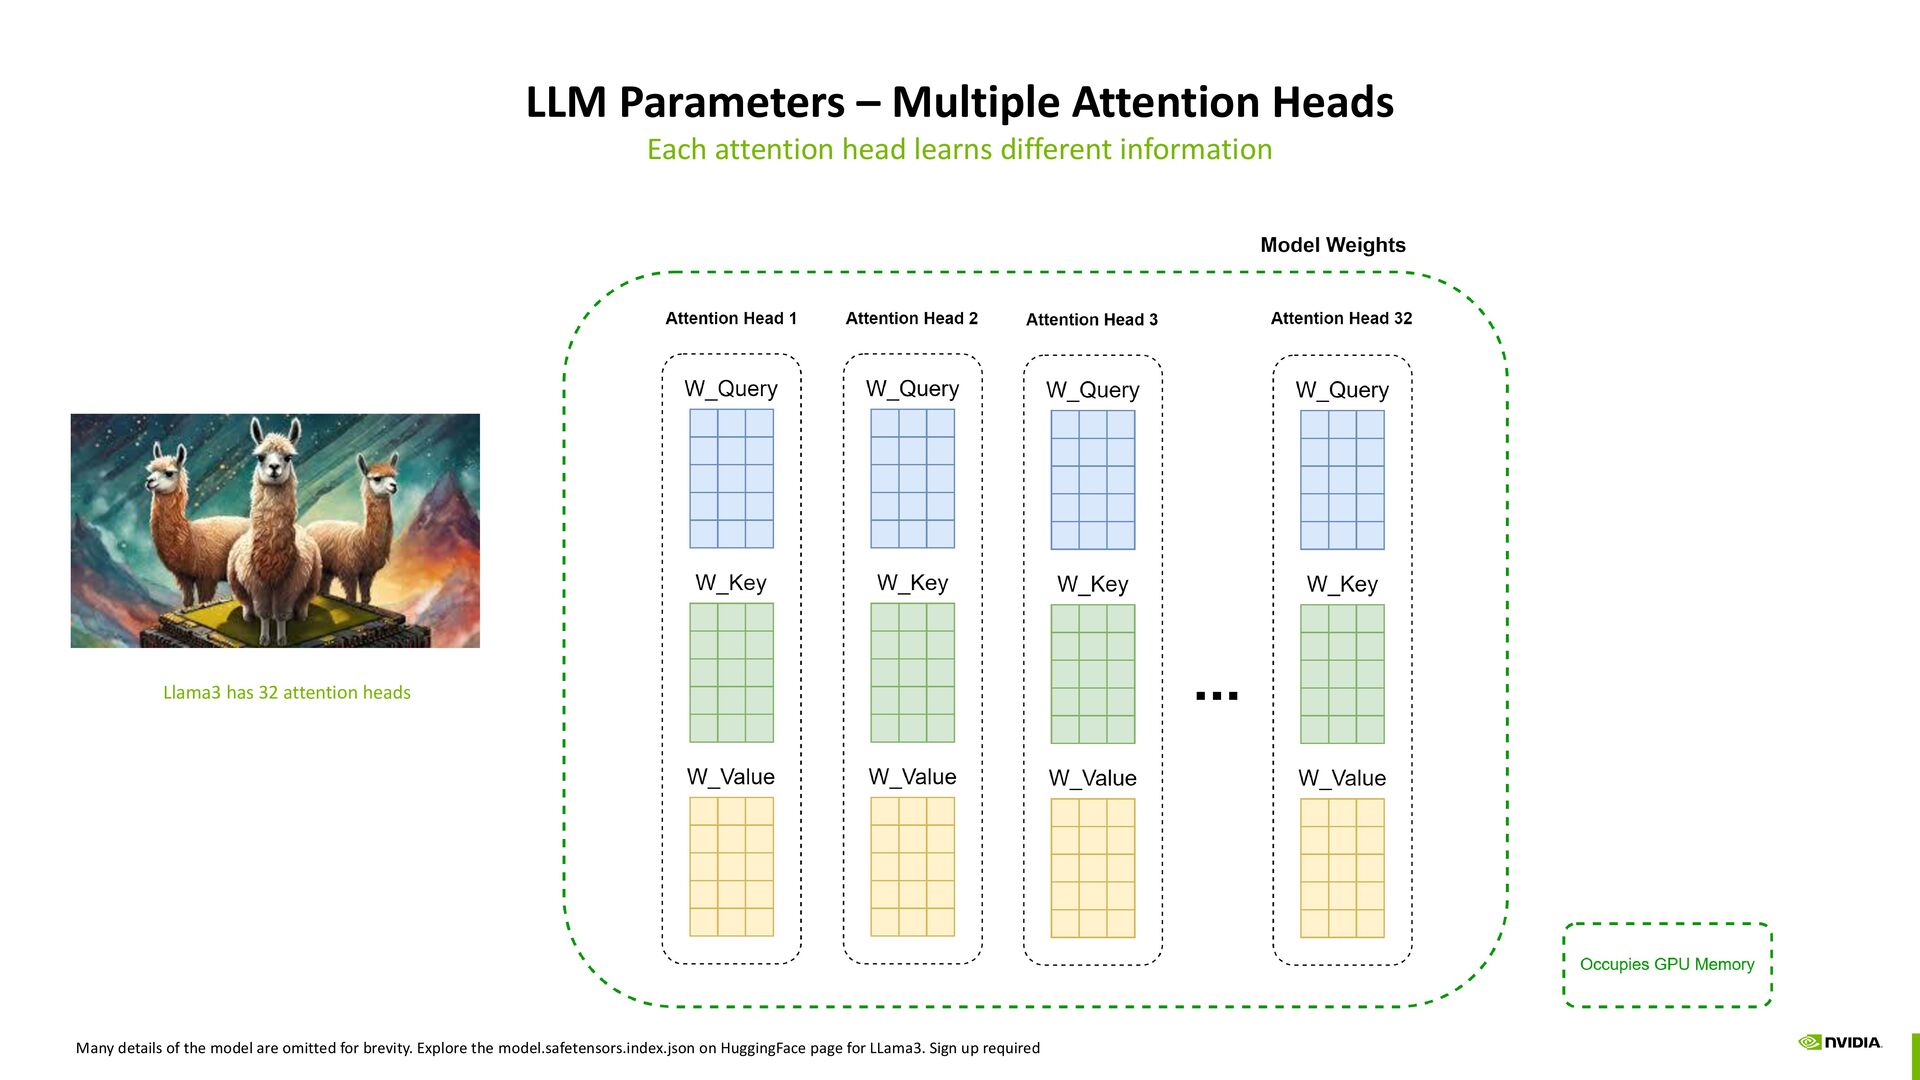
LLM Parameters – Multiple Attention Heads Each attention head learns
different information Llama3 has 32 attention heads Many details of the model are omitted for brevity. Explore the model.safetensors.index.json on HuggingFace page for LLama3. Sign up required -
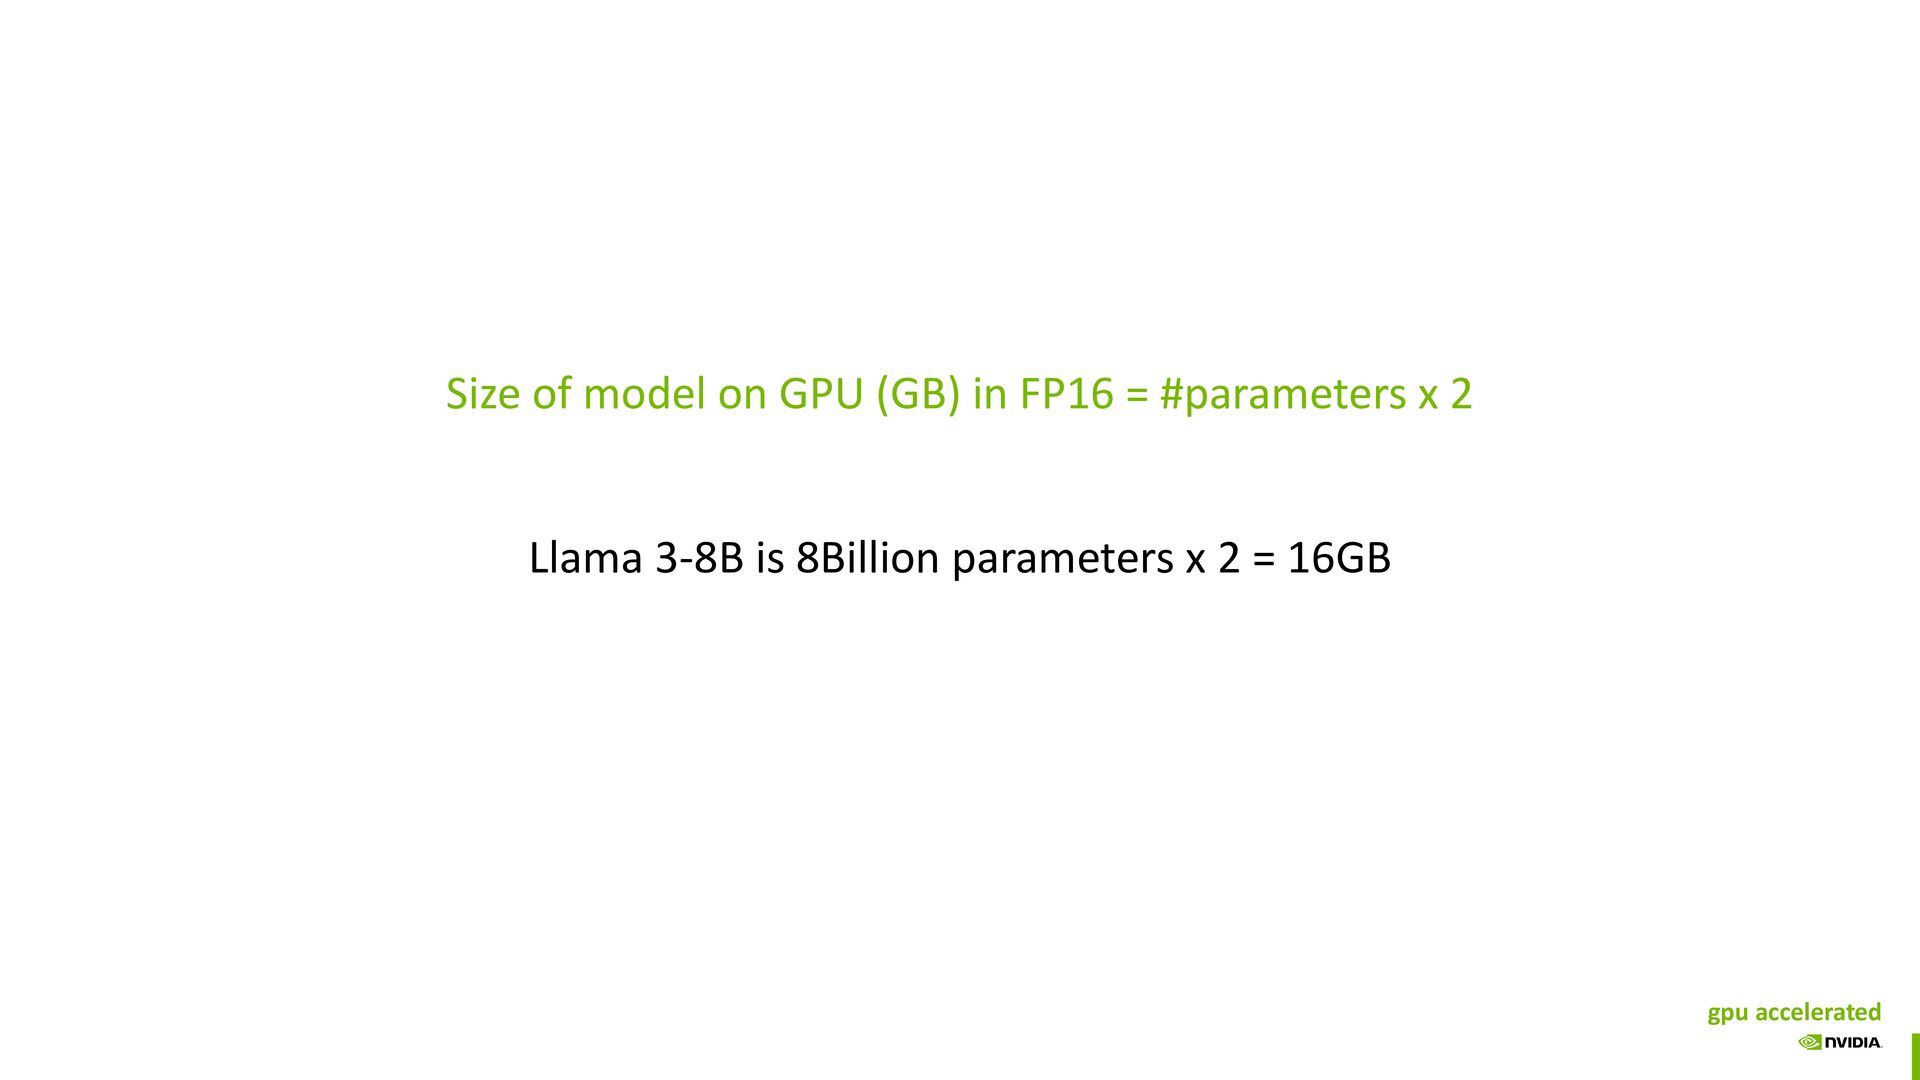
Size of model on GPU (GB) in FP16 = #parameters
x 2 Llama 3-8B is 8Billion parameters x 2 = 16GB gpu accelerated -
NVIDIA NIM CUDA Cloud-Native Stack GPU Operator, Network Operator NVIDIA
Triton Inference Server cuDF, CV-CUDA, DALI, NCCL, Postprocessing Decoder Enterprise Management Health Check, Identity, Metrics, Monitoring, Secrets Management Kubernetes Standard APIs Text, Speech, Image, Video, 3D, Biology Customization Cache P-Tuning, LoRA, Model Weights Optimized Model Single GPU, Multi-GPU, Multi-Node NVIDIA TensorRT and TensorRT-LLM cuBLAS, cuDNN, In-Flight Batching, Memory Optimization, FP8 Quantization -
Container launches and: 1. detects HW 2. mounts cache for
model & asset data 3. attempts to download optimized TRT-LLM model from NGC NVIDIA LLM NIM Pull Sequence User executes “docker run” docker run [...]\ nvn.im/meta-llama/meta- llama-3-8b-instruct NIM container is pulled from NGC Model loaded with TRT-LLM runtime Container pulls HF model for serving with vLLM HF model loaded with vLLM runtime -
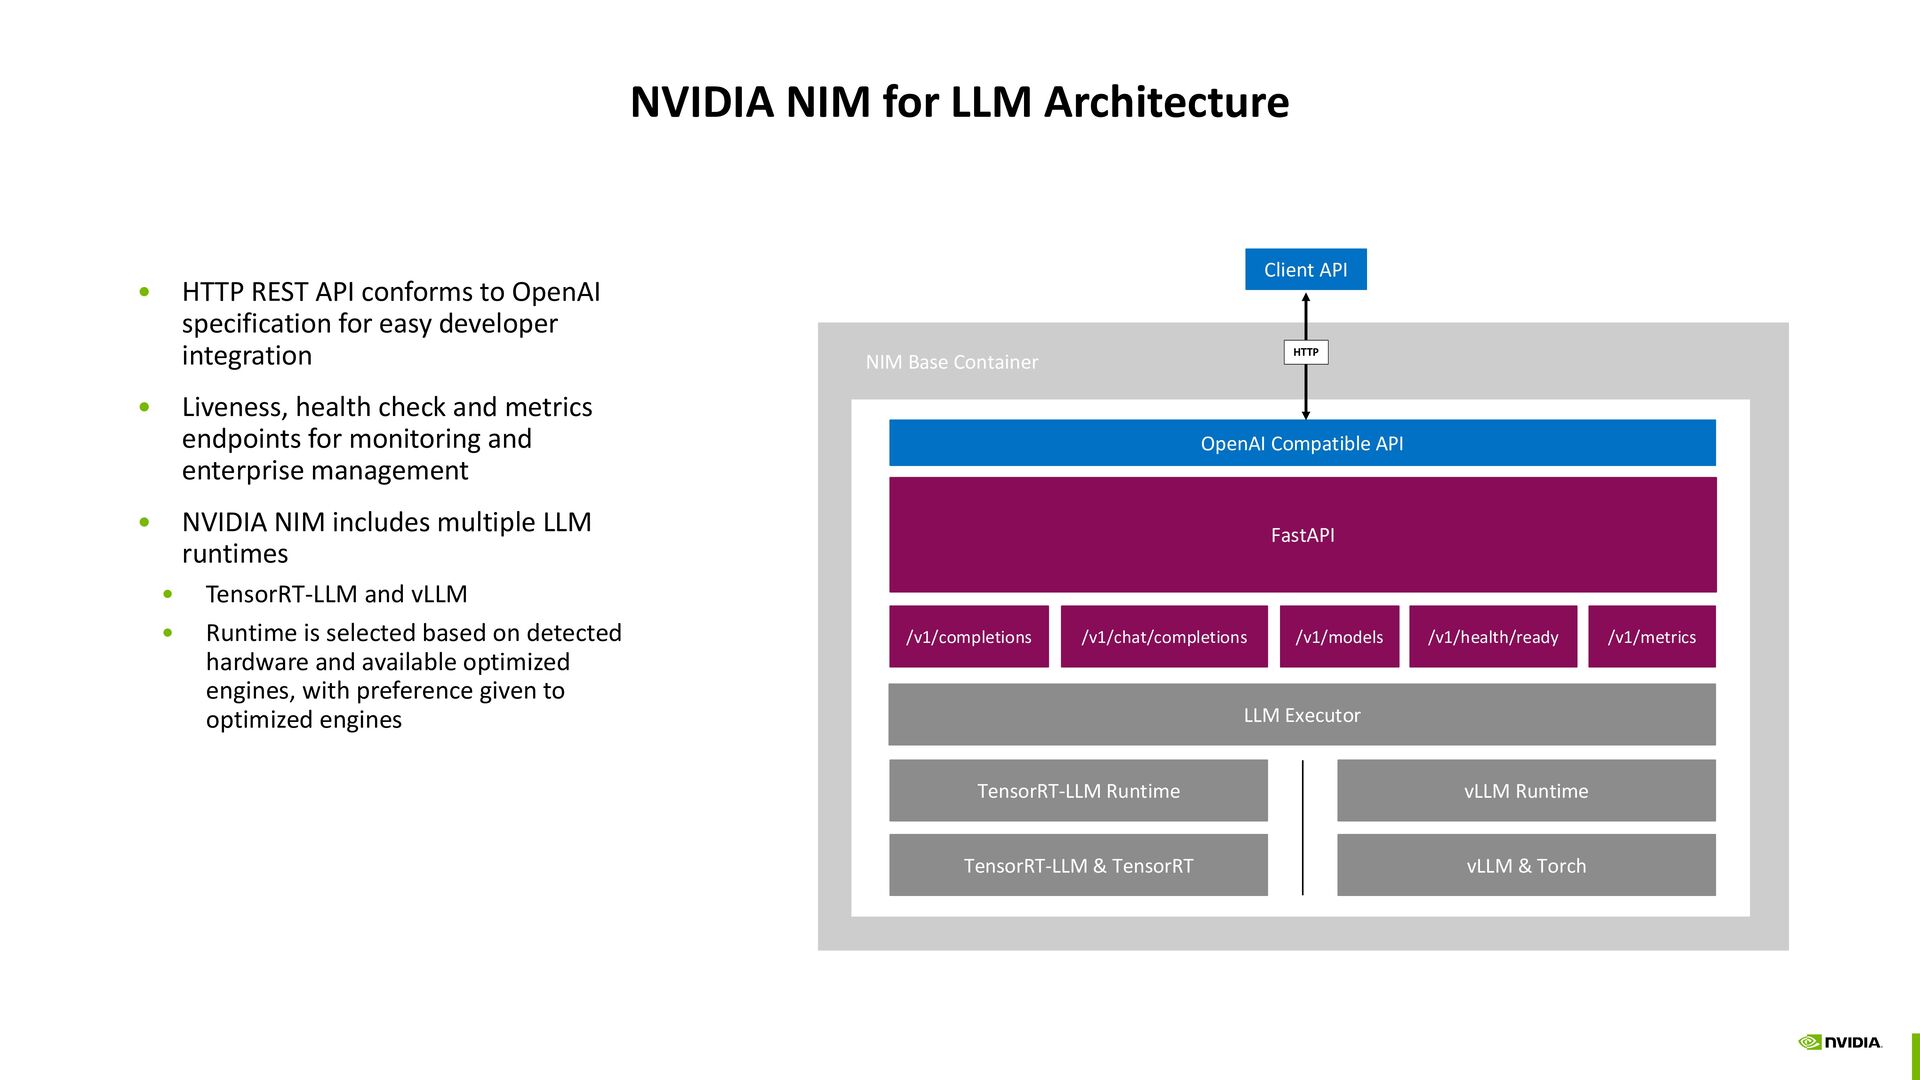
NVIDIA NIM for LLM Architecture • HTTP REST API conforms
to OpenAI specification for easy developer integration • Liveness, health check and metrics endpoints for monitoring and enterprise management • NVIDIA NIM includes multiple LLM runtimes • TensorRT-LLM and vLLM • Runtime is selected based on detected hardware and available optimized engines, with preference given to optimized engines NIM Base Container OpenAI Compatible API FastAPI /v1/completions /v1/chat/completions LLM Executor TensorRT-LLM Runtime TensorRT-LLM & TensorRT vLLM Runtime vLLM & Torch Client API /v1/models /v1/metrics /v1/health/ready HTTP -
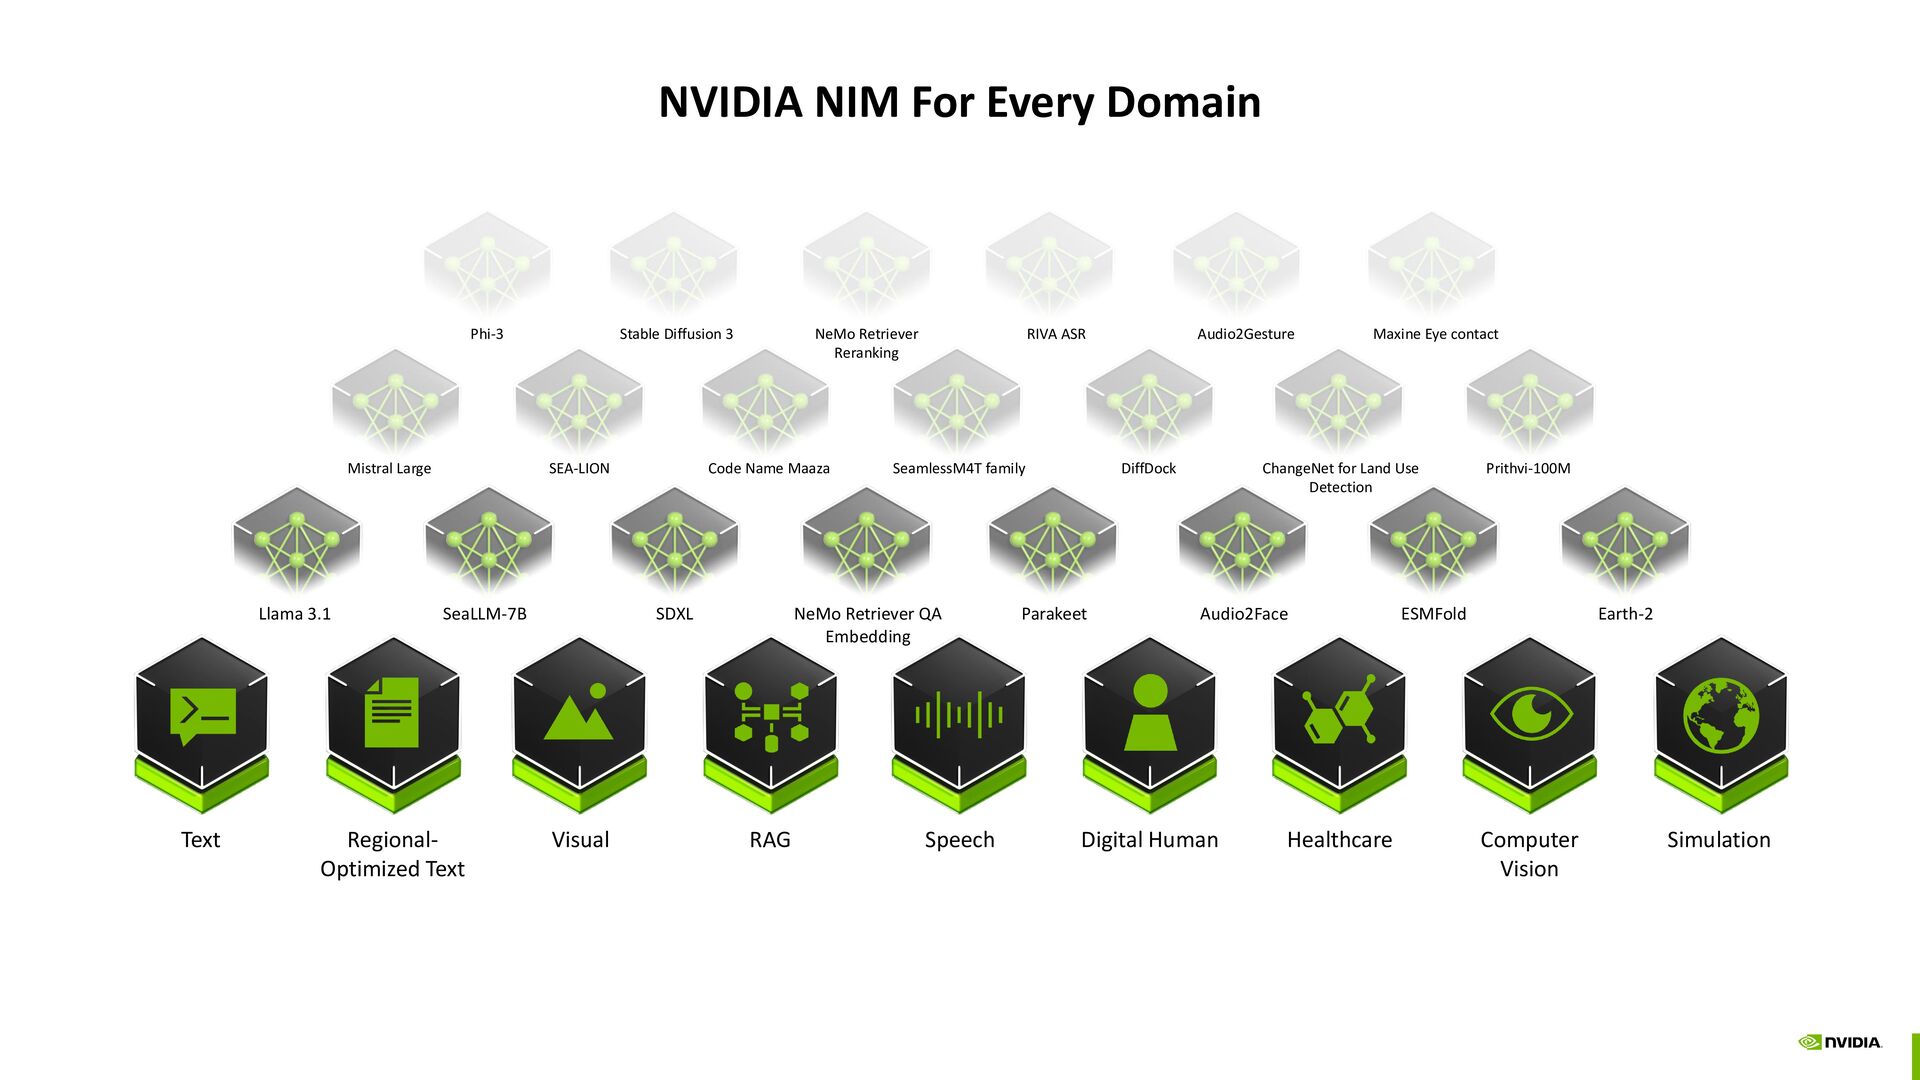
NVIDIA NIM For Every Domain Text Regional- Optimized Text Visual
RAG Speech Digital Human Healthcare Computer Vision Simulation Llama 3.1 SeaLLM-7B SDXL NeMo Retriever QA Embedding Parakeet Audio2Face ESMFold Earth-2 Mistral Large SEA-LION Code Name Maaza SeamlessM4T family DiffDock ChangeNet for Land Use Detection Prithvi-100M Phi-3 Stable Diffusion 3 NeMo Retriever Reranking RIVA ASR Audio2Gesture Maxine Eye contact -
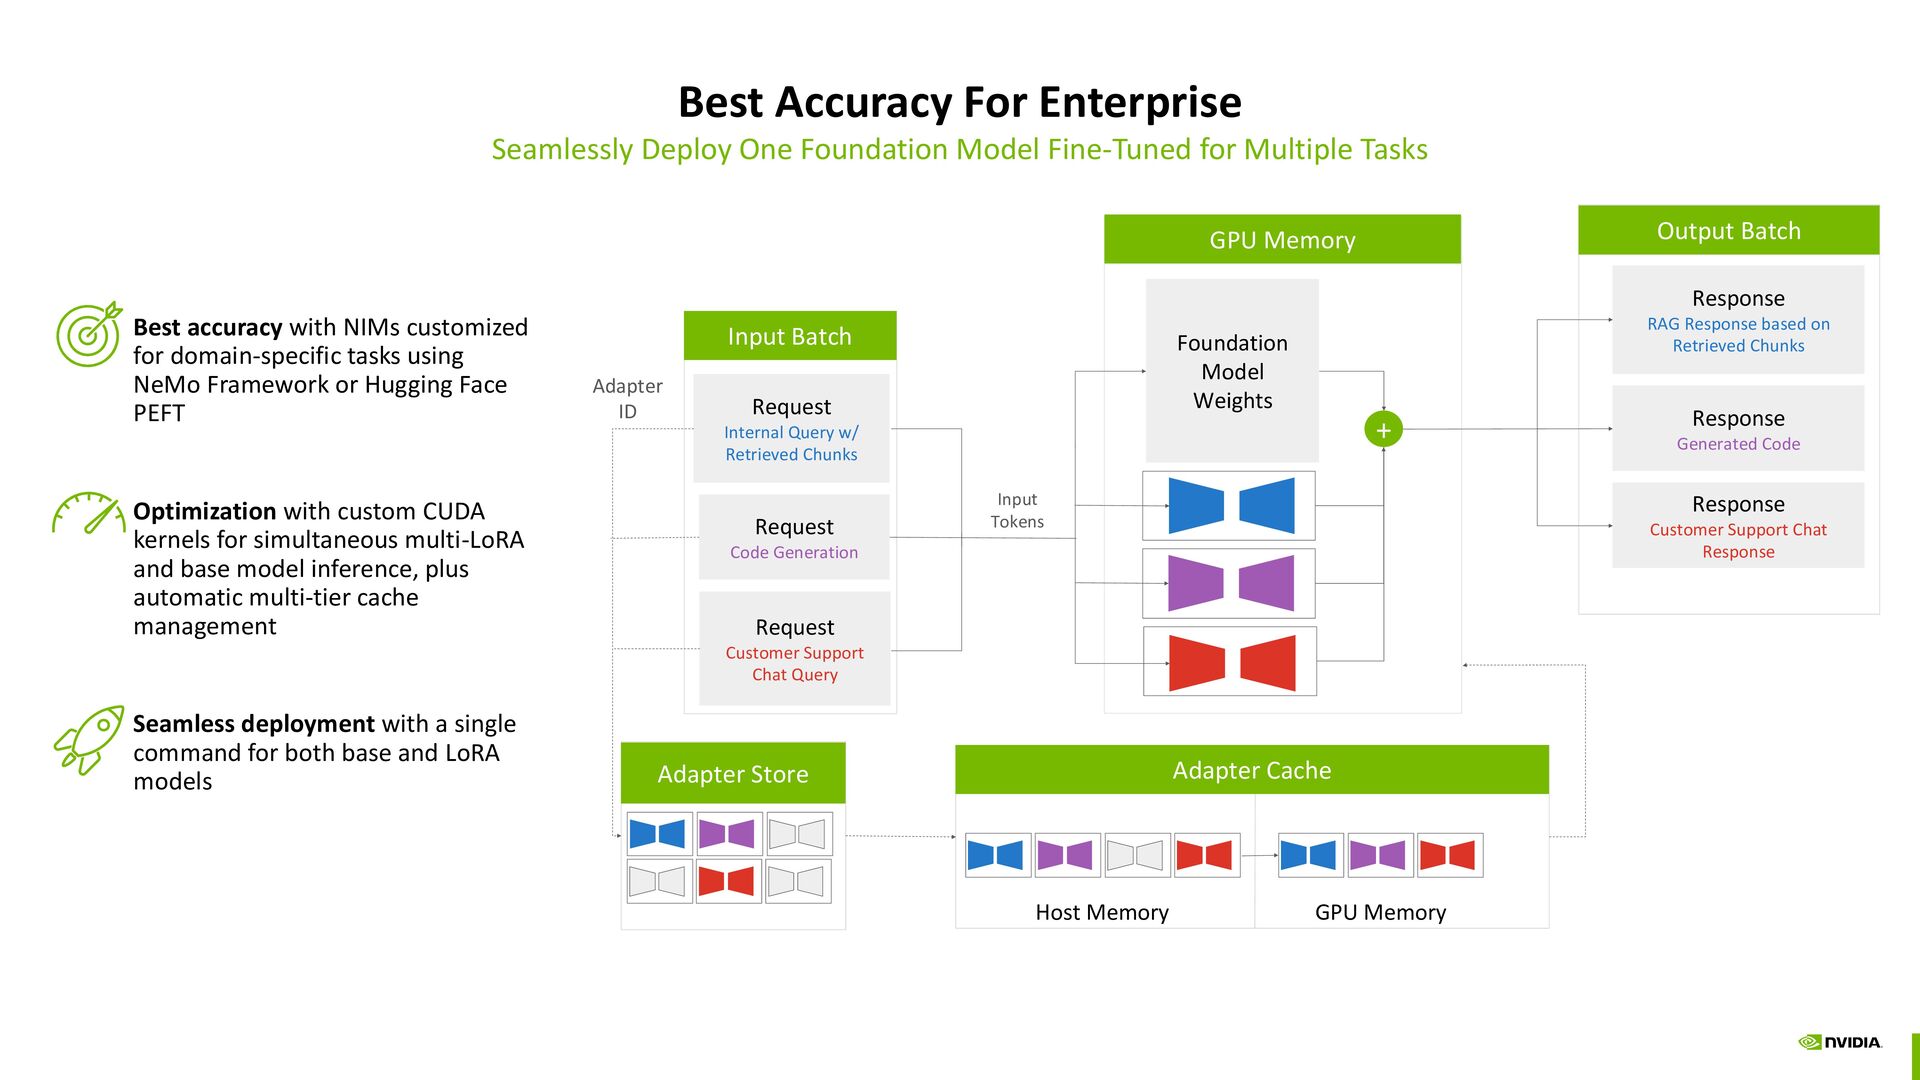
Best Accuracy For Enterprise Seamlessly Deploy One Foundation Model Fine-Tuned
for Multiple Tasks Best accuracy with NIMs customized for domain-specific tasks using NeMo Framework or Hugging Face PEFT Optimization with custom CUDA kernels for simultaneous multi-LoRA and base model inference, plus automatic multi-tier cache management Seamless deployment with a single command for both base and LoRA models GPU Memory GPU Memory Input Batch Customization Cache Foundation Model Weights + Request Internal Query w/ Retrieved Chunks Request Code Generation Request Customer Support Chat Query Host Memory GPU Memory Response RAG Response based on Retrieved Chunks Response Generated Code Response Customer Support Chat Response Input Batch Output Batch Adapter Cache Adapter Store Input Tokens Adapter ID -
How NIMs Leverage Optimized Engines Llama-3-8B-Instruct Optimization for NVIDIA GPUs
with LoRA Support Option A100 GPU Architecture H100 Number of GPUs 1 2 Optimization Profiles Throughput Latency Precision fp8 fp16 bf16 A10G L40S … … … … llama3-8b-instruct:0.10.0+cbc614f5-a100x1-fp16-throughput llama3-8b-instruct:0.10.0+cbc614f5-a100x1-fp16-lora llama3-8b-instruct:0.10.0+cbc614f5-a100x2-fp16-latency llama3-8b-instruct:0.10.0+cbc614f5-h100x2-fp16-latency llama3-8b-instruct:0.10.0+cbc614f5-h100x1-fp8-throughput llama3-8b-instruct:0.10.0+cbc614f5-h100x2-fp8-latency llama3-8b-instruct:0.10.0+cbc614f5-h100x1-fp16-throughput llama3-8b-instruct:0.10.0+cbc614f5-h100x1-fp16-lora llama3-8b-instruct:0.10.0+cbc614f5-a10gx2-fp16-latency llama3-8b-instruct:0.10.0+cbc614f5-a10gx1-fp16-throughput llama3-8b-instruct:0.10.0+cbc614f5-a10gx1-fp16-lora llama3-8b-instruct:0.10.0+cbc614f5-l40sx2-fp8-latency llama3-8b-instruct:0.10.0+cbc614f5-l40sx2-fp16-latency llama3-8b-instruct:0.10.0+cbc614f5-l40sx1-fp8-throughput llama3-8b-instruct:0.10.0+cbc614f5-l40sx1-fp16-throughput llama3-8b-instruct:0.10.0+cbc614f5-l40sx1-fp16-lora Optimized Models … 4 8 -
How NIMs Leverage Optimized Engines Llama-3-70B-Instruct Optimization for NVIDIA GPUs
with LoRA Support Option A100 GPU Architecture H100 Number of GPUs 1 2 Optimization Profiles Throughput Latency Precision fp8 fp16 bf16 L40S … … … … llama3-70b-instruct:0.10.0+cbc614f5-h100x8-fp8-latency llama3-70b-instruct:0.10.0+cbc614f5-h100x8-fp16-latency llama3-70b-instruct:0.10.0+cbc614f5-h100x4-fp8-throughput llama3-70b-instruct:0.10.0+cbc614f5-h100x4-fp16-throughput llama3-70b-instruct:0.10.0+cbc614f5-h100x4-fp16-lora lllama3-70b-instruct:0.10.0+cbc614f5-a100x8-bf16-latency llama3-70b-instruct:0.10.0+cbc614f5-a100x4-fp16-throughput llama3-70b-instruct:0.10.0+cbc614f5-a100x4-fp16-lora llama3-70b-instruct:0.10.0+cbc614f5-l40sx8-fp16-throughput llama3-70b-instruct:0.10.0+cbc614f5-l40sx8-fp8-latency llama3-70b-instruct:0.10.0+cbc614f5-l40sx4-fp8-throughput llama3-70b-instruct:0.10.0+cbc614f5-l40sx8-fp16-lora Optimized Models … 4 8 -
NeMo Retriever Supercharges RAG Applications World’s Best Open, Commercial Text
Q&A Retrieval Pipeline Vector Database Data Optimized Inference Engines State-of-the-art, customizable models, fine-tuned for accuracy Flexible and modular deployment Accelerated vector search Production Ready Plan Event Prompt Retriever Microservice LLM NIM NeMo Retriever Embedding NIM NeMo Retriever Reranking NIM -
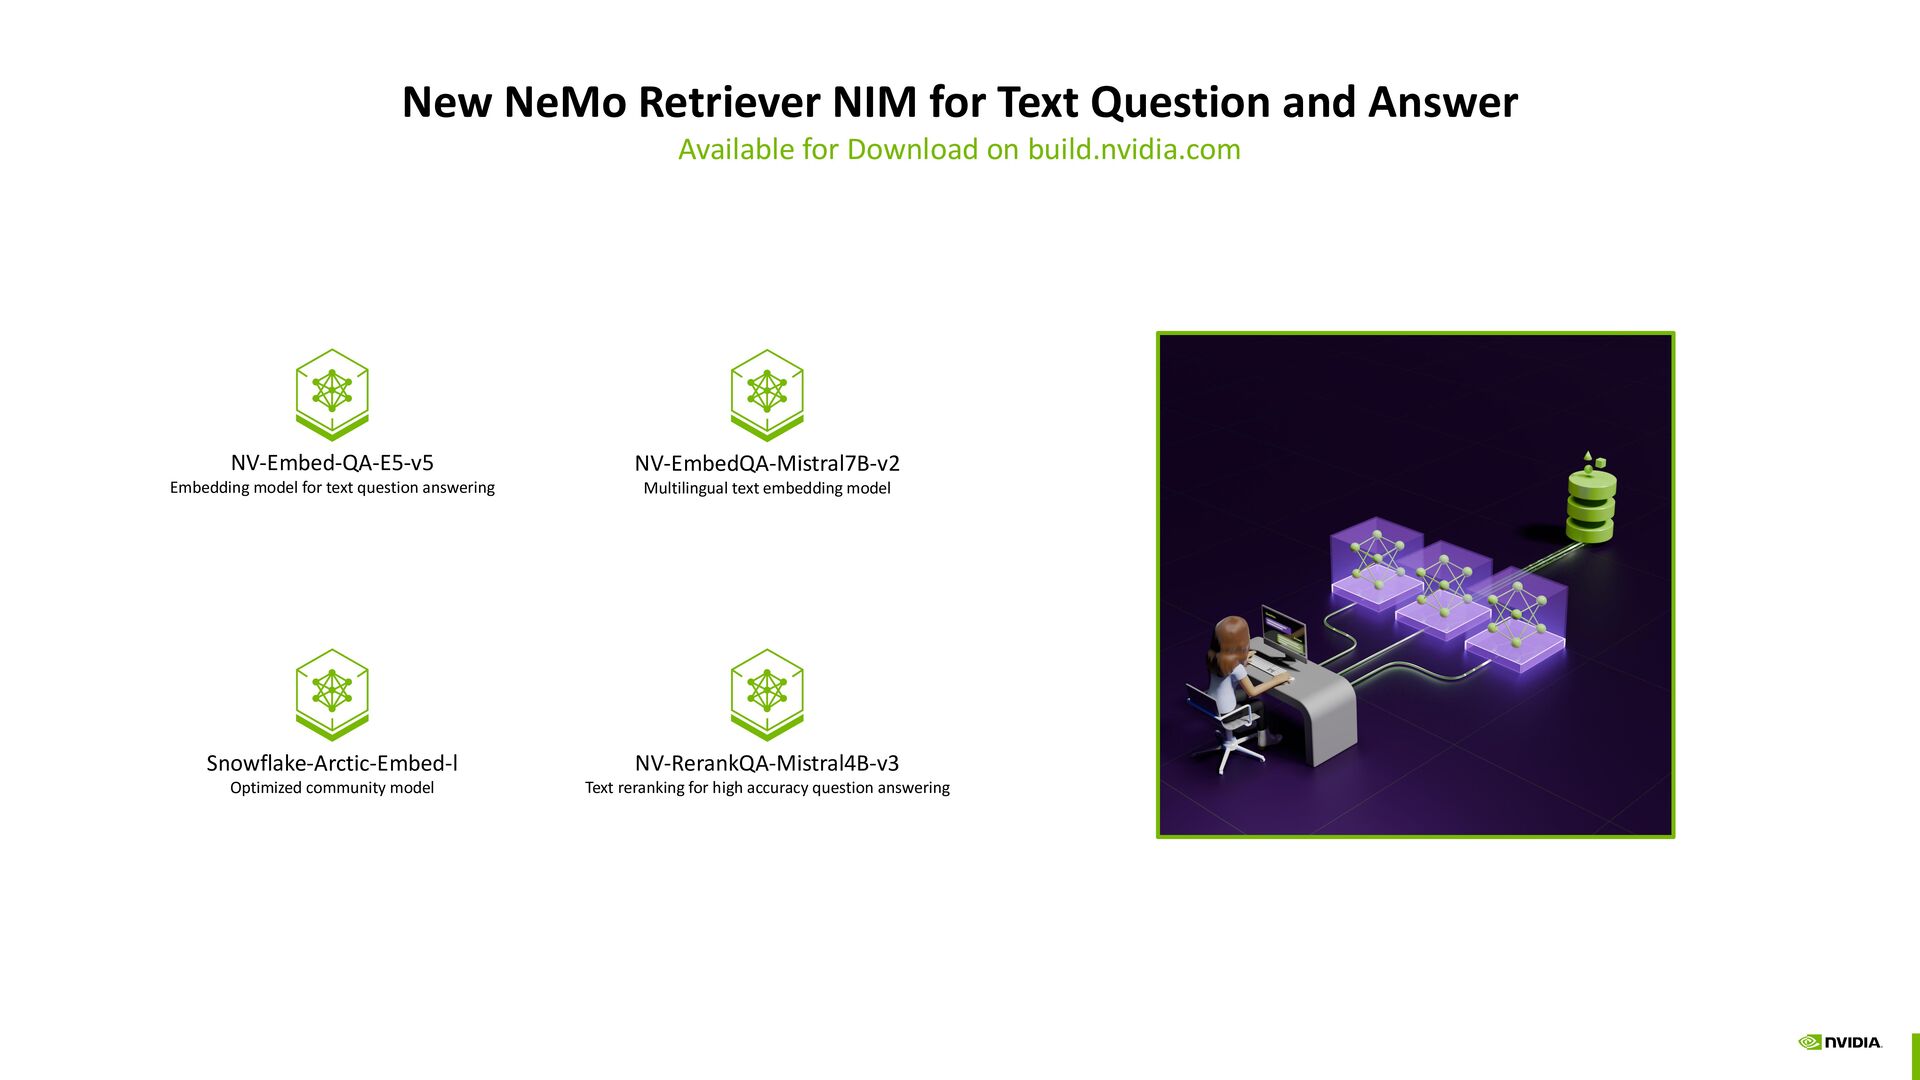
New NeMo Retriever NIM for Text Question and Answer Available
for Download on build.nvidia.com NV-RerankQA-Mistral4B-v3 Text reranking for high accuracy question answering NV-Embed-QA-E5-v5 Embedding model for text question answering NV-EmbedQA-Mistral7B-v2 Multilingual text embedding model Snowflake-Arctic-Embed-l Optimized community model -
Case Study: Cadence Design Systems Recall Top 1 Top 3
Top 5 Top 10 Reference Pipeline 36% 52% 57% 64% NeMo Retriever Hybrid Search 57% 70% 77% 80% NeMo Retriever Hybrid Search + Reranker 69% 81% 86% 89% Improvement Factor 2x 2.5x 3x 3.3x 3.3x fewer incorrect answers retrieving from technical documentation