Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
CloudVisionAPIでOCRする
Search
KosukeShimizu
October 03, 2023
Programming
210
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
CloudVisionAPIでOCRする
KosukeShimizu
October 03, 2023
More Decks by KosukeShimizu
See All by KosukeShimizu
Amazon Personalizeでやらかした話
thimi0412
0
890
Other Decks in Programming
See All in Programming
速く作れる。その次は、速く確かめられる開発へ 〜AIネイティブ開発を支える、Shift Down〜 / Can build fast. Next, moving to development where we can verify fast.
rkaga
8
5.3k
技術的負債を組織課題として解く-増えすぎたマイクロサービスとの戦い-
reimaru
1
2.6k
モジュールの視点からSwiftを読み解く #iosdc
s_shimotori
0
300
KiroのSpecで「五目並べ」を作ってみる
satoshi256kbyte
1
330
Androidだけじゃない、DroidKaigiで広がった私の技術スタック
akkeylab
0
110
ゲームコントローラやキーボードのファームウェアをSwiftで書く
kishikawakatsumi
1
270
Vue Fes Japan 2026 タイムテーブル徹底解説
448jp
1
590
re:Inventに行く前に知っておきたい現地参加のノウハウ
nokomoro3
0
300
ハーネス設計入門 〜 基礎知識の整理から実務へのステップアップ 〜
kinopeee
20
20k
技術的負債の返済は、AI時代の複利で効く投資 — 経営としての意思決定とその遂行
curekoshimizu
1
2.1k
iOS 27でニュースアプリはどう変わる!? 〜日経電子版の新機能対応と、開発事例から〜
lynnswap
7
13k
ソニーのクラウド共通基盤の変遷と AI時代の開発スタイルに合わせた進化 / The Journey of Sony’s Common Cloud Platform and Its Evolution for AI-Native Development
kenjiyoneyama
0
210
Featured
See All Featured
Understanding Cognitive Biases in Performance Measurement
bluesmoon
32
3k
Amusing Abliteration
ianozsvald
1
320
Jess Joyce - The Pitfalls of Following Frameworks
techseoconnect
PRO
1
420
The World Runs on Bad Software
bkeepers
PRO
72
12k
svc-hook: hooking system calls on ARM64 by binary rewriting
retrage
2
600
The Illustrated Guide to Node.js - THAT Conference 2024
reverentgeek
1
550
Large-scale JavaScript Application Architecture
addyosmani
515
110k
A Modern Web Designer's Workflow
chriscoyier
699
190k
BBQ
matthewcrist
89
10k
Speed Design
sergeychernyshev
33
2.1k
From Legacy to Launchpad: Building Startup-Ready Communities
dugsong
0
340
Navigating the Design Leadership Dip - Product Design Week Design Leaders+ Conference 2024
apolaine
2
450
Transcript
© WED, Inc. WED株式会社 | Kosuke Shimizu CloudVisionAPIで OCRする
2 スライドのQRコード
CloudVisionAPIでOCRする 自己紹介 • Name: 清水 幸佑(Kosuke Shimizu) ◦ thimi0412 •
Language ◦ Python ◦ Go • Job: 2022-02 WEDにJOIN ◦ データエンジニア ◦ OCR周りの開発 ◦ データ基盤やデータパイプラインの作成 ◦ ML周りのインフラ基盤の作成 3
CloudVisionAPIと ONEのOCRについて 4
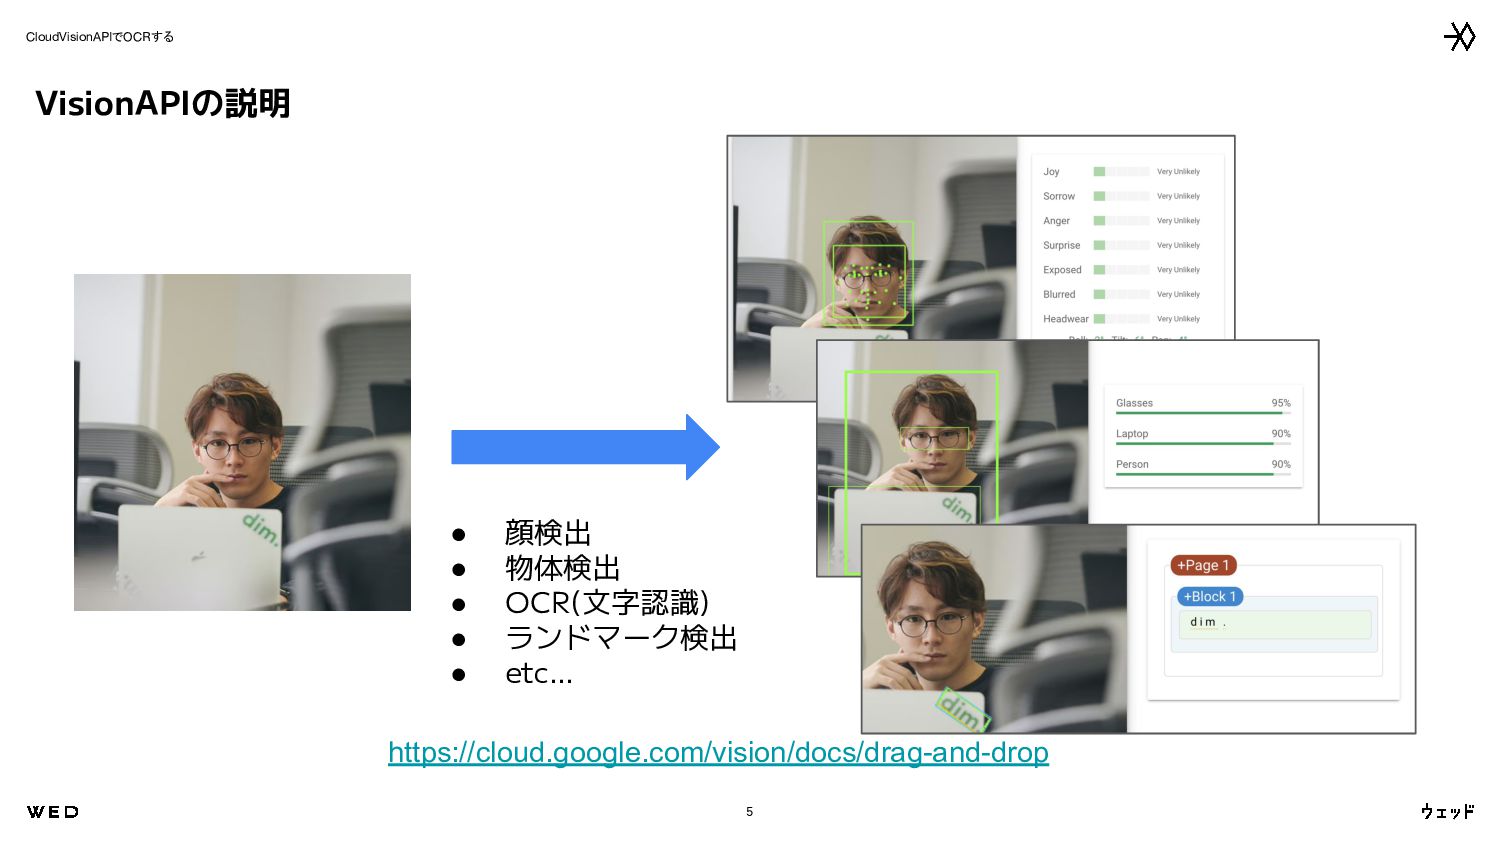
CloudVisionAPIでOCRする 5 VisionAPIの説明 • 顔検出 • 物体検出 • OCR(文字認識) •
ランドマーク検出 • etc… https://cloud.google.com/vision/docs/drag-and-drop
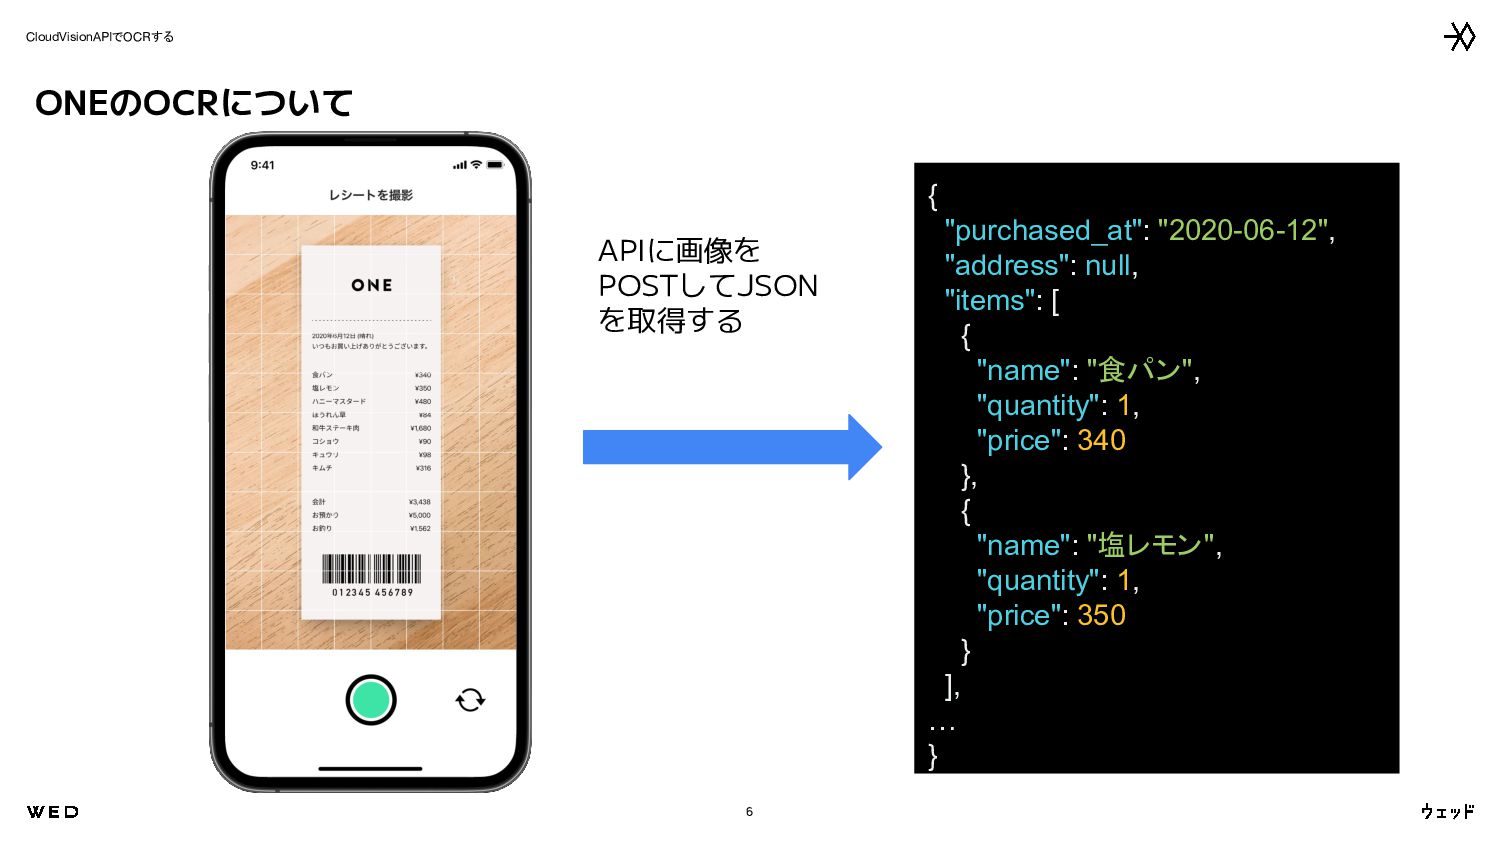
CloudVisionAPIでOCRする 6 ONEのOCRについて { "purchased_at": "2020-06-12", "address": null, "items": [
{ "name": "食パン", "quantity": 1, "price": 340 }, { "name": "塩レモン", "quantity": 1, "price": 350 } ], … } APIに画像を POSTしてJSON を取得する
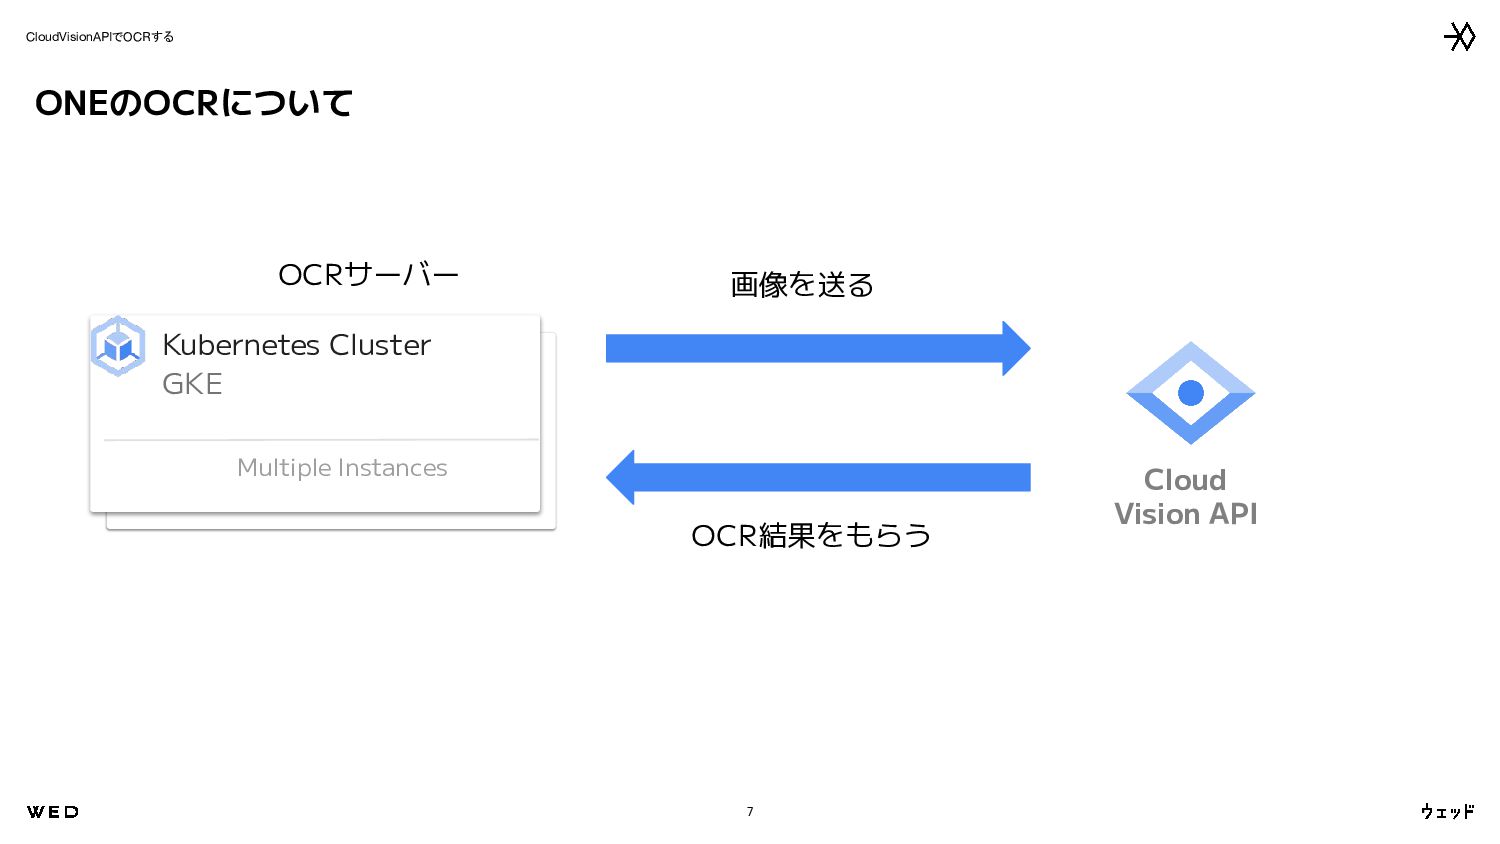
CloudVisionAPIでOCRする 7 ONEのOCRについて Kubernetes Cluster GKE Multiple Instances Cloud Vision
API OCRサーバー 画像を送る OCR結果をもらう
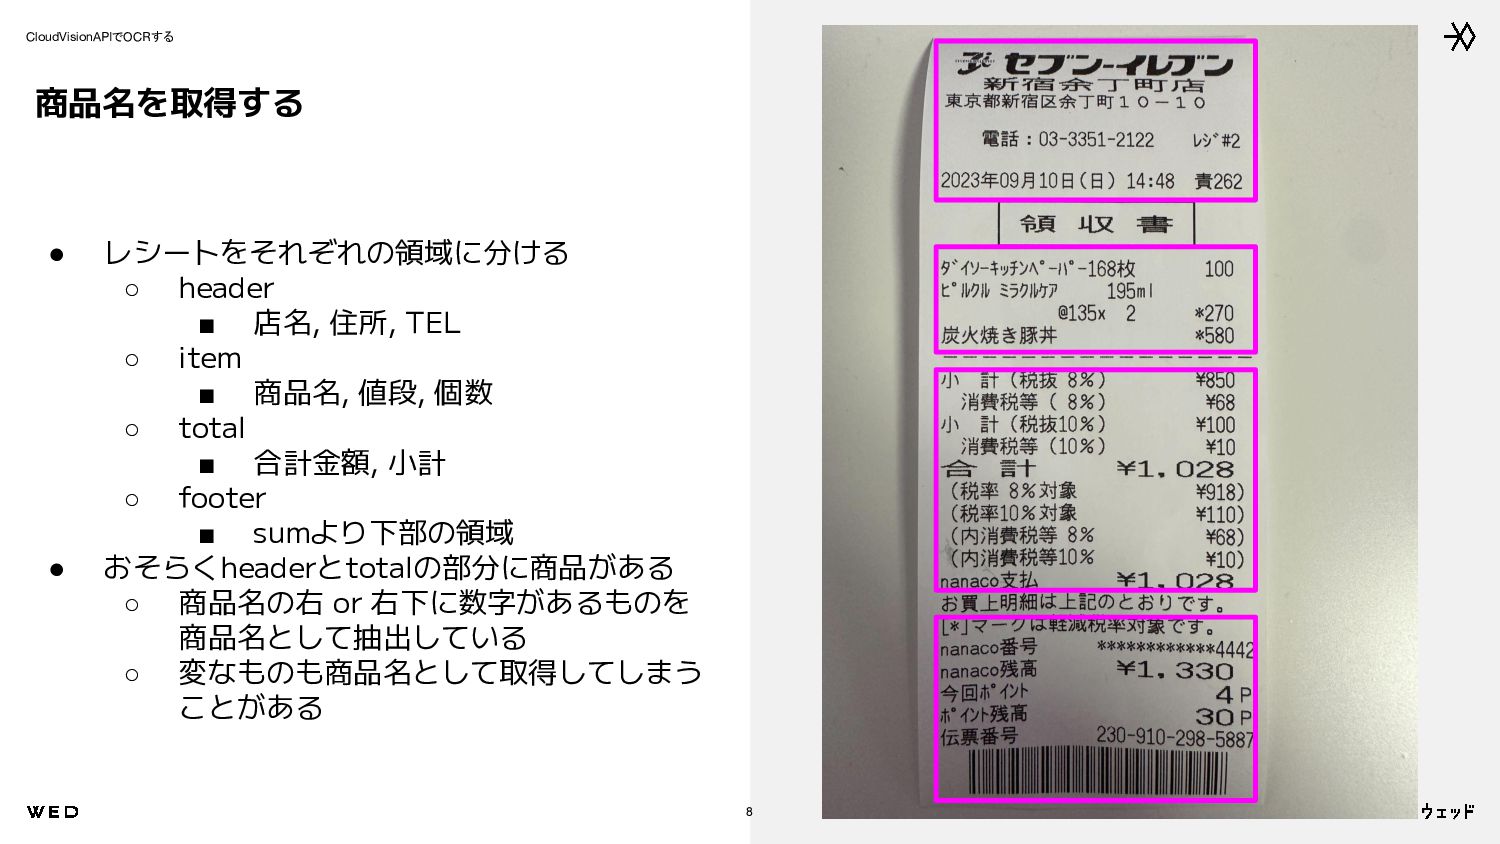
CloudVisionAPIでOCRする • レシートをそれぞれの領域に分ける ◦ header ▪ 店名, 住所, TEL ◦
item ▪ 商品名, 値段, 個数 ◦ total ▪ 合計金額, 小計 ◦ footer ▪ sumより下部の領域 • おそらくheaderとtotalの部分に商品がある ◦ 商品名の右 or 右下に数字があるものを 商品名として抽出している ◦ 変なものも商品名として取得してしまう ことがある 8 商品名を取得する
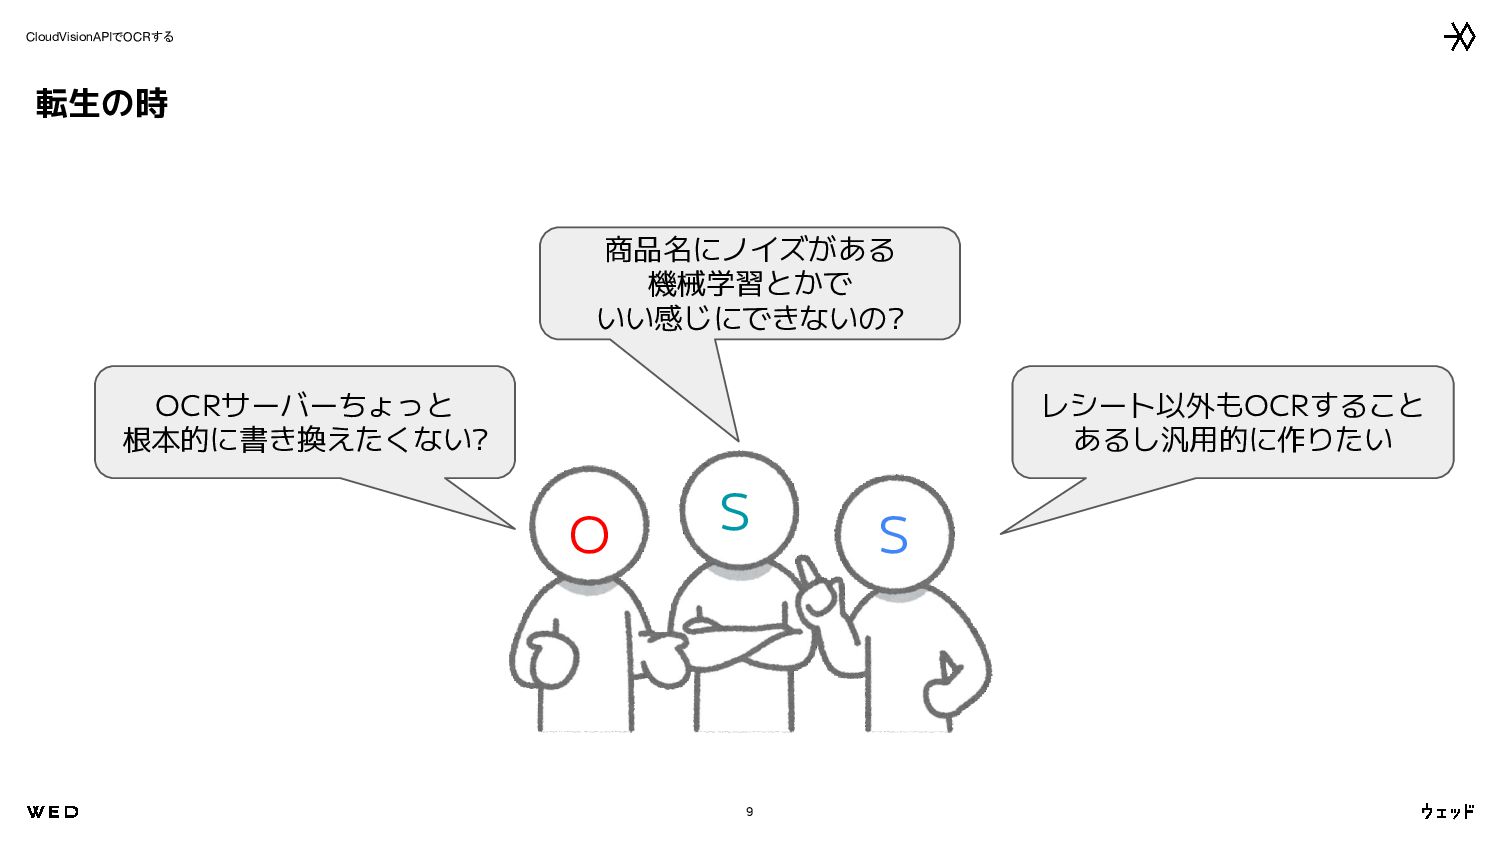
CloudVisionAPIでOCRする 9 転生の時 OCRサーバーちょっと 根本的に書き換えたくない? 商品名にノイズがある 機械学習とかで いい感じにできないの? レシート以外もOCRすること あるし汎用的に作りたい
O S S
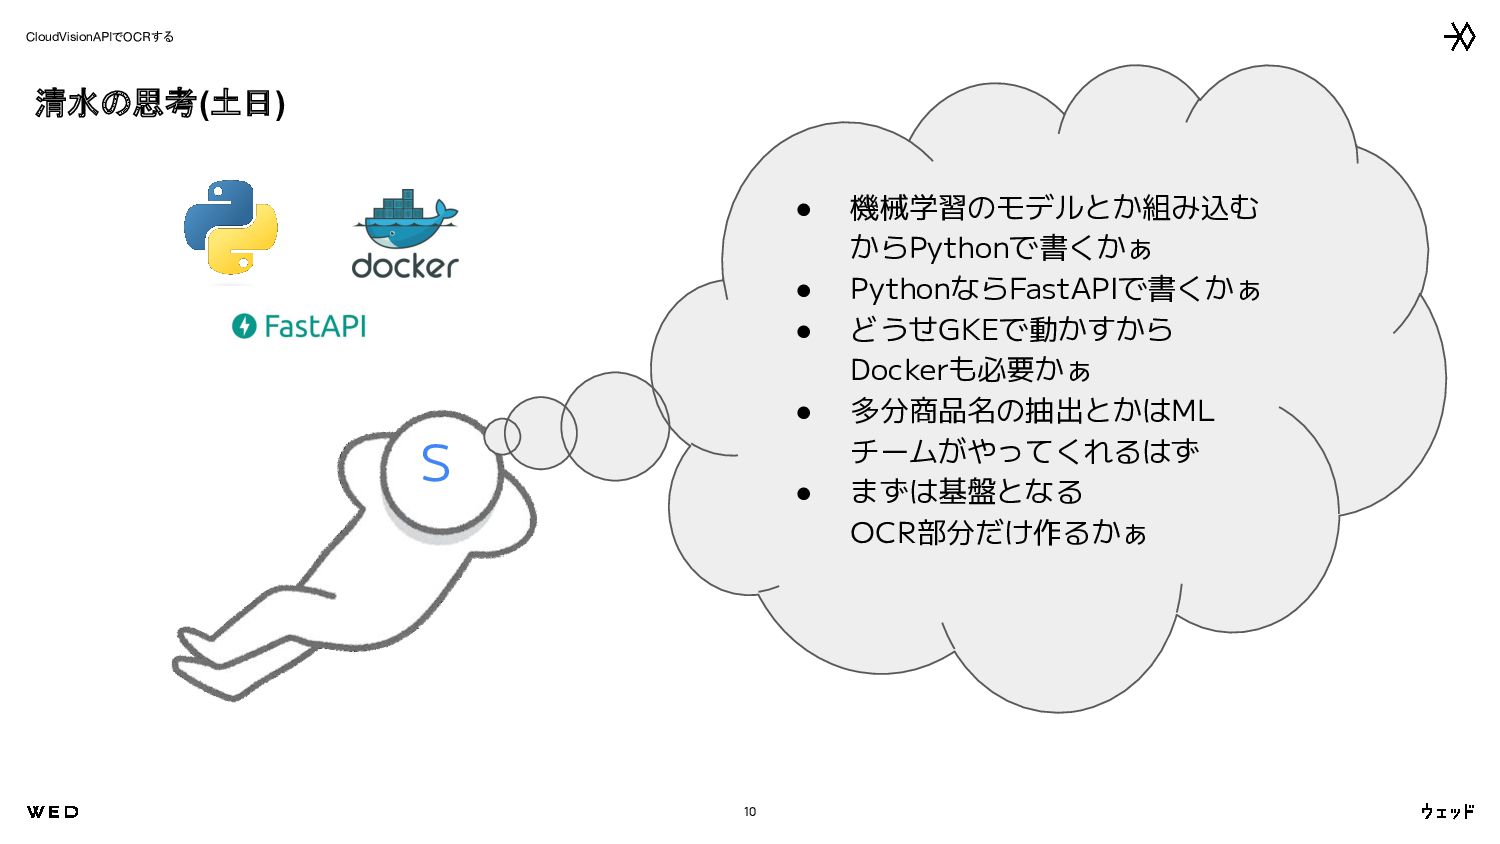
CloudVisionAPIでOCRする 10 清水の思考(土日) S • 機械学習のモデルとか組み込む からPythonで書くかぁ • PythonならFastAPIで書くかぁ •
どうせGKEで動かすから Dockerも必要かぁ • 多分商品名の抽出とかはML チームがやってくれるはず • まずは基盤となる OCR部分だけ作るかぁ
ここからは実装部分の話 11
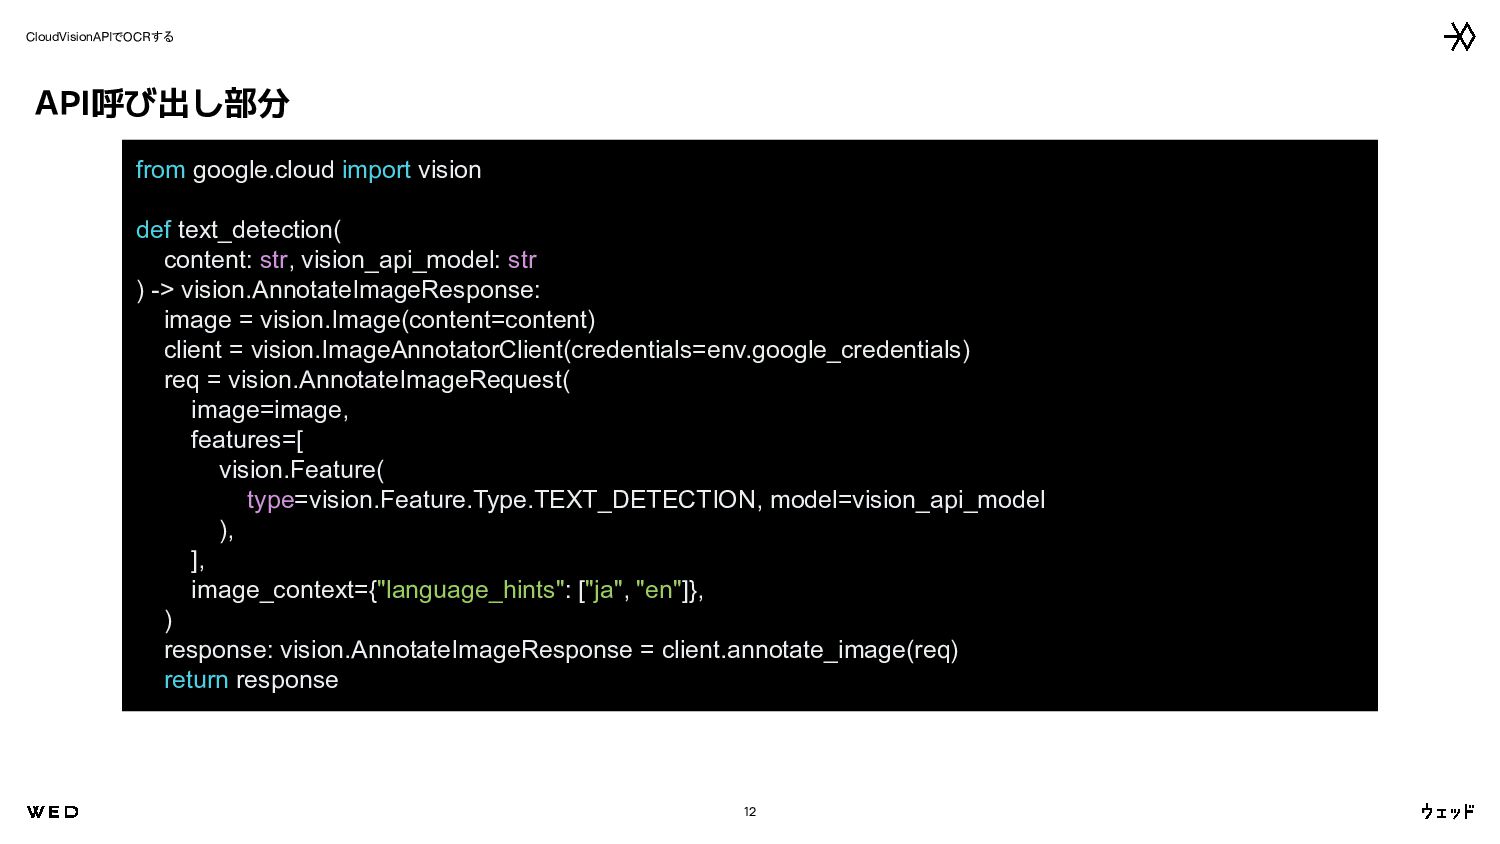
CloudVisionAPIでOCRする 12 API呼び出し部分 from google.cloud import vision def text_detection( content:
str, vision_api_model: str ) -> vision.AnnotateImageResponse: image = vision.Image(content=content) client = vision.ImageAnnotatorClient(credentials=env.google_credentials) req = vision.AnnotateImageRequest( image=image, features=[ vision.Feature( type=vision.Feature.Type.TEXT_DETECTION, model=vision_api_model ), ], image_context={"language_hints": ["ja", "en"]}, ) response: vision.AnnotateImageResponse = client.annotate_image(req) return response
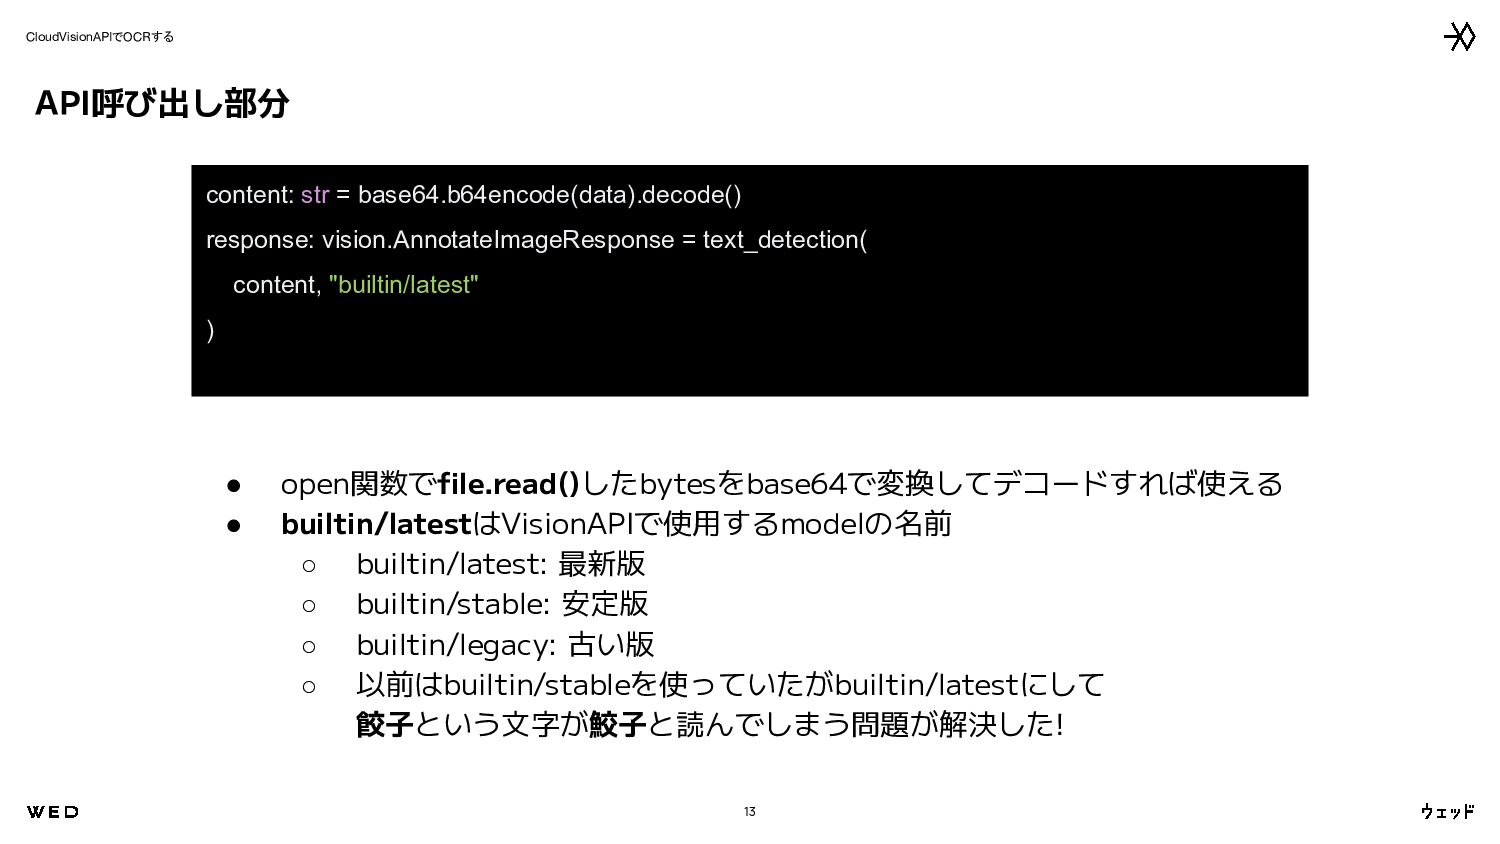
CloudVisionAPIでOCRする 13 API呼び出し部分 content: str = base64.b64encode(data).decode() response: vision.AnnotateImageResponse =
text_detection( content, "builtin/latest" ) • open関数でfile.read()したbytesをbase64で変換してデコードすれば使える • builtin/latestはVisionAPIで使用するmodelの名前 ◦ builtin/latest: 最新版 ◦ builtin/stable: 安定版 ◦ builtin/legacy: 古い版 ◦ 以前はbuiltin/stableを使っていたがbuiltin/latestにして 餃子という文字が鮫子と読んでしまう問題が解決した!
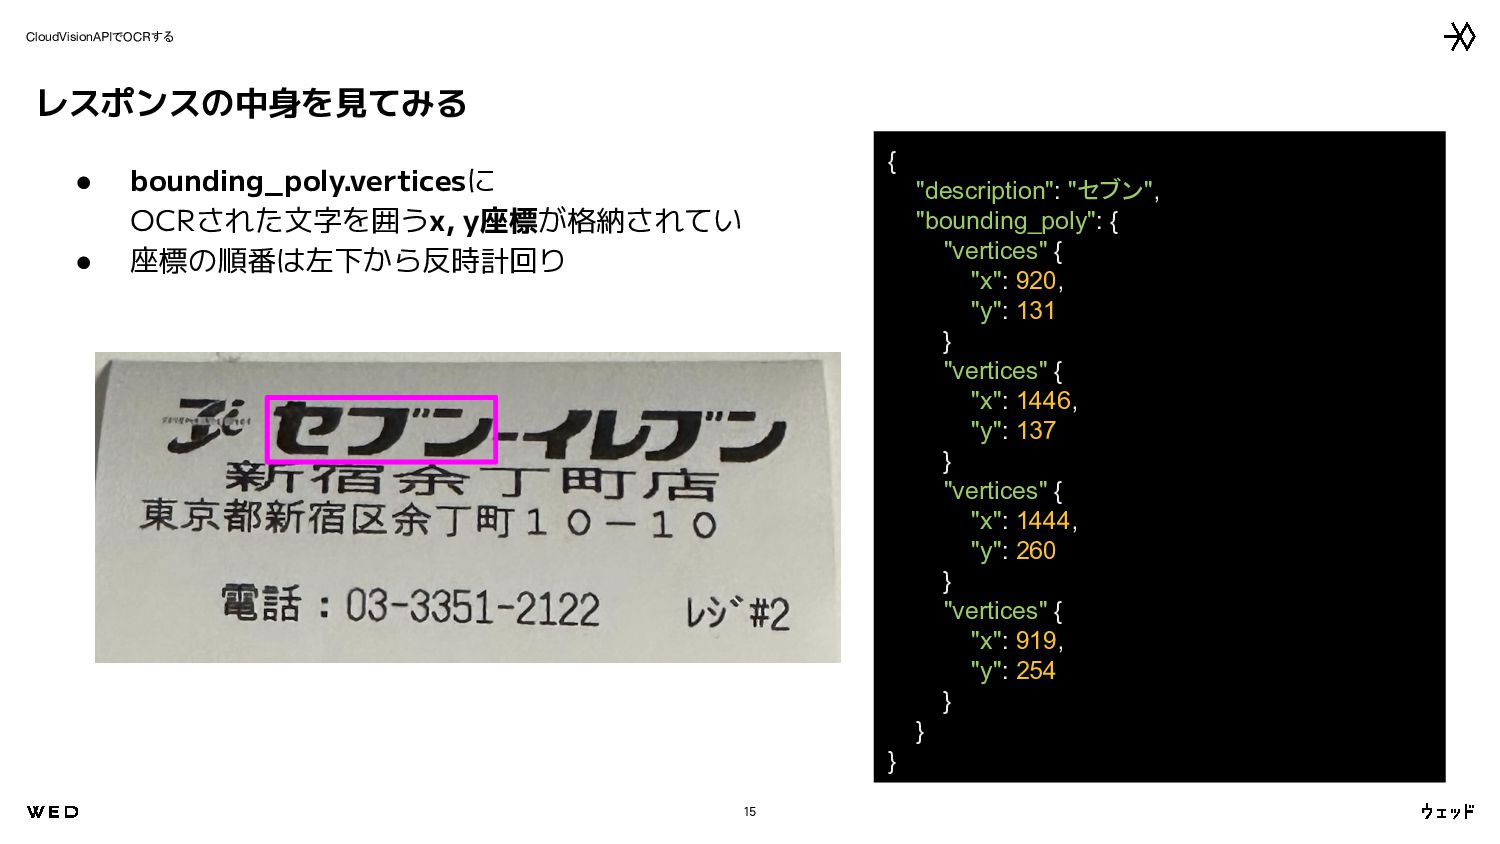
CloudVisionAPIでOCRする 14 レスポンスの中身を見てみる • response.text_annotations[0]には全てのOCR結果が入っている • index1以降はOCR結果が分割されたものが入っている • 基本的にはresponse.text_annotations[1:]を使用していく raw_text,
texts = response.text_annotations[0], response.text_annotations[1:] raw_lines = raw_text.description.split("\n")
CloudVisionAPIでOCRする 15 レスポンスの中身を見てみる { "description": "セブン", "bounding_poly": { "vertices" {
"x": 920, "y": 131 } "vertices" { "x": 1446, "y": 137 } "vertices" { "x": 1444, "y": 260 } "vertices" { "x": 919, "y": 254 } } } • bounding_poly.verticesに OCRされた文字を囲うx, y座標が格納されてい • 座標の順番は左下から反時計回り
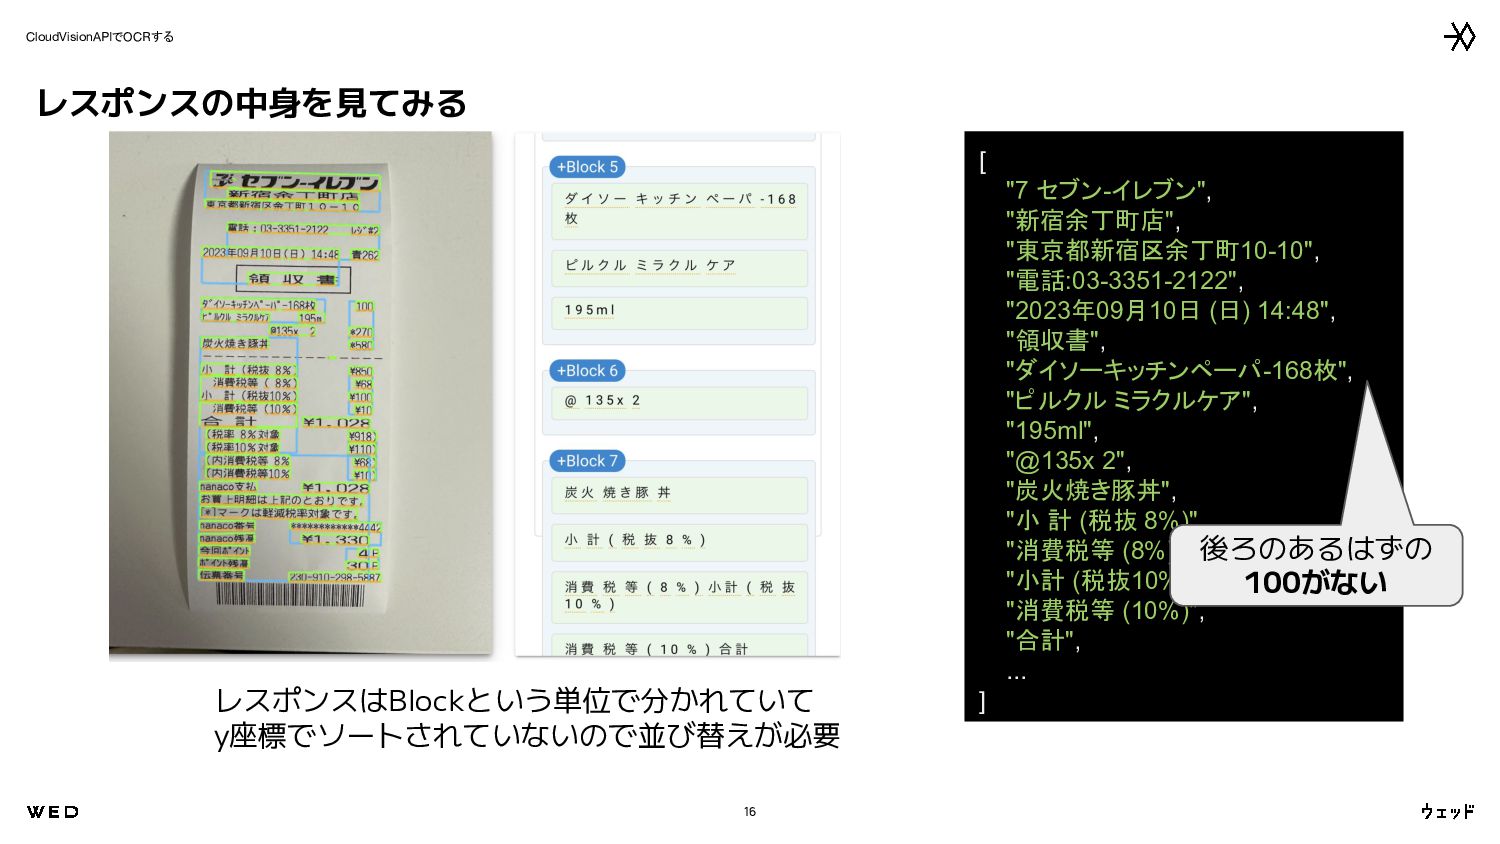
CloudVisionAPIでOCRする 16 レスポンスの中身を見てみる [ "7 セブン-イレブン", "新宿余丁町店", "東京都新宿区余丁町10-10", "電話:03-3351-2122", "2023年09月10日
(日) 14:48", "領収書", "ダイソーキッチンペーパ-168枚", "ピルクル ミラクルケア", "195ml", "@135x 2", "炭火焼き豚丼", "小 計 (税抜 8%)", "消費税等 (8%)", "小計 (税抜10%)", "消費税等 (10%)", "合計", ... ] レスポンスはBlockという単位で分かれていて y座標でソートされていないので並び替えが必要 後ろのあるはずの 100がない
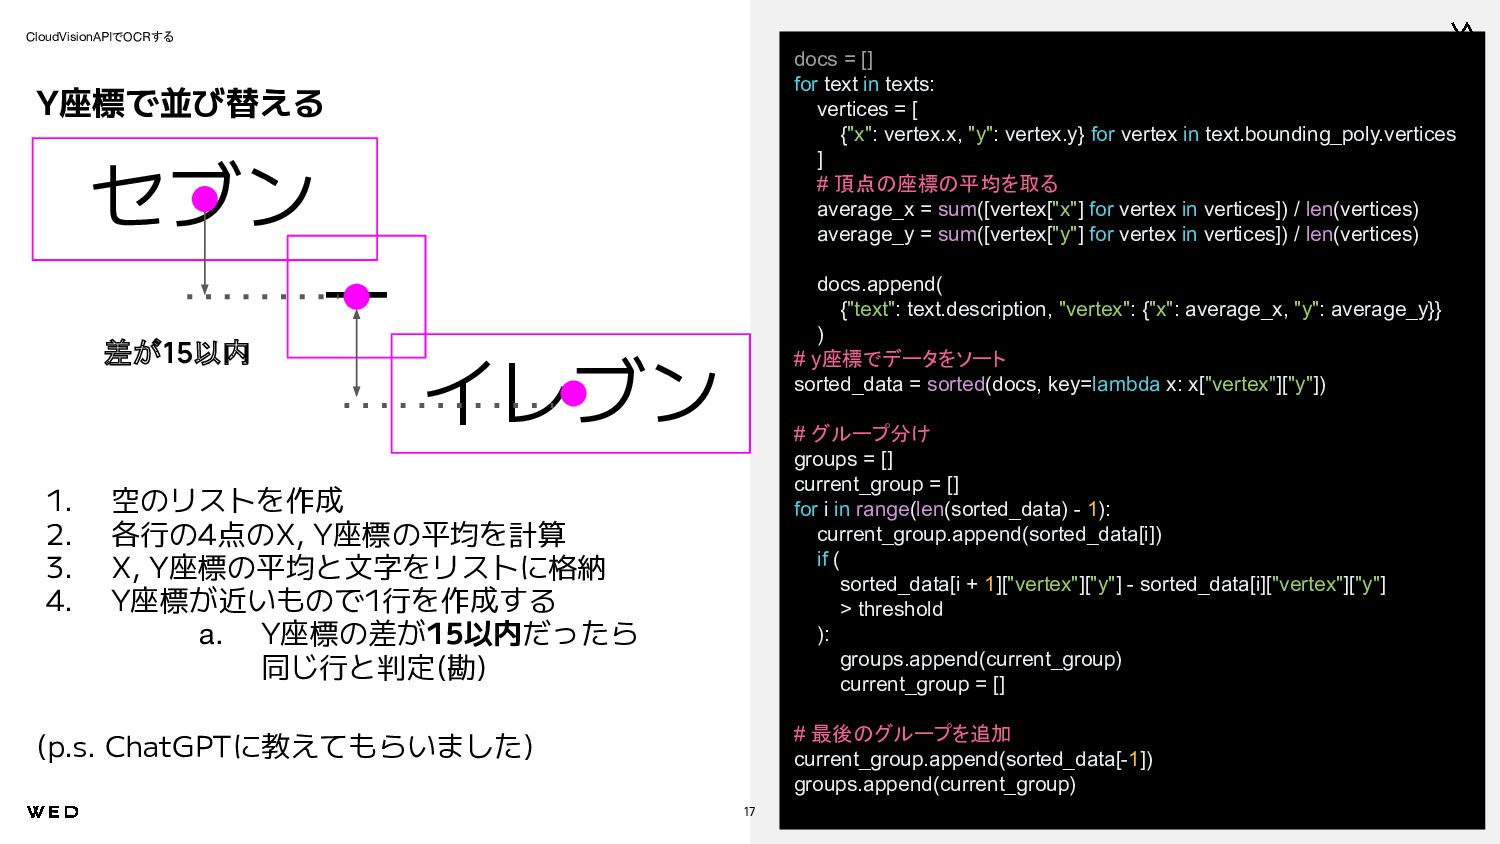
CloudVisionAPIでOCRする 1. 空のリストを作成 2. 各行の4点のX, Y座標の平均を計算 3. X, Y座標の平均と文字をリストに格納 4.
Y座標が近いもので1行を作成する a. Y座標の差が15以内だったら 同じ行と判定(勘) (p.s. ChatGPTに教えてもらいました) 17 Y座標で並び替える docs = [] for text in texts: vertices = [ {"x": vertex.x, "y": vertex.y} for vertex in text.bounding_poly.vertices ] # 頂点の座標の平均を取る average_x = sum([vertex["x"] for vertex in vertices]) / len(vertices) average_y = sum([vertex["y"] for vertex in vertices]) / len(vertices) docs.append( {"text": text.description, "vertex": {"x": average_x, "y": average_y}} ) # y座標でデータをソート sorted_data = sorted(docs, key=lambda x: x["vertex"]["y"]) # グループ分け groups = [] current_group = [] for i in range(len(sorted_data) - 1): current_group.append(sorted_data[i]) if ( sorted_data[i + 1]["vertex"]["y"] - sorted_data[i]["vertex"]["y"] > threshold ): groups.append(current_group) current_group = [] # 最後のグループを追加 current_group.append(sorted_data[-1]) groups.append(current_group) セブン ー イレブン 差が15以内
そして諸々作成したのが こちら(実演) 18
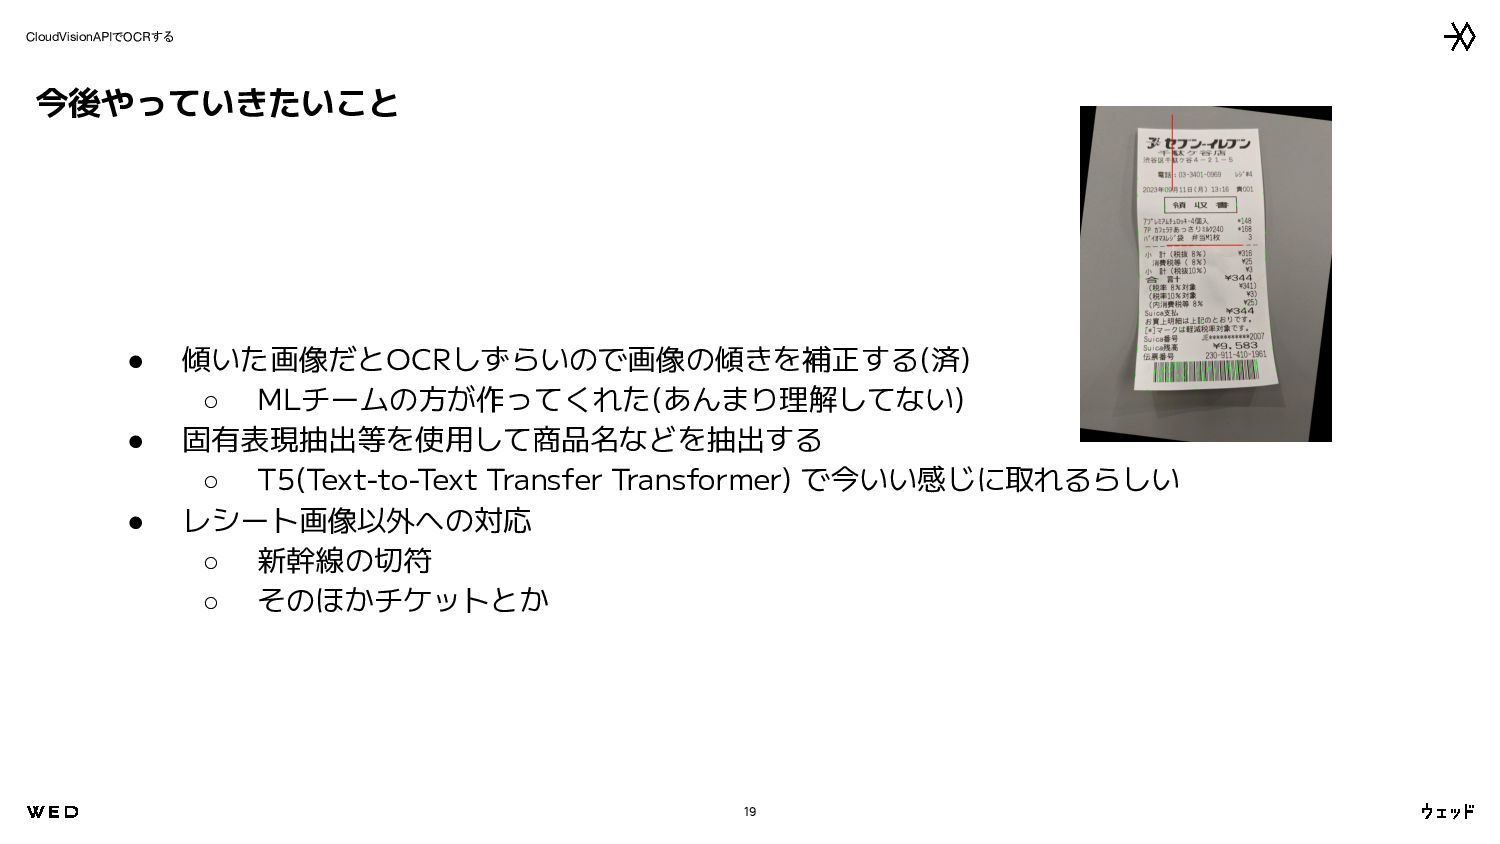
CloudVisionAPIでOCRする • 傾いた画像だとOCRしずらいので画像の傾きを補正する(済) ◦ MLチームの方が作ってくれた(あんまり理解してない) • 固有表現抽出等を使用して商品名などを抽出する ◦ T5(Text-to-Text Transfer
Transformer) で今いい感じに取れるらしい • レシート画像以外への対応 ◦ 新幹線の切符 ◦ そのほかチケットとか 19 今後やっていきたいこと
Thank You 20 今日使ったコード https://gist.github.com/thimi0412/d548cec8c132a0f299d1096cc4e908e0


 thimi0412
 rkaga
 reimaru
 s_shimotori
 satoshi256kbyte
 akkeylab
 kishikawakatsumi
 448jp
 nokomoro3
 kinopeee
 curekoshimizu
 lynnswap
 kenjiyoneyama
 bluesmoon
 ianozsvald
 techseoconnect
 bkeepers
 retrage
 reverentgeek
 addyosmani
 chriscoyier
 matthewcrist
 sergeychernyshev
 dugsong
 apolaine