Upgrade to Pro — share decks privately, control downloads, hide ads and more …

How to stop doing web scraping all wrong

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →

How to stop doing web scraping all wrong

Lightning talk at Step-UP RSLondon conference about avoiding frustration, brittle code and "Not Invented Here" syndrome by using Scrapy to write web-scrapers.

Avatar for Giles Greenway

Giles Greenway

June 15, 2026

Other Decks in Technology

Transcript

  1. How to stop doing web scraping all wrong Giles Greenway,

    RSE Team-Leader (TLDR, Use Scrapy: https://www.scrapy.org/)
  2. Scraping is pervasive in research Scraping is pervasive in research...

    Archive / Restore Legacy Sites Aggregate Published Government / Research Data Research Online Polarization / Misinformation ...and in industry.
  3. Much of the available advice for Python is poor: ”Scrapy

    has a steep learning curve. Try Requests or Beautiful Soup!” “Let’s leave all the complexity of 1000s of branching requests, duplicate URLs, rate-limiting, irregularity, etc… to novice coders!” [Letters to Nature: https://www.nature.com/articles/d41586-020-02558-0]
  4. Looking at you, Real Python https://realpython.com/python-web-scraping-practical-introduction/ (Don’t parse HTML with

    regexes: https://www.youtube.com /watch?v=AqZNebWoqnc) (Some crawlers don’t parse any HTML.)
  5. Requests are not parsed by the same function-call that yielded

    them. Use “AutoThrottle”: https://docs.scrapy.org/en/latest/topics/autothrottle.html Read the tutorial: https://docs.scrapy.org/en/latest/intro/tutorial.html ROBOTSTXT_OBEY = False USER_AGENT = ”PlausibleMozillaGeckoUserAgentString” Scrapy is Good, Actually.
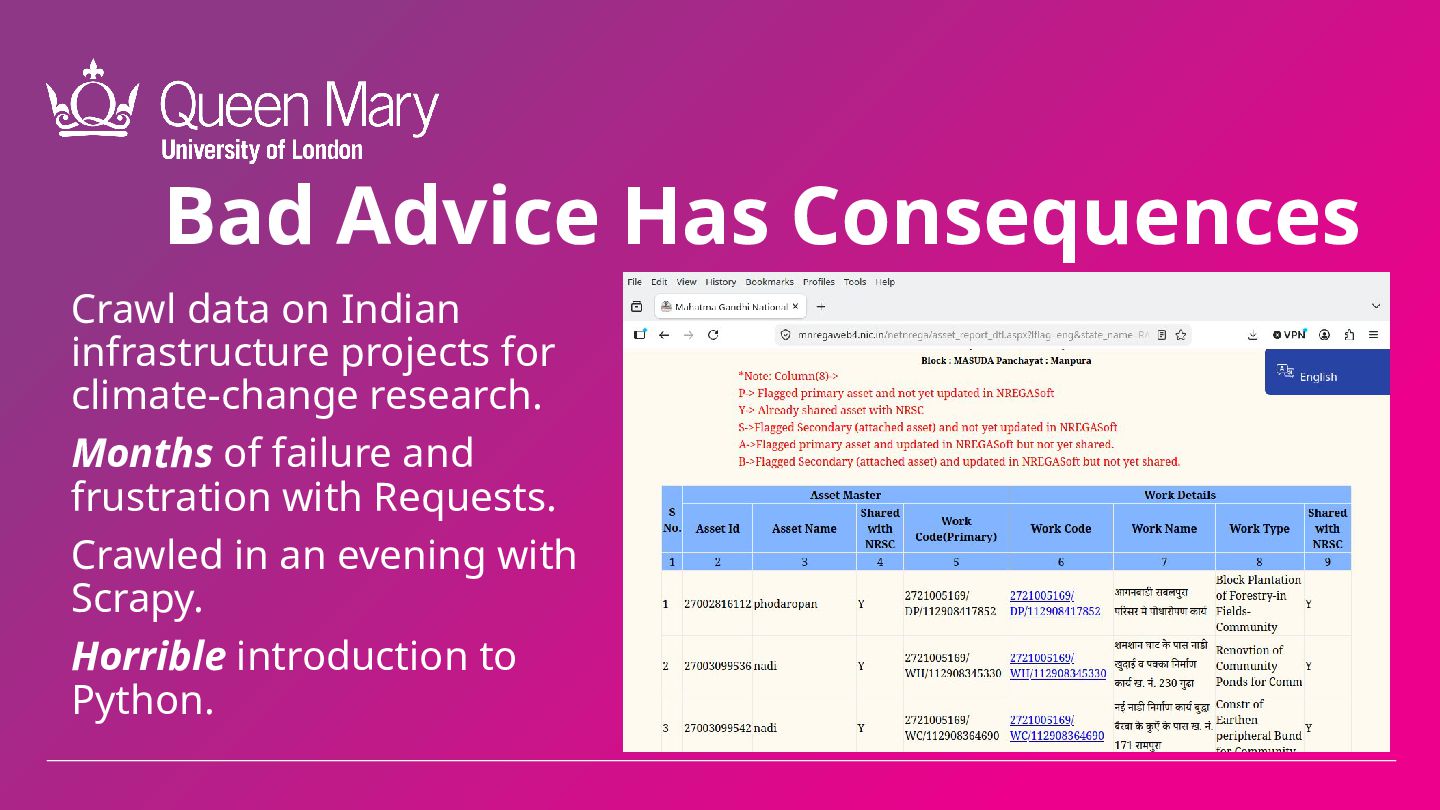
  6. Bad Advice Has Consequences Crawl data on Indian infrastructure projects

    for climate-change research. Months of failure and frustration with Requests. Crawled in an evening with Scrapy. Horrible introduction to Python.
  7. More Scrapy Features: Image / file pipelines: https://docs.scrapy.org/en/latest/topics/media-pipeline.html “Painless” headless-browser

    integration: (Don’t. Use. Selenium.) https://github.com/scrapy-plugins/scrapy-playwright Testing frameworks: https://spidermon.readthedocs.io/en/latest/ Deployment / Monitoring: https://github.com/my8100/scrapydweb