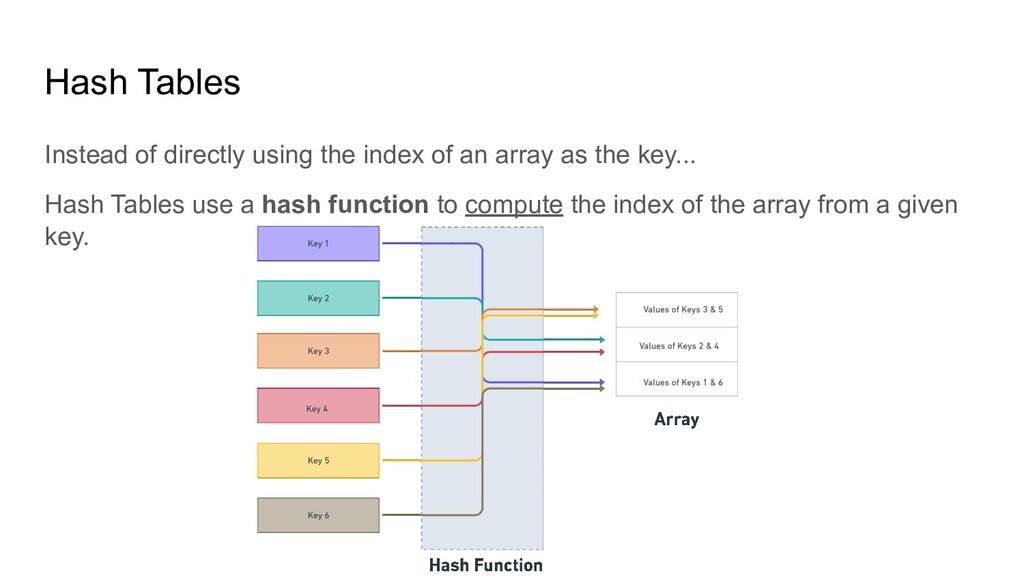
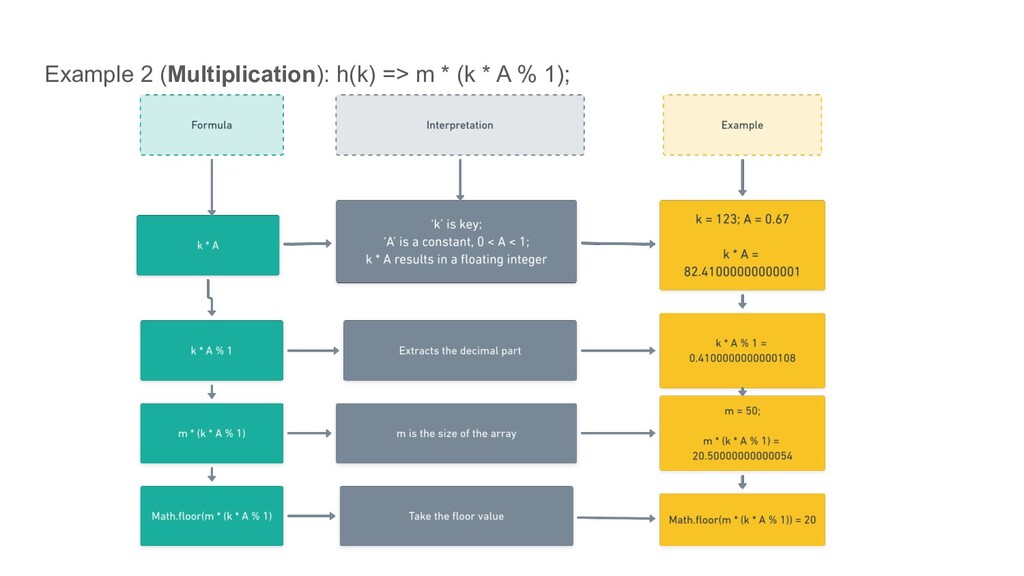
to store data. Key: A unique identifier that points to its associated value Value: Any data-item, including another key-value store Key-value stores (also called ‘Dictionaries) are used to perform the following operations: • Insert a new key-value pair • Delete an existing key-value pair • Update the value of an existing pair • Search the value associated with a particular key JS objects are built-in key-value stores
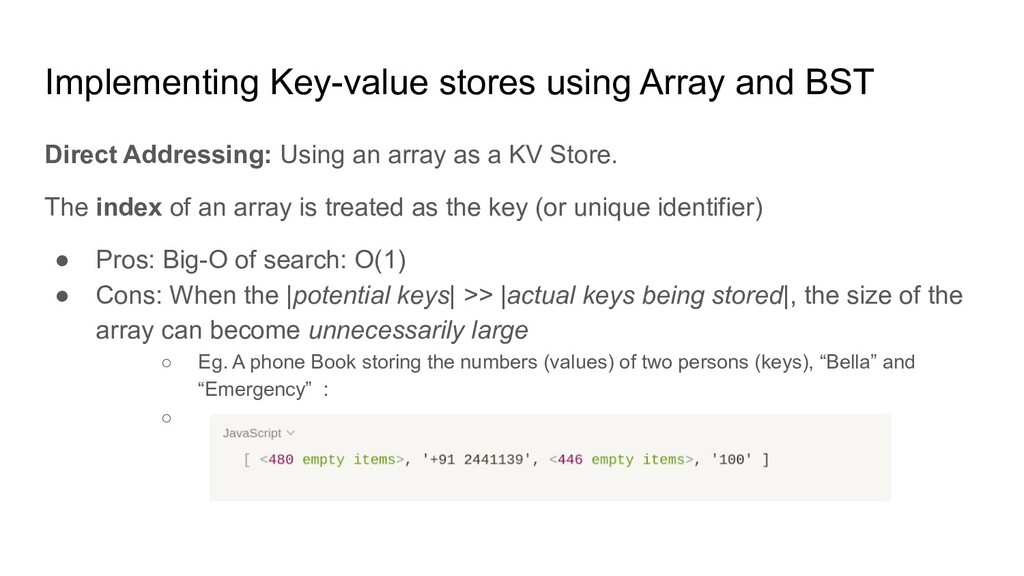
an array as a KV Store. The index of an array is treated as the key (or unique identifier) • Pros: Big-O of search: O(1) • Cons: When the |potential keys| >> |actual keys being stored|, the size of the array can become unnecessarily large ◦ Eg. A phone Book storing the numbers (values) of two persons (keys), “Bella” and “Emergency” : ◦
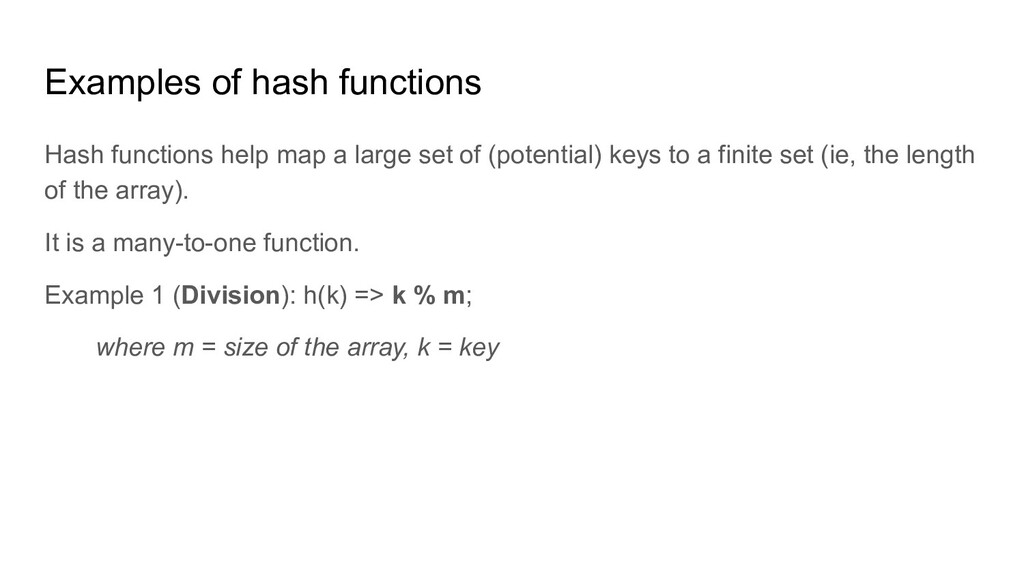
set of (potential) keys to a finite set (ie, the length of the array). It is a many-to-one function. Example 1 (Division): h(k) => k % m; where m = size of the array, k = key
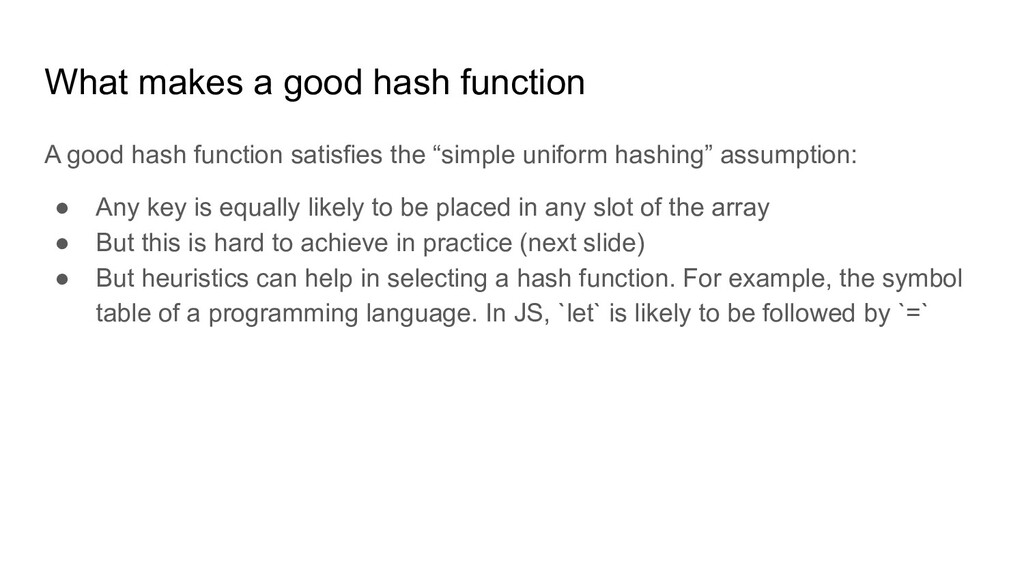
satisfies the “simple uniform hashing” assumption: • Any key is equally likely to be placed in any slot of the array • But this is hard to achieve in practice (next slide) • But heuristics can help in selecting a hash function. For example, the symbol table of a programming language. In JS, `let` is likely to be followed by `=`
or more keys will always map to a single slot in the store. Ideally this should be avoided, ie, hash function to be designed in such a way that no two keys have to share the same slot But this is hard to implement: We cannot predict the probability of how keys are going to be distributed
the associated value in each slot of the hash table, we can have a linked list. Each slot acts like a ‘hash bucket’. Whenever there is a new value to be inserted, it will be added as a new node to the relevant linked list. If there is an existing value in that linked list, the new value will be inserted as another node to the linked list Pros: Ensures that any number of keys can be stored, irrespective of the actual size of the array Cons: Worst-case time-complexity: O(n) (like a linked list)
If there is an existing value already present in a slot, continue probing till an empty slot is found. Probing can be done linearly, quadrically etc. Important: Delete operation should leave behind a special value. Pros: Better space complexity: the hash table itself stores all the values Cons: The size of the actual key-value pairs cannot exceed the size of the hash table


 addyosmani
 kevinliebholz
 3n
 watany
 charlesmeaden
 akademiya2063
 inesmontani
 andyhume
 tammyeverts
 sarafernandez
 kimpetersen