Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Web Scraping for Fun and Profit using Scrapy
Search
Sigit Dewanto
November 26, 2016
Technology
320
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Web Scraping for Fun and Profit using Scrapy
Sigit Dewanto
November 26, 2016
Other Decks in Technology
See All in Technology
子育てエンジニアの可処分時間が減っても成長を諦めない戦い方
sudoakiy
6
4.6k
[JAWS-UG彩の国埼玉#12]そろそろ準備する?re:Invent2026をやさしく解説 / reinvent2026-sainokuni
sh_fk2
1
340
アウトプット初心者、半年間のふりかえり
4o1sobblue
0
430
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
130
M5Stackで作る BLEマウス GPSログの世界
tomokusaba
0
420
Gemini Intelligence 入門 ― AppFunctions と Gemini Nano
takuroabe
0
250
無理せず続ける、子育てエンジニアの学び
codmoninc
PRO
0
860
分析AIエージェントを育てる、動く環境を育てる
codatum
1
1.1k
AI × アーキテクト 第1・2章|生成AIの課題とアーキテクトの素養
daidaidai
0
170
自作バイナリを動かす「入口」8選
puhitaku
2
1.3k
コンテナ運用におけるネットワーク・コンテナコストの削減方法/How to Reduce Network and Container Costs in Container Operations
masakiokuda
1
150
『SAR衛星データ解析入門』の ご紹介とその応用
syuchimu
0
120
Featured
See All Featured
The agentic SEO stack - context over prompts
schlessera
0
970
Intergalactic Javascript Robots from Outer Space
tanoku
273
28k
Are puppies a ranking factor?
jonoalderson
2
4.1k
Google's AI Overviews - The New Search
badams
0
1.6k
New Earth Scene 8
popppiees
4
2.7k
AI Search: Where Are We & What Can We Do About It?
aleyda
0
8.1k
No one is an island. Learnings from fostering a developers community.
thoeni
21
3.9k
Ecommerce SEO: The Keys for Success Now & Beyond - #SERPConf2024
aleyda
1
2.2k
コードの90%をAIが書く世界で何が待っているのか / What awaits us in a world where 90% of the code is written by AI
rkaga
63
46k
The Art of Programming - Codeland 2020
erikaheidi
57
14k
Cheating the UX When There Is Nothing More to Optimize - PixelPioneers
stephaniewalter
287
14k
Designing for Timeless Needs
cassininazir
1
530
Transcript
Web Scraping for Fun and Profit using Scrapy Sigit Dewanto
@seagatesoft
Tentang Saya • Software engineer di Scrapinghub (2014 - ?)
◦ Scrapinghub adalah Scrapy official maintainer • Sebelumnya Java dev di Wego.com, tim FPI ◦ Wego adalah travel meta-search engine
Web Scraping? Web Crawling?
Web Crawling • Bagaimana mendapatkan halaman web yang kita inginkan?
• Yang kita butuhkan: HTTP Client ◦ Requests (Kenneth Reitz) ◦ Twisted web client
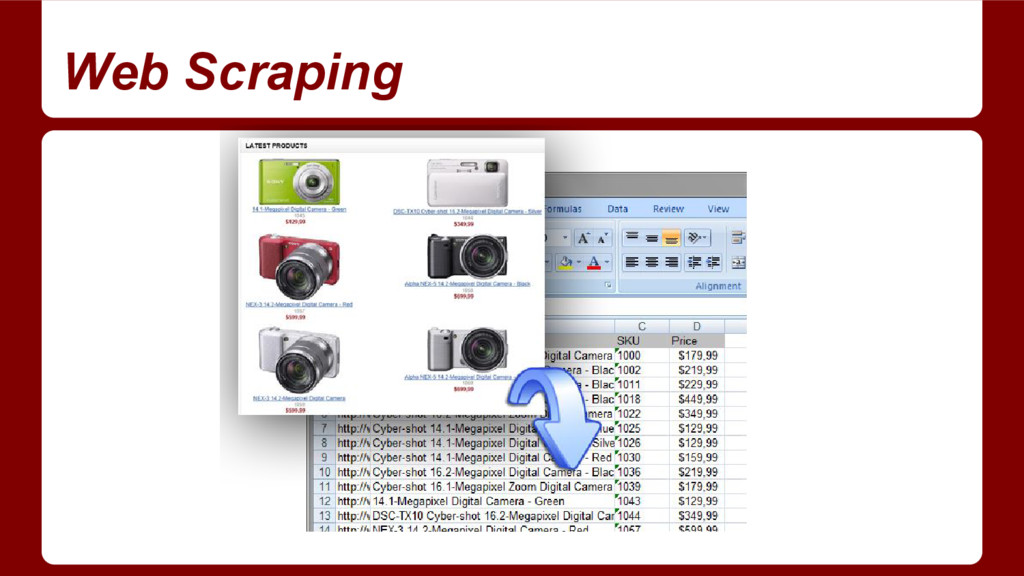
Web Scraping
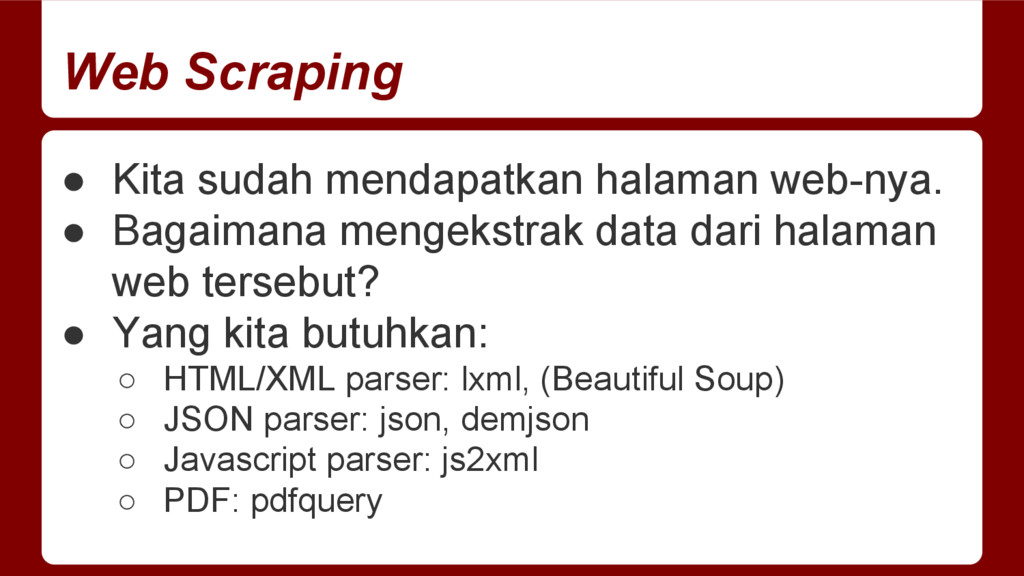
Web Scraping • Kita sudah mendapatkan halaman web-nya. • Bagaimana
mengekstrak data dari halaman web tersebut? • Yang kita butuhkan: ◦ HTML/XML parser: lxml, (Beautiful Soup) ◦ JSON parser: json, demjson ◦ Javascript parser: js2xml ◦ PDF: pdfquery
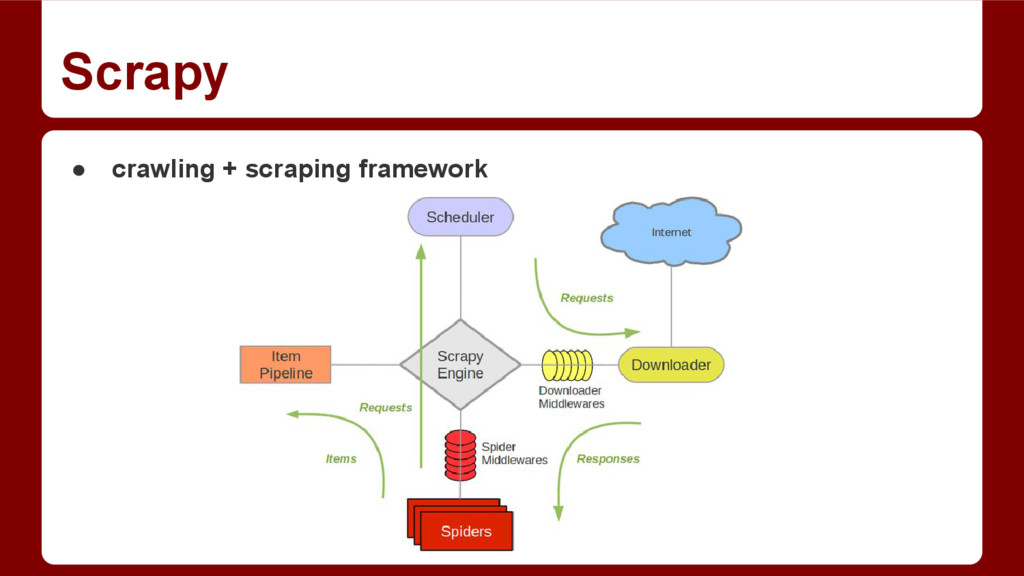
Scrapy • crawling + scraping framework
(Pakar Telematika)
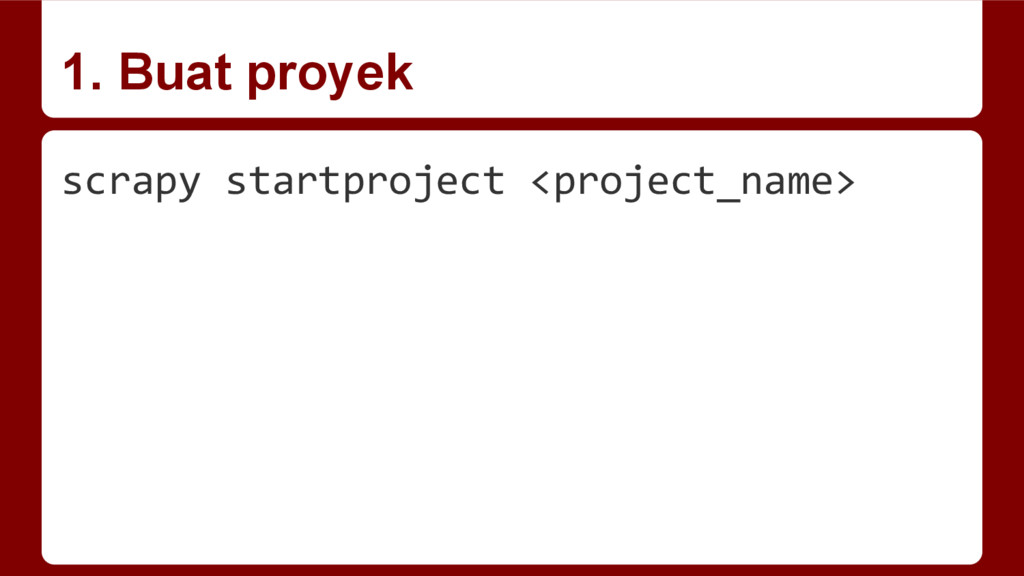
1. Buat proyek scrapy startproject <project_name>
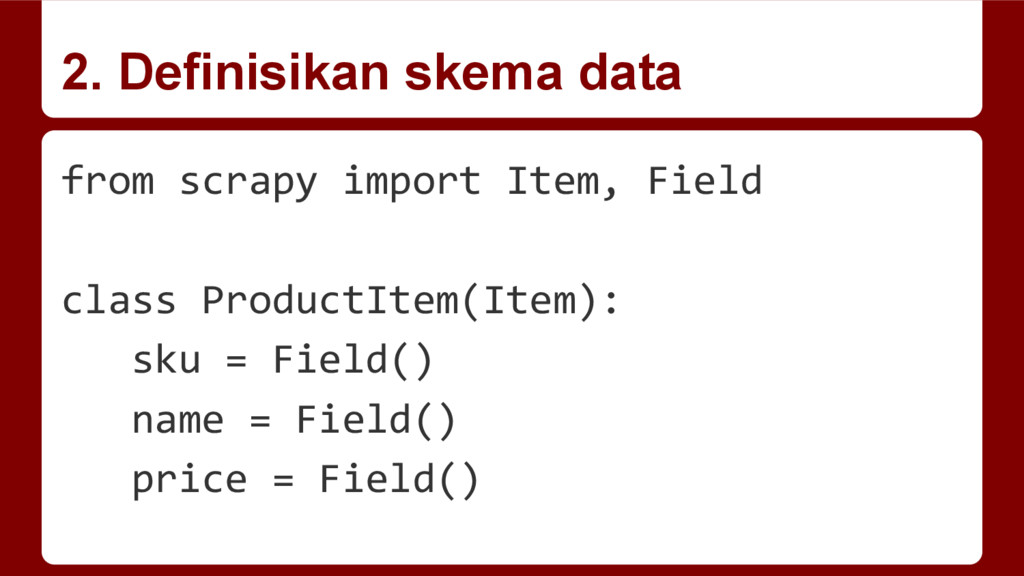
2. Definisikan skema data from scrapy import Item, Field class
ProductItem(Item): sku = Field() name = Field() price = Field()
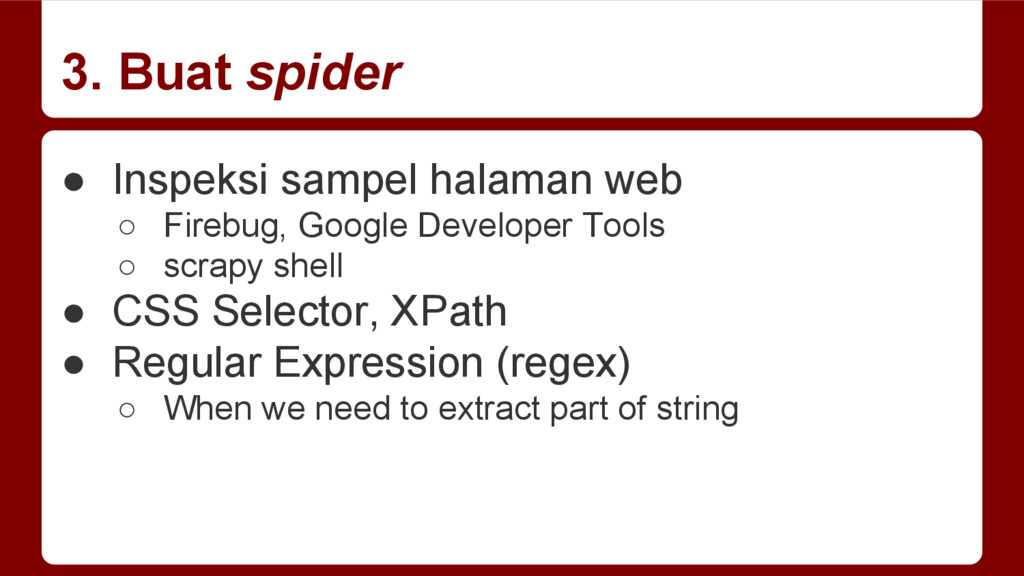
3. Buat spider • Inspeksi sampel halaman web ◦ Firebug,
Google Developer Tools ◦ scrapy shell • CSS Selector, XPath • Regular Expression (regex) ◦ When we need to extract part of string
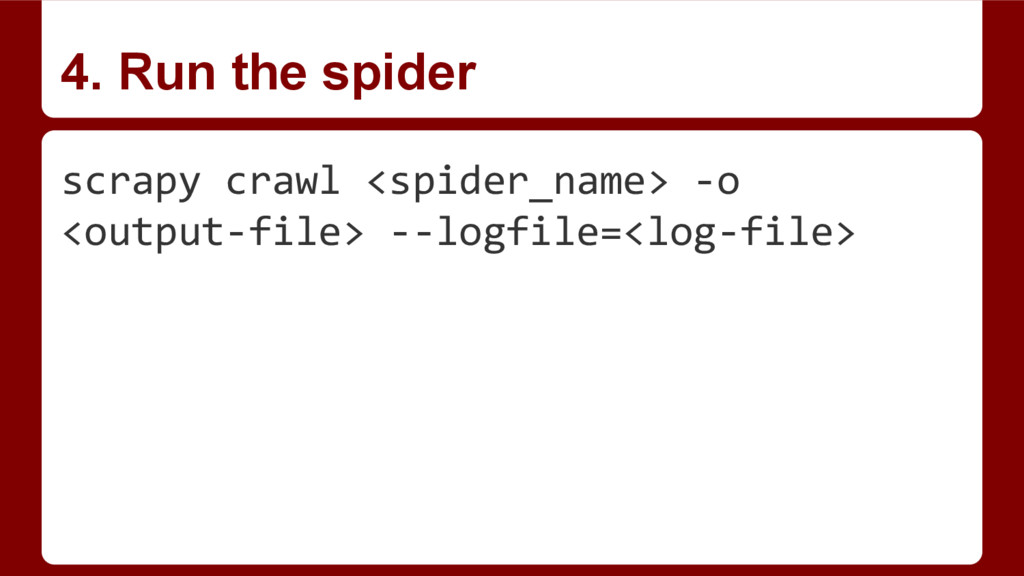
4. Run the spider scrapy crawl <spider_name> -o <output-file> --logfile=<log-file>
Scrapinghub Cloud • Dash: web dashboard • shub: command line
tool untuk deployment • scrapinghub: wrapper untuk Scrapinghub API
Terima Kasih! • Source code ◦ https://github.com/seagatesoft/scrapydemo • Tertarik menggunakan
Scrapinghub cloud? ◦ https://app.scrapinghub.com/account/signup/
Etika/Kesopanan • Crawl rate ◦ Jeda antara HTTP request ◦
Batasi concurrent requests • Patuhi robots.txt • Identifikasi crawler Anda dengan User-Agent header
Aspek Legal “It’s not scraping itself which is good or
bad, or legal or illegal, but the circumstances in which you’re doing it.” Francis Irving - ScraperWiki (https://blog.scraperwiki.com/2012/04/is-scraping-legal/ )
Common issues • HTML page manipulated by Javascript • Antibot
measurements ◦ Bot detection + ban ◦ Spider trap ◦ CAPTCHA • Huge number of links/pages • Irregular structure (no pattern)


 sudoakiy
 sh_fk2
 4o1sobblue
 pfn
 tomokusaba
 takuroabe
 codmoninc
 codatum
 daidaidai
 puhitaku
 masakiokuda
 syuchimu
 schlessera
 tanoku
 jonoalderson
 badams
 popppiees
 aleyda
 thoeni
 rkaga
 erikaheidi
 stephaniewalter
 cassininazir