Share
Embed
テキストからの実世界理解に向けて
IBIS2023 企画セッション1
Vision and Languageの最前線
テキストからの実世界理解に向けて

Shuhei Kurita
October 30, 2023
Transcript
47 slides
-
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQAとSceneGraph, DenceCaptioning 2. 参照表現理解 (Referring
Expression Comprehension) 3. 対照学習(Contrastive Learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画に対する参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 2 -
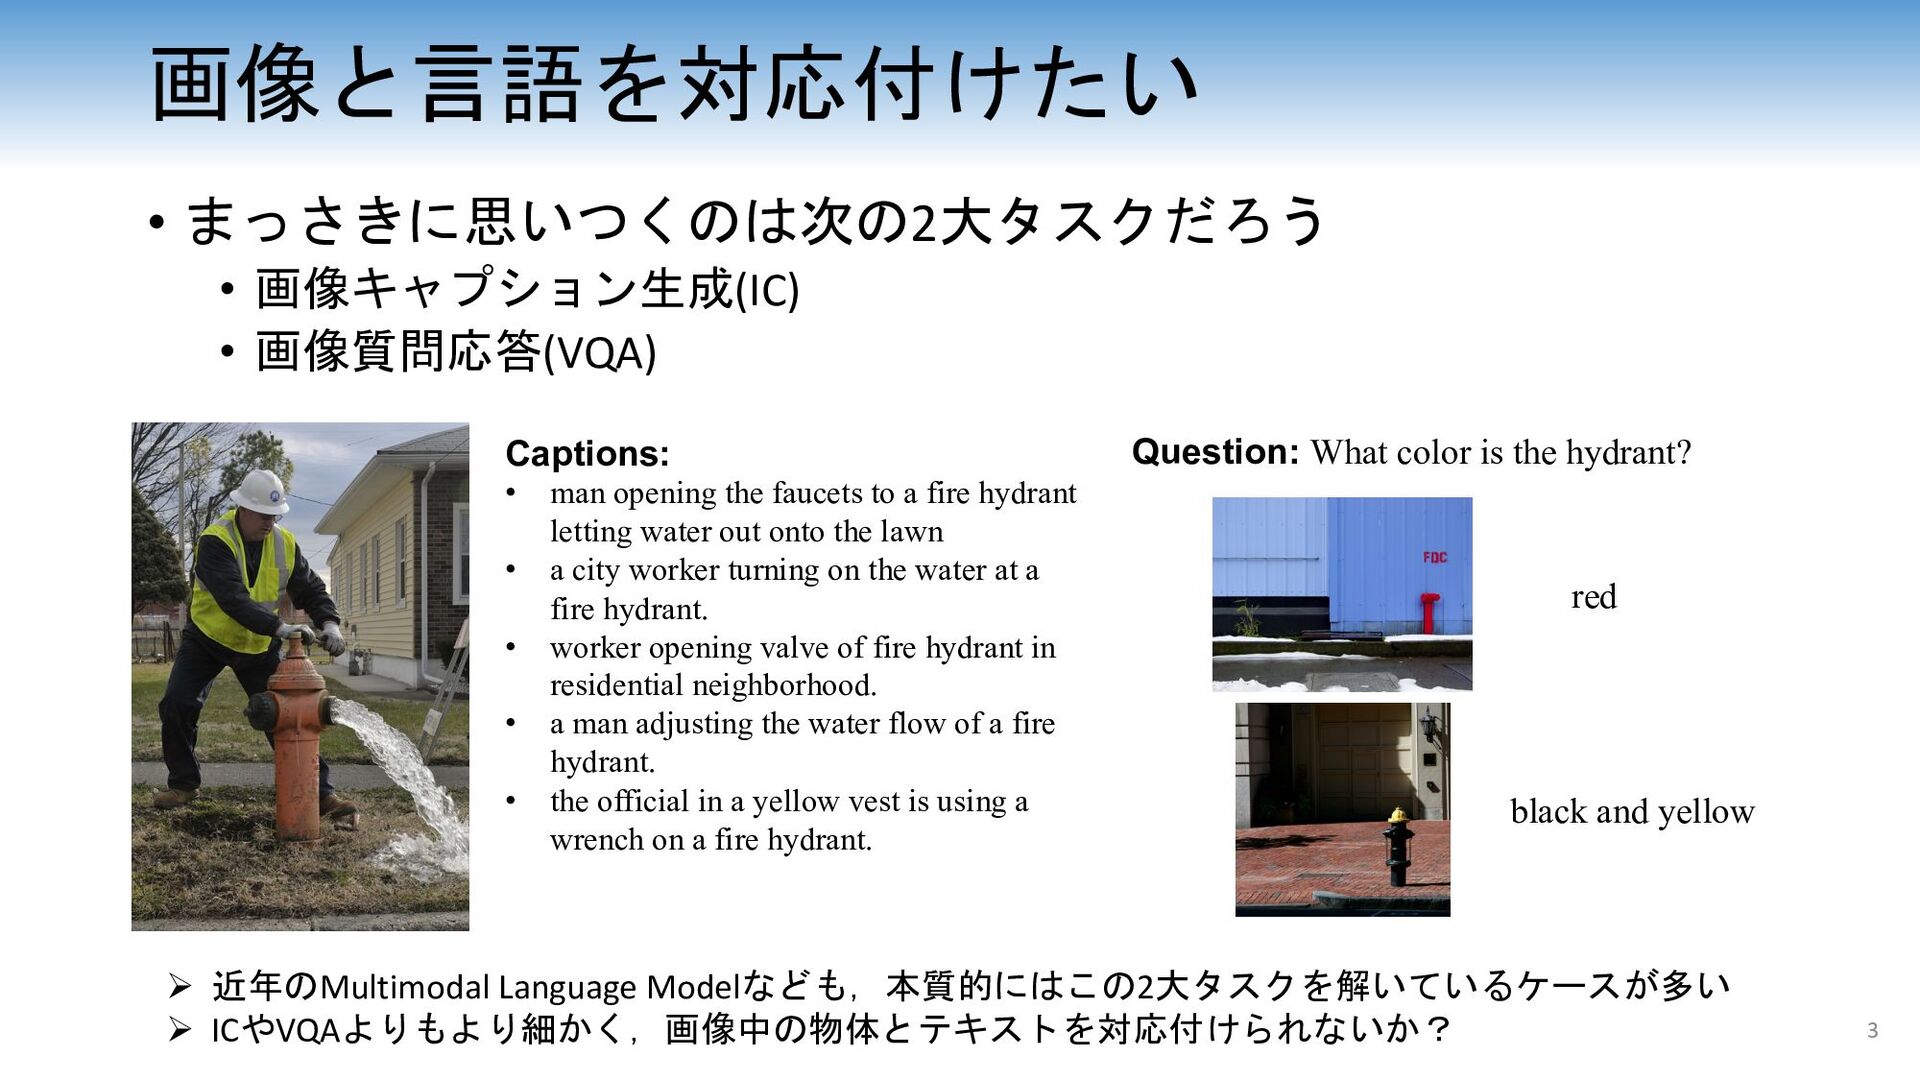
画像と言語を対応付けたい • まっさきに思いつくのは次の2大タスクだろう • 画像キャプション生成(IC) • 画像質問応答(VQA) Captions: • man
opening the faucets to a fire hydrant letting water out onto the lawn • a city worker turning on the water at a fire hydrant. • worker opening valve of fire hydrant in residential neighborhood. • a man adjusting the water flow of a fire hydrant. • the official in a yellow vest is using a wrench on a fire hydrant. Question: What color is the hydrant? red black and yellow 3 Ø 近年のMultimodal Language Modelなども,本質的にはこの2大タスクを解いているケースが多い Ø ICやVQAよりもより細かく,画像中の物体とテキストを対応付けられないか? -
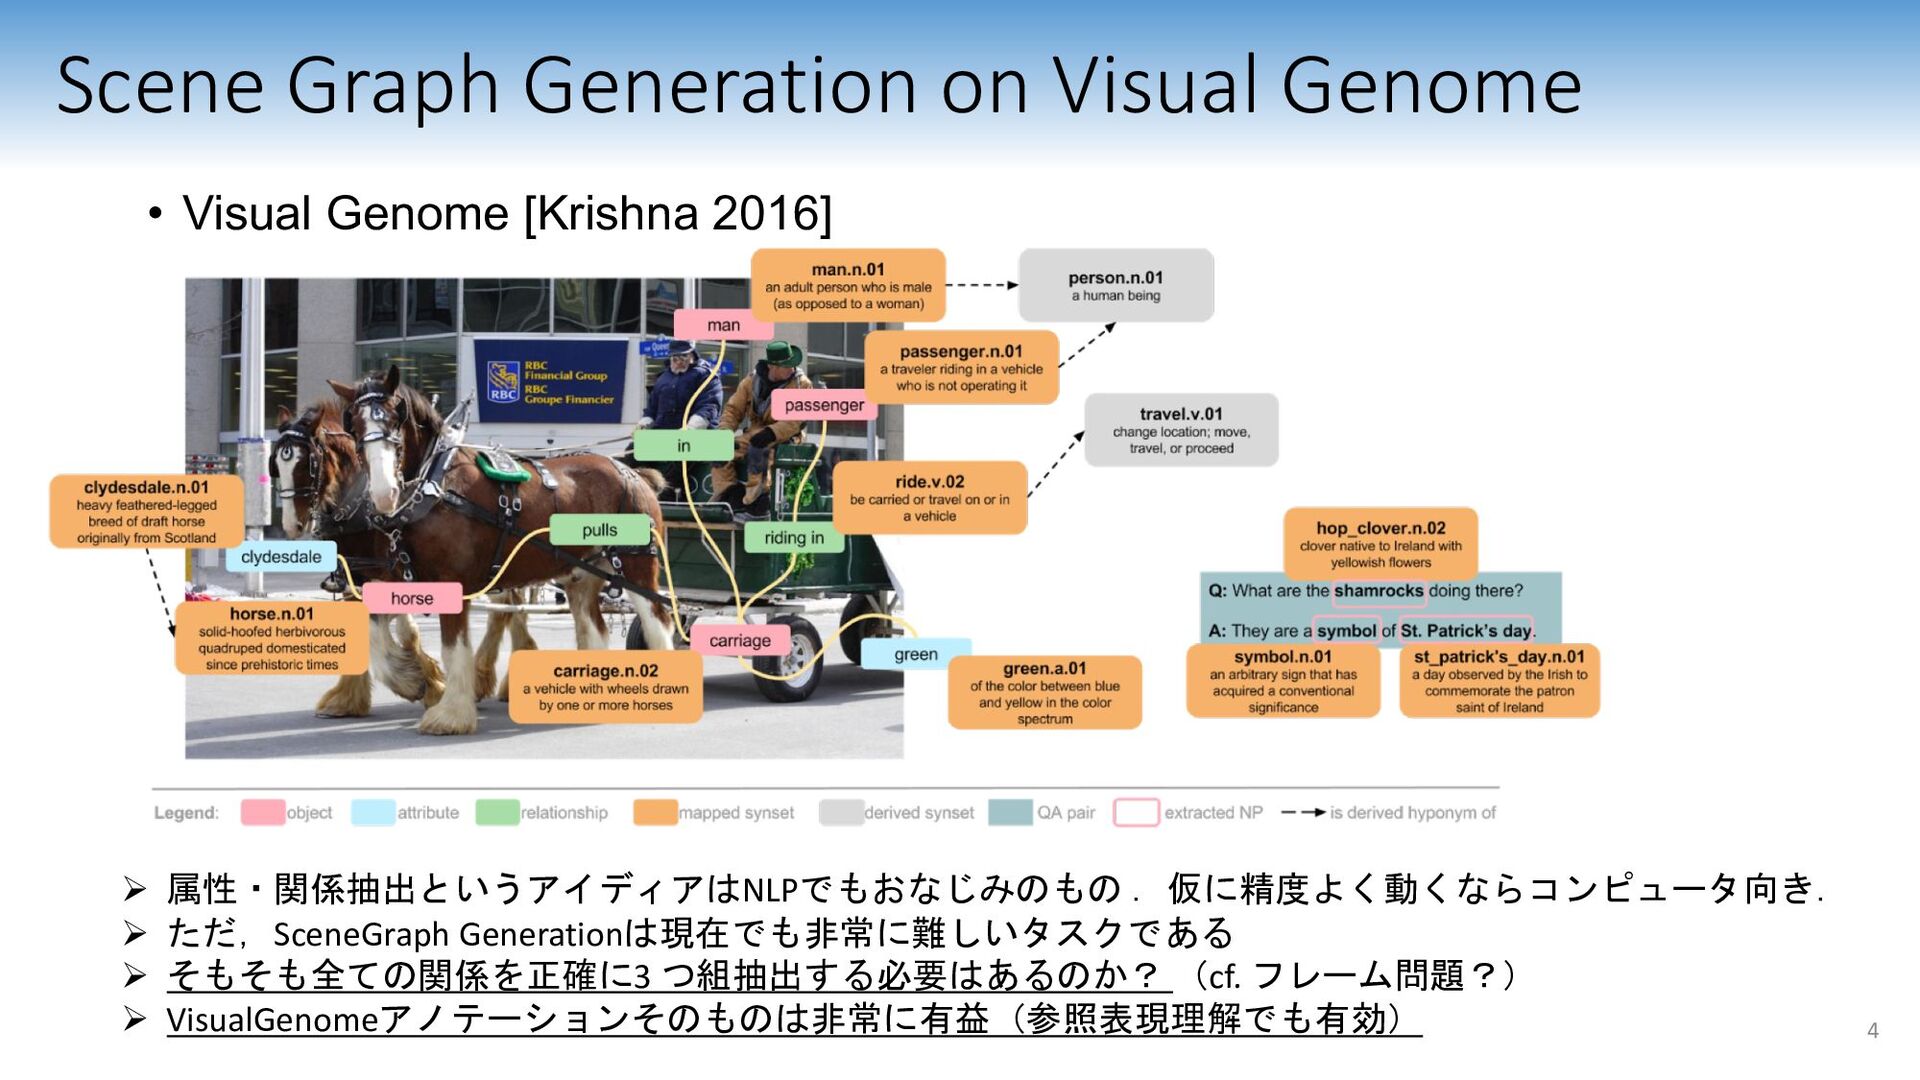
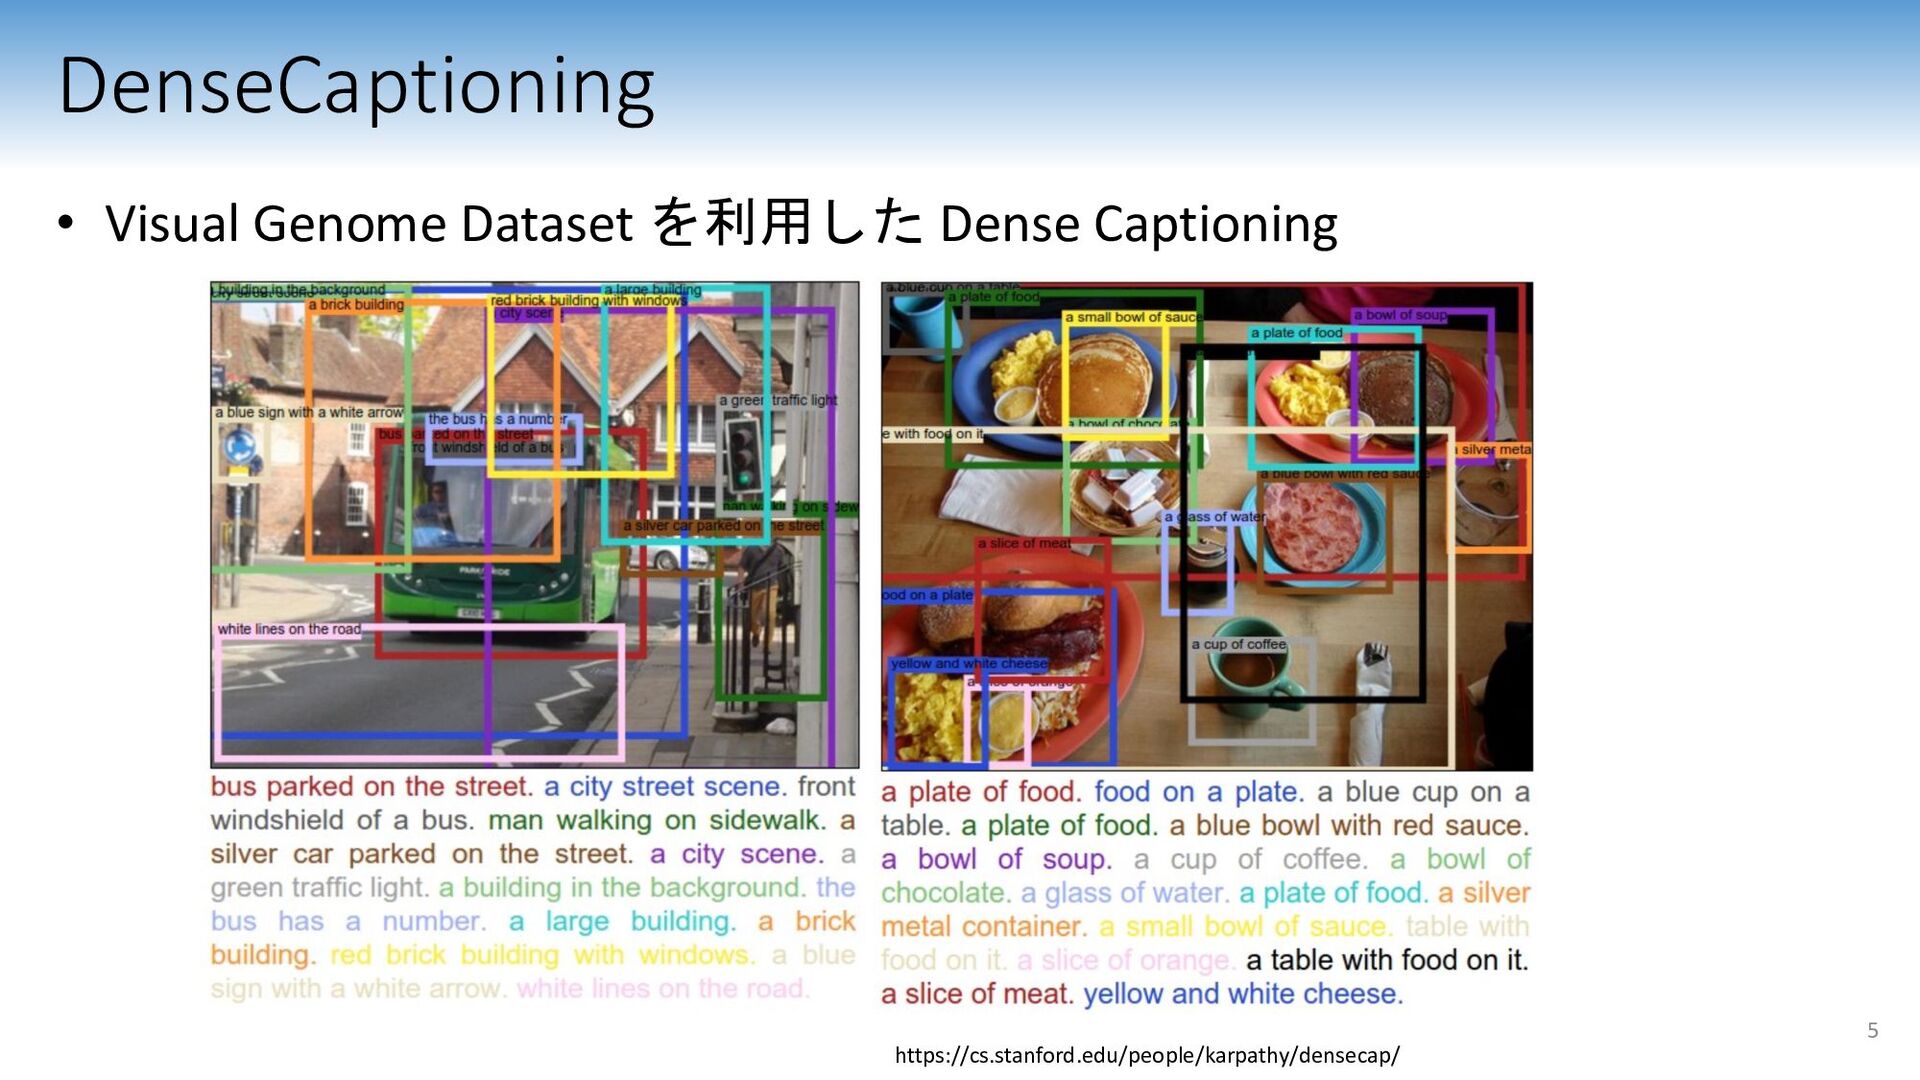
Scene Graph Generation on Visual Genome • Visual Genome [Krishna
2016] Ø 属性・関係抽出というアイディアはNLPでもおなじみのもの .仮に精度よく動くならコンピュータ向き. Ø ただ,SceneGraph Generationは現在でも非常に難しいタスクである Ø そもそも全ての関係を正確に3 つ組抽出する必要はあるのか? (cf. フレーム問題?) Ø VisualGenomeアノテーションそのものは非常に有益(参照表現理解でも有効) 4 -
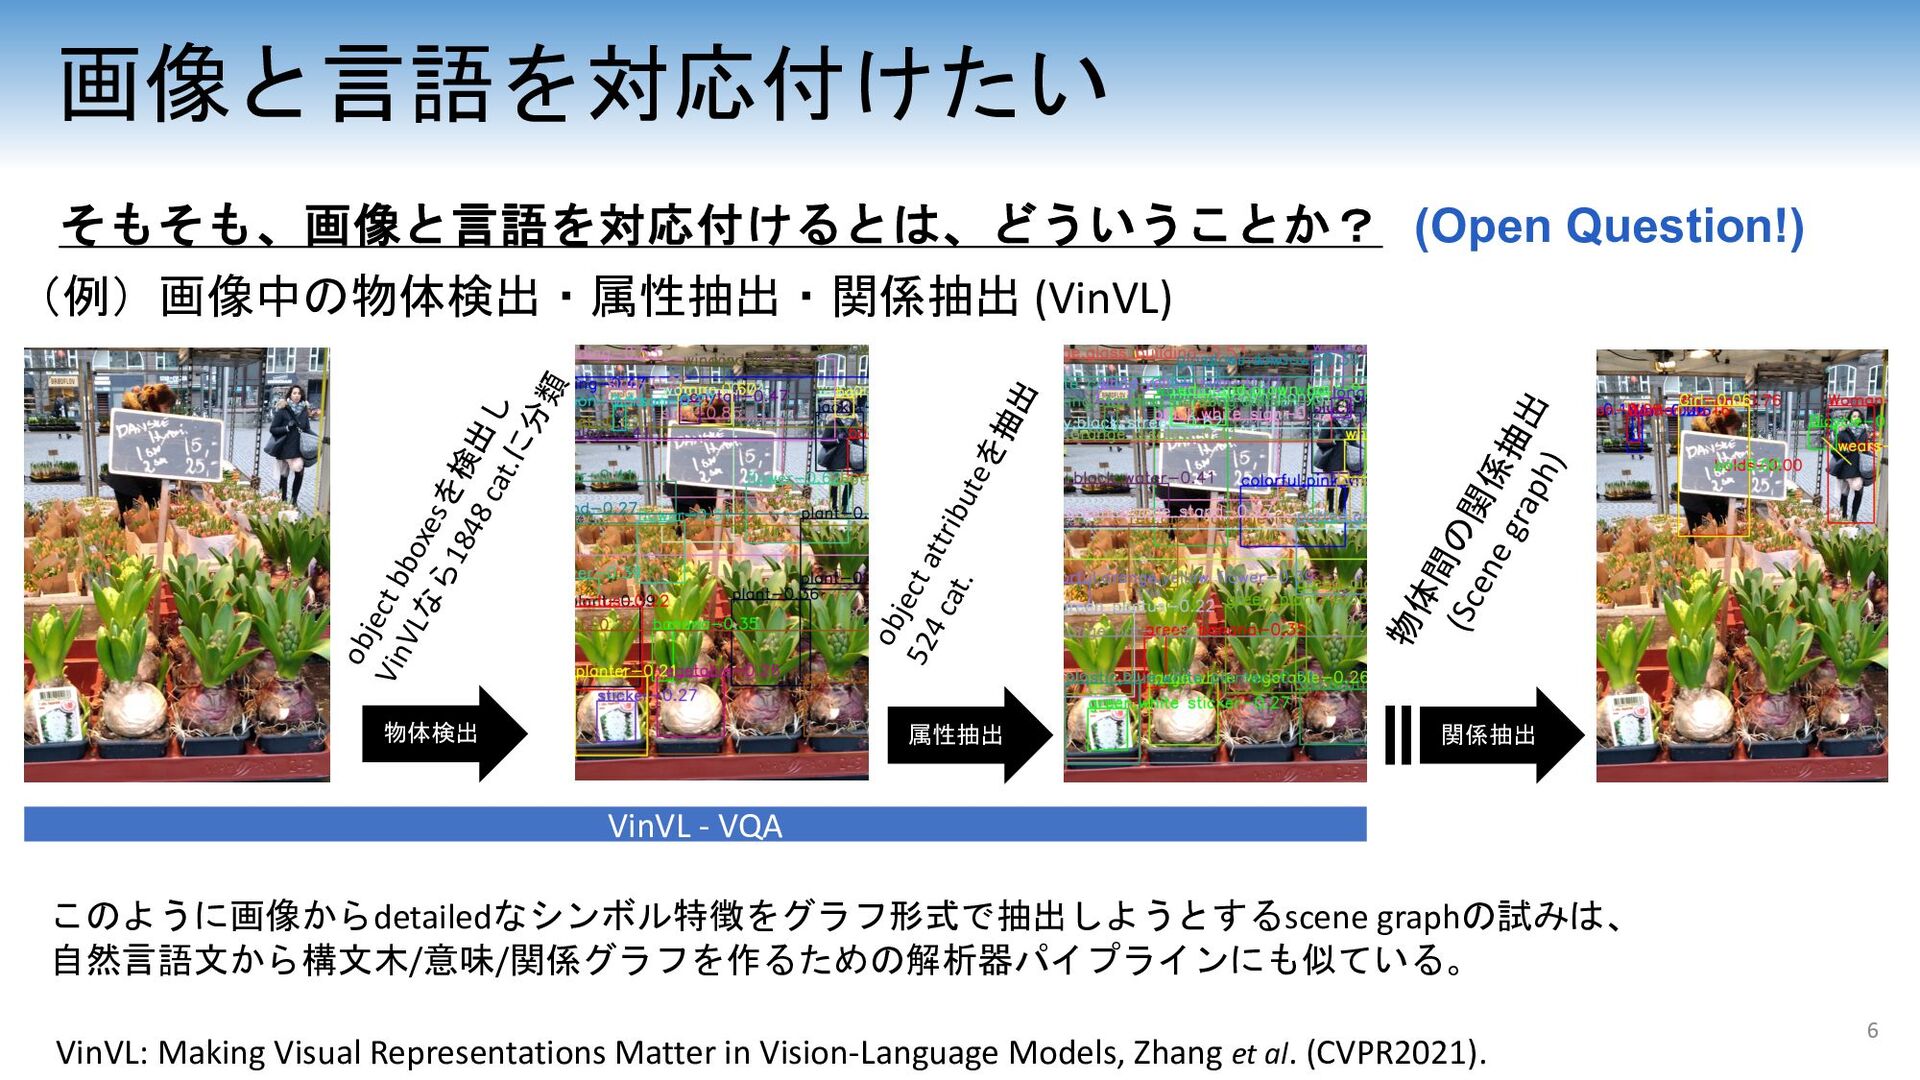
画像と言語を対応付けたい (例)画像中の物体検出・属性抽出・関係抽出 (VinVL) このように画像からdetailedなシンボル特徴をグラフ形式で抽出しようとするscene graphの試みは、 自然言語文から構文木/意味/関係グラフを作るための解析器パイプラインにも似ている。 そもそも、画像と言語を対応付けるとは、どういうことか? (Open Question!) object
attributeを抽出 524 cat. object bboxesを検出し VinVLなら 1848 cat.に分類 物体間の関係抽出 (Scene graph) 物体検出 属性抽出 関係抽出 VinVL - VQA 6 VinVL: Making Visual Representations Matter in Vision-Language Models, Zhang et al. (CVPR2021). -
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQAとSceneGraph, DenceCaptioning 2. 参照表現理解 (Referring
Expression Comprehension) 3. 対照学習(Contrastive Learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画に対する参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 7 -
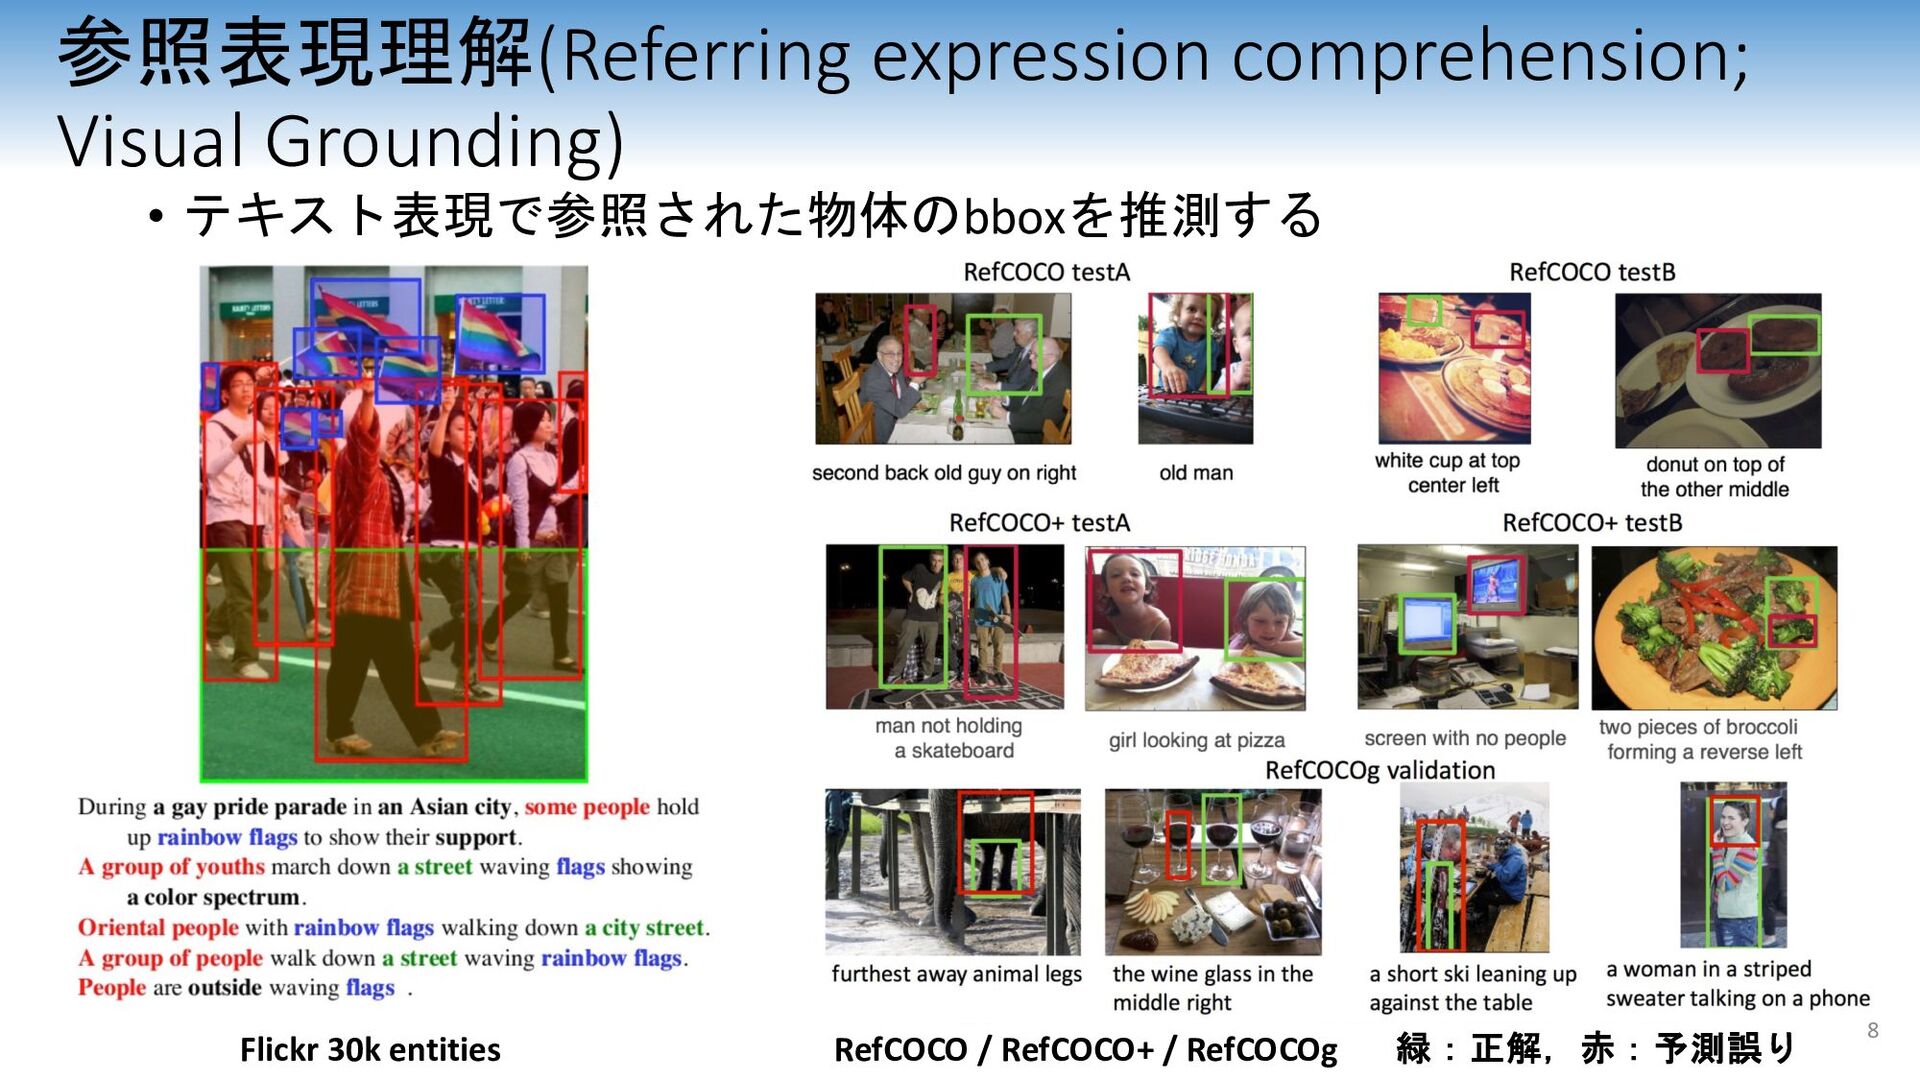
参照表現理解(Referring expression comprehension; Visual Grounding) • テキスト表現で参照された物体のbboxを推測する 8 RefCOCO /
RefCOCO+ / RefCOCOg 緑:正解,赤:予測誤り Flickr 30k entities -
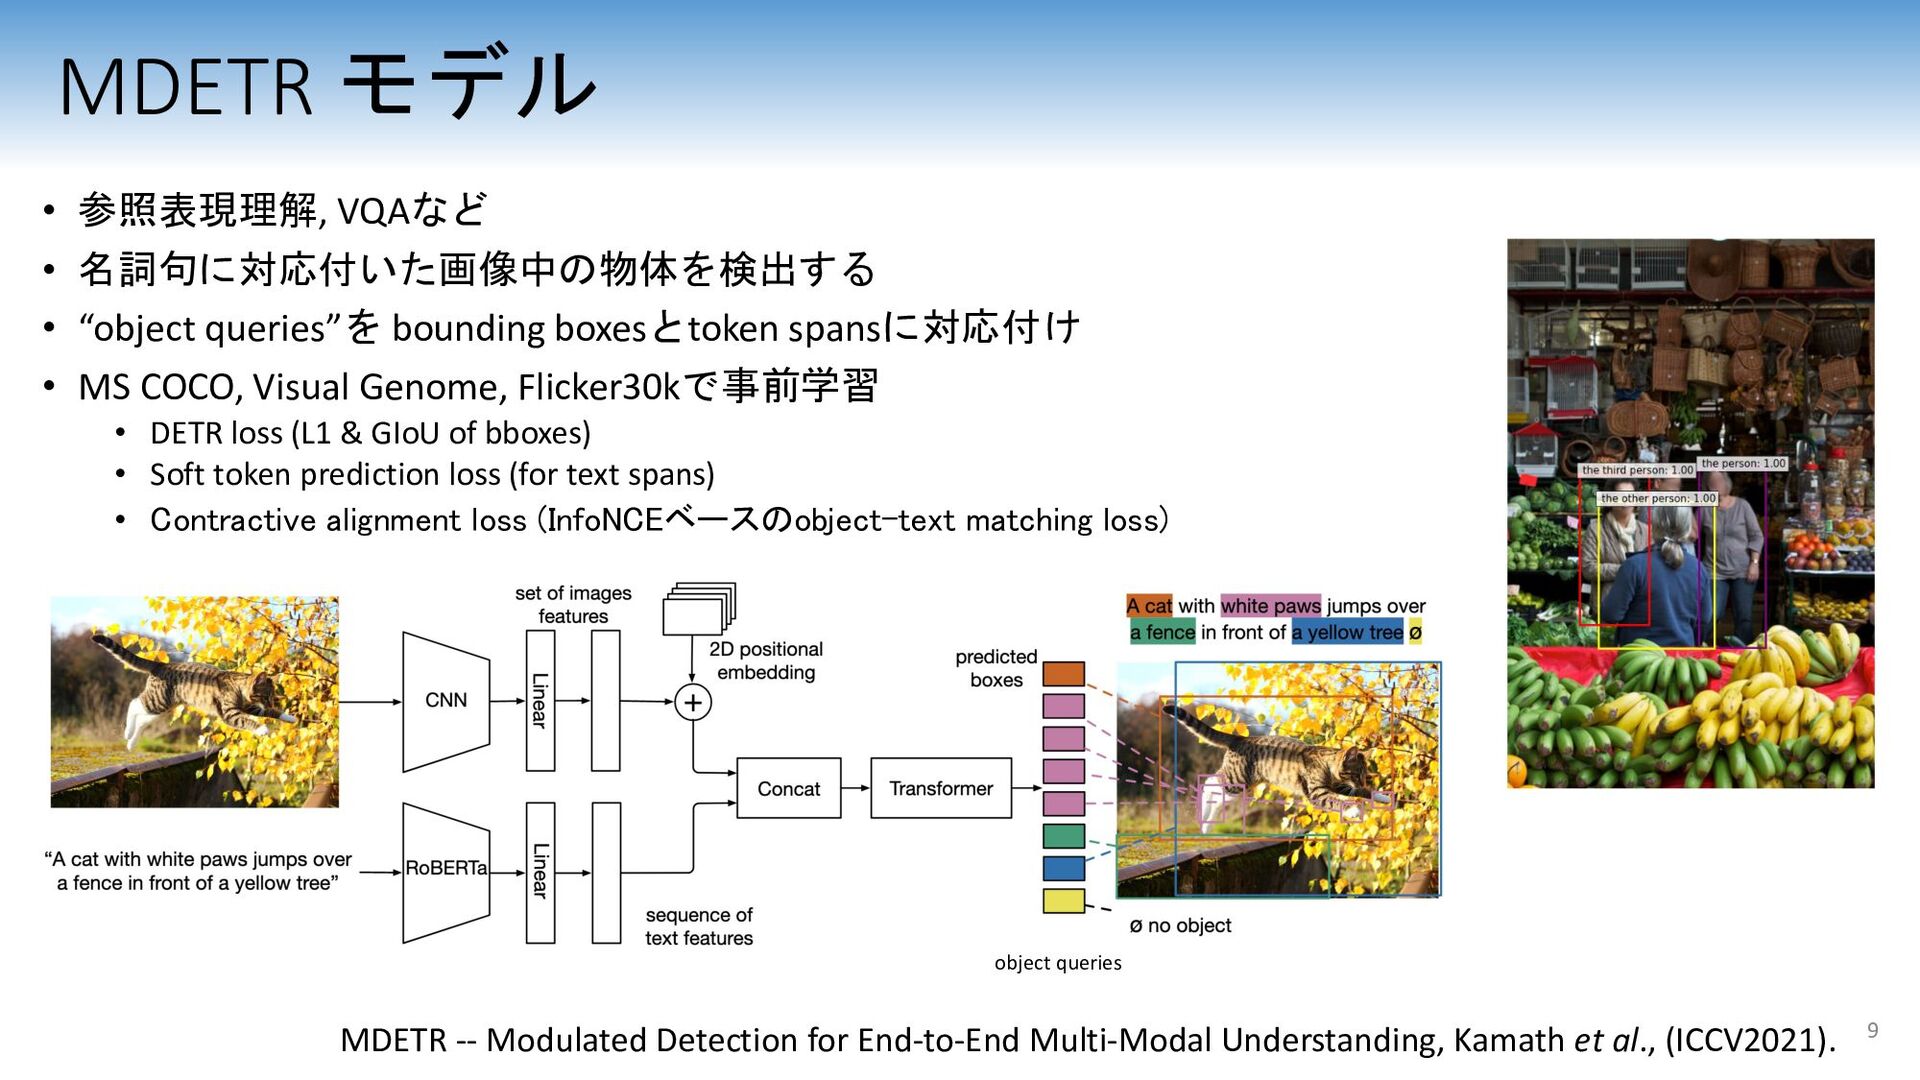
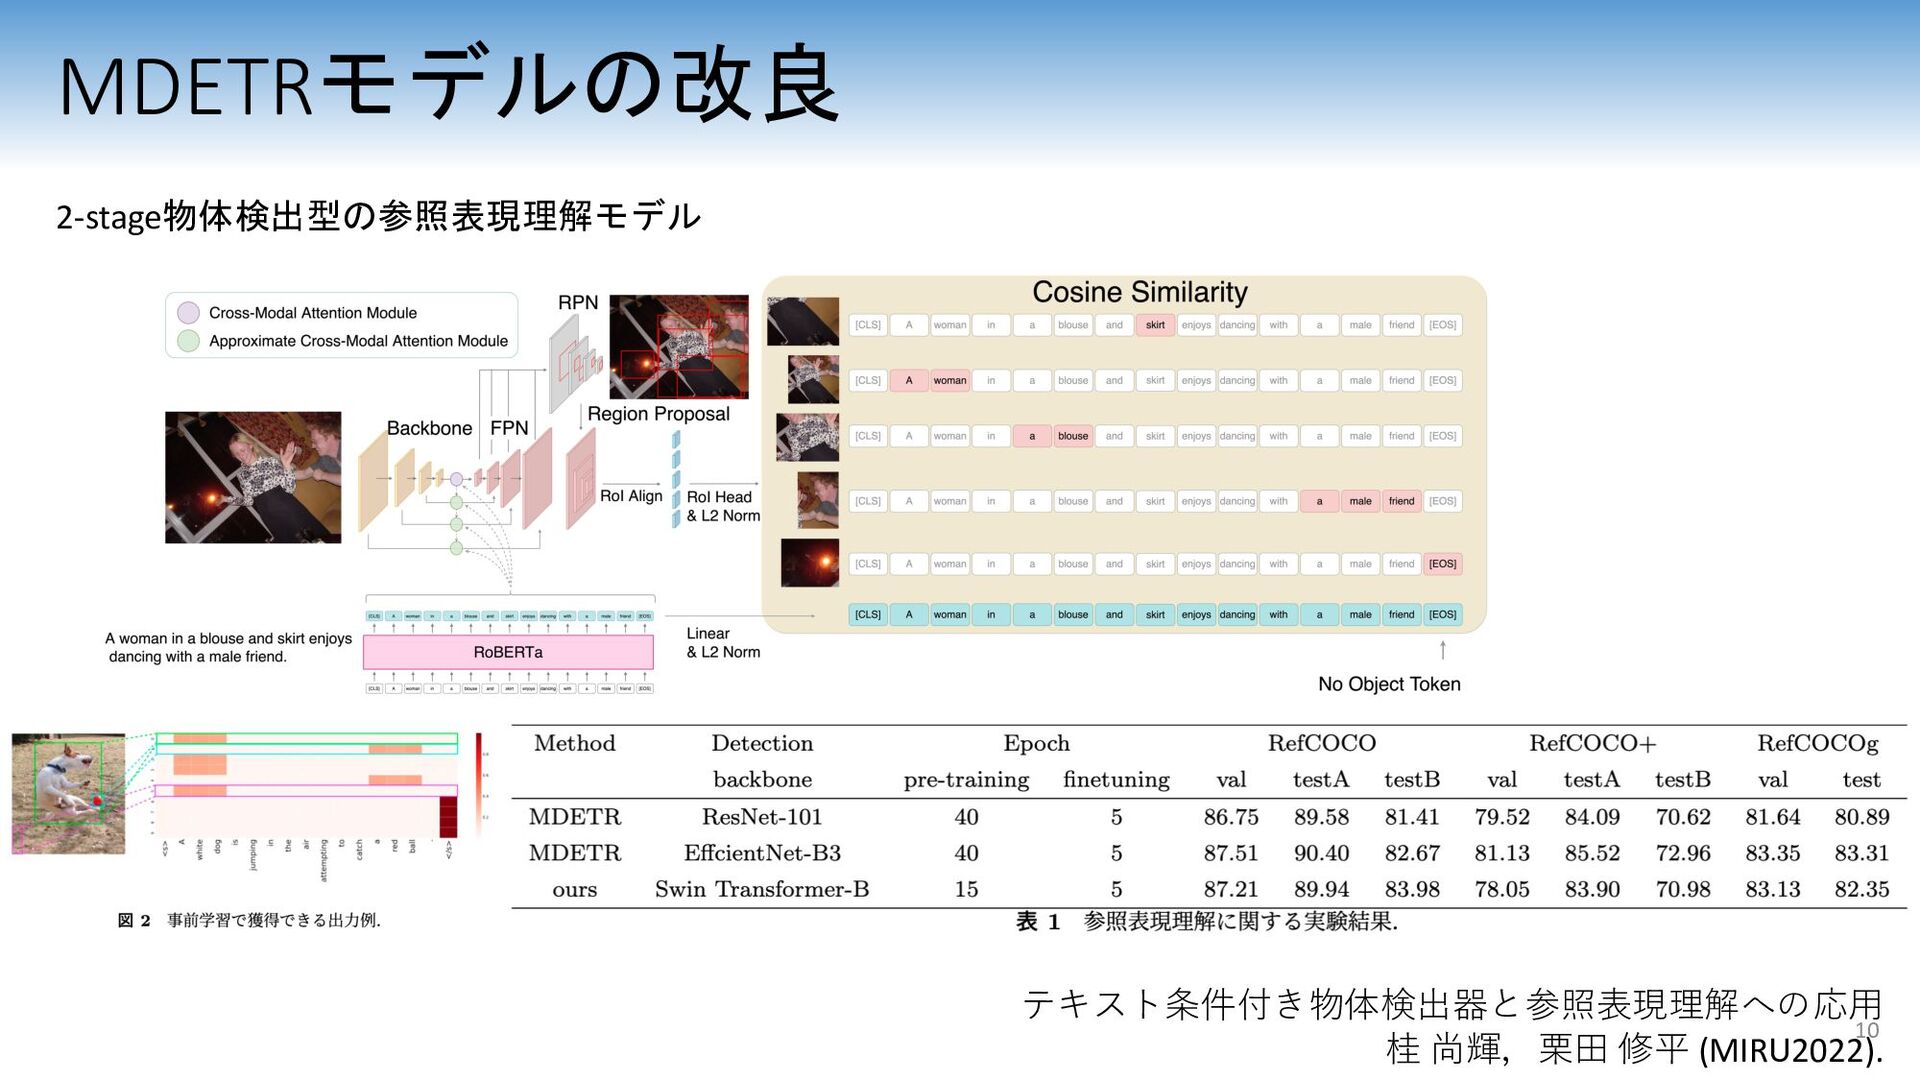
MDETR モデル • 参照表現理解, VQAなど • 名詞句に対応付いた画像中の物体を検出する • “object queries”を
bounding boxesとtoken spansに対応付け • MS COCO, Visual Genome, Flicker30kで事前学習 • DETR loss (L1 & GIoU of bboxes) • Soft token prediction loss (for text spans) • Contractive alignment loss (InfoNCEベースのobject-text matching loss) 9 MDETR -- Modulated Detection for End-to-End Multi-Modal Understanding, Kamath et al., (ICCV2021). object queries -
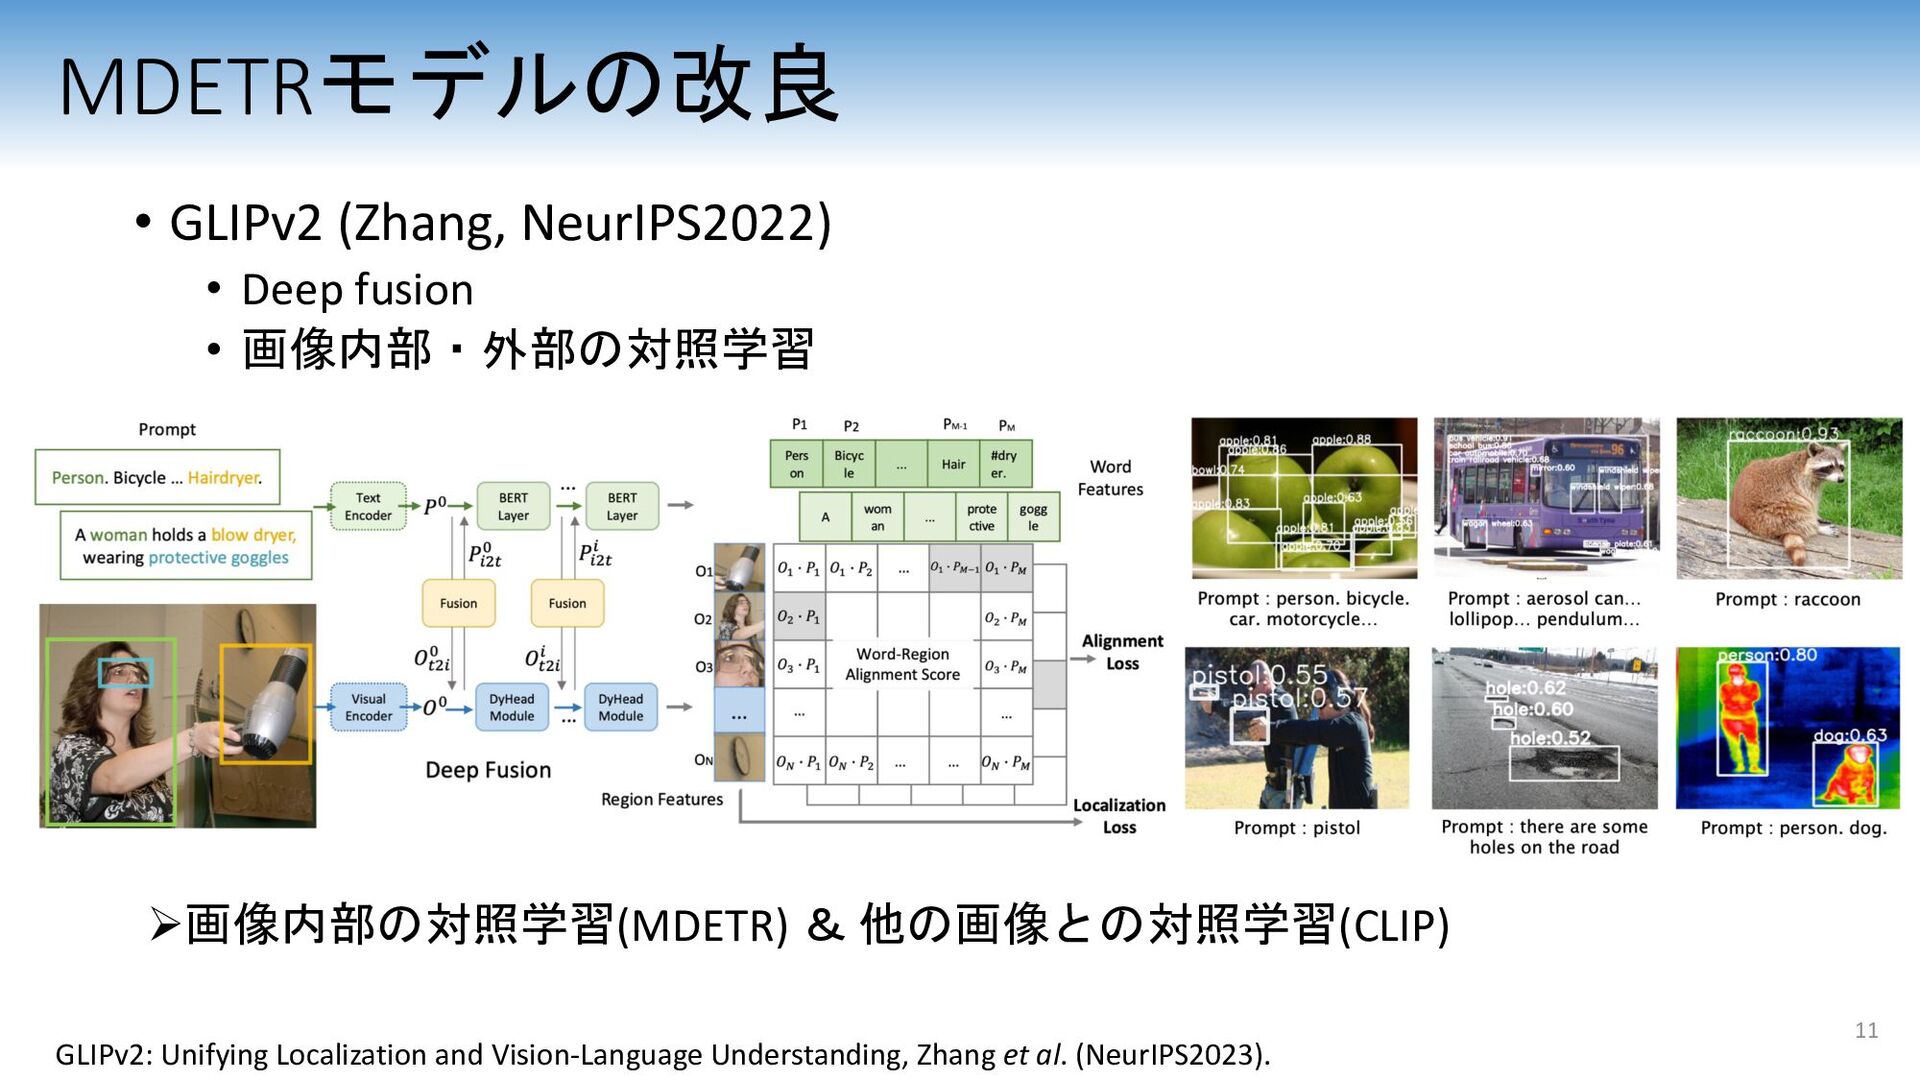
MDETRモデルの改良 Ø画像内部の対照学習(MDETR) & 他の画像との対照学習(CLIP) • GLIPv2 (Zhang, NeurIPS2022) • Deep
fusion • 画像内部・外部の対照学習 11 GLIPv2: Unifying Localization and Vision-Language Understanding, Zhang et al. (NeurIPS2023). -
参照表現理解 & 言語モデル • OFA [Wang 2022] • 複数のタスク,複数のデータセットを 結合してone
modelで学習する 12 OFA: Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework, Wang et al. (ICML2022). -
参照表現理解 & 言語モデル • OFA [Wang 2022] • 参照表現理解や物体検出時,bounding boxの
(x1 y1 x2 y2)を 言語モデルとして予測するという わけのわからない 革新的な出力を採用 • MDETRと違って, 1 textに1 bboxしか予測できないというデメリットがある • 参照表現に加えて,画像キャプション生成(MS COCO Caption)でもSoTA (だった) 13 -
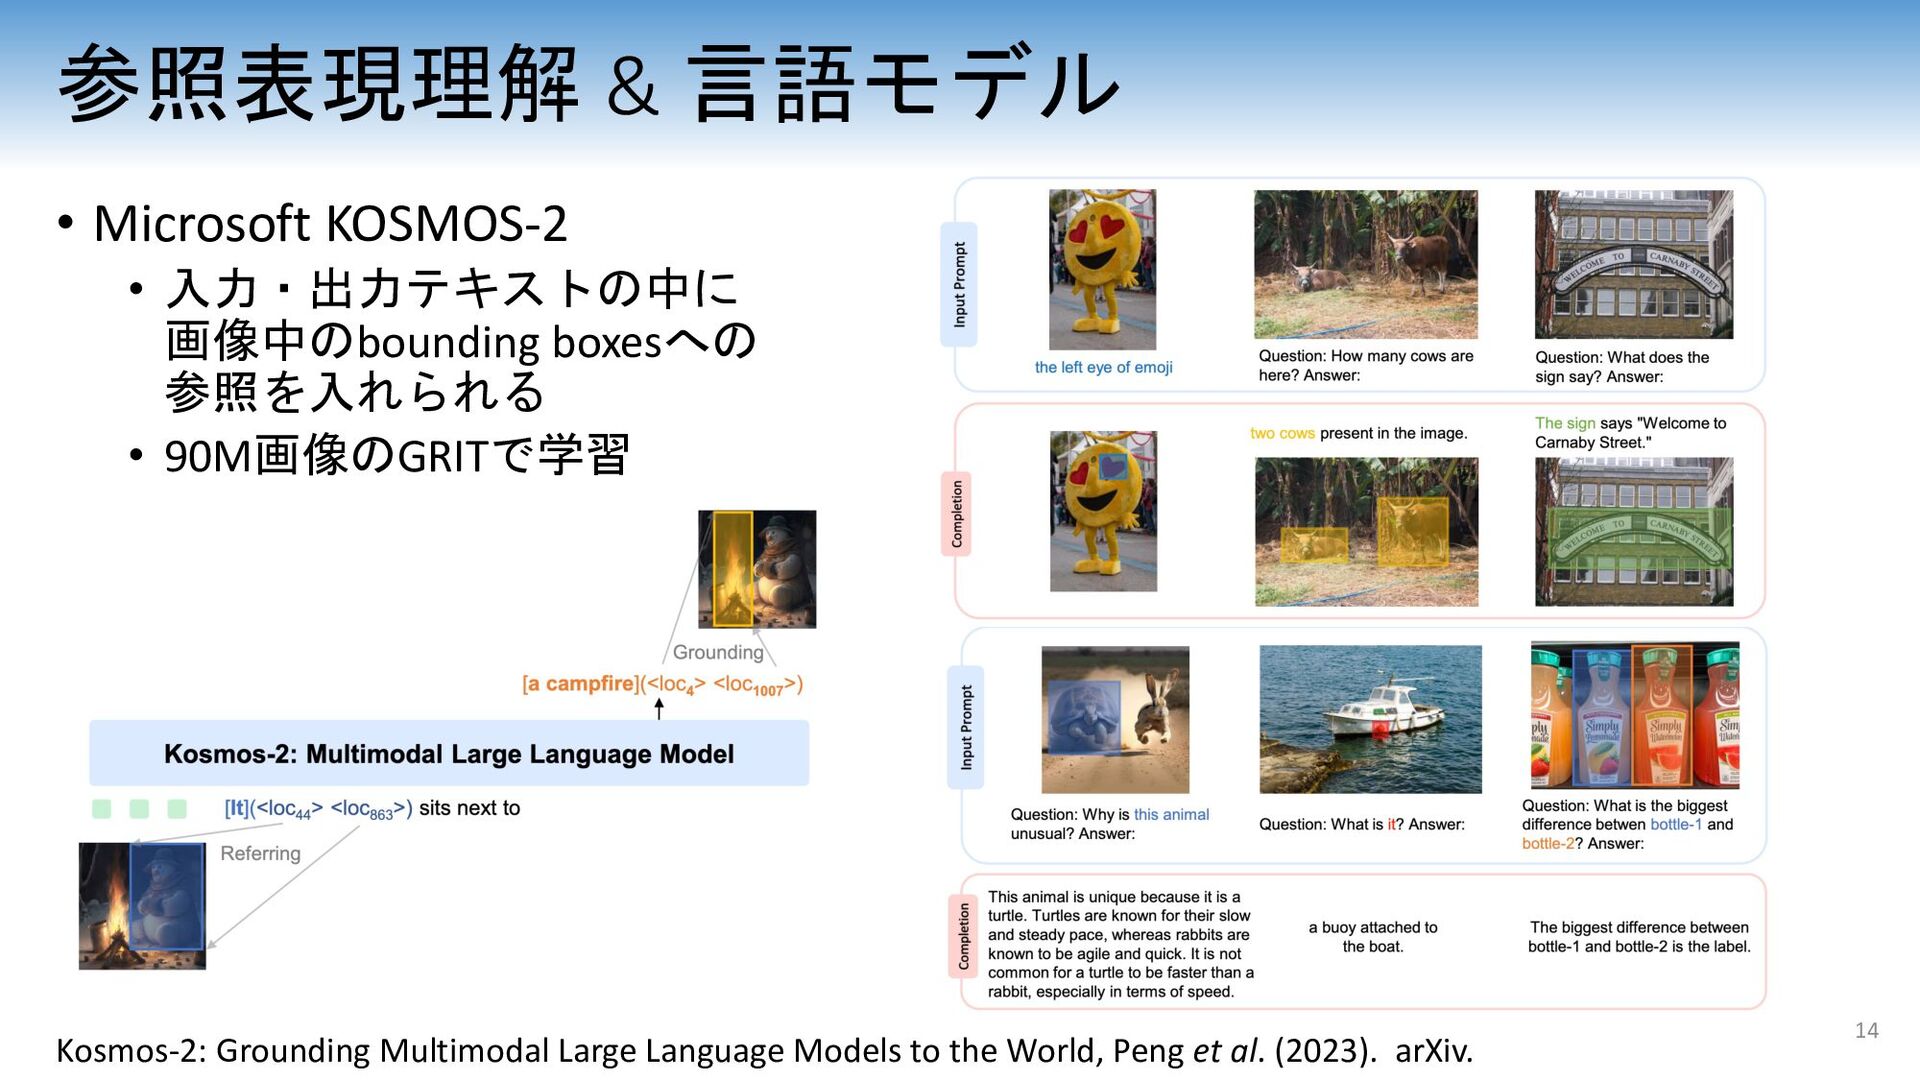
参照表現理解 & 言語モデル • Microsoft KOSMOS-2 • 入力・出力テキストの中に 画像中のbounding boxesへの
参照を入れられる • 90M画像のGRITで学習 14 Kosmos-2: Grounding Multimodal Large Language Models to the World, Peng et al. (2023). arXiv. -
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQAとSceneGraph, DenceCaptioning 2. 参照表現理解 (Referring
Expression Comprehension) 3. 対照学習(Contrastive Learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画に対する参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 15 -
画像と言語の対照学習と基盤モデル • CLIP [Radford, 2021] • (1) バッチ内部の複数枚の画像とテキストとのアライメントを対照事前学習 • 推論時に
(2) 新規のラベルも外挿することで (3) 新しいラベルに対するzero-shot予測も可能 • 既存のDenseなアノテーション(例:MS-COCO,VisualGenome)をpretrainでは使用していない Ø 画像全体をあるテキストに対応付けるには向いている Ø キャプションを生成する画像の細部とテキストの細部の対応を取る用途には向いていない 17 Ø V&Lの対照学習は,”bag-of-words”のように振る舞うという報告がある (Yuksekgonul, ICLR2023). -
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQA, SceneGraph, DenceCaptioning 2. 参照表現理解
(Referring Expression Comprehension) 3. 対照学習(Contrastive Learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画に対する参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 18 -
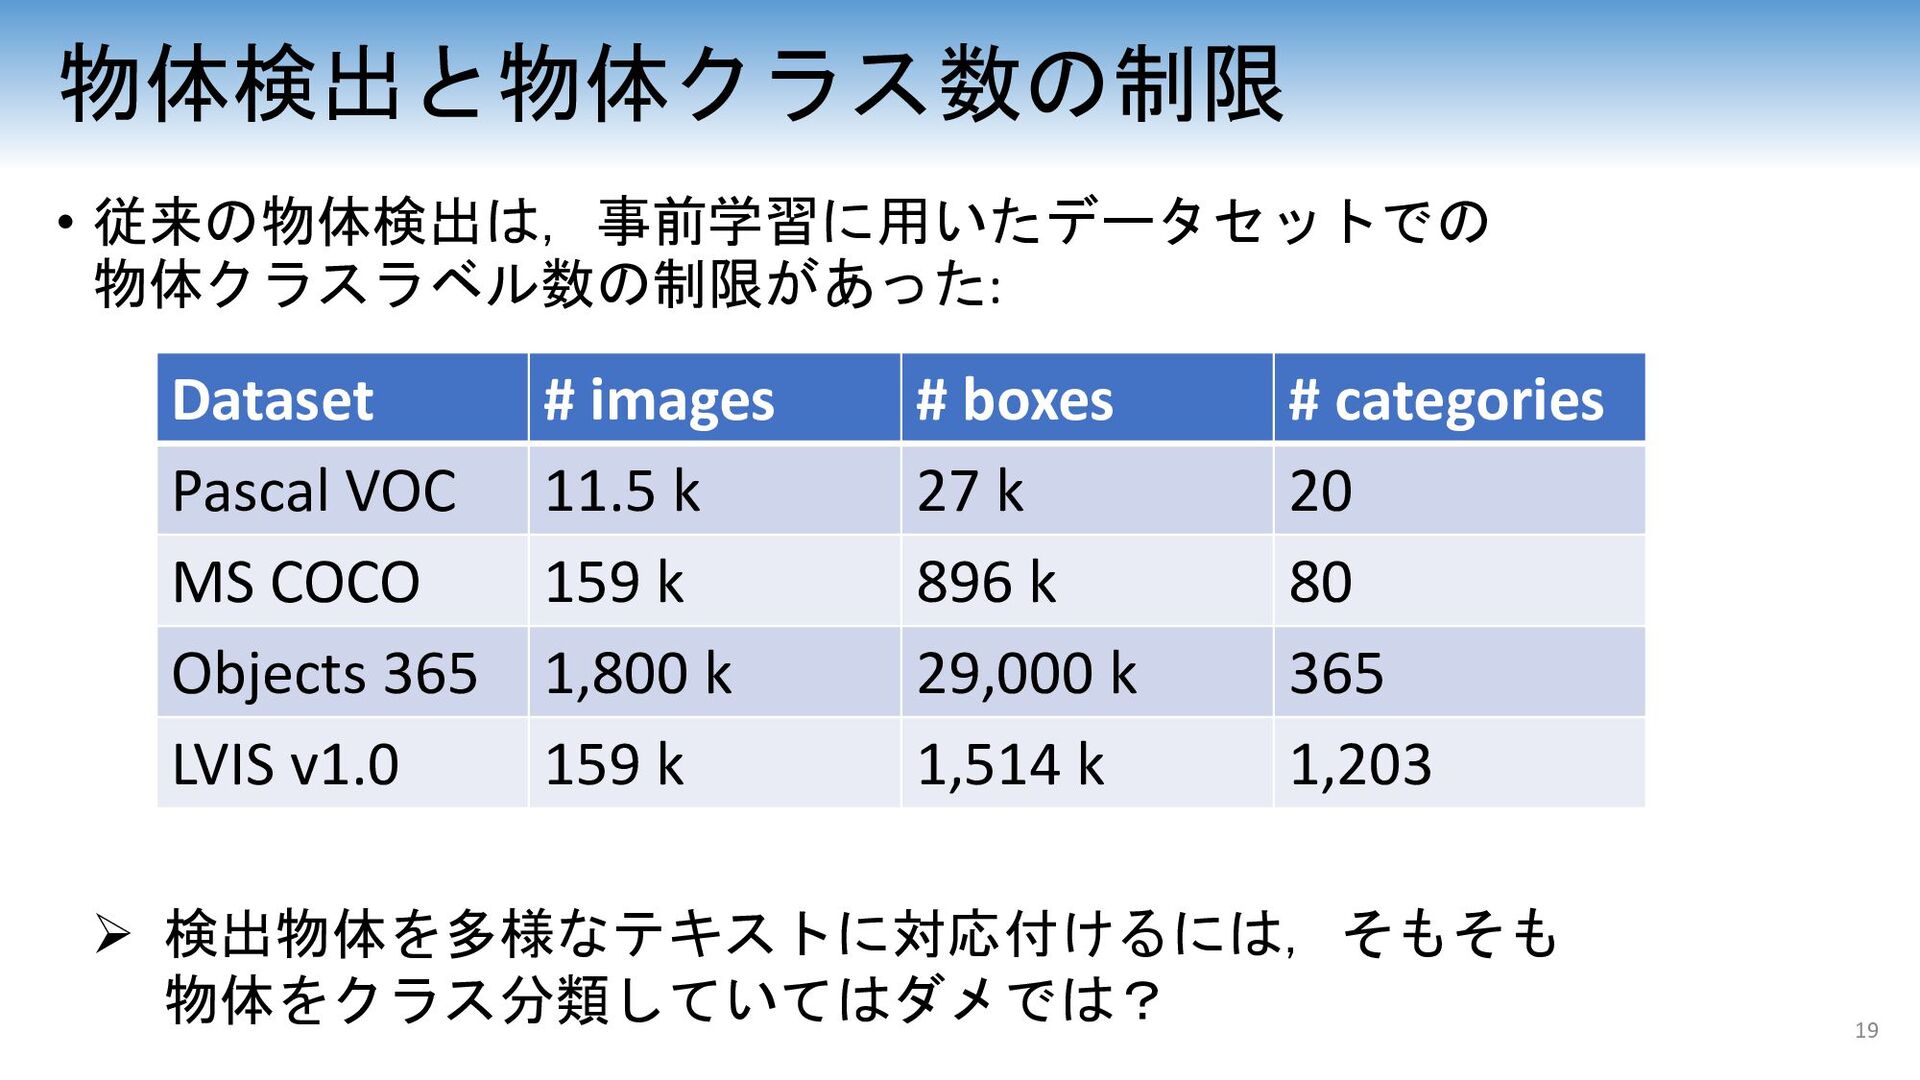
物体検出と物体クラス数の制限 • 従来の物体検出は,事前学習に用いたデータセットでの 物体クラスラベル数の制限があった: 19 Dataset # images # boxes
# categories Pascal VOC 11.5 k 27 k 20 MS COCO 159 k 896 k 80 Objects 365 1,800 k 29,000 k 365 LVIS v1.0 159 k 1,514 k 1,203 Ø 検出物体を多様なテキストに対応付けるには,そもそも 物体をクラス分類していてはダメでは? -
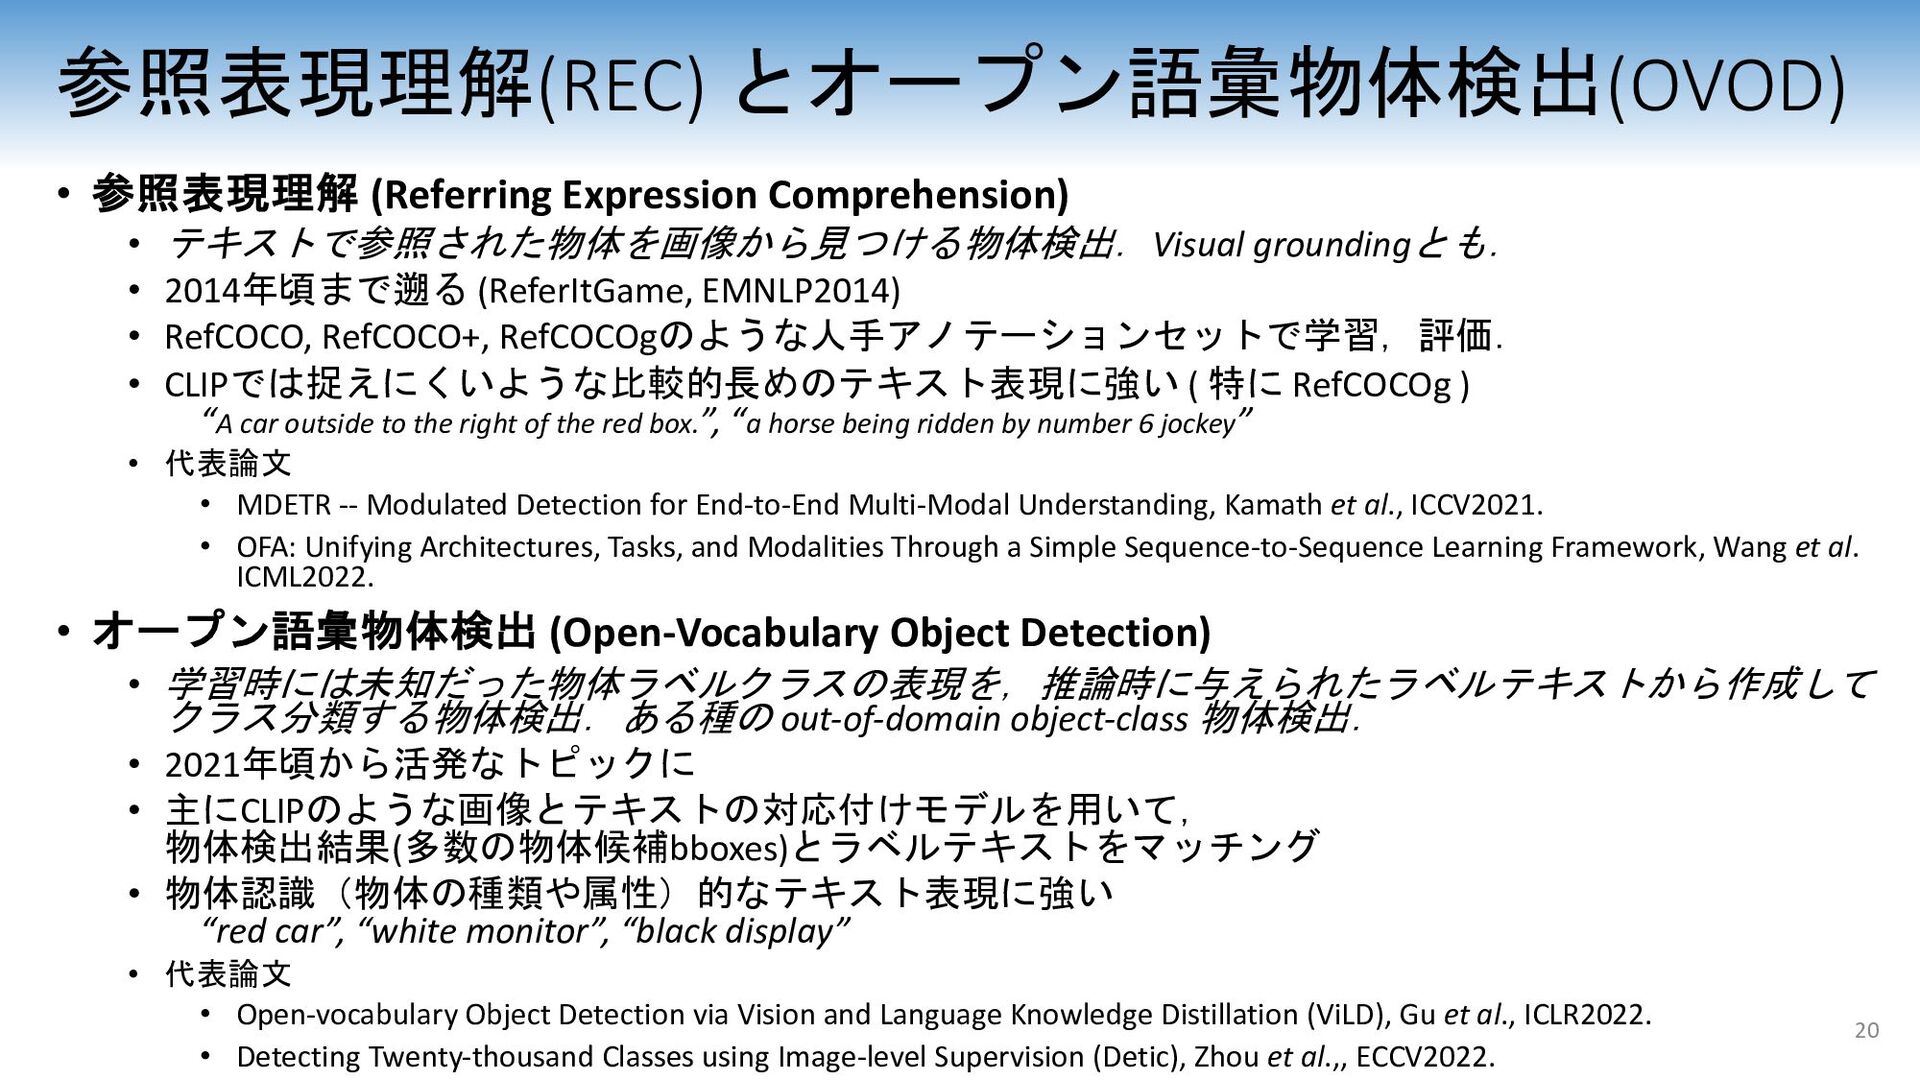
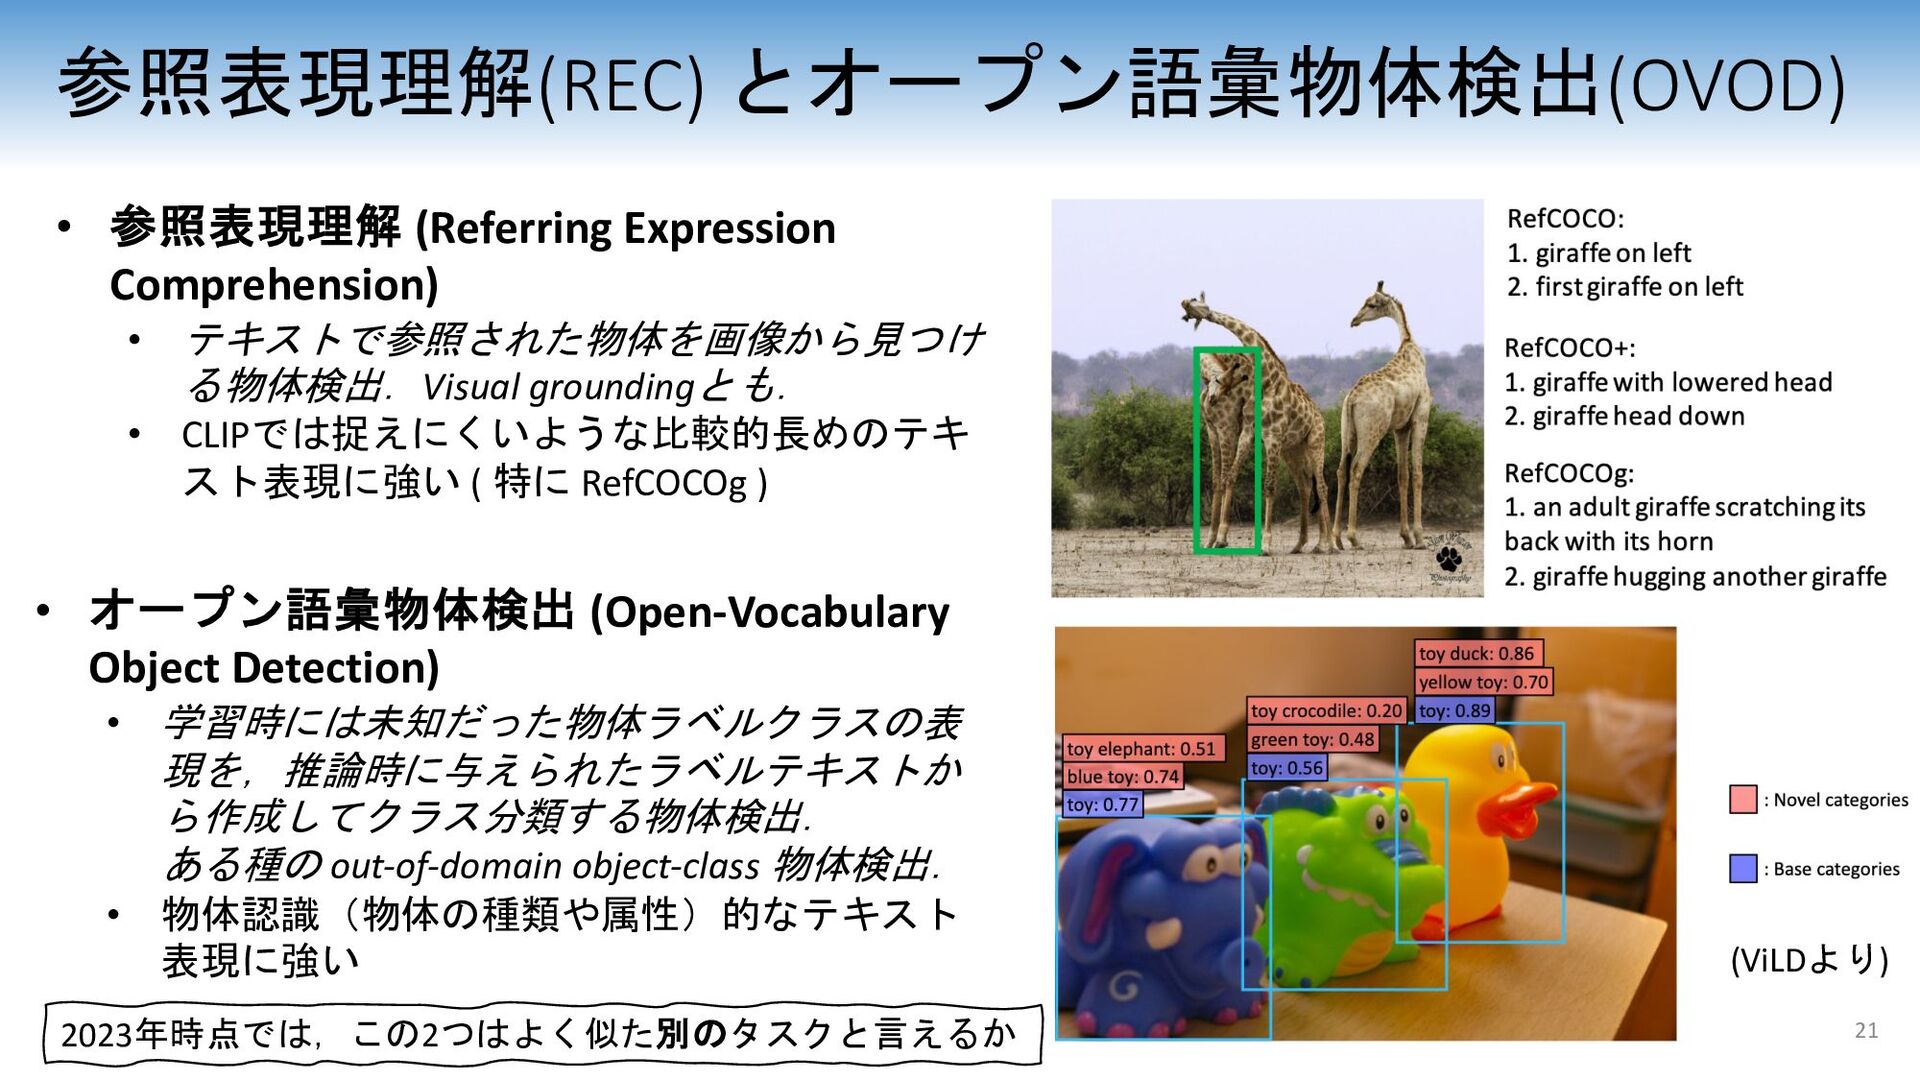
参照表現理解(REC) とオープン語彙物体検出(OVOD) • 参照表現理解 (Referring Expression Comprehension) • テキストで参照された物体を画像から見つける物体検出.Visual groundingとも.
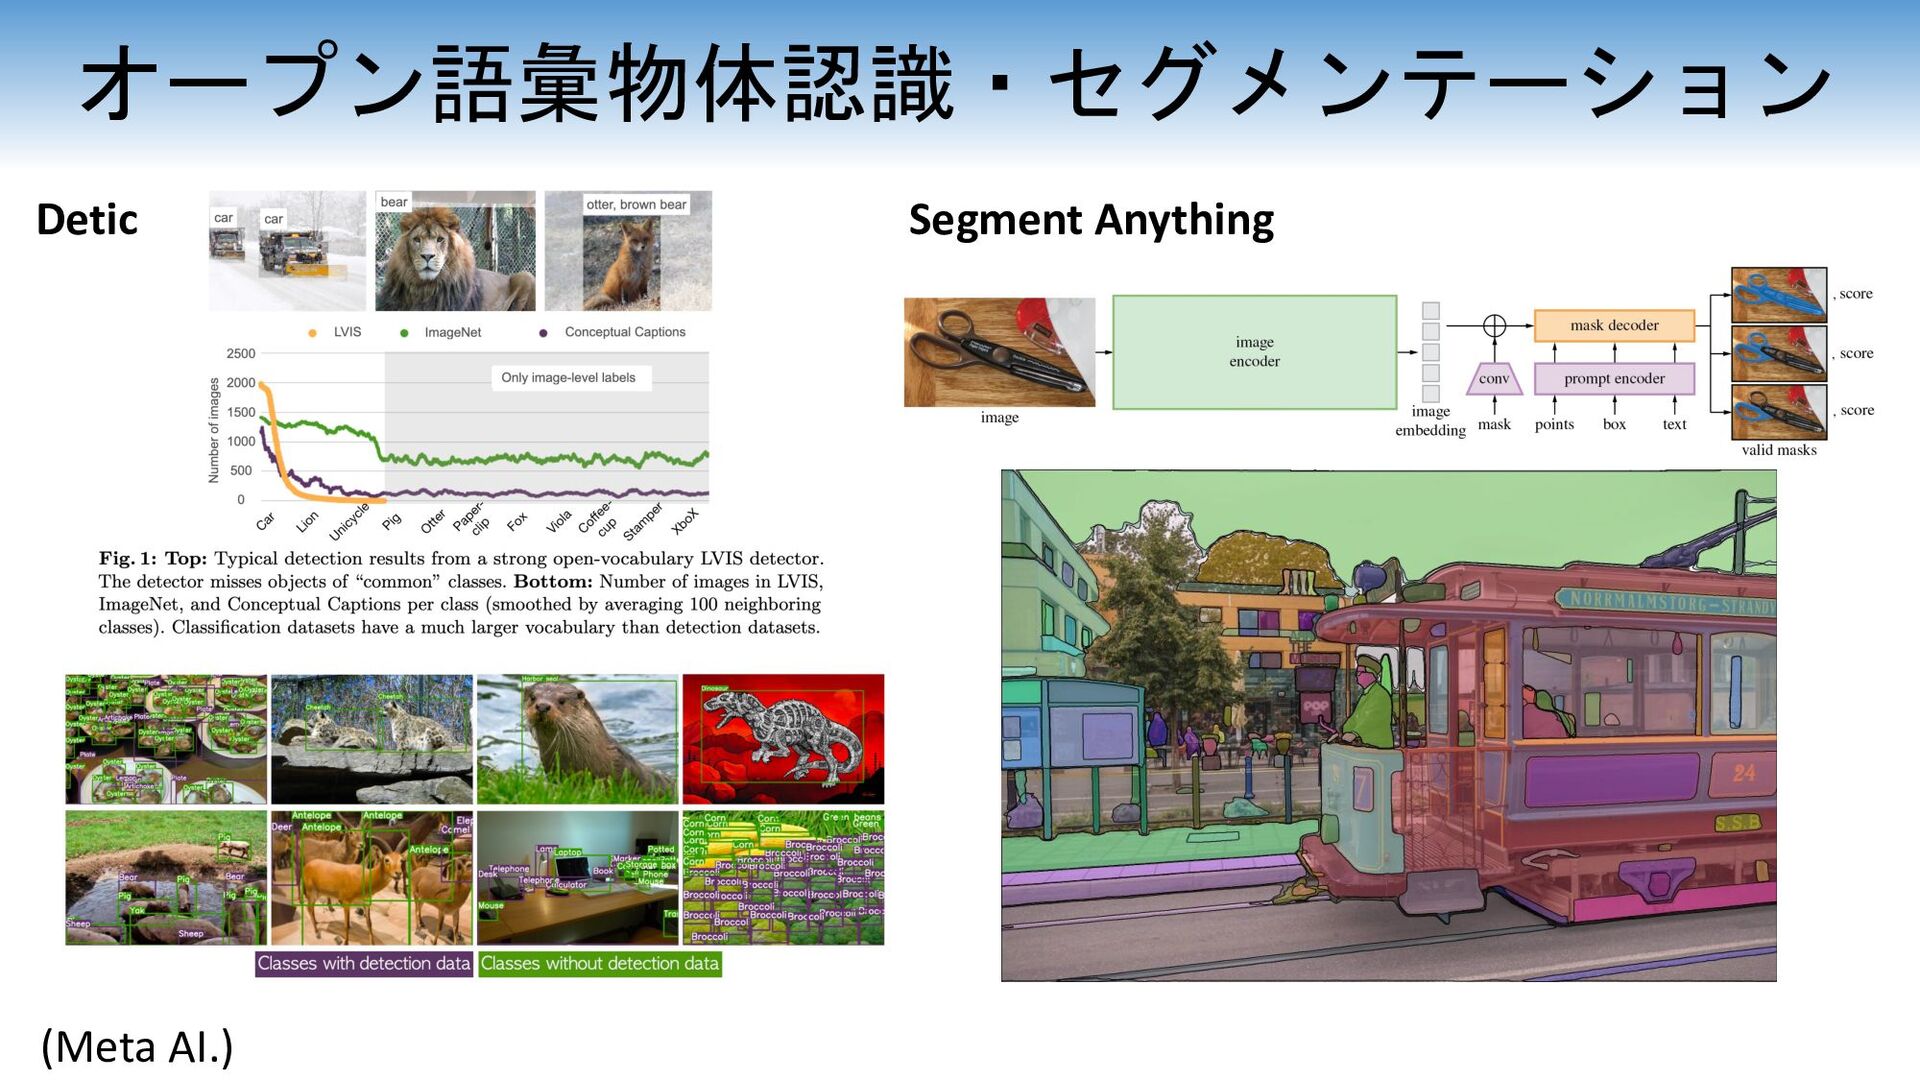
• 2014年頃まで遡る (ReferItGame, EMNLP2014) • RefCOCO, RefCOCO+, RefCOCOgのような人手アノテーションセットで学習,評価. • CLIPでは捉えにくいような比較的長めのテキスト表現に強い ( 特に RefCOCOg ) “A car outside to the right of the red box.”, “a horse being ridden by number 6 jockey” • 代表論文 • MDETR -- Modulated Detection for End-to-End Multi-Modal Understanding, Kamath et al., ICCV2021. • OFA: Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework, Wang et al. ICML2022. • オープン語彙物体検出 (Open-Vocabulary Object Detection) • 学習時には未知だった物体ラベルクラスの表現を,推論時に与えられたラベルテキストから作成して クラス分類する物体検出.ある種の out-of-domain object-class 物体検出. • 2021年頃から活発なトピックに • 主にCLIPのような画像とテキストの対応付けモデルを用いて, 物体検出結果(多数の物体候補bboxes)とラベルテキストをマッチング • 物体認識(物体の種類や属性)的なテキスト表現に強い “red car”, “white monitor”, “black display” • 代表論文 • Open-vocabulary Object Detection via Vision and Language Knowledge Distillation (ViLD), Gu et al., ICLR2022. • Detecting Twenty-thousand Classes using Image-level Supervision (Detic), Zhou et al.,, ECCV2022. 20 -
参照表現理解(REC) とオープン語彙物体検出(OVOD) 21 2023年時点では,この2つはよく似た別のタスクと言えるか • オープン語彙物体検出 (Open-Vocabulary Object Detection) •
学習時には未知だった物体ラベルクラスの表 現を,推論時に与えられたラベルテキストか ら作成してクラス分類する物体検出. ある種の out-of-domain object-class 物体検出. • 物体認識(物体の種類や属性)的なテキスト 表現に強い • 参照表現理解 (Referring Expression Comprehension) • テキストで参照された物体を画像から見つけ る物体検出.Visual groundingとも. • CLIPでは捉えにくいような比較的長めのテキ スト表現に強い ( 特に RefCOCOg ) (ViLDより) -
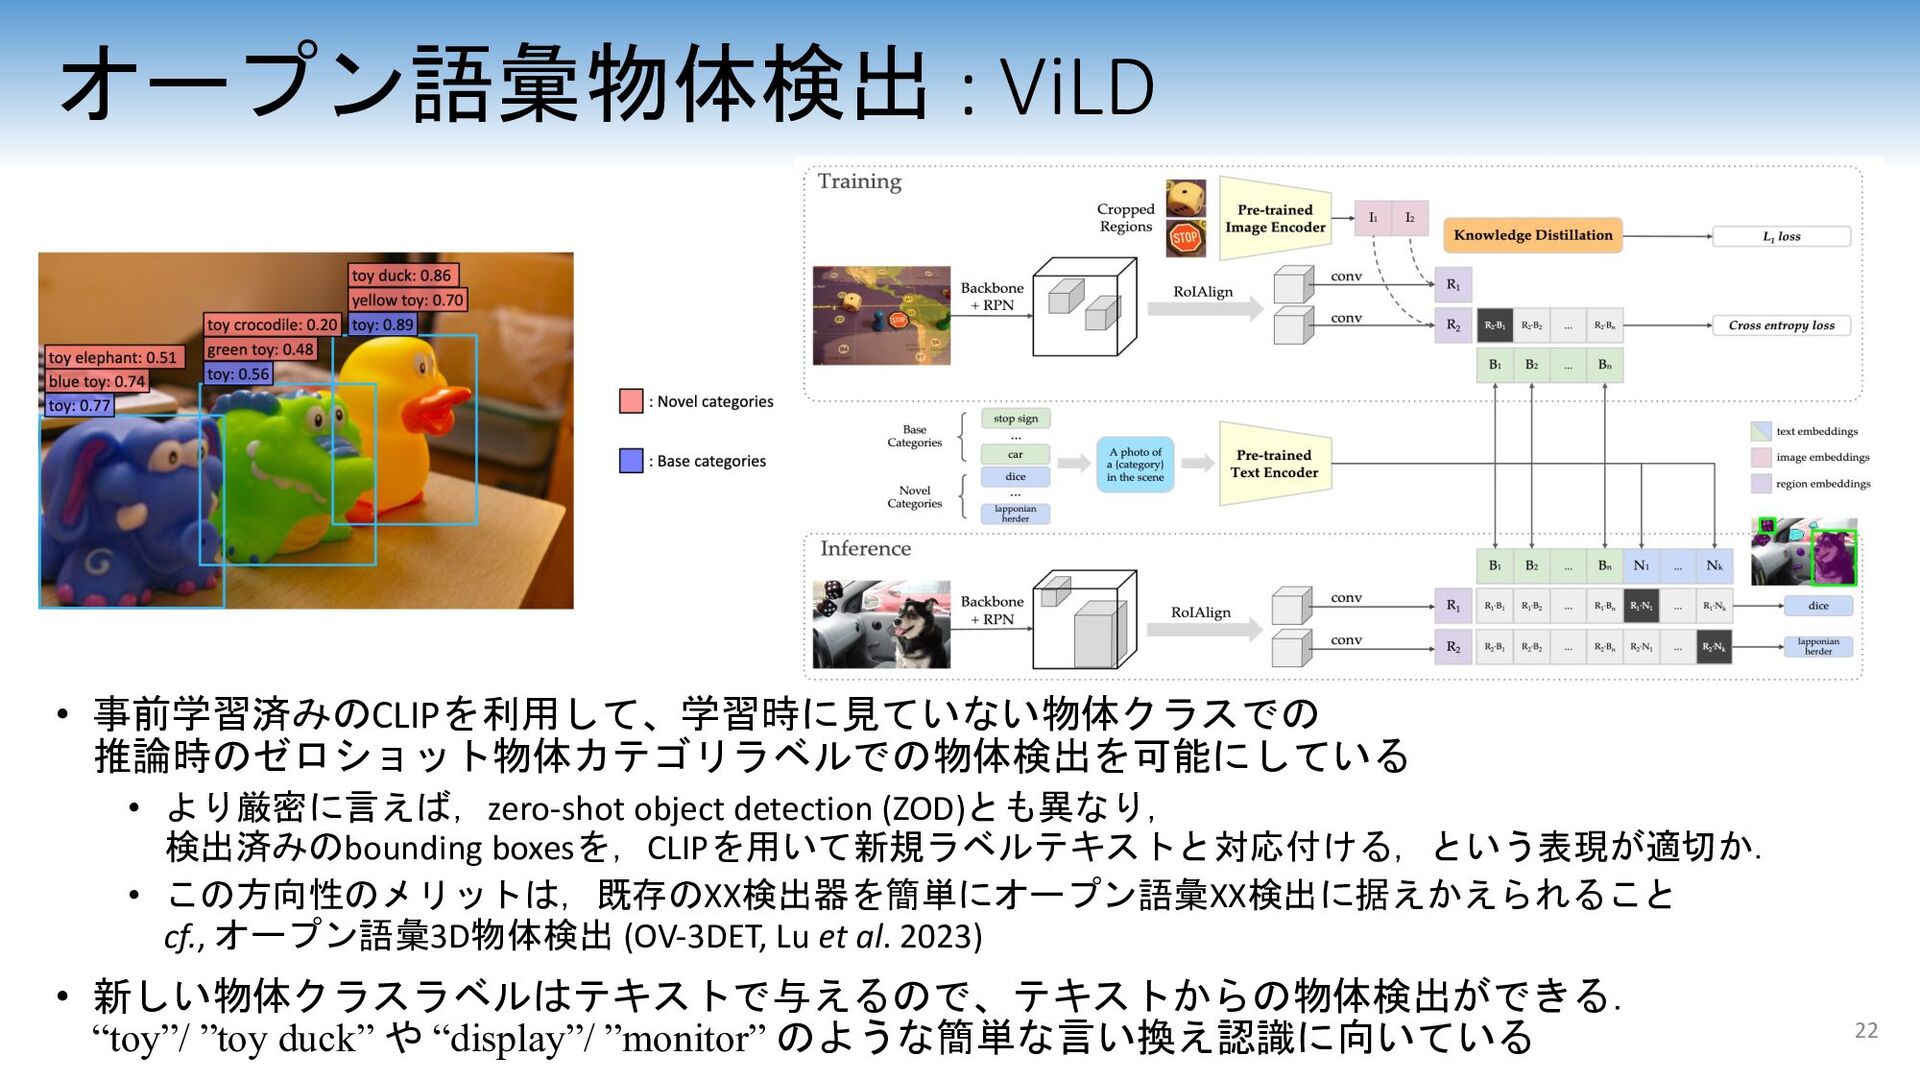
オープン語彙物体検出 : ViLD • 事前学習済みのCLIPを利用して、学習時に見ていない物体クラスでの 推論時のゼロショット物体カテゴリラベルでの物体検出を可能にしている • より厳密に言えば,zero-shot object detection
(ZOD)とも異なり, 検出済みのbounding boxesを,CLIPを用いて新規ラベルテキストと対応付ける,という表現が適切か. • この方向性のメリットは,既存のXX検出器を簡単にオープン語彙XX検出に据えかえられること cf., オープン語彙3D物体検出 (OV-3DET, Lu et al. 2023) • 新しい物体クラスラベルはテキストで与えるので、テキストからの物体検出ができる. “toy”/ ”toy duck” や “display”/ ”monitor” のような簡単な言い換え認識に向いている 22 -
Grounding DINO • オープン語彙物体認識の性能でGLIP超え • RECの性能ではOFAに負けている… 24 Grounding DINO: Marrying
DINO with Grounded Pre-Training for Open-Set Object Detection, Liu et al., 2023. arXiv. -
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQA, SceneGraph, DenceCaptioning 2. 参照表現理解
(Referring Expression Comprehension) 3. 対照学習(Contrastive Learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画に対する参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 25 -
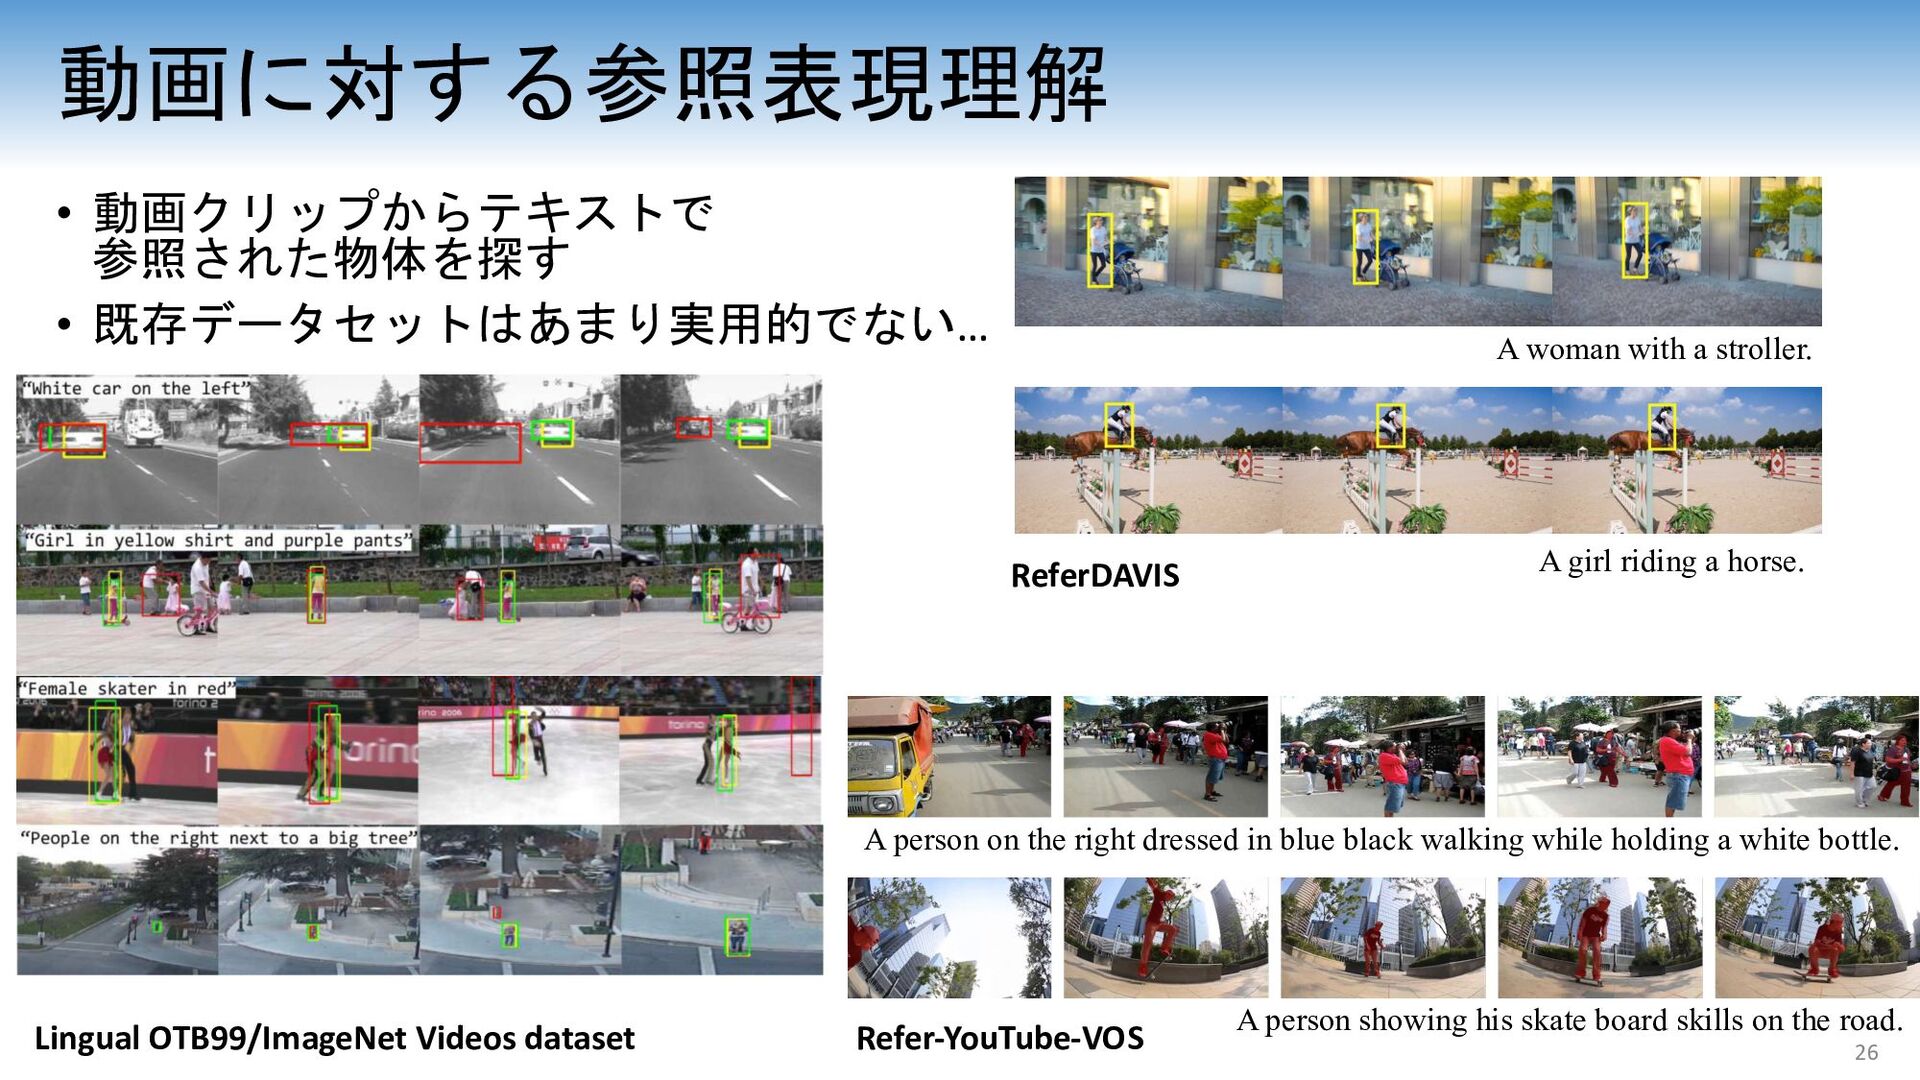
動画に対する参照表現理解 • 動画クリップからテキストで 参照された物体を探す • 既存データセットはあまり実用的でない… 26 Lingual OTB99/ImageNet Videos
dataset A woman with a stroller. A girl riding a horse. ReferDAVIS Refer-YouTube-VOS A person showing his skate board skills on the road. A person on the right dressed in blue black walking while holding a white bottle. -
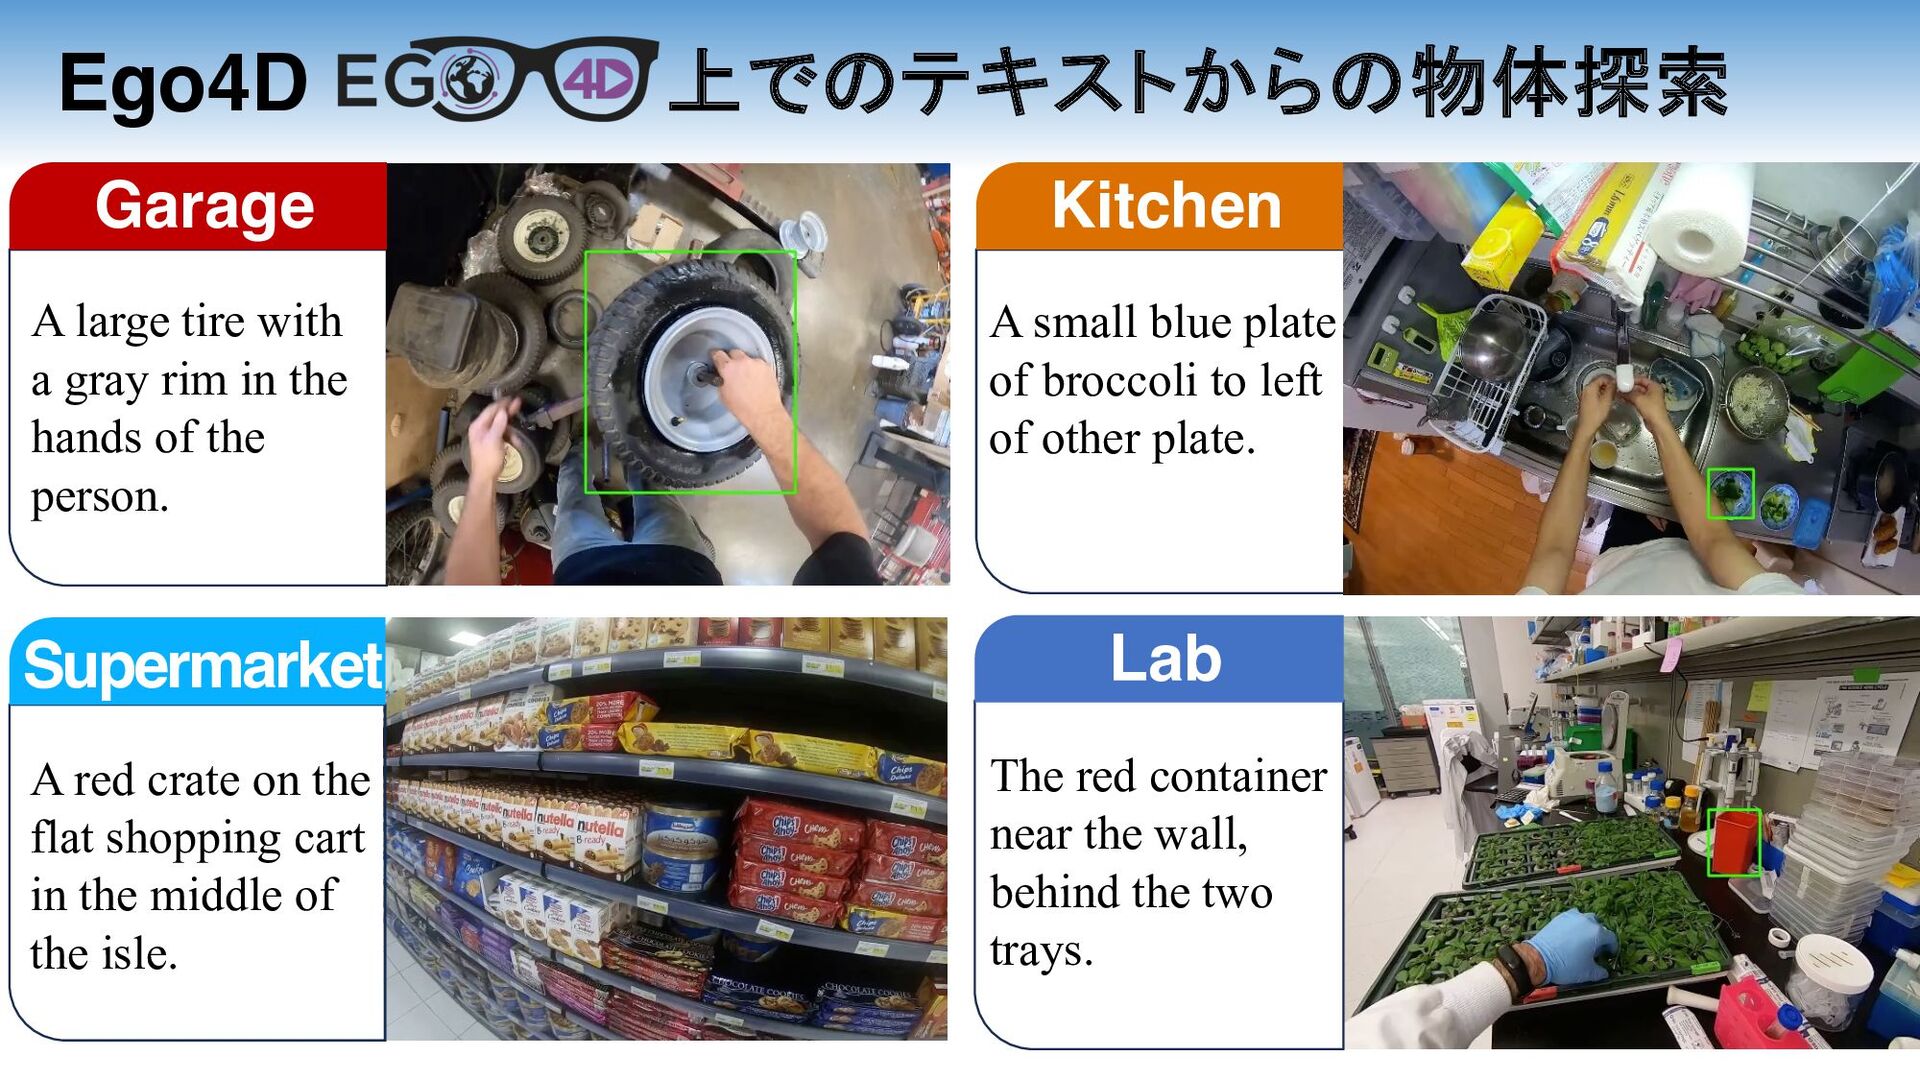
Ego4D 上でのテキストからの物体探索 27 A large tire with a gray rim
in the hands of the person. A red crate on the flat shopping cart in the middle of the isle. A small blue plate of broccoli to left of other plate. The red container near the wall, behind the two trays. Garage Kitchen Lab Supermarket -
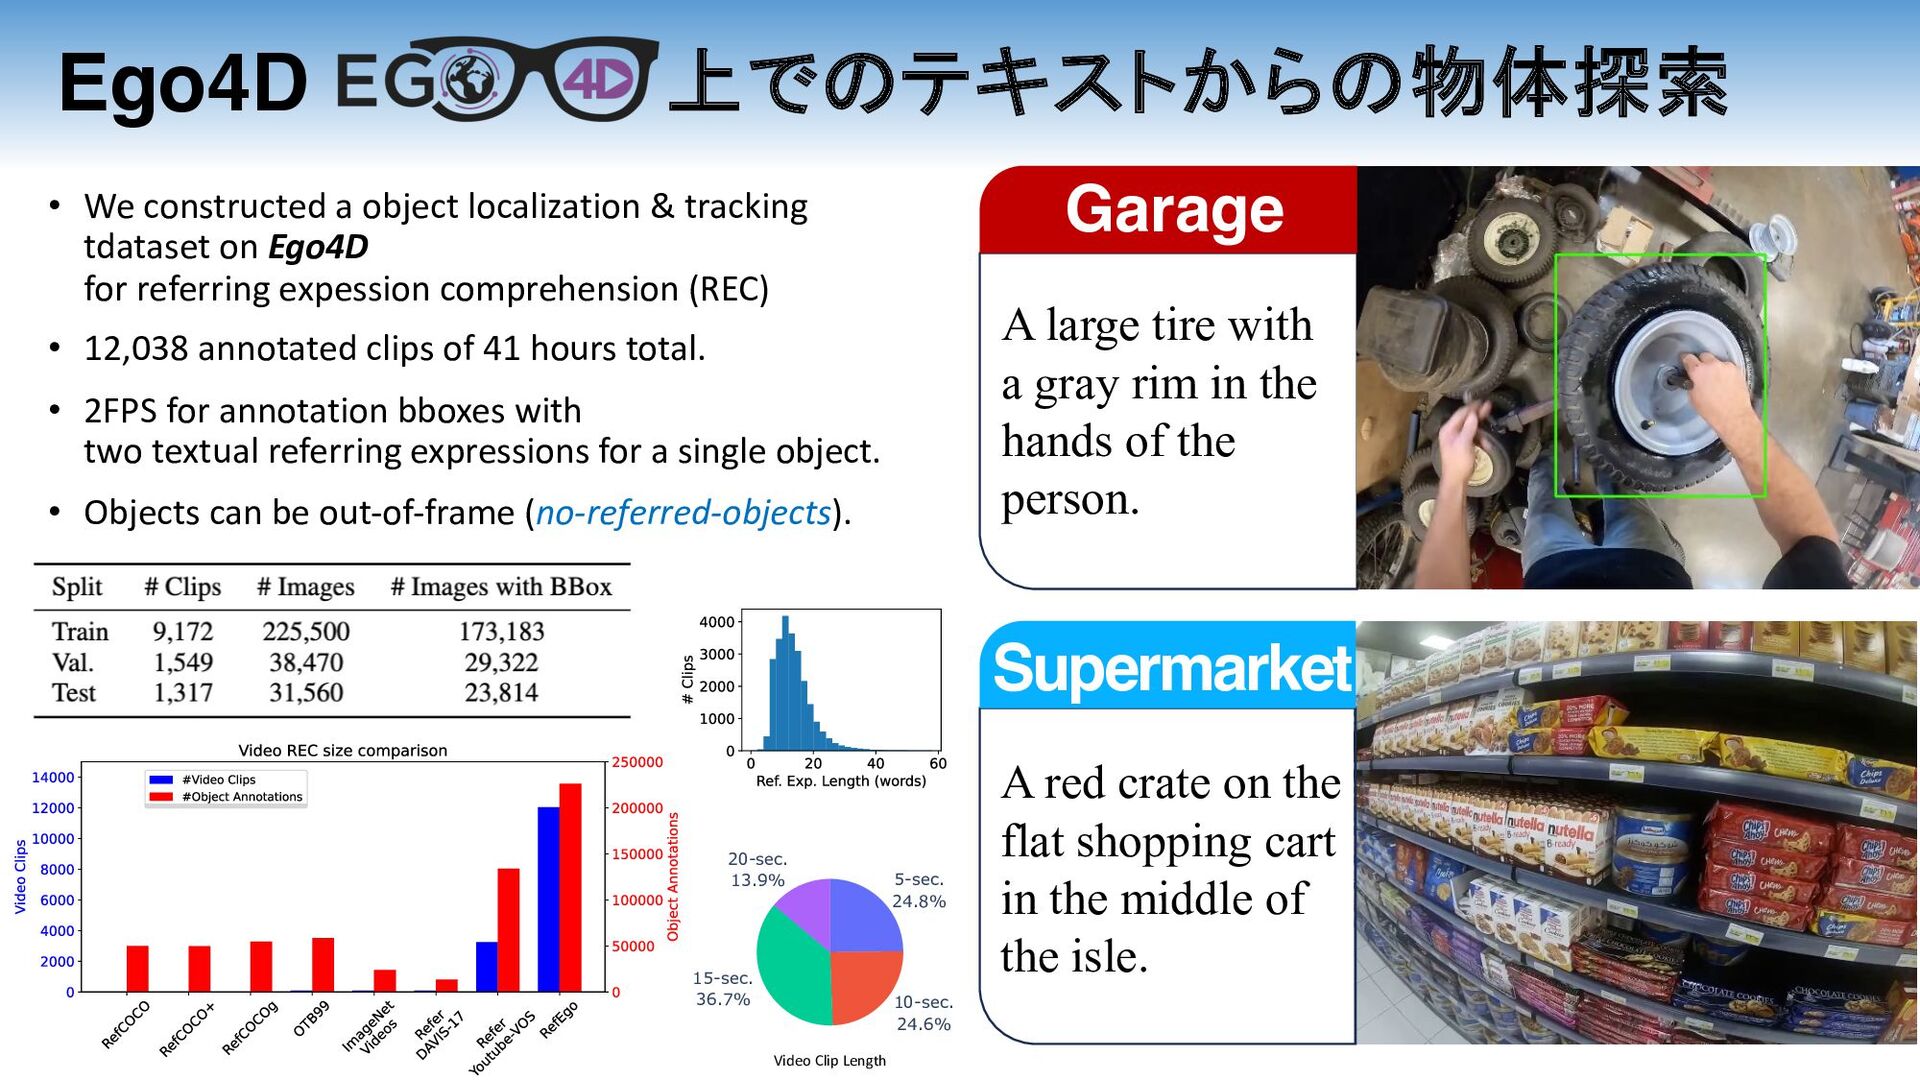
Ego4D 上でのテキストからの物体探索 5-sec. 24.8% 10-sec. 24.6% 15-sec. 36.7% 20-sec. 13.9%
• We constructed a object localization & tracking tdataset on Ego4D for referring expession comprehension (REC) • 12,038 annotated clips of 41 hours total. • 2FPS for annotation bboxes with two textual referring expressions for a single object. • Objects can be out-of-frame (no-referred-objects). Video Clip Length A large tire with a gray rim in the hands of the person. A red crate on the flat shopping cart in the middle of the isle. Garage Supermarket -
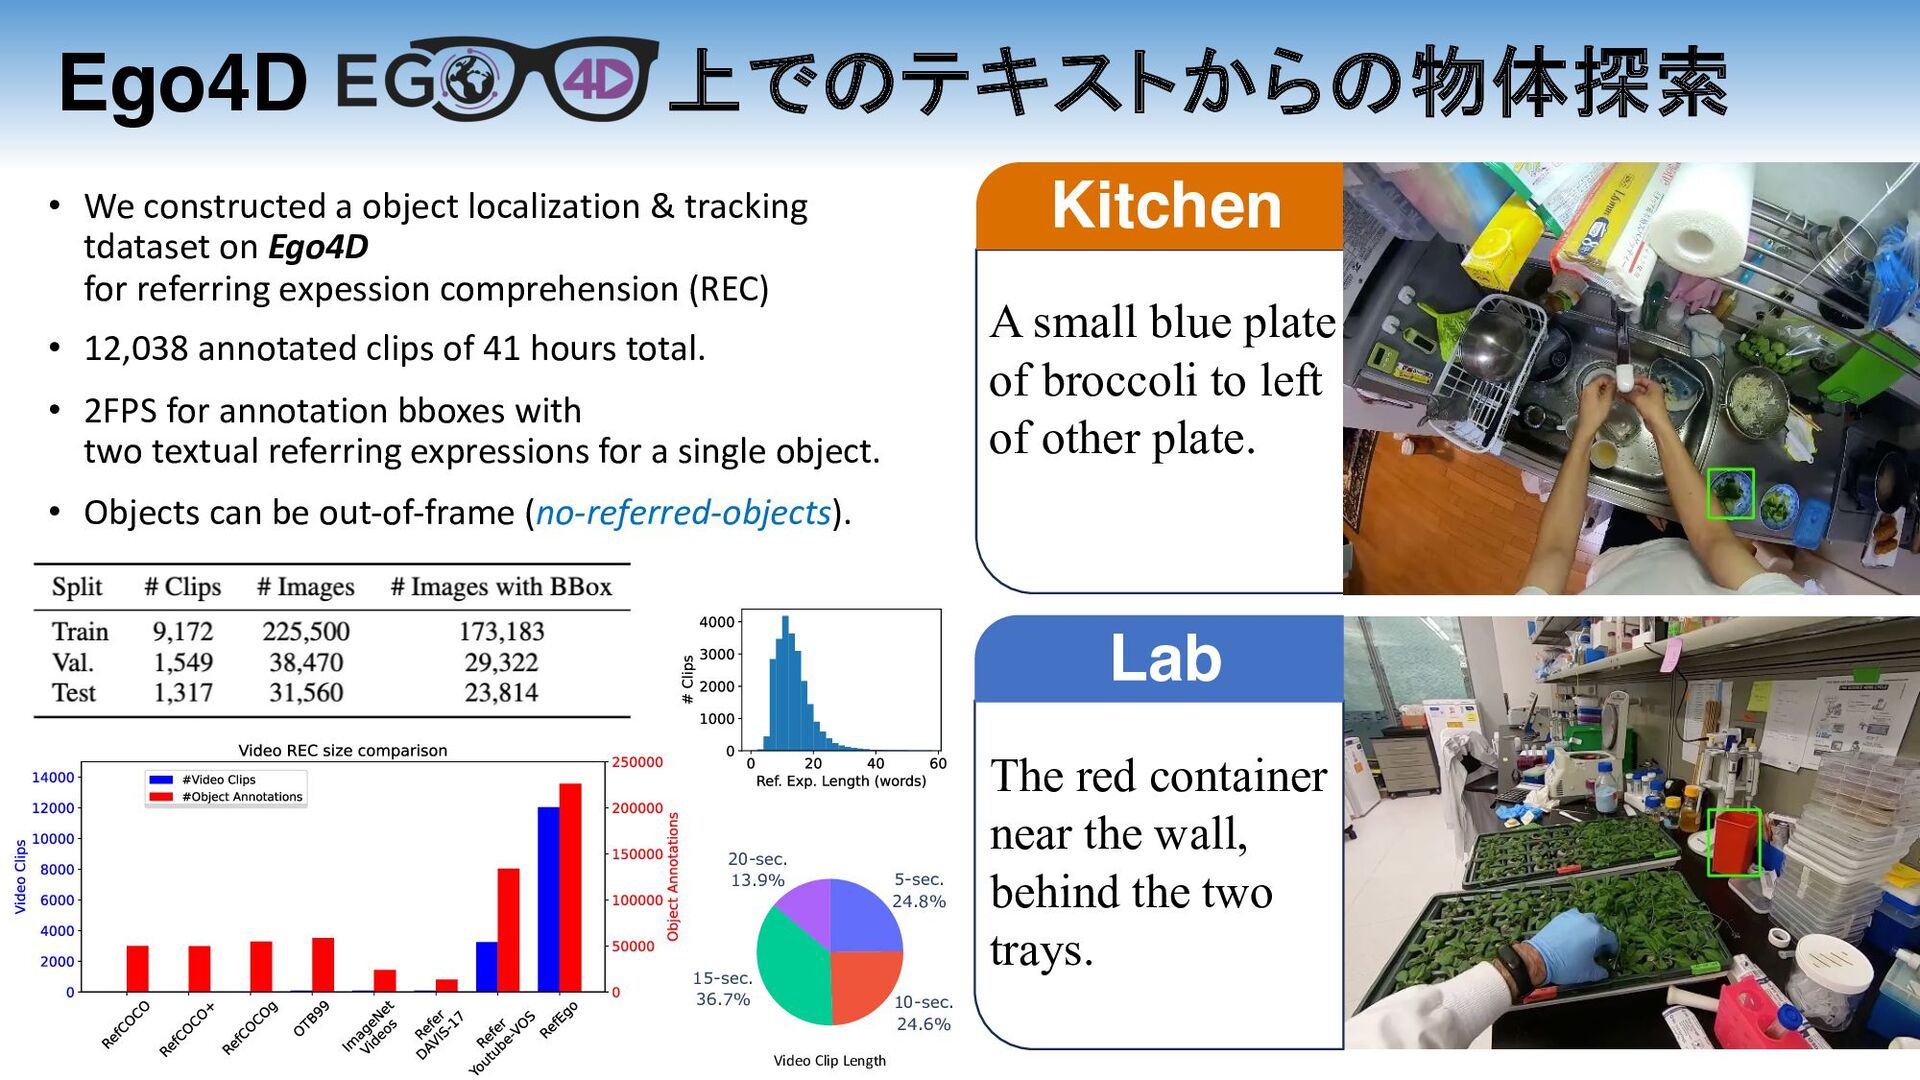
Ego4D 上でのテキストからの物体探索 29 A small blue plate of broccoli to
left of other plate. The red container near the wall, behind the two trays. Kitchen Lab 5-sec. 24.8% 10-sec. 24.6% 15-sec. 36.7% 20-sec. 13.9% • We constructed a object localization & tracking tdataset on Ego4D for referring expession comprehension (REC) • 12,038 annotated clips of 41 hours total. • 2FPS for annotation bboxes with two textual referring expressions for a single object. • Objects can be out-of-frame (no-referred-objects). Video Clip Length -
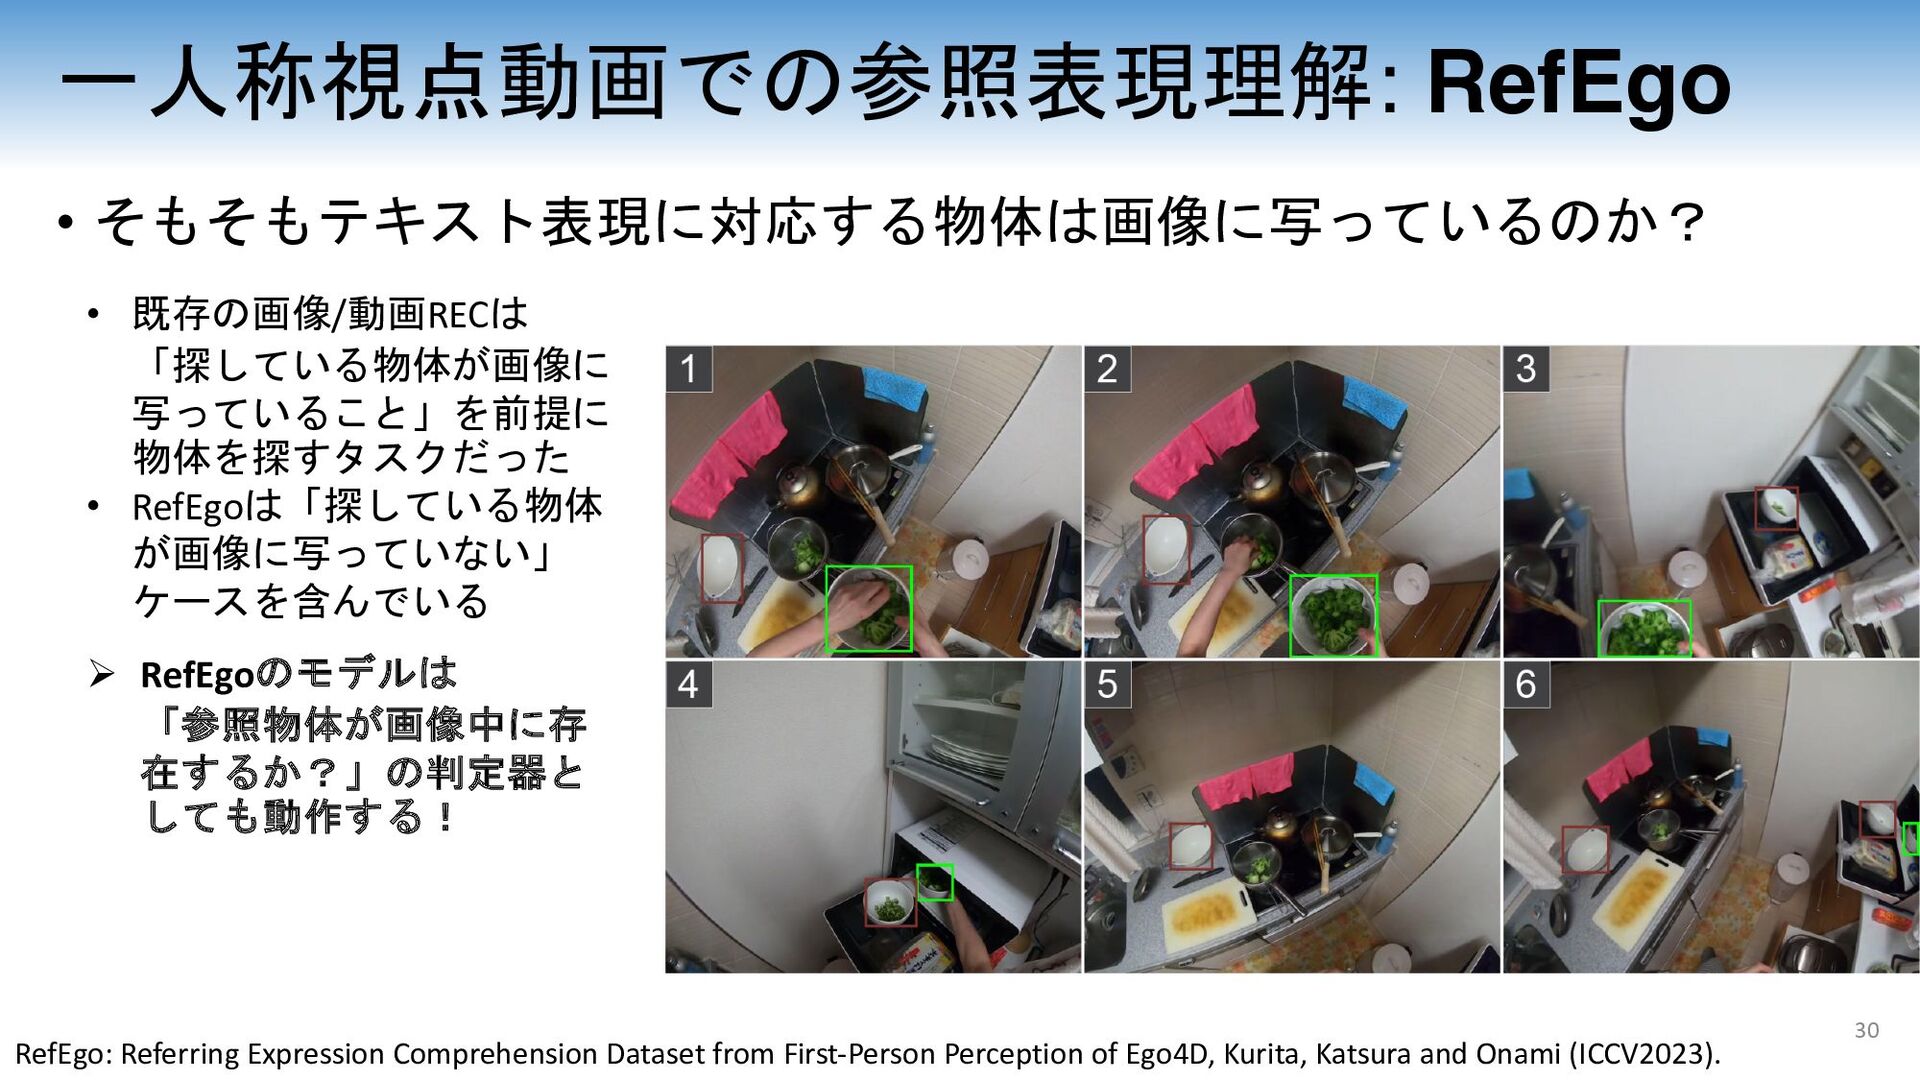
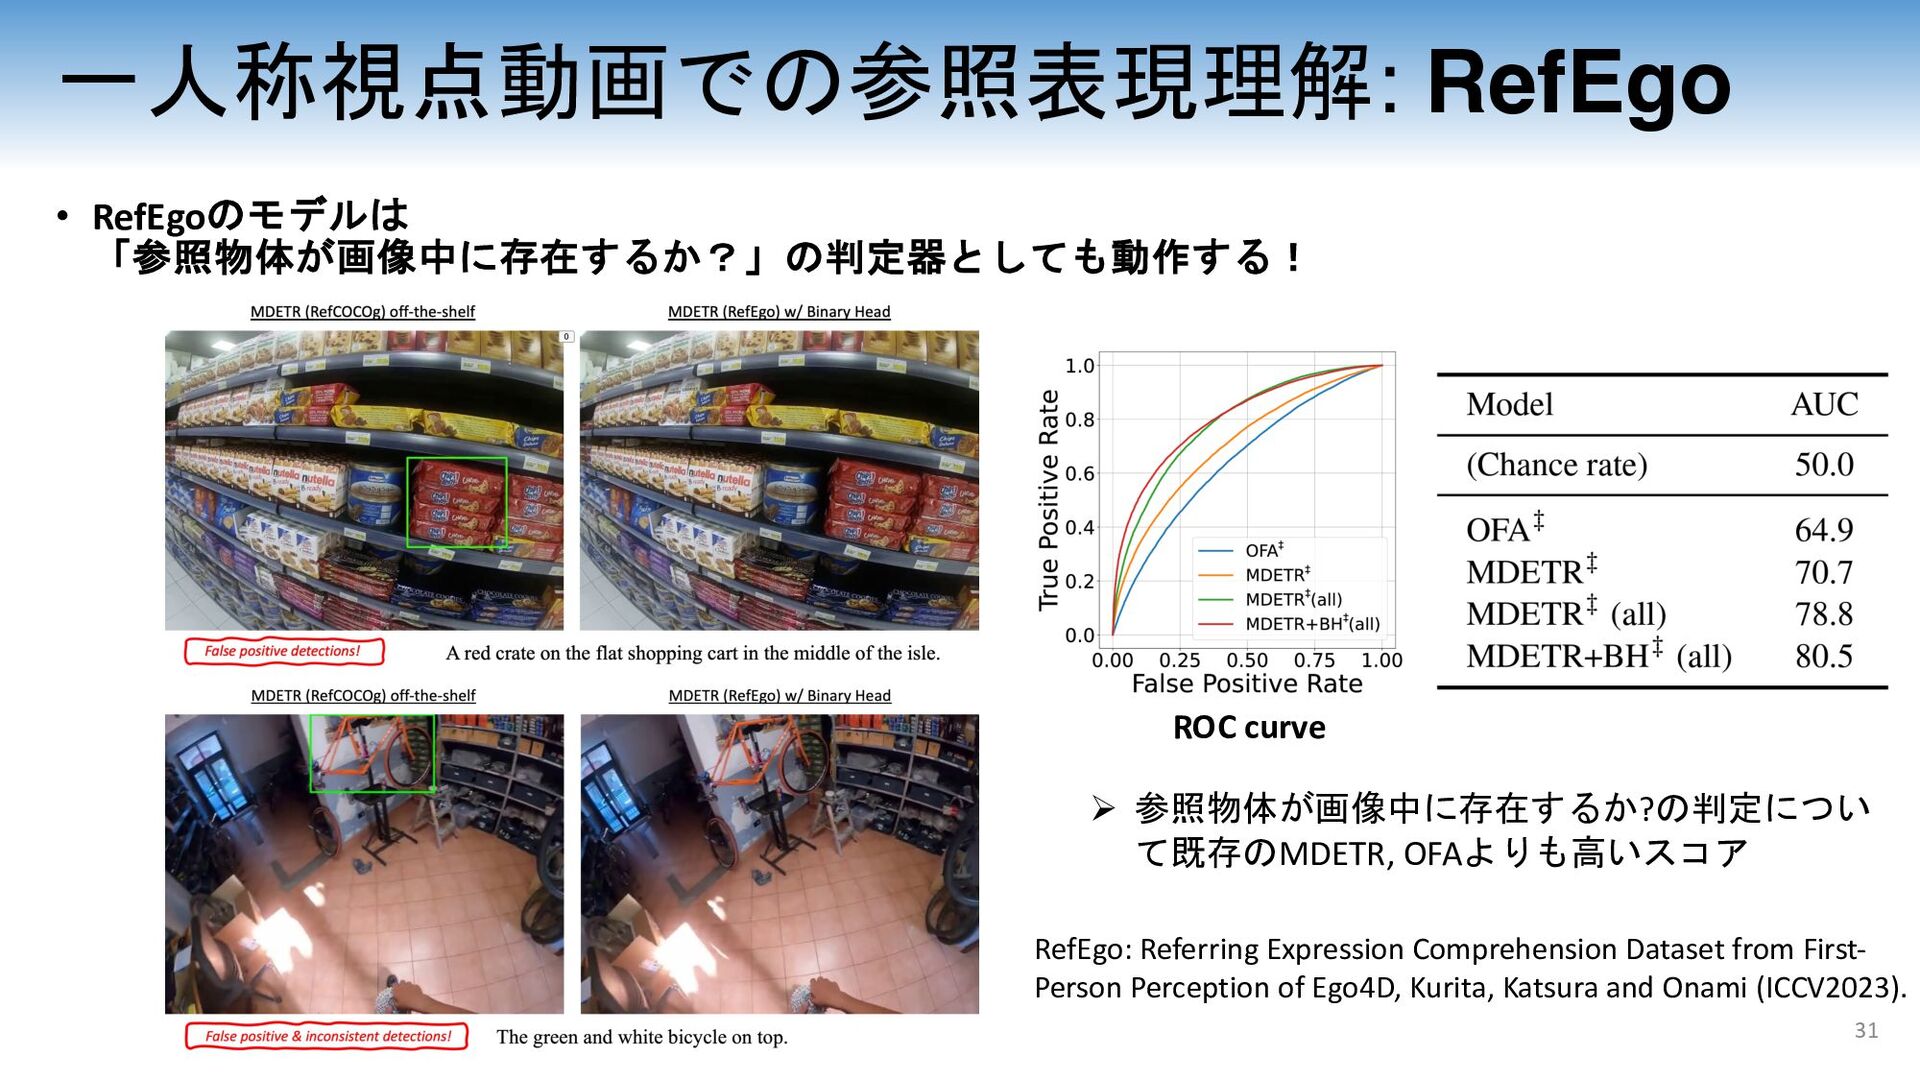
一人称視点動画での参照表現理解: RefEgo • そもそもテキスト表現に対応する物体は画像に写っているのか? 30 • 既存の画像/動画RECは 「探している物体が画像に 写っていること」を前提に 物体を探すタスクだった
• RefEgoは「探している物体 が画像に写っていない」 ケースを含んでいる Ø RefEgoのモデルは 「参照物体が画像中に存 在するか?」の判定器と しても動作する! RefEgo: Referring Expression Comprehension Dataset from First-Person Perception of Ego4D, Kurita, Katsura and Onami (ICCV2023). -
一人称視点動画での参照表現理解: RefEgo • RefEgoのモデルは 「参照物体が画像中に存在するか?」の判定器としても動作する! 31 RefEgo: Referring Expression Comprehension
Dataset from First- Person Perception of Ego4D, Kurita, Katsura and Onami (ICCV2023). Ø 参照物体が画像中に存在するか?の判定につい て既存のMDETR, OFAよりも高いスコア ROC curve -
目次 1. 言語と画像や動画の詳細な対応付け技術 1. IC, VQA, SceneGraph, DenceCaptioning 2. 参照表現理解
(Referring Expression Comprehension) 3. 対照学習(Contrastive learning) 4. 参照表現理解(REC) とオープン語彙物体検出(OVOD) 5. 動画からの参照表現理解: RefEgo 2. 言語理解技術の物理的な実世界応用 1. Vision-and-language navigation 2. Robotics and language 32 -
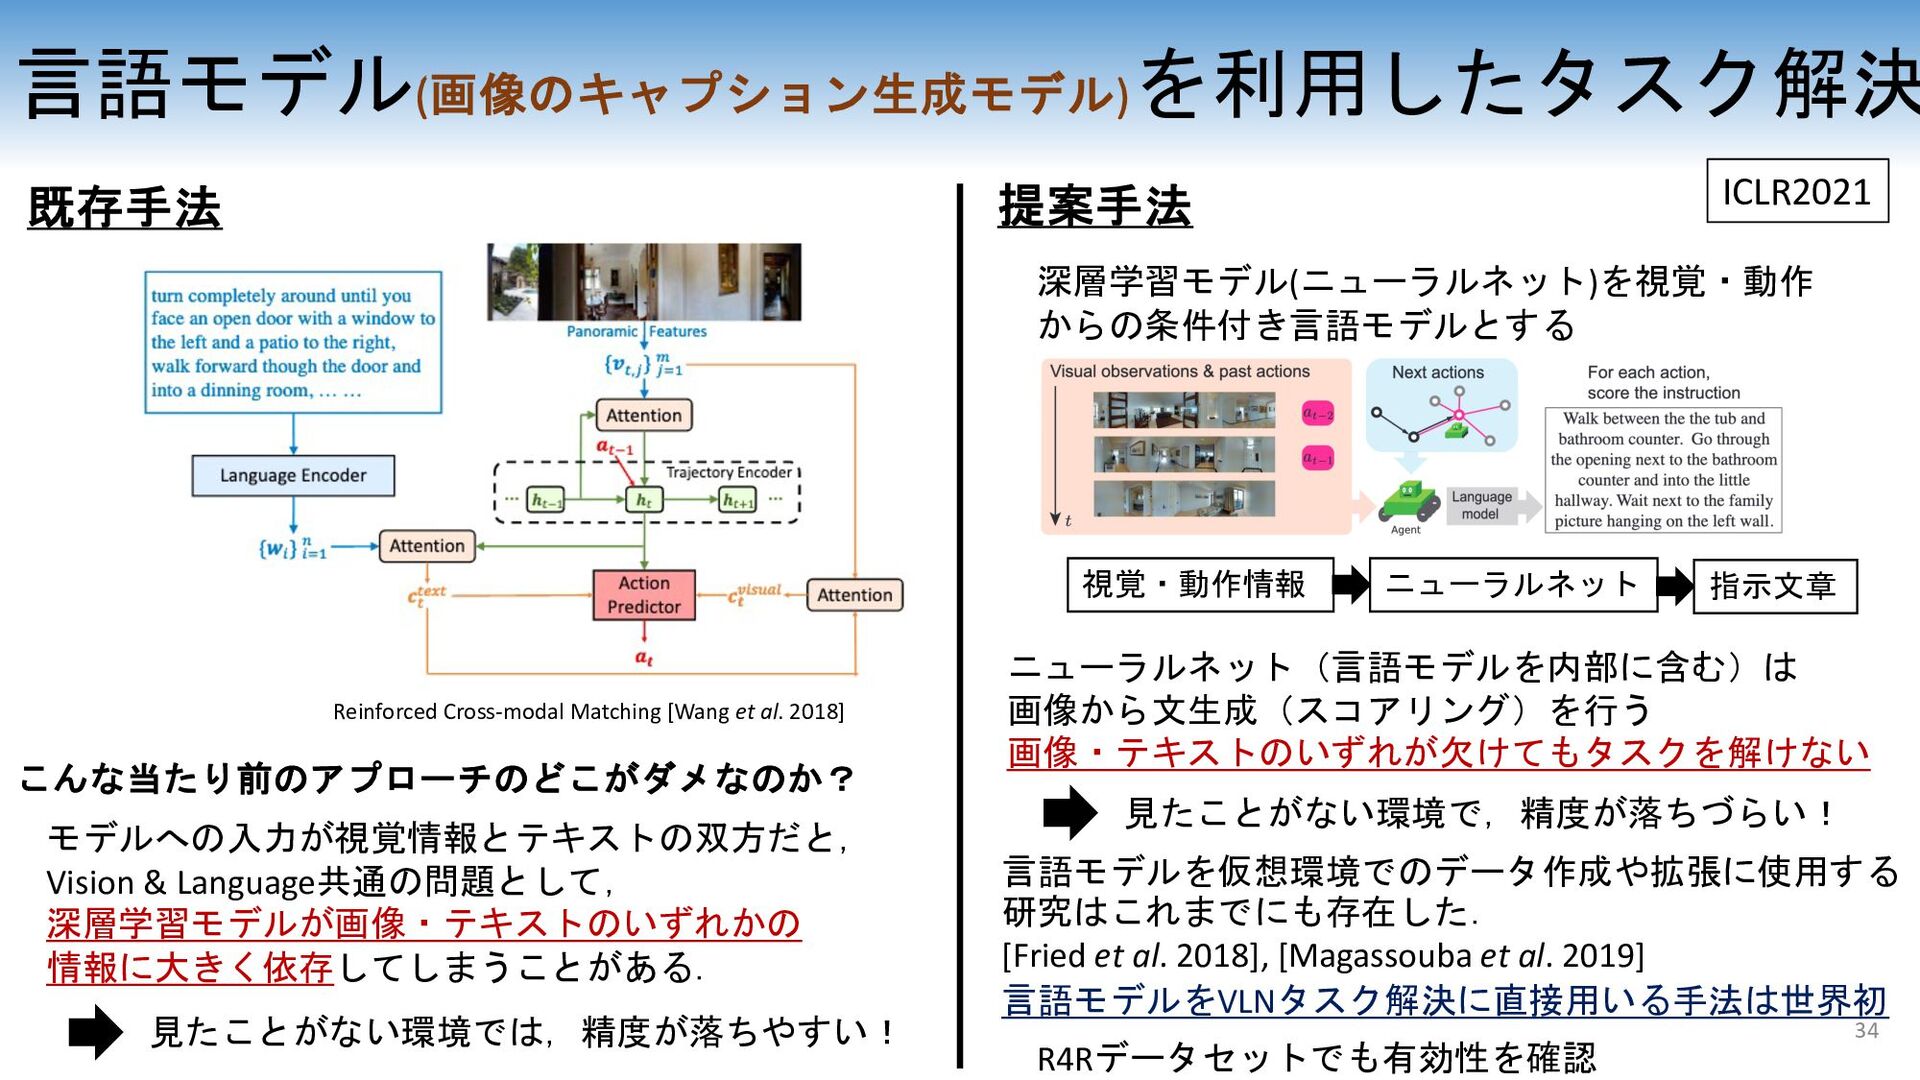
言語モデル(画像のキャプション生成モデル) を利用したタスク解決 言語モデルをVLNタスク解決に直接用いる手法は世界初 既存手法 提案手法 こんな当たり前のアプローチのどこがダメなのか? モデルへの入力が視覚情報とテキストの双方だと, Vision & Language共通の問題として,
深層学習モデルが画像・テキストのいずれかの 情報に大きく依存してしまうことがある. 見たことがない環境では,精度が落ちやすい! Reinforced Cross-modal Matching [Wang et al. 2018] 見たことがない環境で,精度が落ちづらい! 深層学習モデル(ニューラルネット)を視覚・動作 からの条件付き言語モデルとする ニューラルネット(言語モデルを内部に含む)は 画像から文生成(スコアリング)を行う 画像・テキストのいずれが欠けてもタスクを解けない 言語モデルを仮想環境でのデータ作成や拡張に使用する 研究はこれまでにも存在した. [Fried et al. 2018], [Magassouba et al. 2019] 視覚・動作情報 ニューラルネット 指示文章 R4Rデータセットでも有効性を確認 ICLR2021 34 -
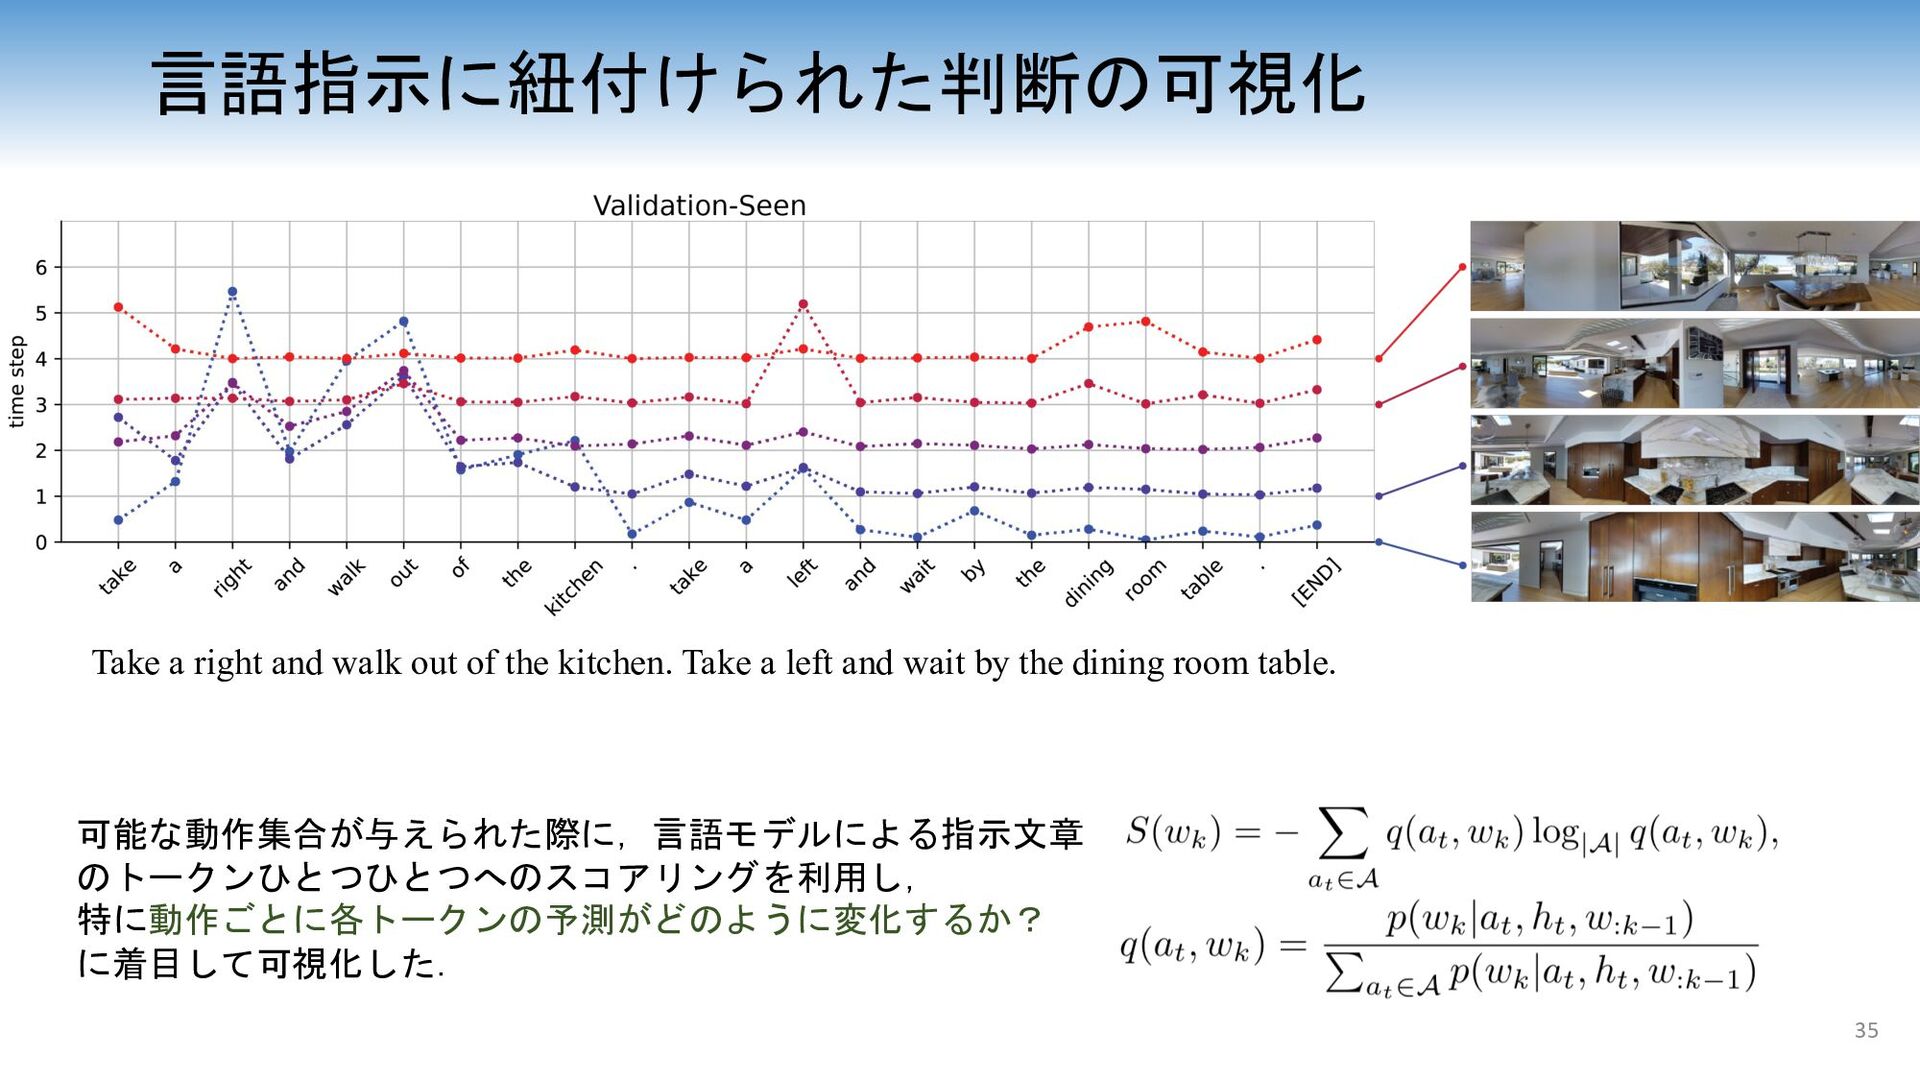
Take a right and walk out of the kitchen. Take
a left and wait by the dining room table. 言語指示に紐付けられた判断の可視化 可能な動作集合が与えられた際に,言語モデルによる指示文章 のトークンひとつひとつへのスコアリングを利用し, 特に動作ごとに各トークンの予測がどのように変化するか? に着目して可視化した. 35 -
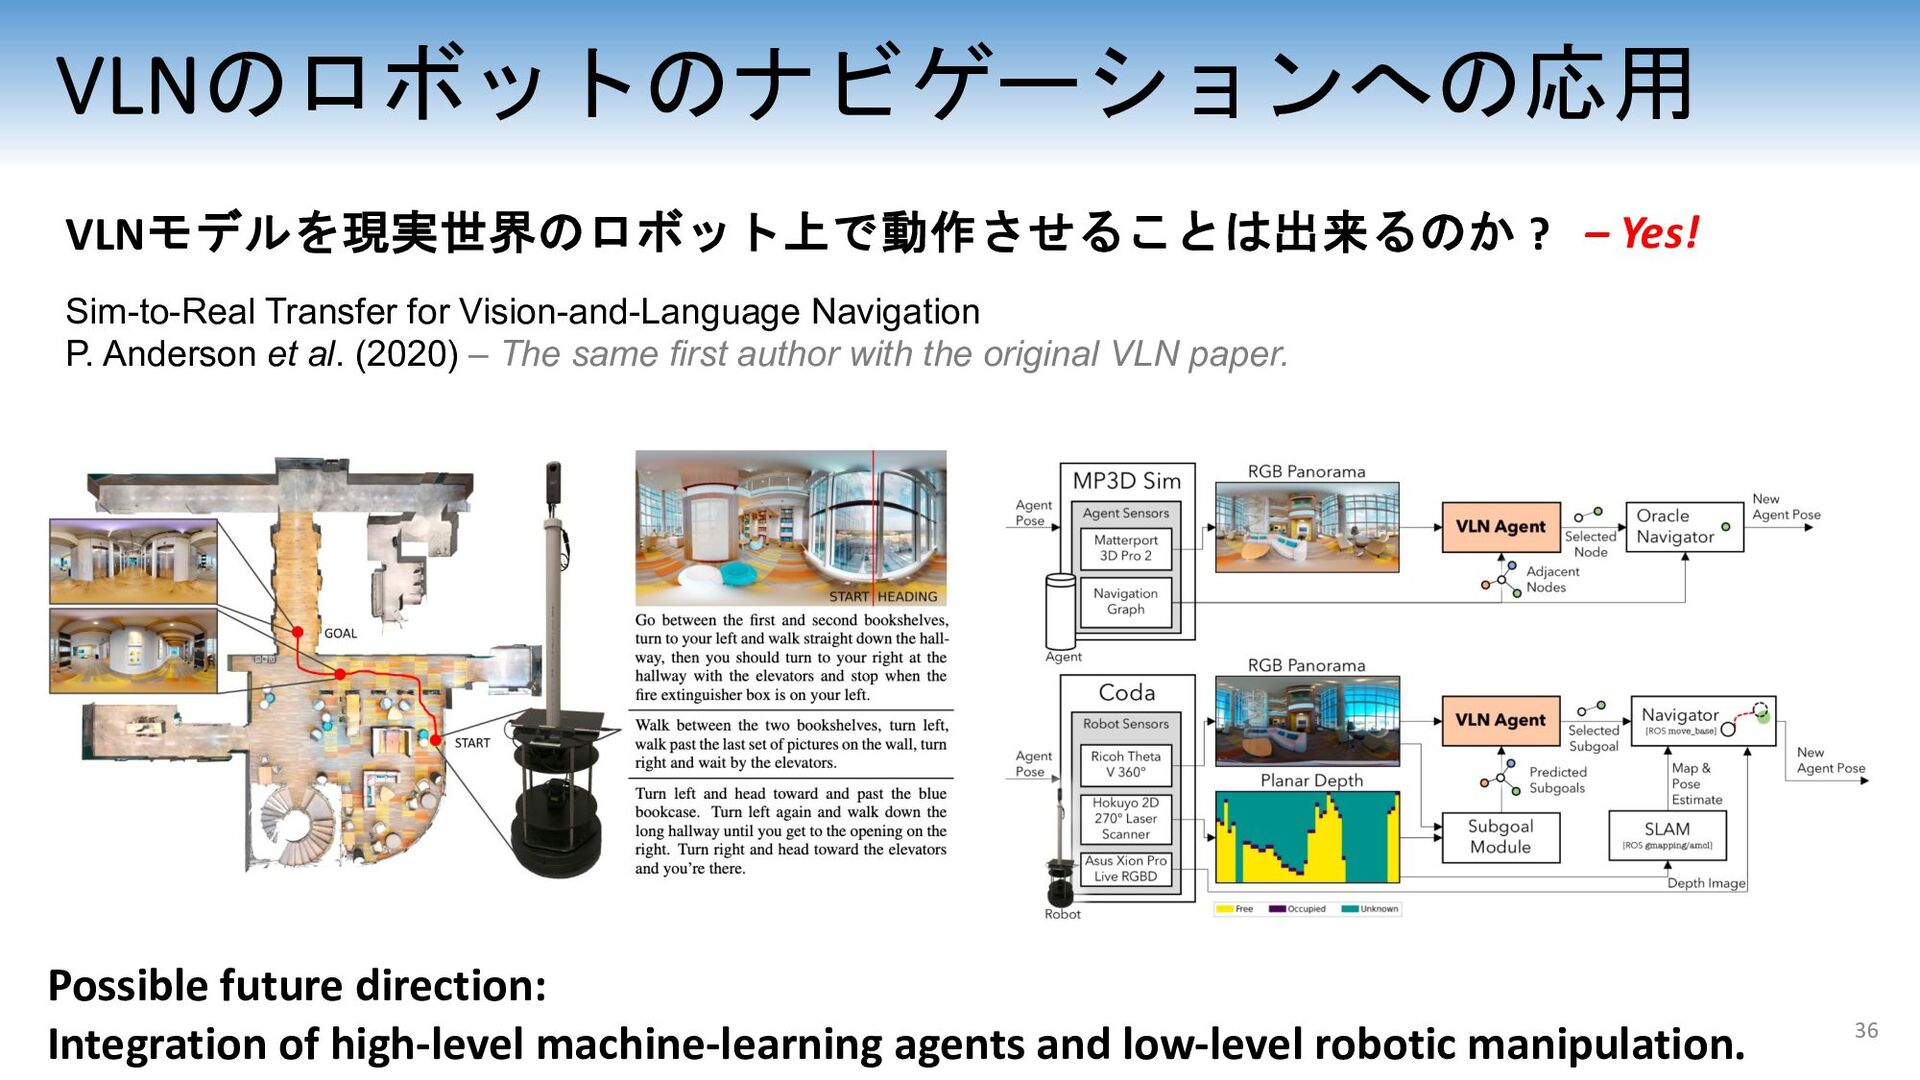
VLNのロボットのナビゲーションへの応用 VLNモデルを現実世界のロボット上で動作させることは出来るのか ? Sim-to-Real Transfer for Vision-and-Language Navigation P. Anderson
et al. (2020) – The same first author with the original VLN paper. Possible future direction: Integration of high-level machine-learning agents and low-level robotic manipulation. – Yes! 36 -
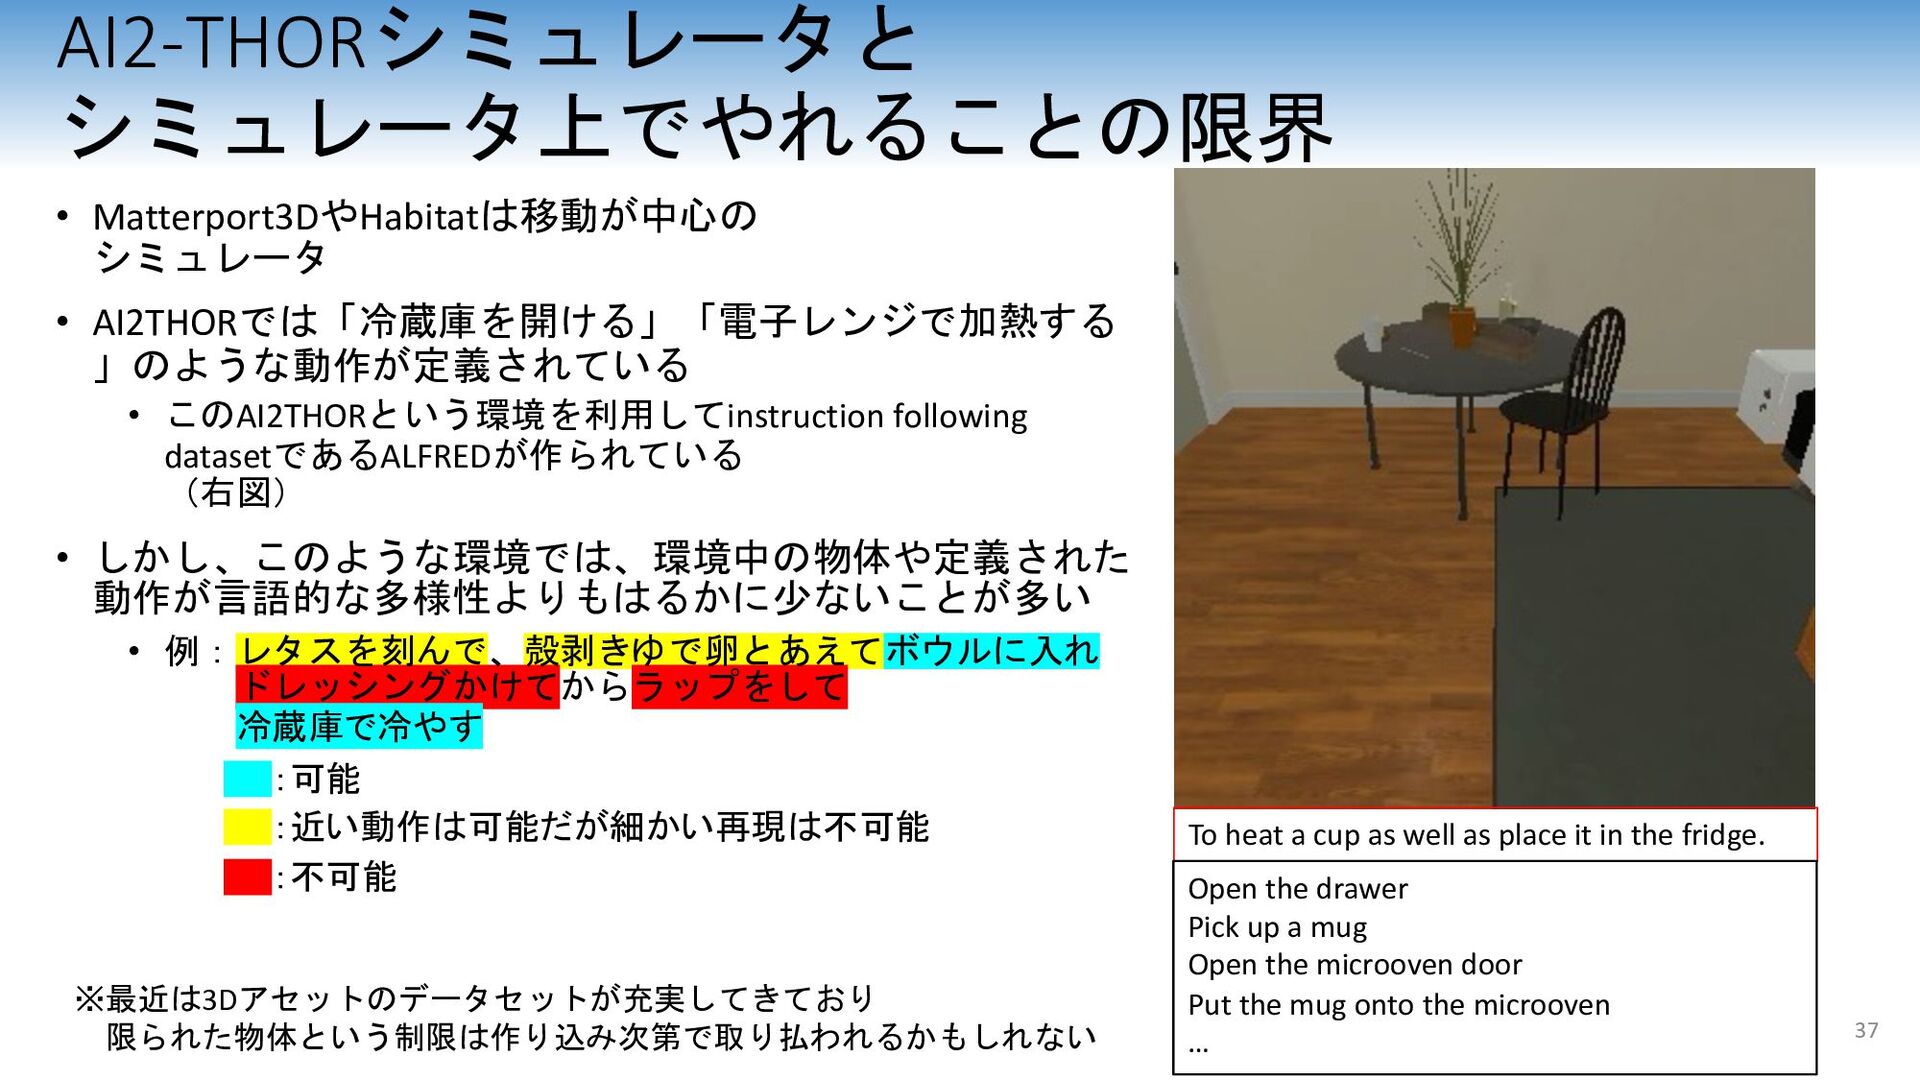
AI2-THORシミュレータと シミュレータ上でやれることの限界 • Matterport3DやHabitatは移動が中心の シミュレータ • AI2THORでは「冷蔵庫を開ける」「電子レンジで加熱する 」のような動作が定義されている • このAI2THORという環境を利用してinstruction
following datasetであるALFREDが作られている (右図) • しかし、このような環境では、環境中の物体や定義された 動作が言語的な多様性よりもはるかに少ないことが多い • 例:レタスを刻んで、殻剥きゆで卵とあえてボウルに入れ ドレッシングかけてからラップをして 冷蔵庫で冷やす :可能 :近い動作は可能だが細かい再現は不可能 :不可能 To heat a cup as well as place it in the fridge. Open the drawer Pick up a mug Open the microoven door Put the mug onto the microoven … ※最近は3Dアセットのデータセットが充実してきており 限られた物体という制限は作り込み次第で取り払われるかもしれない 37 -
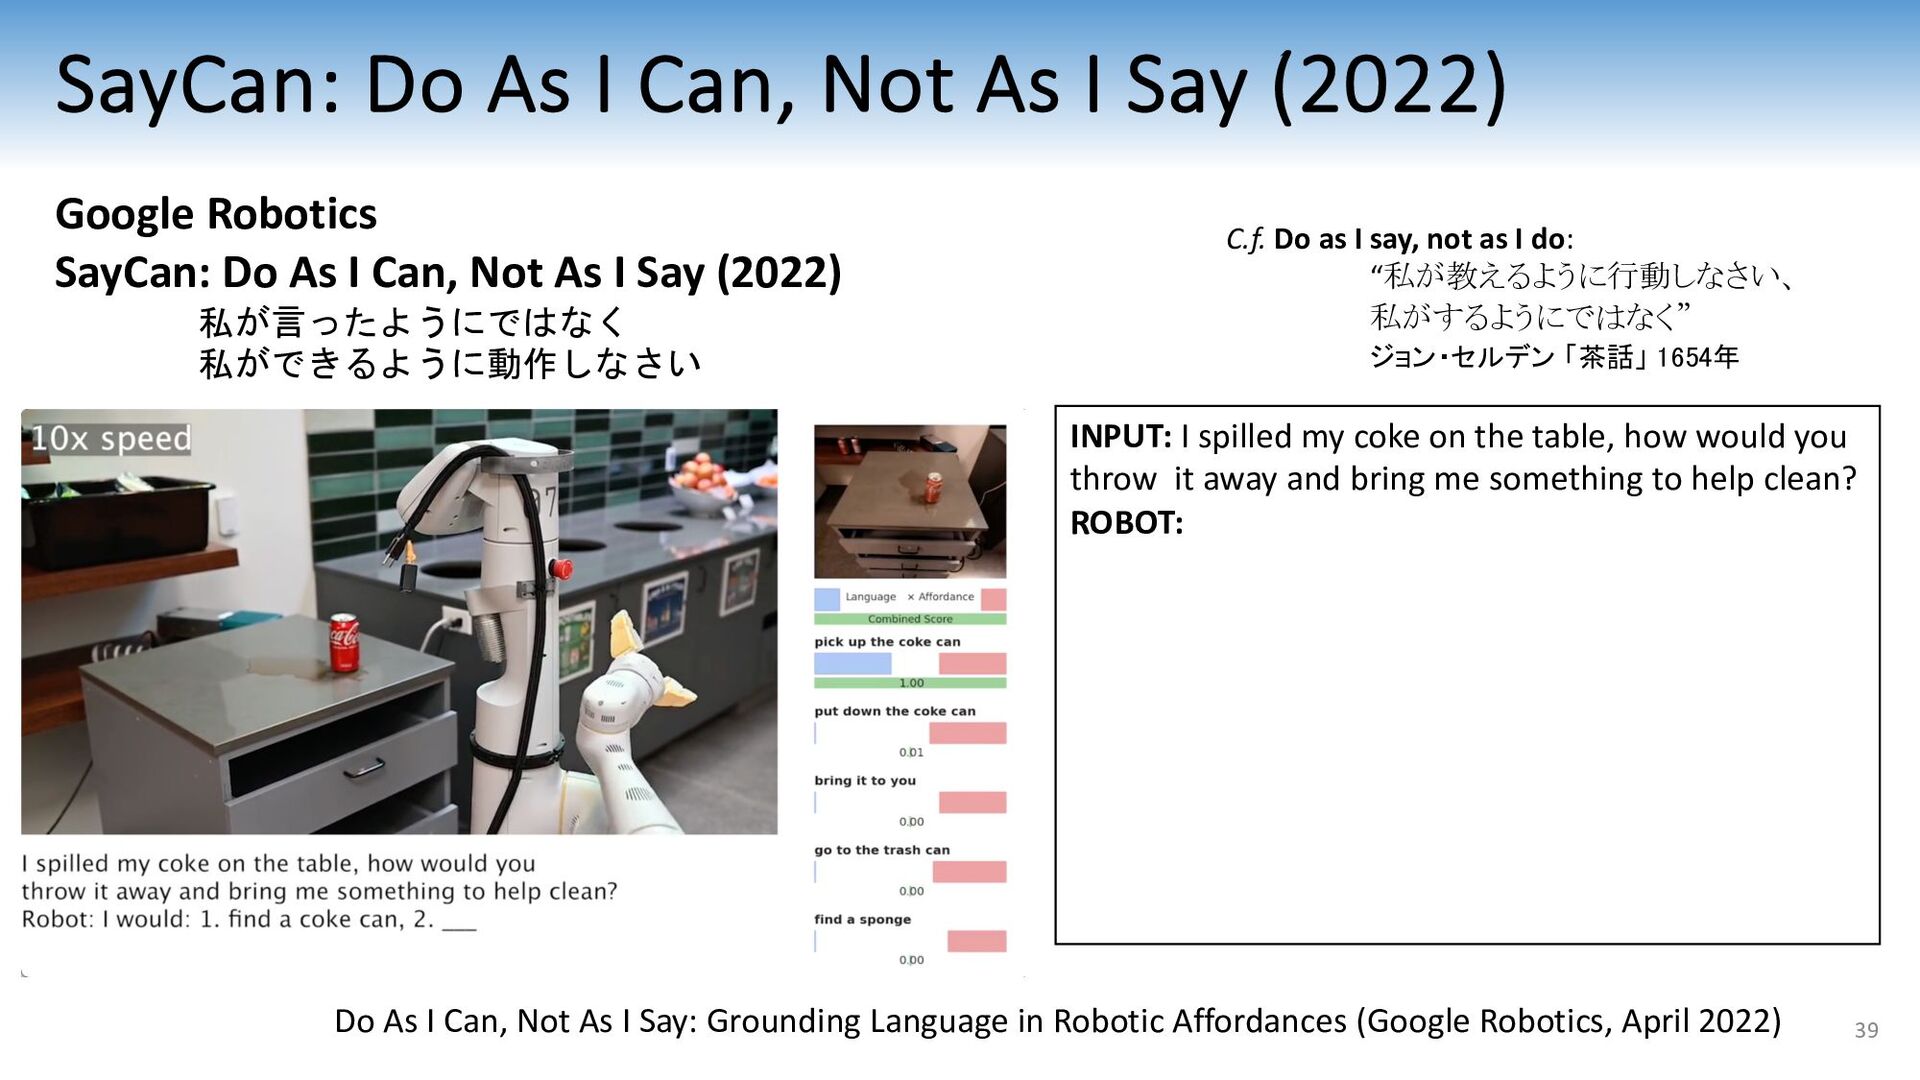
SayCan: Do As I Can, Not As I Say (2022)
C.f. Do as I say, not as I do: “私が教えるように行動しなさい、 私がするようにではなく” ジョン・セルデン 「茶話」 1654年 Do As I Can, Not As I Say: Grounding Language in Robotic Affordances (Google Robotics, April 2022) Google Robotics SayCan: Do As I Can, Not As I Say (2022) 私が言ったようにではなく 私ができるように動作しなさい INPUT: I spilled my coke on the table, how would you throw it away and bring me something to help clean? ROBOT: 39 -
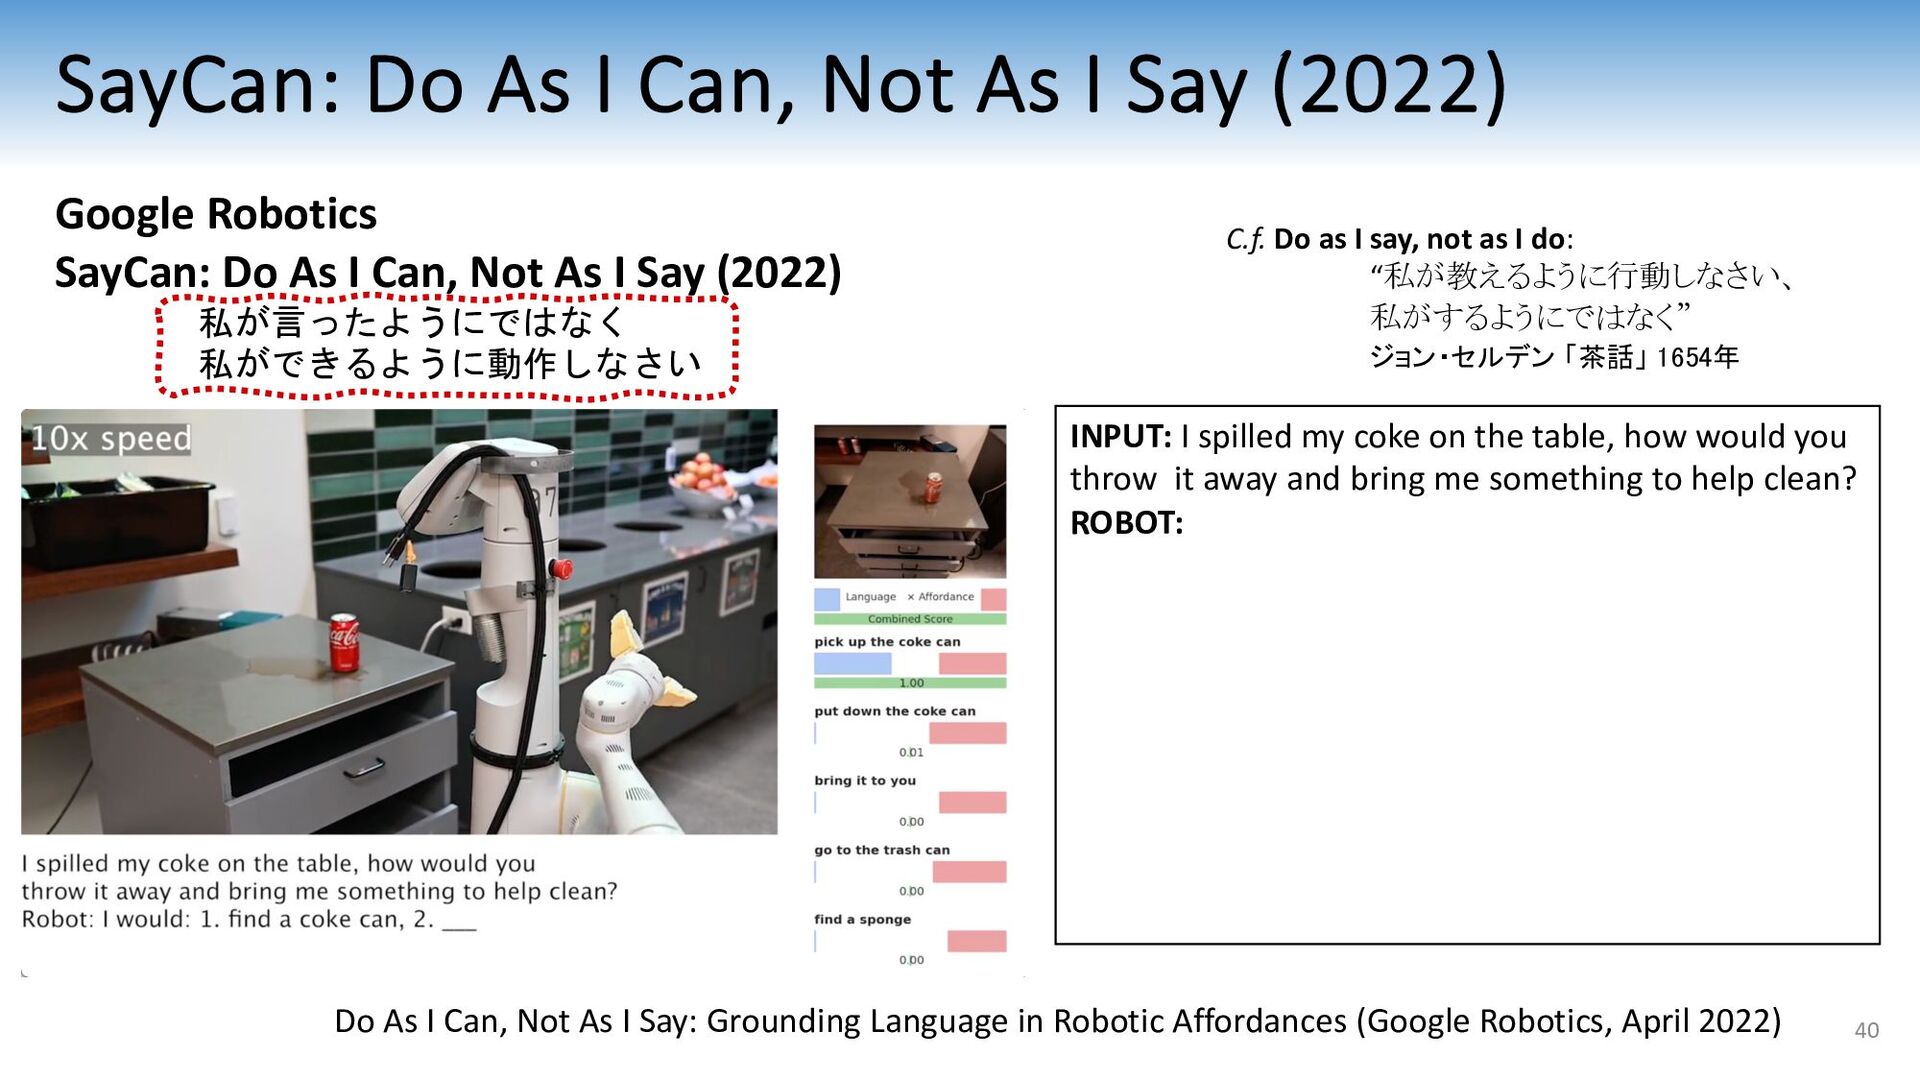
SayCan: Do As I Can, Not As I Say (2022)
C.f. Do as I say, not as I do: “私が教えるように行動しなさい、 私がするようにではなく” ジョン・セルデン 「茶話」 1654年 Do As I Can, Not As I Say: Grounding Language in Robotic Affordances (Google Robotics, April 2022) Google Robotics SayCan: Do As I Can, Not As I Say (2022) 私が言ったようにではなく 私ができるように動作しなさい INPUT: I spilled my coke on the table, how would you throw it away and bring me something to help clean? ROBOT: 40 -
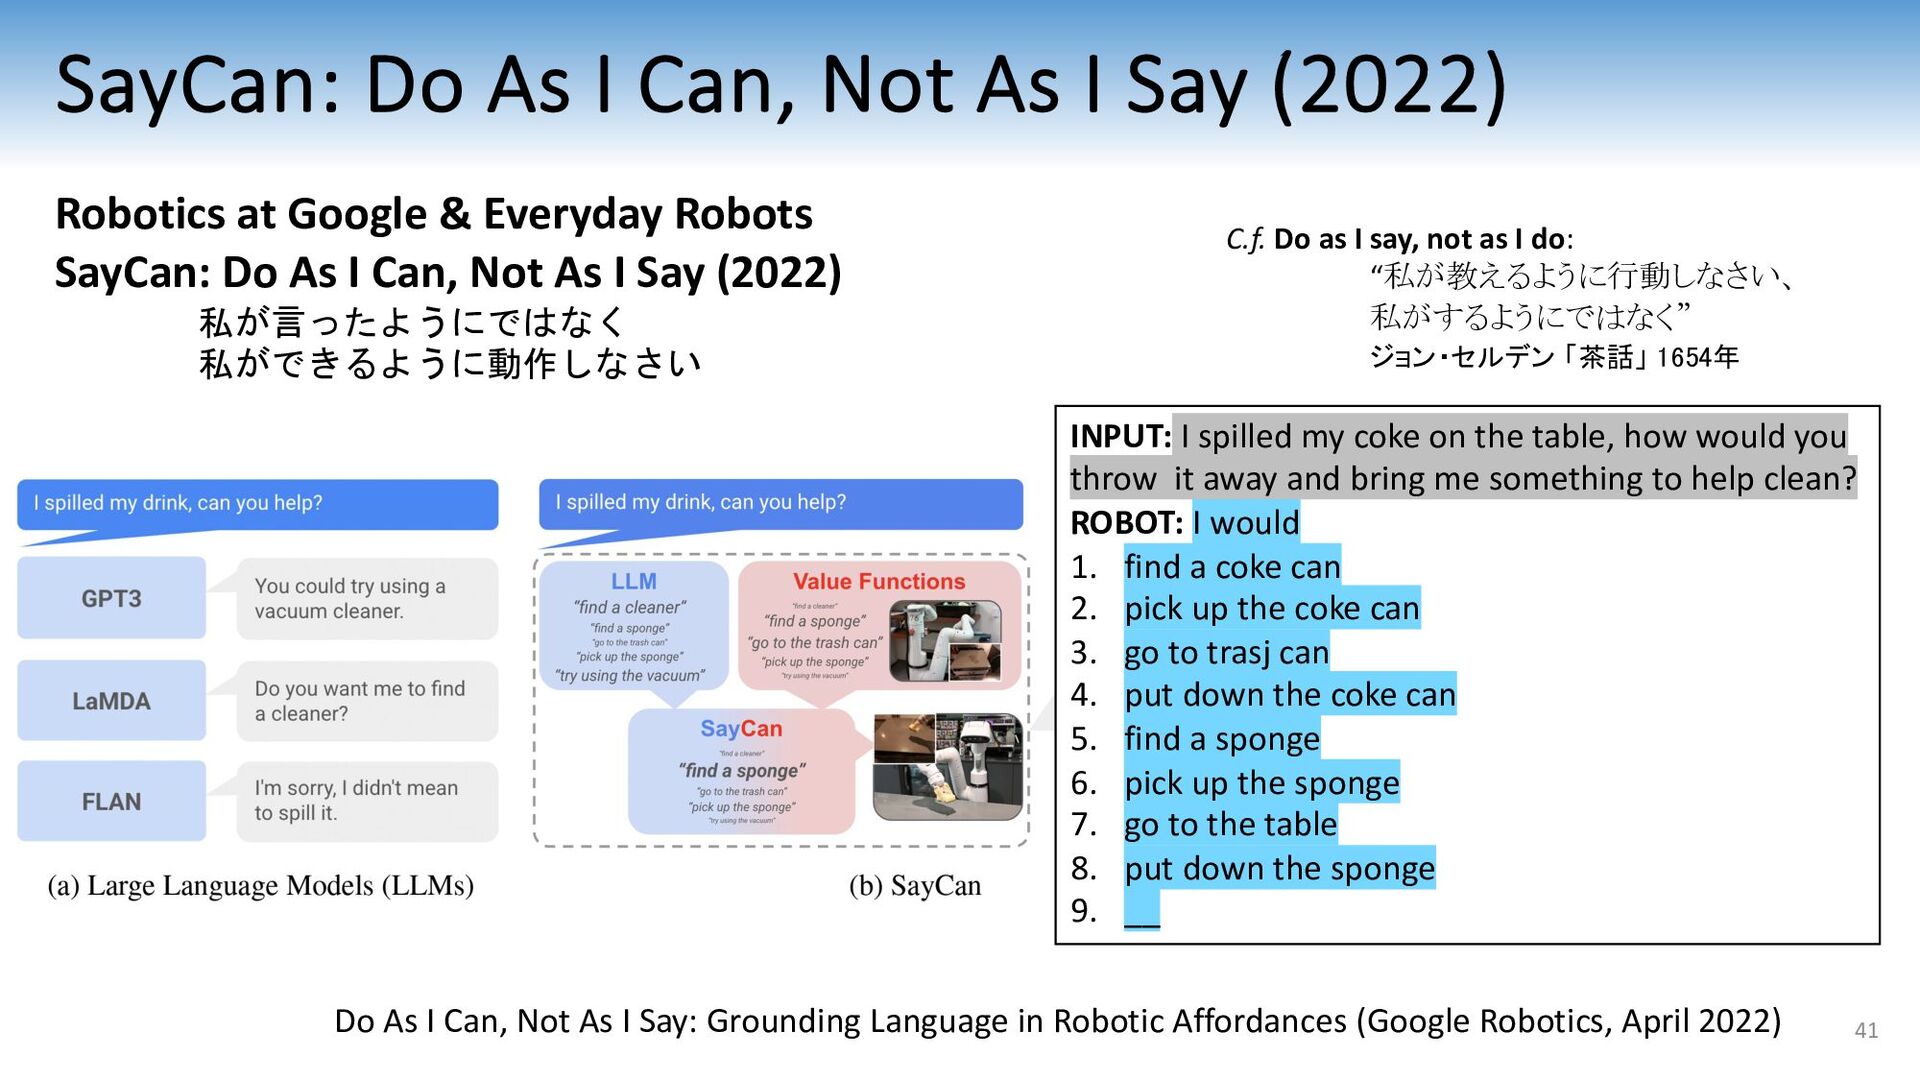
SayCan: Do As I Can, Not As I Say (2022)
C.f. Do as I say, not as I do: “私が教えるように行動しなさい、 私がするようにではなく” ジョン・セルデン 「茶話」 1654年 Do As I Can, Not As I Say: Grounding Language in Robotic Affordances (Google Robotics, April 2022) Robotics at Google & Everyday Robots SayCan: Do As I Can, Not As I Say (2022) 私が言ったようにではなく 私ができるように動作しなさい INPUT: I spilled my coke on the table, how would you throw it away and bring me something to help clean? ROBOT: I would 1. find a coke can 2. pick up the coke can 3. go to trasj can 4. put down the coke can 5. find a sponge 6. pick up the sponge 7. go to the table 8. put down the sponge 9. __ 41 -
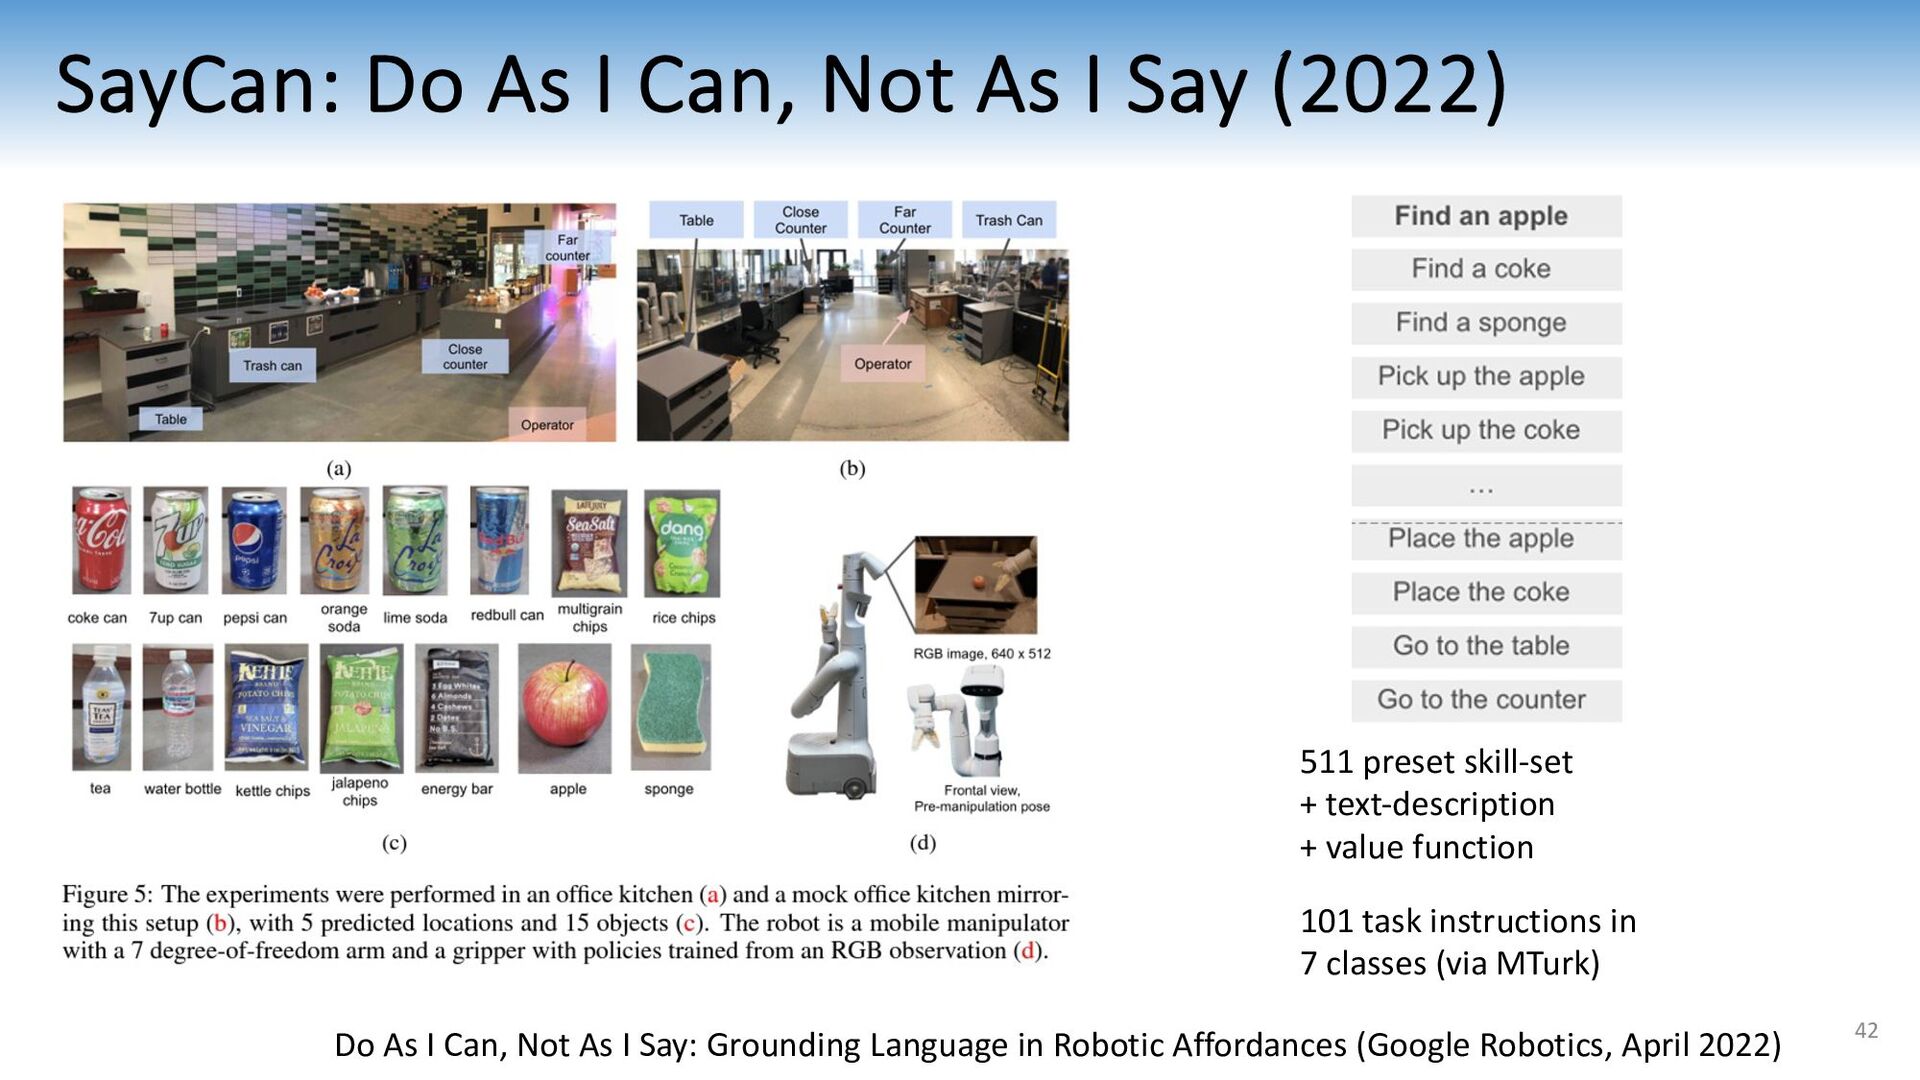
SayCan: Do As I Can, Not As I Say (2022)
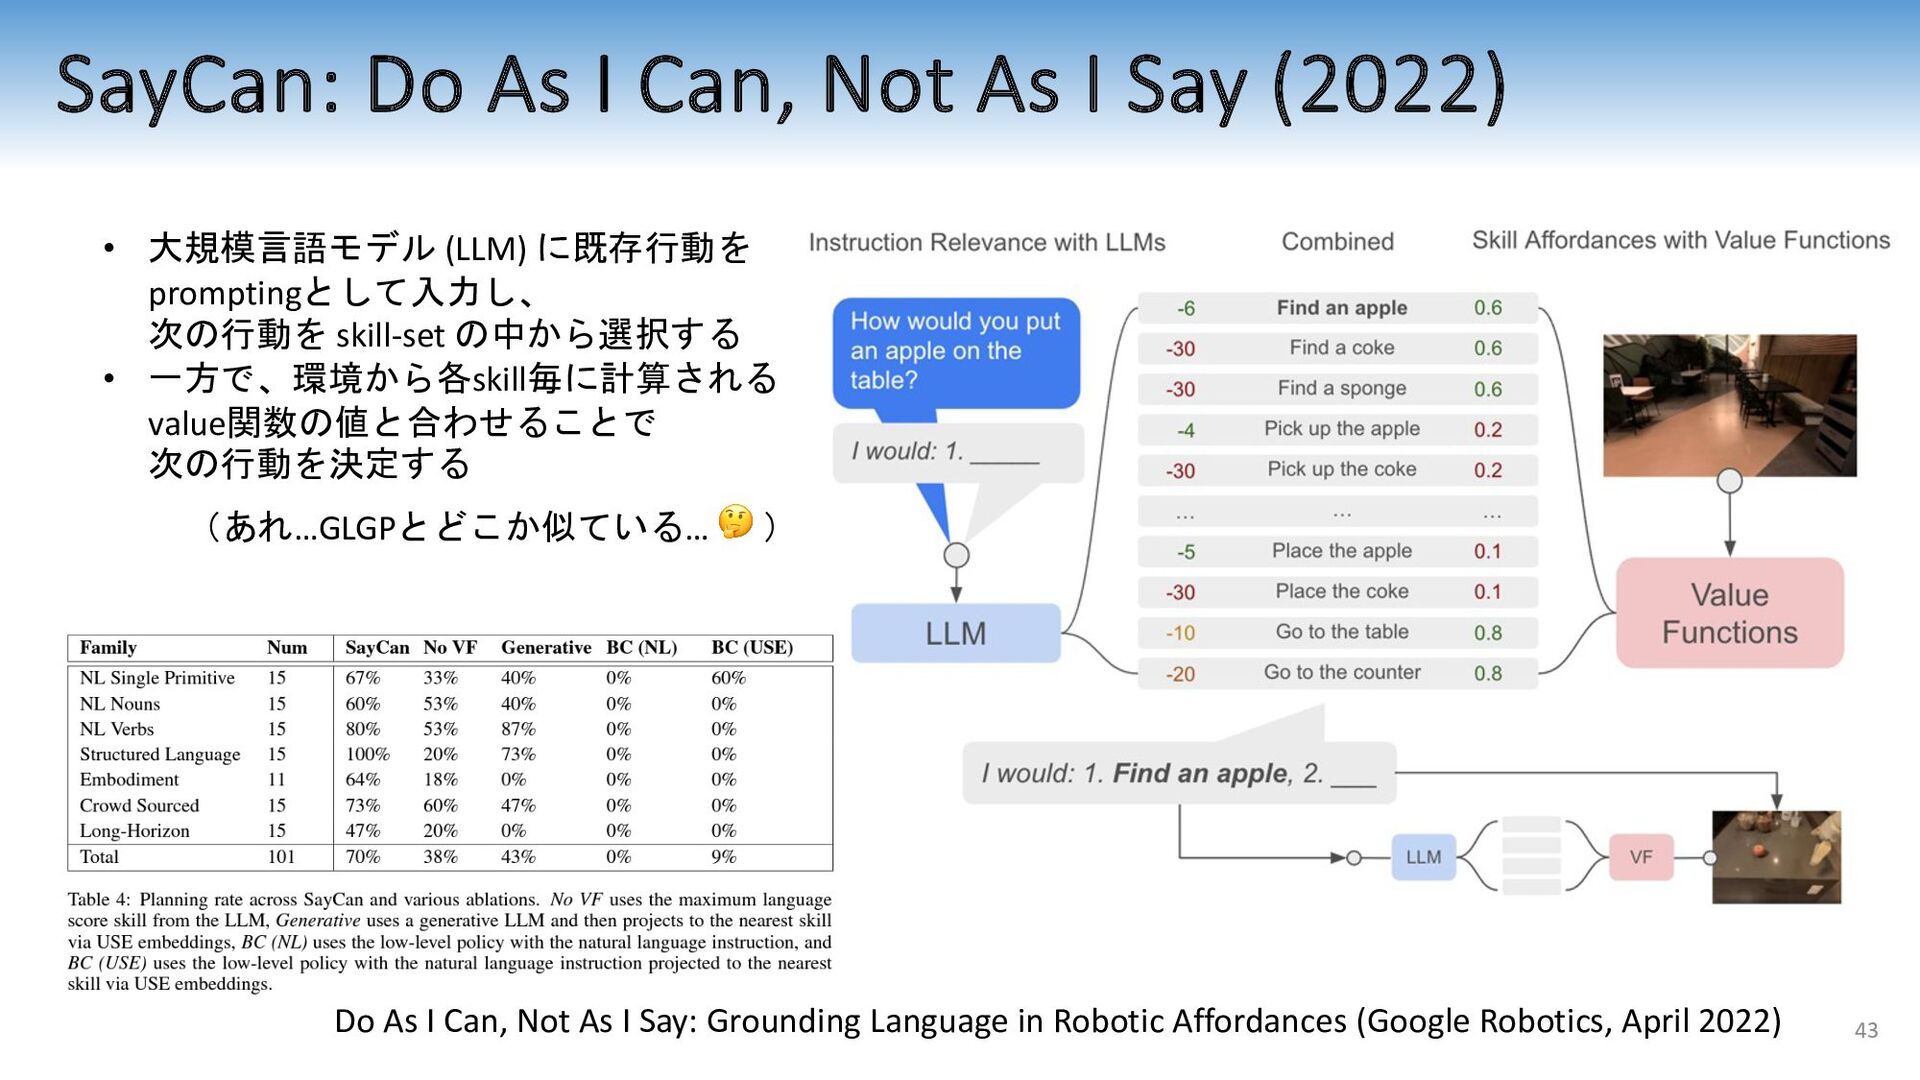
Do As I Can, Not As I Say: Grounding Language in Robotic Affordances (Google Robotics, April 2022) 511 preset skill-set + text-description + value function 101 task instructions in 7 classes (via MTurk) 42 -
SayCan: Do As I Can, Not As I Say (2022)
Do As I Can, Not As I Say: Grounding Language in Robotic Affordances (Google Robotics, April 2022) • 大規模言語モデル (LLM) に既存行動を promptingとして入力し、 次の行動を skill-set の中から選択する • 一方で、環境から各skill毎に計算される value関数の値と合わせることで 次の行動を決定する (あれ…GLGPとどこか似ている… 🤔 ) 43 -
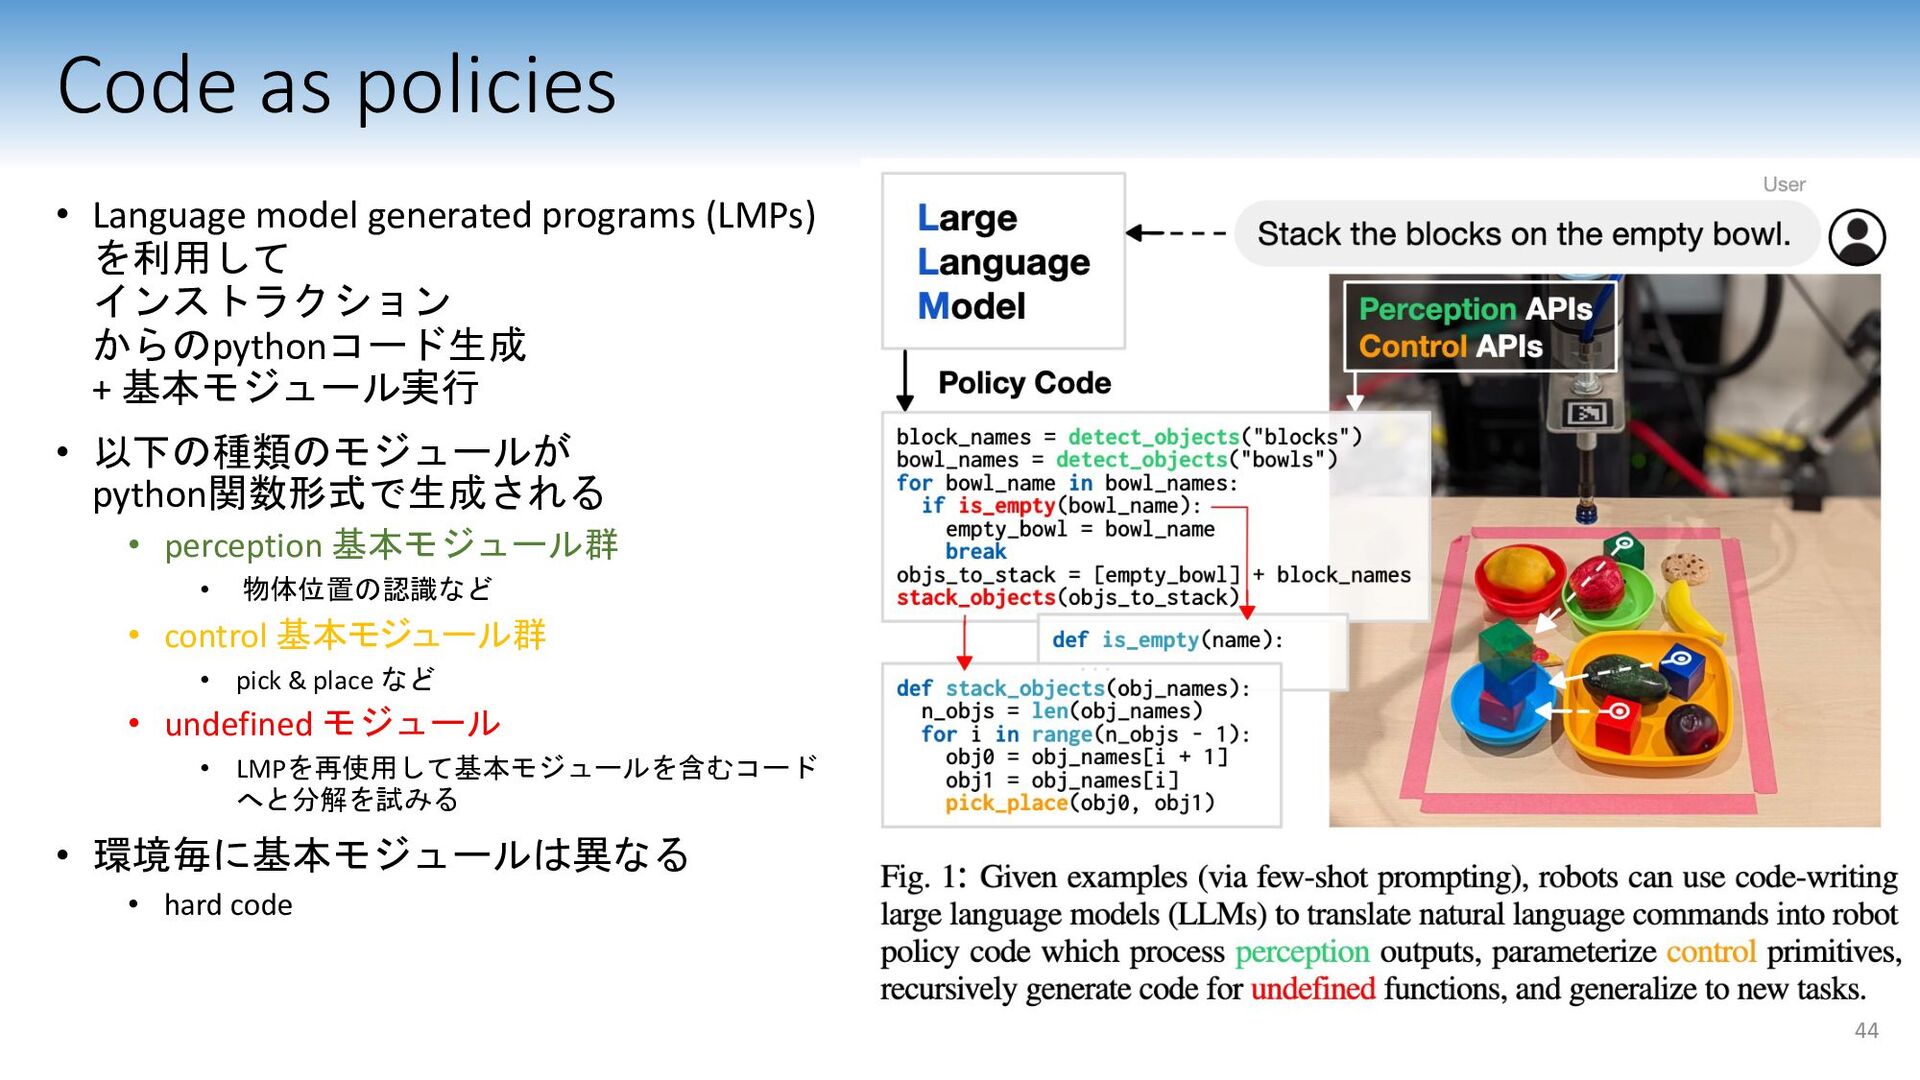
Code as policies • Language model generated programs (LMPs) を利用して
インストラクション からのpythonコード生成 + 基本モジュール実行 • 以下の種類のモジュールが python関数形式で生成される • perception 基本モジュール群 • 物体位置の認識など • control 基本モジュール群 • pick & place など • undefined モジュール • LMPを再使用して基本モジュールを含むコード へと分解を試みる • 環境毎に基本モジュールは異なる • hard code 44 -
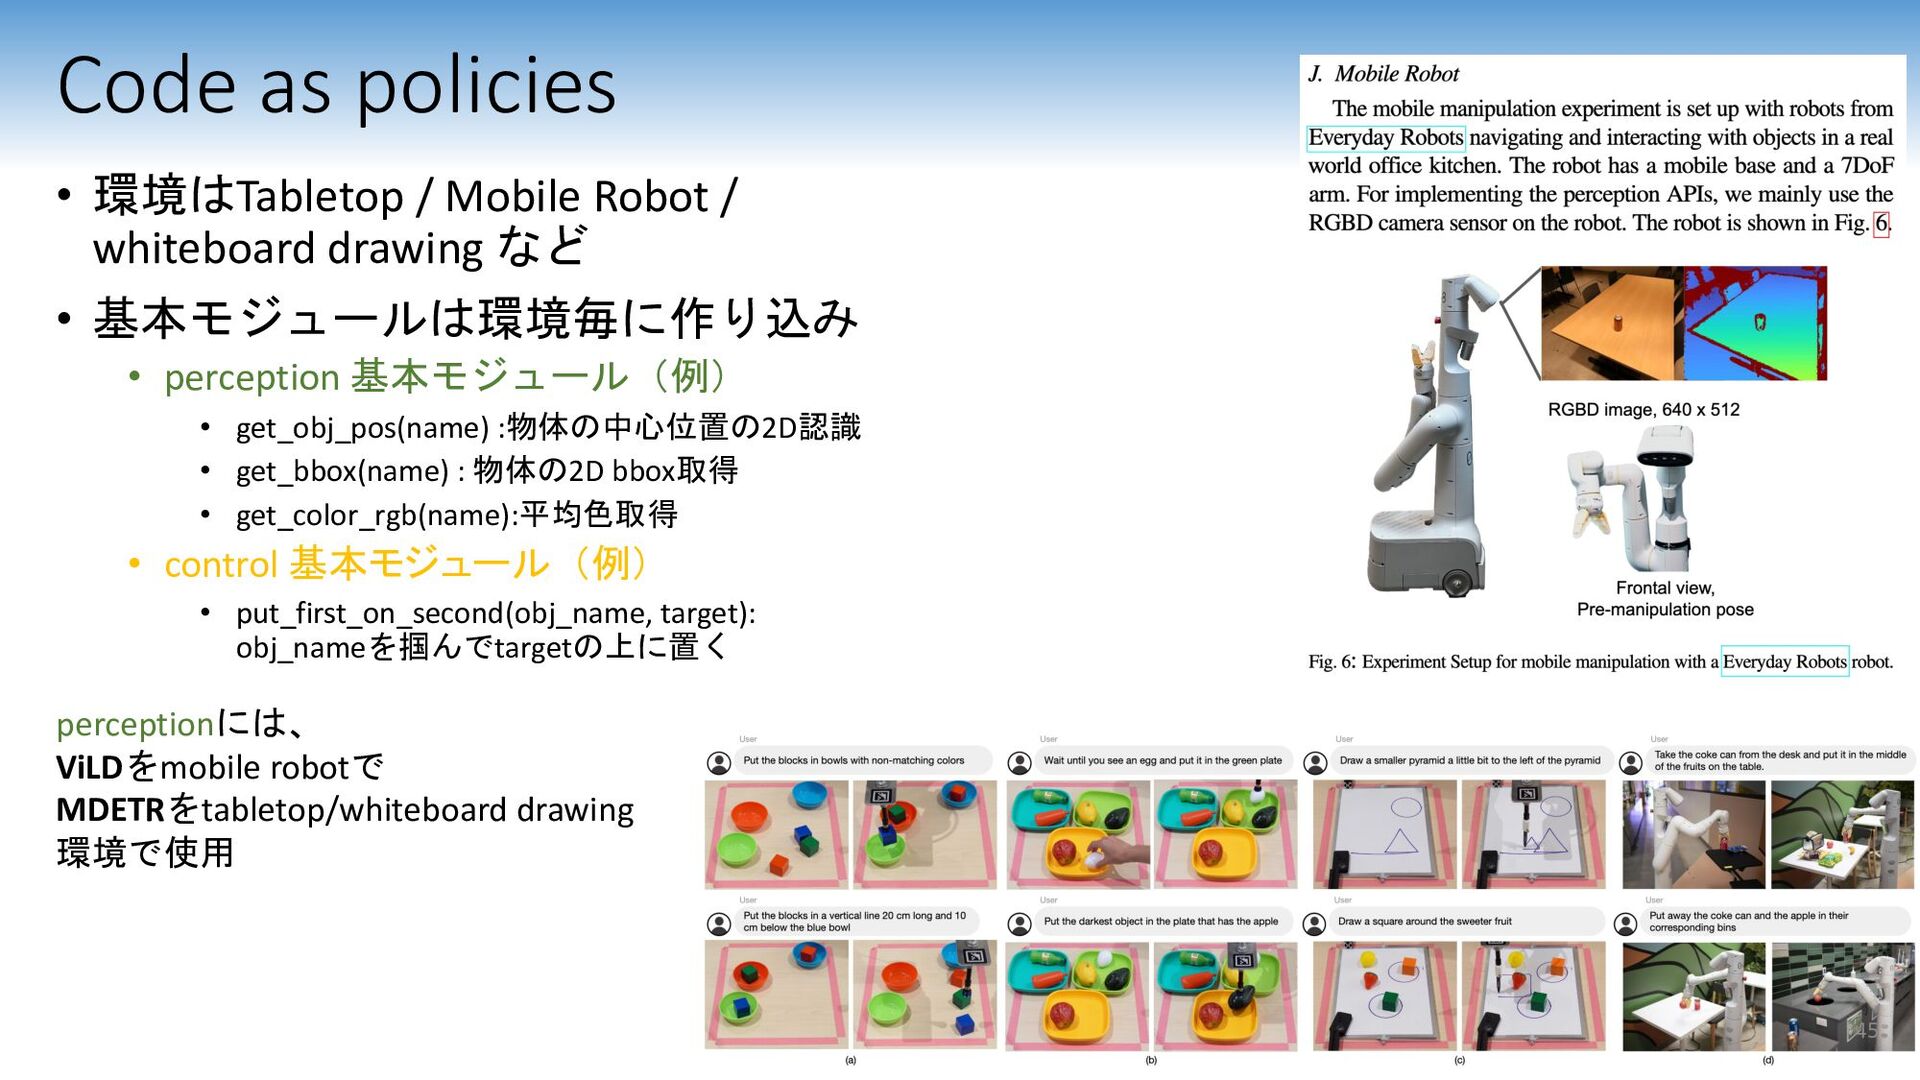
Code as policies • 環境はTabletop / Mobile Robot / whiteboard
drawing など • 基本モジュールは環境毎に作り込み • perception 基本モジュール(例) • get_obj_pos(name) :物体の中心位置の2D認識 • get_bbox(name) : 物体の2D bbox取得 • get_color_rgb(name):平均色取得 • control 基本モジュール(例) • put_first_on_second(obj_name, target): obj_nameを掴んでtargetの上に置く perceptionには、 ViLDをmobile robotで MDETRをtabletop/whiteboard drawing 環境で使用 45 -
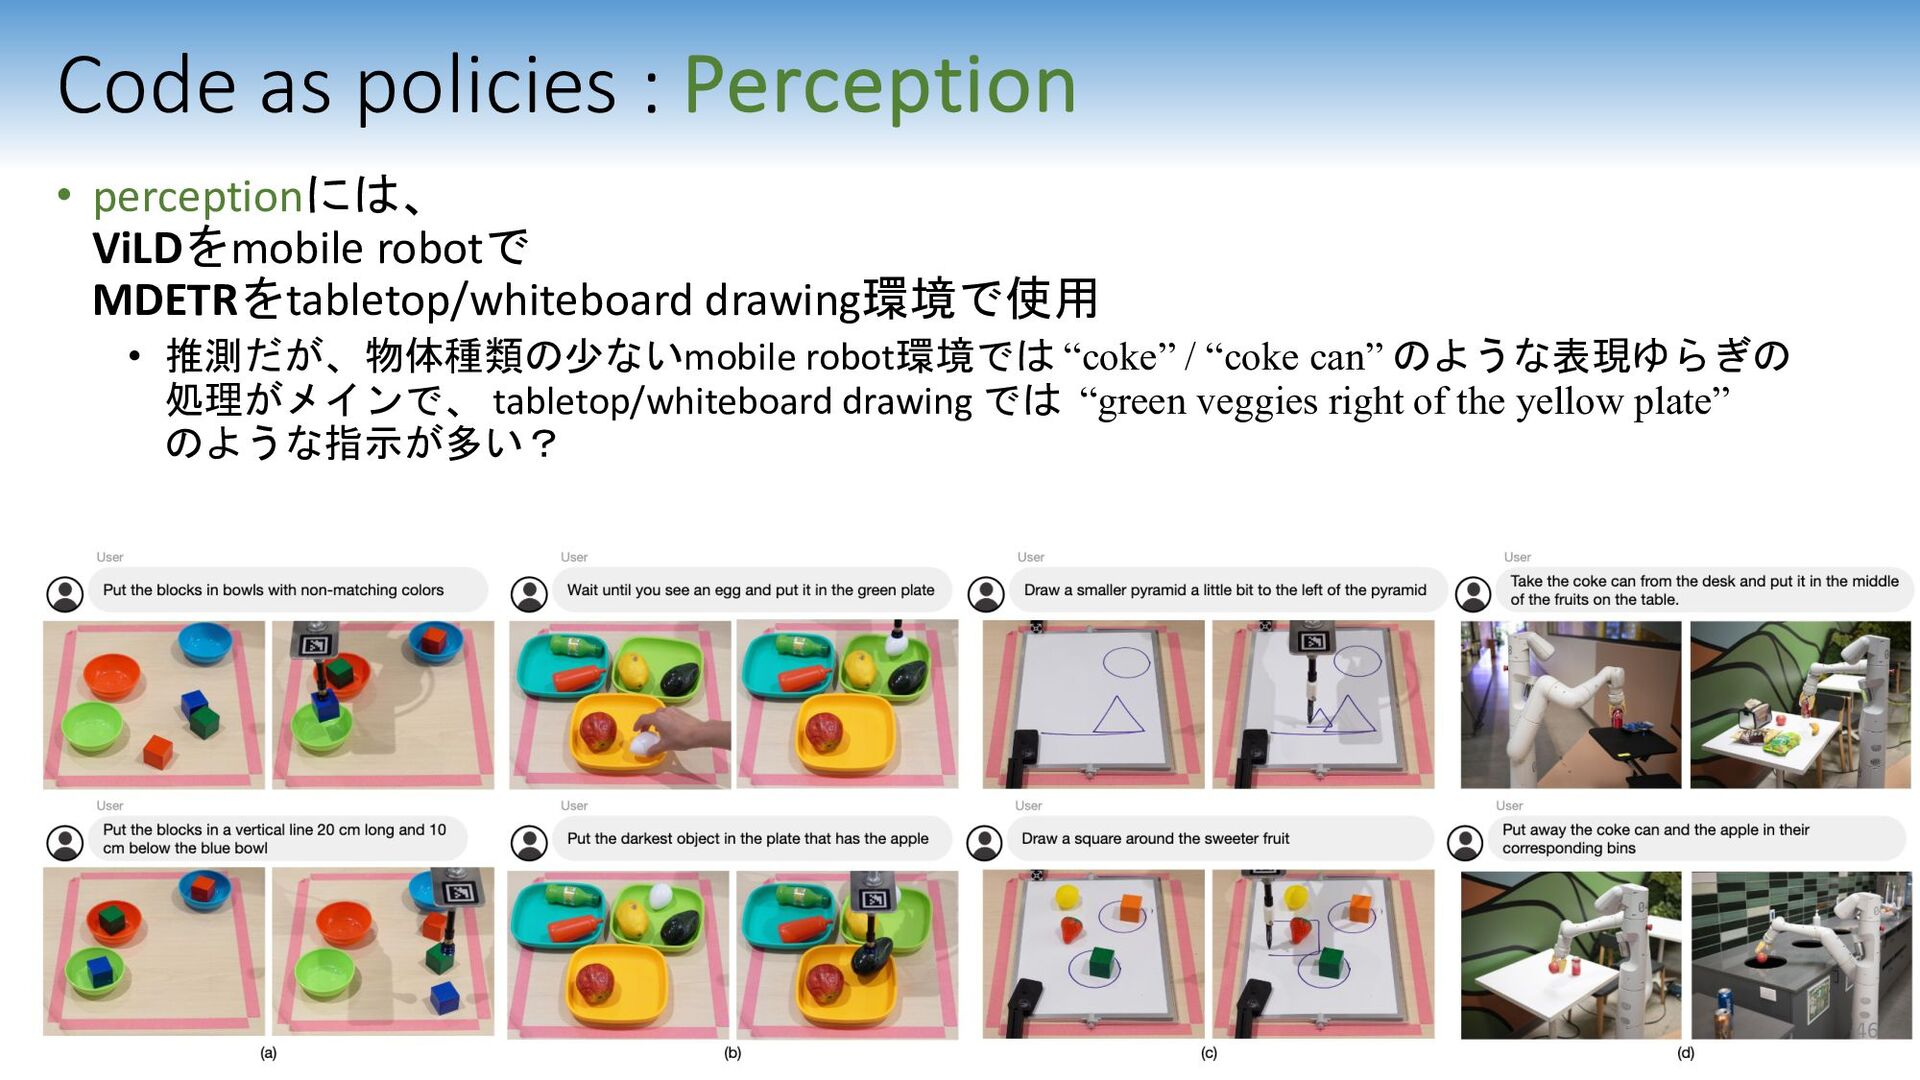
Code as policies : Perception • perceptionには、 ViLDをmobile robotで MDETRをtabletop/whiteboard
drawing環境で使用 • 推測だが、物体種類の少ないmobile robot環境では “coke” / “coke can” のような表現ゆらぎの 処理がメインで、 tabletop/whiteboard drawing では “green veggies right of the yellow plate” のような指示が多い? 46 -
栗田修平 (Shuhei Kurita) PhD of Informatics, Kyoto University (2019). RIKEN
AIP 研究員 (関根チーム) JSTさきがけ [email protected] SELECTED PUBLICATIONS Ø RefEgo: Referring Expression Comprehension Dataset from First-Person Perception of Ego4D Shuhei Kurita, Naoki Katsura, Eri Onami @ICCV2023. Ø ScanQA: 3D Question Answering for Spatial Scene Understanding @CVPR2022. Daichi Azuma (*), Taiki Miyanishi (*), Shuhei Kurita (*), Motoaki Kawanabe (*):Eq. Cont. Ø Generative Language-Grounded Policy in Vision-and-Language Navigation with Bayes’ Rule, Shuhei Kurita and Kyunghyun Cho, @ICLR2021. Ø Reconstructing neuronal circuitry from parallel spike trains, Ryota Kobayashi, Shuhei Kurita, Anno Kurth, Katsunori Kitano, Kenji Mizuseki, Markus Diesmann, Barry J Richmond, Shigeru Shinomoto @ Nature Communications (2019). Ø Multi-Task Semantic Dependency Parsing with Policy Gradient for Learning Easy-First Strategies, Shuhei Kurita and Anders Søgaard, @ACL2019. Ø Neural Joint Model for Transition-based Chinese Syntactic Analysis, Shuhei Kurita, Daisuke Kawahara and Sadao Kurohashi, @ACL2017. Selected Out-standing paper! CURRENT INTEREST: Visual grounding / NLP in (physical) real-world.
 danielanewman
 aleyda
 axbom
 geoffreycrofte
 rocio
 tmiket
 reverentgeek
 livdayseo
 ammeep
 marktimemedia
 rasmusluckow