Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Building distributed systems with OSS

Building distributed systems with OSS

Mateusz Gajewski

October 03, 2015

Transcript

40 slides
  1. Distributed toolbox dynamic flow control, rate limiting, exponential back-offs, automatic

    failover, hinted-handoffs, data scrubbing, CRDTs, backpressure, circuit breakers, bulk heads vector clocks, two-phase commit, consensus algorithms, gossip protocols, leader election, distributed coordination, eventual consistency, data replication, OCC, MVCC...
  2. Thesis: Most of our problems/needs can be addressed using existing

    Open Source Software. Proof through: a lot of companies i.e. Allegro ;)
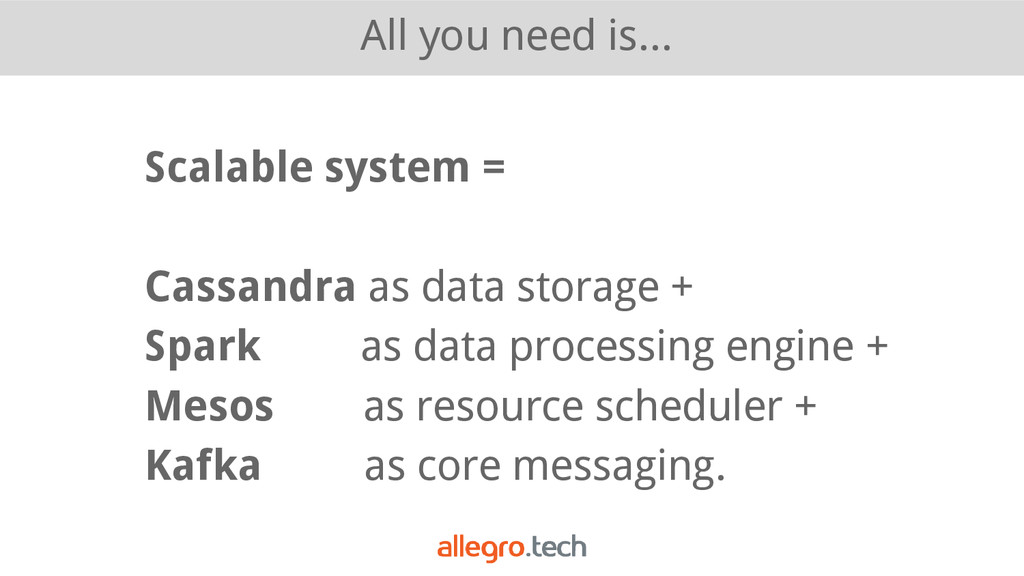
  3. All you need is... Scalable system = Cassandra as data

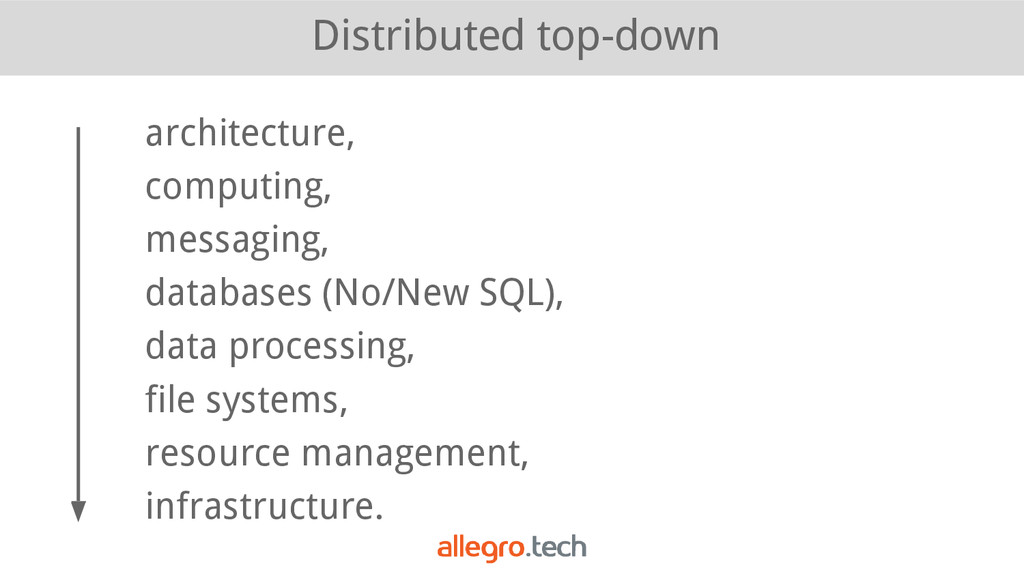
    storage + Spark as data processing engine + Mesos as resource scheduler + Kafka as core messaging.
  4. OSS cons • immature (not production-ready), • bugs, • poor

    or misleading documentation, • learning curve, • few or no experts on the market, • slow adoption rate, • dependencies on other OSS, • (sometimes) lack of support
  5. OSS pros • “there is OSS for that” ;) •

    licensing, • sources, • speeds up time-to-market • helps recruiting
  6. OSS tips • stay up-to-date, • don’t trust docs -

    deep dive instead, • engage with community, • remove OSS barriers - contribute back, • release your software - share, • grow experts in your company - educate, • evaluate-hold-adopt cycle - experiment, • know your hardware & OS - tune, • be patient ;)
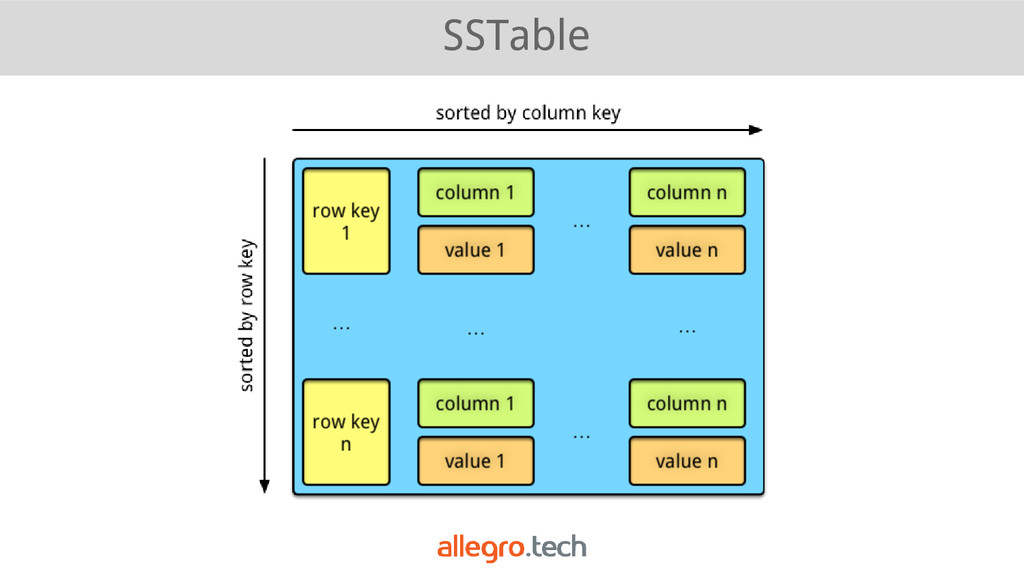
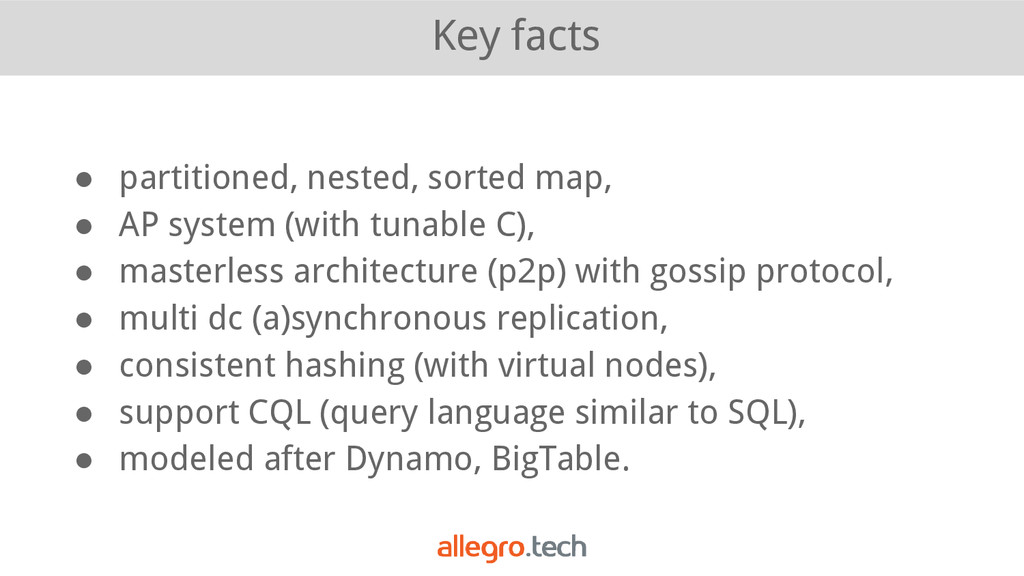
  7. Key facts • partitioned, nested, sorted map, • AP system

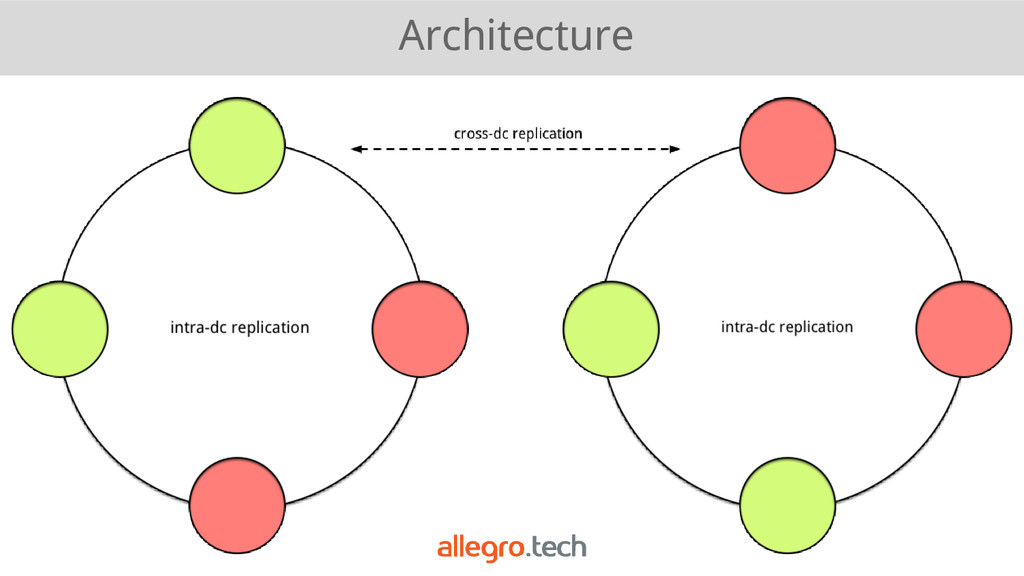
    (with tunable C), • masterless architecture (p2p) with gossip protocol, • multi dc (a)synchronous replication, • consistent hashing (with virtual nodes), • support CQL (query language similar to SQL), • modeled after Dynamo, BigTable.
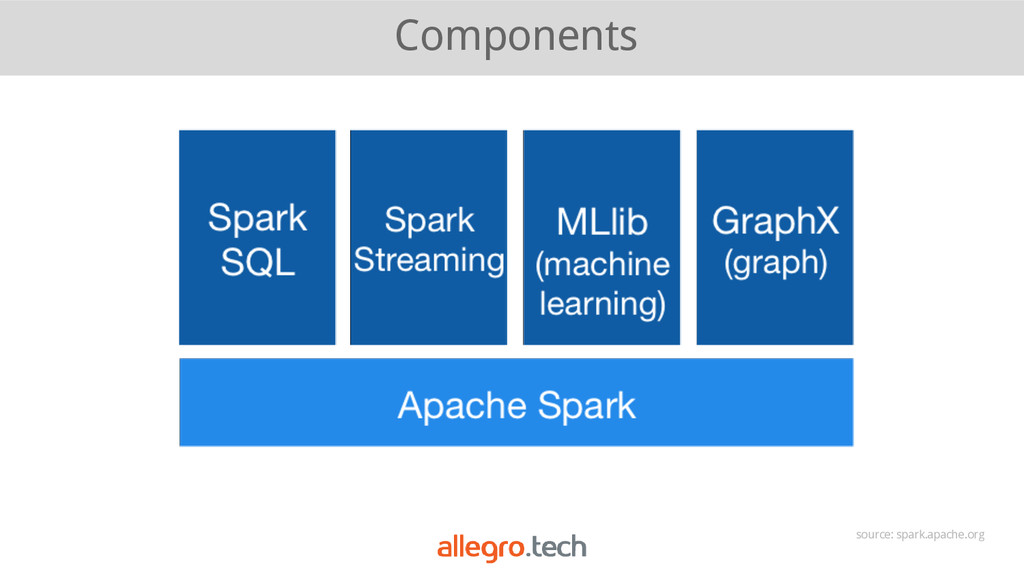
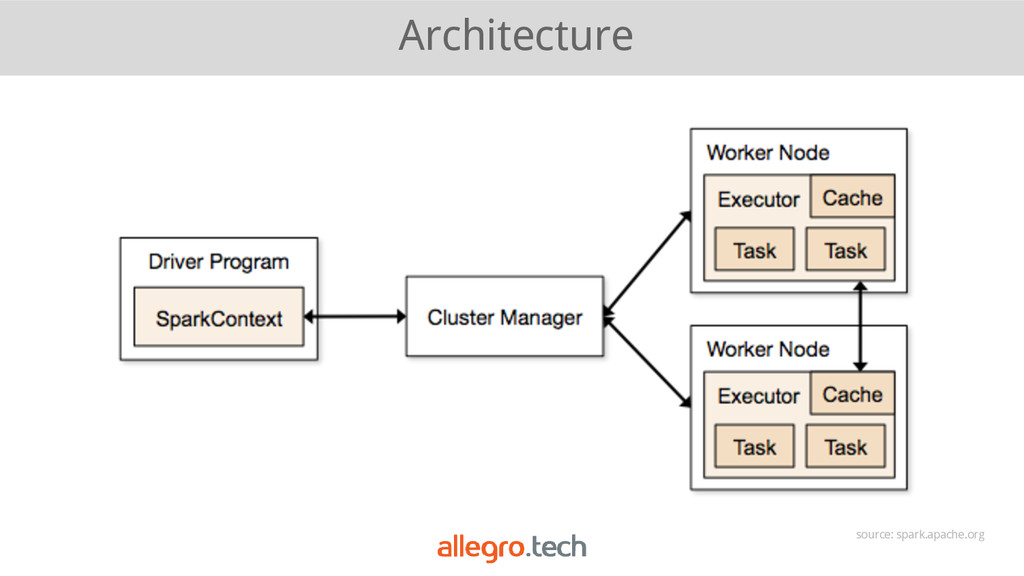
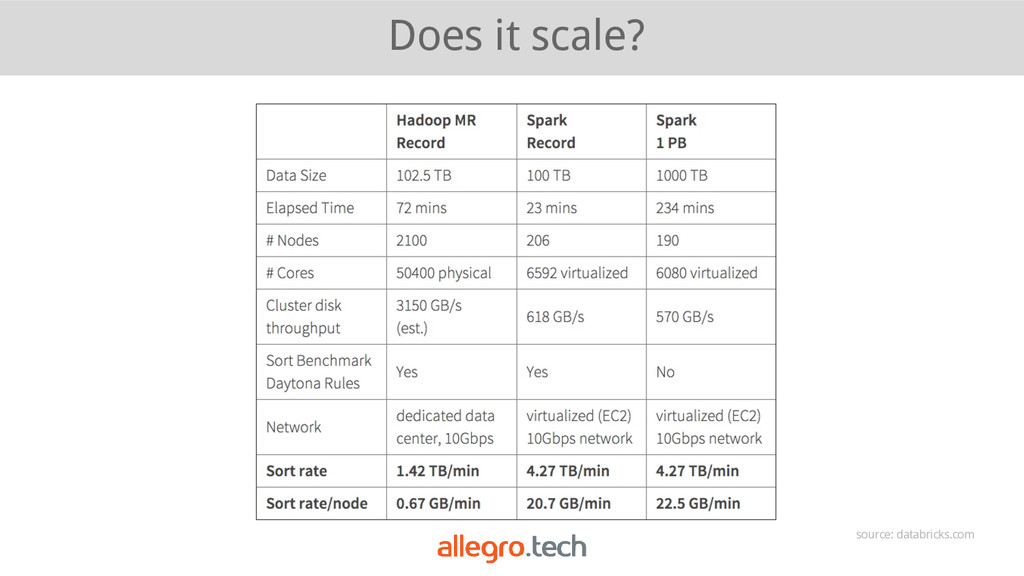
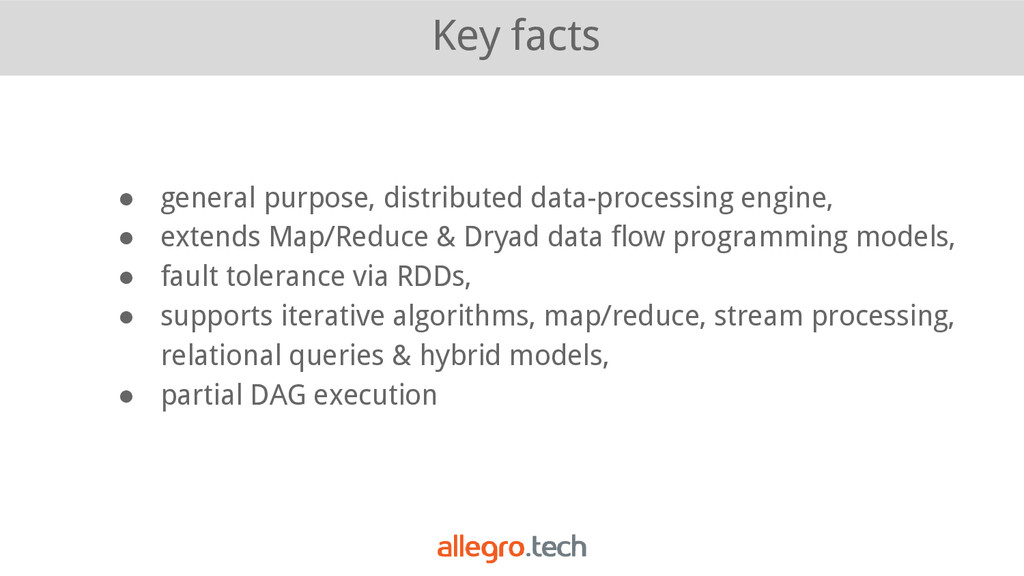
  8. Key facts • general purpose, distributed data-processing engine, • extends

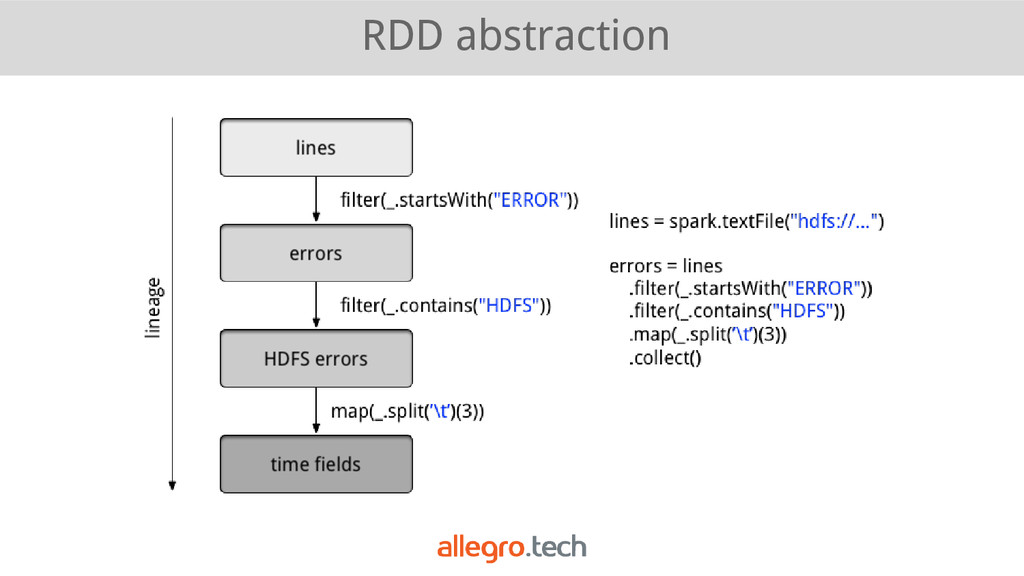
    Map/Reduce & Dryad data flow programming models, • fault tolerance via RDDs, • supports iterative algorithms, map/reduce, stream processing, relational queries & hybrid models, • partial DAG execution
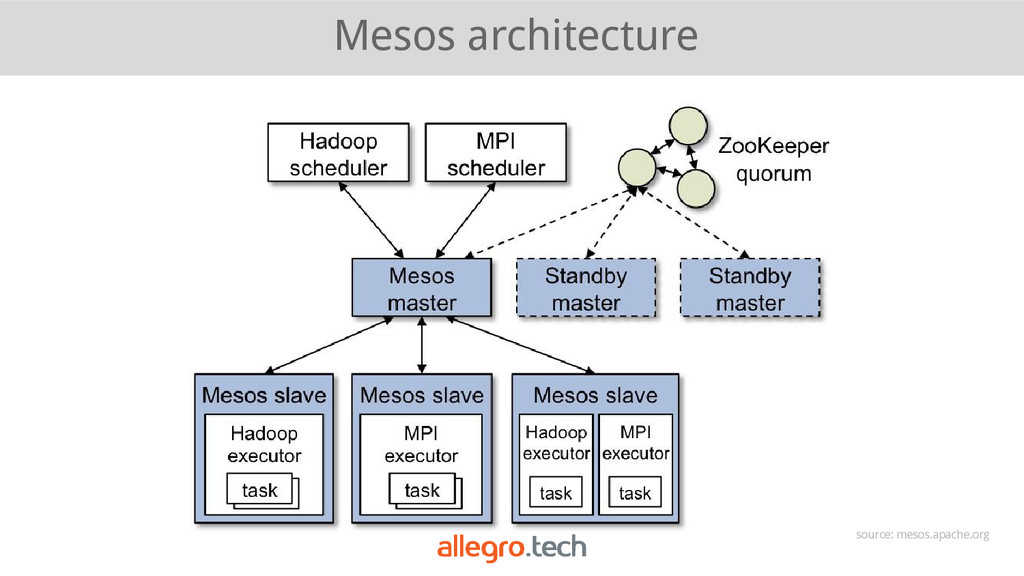
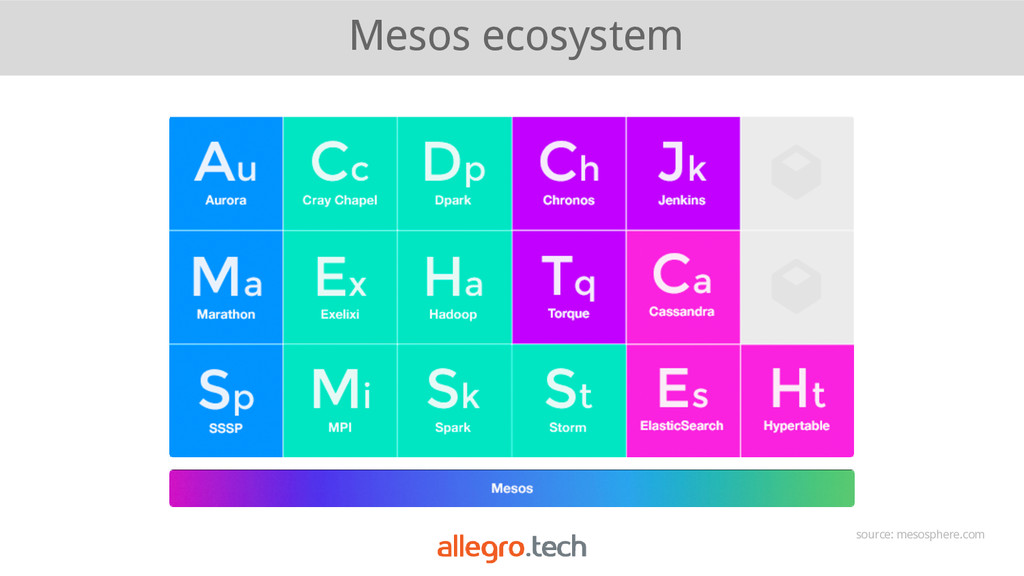
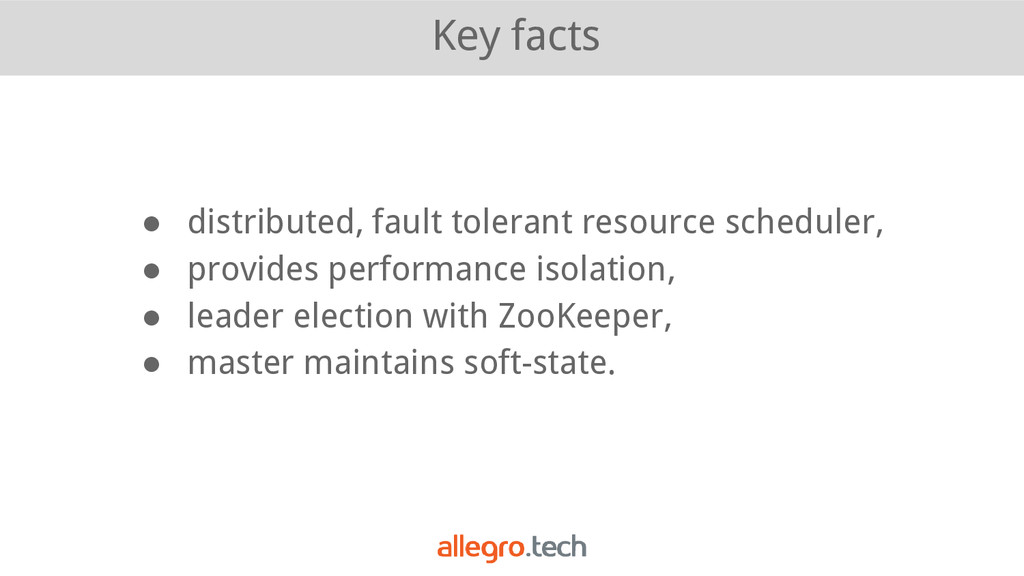
  9. Key facts • distributed, fault tolerant resource scheduler, • provides

    performance isolation, • leader election with ZooKeeper, • master maintains soft-state.
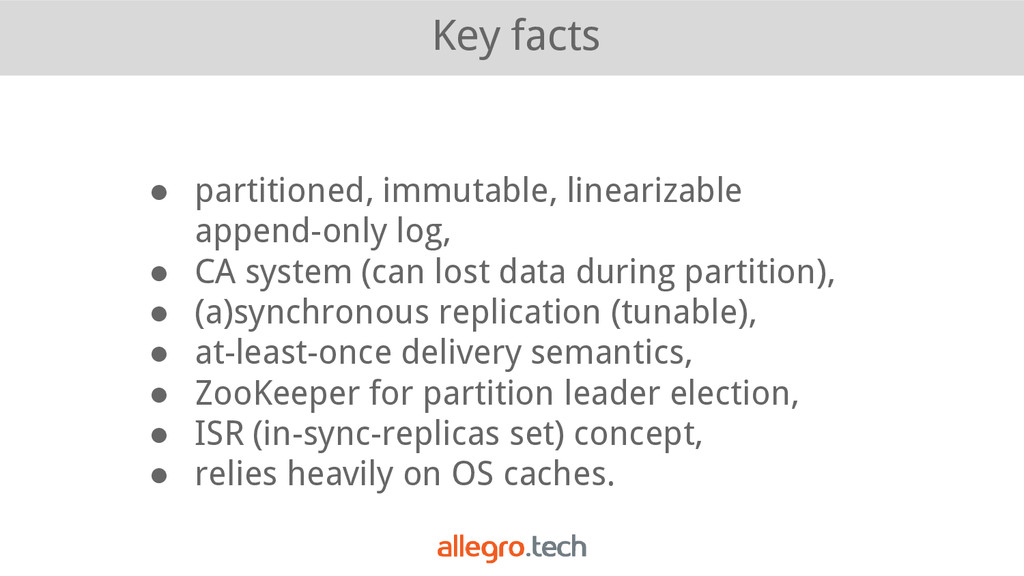
  10. Key facts • partitioned, immutable, linearizable append-only log, • CA

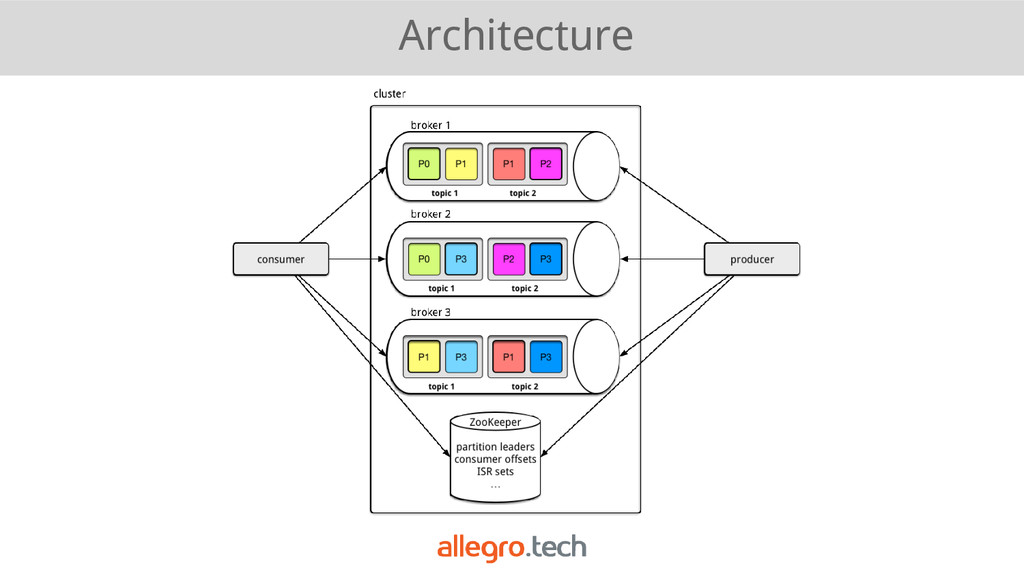
    system (can lost data during partition), • (a)synchronous replication (tunable), • at-least-once delivery semantics, • ZooKeeper for partition leader election, • ISR (in-sync-replicas set) concept, • relies heavily on OS caches.

More Decks by Mateusz Gajewski

Other Decks in Programming