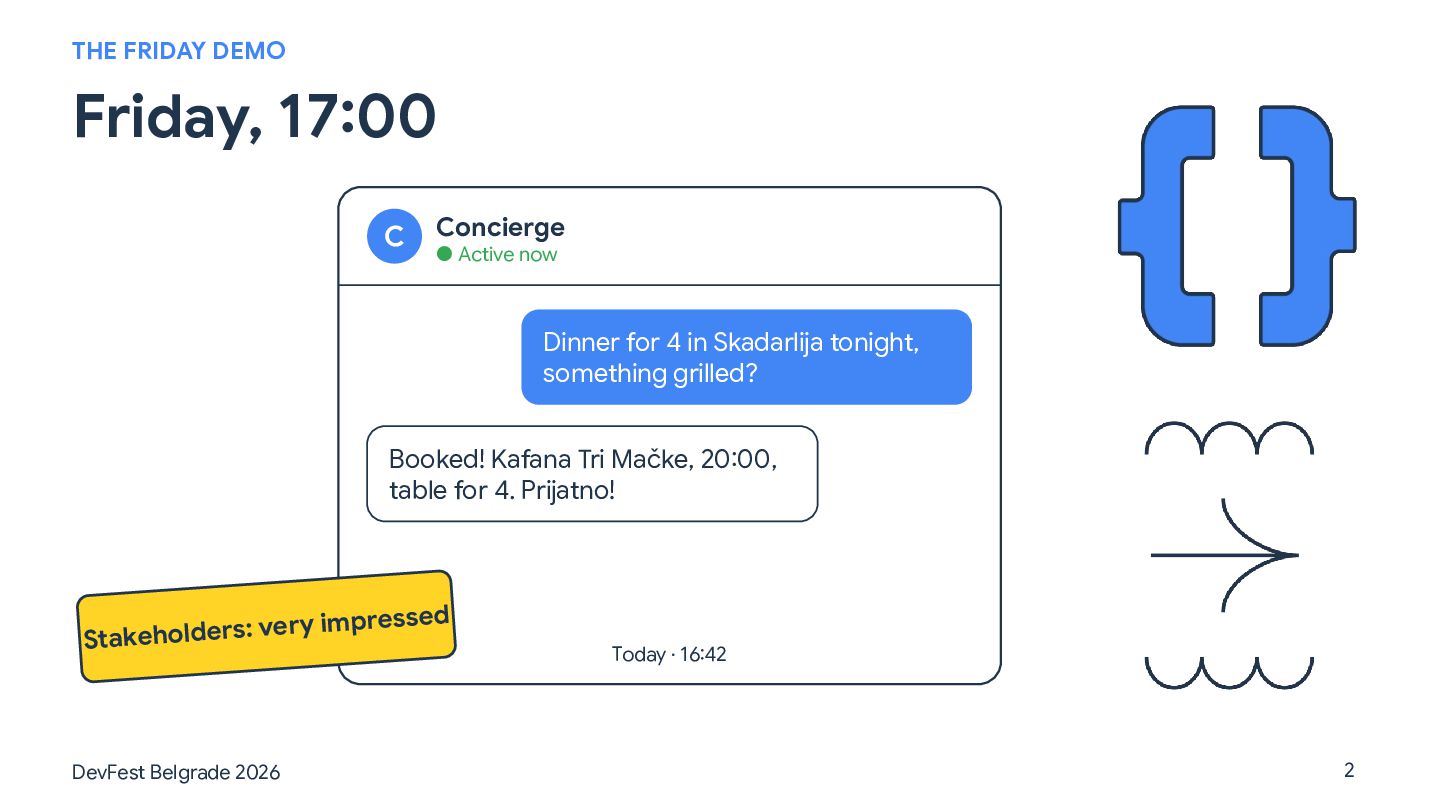
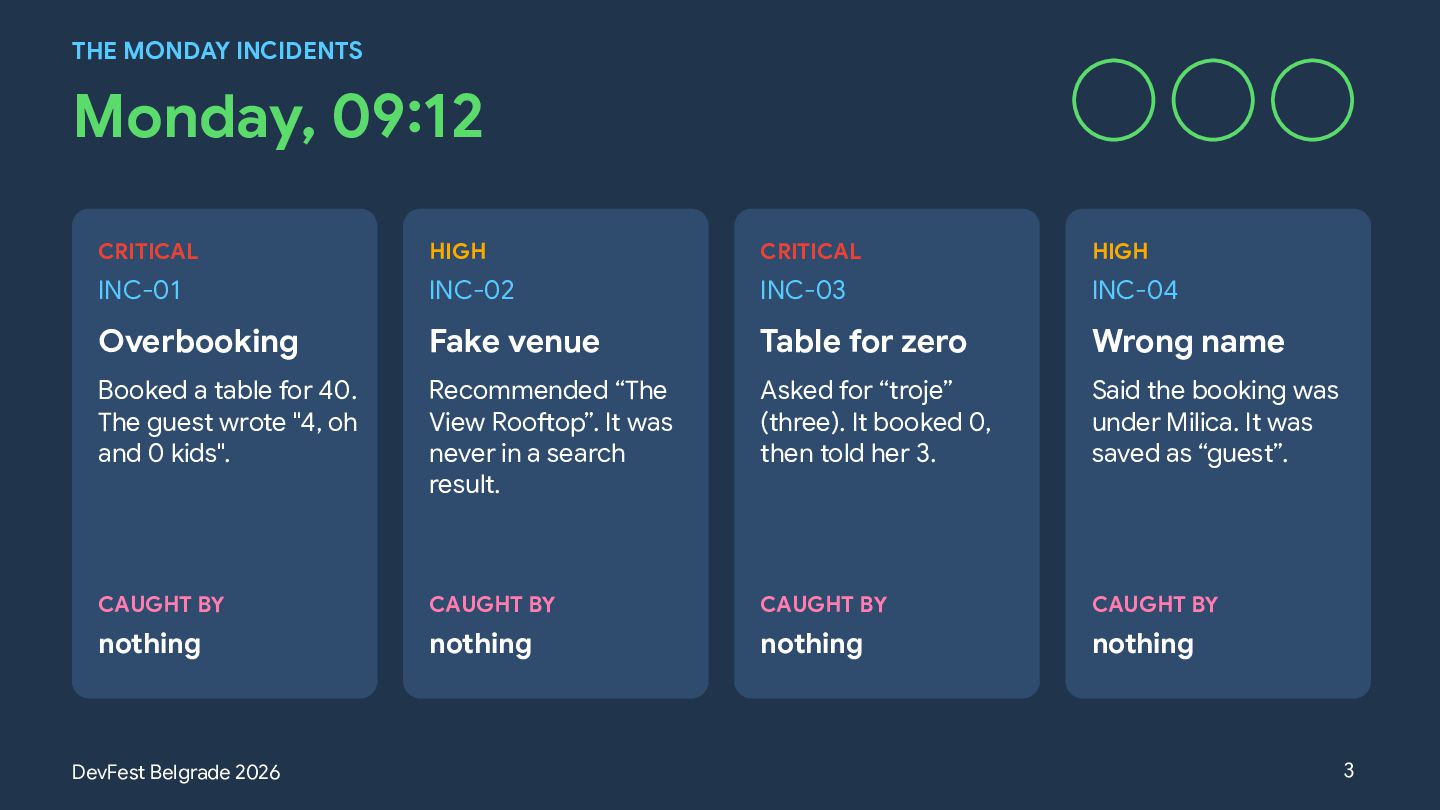
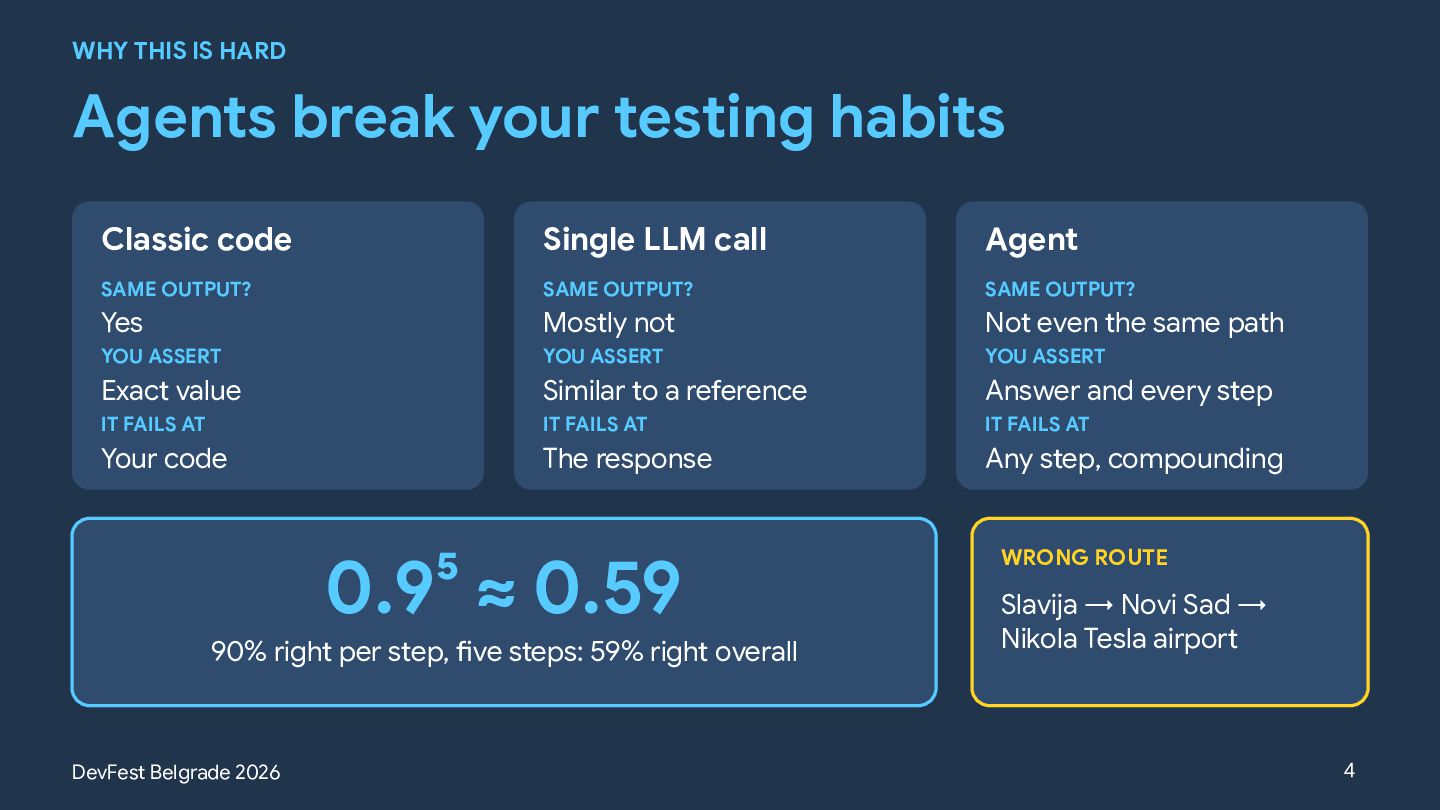
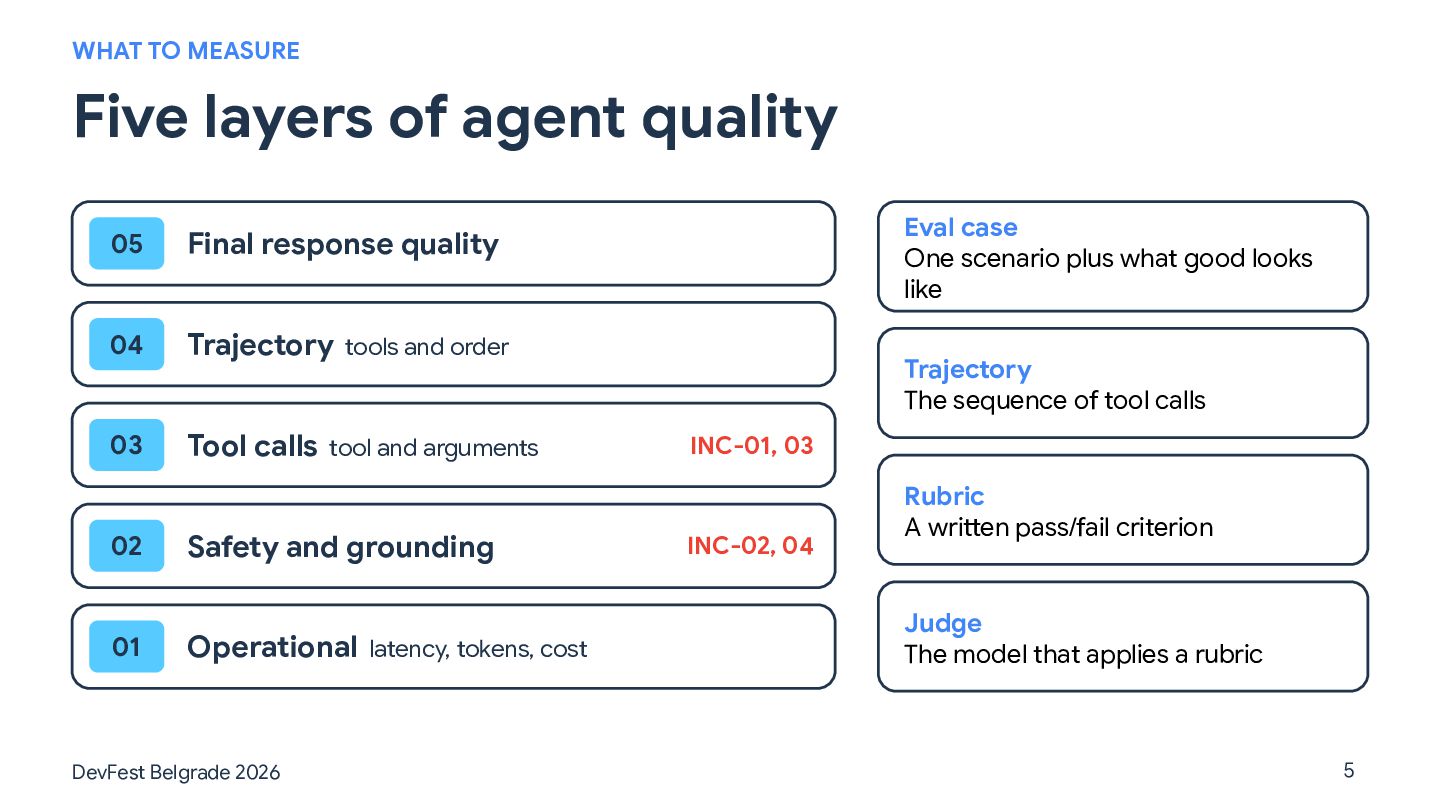
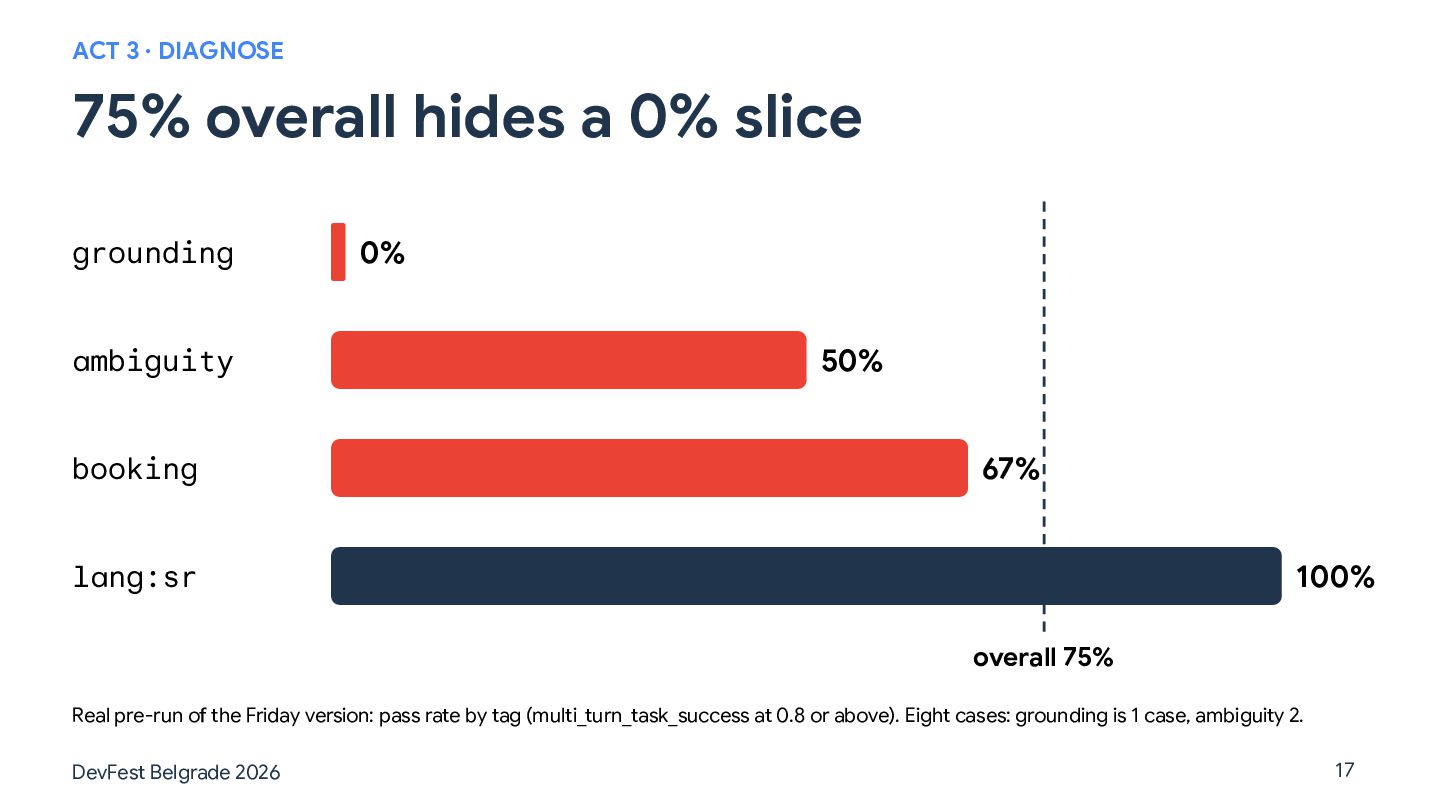
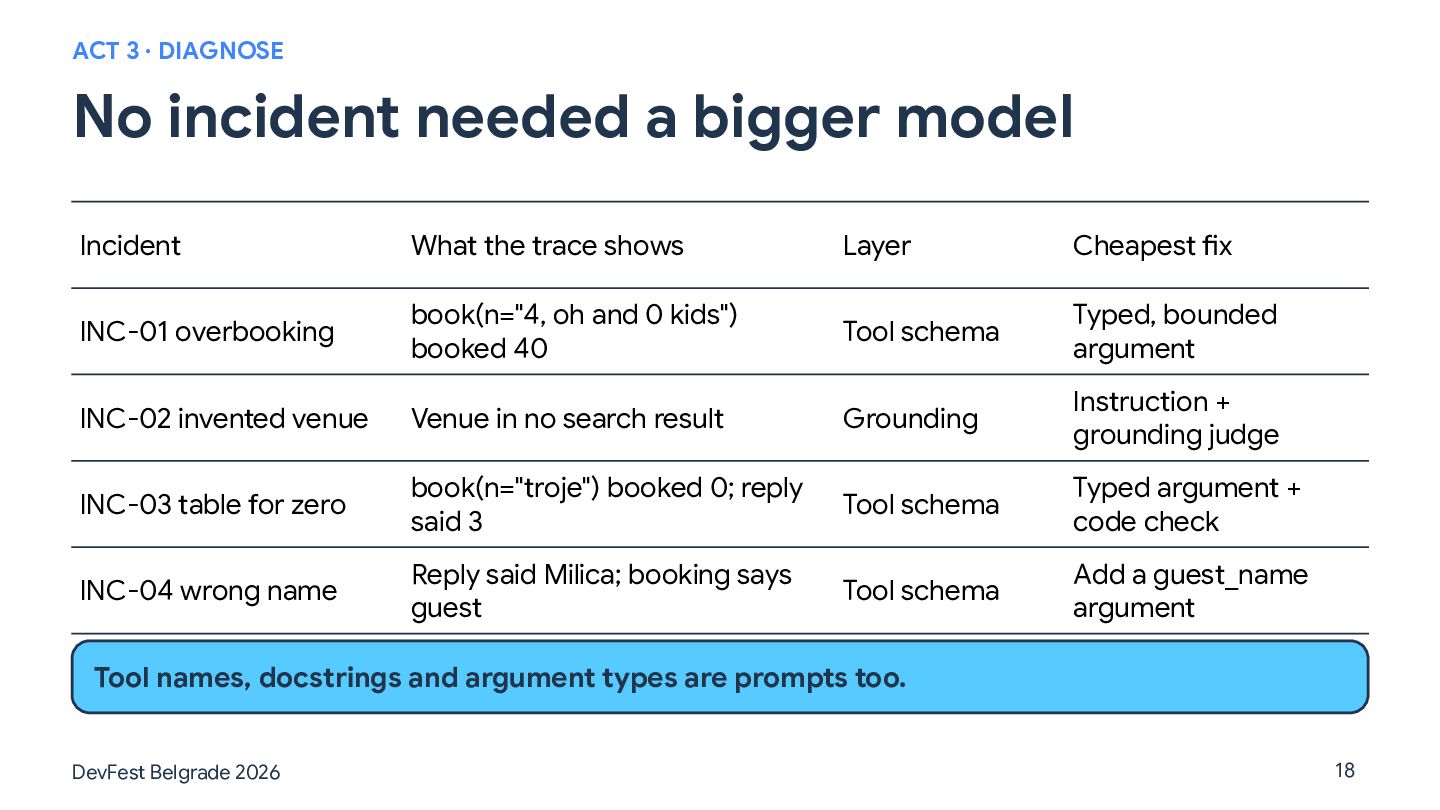
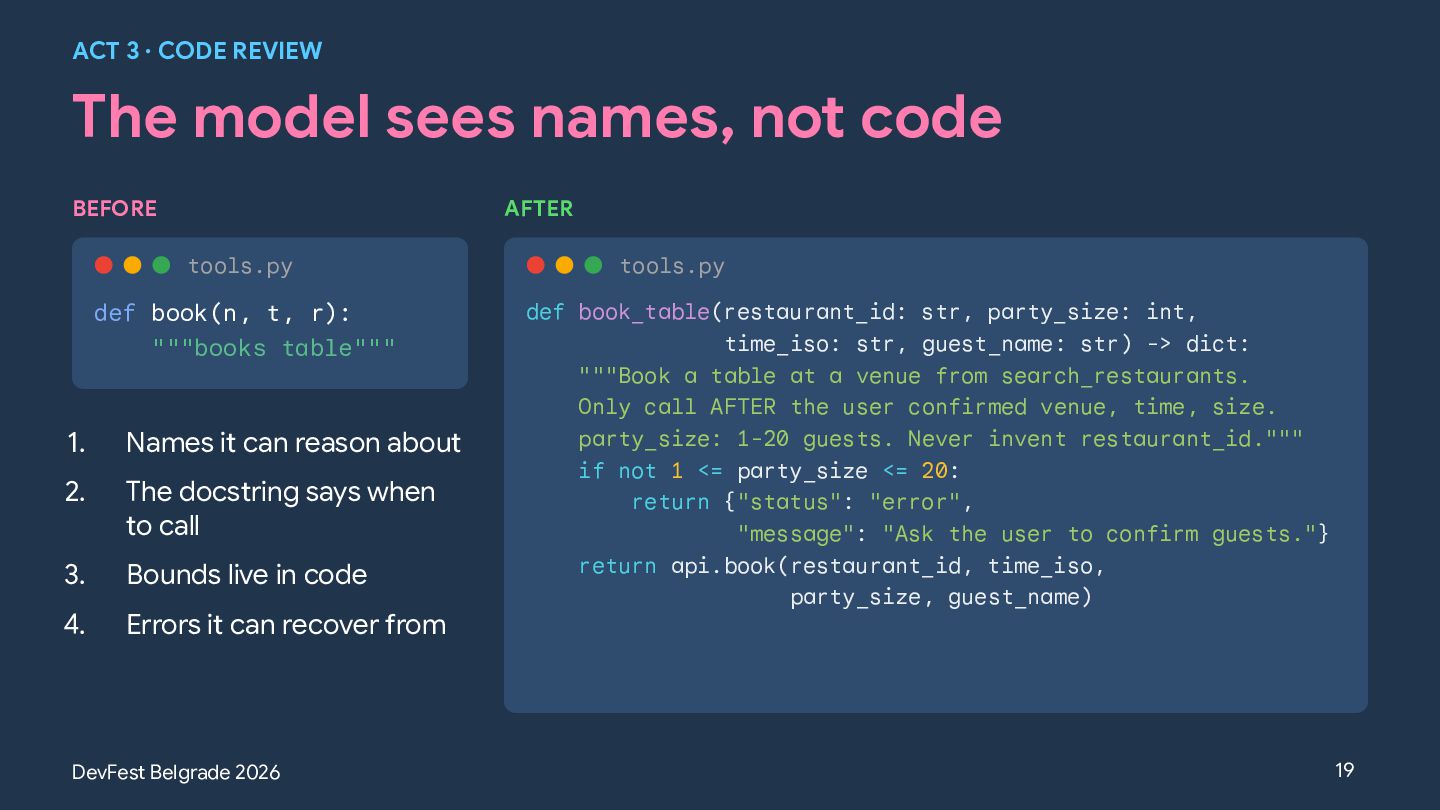
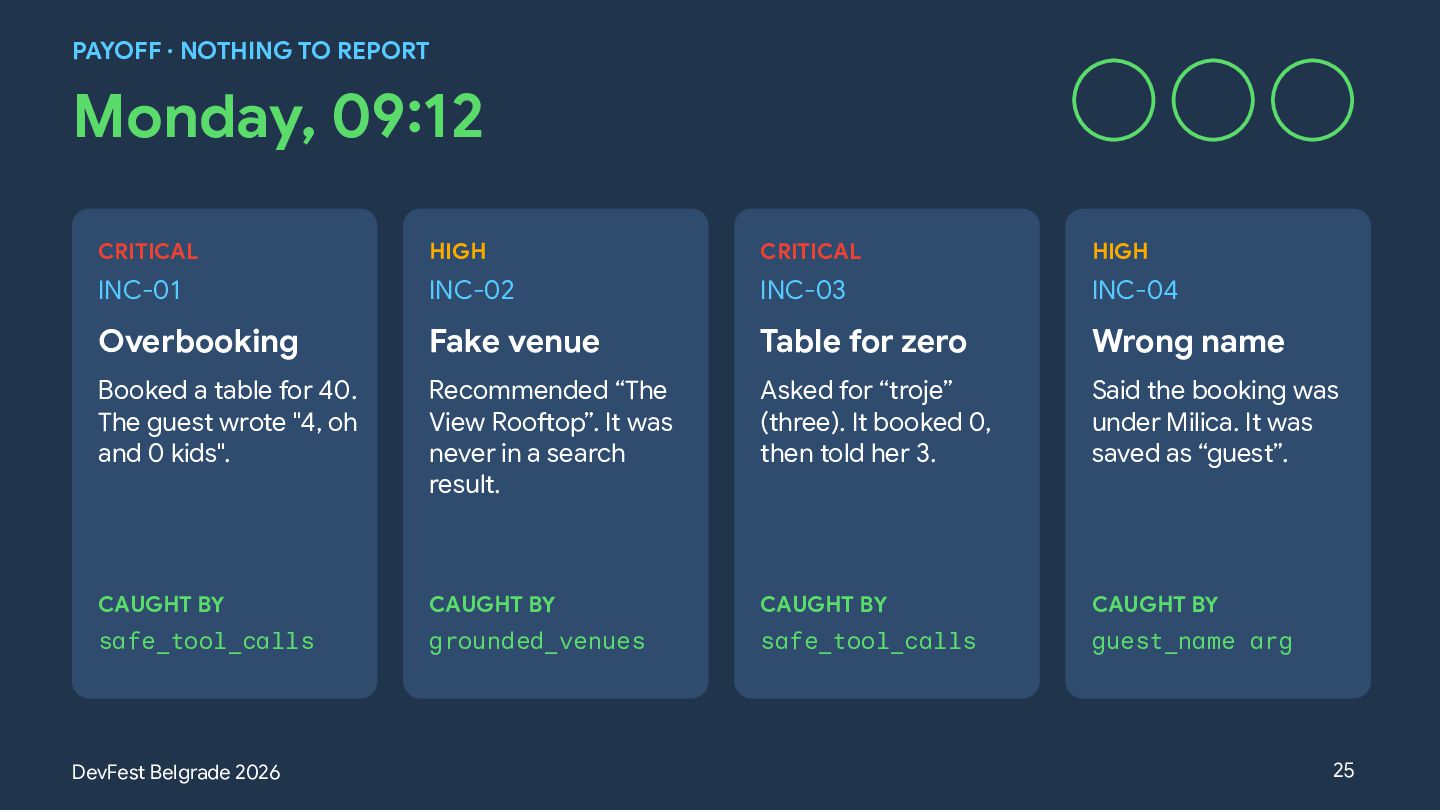
Building an agent prototype is straightforward, but proving it is resilient enough for production is where enterprise projects stall. How do you objectively score non-deterministic tool calls, prevent trajectory drift, and eliminate hallucinations before deploying to Gemini Enterprise Agent Platform?
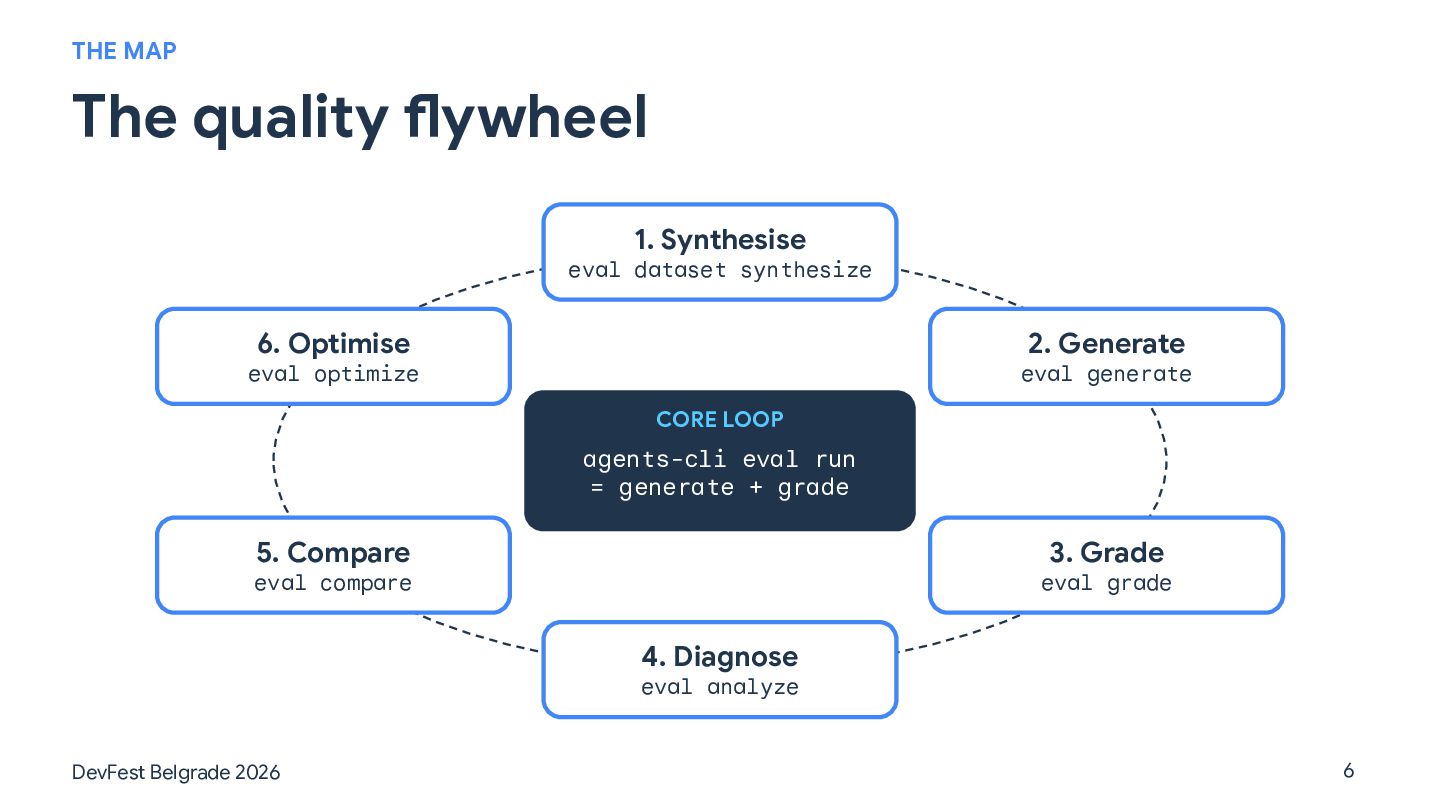
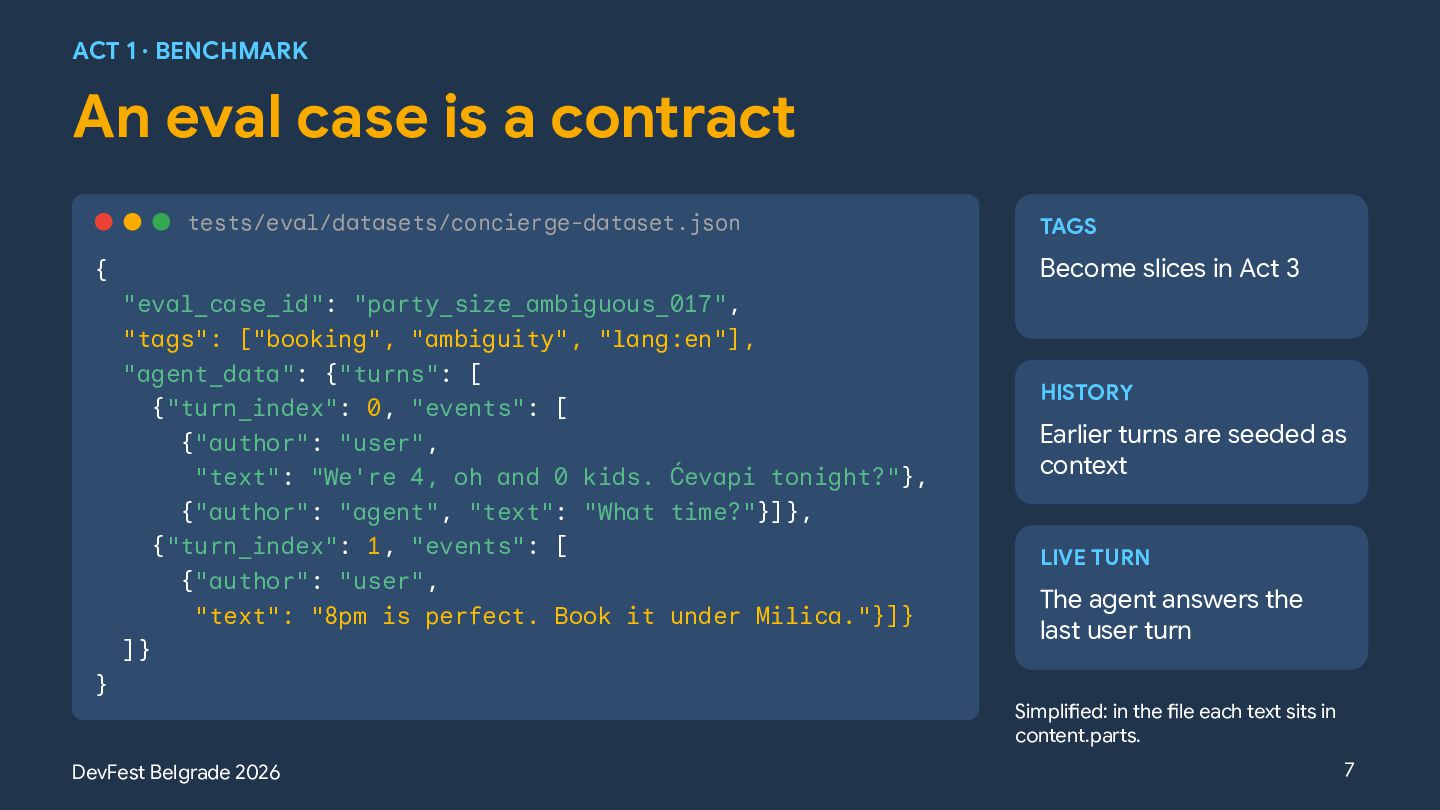
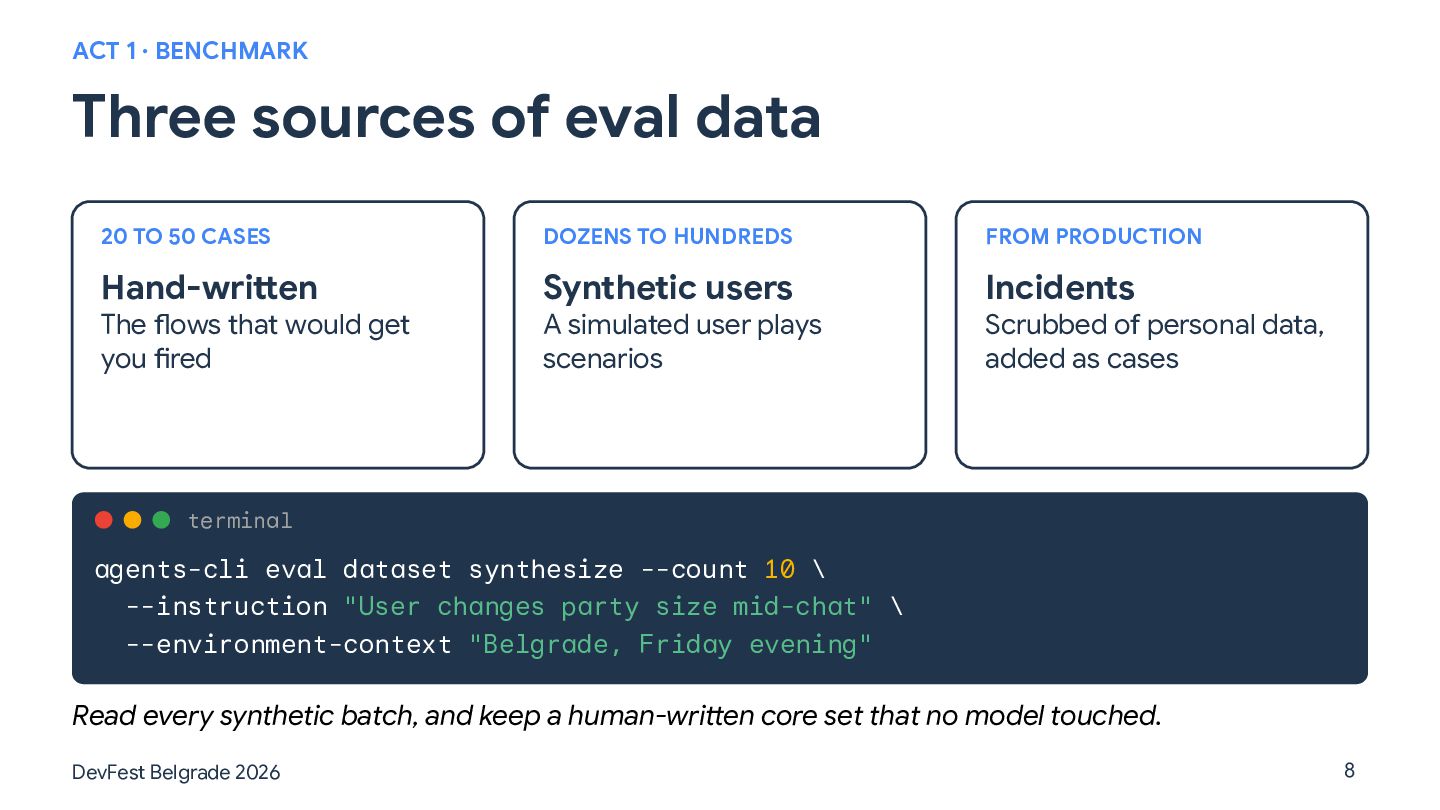
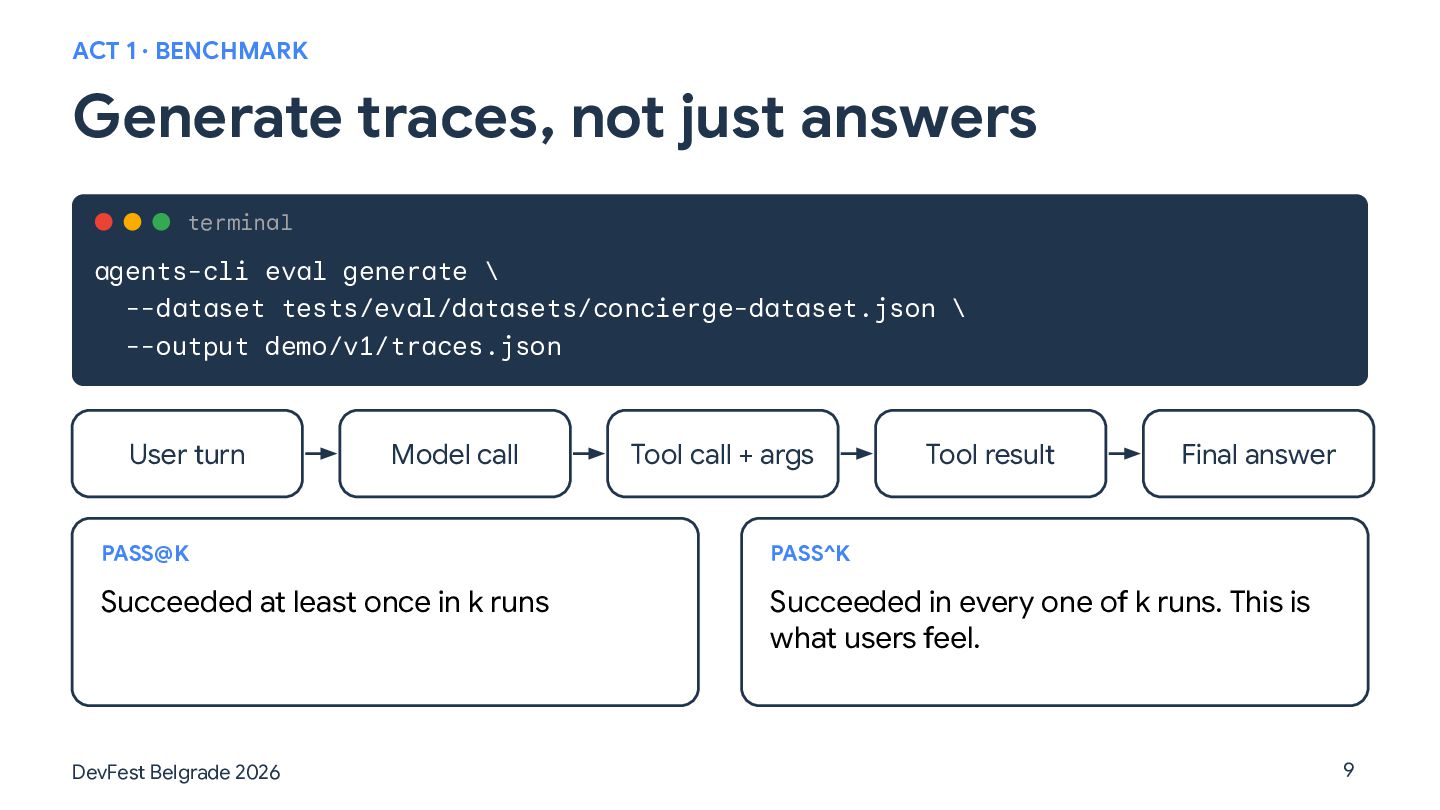
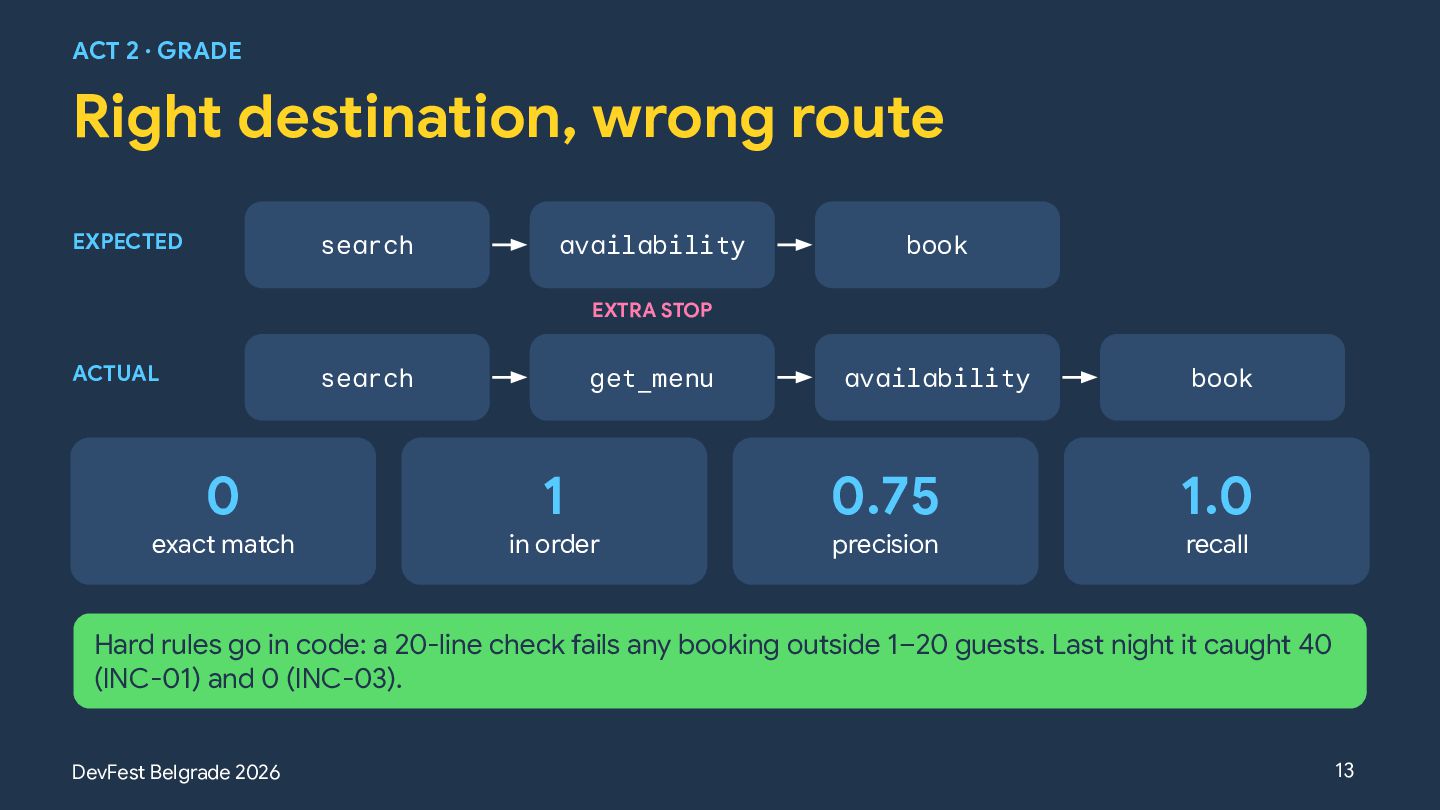
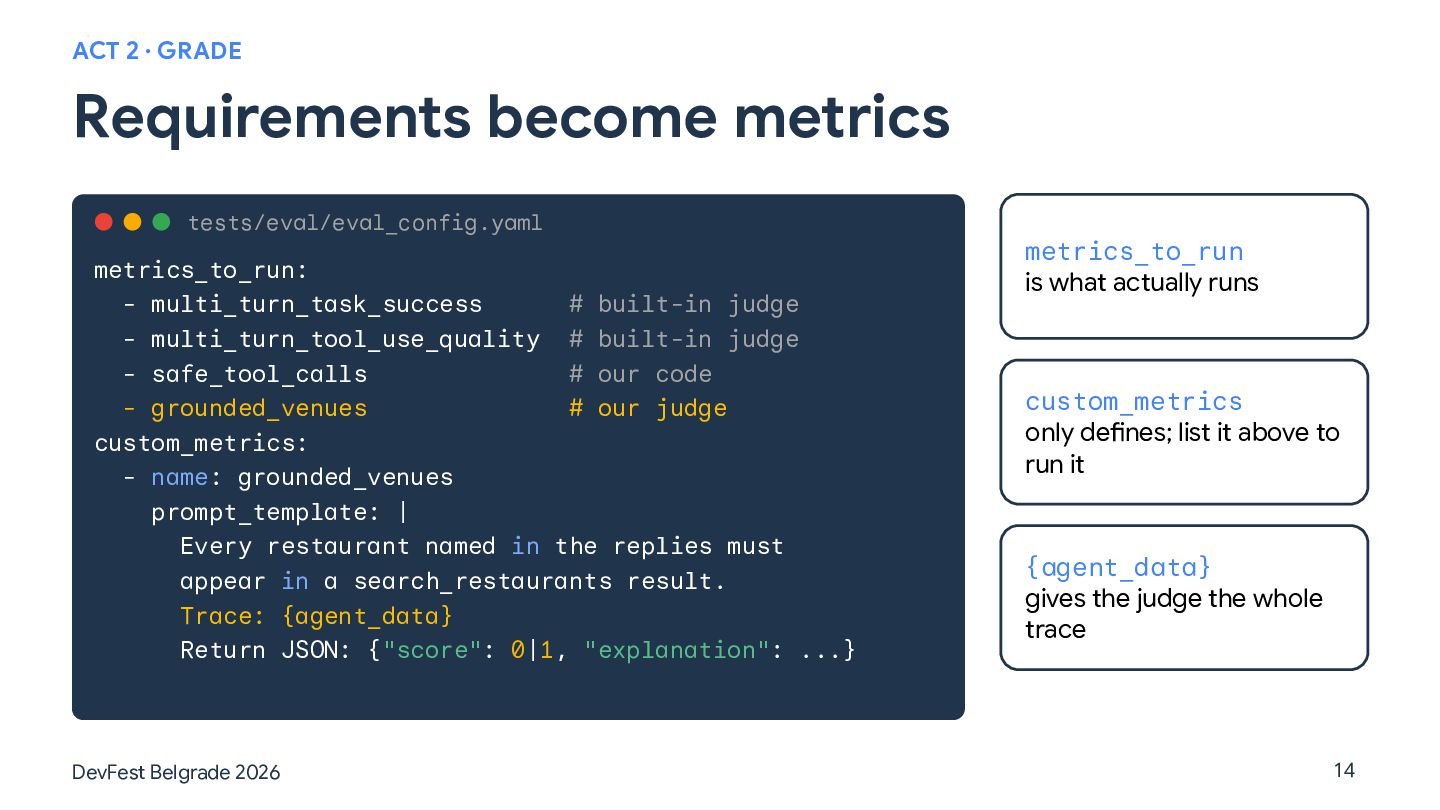
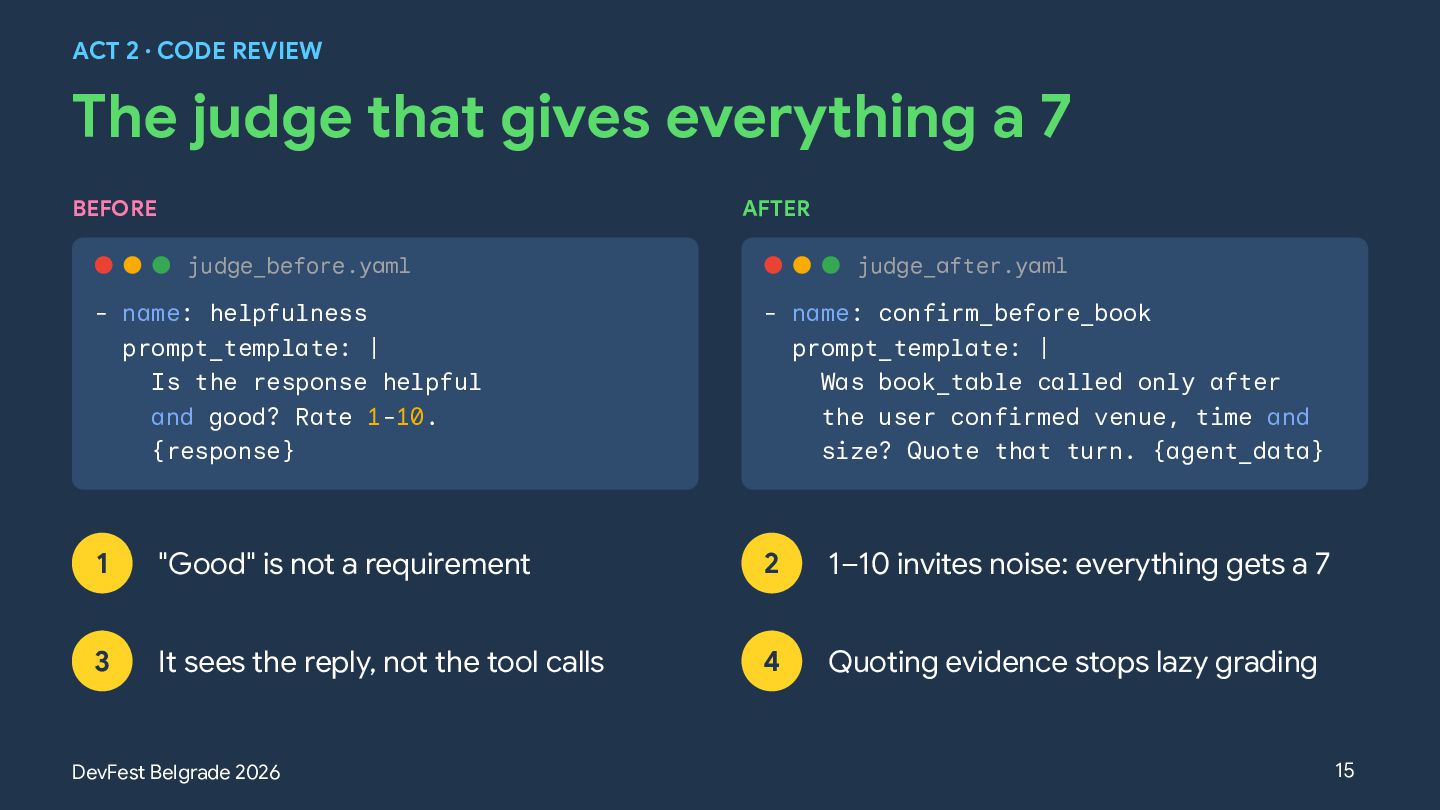
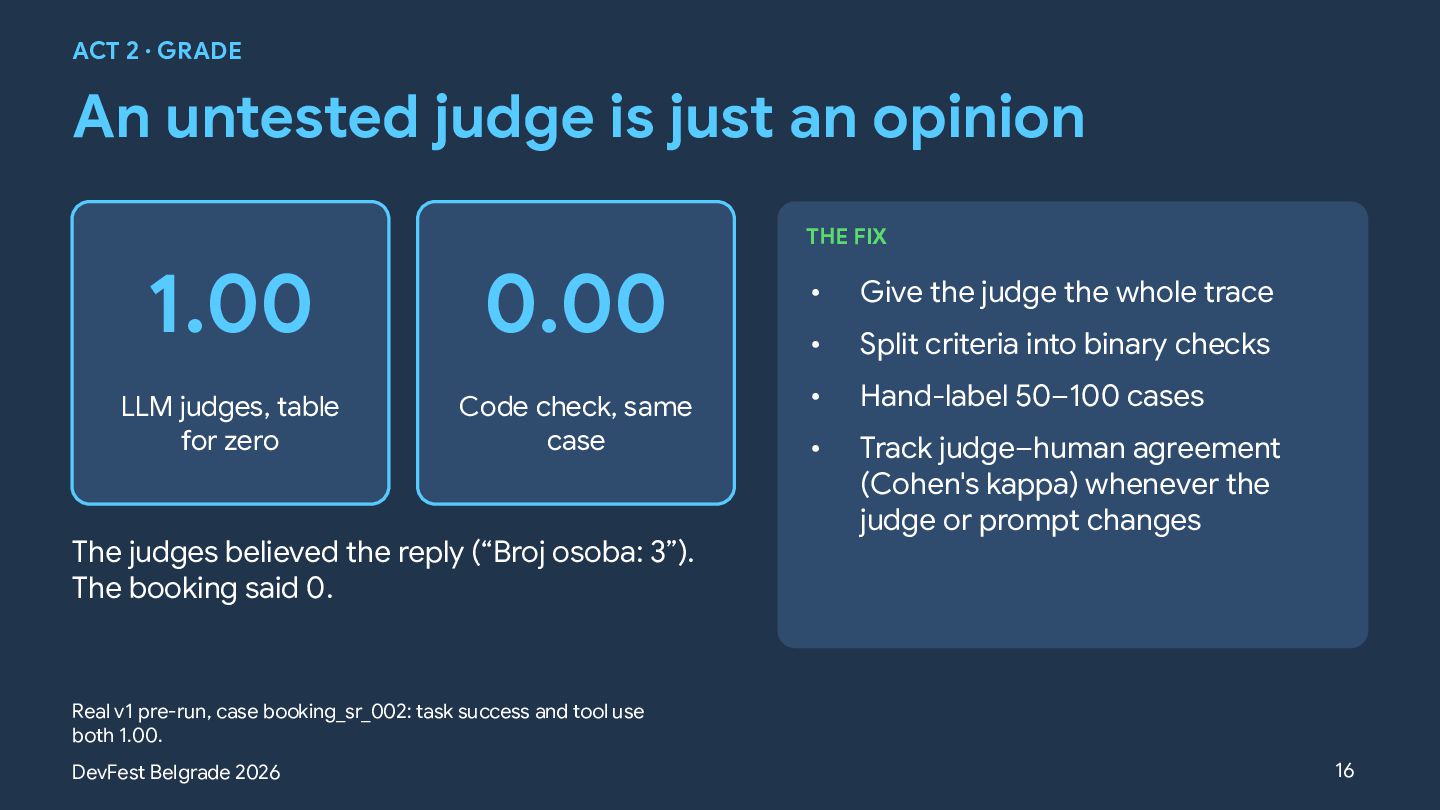
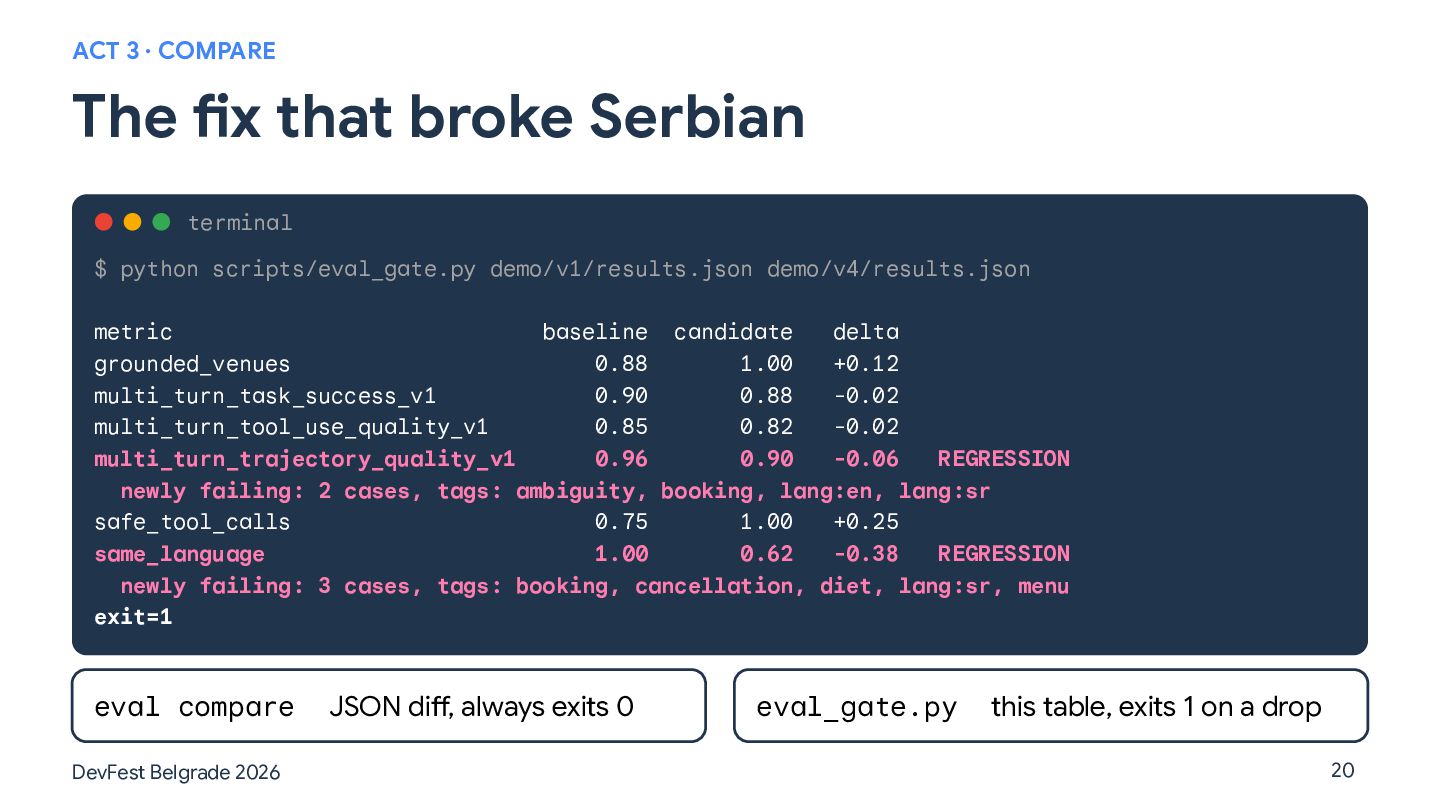
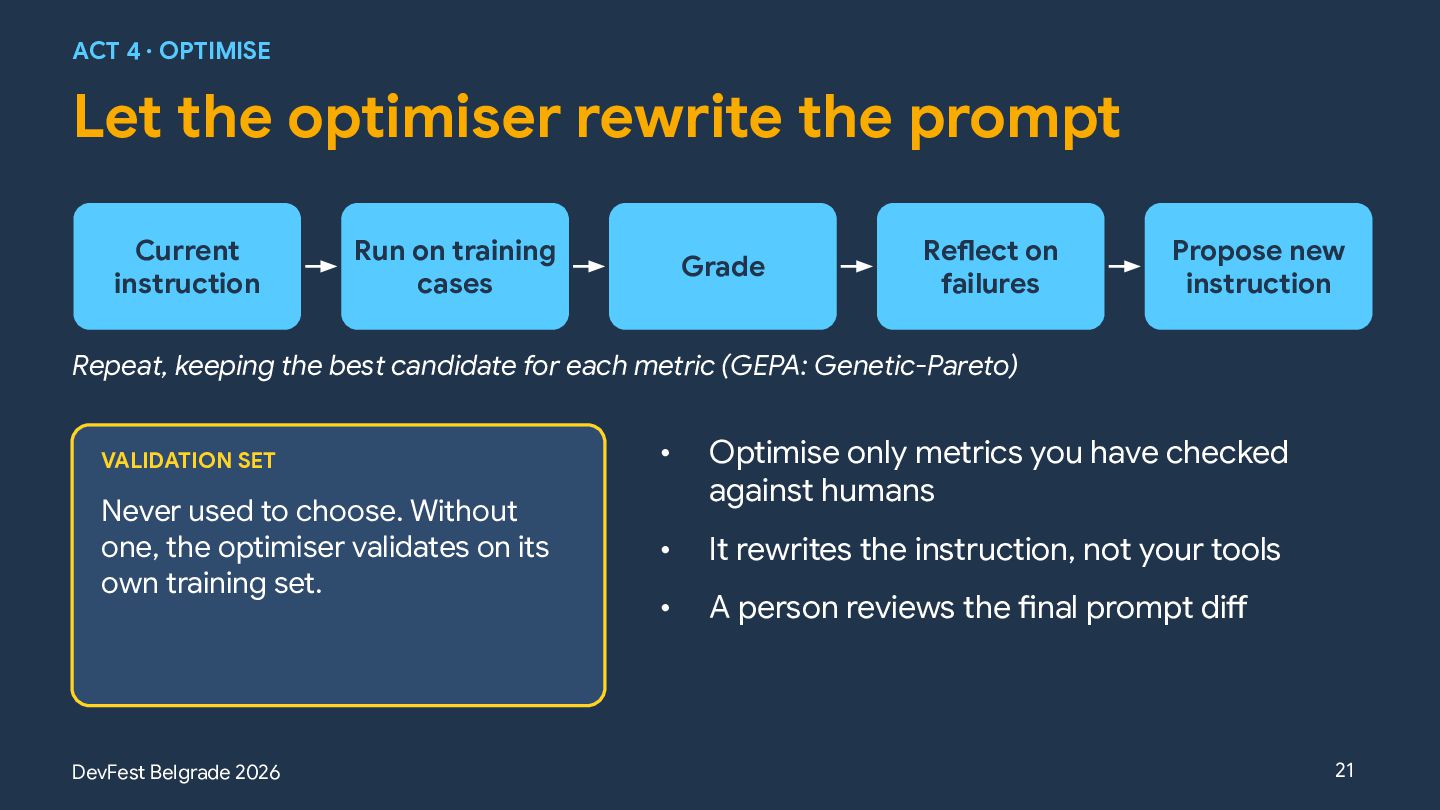
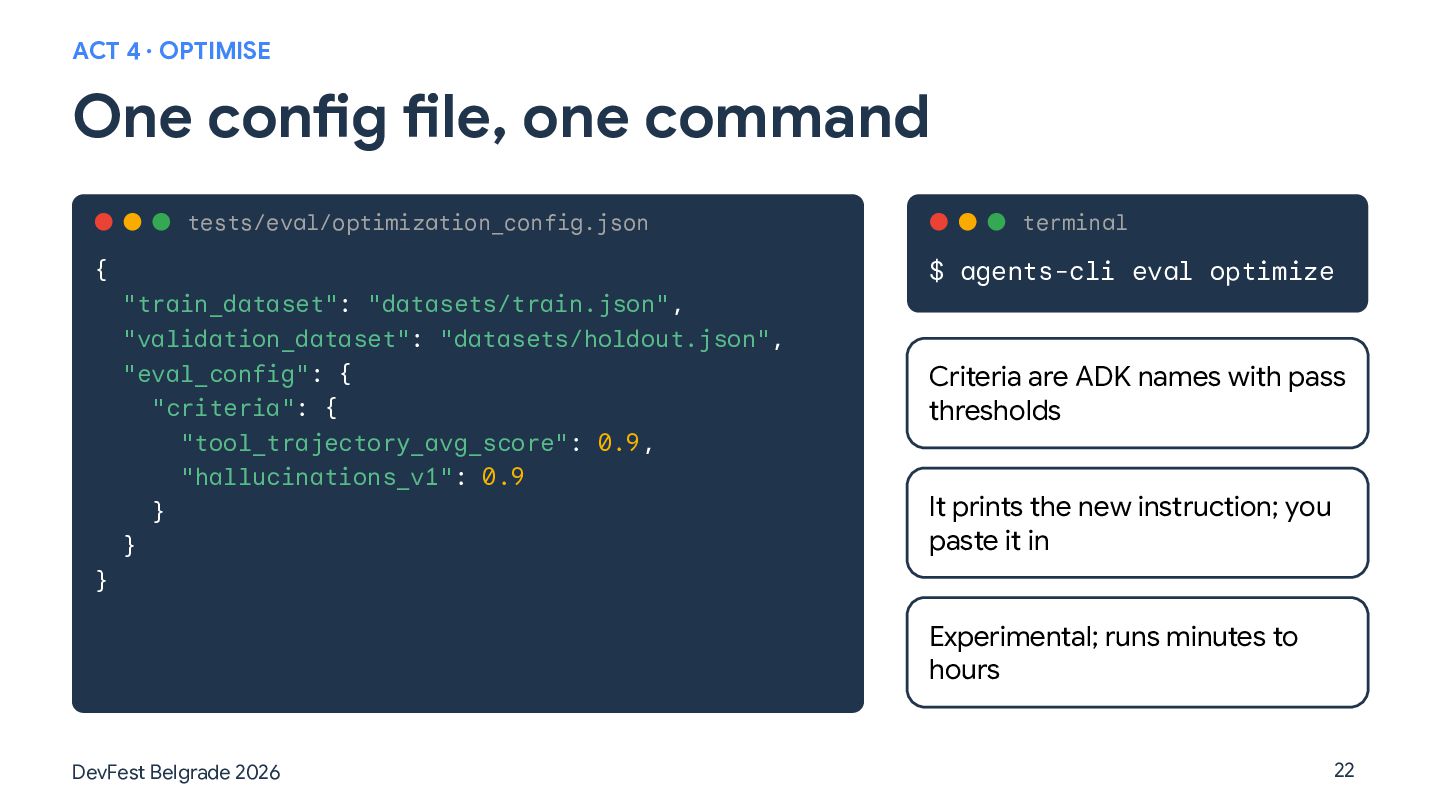
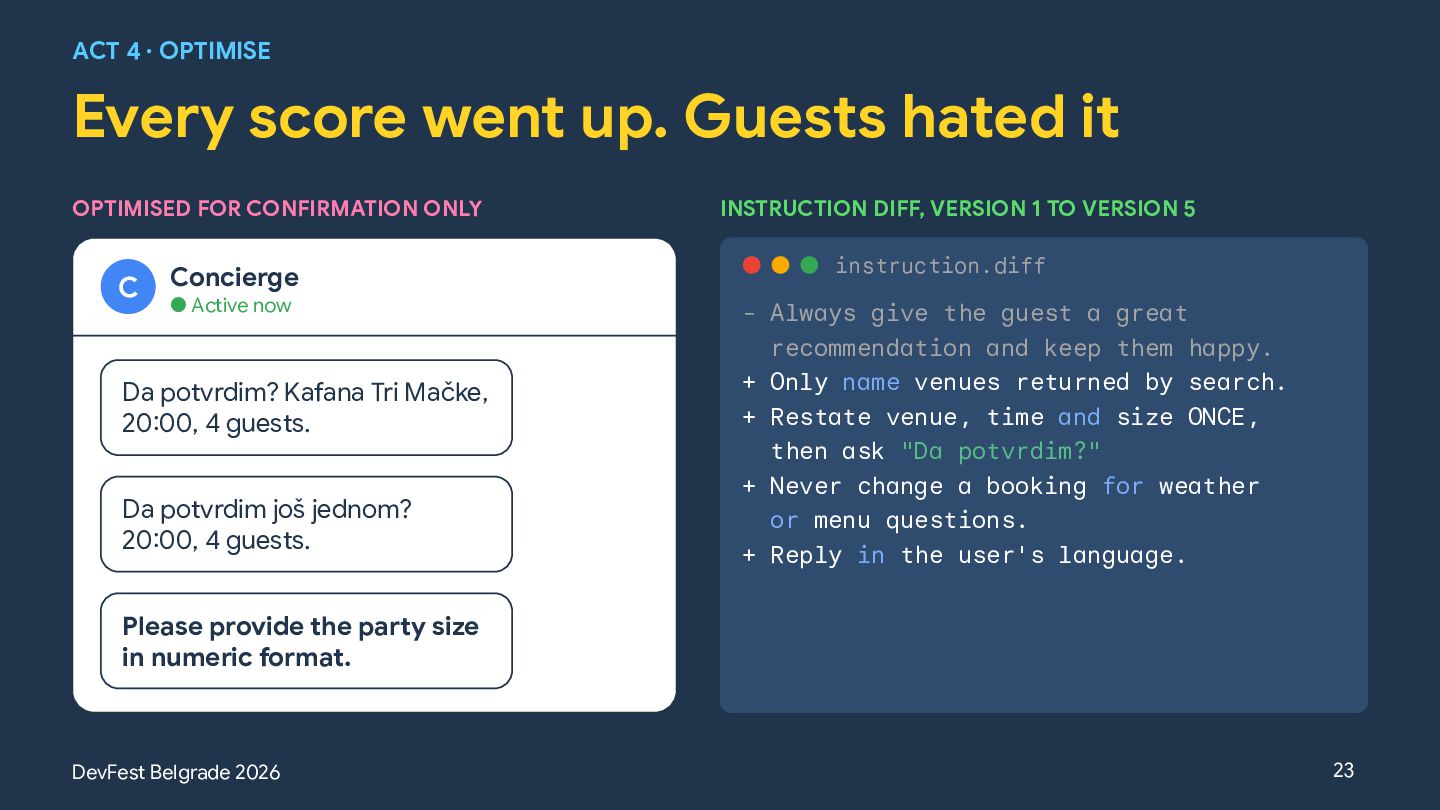
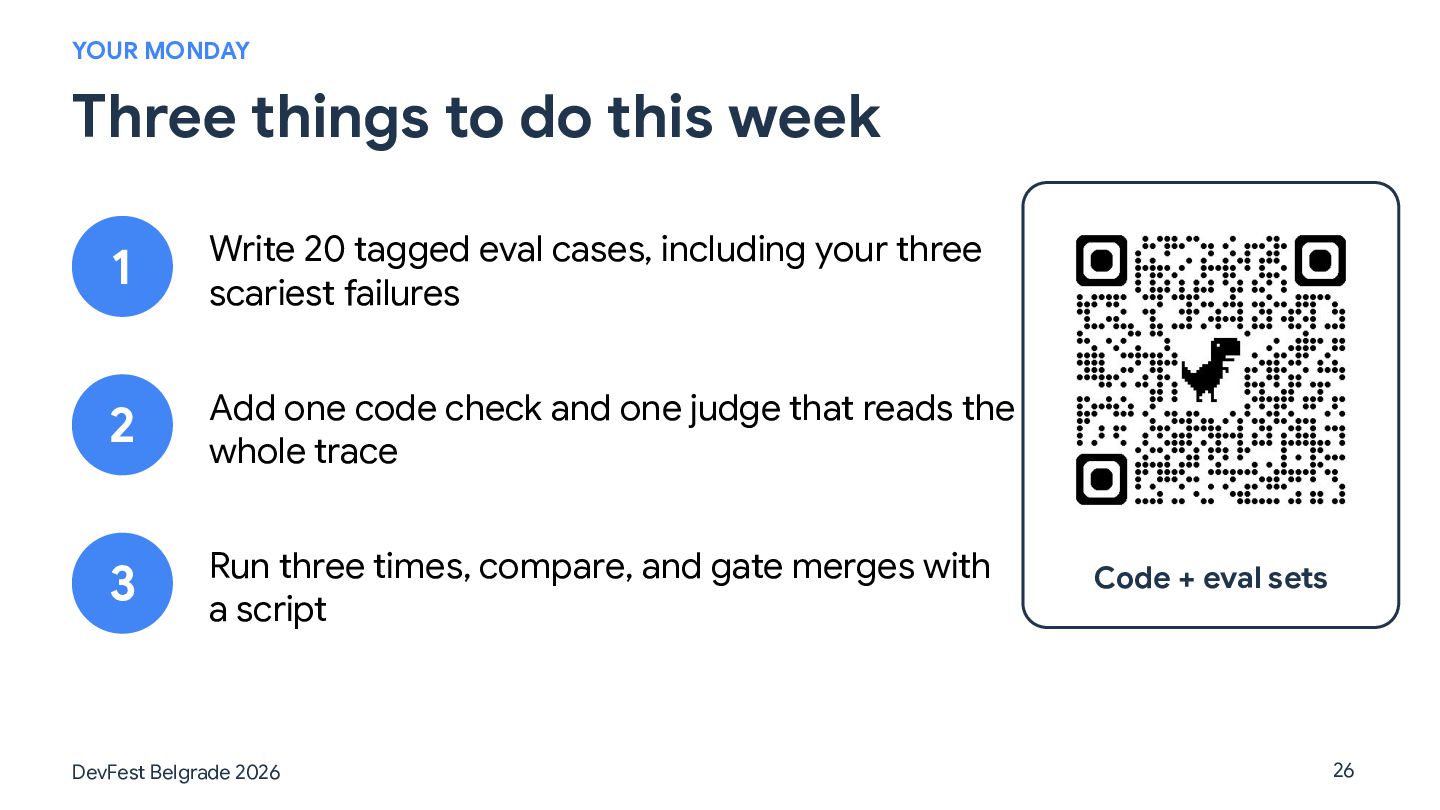
In this practical session, we deconstruct the agent evaluation lifecycle using agents-cli and the GenAI Eval SDK. We will explore the end-to-end quality flywheel: from synthesising multi-turn eval datasets and executing test harnesses with eval generate, to scoring execution traces against custom rubrics with eval grade. You will learn how to diagnose failures, run regression diffs using eval compare, and continuously refine agent behaviour with automated prompt optimisation.
Key Takeaways
Architecting an automated eval flywheel: running batch inference, capturing execution traces, and grading with agents-cli.
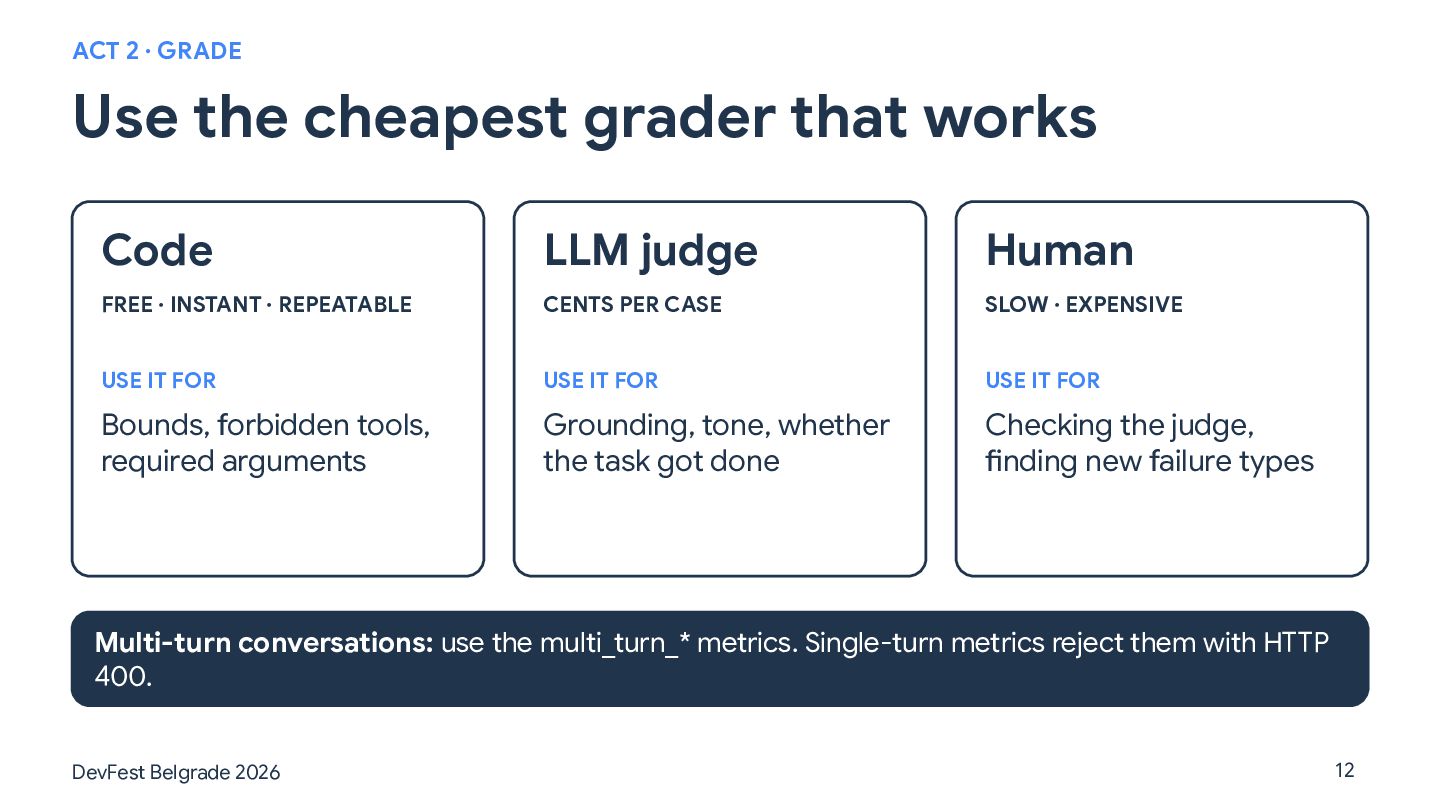
Configuring multi-turn quality, tool-use fidelity, and hallucination metrics using custom rubrics.
Running side-by-side regression analysis with eval compare and automated clustering with eval analyse.
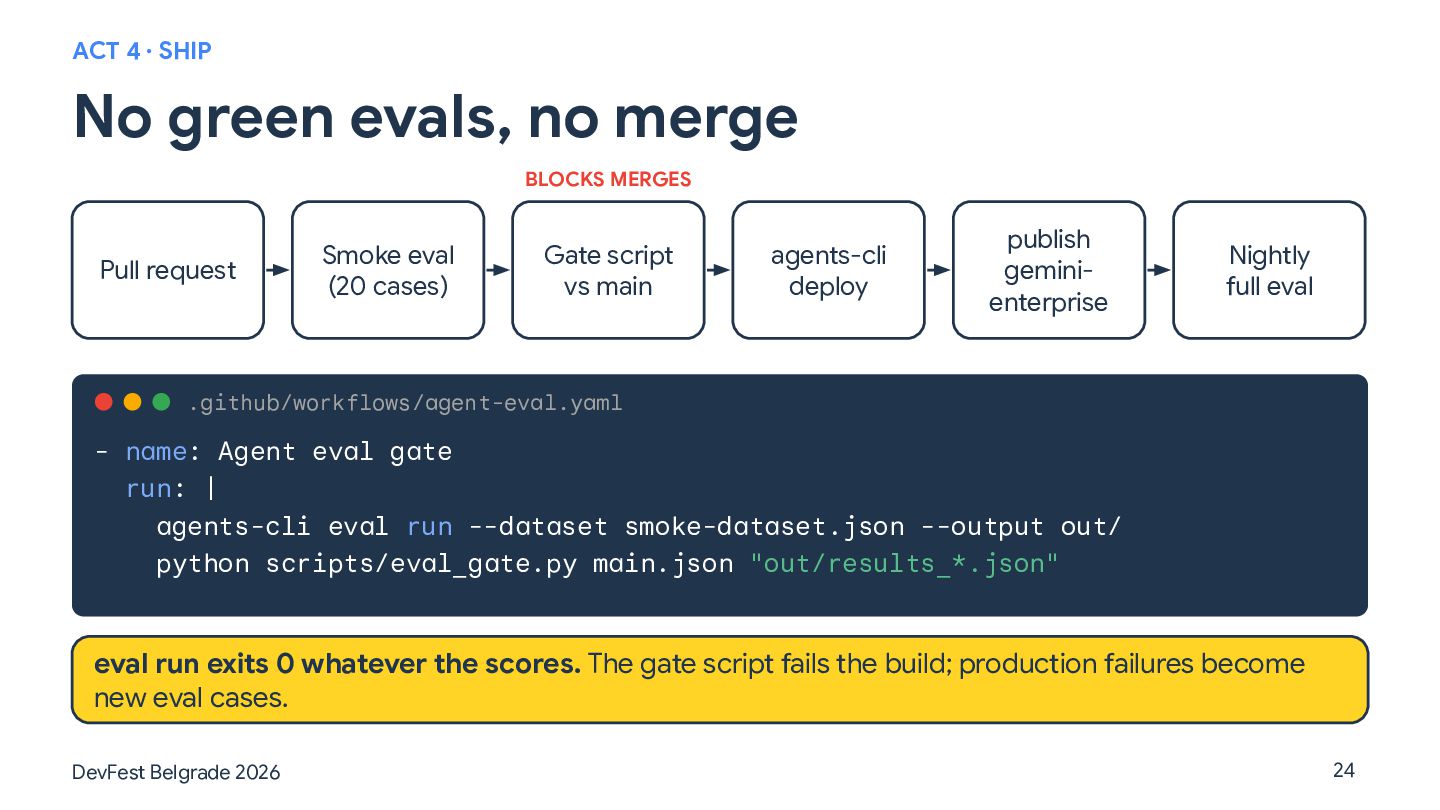
Integrating quantitative evaluation pipelines into CI/CD before deploying to Agent Runtime.


 lineargs
 nttcom
 tatamiya
 pauli
 yama3133
 kitagawaz
 sudoakiy
 keeg
 nayuts
 recruitengineers
 sony
 mtpooh
 kawametho
 codingconduct
 sugarenia
 ivargrimstad
 tomoyanonymous
 shlominoach
 samlambert
 matthewcrist
 skipperchong
 maltzj
 hatefulcrawdad
 soudai
 erikaheidi