Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Command line & Data Science
Search
Yatish Mehta
October 28, 2014
64
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Command line & Data Science
Yatish Mehta
October 28, 2014
More Decks by Yatish Mehta
See All by Yatish Mehta
Shore | A modern Ruby on Rails template to start your next project
yatish27
0
140
Taming The Rails Monolith Mammoth
yatish27
0
51
ActionCable and ReactJS tie the knot
yatish27
1
290
Featured
See All Featured
30 Presentation Tips
portentint
PRO
1
460
Unsuck your backbone
ammeep
672
58k
Art, The Web, and Tiny UX
lynnandtonic
304
22k
Large-scale JavaScript Application Architecture
addyosmani
516
110k
Design in an AI World
tapps
1
390
Taking LLMs out of the black box: A practical guide to human-in-the-loop distillation
inesmontani
PRO
3
2.5k
State of Search Keynote: SEO is Dead Long Live SEO
ryanjones
0
350
コードの90%をAIが書く世界で何が待っているのか / What awaits us in a world where 90% of the code is written by AI
rkaga
63
48k
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
Collaborative Software Design: How to facilitate domain modelling decisions
baasie
1
370
The browser strikes back
jonoalderson
0
1.9k
Building Experiences: Design Systems, User Experience, and Full Site Editing
marktimemedia
1
660
Transcript
Yatish Mehta @yatish27
Command line & Data Science
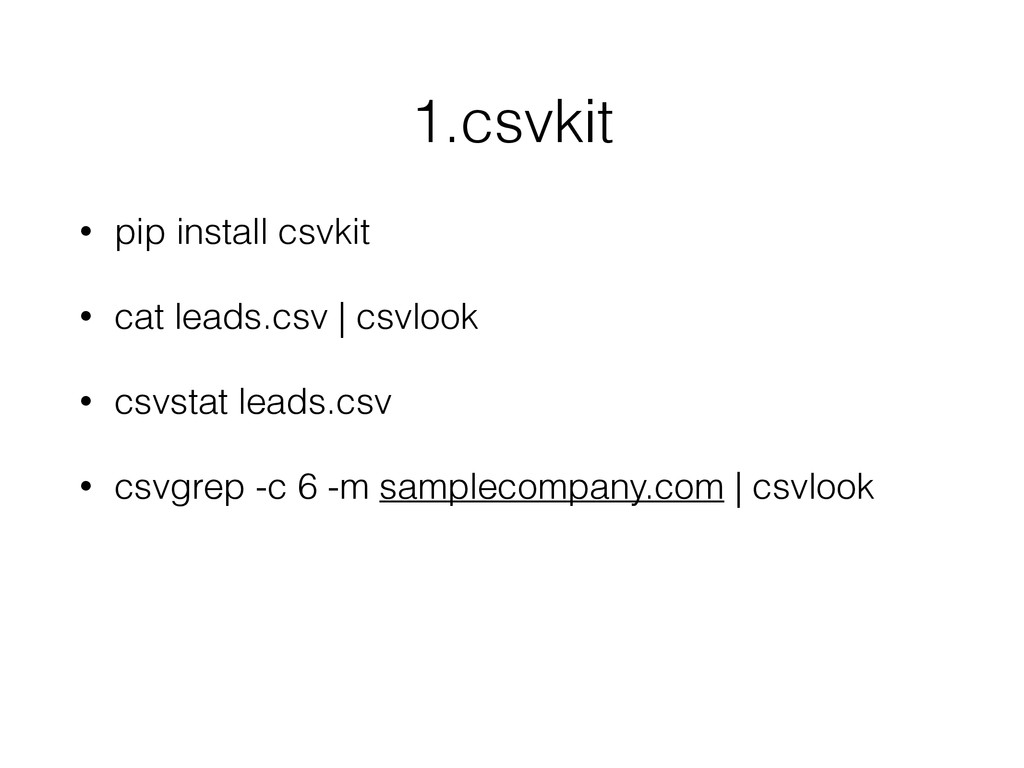
• pip install csvkit • cat leads.csv | csvlook •
csvstat leads.csv • csvgrep -c 6 -m samplecompany.com | csvlook 1.csvkit
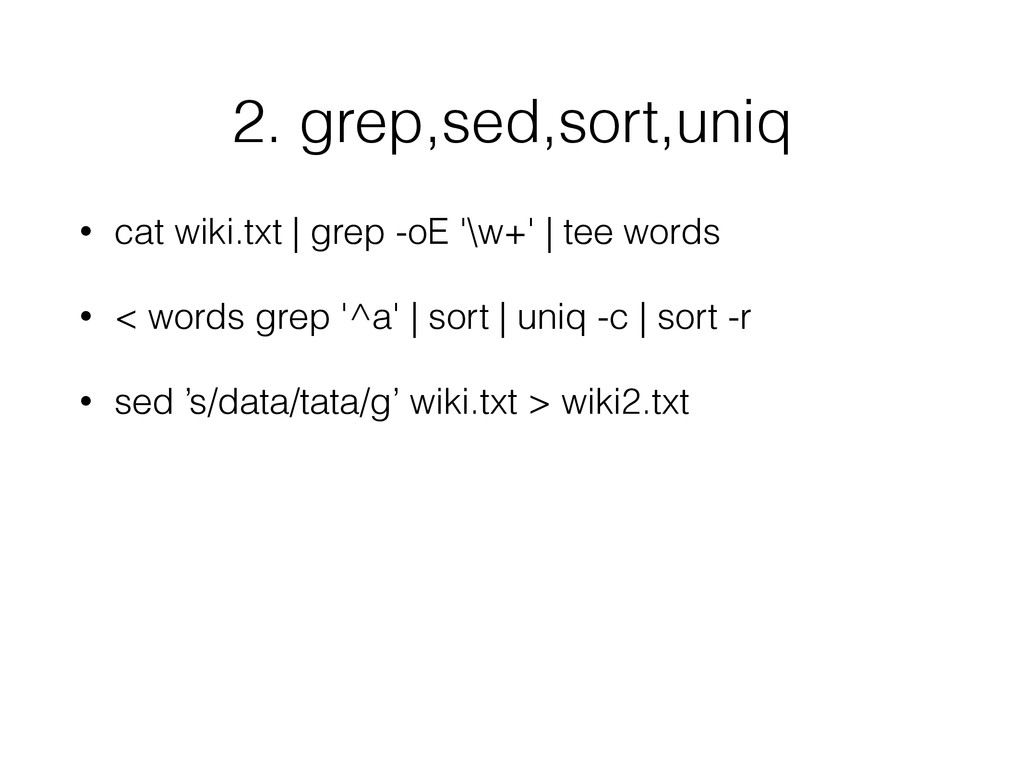
2. grep,sed,sort,uniq • cat wiki.txt | grep -oE '\w+' |
tee words • < words grep '^a' | sort | uniq -c | sort -r • sed ’s/data/tata/g’ wiki.txt > wiki2.txt
• brew install jq • < data.json jq ‘.[]’ •
< data.json jq ‘.[] | select(.age>22)’ • cat data.json | jq '.[] | {isActive: ._id, name: .name}' 3. jq JSON processor
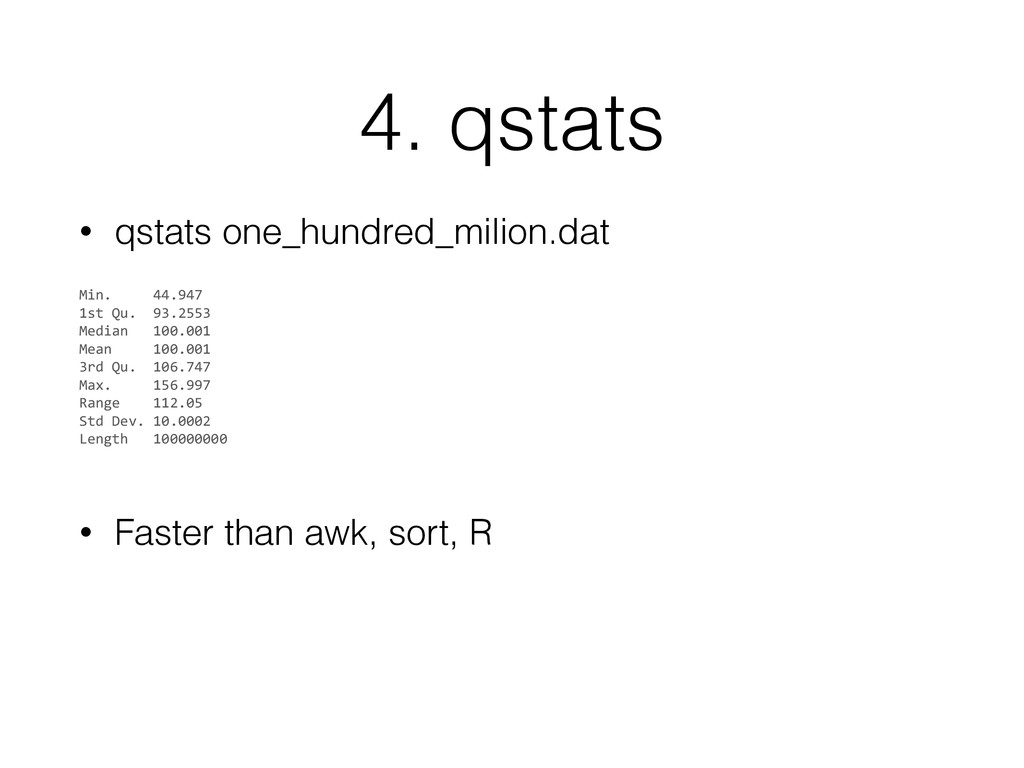
4. qstats • qstats one_hundred_milion.dat Min.
44.947 1st Qu. 93.2553 Median 100.001 Mean 100.001 3rd Qu. 106.747 Max. 156.997 Range 112.05 Std Dev. 10.0002 Length 100000000 • Faster than awk, sort, R
5. parallel • iterative • shell parallel.sh , each action
as a job • parallel keyword
Thank You


 yatish27
 portentint
 ammeep
 lynnandtonic
 addyosmani
 tapps
 inesmontani
 ryanjones
 rkaga
 tammyeverts
 baasie
 jonoalderson
 marktimemedia