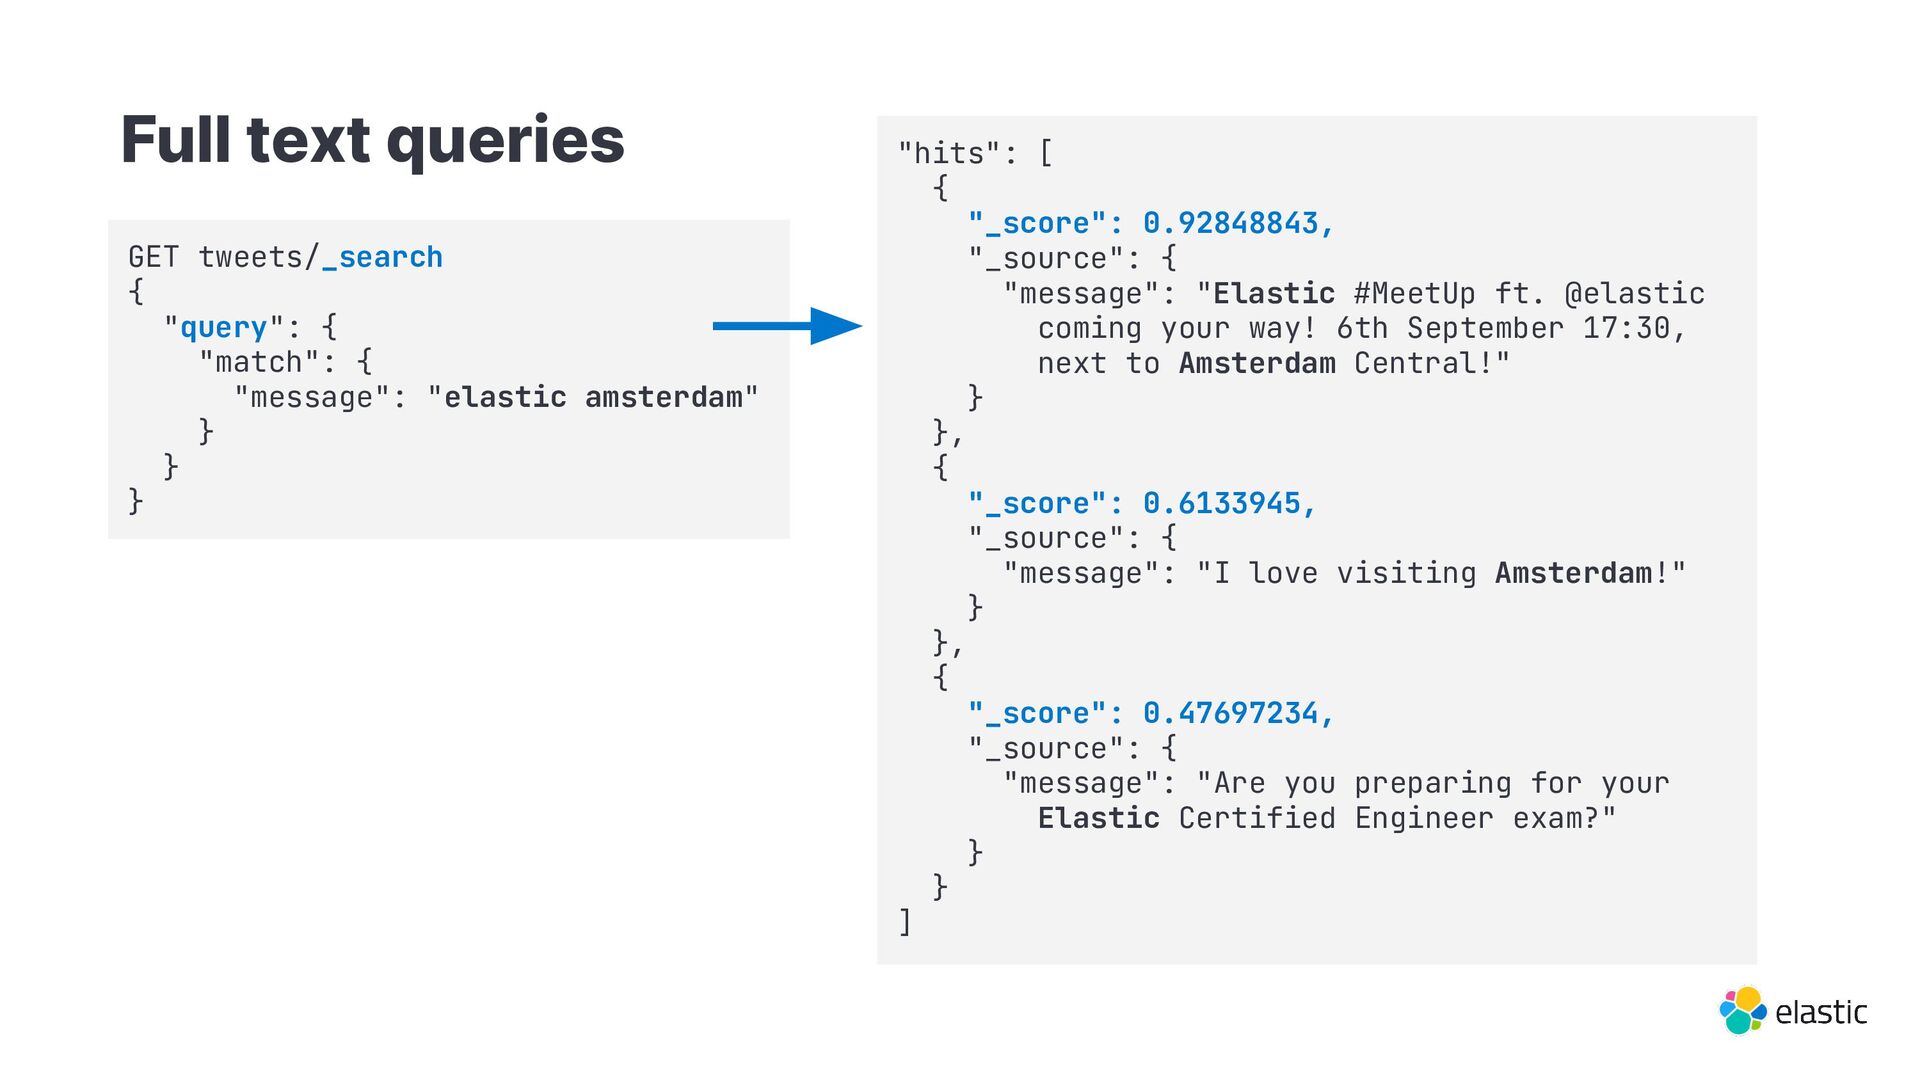
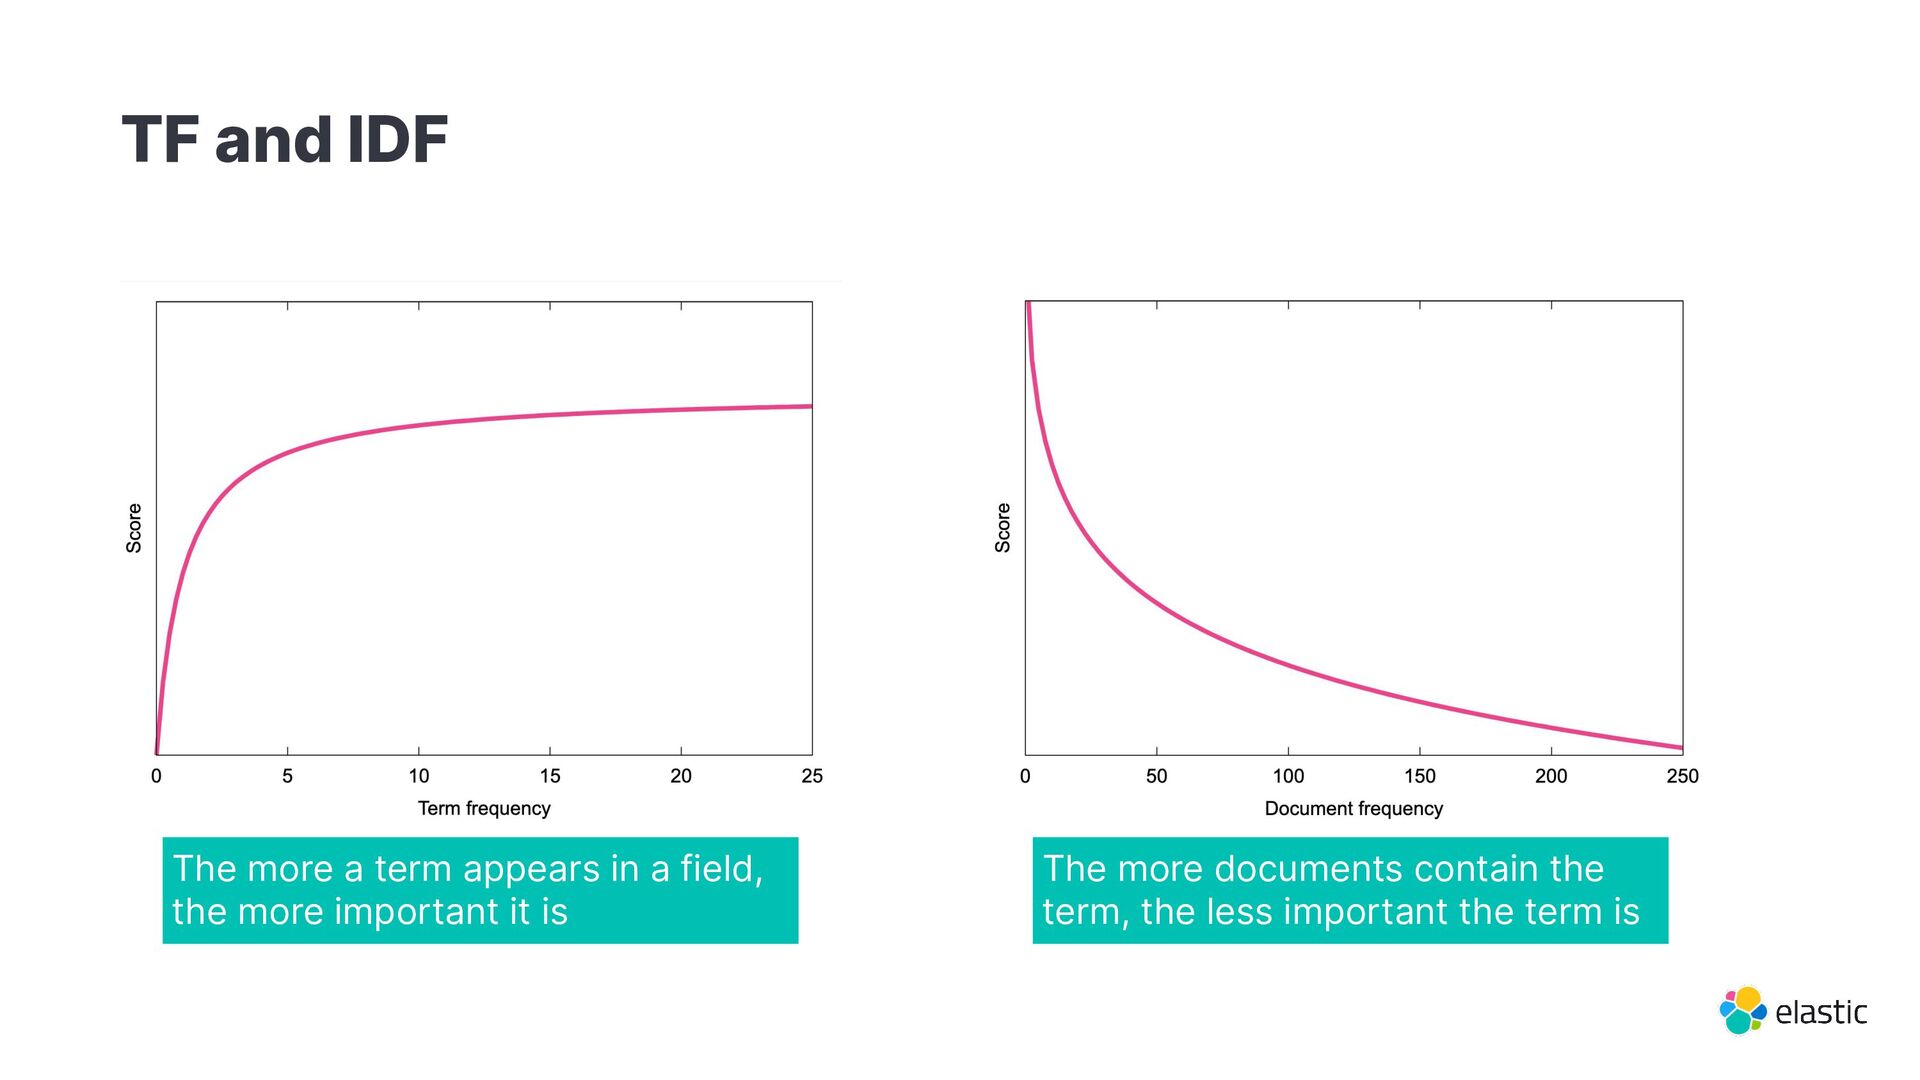
the relevance of a hit with respect to the query • Default scoring algorithm is BM25/BM25F • Three elements determine a document’s score: ◦ TF (term frequency): the more a term appears in a field, the more important it is ◦ IDF (inverse document frequency): the more documents that contain the term, the less important the term is ◦ field length: shorter fields are more likely to be relevant than longer fields
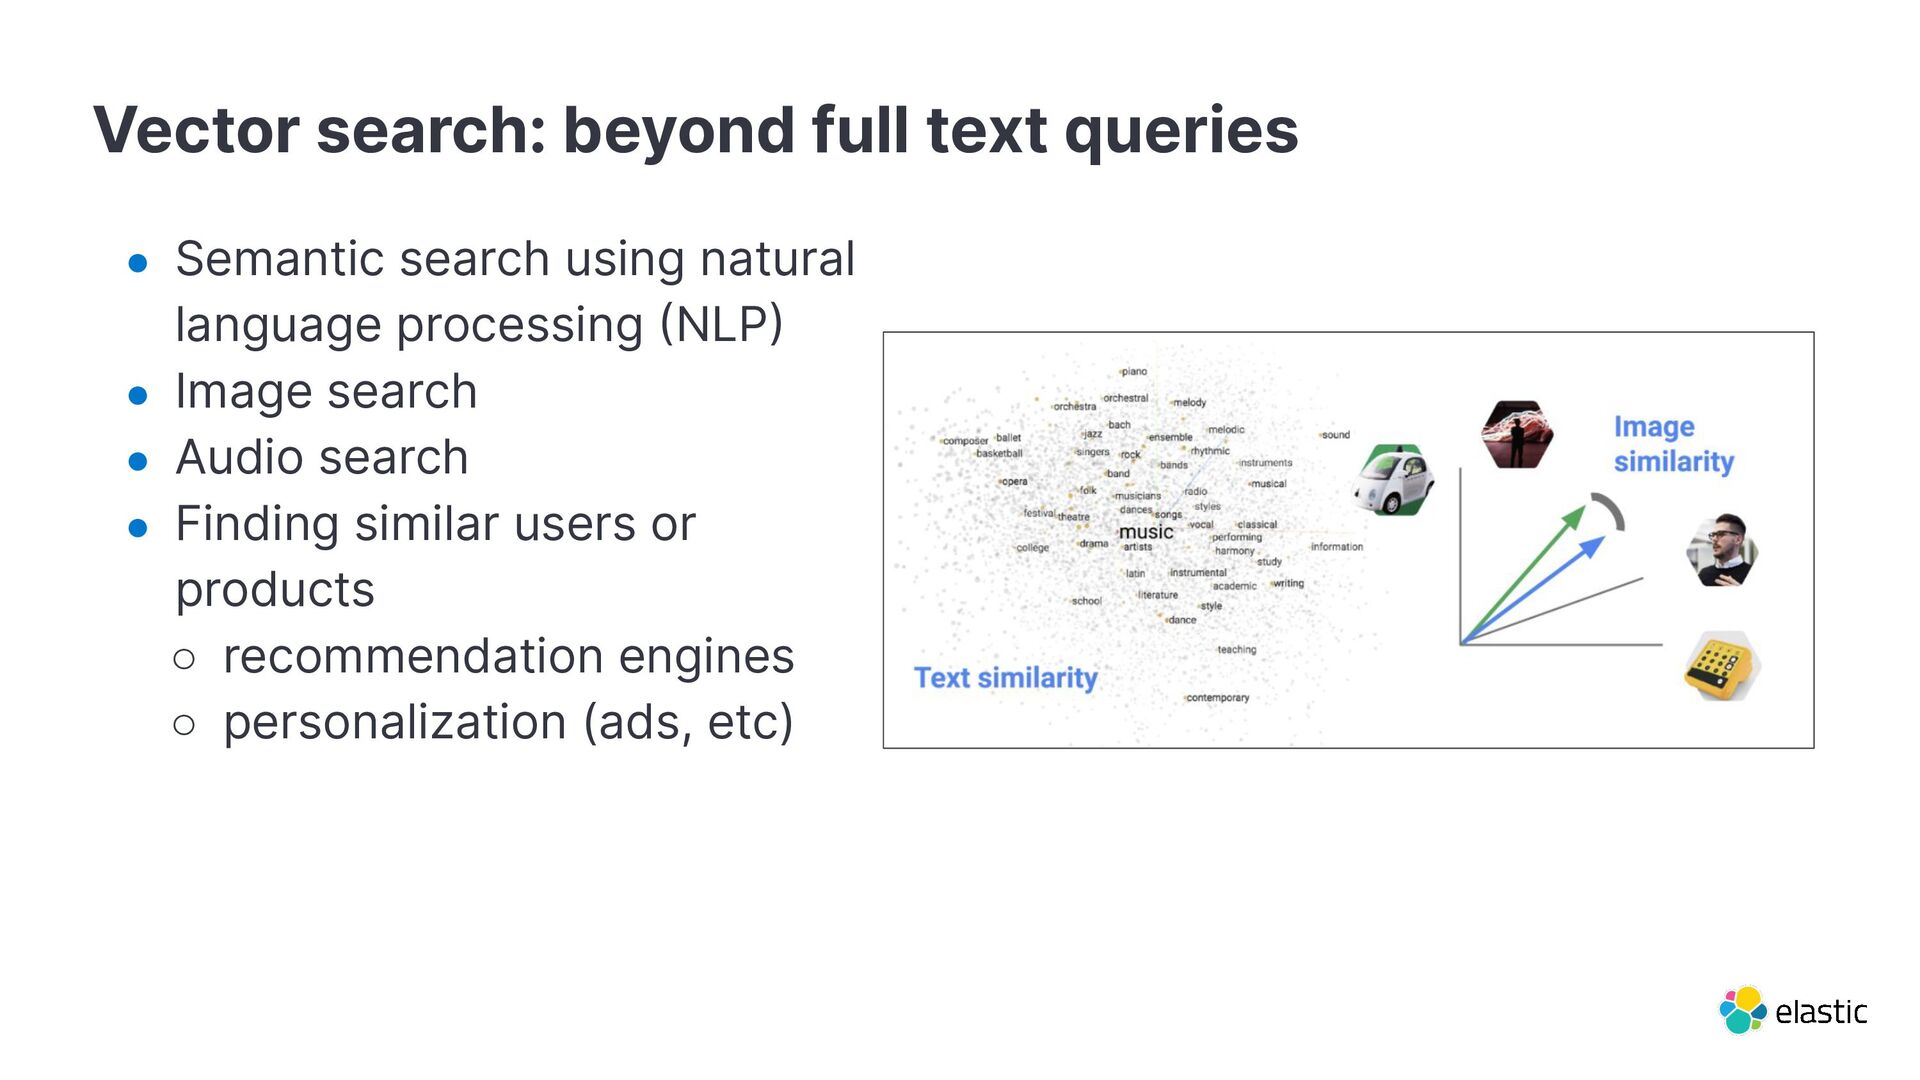
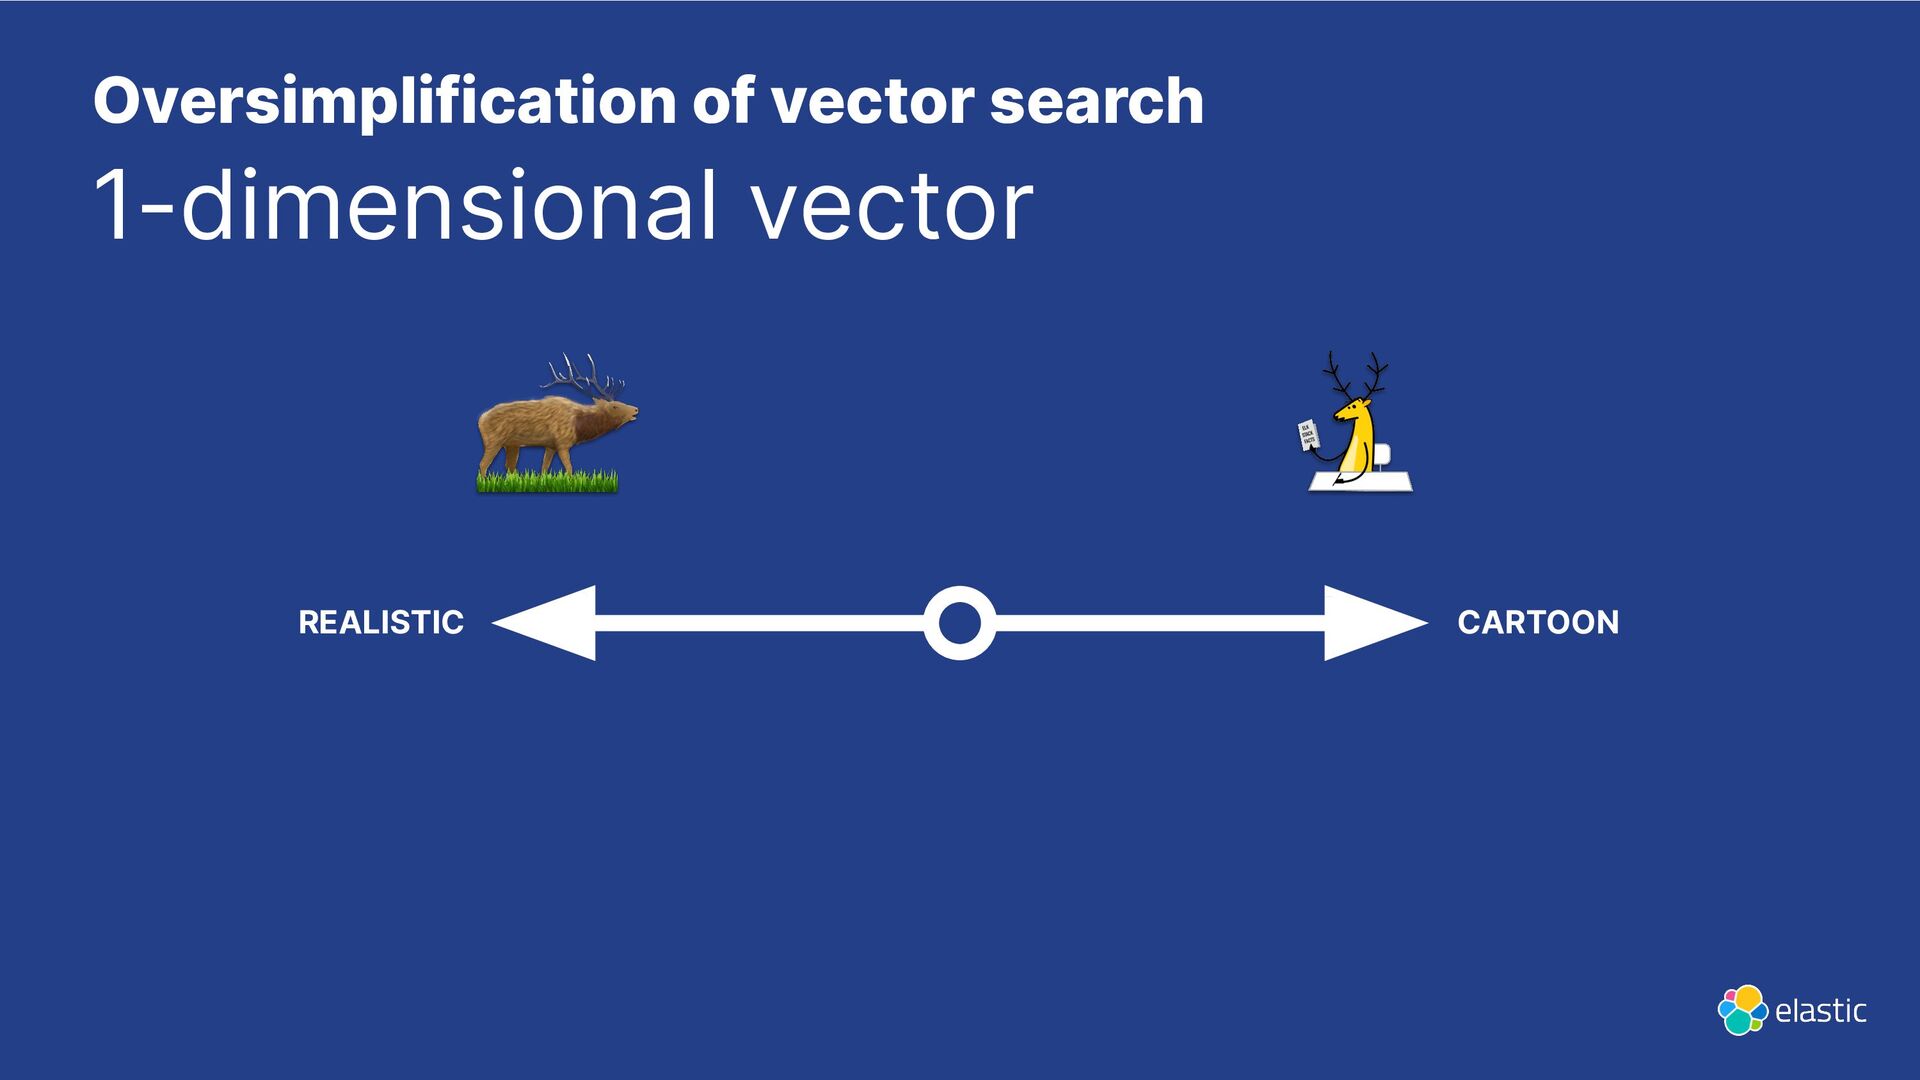
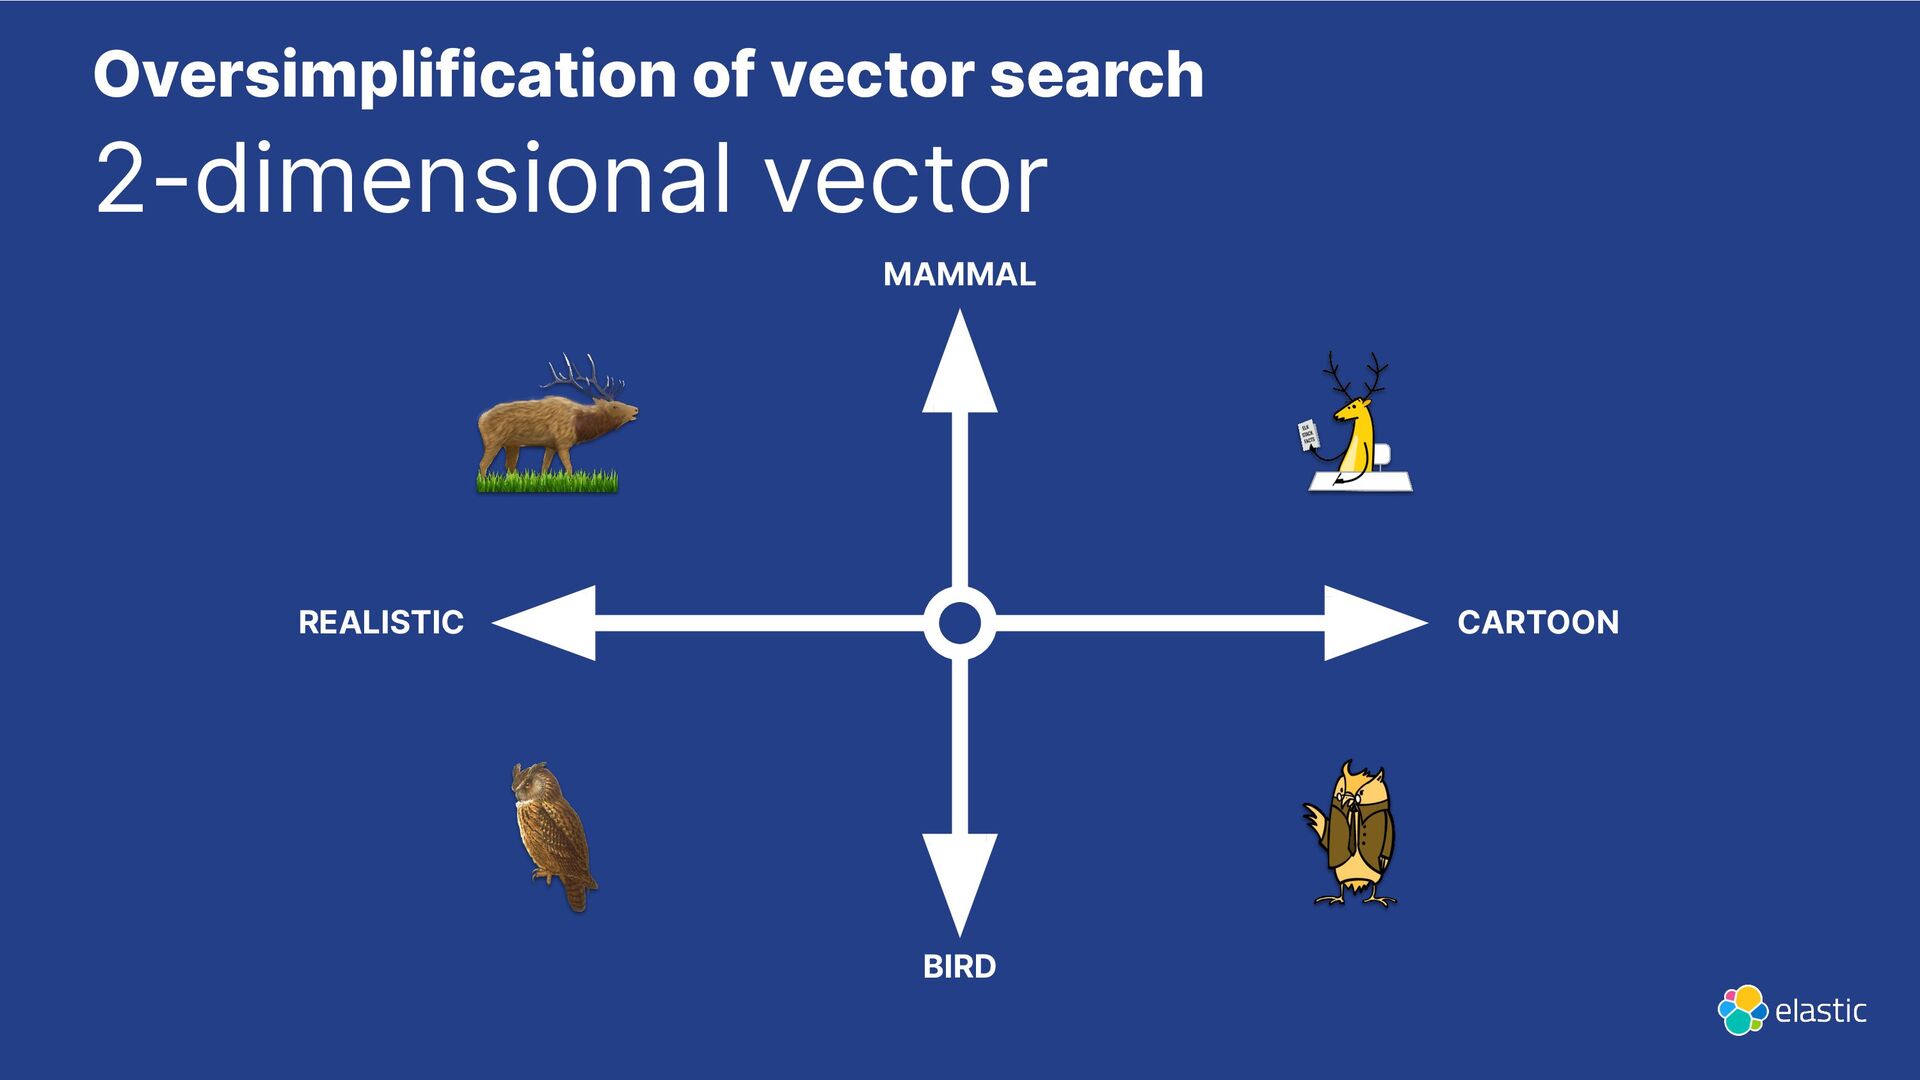
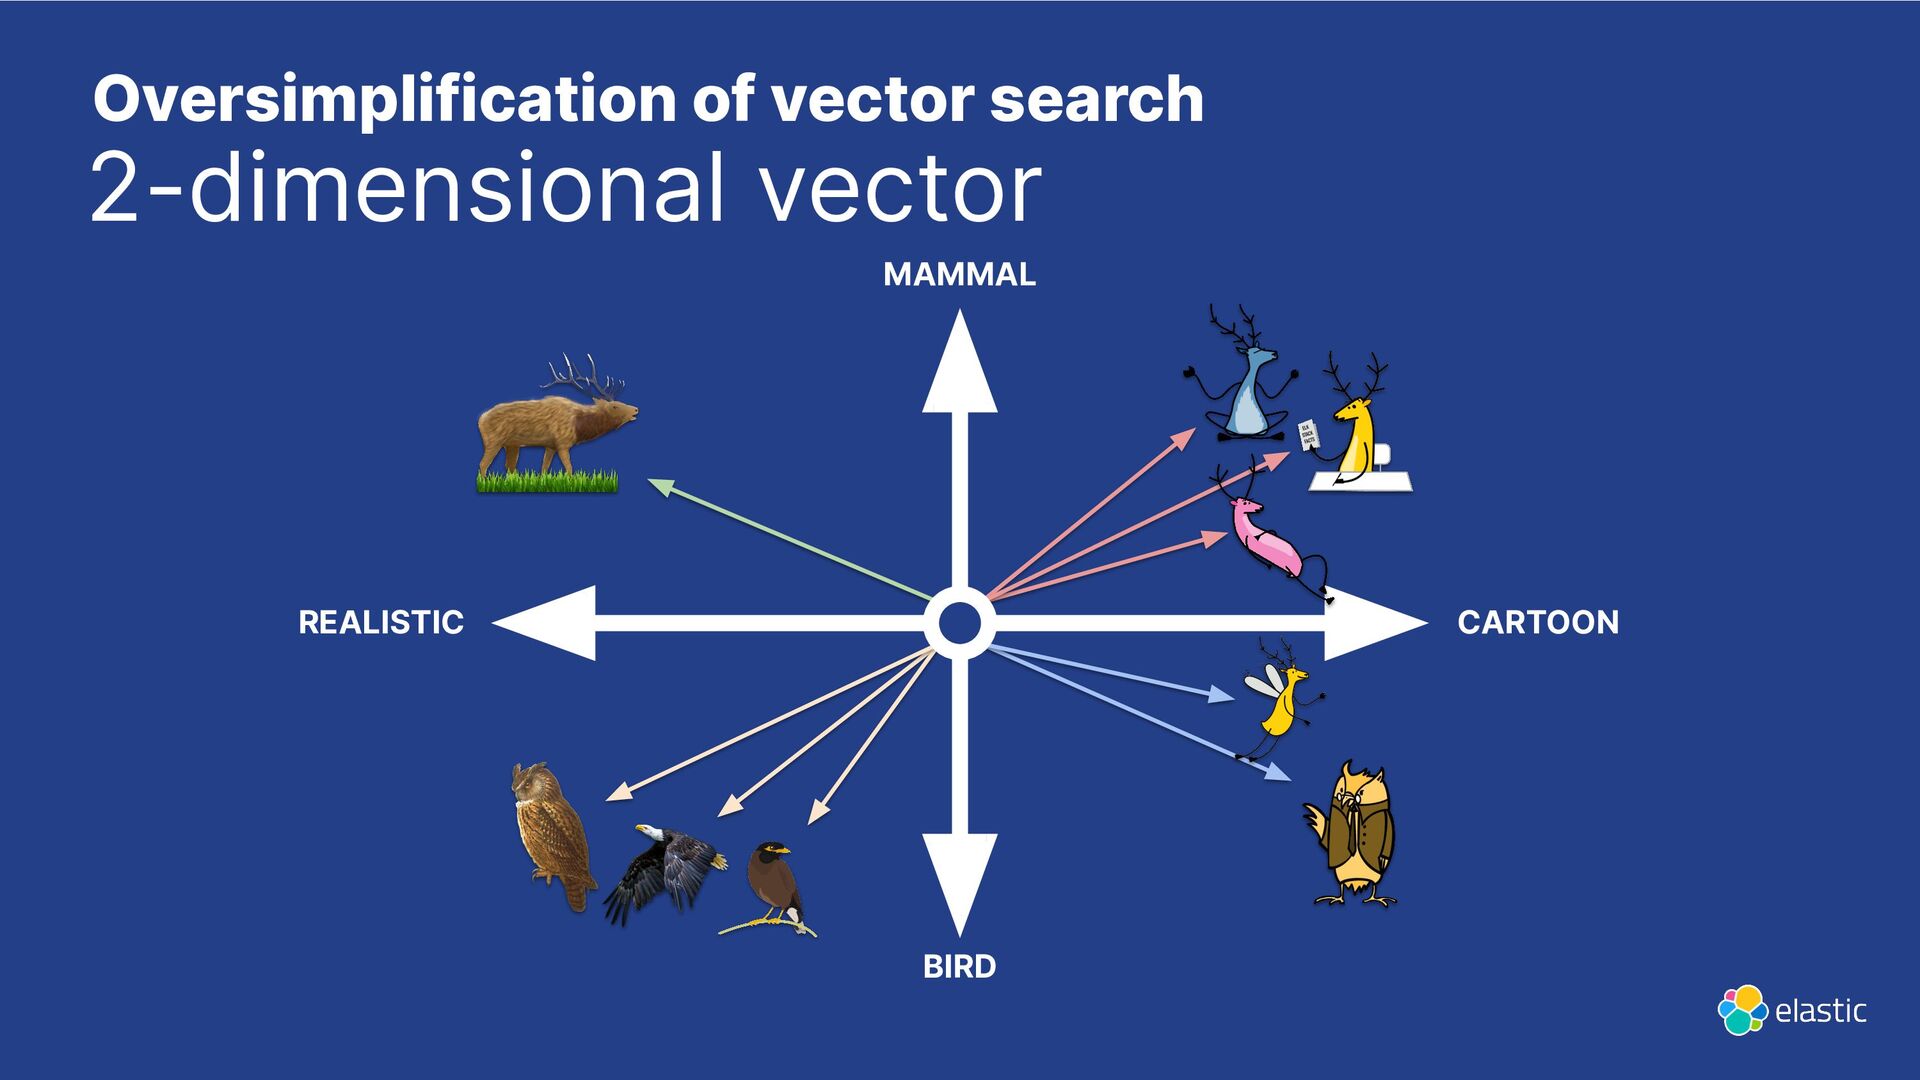
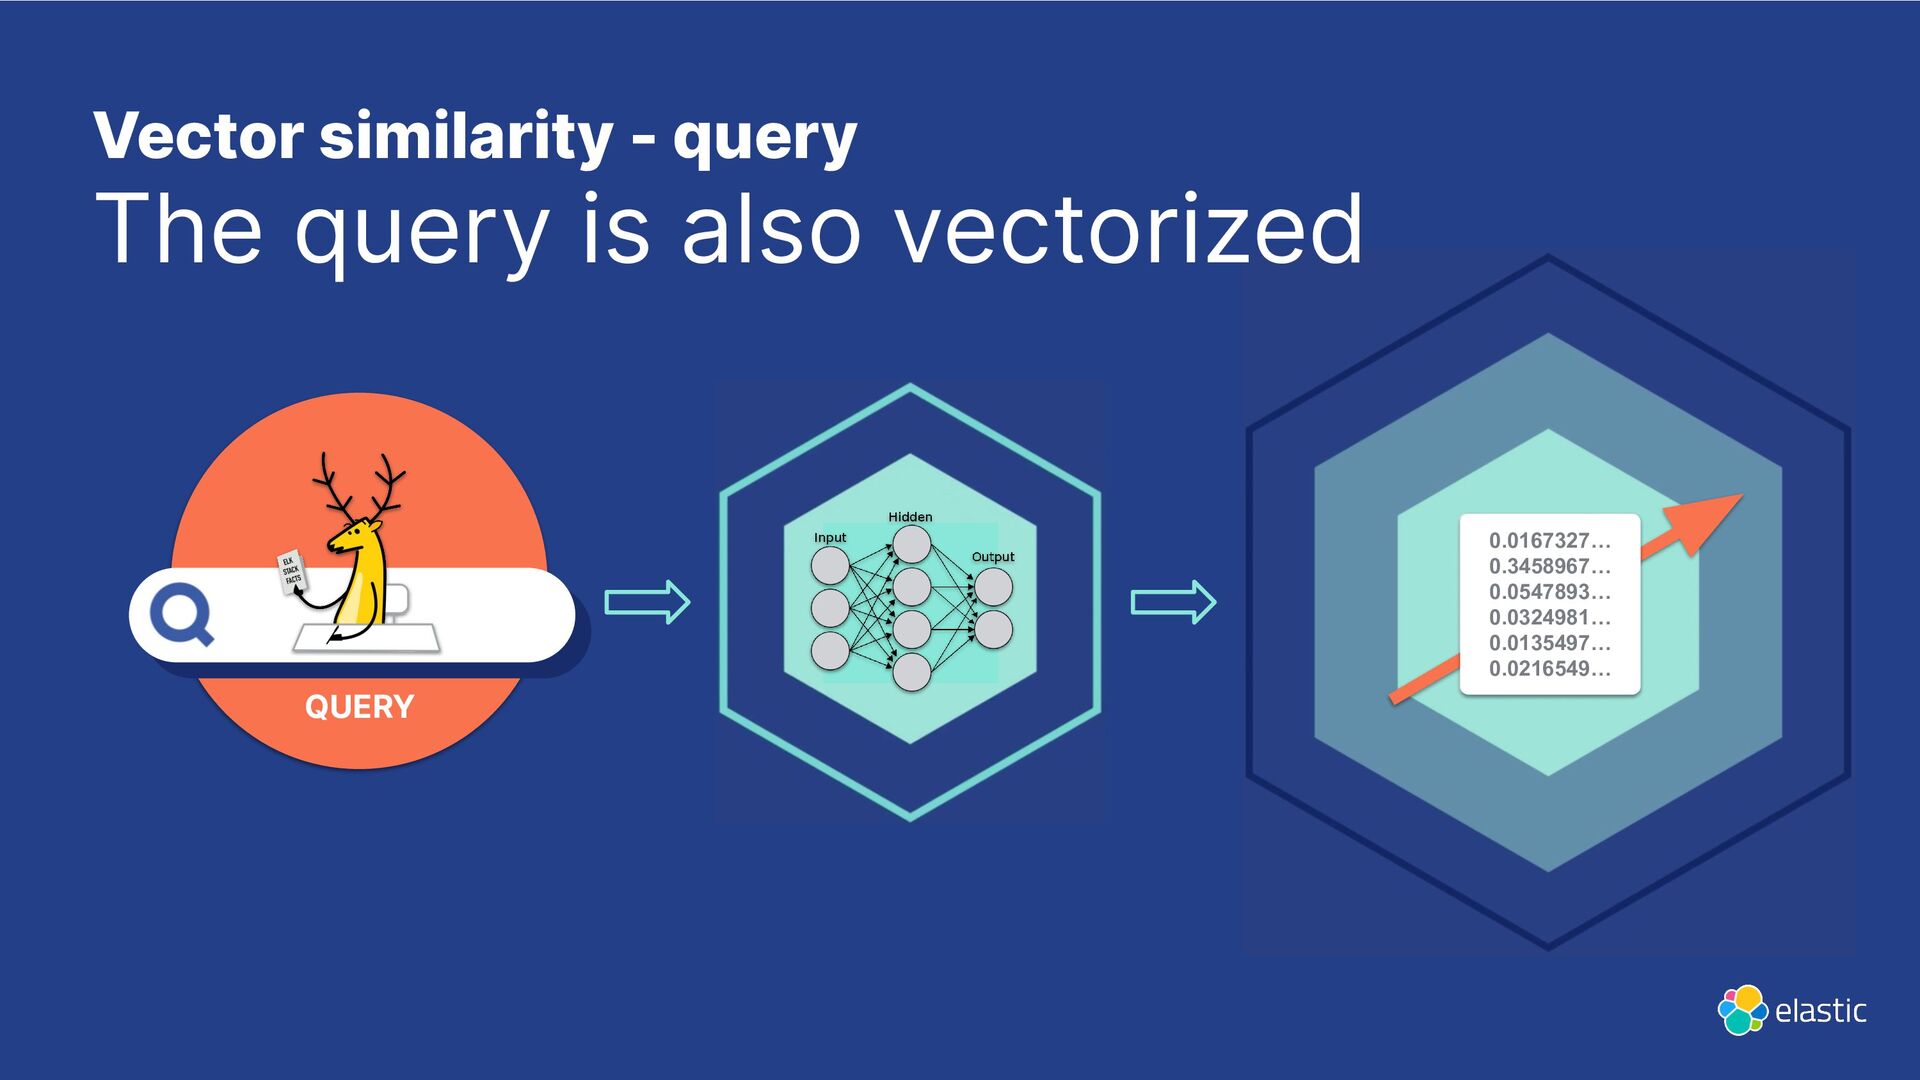
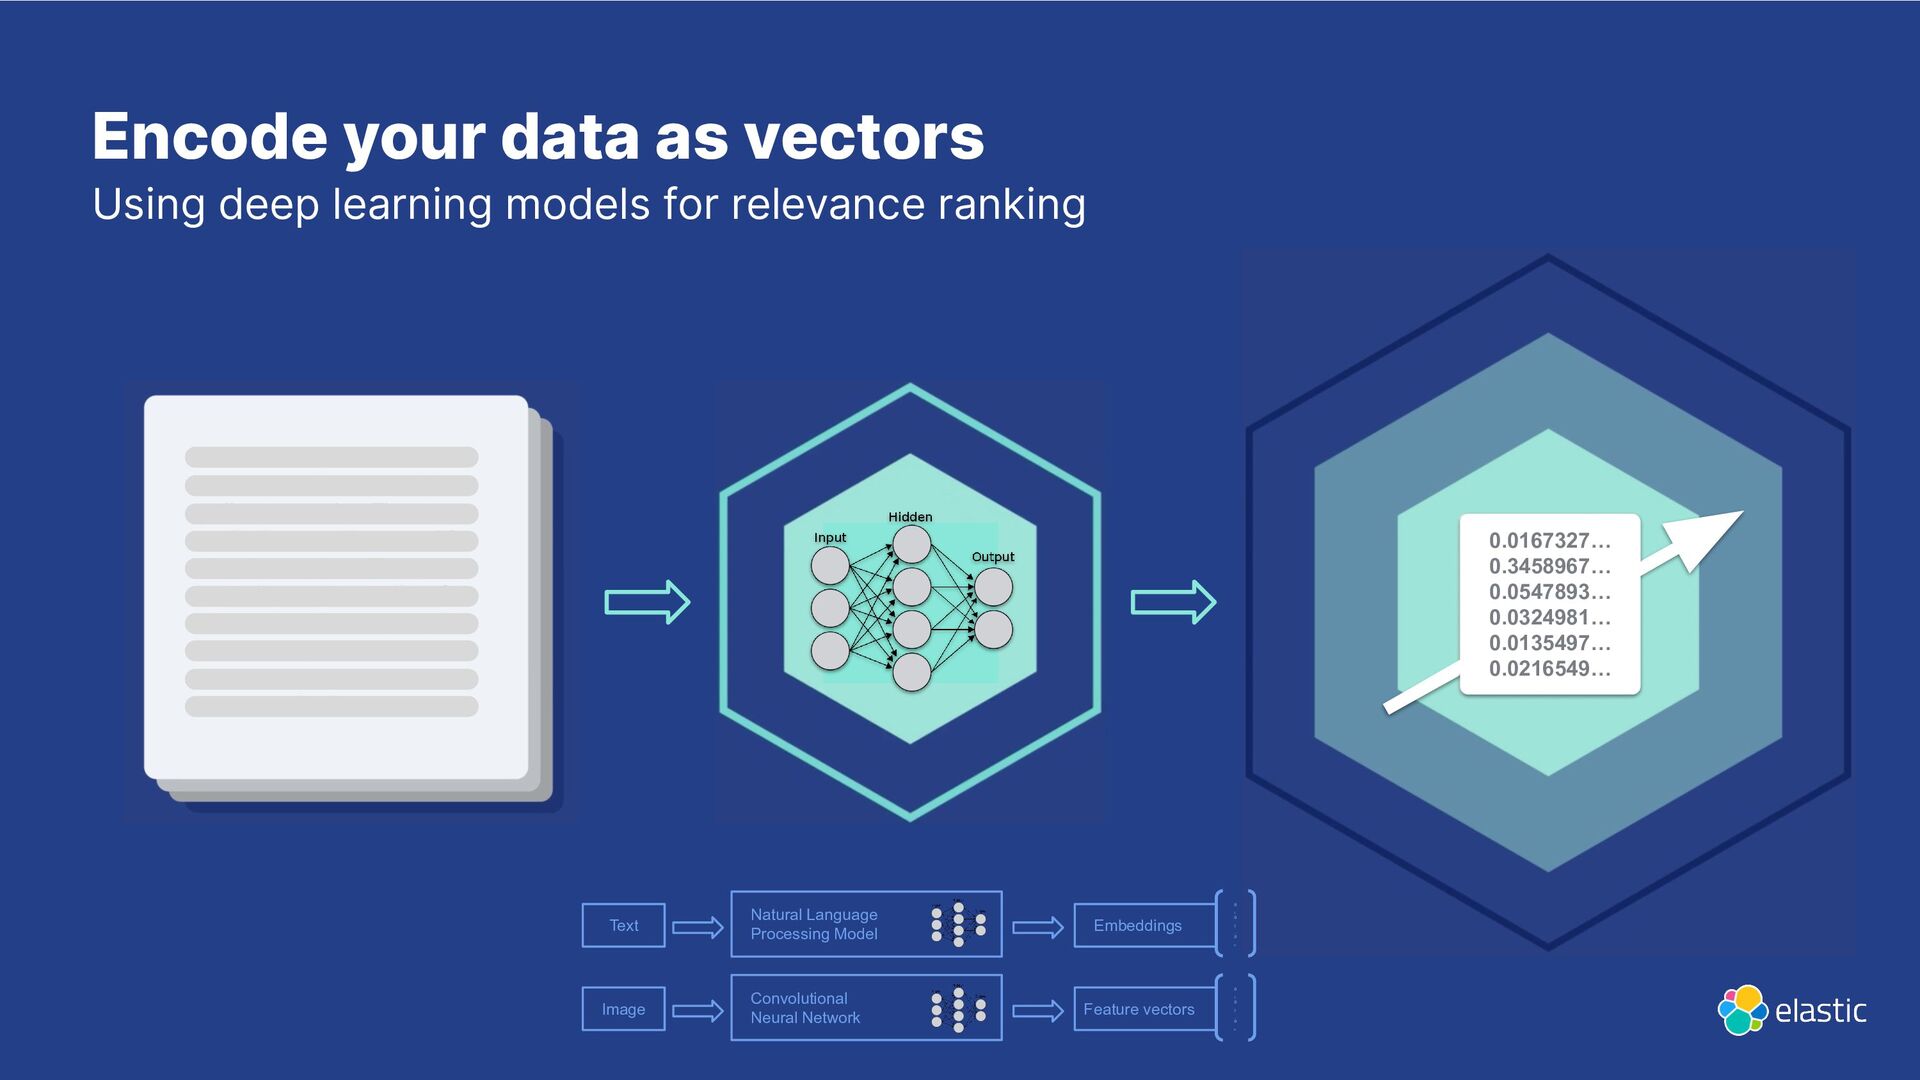
relevance ranking Natural Language Processing Model Text Convolutional Neural Network Image Embeddings Feature vectors a 1 a 2 … a n a 1 a 2 … a n 0.0167327… 0.3458967… 0.0547893… 0.0324981… 0.0135497… 0.0216549…
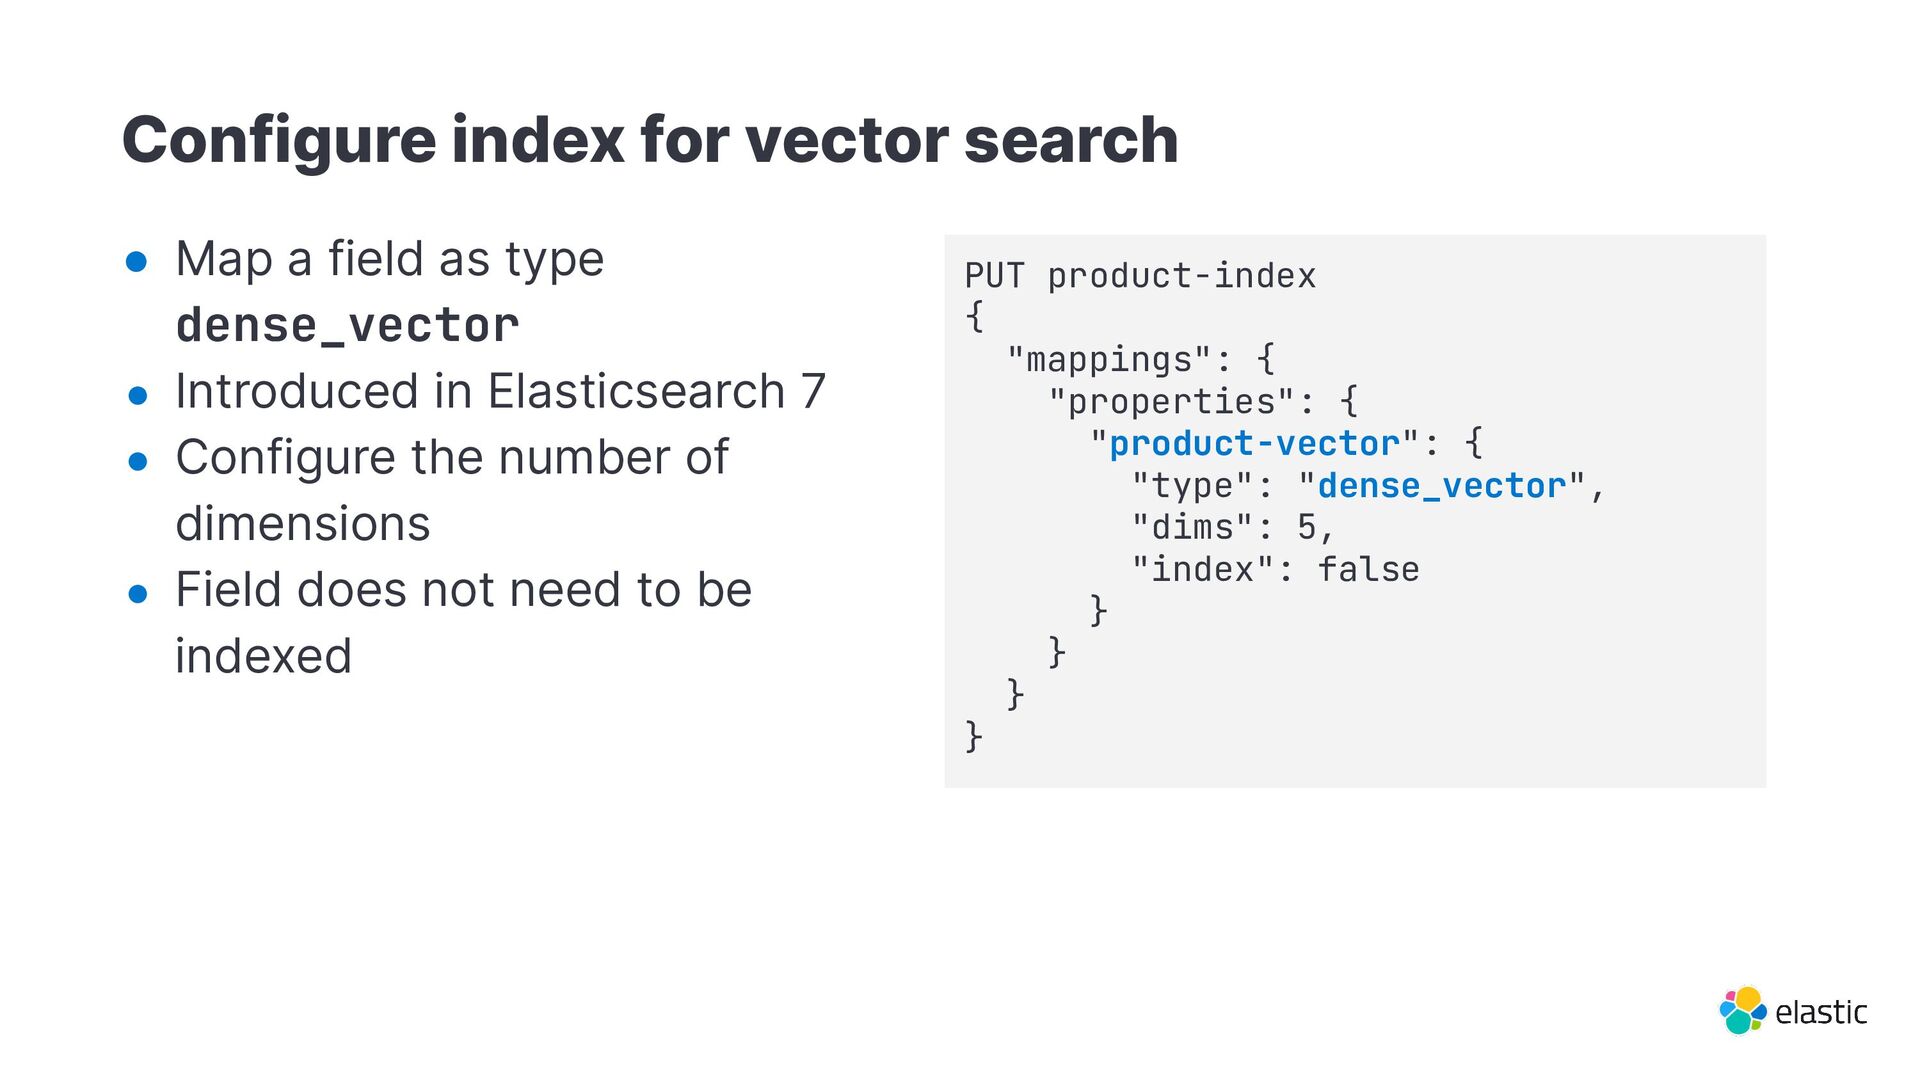
type dense_vector • Introduced in Elasticsearch 7 • Configure the number of dimensions • Field does not need to be indexed PUT product-index { "mappings": { "properties": { "product-vector": { "type": "dense_vector", "dims": 5, "index": false } } } }
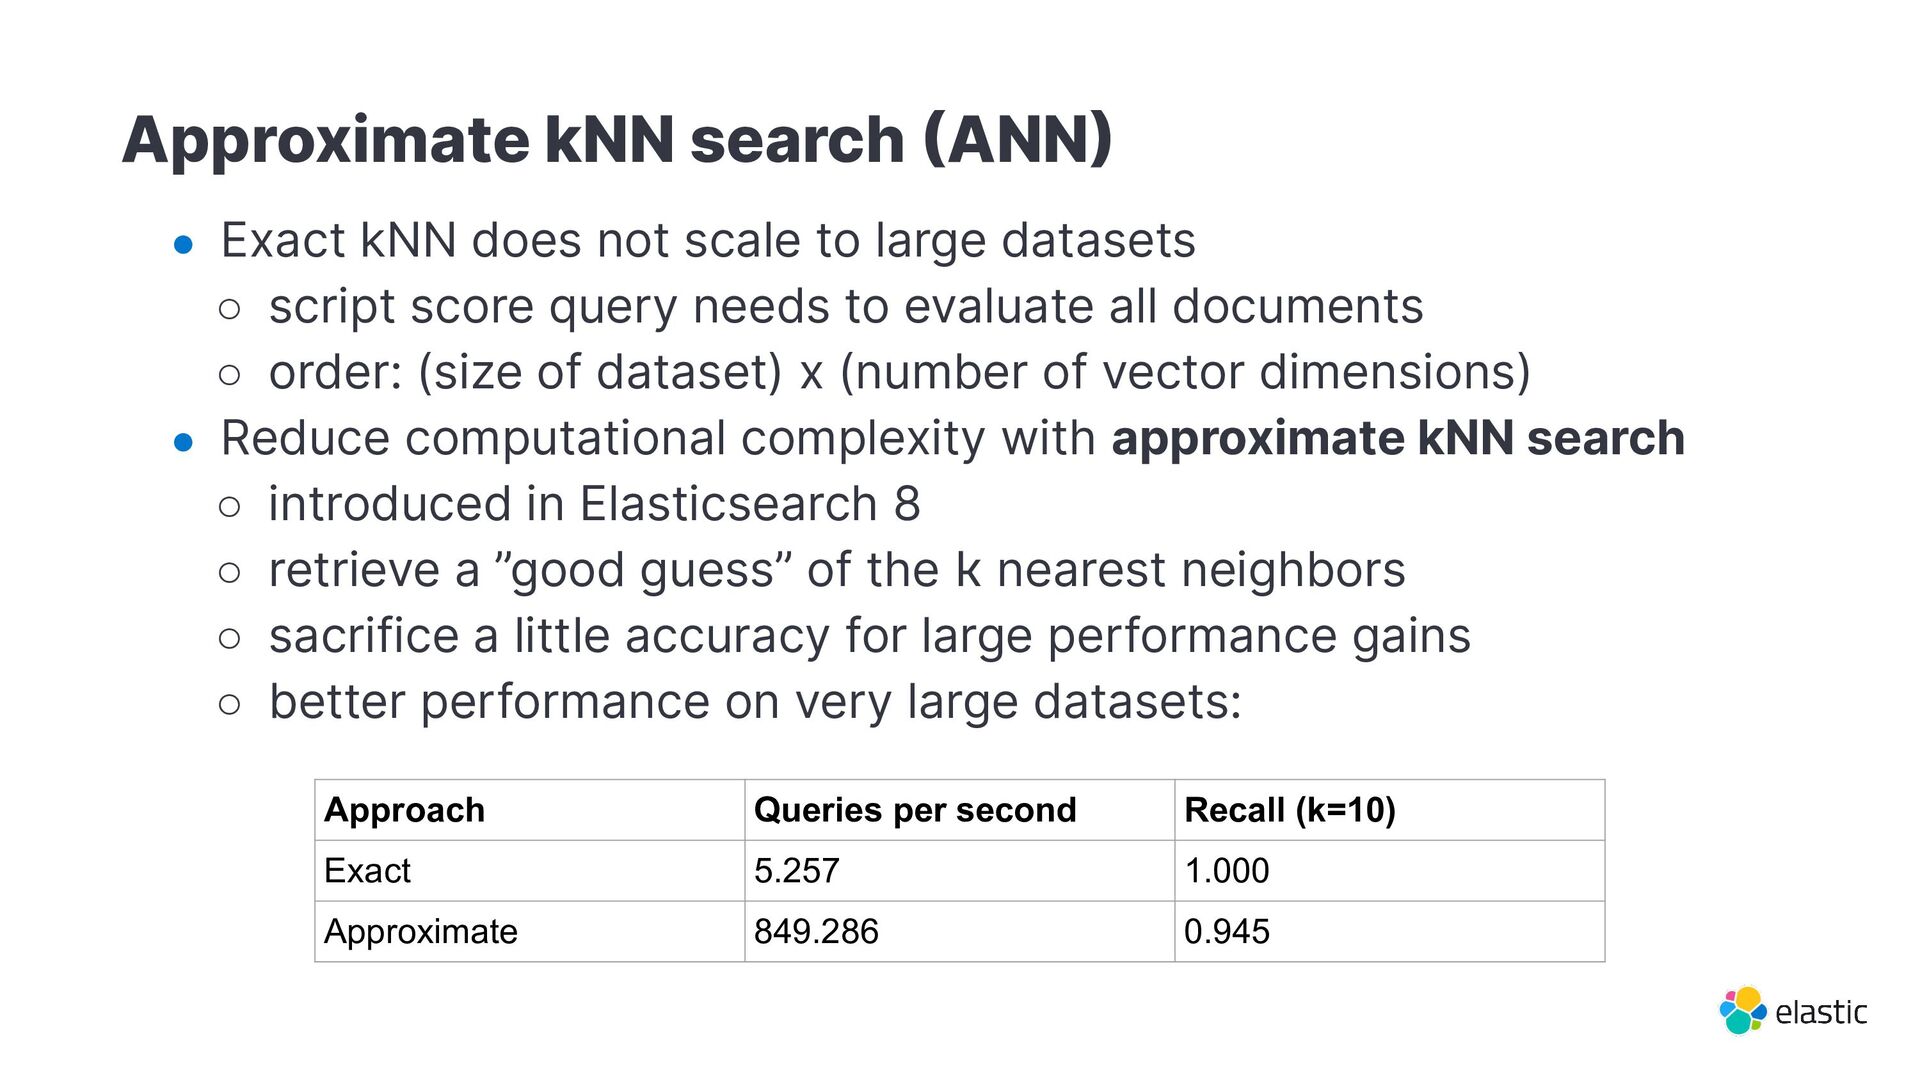
to large datasets ◦ script score query needs to evaluate all documents ◦ order: (size of dataset) x (number of vector dimensions) • Reduce computational complexity with approximate kNN search ◦ introduced in Elasticsearch 8 ◦ retrieve a ”good guess” of the k nearest neighbors ◦ sacrifice a little accuracy for large performance gains ◦ better performance on very large datasets: Approach Queries per second Recall (k=10) Exact 5.257 1.000 Approximate 849.286 0.945
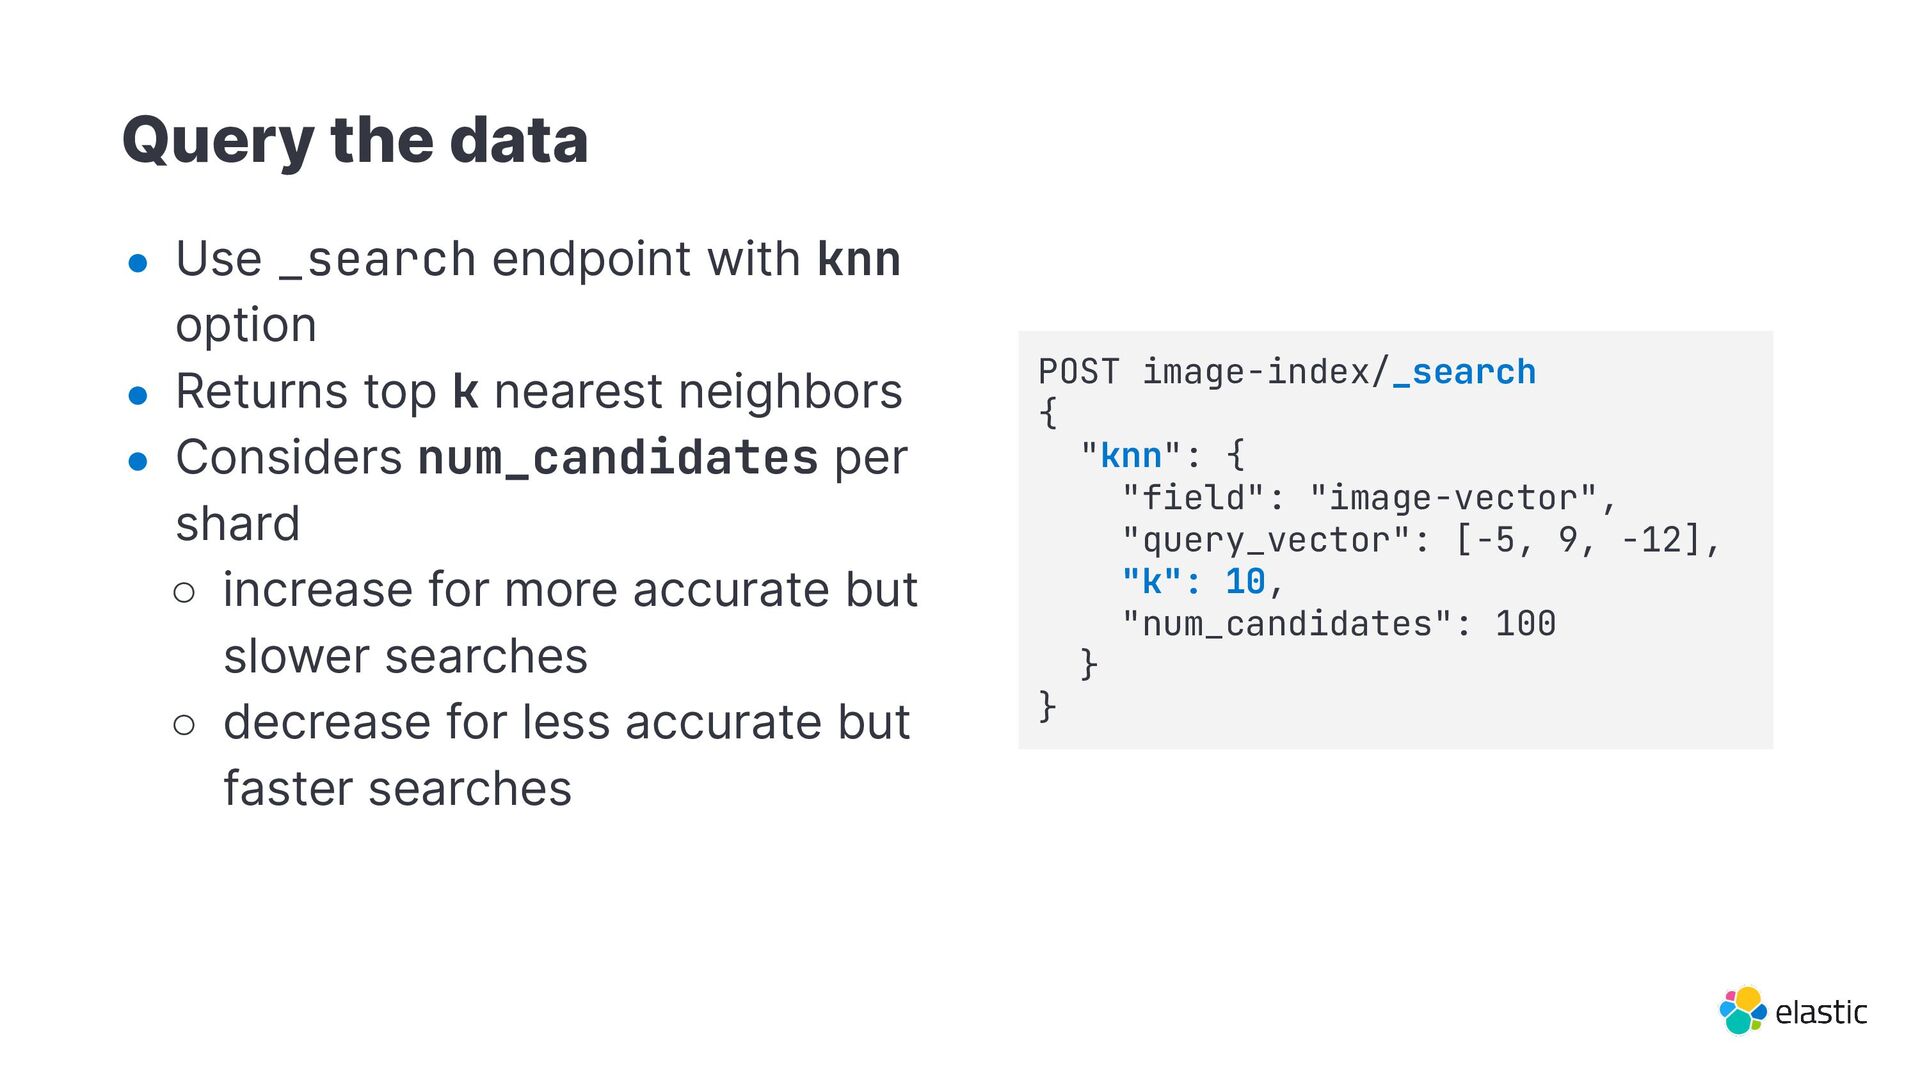
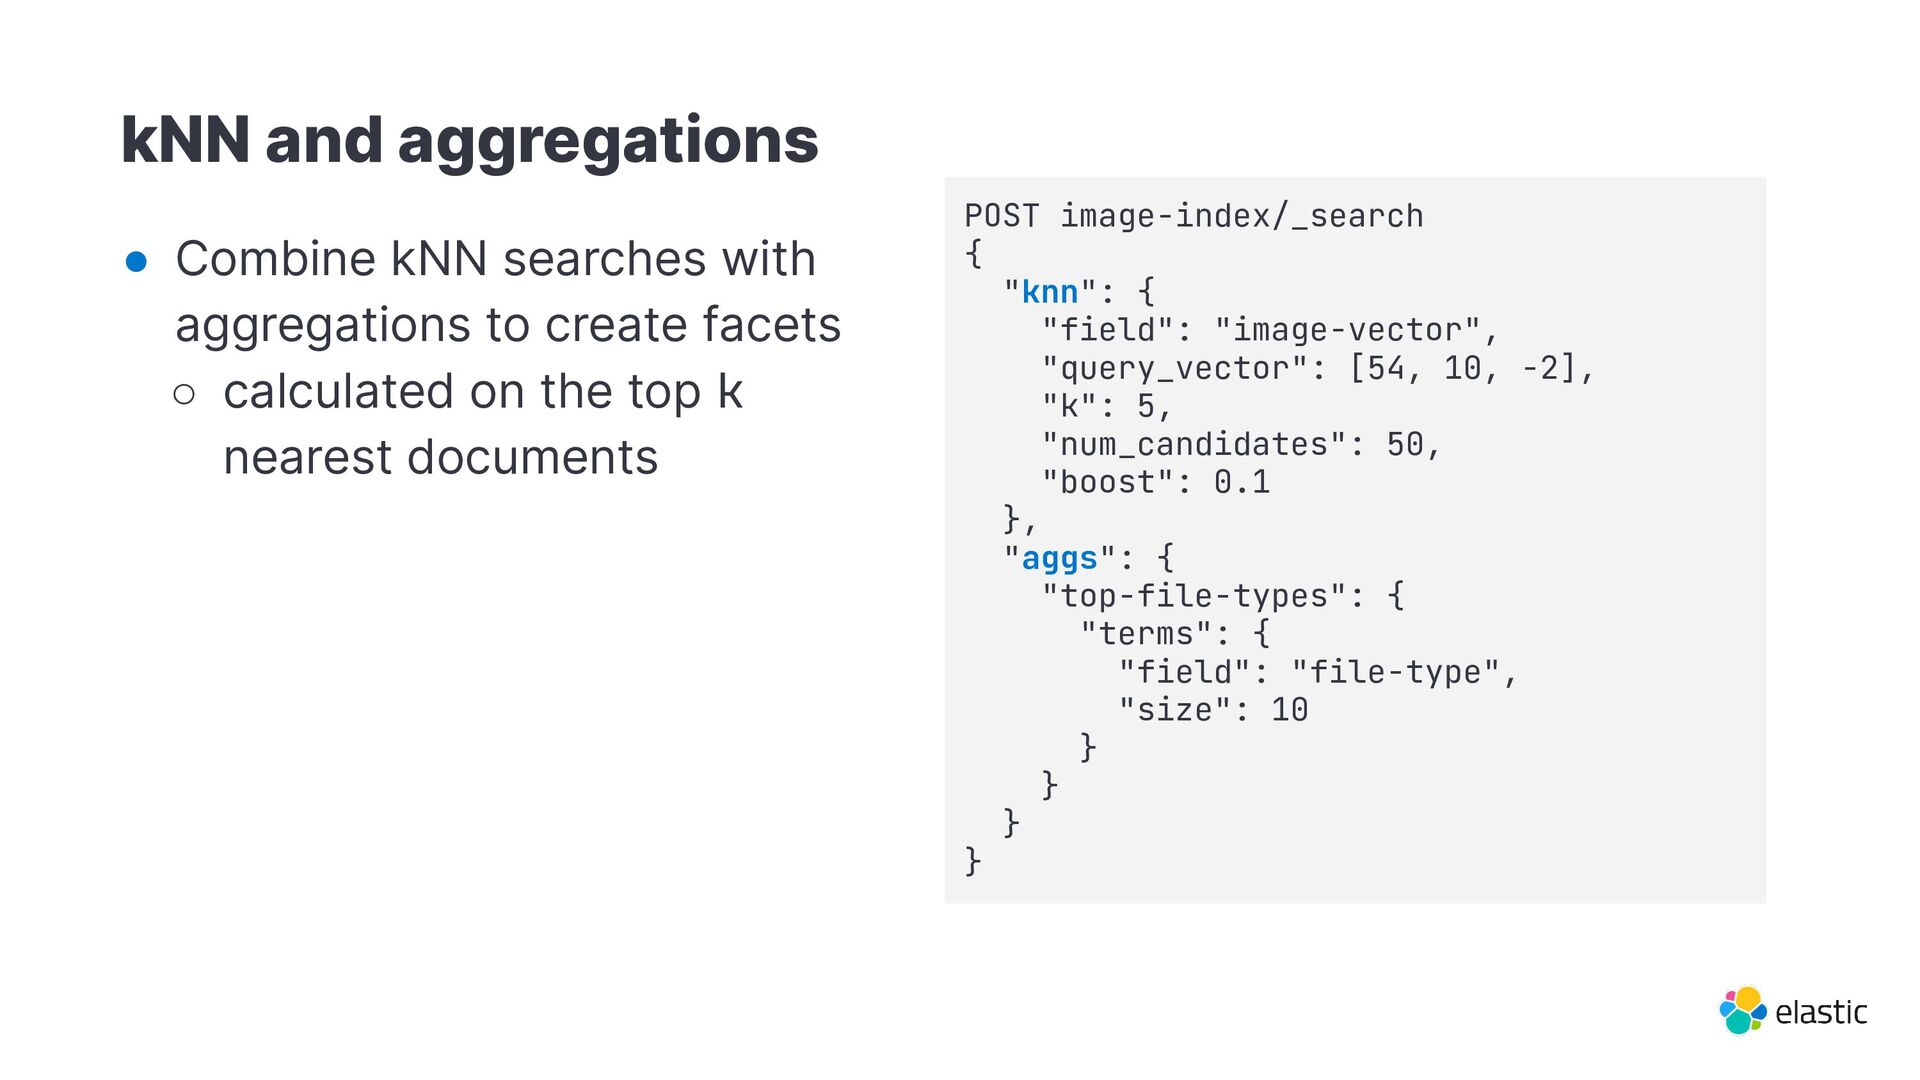
"query_vector": [-5, 9, -12], "k": 10, "num_candidates": 100 } } • Use _search endpoint with knn option • Returns top k nearest neighbors • Considers num_candidates per shard ◦ increase for more accurate but slower searches ◦ decrease for less accurate but faster searches
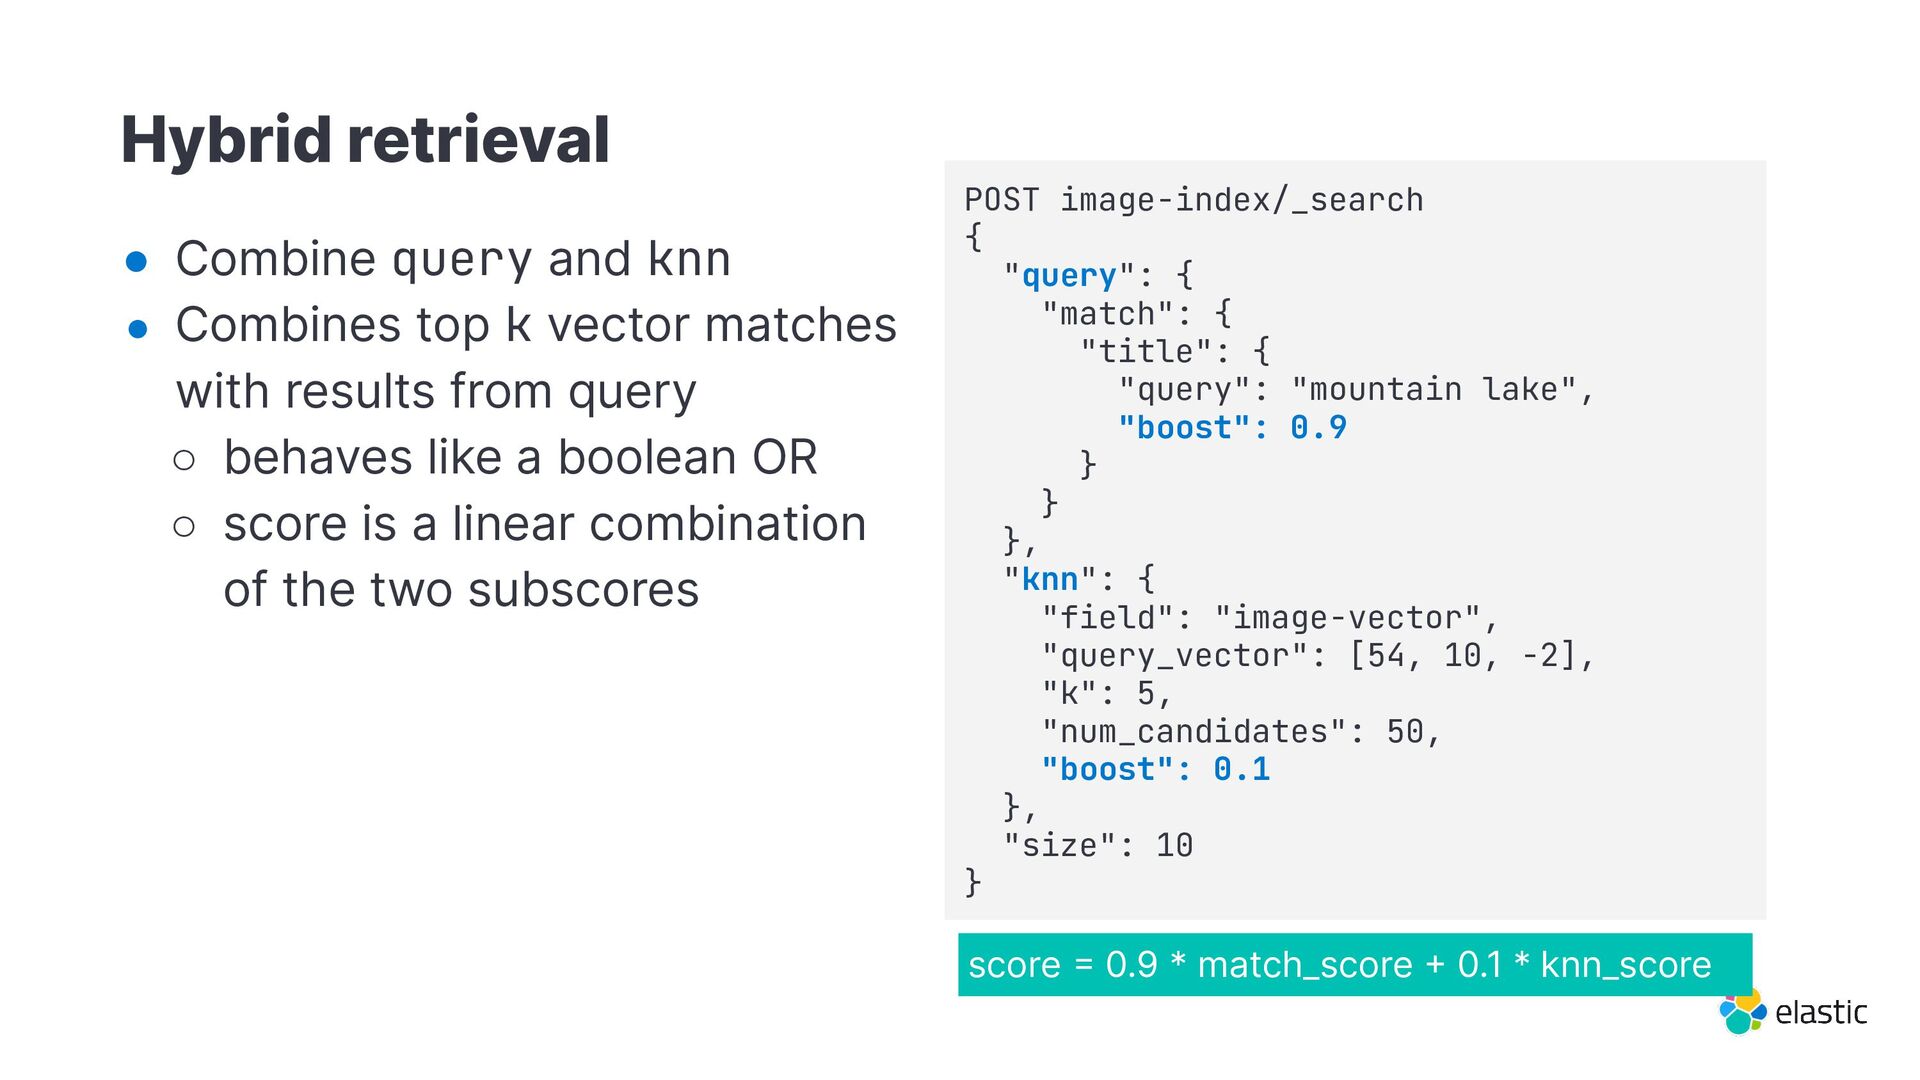
{ "query": "mountain lake", "boost": 0.9 } } }, "knn": { "field": "image-vector", "query_vector": [54, 10, -2], "k": 5, "num_candidates": 50, "boost": 0.1 }, "size": 10 } • Combine query and knn • Combines top k vector matches with results from query ◦ behaves like a boolean OR ◦ score is a linear combination of the two subscores score = 0.9 * match_score + 0.1 * knn_score
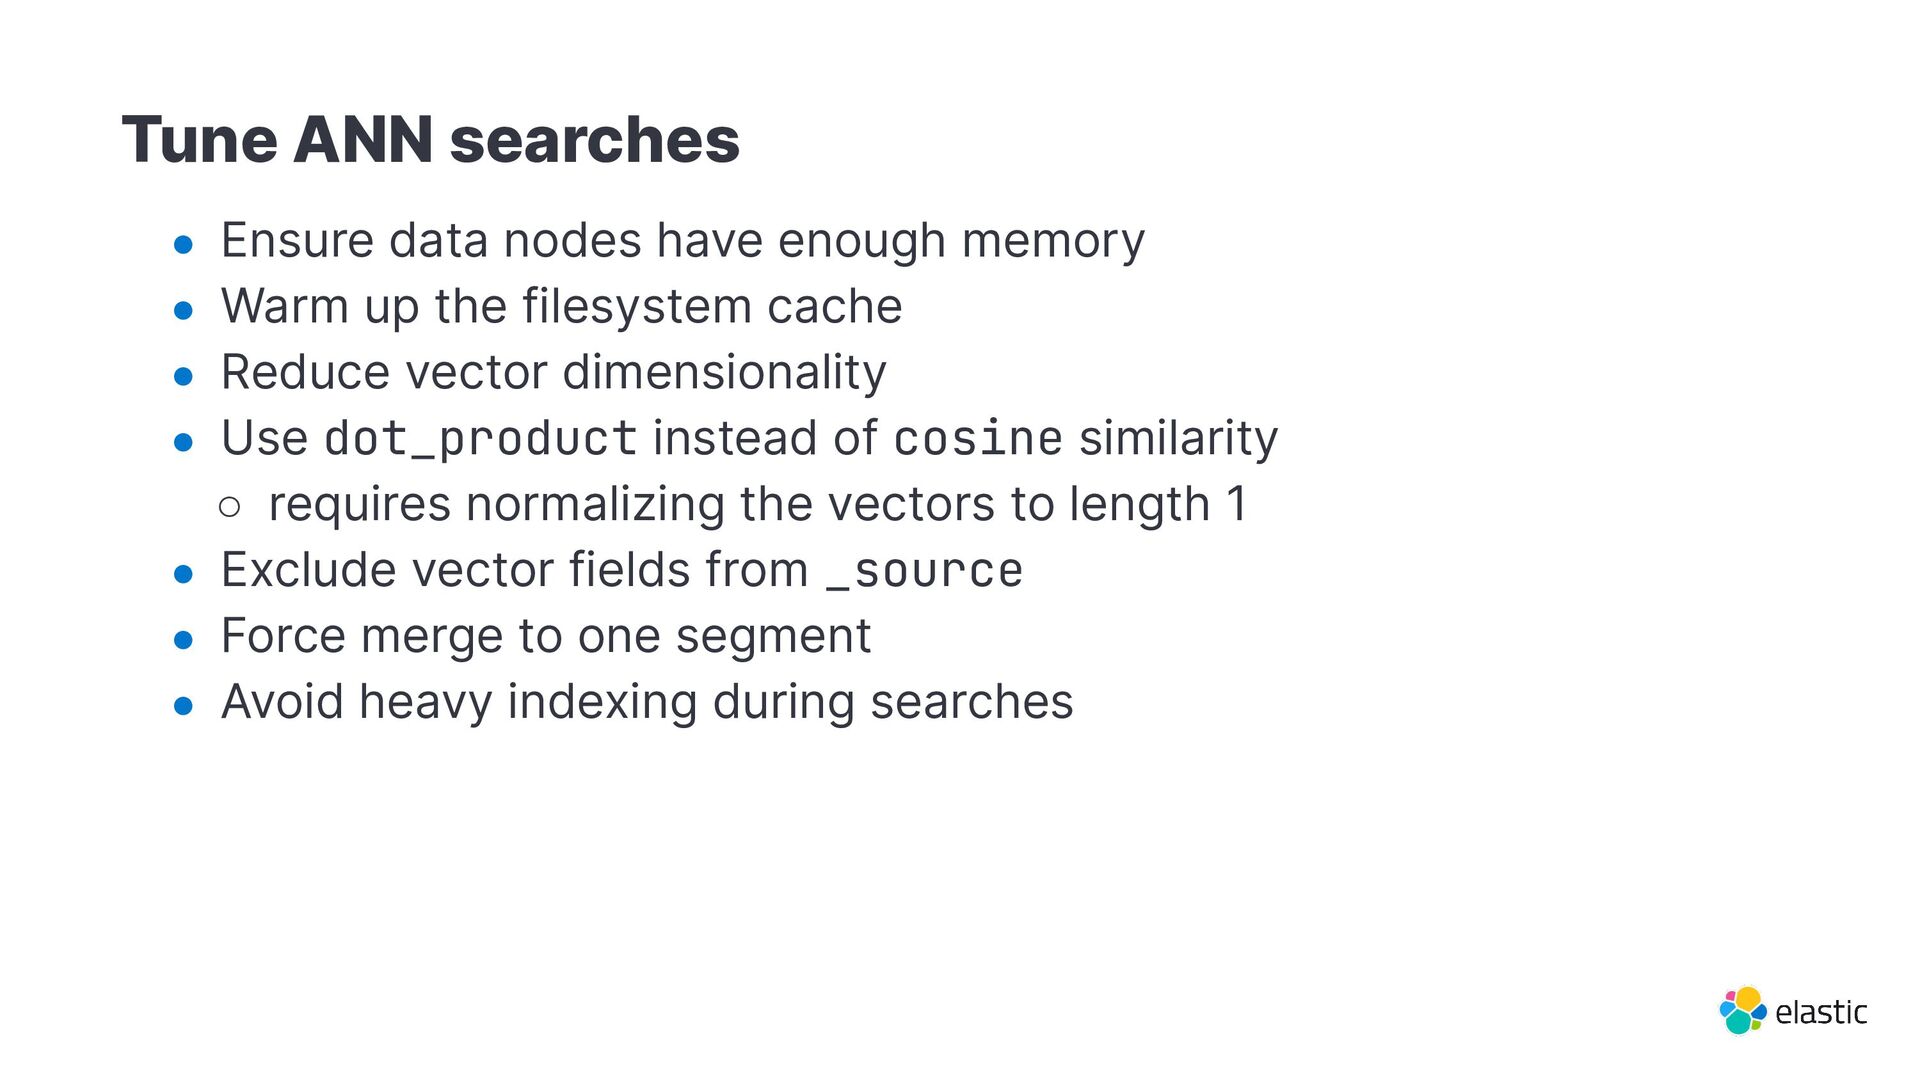
• Warm up the filesystem cache • Reduce vector dimensionality • Use dot_product instead of cosine similarity ◦ requires normalizing the vectors to length 1 • Exclude vector fields from _source • Force merge to one segment • Avoid heavy indexing during searches
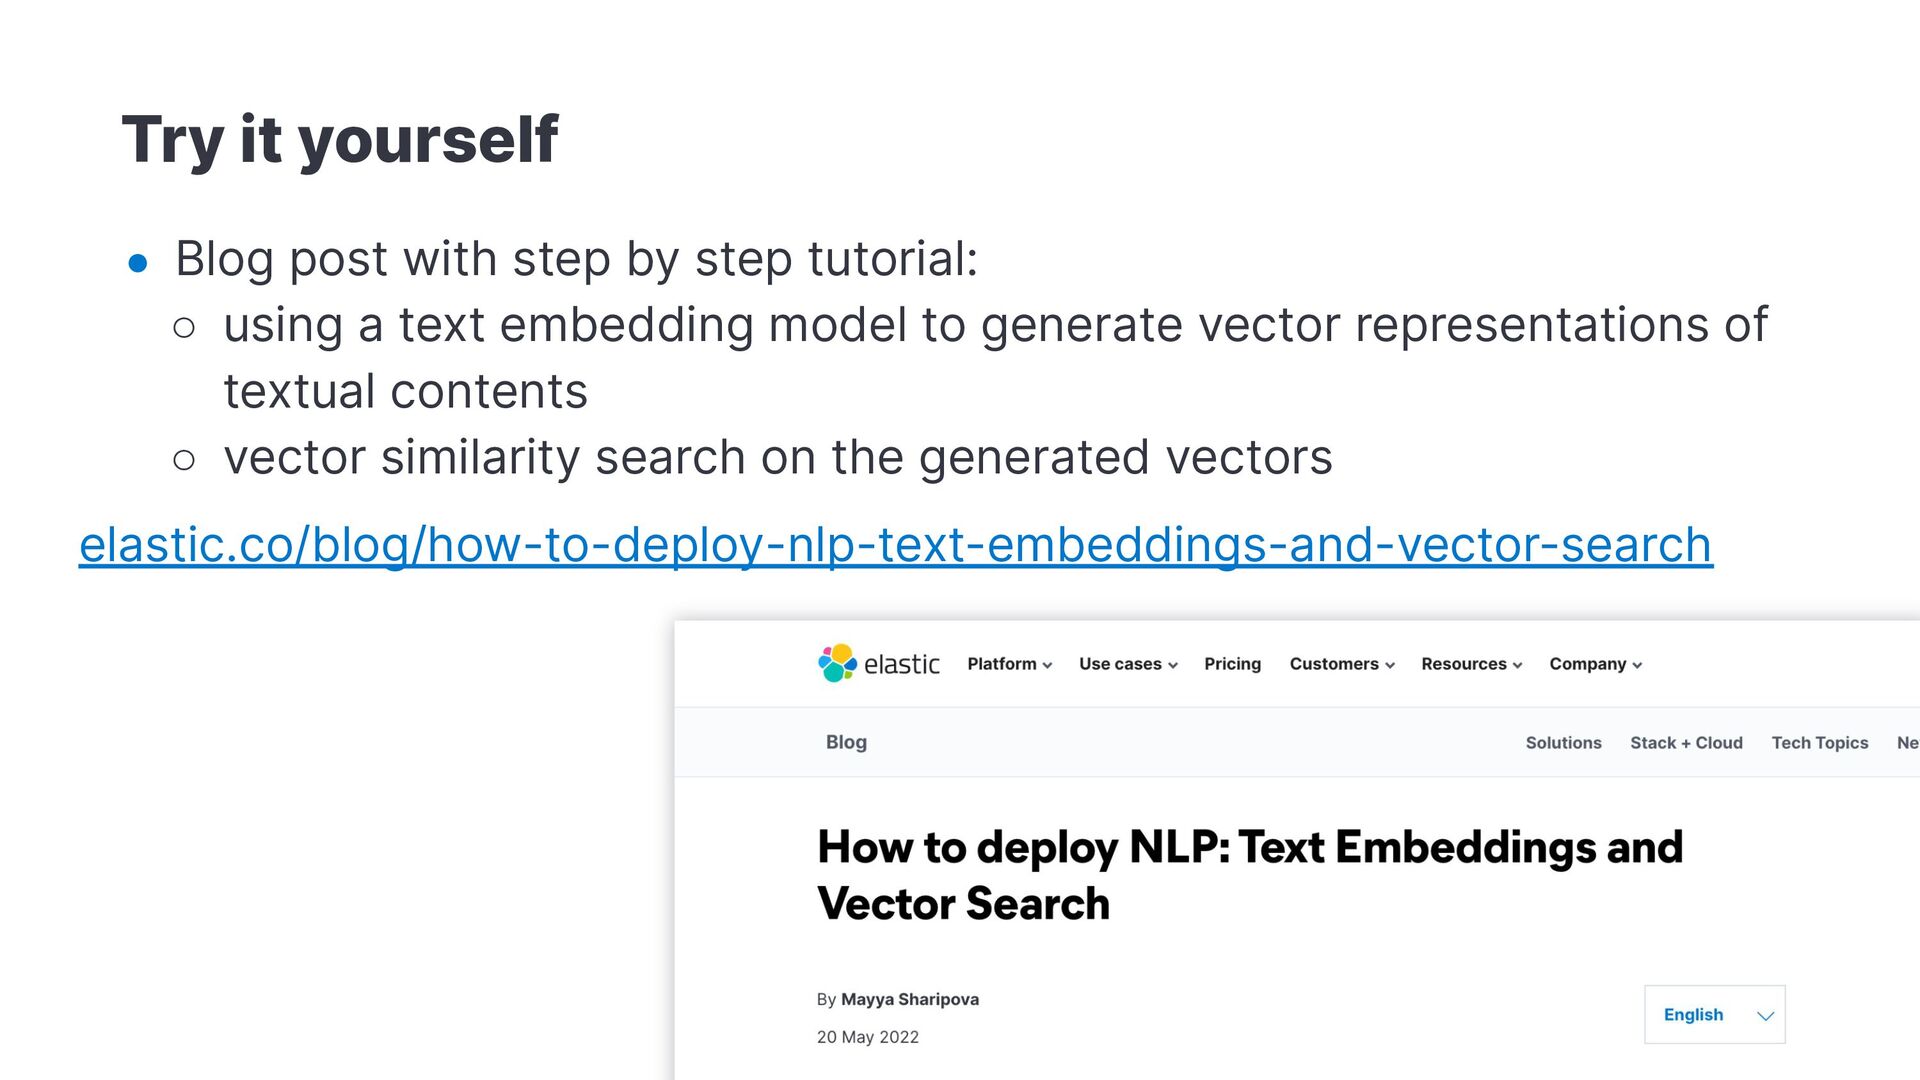
a text embedding model to generate vector representations of textual contents ◦ vector similarity search on the generated vectors elastic.co/blog/how-to-deploy-nlp-text-embeddings-and-vector-search Try it yourself


 abdon
 cromwellryan
 geshan
 nikkihalliwell
 inesmontani
 nmsamuel
 sarafernandez
 coloredviolet
 madoxten
 seathinner
 bcantrill
 lfama