Share
Embed
Re-architecting in GANMA!
ScalaMatsuri 2020 TrackA, 15:00 ~

Naoki Aoyama - @aoiroaoino
October 17, 2020
Transcript
92 slides
-
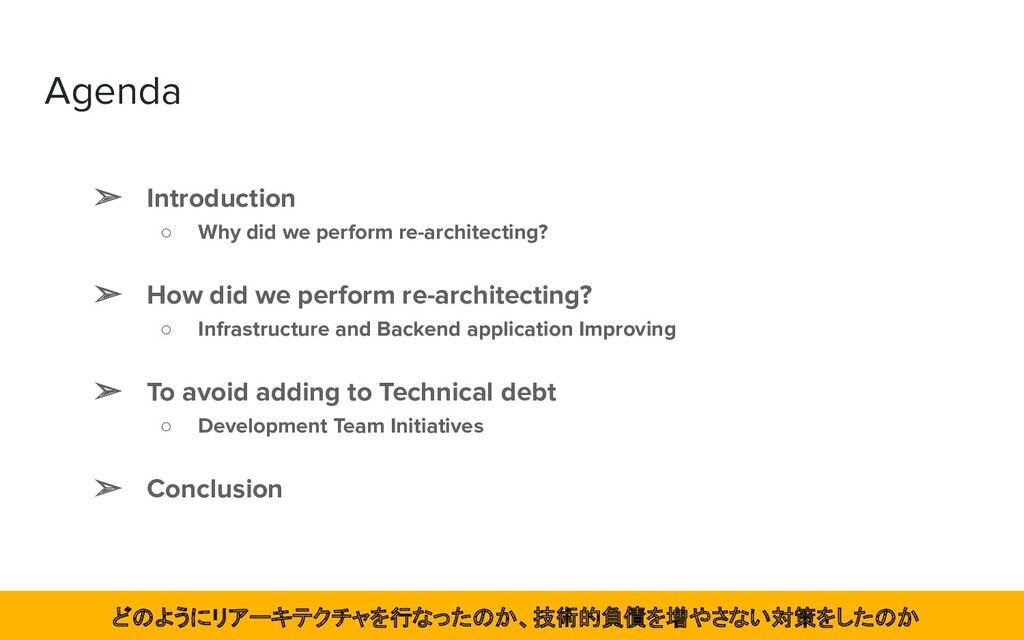
Agenda ➢ Introduction ◦ Why did we perform re-architecting? ➢
How did we perform re-architecting? ◦ Infrastructure and Backend application Improving ➢ To avoid adding to Technical debt ◦ Development Team Initiatives ➢ Conclusion どのようにリアーキテクチャを行なったのか、技術的負債を増やさない対策をしたのか -
Why did we perform re-architecting? 7 years have passed since
starting a project and have a lot of technical debt. プロジェクト開始から7年が経過し、多くの技術的負債が溜まっていました -
Why did we perform re-architecting? It was becoming impossible to
ignore the negative effects of technical debt that could affect the business. ビジネスに影響を及ぼしかねない、技術的負債による弊害を無視できない状態だった -
Why did we perform re-architecting? e.g. If there's an system
failure during a high-traffic time, you won't be able to read the comic. 例: アクセスが集中する時間帯に障害が発生すれば、マンガが読めない -
Why did we perform re-architecting? e.g. Exhausted engineers quit, after
days of conflicting with technical debt and system troubleshooting. 例: 技術的負債や障害対応に追われる日々が続いて疲弊し、エンジニアが辞めてしまう -
We want to work on it. But... ➔ We can't
stop feature development ➔ We can’t stop backend system 24/7 ➔ There's no time to pay off the technical debt ➔ Almost none people involved in the initial development of the system サービスも機能開発も止められない、時間も足りない、初期開発メンバーもほぼいない -
Therefore... There is no choice but to continue steady improvement
activities little by little. 少しずつ、地道な改善活動を続けるしかない -
Objectives Increase system availability and maintainability Create a new implementation
policy and de facto standard 可用性と保守性を高め、新しい実装の方針、デファクトスタンダードを作る -
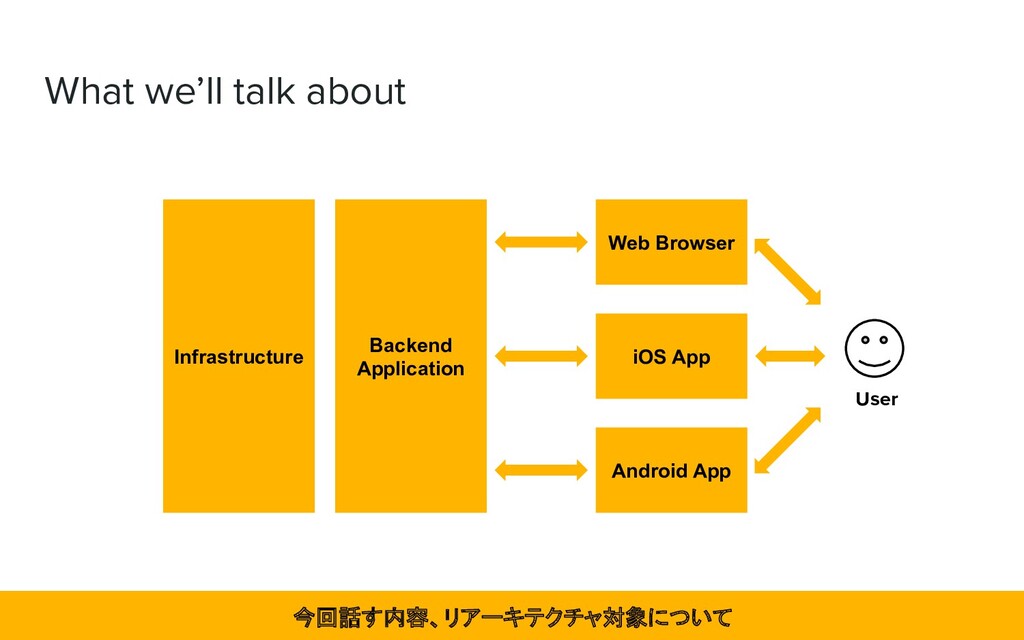
What we’ll talk about 今回話す内容、リアーキテクチャ対象について Infrastructure Backend Application Web Browser
iOS App Android App User -
What we’ll talk about 今回話す内容、リアーキテクチャ対象について Infrastructure Backend Application Web Browser
iOS App Android App User -
How did we perform re-architecting? ❖ There were issues with
both the infrastructure and backend application. ➢ Difficult to solve just by refactoring the application ❖ We decided to focus on improving the infrastructure first and then improve the application. アプリケーションのリファクタリングだけでは根本解決が難しいので、インフラ改善から着手 -
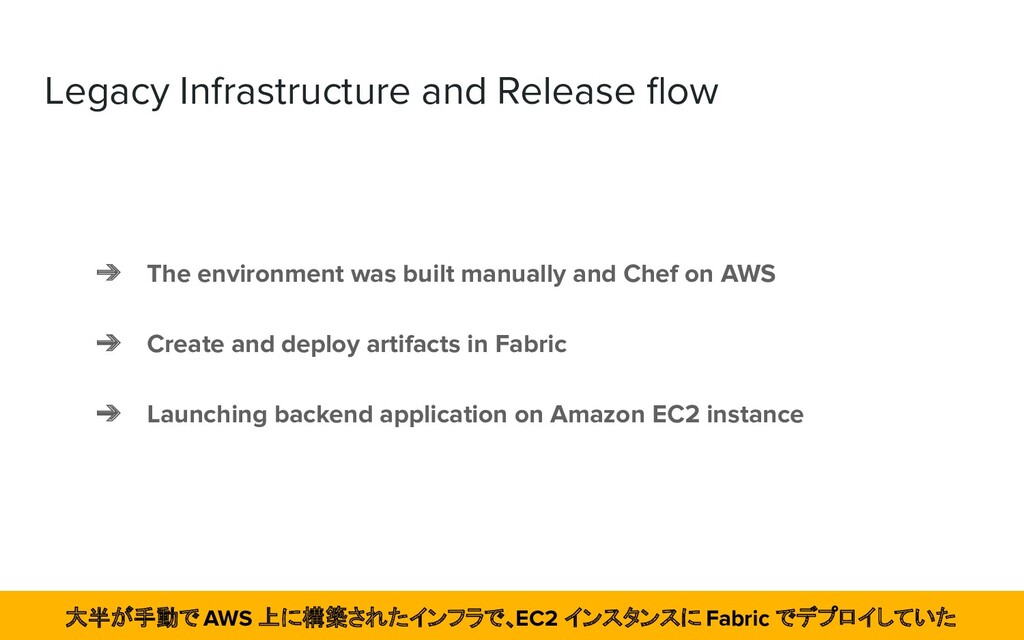
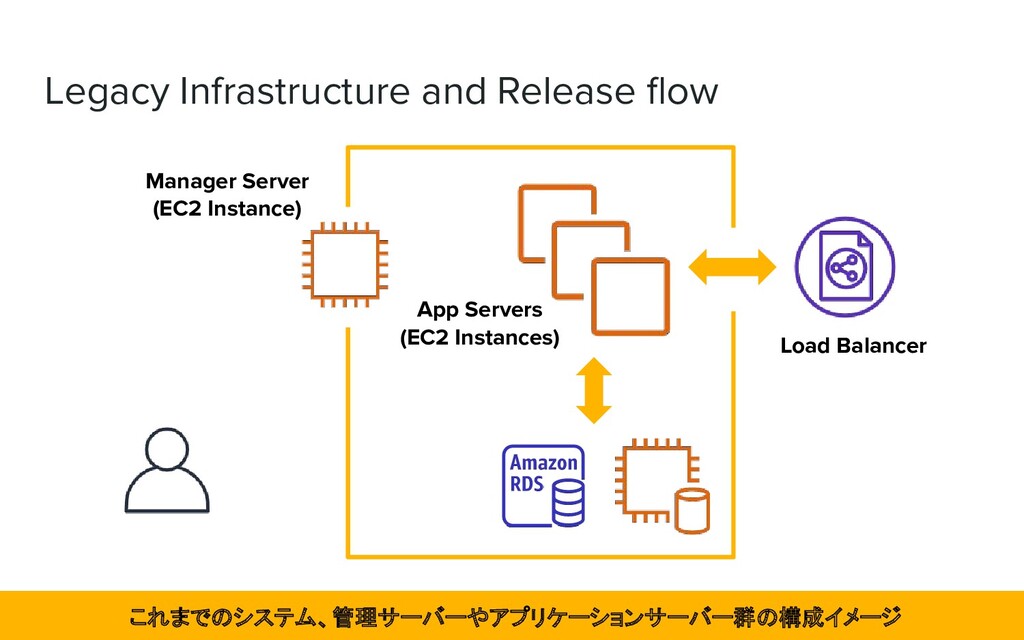
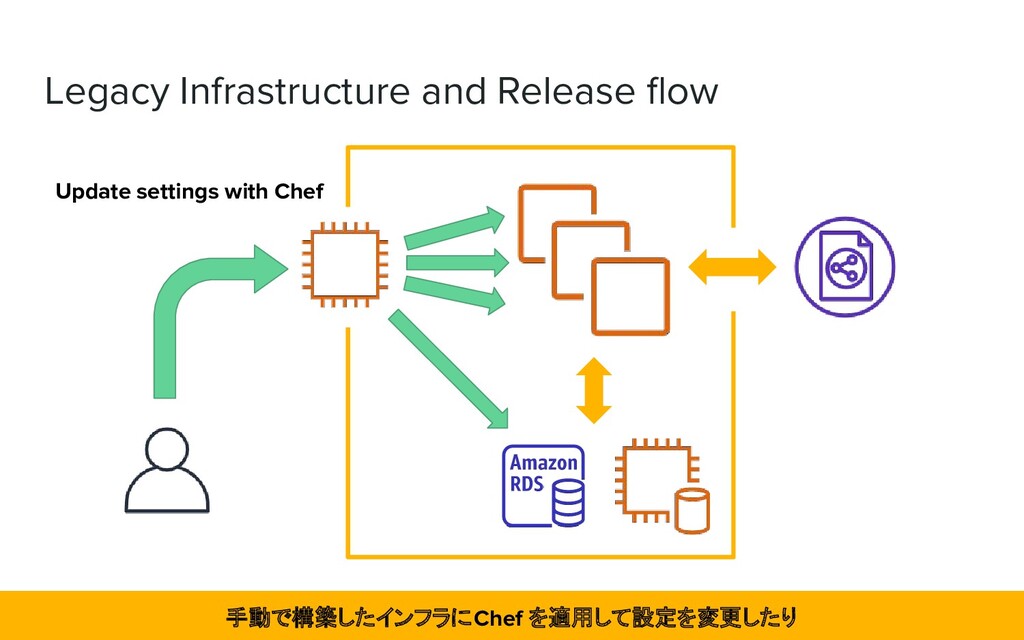
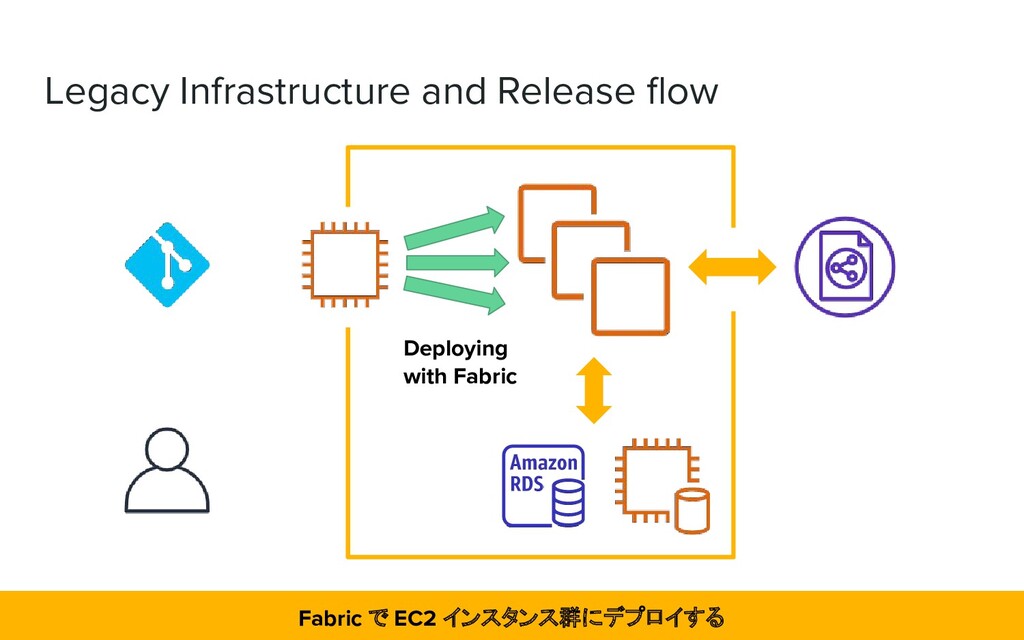
Legacy Infrastructure and Release flow ➔ The environment was built
manually and Chef on AWS ➔ Create and deploy artifacts in Fabric ➔ Launching backend application on Amazon EC2 instance 大半が手動で AWS 上に構築されたインフラで、EC2 インスタンスに Fabric でデプロイしていた -
Legacy Infrastructure and Release flow Manager Server (EC2 Instance) これまでのシステム、管理サーバーやアプリケーションサーバー群の構成イメージ
App Servers (EC2 Instances) Load Balancer -
Legacy Infrastructure and Release flow Update settings with Chef 手動で構築したインフラに
Chef を適用して設定を変更したり -
Legacy Infrastructure and Release flow CI and create JAR file
リモートリポジトリに git push し、管理サーバーにて CI と JAR ファイルの生成を行い git push -
Legacy Infrastructure and Release flow Deploying with Fabric Fabric で
EC2 インスタンス群にデプロイする -
Legacy Infrastructure and Release flow ➔ Auto Scaling is not
possible ➔ Chef, Fabric are practically unmaintainable due to the secret sauce ➔ The current infrastructure is not reproducible Auto Scaling ができず、Chef や Fabric が秘伝のタレでインフラの再現が難しい状態 -
Decided to use Amazon EKS ❖ We was already using
a lot of AWS services ➢ As a result of the test, we determined that it was practical and could be operated by us if it was managed ❖ The team had engineers familiar with Cloud Native technology ➢ Not EKS, but the k8s itself had already been introduced in the company EKS を採用。社内導入事例もあり、検証して実用可能と判断 -
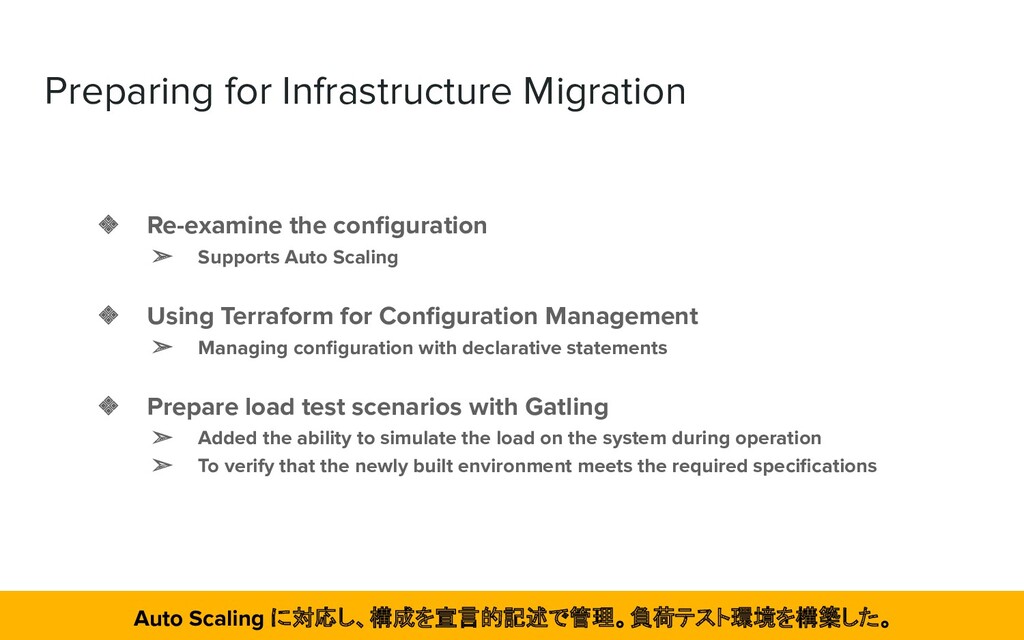
Preparing for Infrastructure Migration ❖ Re-examine the configuration ➢ Supports
Auto Scaling ❖ Using Terraform for Configuration Management ➢ Managing configuration with declarative statements ❖ Prepare load test scenarios with Gatling ➢ Added the ability to simulate the load on the system during operation ➢ To verify that the newly built environment meets the required specifications Auto Scaling に対応し、構成を宣言的記述で管理。負荷テスト環境を構築した。 -
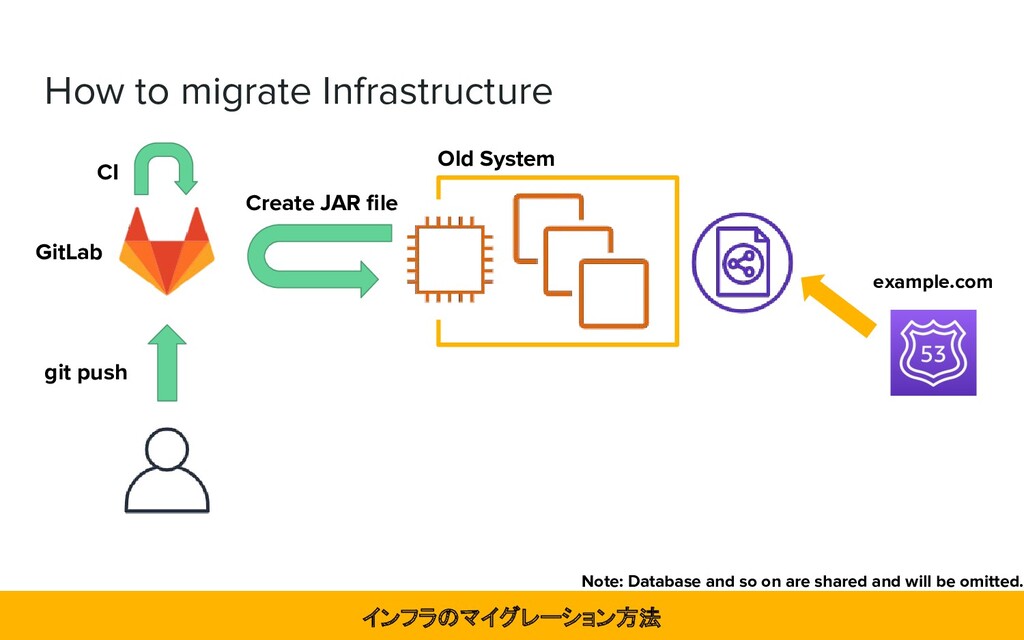
How to migrate Infrastructure GitLab インフラのマイグレーション方法 Old System Create JAR
file CI git push example.com Note: Database and so on are shared and will be omitted. -
Application build generates docker images New Cluster GitLab 新しいクラスターを用意し、アプリケーションをデプロイできるようにした Old
System Push to ECR CI git push example.com Note: Database and so on are shared and will be omitted. -
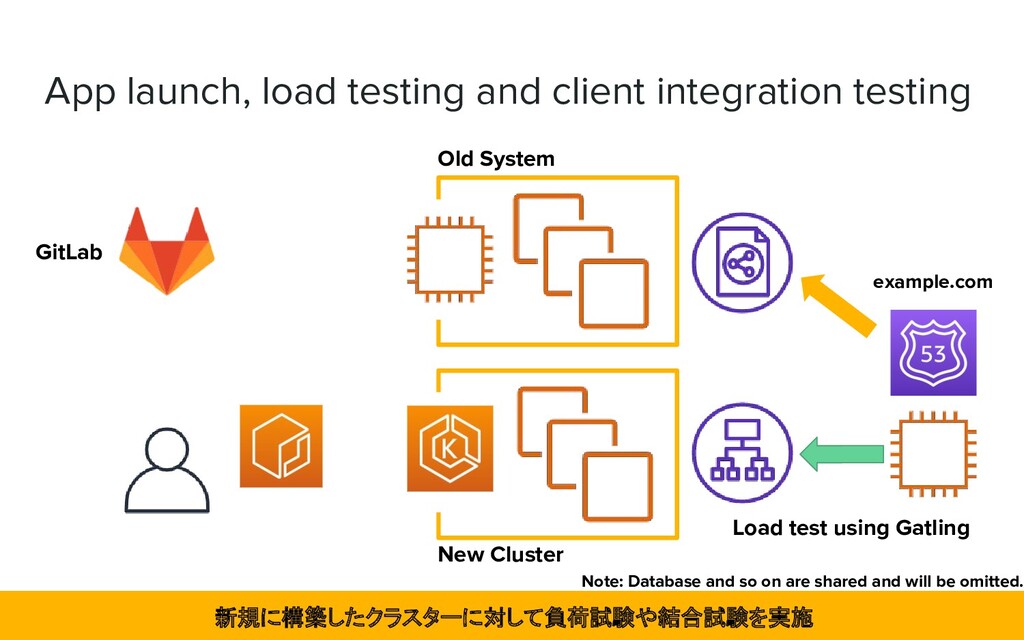
App launch, load testing and client integration testing New Cluster
GitLab 新規に構築したクラスターに対して負荷試験や結合試験を実施 Old System example.com Note: Database and so on are shared and will be omitted. Load test using Gatling -
Canary release while monitoring the system New Cluster GitLab Old
System example.com Note: Database and so on are shared and will be omitted. Switching DNS カナリアリリース実施。問題が発生しないか監視しつつ、徐々にトラフィックを切り替える ・ ・ ・ -
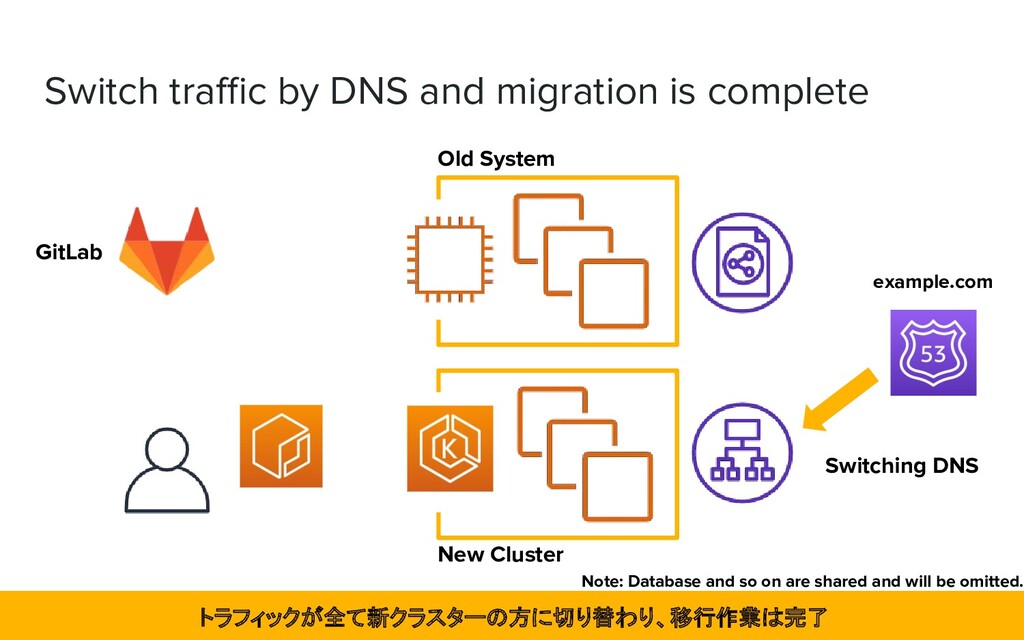
Switch traffic by DNS and migration is complete New Cluster
GitLab トラフィックが全て新クラスターの方に切り替わり、移行作業は完了 Old System example.com Note: Database and so on are shared and will be omitted. Switching DNS -
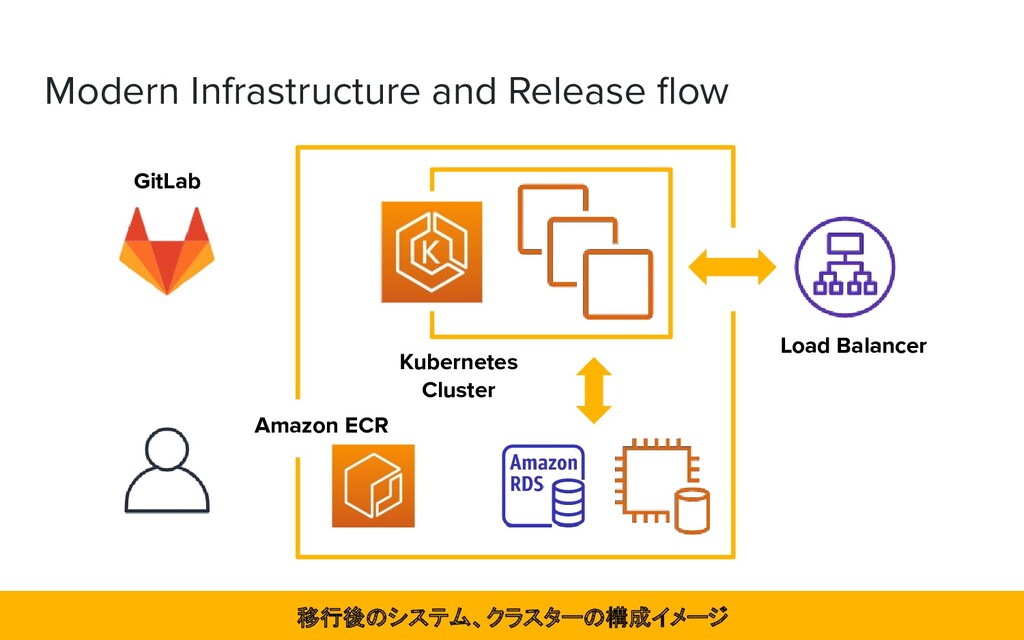
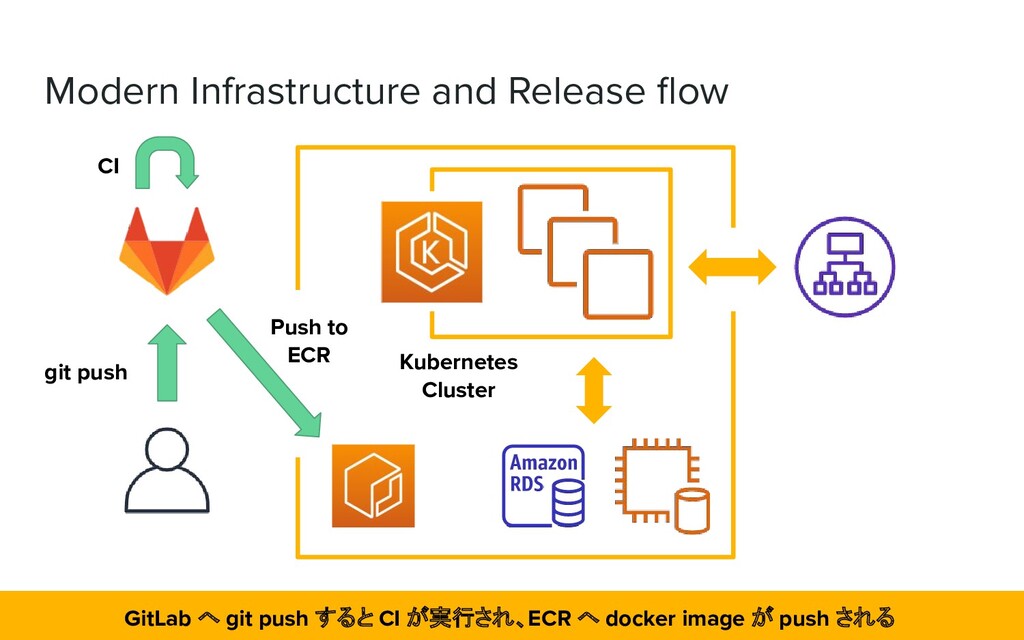
Modern Infrastructure and Release flow Kubernetes Cluster git push CI
Push to ECR GitLab へ git push すると CI が実行され、ECR へ docker image が push される -
Modern Infrastructure and Release flow Kubernetes Cluster helmfile apply GitLab
の CI/CD 機能から helmfile apply を実行し、マニフェストを更新 -
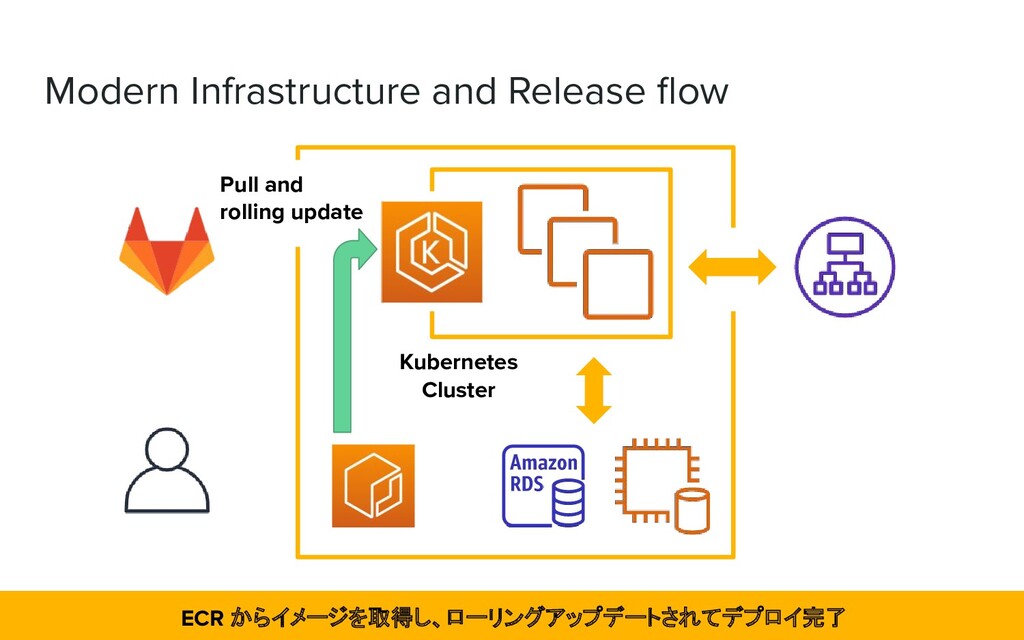
Modern Infrastructure and Release flow Kubernetes Cluster Pull and rolling
update ECR からイメージを取得し、ローリングアップデートされてデプロイ完了 -
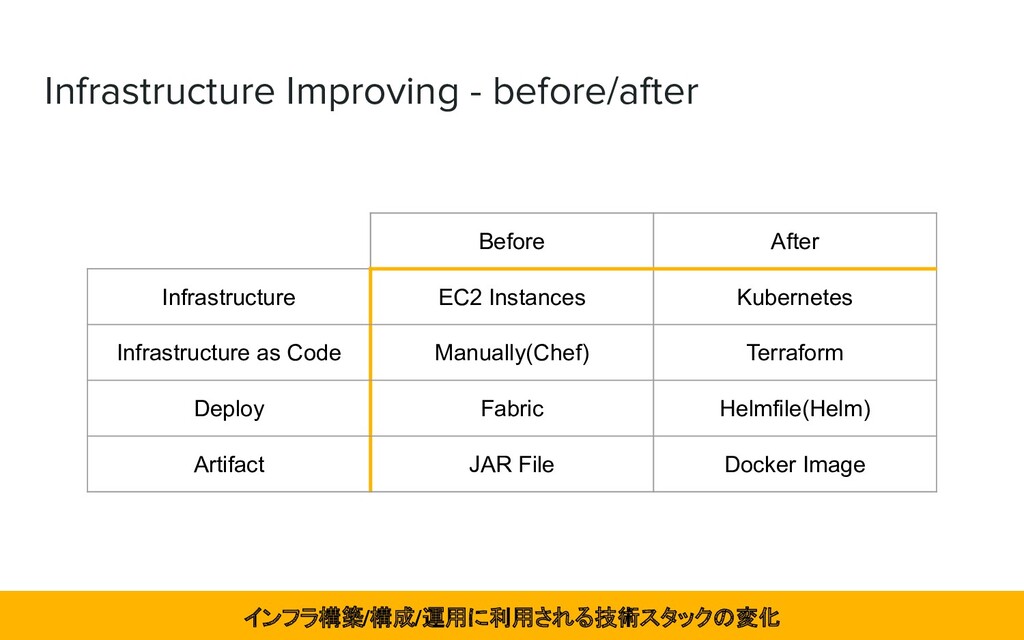
Infrastructure Improving - before/after Before After Infrastructure EC2 Instances Kubernetes
Infrastructure as Code Manually(Chef) Terraform Deploy Fabric Helmfile(Helm) Artifact JAR File Docker Image インフラ構築/構成/運用に利用される技術スタックの変化 -
Result of Infrastructure Improving ❖ The division of the Backend
Application is now more flexible ➢ Terraform allows us to rebuild our own systems from the infrastructure ➢ Existing members of the team are now experienced in building initial infrastructure ❖ It led to reduced operational costs ➢ All application engineers can now manage the infrastructure as well アプリケーション分割に自由度が生まれ、再構築が可能になり、コスト削減にもつながった -
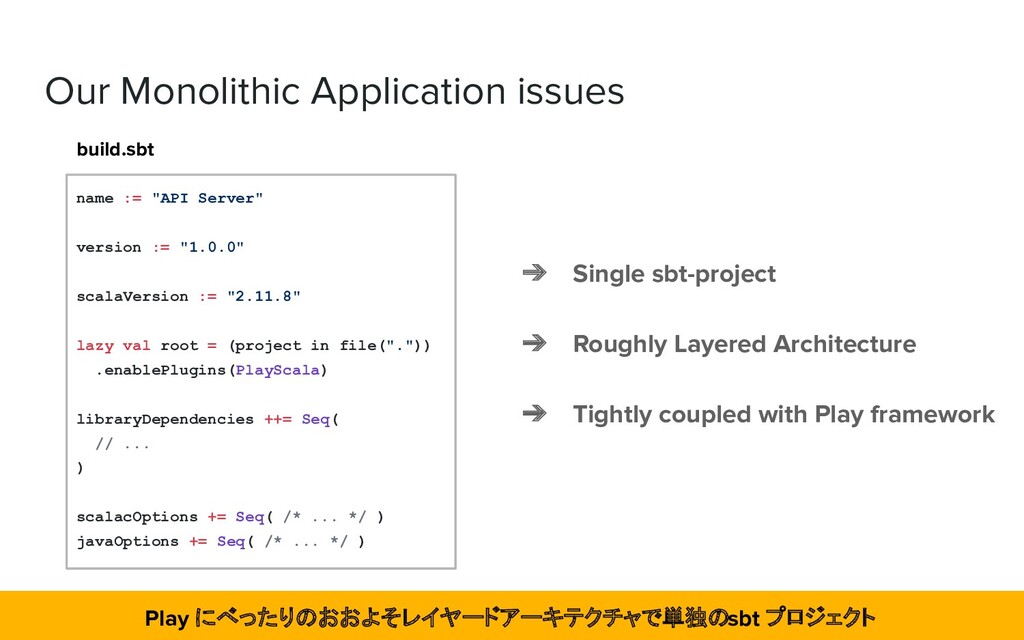
Our Monolithic Application issues ➔ Single sbt-project ➔ Roughly Layered
Architecture ➔ Tightly coupled with Play framework name := "API Server" version := "1.0.0" scalaVersion := "2.11.8" lazy val root = (project in file(".")) .enablePlugins(PlayScala) libraryDependencies ++= Seq( // ... ) scalacOptions += Seq( /* ... */ ) javaOptions += Seq( /* ... */ ) build.sbt Play にべったりのおおよそレイヤードアーキテクチャで単独の sbt プロジェクト -
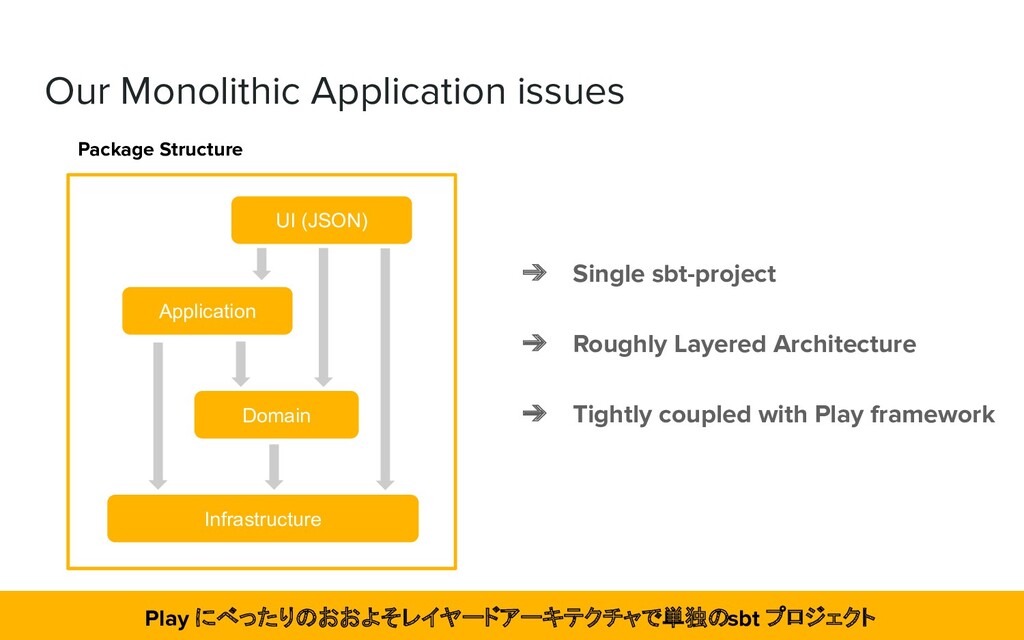
Our Monolithic Application issues Package Structure ➔ Single sbt-project ➔
Roughly Layered Architecture ➔ Tightly coupled with Play framework Infrastructure Application Domain UI (JSON) Play にべったりのおおよそレイヤードアーキテクチャで単独の sbt プロジェクト -
Our Monolithic Application issues ➔ Infra layer depended domain models
➔ Odd DI patterns (like Service Locator) everywhere ➔ Complex multi-stage cache ➔ Limited release time ➔ etc... 課題: インフラレイヤ依存のドメイン、独特な DI、複雑な cache、限られるリリース時刻など -
Why didn't we go with microservices? ❖ It was difficult
for the team structure. ❖ The aggregation was not sufficiently analyzed. ➢ It was decided that the first step was to better define the context boundaries of the application. ❖ There were many considerations ➢ The first priority is to develop features. Then we had to get used to developing and operating on the new infrastructure. ➢ Technology verification is underway. マイクロサービス化実施せず。機能開発、新インフラの運用に慣れることを優先。技術検証中 -
Analyze application context boundaries Backend Application (sbt-project) ❖ We analyzed
how our monolithic application features 我々のモノリシックなアプリケーションがどのような機能を持っているのかを改めて分析 -
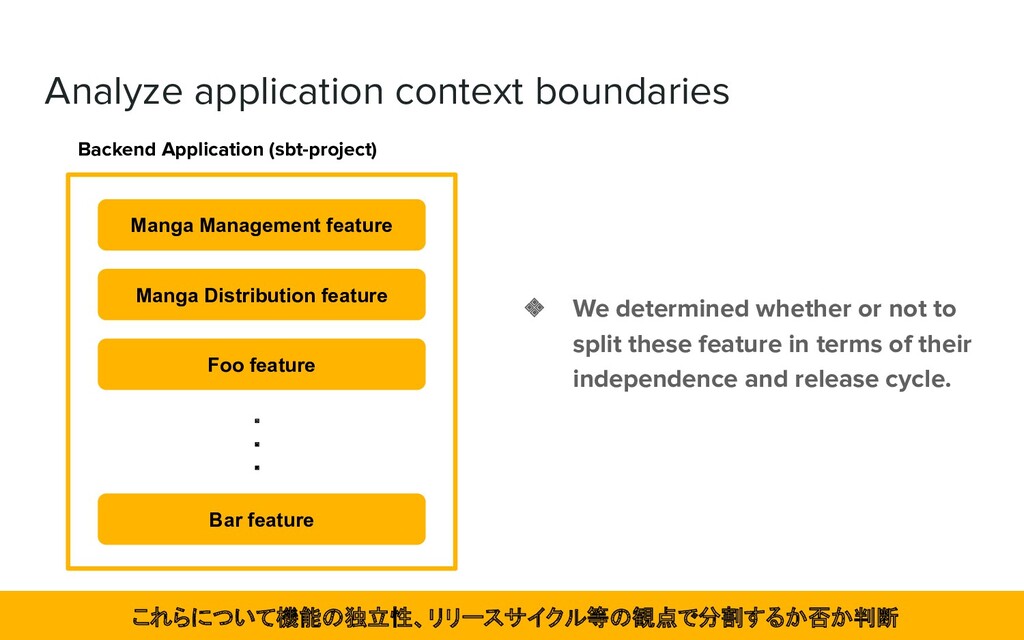
Analyze application context boundaries Backend Application (sbt-project) ❖ We determined
whether or not to split these feature in terms of their independence and release cycle. Manga Management feature Manga Distribution feature Foo feature Bar feature ・ ・ ・ これらについて機能の独立性、リリースサイクル等の観点で分割するか否か判断 -
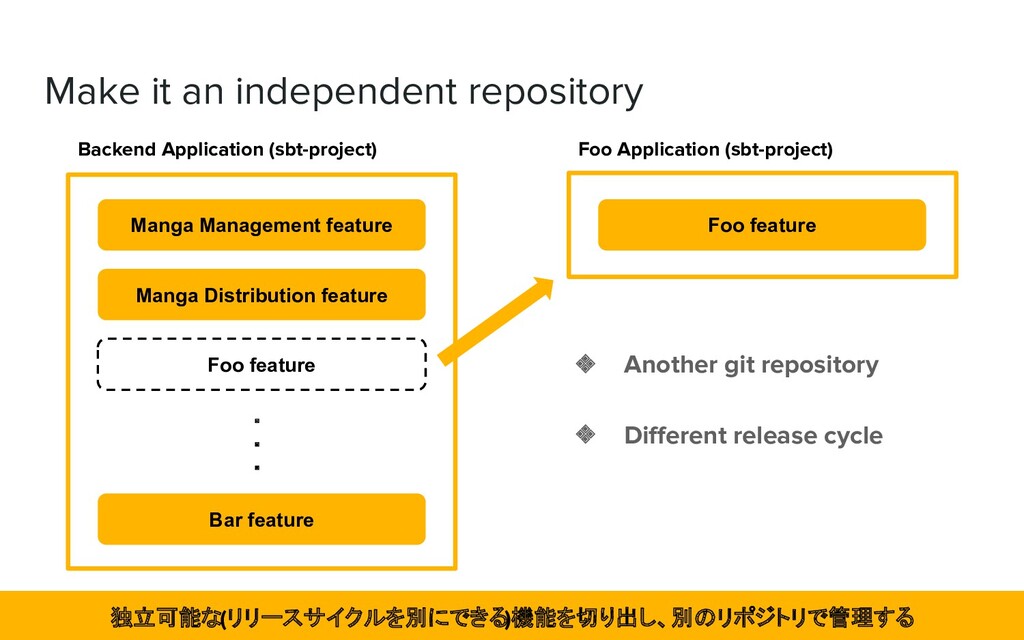
Make it an independent repository Backend Application (sbt-project) Manga Management
feature Manga Distribution feature Foo feature Bar feature ・ ・ ・ Foo feature Foo Application (sbt-project) ❖ Another git repository ❖ Different release cycle 独立可能な(リリースサイクルを別にできる)機能を切り出し、別のリポジトリで管理する -
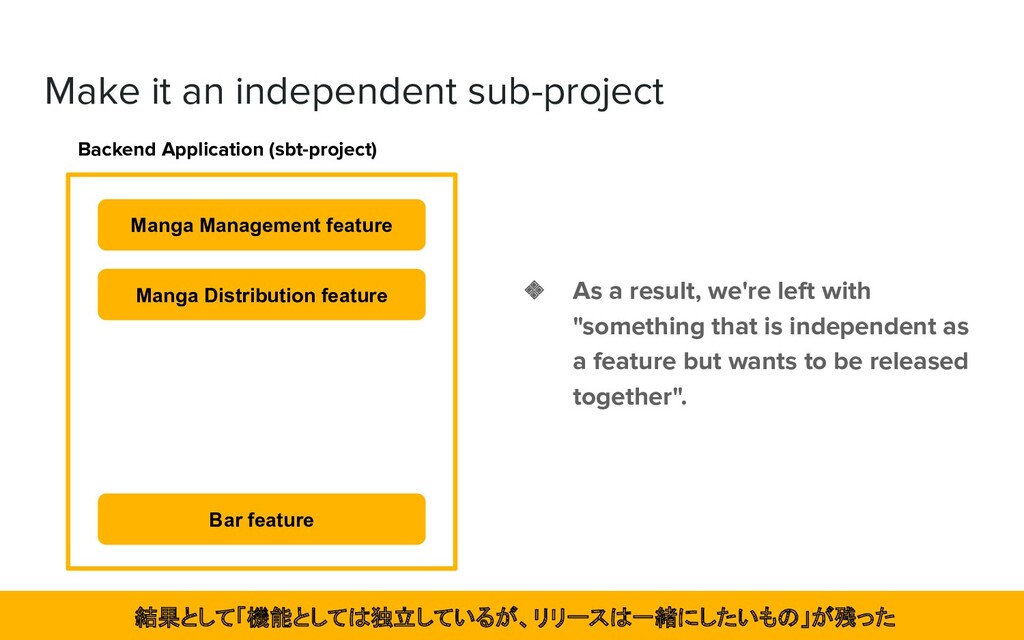
Make it an independent sub-project Backend Application (sbt-project) Manga Management
feature Manga Distribution feature Bar feature ❖ As a result, we're left with "something that is independent as a feature but wants to be released together". 結果として「機能としては独立しているが、リリースは一緒にしたいもの」が残った -
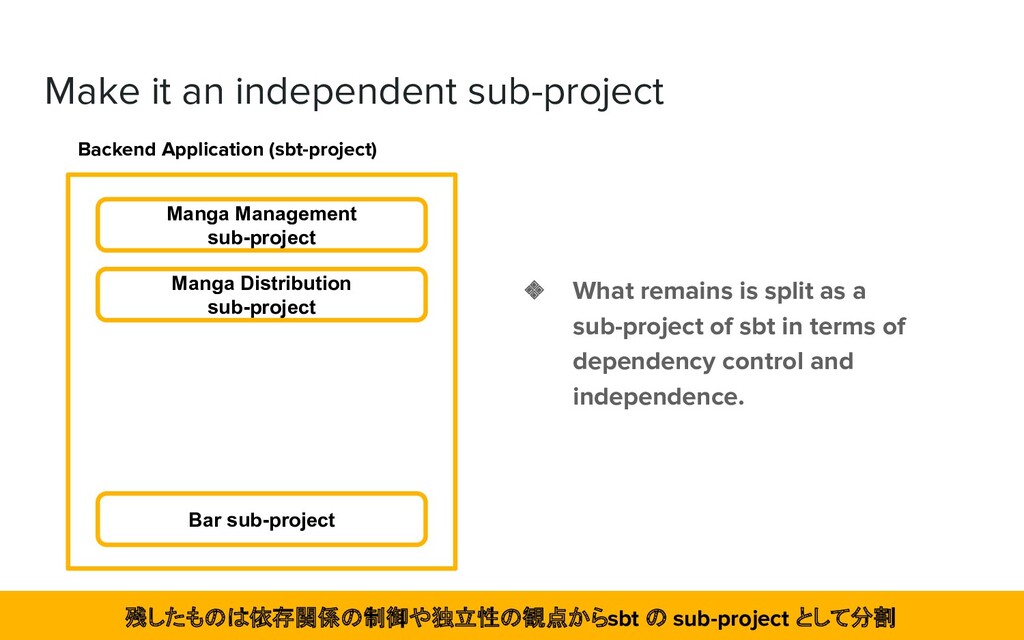
Make it an independent sub-project Backend Application (sbt-project) Manga Management
sub-project Manga Distribution sub-project Bar sub-project ❖ What remains is split as a sub-project of sbt in terms of dependency control and independence. 残したものは依存関係の制御や独立性の観点から sbt の sub-project として分割 -
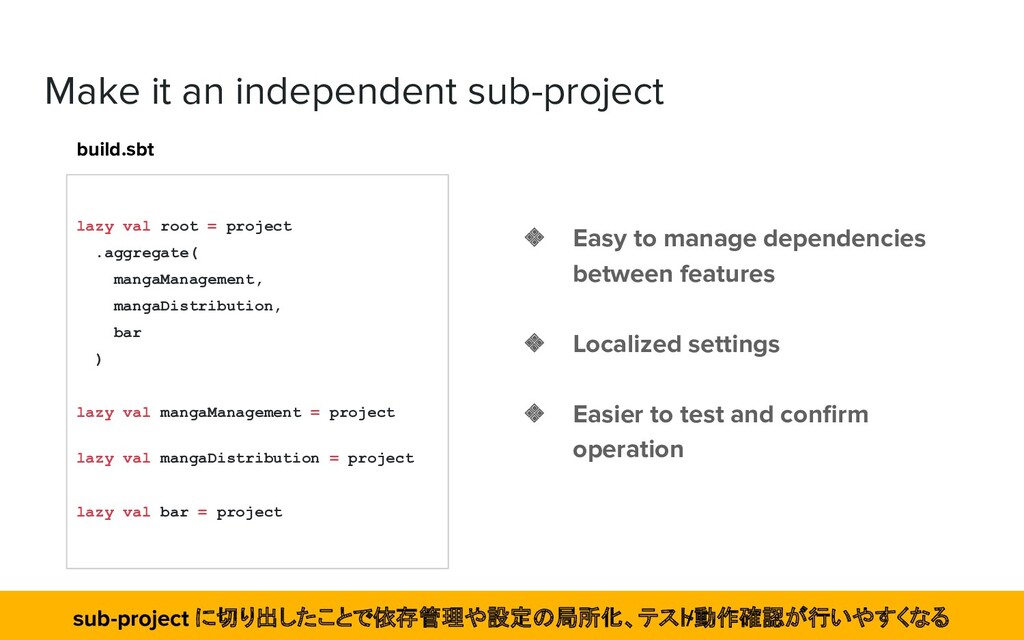
Make it an independent sub-project ❖ Easy to manage dependencies
between features ❖ Localized settings ❖ Easier to test and confirm operation lazy val root = project .aggregate( mangaManagement, mangaDistribution, bar ) lazy val mangaManagement = project lazy val mangaDistribution = project lazy val bar = project build.sbt sub-project に切り出したことで依存管理や設定の局所化、テスト /動作確認が行いやすくなる -
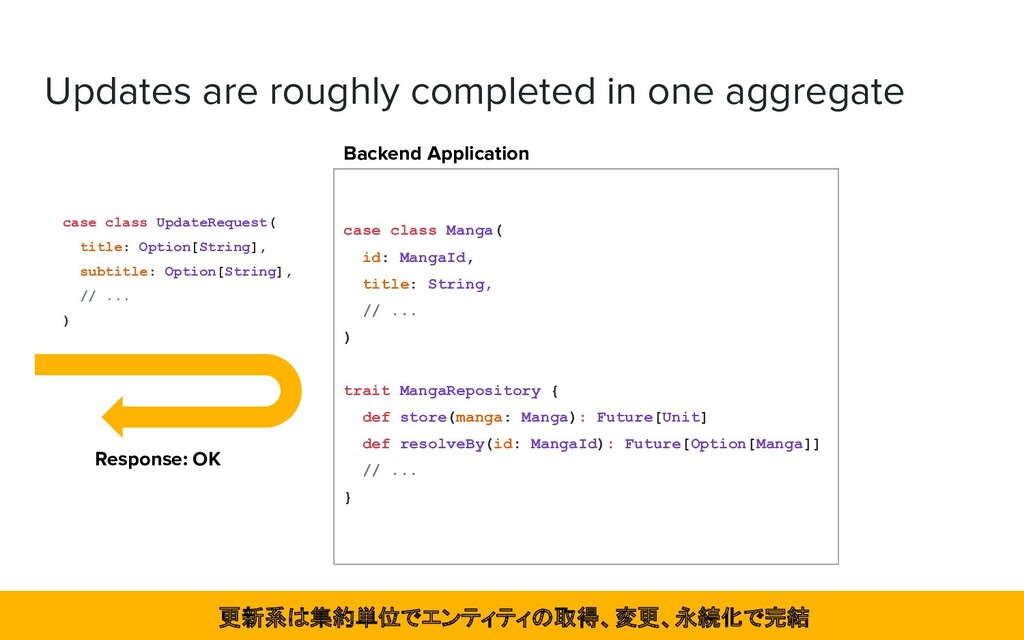
Updates are roughly completed in one aggregate case class Manga(
id: MangaId, title: String, // ... ) trait MangaRepository { def store(manga: Manga): Future[Unit] def resolveBy(id: MangaId): Future[Option[Manga]] // ... } Backend Application case class UpdateRequest( title: Option[String], subtitle: Option[String], // ... ) Response: OK 更新系は集約単位でエンティティの取得、変更、永続化で完結 -
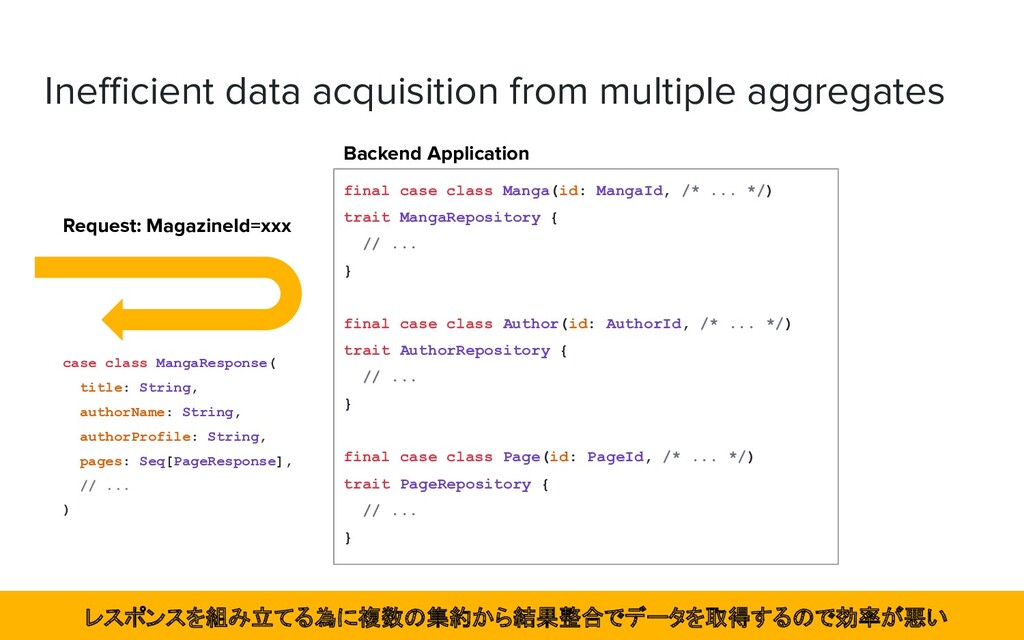
final case class Manga(id: MangaId, /* ... */) trait MangaRepository
{ // ... } final case class Author(id: AuthorId, /* ... */) trait AuthorRepository { // ... } final case class Page(id: PageId, /* ... */) trait PageRepository { // ... } Inefficient data acquisition from multiple aggregates Backend Application case class MangaResponse( title: String, authorName: String, authorProfile: String, pages: Seq[PageResponse], // ... ) Request: MagazineId=xxx レスポンスを組み立てる為に複数の集約から結果整合でデータを取得するので効率が悪い -
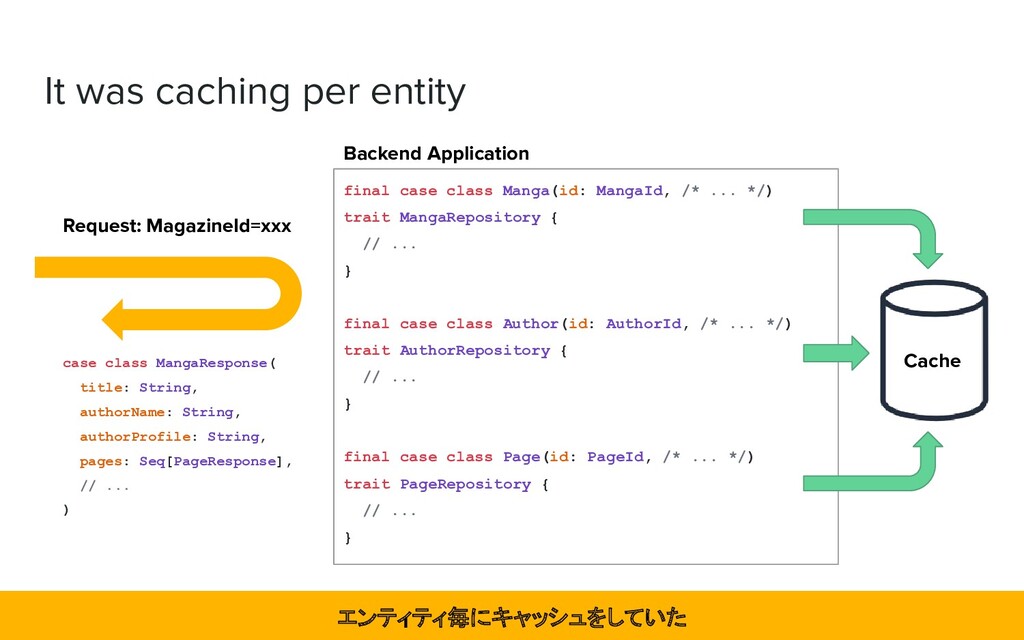
final case class Manga(id: MangaId, /* ... */) trait MangaRepository
{ // ... } final case class Author(id: AuthorId, /* ... */) trait AuthorRepository { // ... } final case class Page(id: PageId, /* ... */) trait PageRepository { // ... } It was caching per entity Backend Application case class MangaResponse( title: String, authorName: String, authorProfile: String, pages: Seq[PageResponse], // ... ) Request: MagazineId=xxx Cache エンティティ毎にキャッシュをしていた -
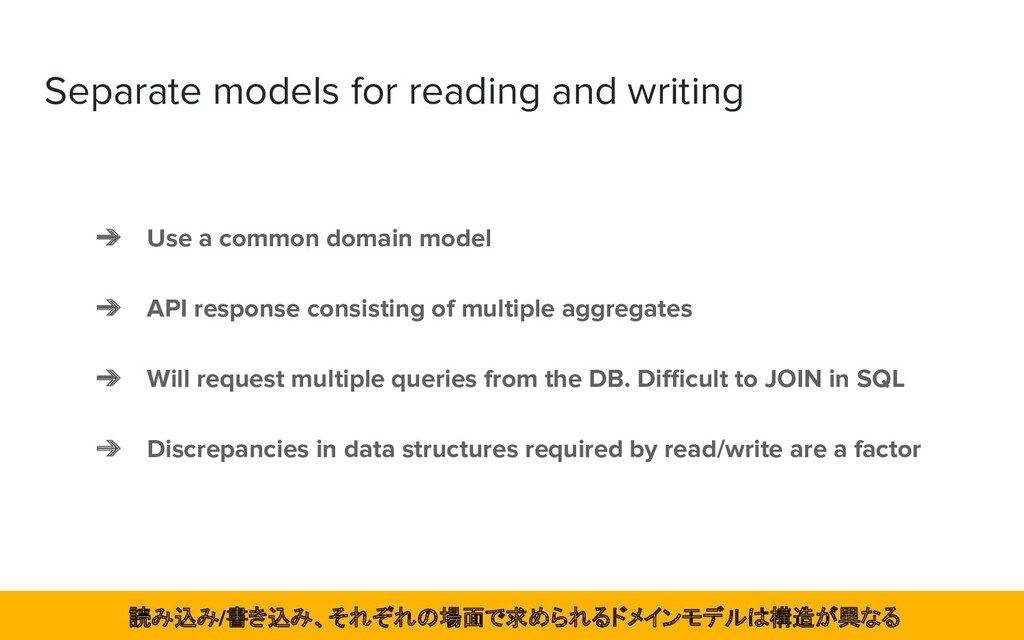
Separate models for reading and writing ➔ Use a common
domain model ➔ API response consisting of multiple aggregates ➔ Will request multiple queries from the DB. Difficult to JOIN in SQL ➔ Discrepancies in data structures required by read/write are a factor 読み込み/書き込み、それぞれの場面で求められるドメインモデルは構造が異なる -
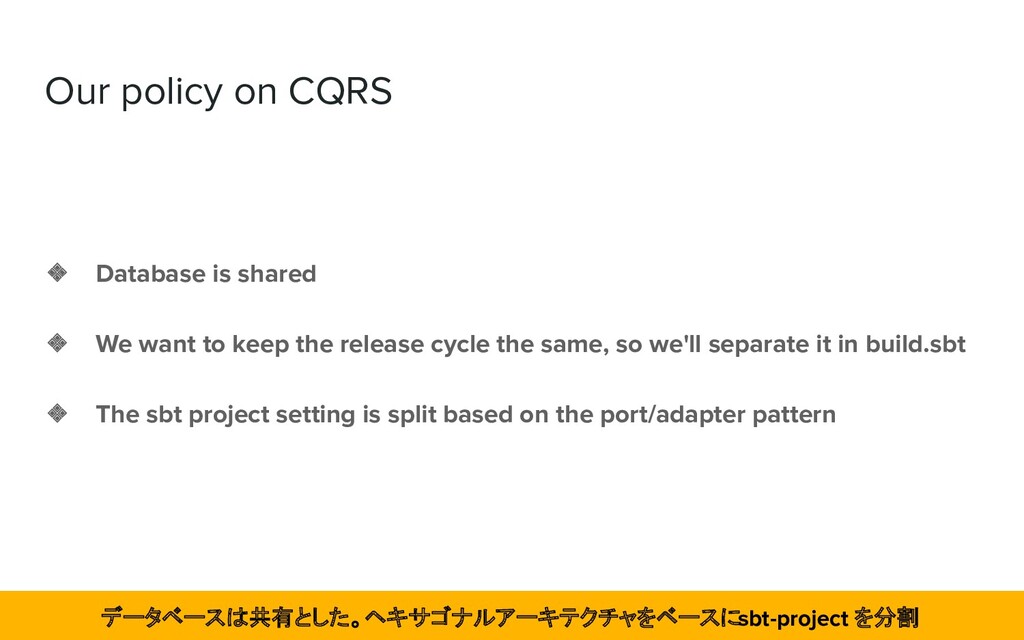
Our policy on CQRS ❖ Database is shared ❖ We
want to keep the release cycle the same, so we'll separate it in build.sbt ❖ The sbt project setting is split based on the port/adapter pattern データベースは共有とした。ヘキサゴナルアーキテクチャをベースに sbt-project を分割 -
Our policy on CQRS - Command lazy val commandModel =
project lazy val commandUseCase = project .dependsOn(commandModel) lazy val commandAdapterRDB = project .dependsOn(commandModel, commandUseCase) lazy val commandAdapterHTTP = project .dependsOn(commandModel, commandUseCase) lazy val commandMain = project .dependsOn(commandModel, commandUseCase, commandAdapterRDB, commandAdapterHTTP) commandAdapter(s) commandModel commandUseCase commandMain Command の sbt-project 定義と構成の概要 -
Our policy on CQRS - Query lazy val queryUseCase =
project lazy val queryAdapterRDB = project .dependsOn(queryUseCase) lazy val queryAdapterHTTP = project .dependsOn(queryUseCase, queryAdapterRDB) lazy val queryMain = project .dependsOn(queryUseCase, queryAdapterRDB, queryAdapterHTTP) queryUseCase queryAdapter(s) queryMain Query の sbt-project 定義と構成の概要 -
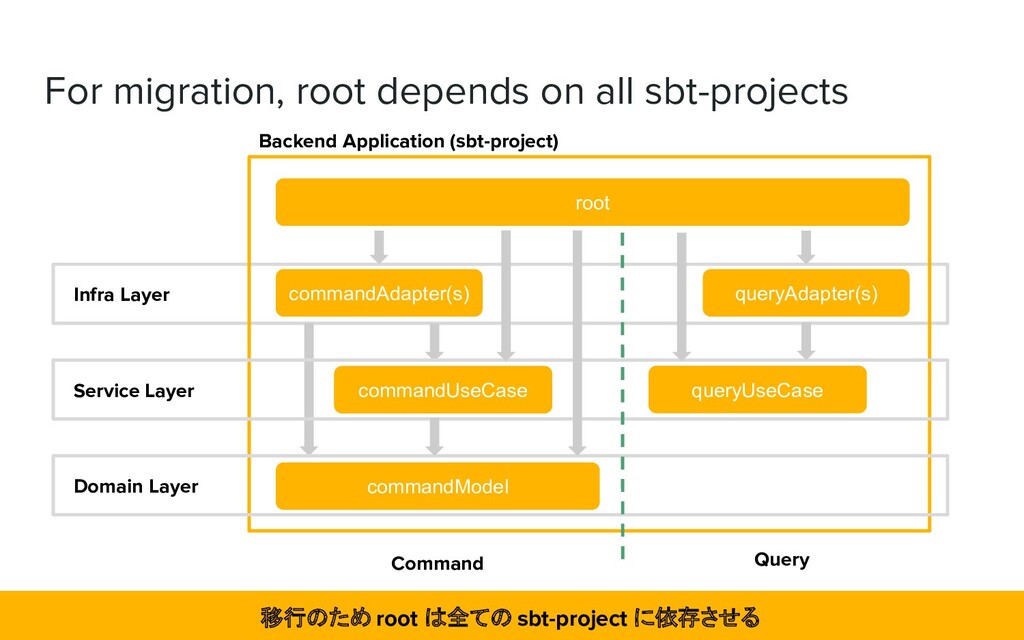
For migration, root depends on all sbt-projects lazy val root
= project .dependsOn( // Manga Management mangaManagement, // Manga Distribution commandModel, commandUseCase, commandAdapterRDB, commandAdapterHTTP, commandMain, queryUseCase, queryAdapterRDB, queryAdapterHTTP, queryMain, // other bar ) .aggregate( /* ... */ ) 移行のため root は全ての sbt-project に依存させる -
commandAdapter(s) For migration, root depends on all sbt-projects Domain Layer
commandModel commandUseCase root queryUseCase queryAdapter(s) Service Layer Infra Layer Command Query Backend Application (sbt-project) 移行のため root は全ての sbt-project に依存させる -
Migration to the new architecture ❖ We've made old projects
dependent on new projects ❖ The API implementation was moved (re-implemented), categorized by command / query コマンド/クエリの分類をしながら古い実装を移動 (再実装)していった -
Migration to the new architecture The rest is just a
matter of time. Everything is fine ... あとは粛々と進めるだけ。全て順調 ... -
Unspecified API responses ➔ There was no DTO and the
response JSON was dynamically assembled ➔ The structure cannot be ignored in order to migrate the implementation without changing the behavior of the API ➔ There was a demand for this in the development of new API ➔ It's hard to documentation with OpenAPI レスポンス JSON が動的に組み立てられていた。構造をドキュメント化したいが OpenAPI は辛い -
Original API Specification Language We developed Outer DSL to define
the API specifications API 仕様を定義する独自の DSL を開発 -
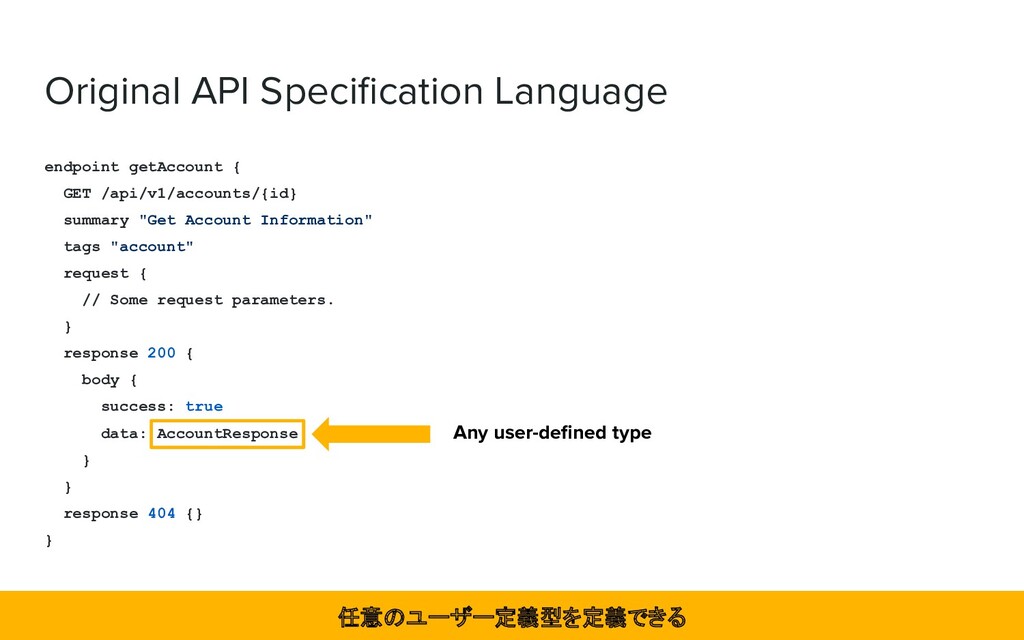
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters. } response 200 { body { success: true data: AccountResponse } } response 404 {} } API 仕様記述言語の例 -
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters } response 200 { body { success: true data: AccountResponse } } response 404 {} } URL, Overview, and other API information API 仕様記述言語: URL や概要などの情報を記述 -
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters } response 200 { body { success: true data: AccountResponse } } response 404 {} } Request parameters. Headers, forms, query strings, etc. API 仕様記述言語: ヘッダーやフォーム、クエリ文字列などリクエストを定義 -
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters } response 200 { body { success: true data: AccountResponse } } response 404 {} } Response data. Status, Headers, body, etc API 仕様記述言語: ステータスやヘッダー、ボディの構造などレスポンスを定義 -
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters. } response 200 { body { success: true data: AccountResponse } } response 404 {} } Generate openapi: 3.0.0 ... paths: /api/v1/accounts/{id}: get: operationId: getAccount parameters: ... responses: '200': content: application/json: schema: properties: data: $ref: '#/components/schemas/AccountResponse' success: enum: - 'true' type: boolean required: - success - data type: object description: '' '404': ... API 仕様記述言語から OpenAPI の YAML を生成する -
Original API Specification Language endpoint getAccount { GET /api/v1/accounts/{id} summary
"Get Account Information" tags "account" request { // Some request parameters. } response 200 { body { success: true data: AccountResponse } } response 404 {} } Any user-defined type 任意のユーザー定義型を定義できる -
Original API Specification Language type EmailAddress = String type AccountResponse
= { name: String emailAddress: EmailAddress age?: Int32 } DSL - API Specification Language API 仕様記述言語で定義されたデータ構造から直接 Scala のコードを生成し、DTO として利用 -
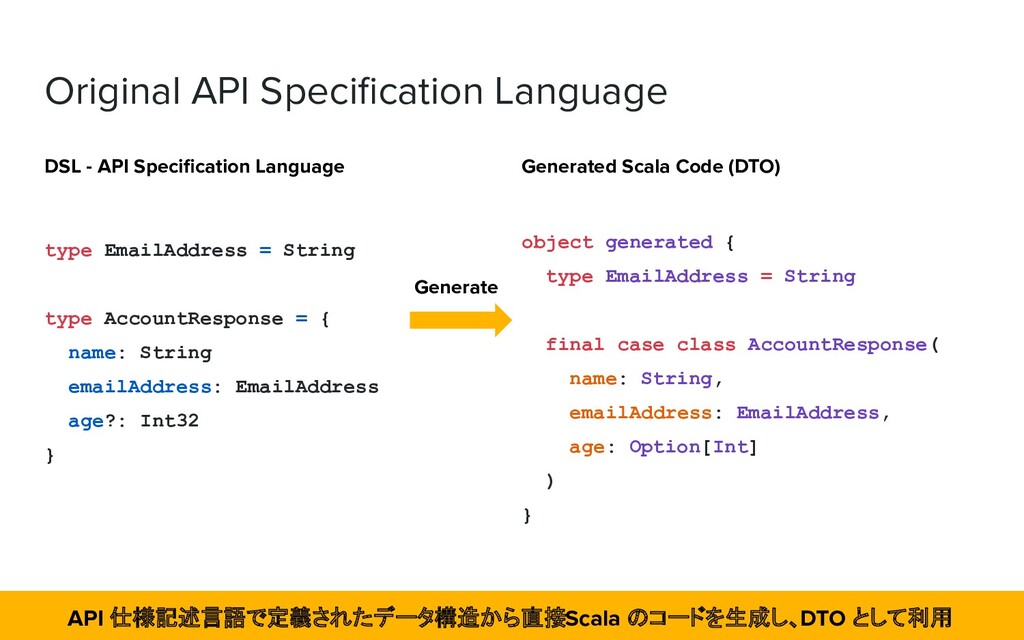
Original API Specification Language type EmailAddress = String type AccountResponse
= { name: String emailAddress: EmailAddress age?: Int32 } object generated { type EmailAddress = String final case class AccountResponse( name: String, emailAddress: EmailAddress, age: Option[Int] ) } Generate DSL - API Specification Language Generated Scala Code (DTO) API 仕様記述言語で定義されたデータ構造から直接 Scala のコードを生成し、DTO として利用 -
Original API Specification Language ❖ Save time on specification definition
❖ No need to test the JSON structure, so less testing time is required ❖ The generated DTO makes it easier to implement new features DSL を開発したことで仕様定義やテスト、 API の移行や新機能の開発について工数を削減できた -
Result of Application Improving ❖ Dividing it up by feature
has made it easier to estimate the work ➢ Reduced CI and release time ❖ Open to expand and close to modify compared to before re-architecture ➢ It also led to a system for inter-service communication in the k8s cluster 分割したことで作業見積もりのしやすさや CI/CD の時間削減、機能の追加変更に強くなった -
Prevention is also important Even if you do your best
to repay your technical debt, there is no point in adding it faster than that. 技術的負債を増やさないよう予防する -
Focus on design and documentation ❖ Flexible development flow based
on the size of the development item ➢ Design is always necessary, but you can flexibly switch between them depending on the scale of the project and the time it takes to work. ➢ If it is complicated, implement user story mapping etc ❖ Incorporated the definition of communication format by DSL into the flow ➢ Developers can now seamlessly define specifications between server and client 規模感に応じた設計/開発の流れを柔軟に。API 仕様定義 DSL を開発フローに組み込んだ -
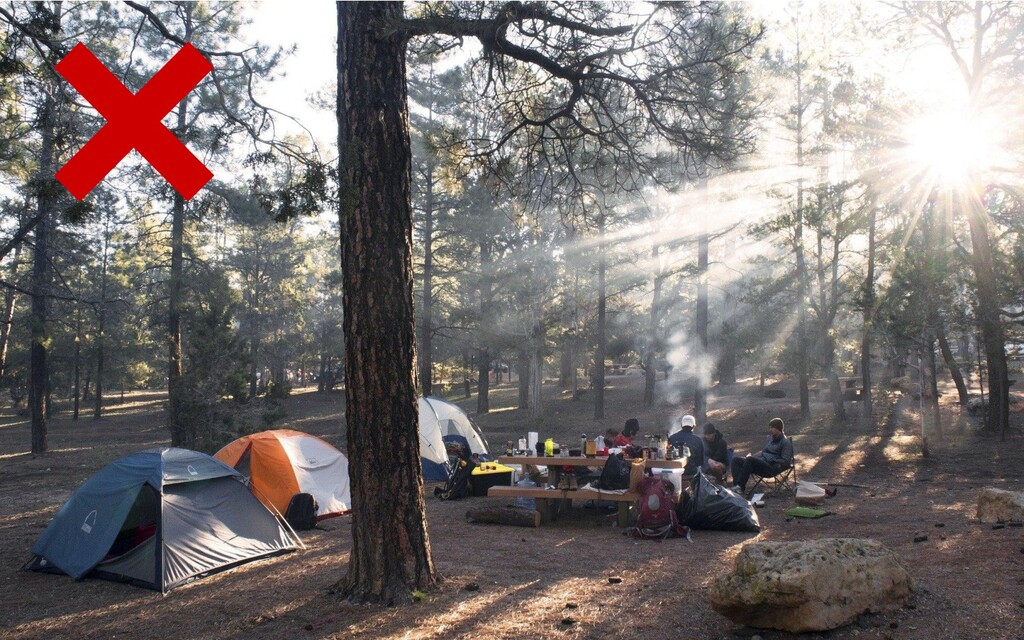
An effort called “Camp” ❖ It’s like pre-season training for
a baseball team. ➢ It is not a Camping ➢ Held once a quarter, two weeks ❖ Do “Not Urgent but Important” tasks. ➢ No feature development tickets will be implemented. ❖ Contributes not only to repayment of technical debt, but also to elimination of events that could become debt in the future 四半期に一度「重要だけど緊急でない」作業に二週間がっつり取り組む通称「キャンプ」を実施 -
Conclusion We chose to re-architect and continue to make steady
improvements. 我々はリアーキテクチャを選び、地道に改善を続けることを選んだ -
Result of Infrastructure Improving (re-post) ❖ The division of the
Backend Application is now more flexible ➢ Terraform allows us to rebuild our own systems from the infrastructure ➢ Existing members of the team are now experienced in building initial infrastructure ❖ It led to reduced operational costs ➢ All application engineers can now manage the infrastructure as well アプリケーション分割に自由度が生まれ、再構築が可能になり、コスト削減にもつながった -
Result of Application Improving (re-post) ❖ Dividing it up by
feature has made it easier to estimate the work ➢ Reduced CI and release time ❖ Open to expand and close to modify compared to before re-architecture ➢ It also led to a system for inter-service communication in the k8s cluster 分割したことで作業見積もりのしやすさや CI/CD の時間削減、機能の追加変更に強くなった -
Achieve our objectives Increase system availability and maintainability Create a
new implementation policy and de facto standard 可用性と保守性を高める事に成功し、新しい実装の方針、デファクトスタンダードを確立した -
Conclusion ❖ As a result of accumulating small improvements, we
have achieved great results ➢ We didn't choose to system replace or big-rewrite ➢ It took a while, but I was able to see and feel the changes ❖ Re-architecture given us a flexible system ➢ The groundwork has been laid for the introduction of advanced technology. ➢ This is passage. To be continued… ❖ We have an ongoing system in place to confront technical debt ➢ An approach from both a technical debt repayment and prevention perspective. 小さな改善を積み重ね、柔軟なシステムを得た。技術的負債と向き合う体制も整備。改善はつづく
 aoiroaoino
 moro
 dalinaum
 takai
 steliosf
 sorah
 rkaga
 akihisaikeda
 iwiwi
 sodainc
 kmkim
 hal_spidernight
 axbom
 mfonobong
 shlominoach
 scottboms
 maltzj
 retrage
 katiecoart
 sachag
 reverentgeek
 aleyda
 codingconduct