Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
発表用スライド「Auris」
Search
ユウト
May 01, 2024
75
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
発表用スライド「Auris」
ユウト
May 01, 2024
Featured
See All Featured
I Don’t Have Time: Getting Over the Fear to Launch Your Podcast
jcasabona
35
2.9k
The Myth of the Modular Monolith - Day 2 Keynote - Rails World 2024
eileencodes
28
3.7k
Making Projects Easy
brettharned
120
6.8k
Lightning talk: Run Django tests with GitHub Actions
sabderemane
0
300
Max Prin - Stacking Signals: How International SEO Comes Together (And Falls Apart)
techseoconnect
PRO
0
490
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
990
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
360
職位にかかわらず全員がリーダーシップを発揮するチーム作り / Building a team where everyone can demonstrate leadership regardless of position
madoxten
69
67k
Test your architecture with Archunit
thirion
2
2.4k
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k
Navigating Team Friction
lara
192
16k
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
300
Transcript
歌声合成, 変換, TTSが できる効率的な日本語 事前学習済みモデルの 開発 Auris uthree, yuto Project
Auris
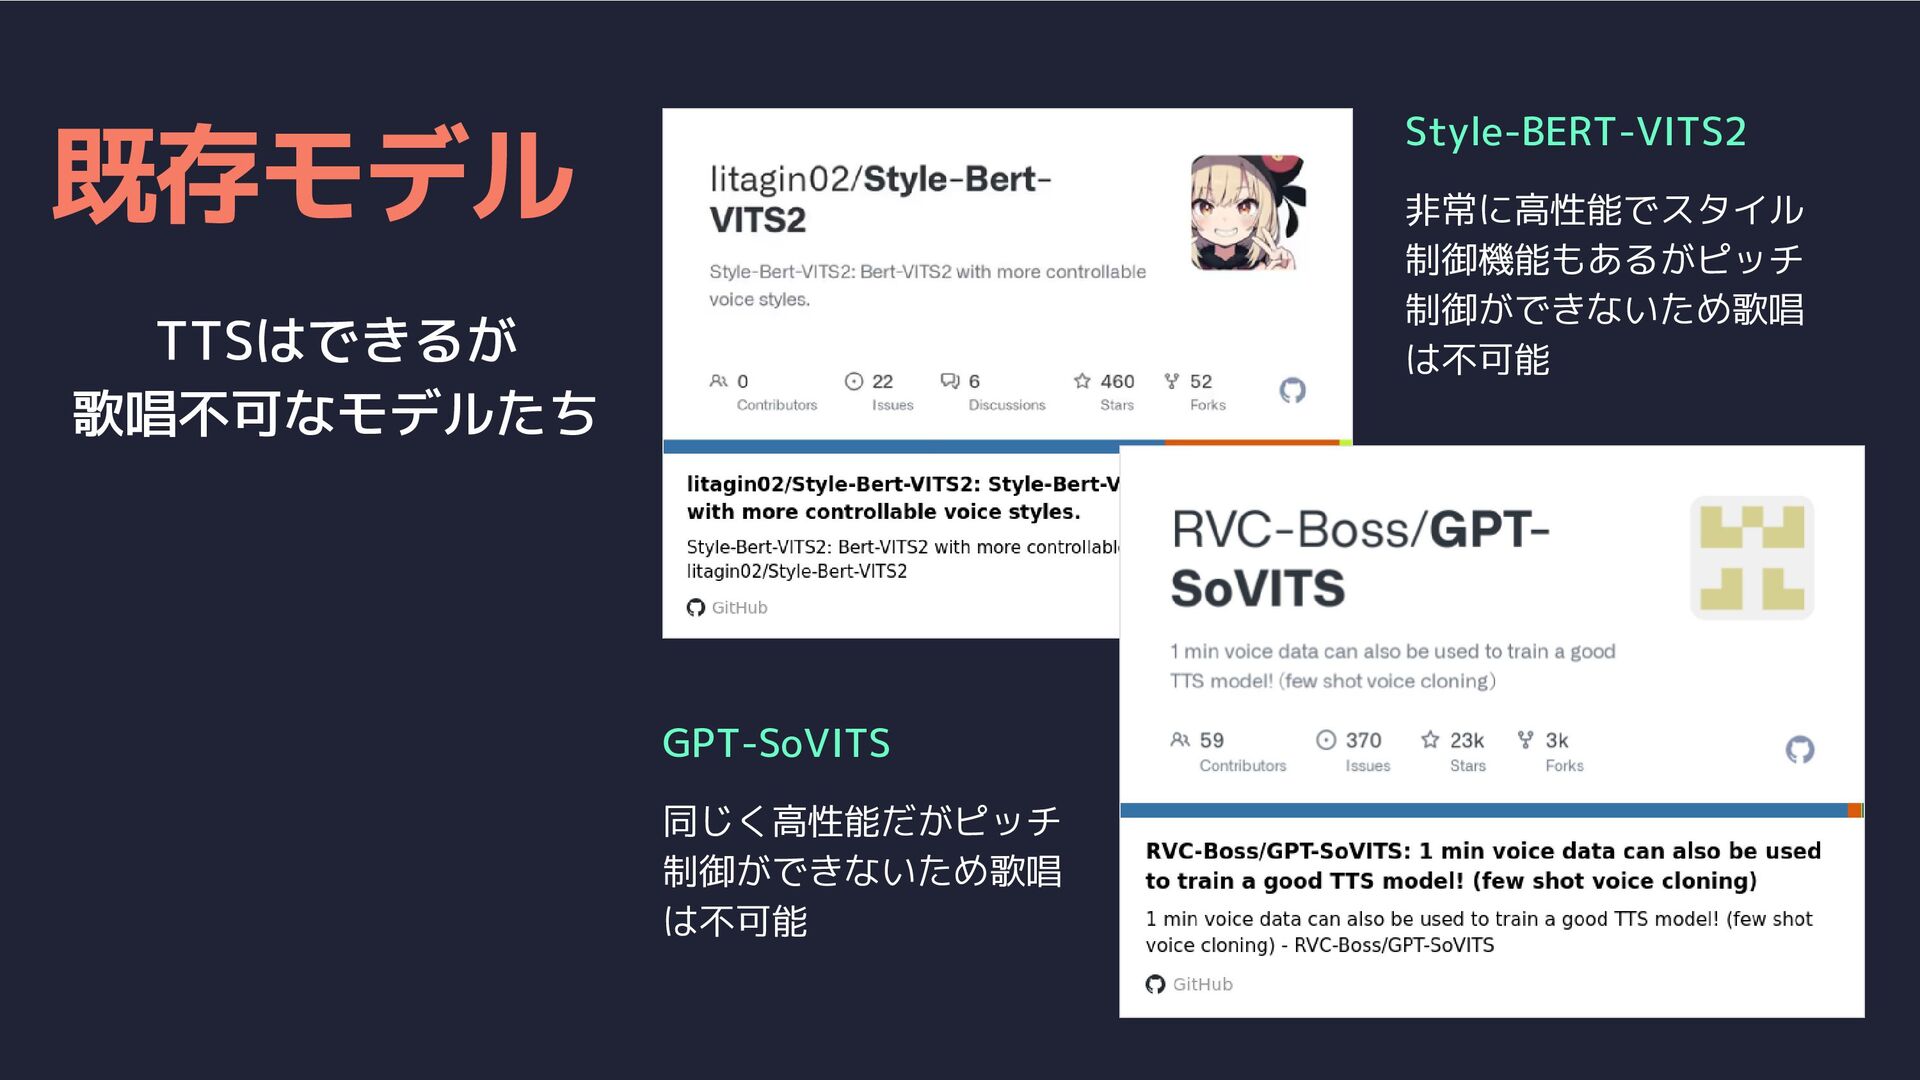
既存モデル 非常に高性能でスタイル 制御機能もあるがピッチ 制御ができないため歌唱 は不可能 Style-BERT-VITS2 同じく高性能だがピッチ 制御ができないため歌唱 は不可能 GPT-SoVITS
TTSはできるが 歌唱不可なモデルたち
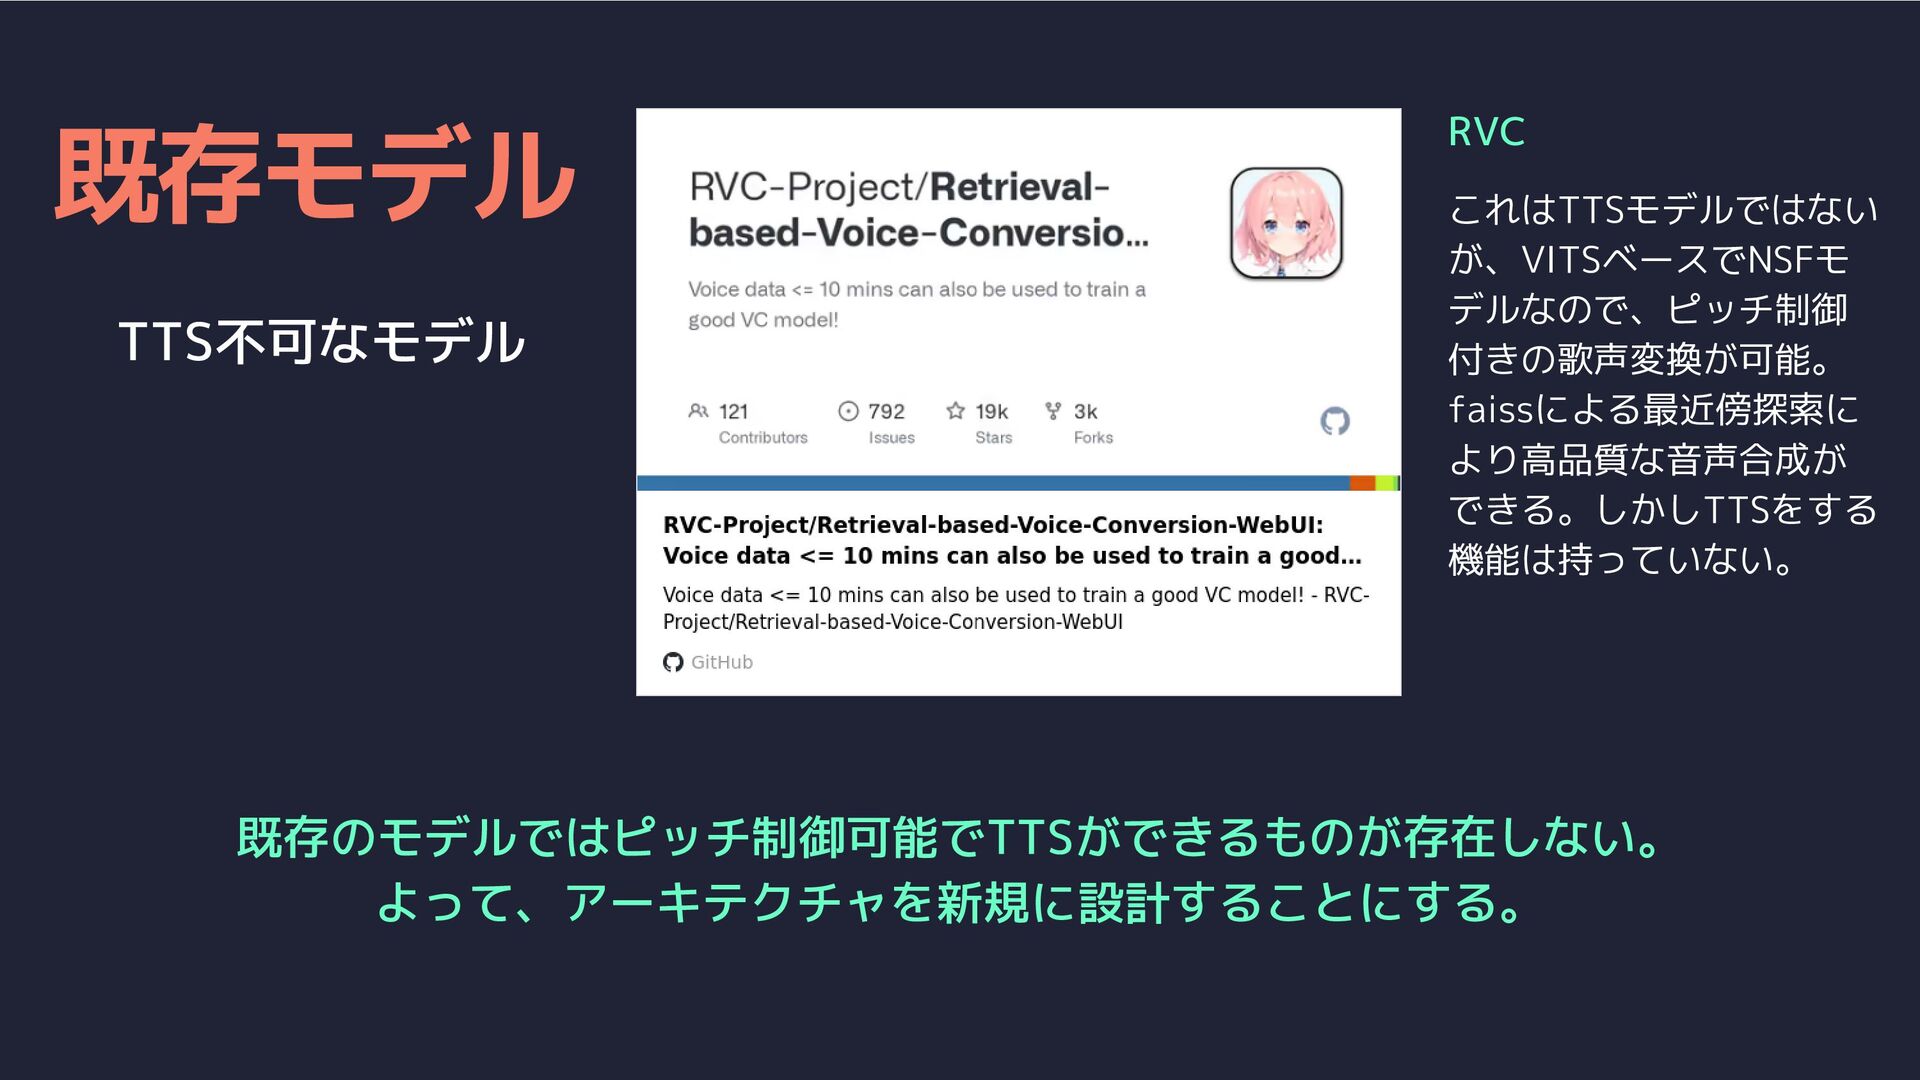
既存モデル これはTTSモデルではない が、VITSベースでNSFモ デルなので、ピッチ制御 付きの歌声変換が可能。 faissによる最近傍探索に より高品質な音声合成が できる。しかしTTSをする 機能は持っていない。 RVC
既存のモデルではピッチ制御可能でTTSができるものが存在しない。 よって、アーキテクチャを新規に設計することにする。 TTS不可なモデル
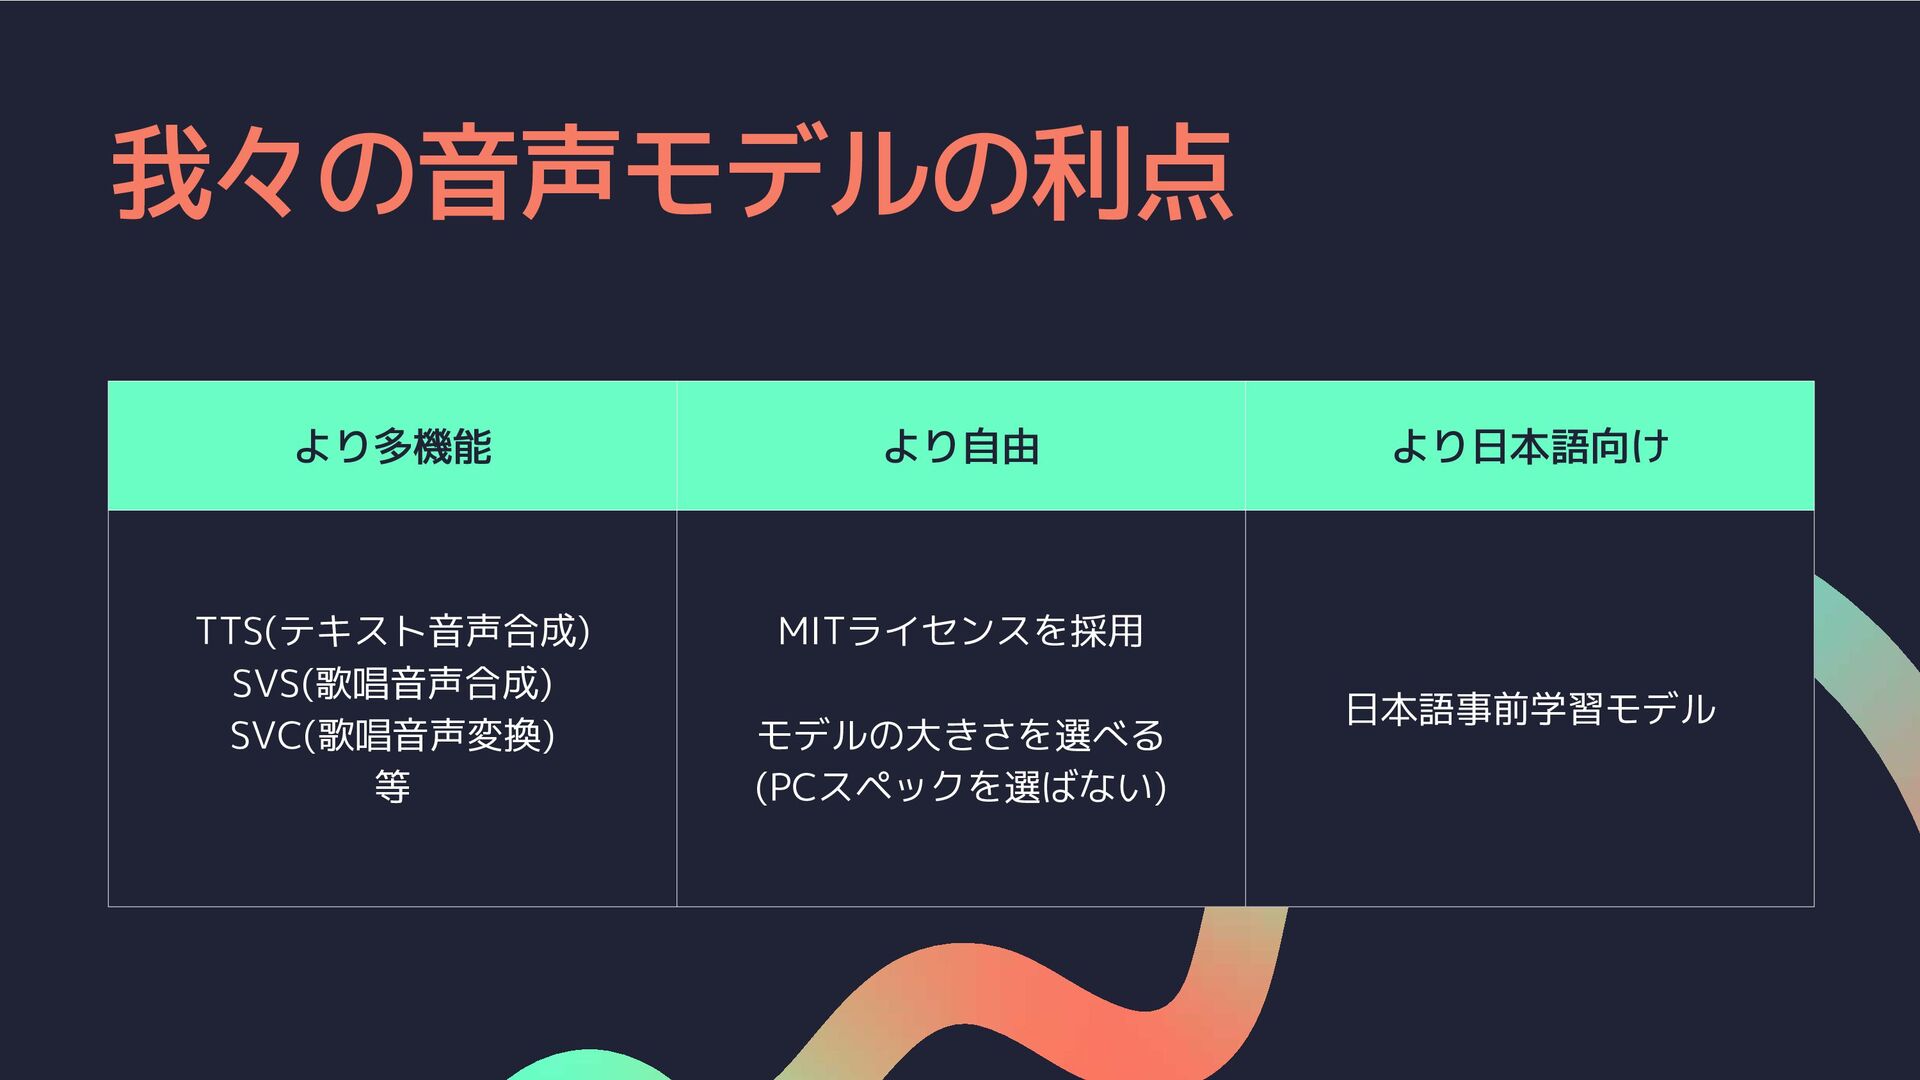
我々の音声モデルの利点 より多機能 より自由 より日本語向け TTS(テキスト音声合成) SVS(歌唱音声合成) SVC(歌唱音声変換) 等 MITライセンスを採用 モデルの大きさを選べる
(PCスペックを選ばない) 日本語事前学習モデル
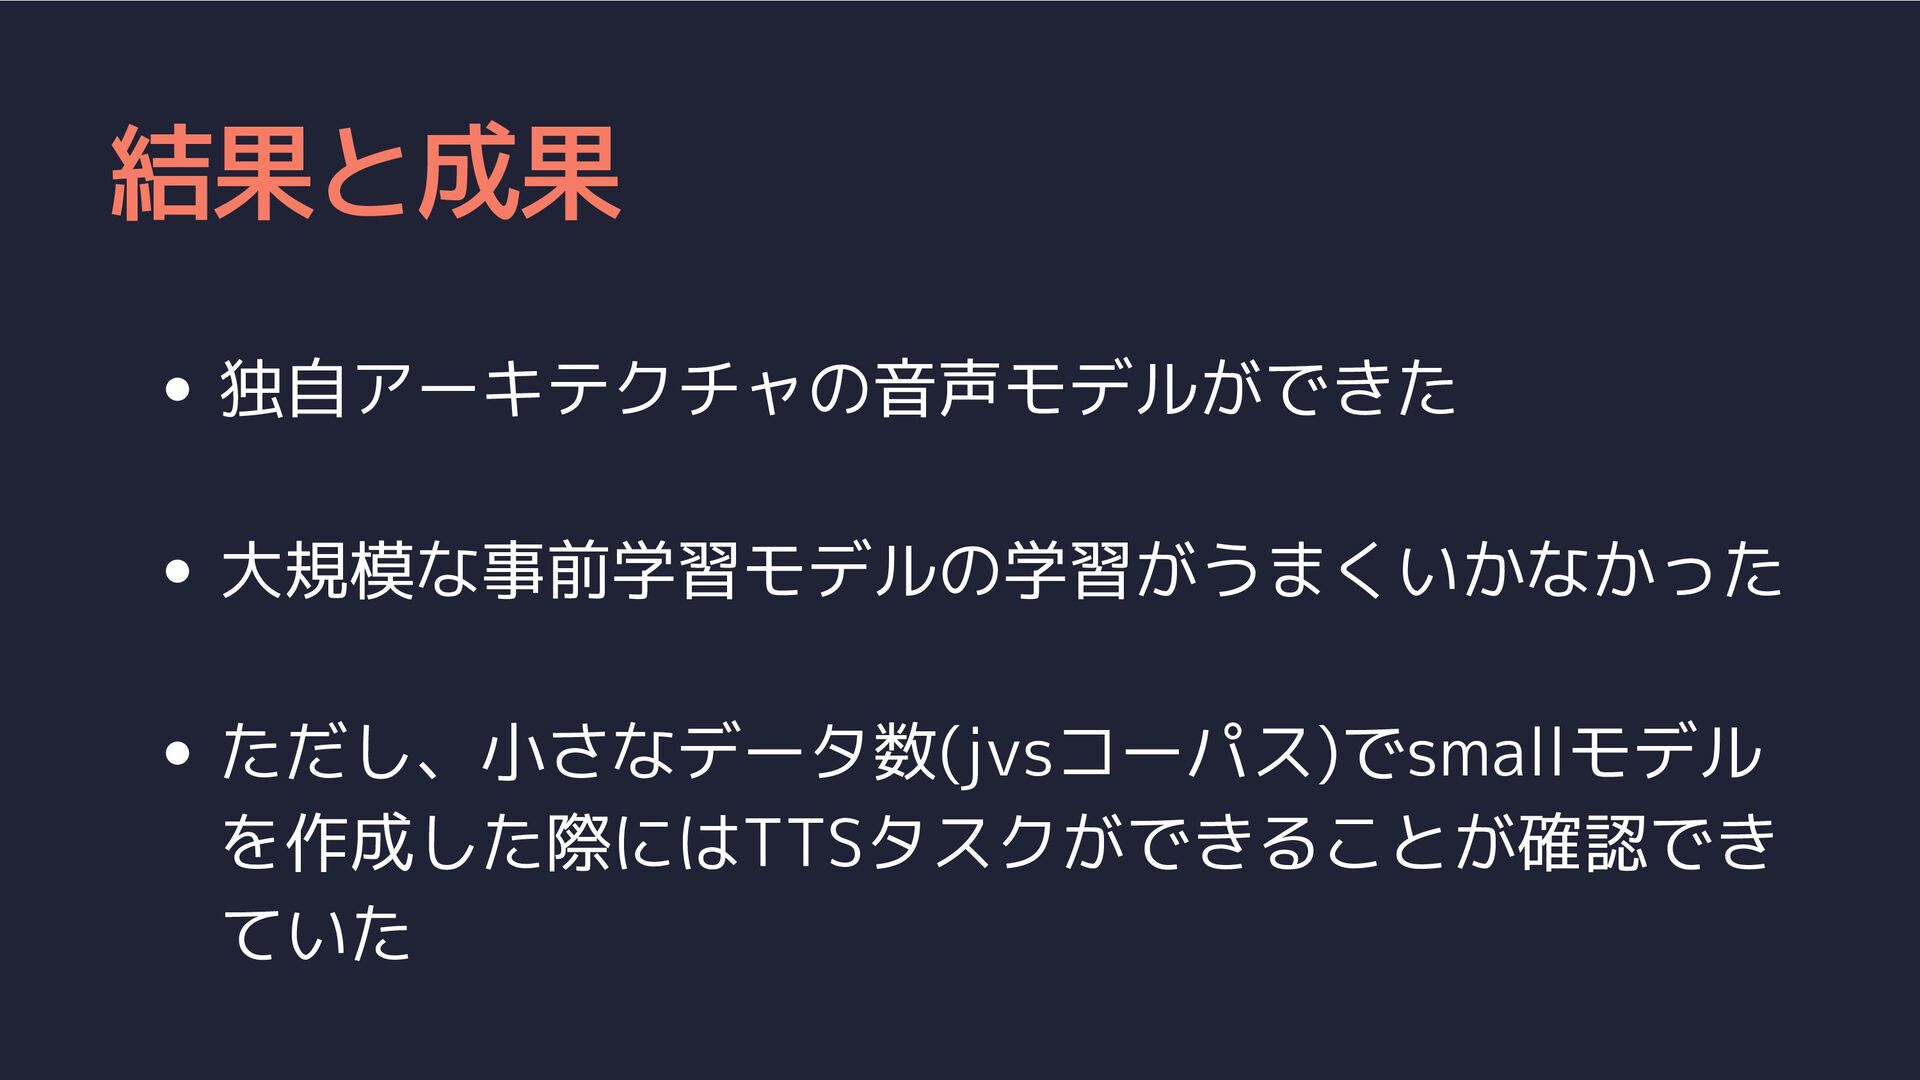
結果と成果 独自アーキテクチャの音声モデルができた 大規模な事前学習モデルの学習がうまくいかなかった ただし、小さなデータ数(jvsコーパス)でsmallモデル を作成した際にはTTSタスクができることが確認でき ていた
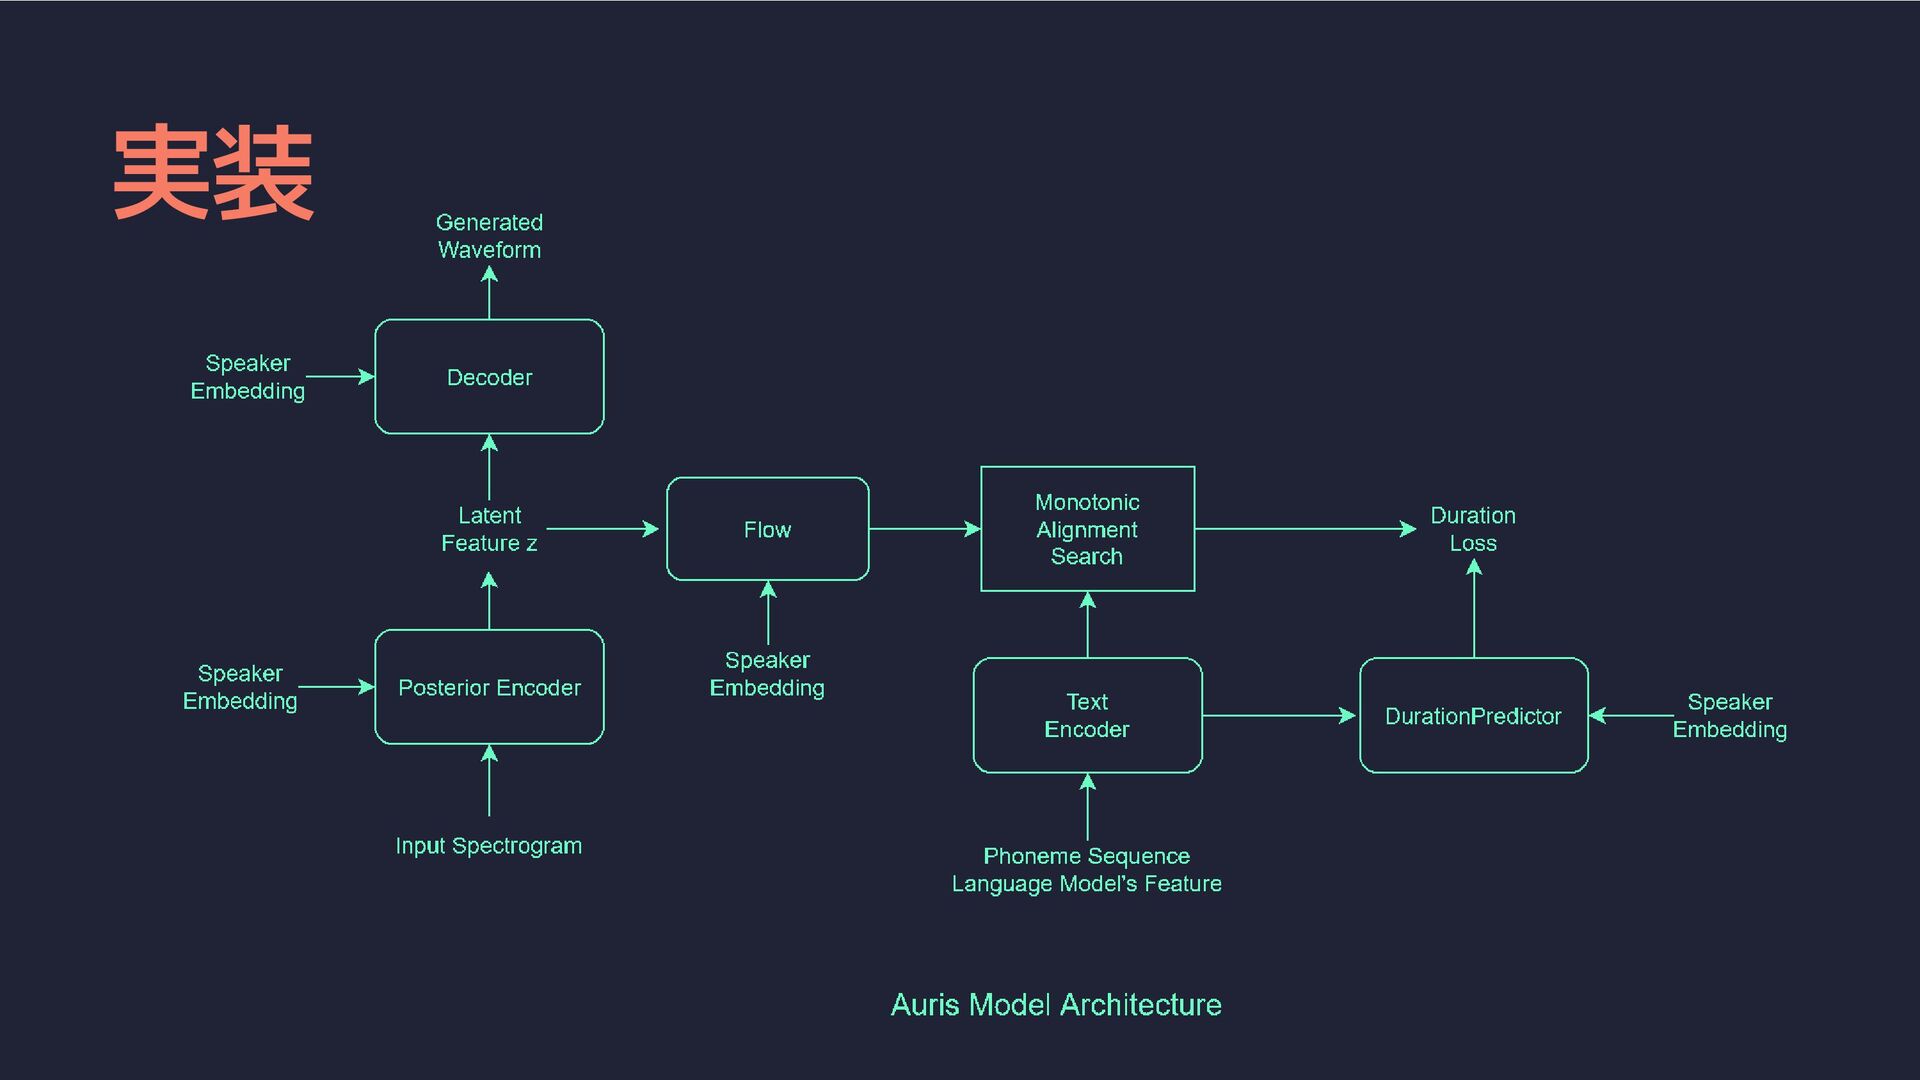
実装
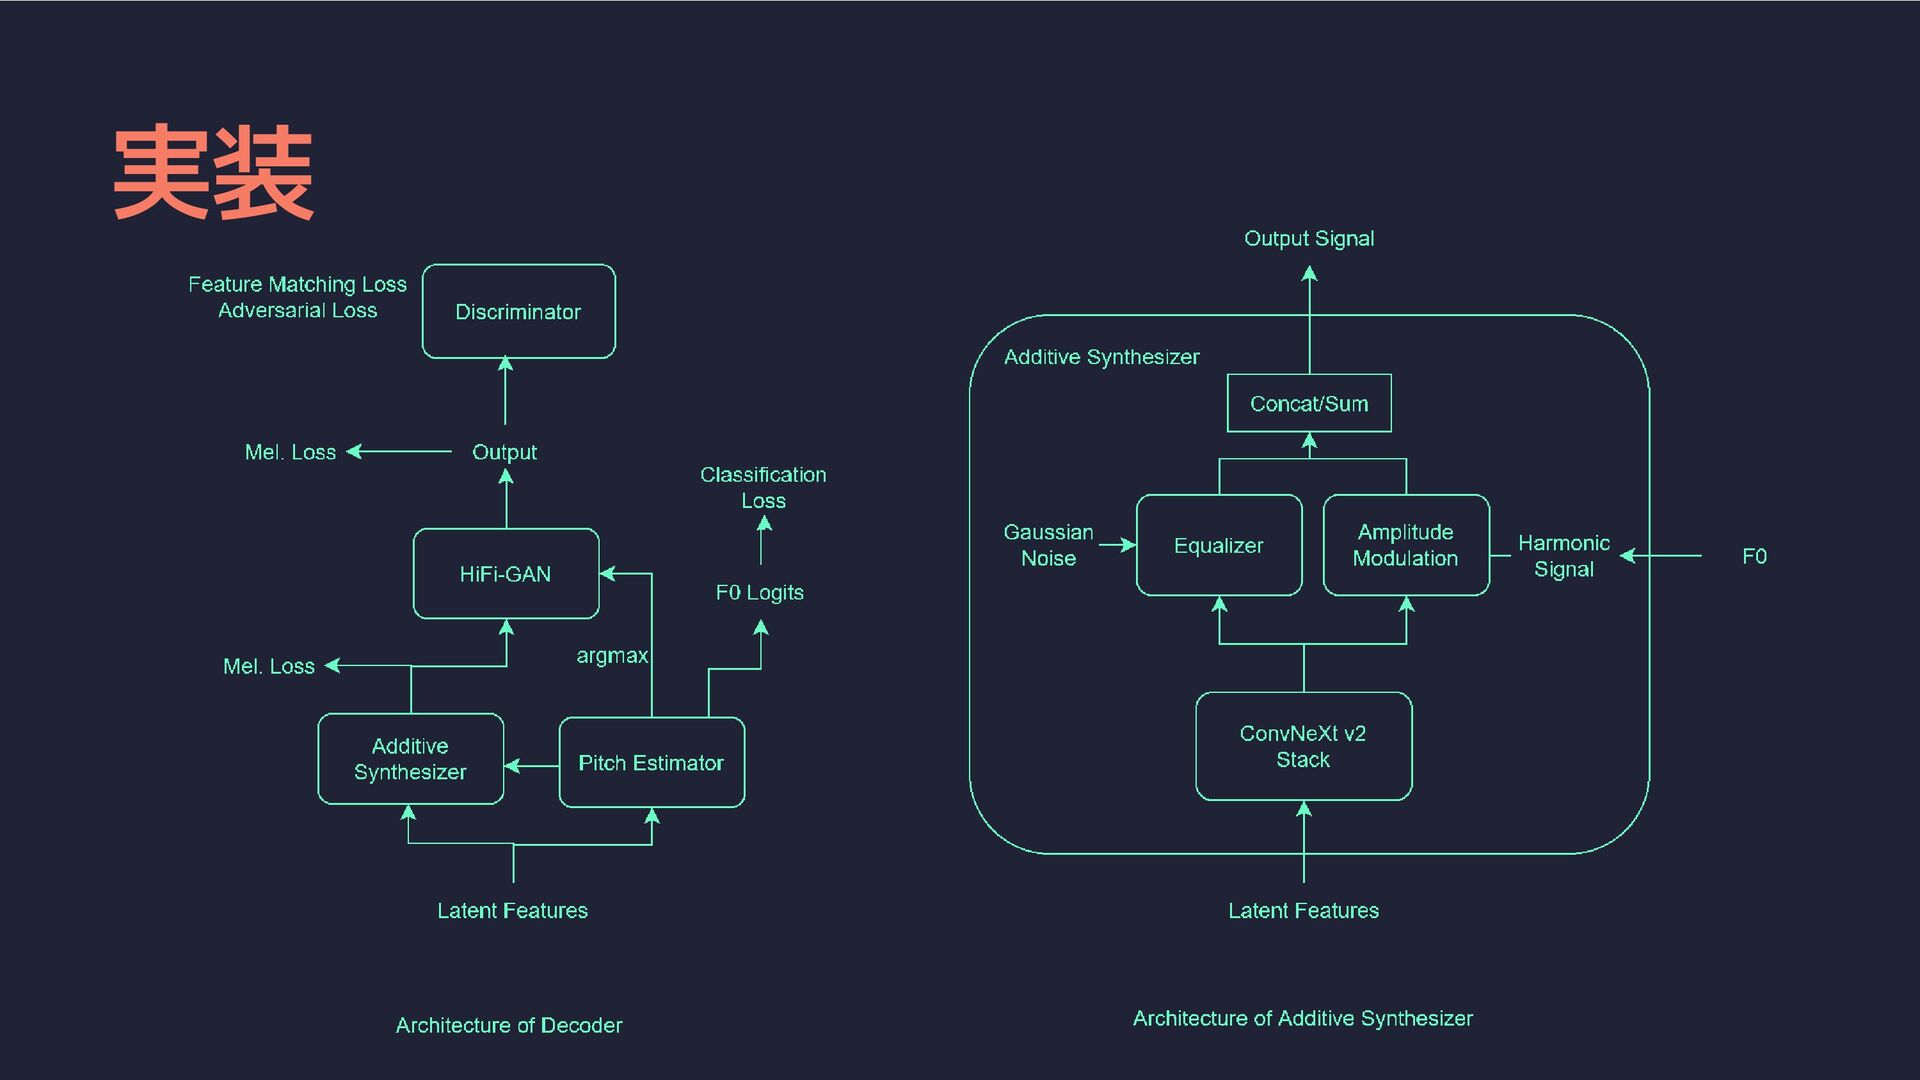
実装
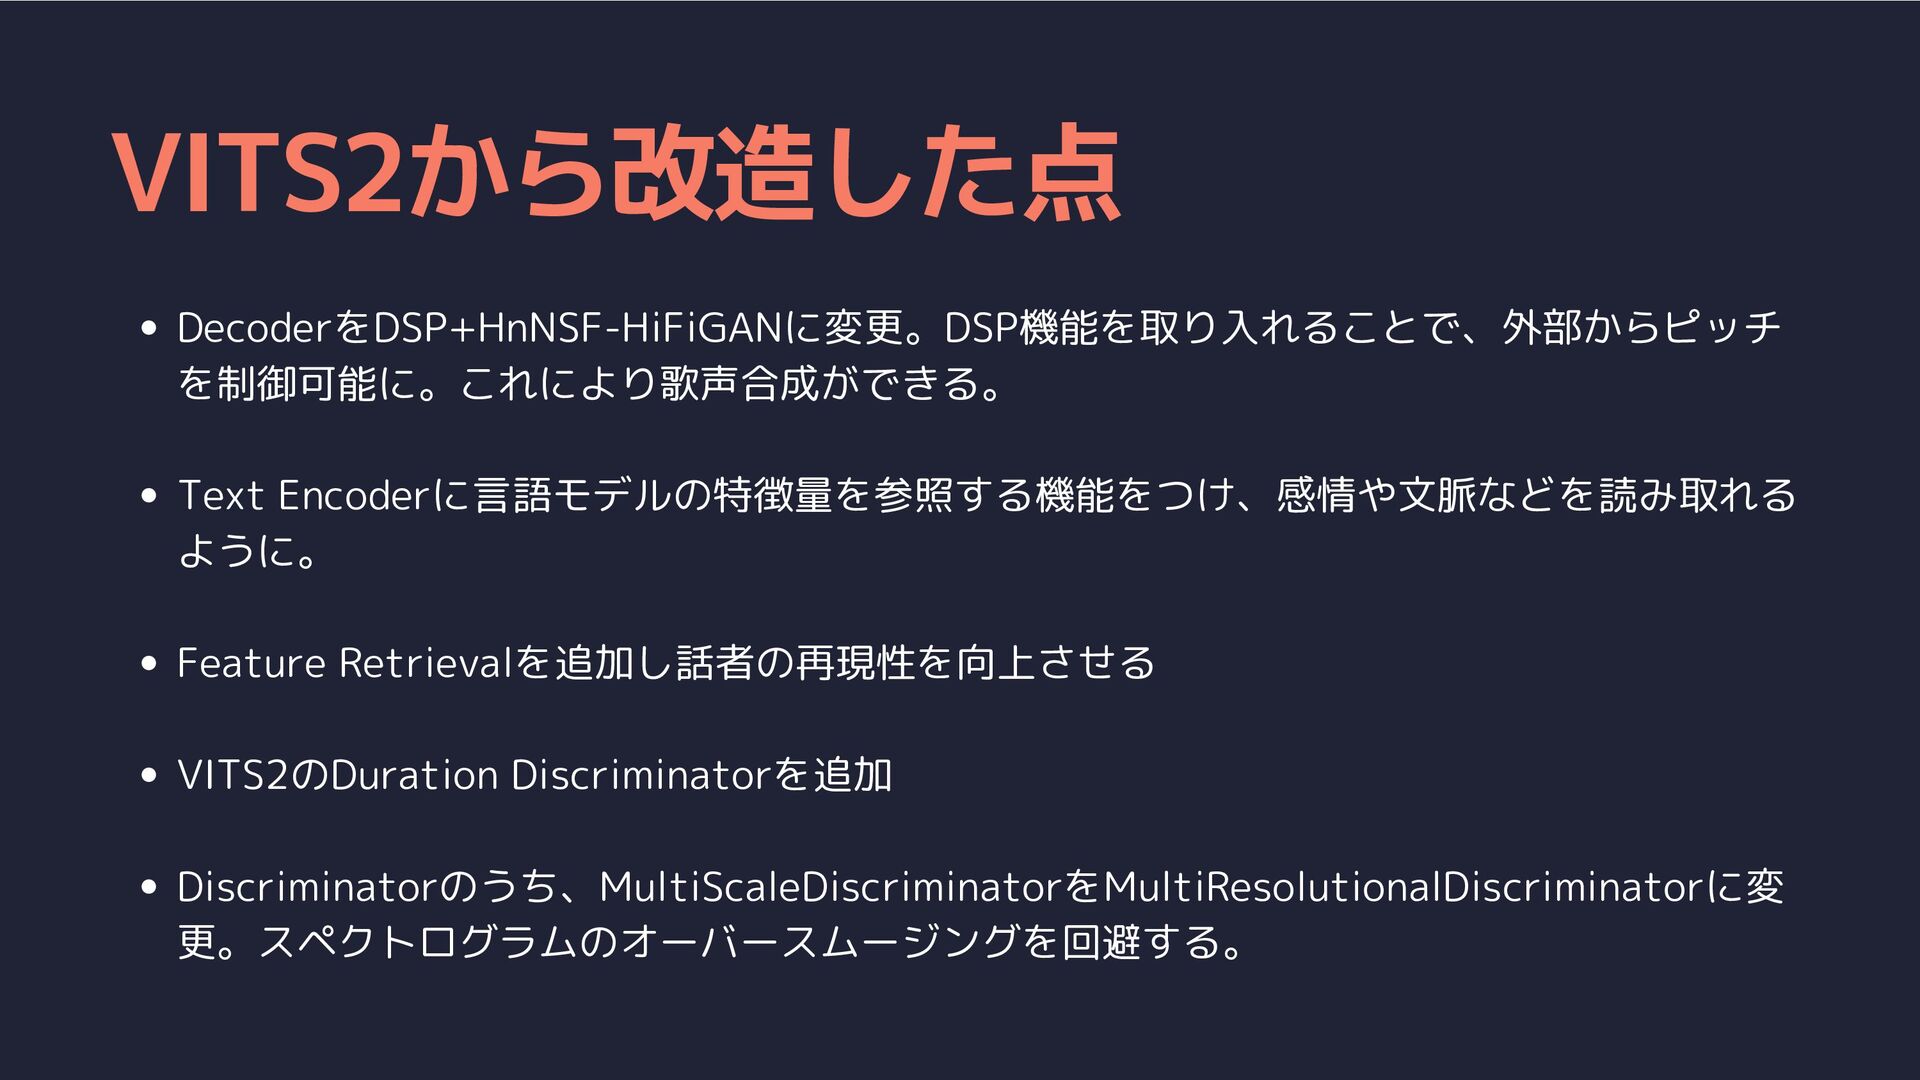
VITS2から改造した点 DecoderをDSP+HnNSF-HiFiGANに変更。DSP機能を取り入れることで、外部からピッチ を制御可能に。これにより歌声合成ができる。 Text Encoderに言語モデルの特徴量を参照する機能をつけ、感情や文脈などを読み取れる ように。 Feature Retrievalを追加し話者の再現性を向上させる VITS2のDuration Discriminatorを追加
Discriminatorのうち、MultiScaleDiscriminatorをMultiResolutionalDiscriminatorに変 更。スペクトログラムのオーバースムージングを回避する。
うまくいかなかった原因の考察 ハイパーパラメータの値 が、手元のコンピュター、 学習素材を用いて学習した 時とは勝手が異なっており 学習がうまくいかなかった 正直原因がわかっていない
今後の展望 うまくいかなかった事前学習モデル作成をまたの 機会にリベンジしたい リベンジ 作成した音声モデルはGit Hubで公開する 第三者によるレビューを受けて改善したい コード公開
質問はございますか? ありがとう ございました


 jcasabona
 eileencodes
 brettharned
 sabderemane
 techseoconnect
 frankvandijk
 nikkihalliwell
 madoxten
 thirion
 tammyeverts
 lara
 sarafernandez