Share
Embed
Transcript
58 slides
-
How much data can we cram into 16GB RAM with
less budget? Joeun Park #pyconapac_5 13:30-13:45 1 -
• Using Pandas to reduce file size: Chunking, changing file
formats, and compression techniques. • How to minimize memory usage by adjusting data types. • Strategies to reduce both memory and file size simultaneously. • Using the Parquet File Format Agenda Image generated by OpenAI's DALL·E 3 3 -
One day, someone with a computer🖥 that only had 8GB
of RAM came to me for help. They were facing the challenge of having to load and analyze📊 a file that was a massive 32GB. 🤔 Image generated by OpenAI's DALL·E 3 4 -
They wanted a solution that 🚫 didn't involve buying a
new laptop 💻 or racking up costs 💰 on cloud services. ☁🔧 Image generated by OpenAI's DALL·E 3 5 -
💻 If you're on a tight budget and working with
the equipment you already possess, you might need to explore ways to minimize memory usage to get things done. 😟💰🔒🛠🔍 Image generated by OpenAI's DALL·E 3 6 -
So, I'm going to share some tips💡 on how you
can load 🔄, preprocess, and analyze data📊 that's far larger than your computer's available memory, all without having to upgrade ⏫ your hardware 🖥🚫🔧 or incur additional expenses. 🚫💰 Image generated by OpenAI's DALL·E 3 7 -
How much memory is available on your computer? Image generated
by OpenAI's DALL·E 3 8 -
Most personal devices are usually equipped with between 4GB and
64GB of RAM. 💻 Image generated by OpenAI's DALL·E 3 If you're fortunate enough to have a device with more RAM, I must say I'm a bit envious! 9 -
But what if you need to load and analyze data
that's several times larger than the RAM on the device you're using? 🤔💭📊📈💻🔍🤯 Image generated by OpenAI's DALL·E 3 10 -
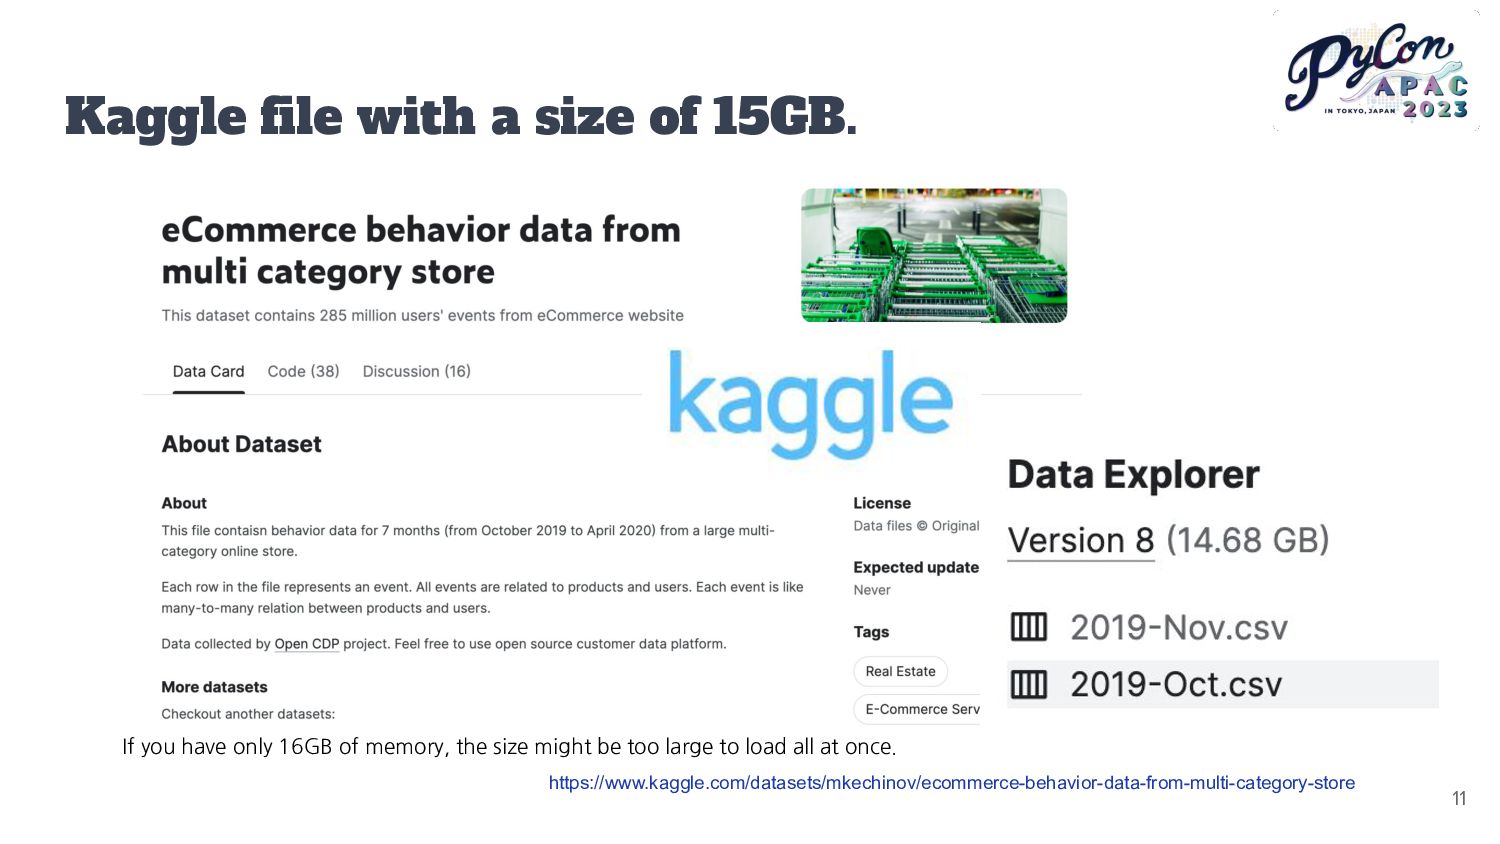
Kaggle file with a size of 15GB. https://www.kaggle.com/datasets/mkechinov/ecommerce-behavior-data-from-multi-category-store If you
have only 16GB of memory, the size might be too large to load all at once. 11 -
Attempting to load a large-size file all at once could
either fail to load or be extremely slow. ⚠🖥📁🐢💤 Image generated by OpenAI's DALL·E 3 12 -
Challenges in Handling Data with Pandas • By default, when
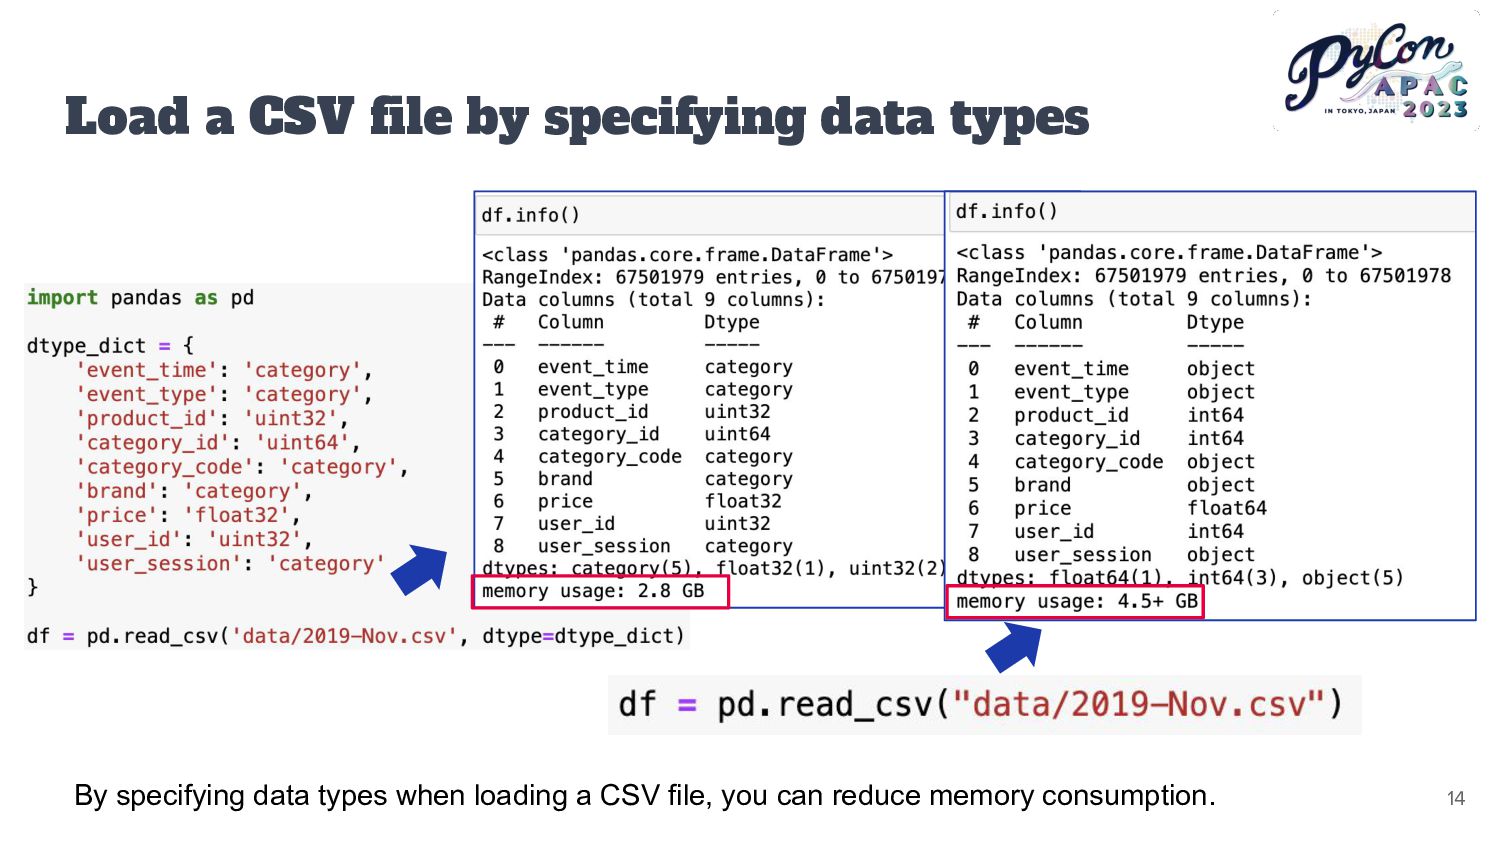
you load a CSV file in Pandas, integers are read as int64 and floats as float64. • If the size of the data is larger than the default specified size, it results in memory wastage. • Can struggle with analyzing datasets larger than the available memory • Even with datasets of adaptable size, memory usage tends to increase due to operations requiring the creation of intermediate copies 13 -
Load a CSV file by specifying data types By specifying
data types when loading a CSV file, you can reduce memory consumption. 14 -
• Load data in chunks, • Downcast, • Save as
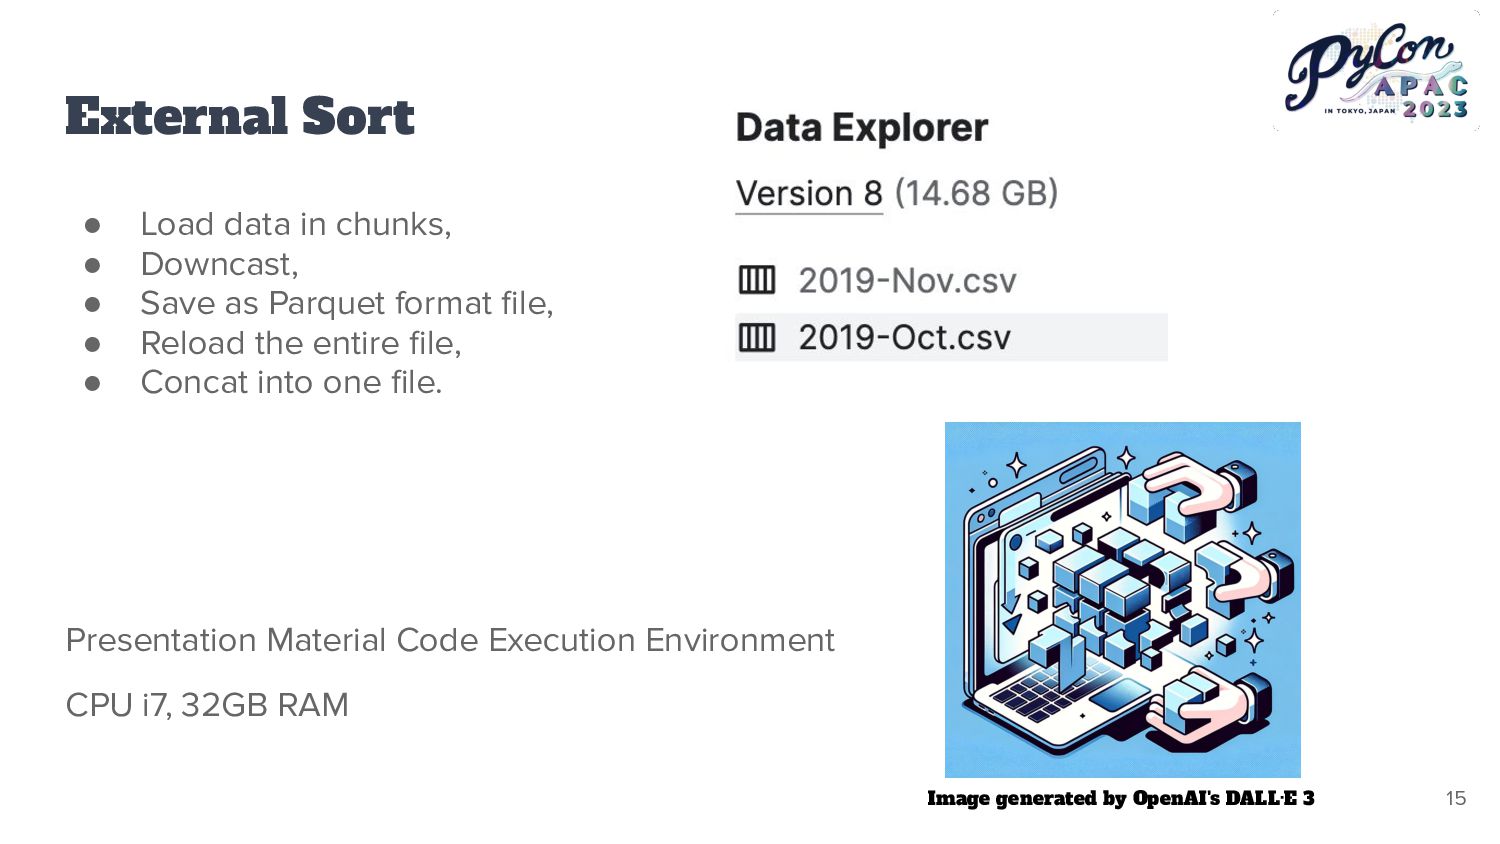
Parquet format file, • Reload the entire file, • Concat into one file. Presentation Material Code Execution Environment CPU i7, 32GB RAM External Sort Image generated by OpenAI's DALL·E 3 15 -
Loading large-sized files with limited memory capacity. Image generated by
OpenAI's DALL·E 3 16 -
If you're unable to load large data all at once,
how about fetching it in smaller parts? Image generated by OpenAI's DALL·E 3 17 -
Chunked Processing • 🧩 Process data in small, manageable chunks.
• 🔄 Handle data iteratively rather than loading it all at once into memory. • 📊 This method allows for dataset analysis without the need for full memory loading. • 🐼 Using the chunksize parameter in Pandas' read_csv() for this approach. Image generated by OpenAI's DALL·E 3 18 -
Using an Iterator • 🔄 Process the data in fixed-size
chunks sequentially using iterations. • 🧩 Each chunk is not loaded into memory and is only processed when needed, reducing memory strain. 19 -
Load permissible parts of the file into memory Remove unused
columns or rows Reduce memory usage through downcasting Save in Parquet format 20 -
Load permissible parts of the file into memory Remove unused
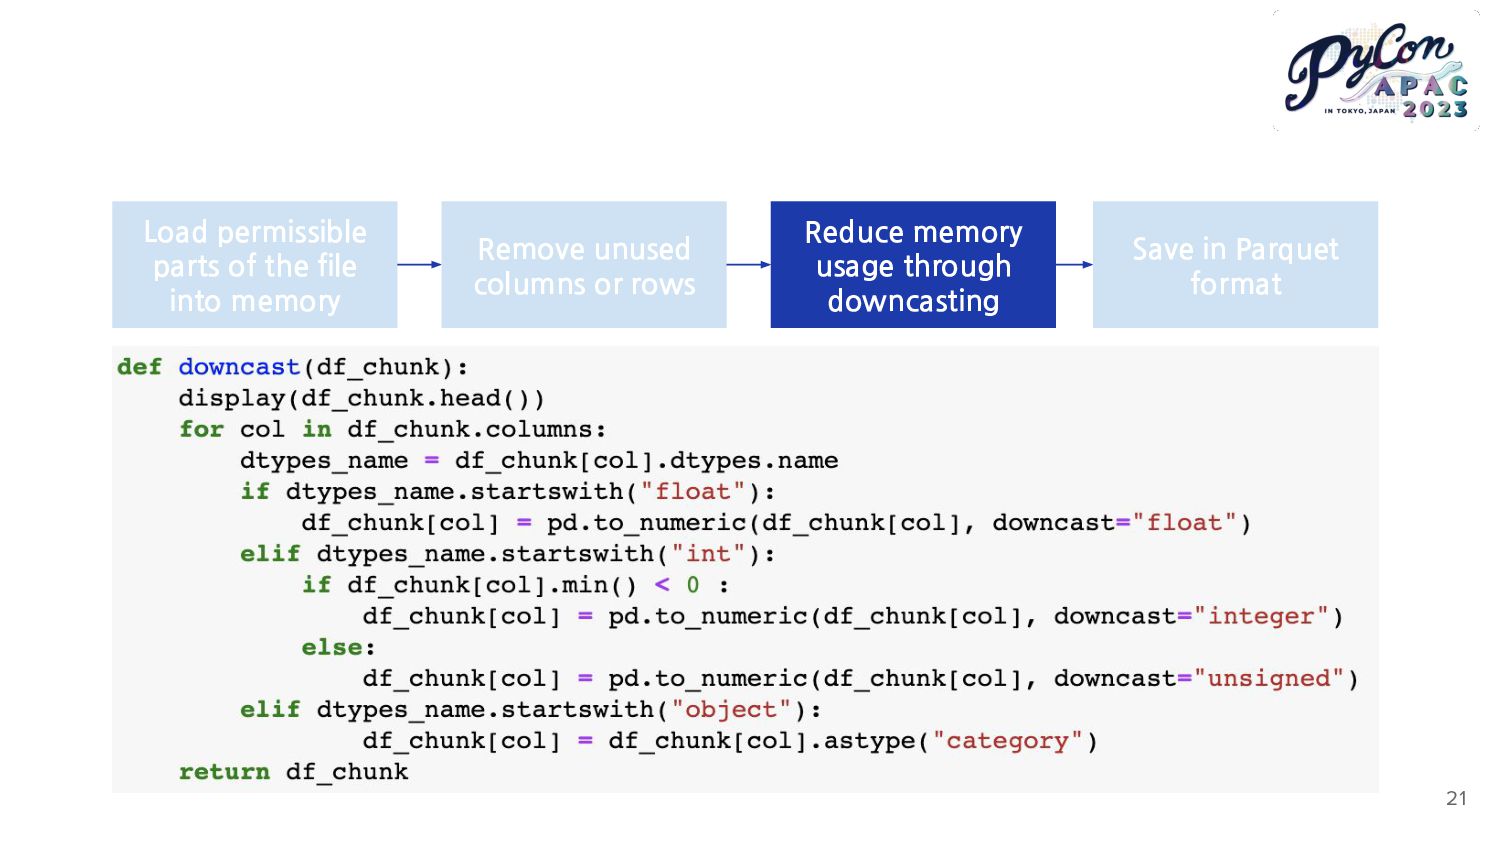
columns or rows Reduce memory usage through downcasting Save in Parquet format 21 -
How much can the size be reduced by applying downcasting
to the entire pandas DataFrame? Image generated by OpenAI's DALL·E 3 Changing the data type alone can be effective in reducing the storage and processing costs of data. For instance, converting data from the float64 type to float32 can cut memory usage in half. 22 -
https://pandas.pydata.org/docs/reference/api/pandas.to_numeric.html Load permissible parts of the file into memory Remove
unused columns or rows Reduce memory usage through downcasting Save in Parquet format For numerical types, you can use to_numeric for downcasting. 23 -
https://pandas.pydata.org/docs/user_guide/categorical.html Load permissible parts of the file into memory Remove
unused columns or rows Reduce memory usage through downcasting Save in Parquet format For string-type data, converting values with low cardinality to categorical values can reduce memory usage. 24 -
Reduce File Size https://pandas.pydata.org/docs/getting_started/intro_tutorials/02_read_write.html#min-tut-02-read-write Load permissible parts of the file
into memory Remove unused columns or rows Reduce memory usage through downcasting Save in Parquet format 25 -
🔄 After converting to Parquet and splitting it into smaller
chunks🗂, it occupies much less space 📉 than the original file. Image generated by OpenAI's DALL·E 3 26 -
Reducing Memory Usage and File Size Splitting the file into
smaller parts for faster loading. Load permissible parts of the file into memory Remove unused columns or rows Reduce memory usage through downcasting Save in Parquet format 27 -
Save after downcasting to Parquet format. File info : https://www.kaggle.com/datasets/mkechinov/ecommerce-behavior-data-from-multi-category-store
Two original files totaling 14.68GB (one more is a hidden system file). After conversion, approximately 111 files totaling 2.24GB (one more is a hidden system file). This is based on the assumption that even in Parquet format, it has been downcasted. 28 -
The choice of data storage and compression methods can significantly
impact performance, storage efficiency, and access speed. Image generated by OpenAI's DALL·E 3 29 -
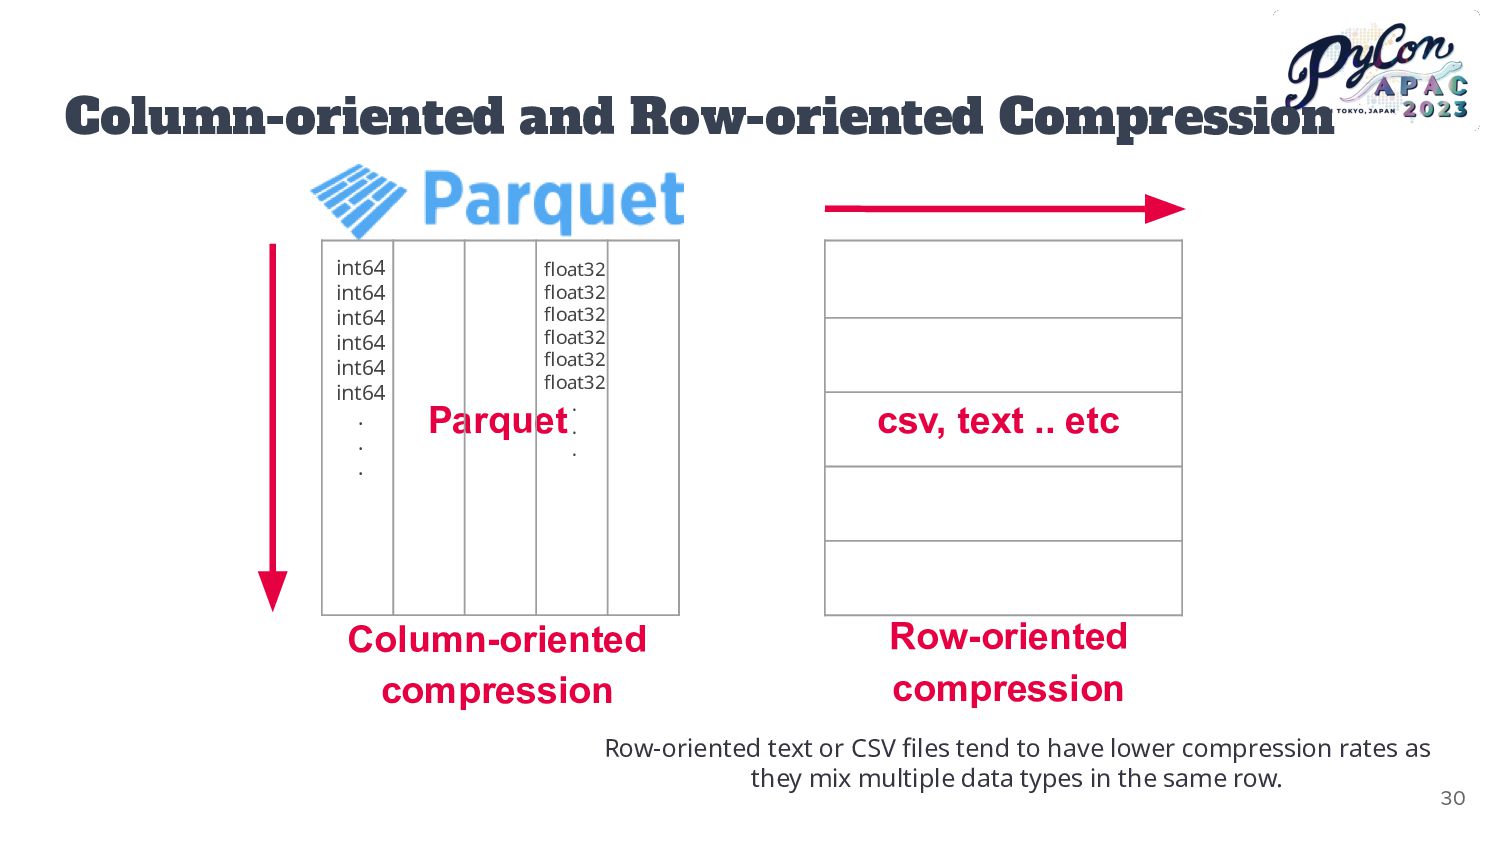
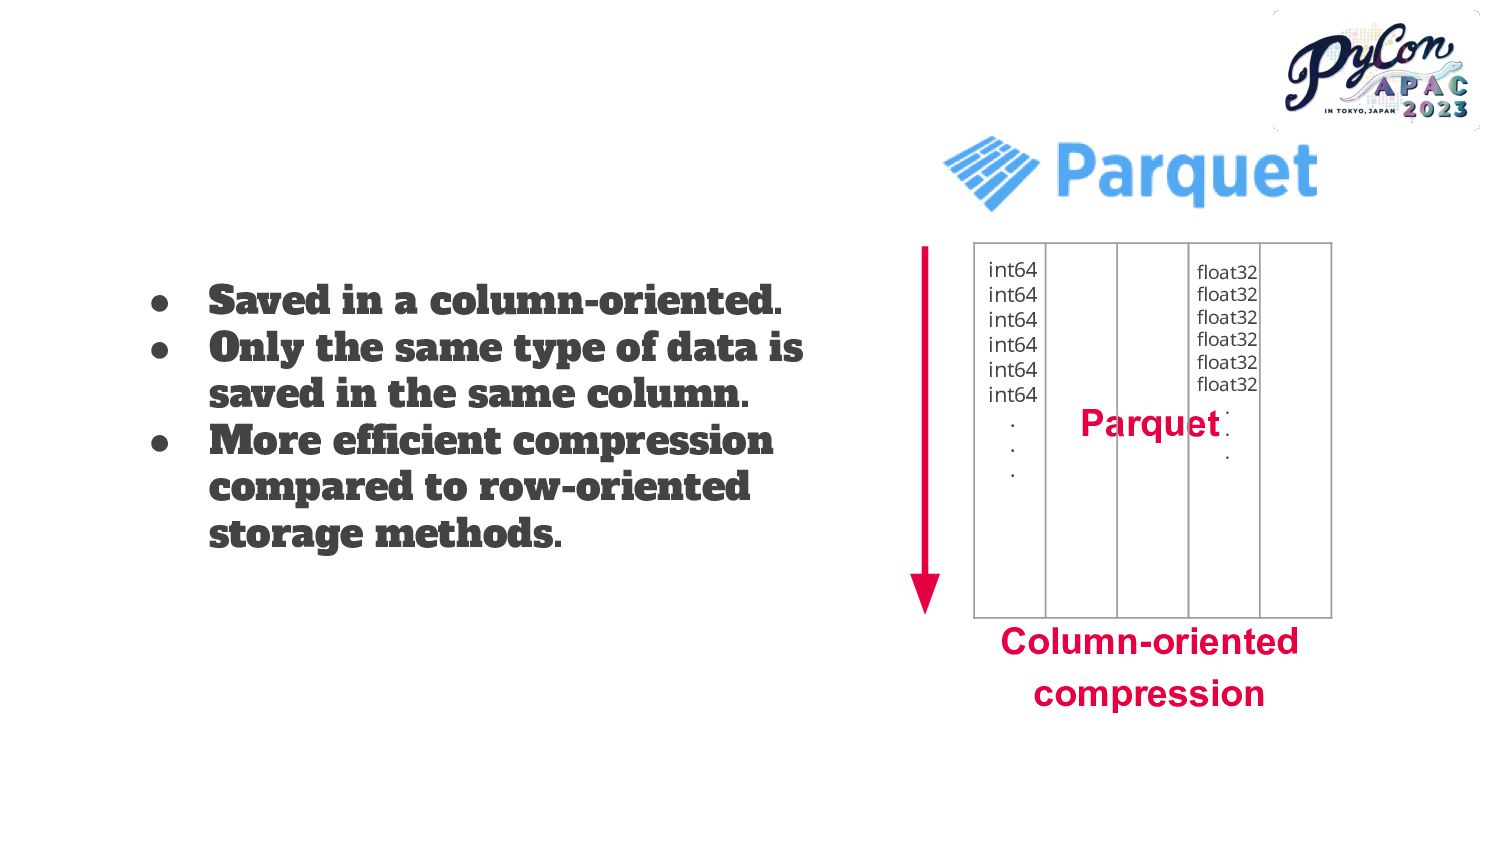
Column-oriented and Row-oriented Compression Column-oriented compression Row-oriented compression Row-oriented text
or CSV files tend to have lower compression rates as they mix multiple data types in the same row. int64, float64, object, bool int64 int64 int64 int64 int64 int64 . . . float32 float32 float32 float32 float32 float32 . . . Parquet csv, text .. etc int64 int64 int64 int64 int64 int64 . . . float32 float32 float32 float32 float32 float32 . . . 30 -
• CSV does not store schema or data type metadata
within the file. • Each time it's loaded, it defaults to a basic data type. • To load it as a specific type, you have to specify it every time, which can be tedious. When using CSV or TXT files. Image generated by OpenAI's DALL·E 3 31 -
• Saved in a column-oriented. • Only the same type
of data is saved in the same column. • More efficient compression compared to row-oriented storage methods. Column-oriented compression int64 int64 int64 int64 int64 int64 . . . float32 float32 float32 float32 float32 float32 . . . Parquet int64 int64 int64 int64 int64 int64 . . . float32 float32 float32 float32 float32 float32 . . . 32 -
Parquet Schema Parquet includes a schema. The schema defines the
structure of the data, allowing for the specification of data types, hierarchy, and other metadata information. 33 -
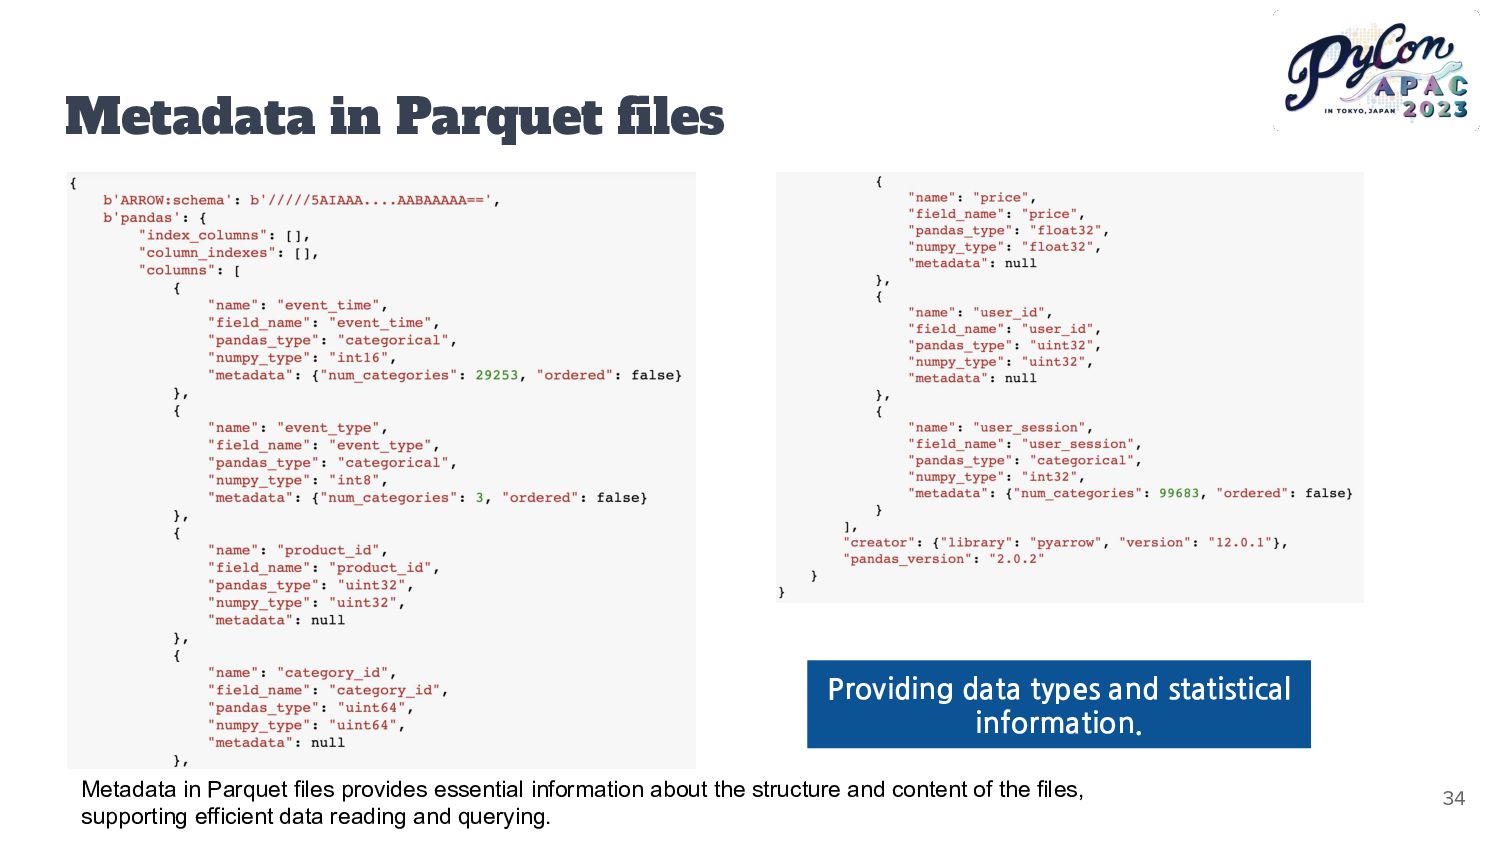
Metadata in Parquet files Providing data types and statistical information.
Metadata in Parquet files provides essential information about the structure and content of the files, supporting efficient data reading and querying. 34 -
Metadata in Parquet files • The version of the Parquet
format. • Schema information of the data. • The total number of rows stored in the file. • Metadata for each column. • Data types and encoding methods. • The compression methods used. • Basic statistical information for each column, like maximum value, minimum value, and count. 35 -
By using these statistical pieces of metadata, the range of
data scanning can be reduced. Image generated by OpenAI's DALL·E 3 36 -
Alright, let's concat the smaller Parquet files into one single
Parquet file. Image generated by OpenAI's DALL·E 3 37 -
It takes about 1 minute to load a single CSV
file with 40 million rows. Imagine the time if there are multiple such files? Image generated by OpenAI's DALL·E 3 38 -
Load the reduced-size file. However, by splitting the three times
larger file into about 100 separate parquet files, they can be loaded in just 30 seconds. Load Parquet format file concat() Remove unused columns or rows To analyze 39 -
1) Load Parquet files and concat into a single dataset
with approximately 100 million rows. 40 -
2) Save the concatenated data to a single file. If
saved as a file, we can use it again later or even share it with colleagues for their use. 41 -
Concatenated dataframe. While the concatenated file size is about 2.24GB,
the actual memory usage when loaded is 5.4GB. 43 -
Do we need all the data? Image generated by OpenAI's
DALL·E 3 Just as we've implemented strategies to optimize memory by eliminating unnecessary usage, we might not require all the data when managing datasets. 44 -
• Check whether all columns and rows are needed. •
Remove any unnecessary columns or rows, • and sample only the data that is required. Process only the necessary data into subsets. Image generated by OpenAI's DALL·E 3 45 -
Data sampling • Reduce to a smaller dataset size. •
Analyze while avoiding memory constraints. • Sampling uses randomly selected data.🎲 ◦ df.sample(n), df.sample(frac=0.1) • Determine sampling criteria based on domain knowledge. ◦ Examples: ▪ Specific product category 🛍 ▪ specific time period ⏰ ▪ specific customer group 👥 ▪ age group 👶🧓 ▪ gender, etc. Image generated by OpenAI's DALL·E 346 -
Using Technical Solutions and Incorporating Real-World Problem Solving Methods Image
generated by OpenAI's DALL·E 3 47 -
For instance, if you only need specific products from the
sales records? Image generated by OpenAI's DALL·E 3 48 -
If you only need user and datetime information to calculate
retention? Image generated by OpenAI's DALL·E 3 49 -
• Create subsets. 📂 • Save those subsets to files.
💾 • Repeatedly concat the subsets. 🔀 • With limited memory, handle large data by processing and then deleting. 🔄🗑 Searching through the entire data set can be time-consuming. 50 -
Concat into a single dataframe. Load Parquet format file concat()
Remove unused columns or rows To analyze 51 -
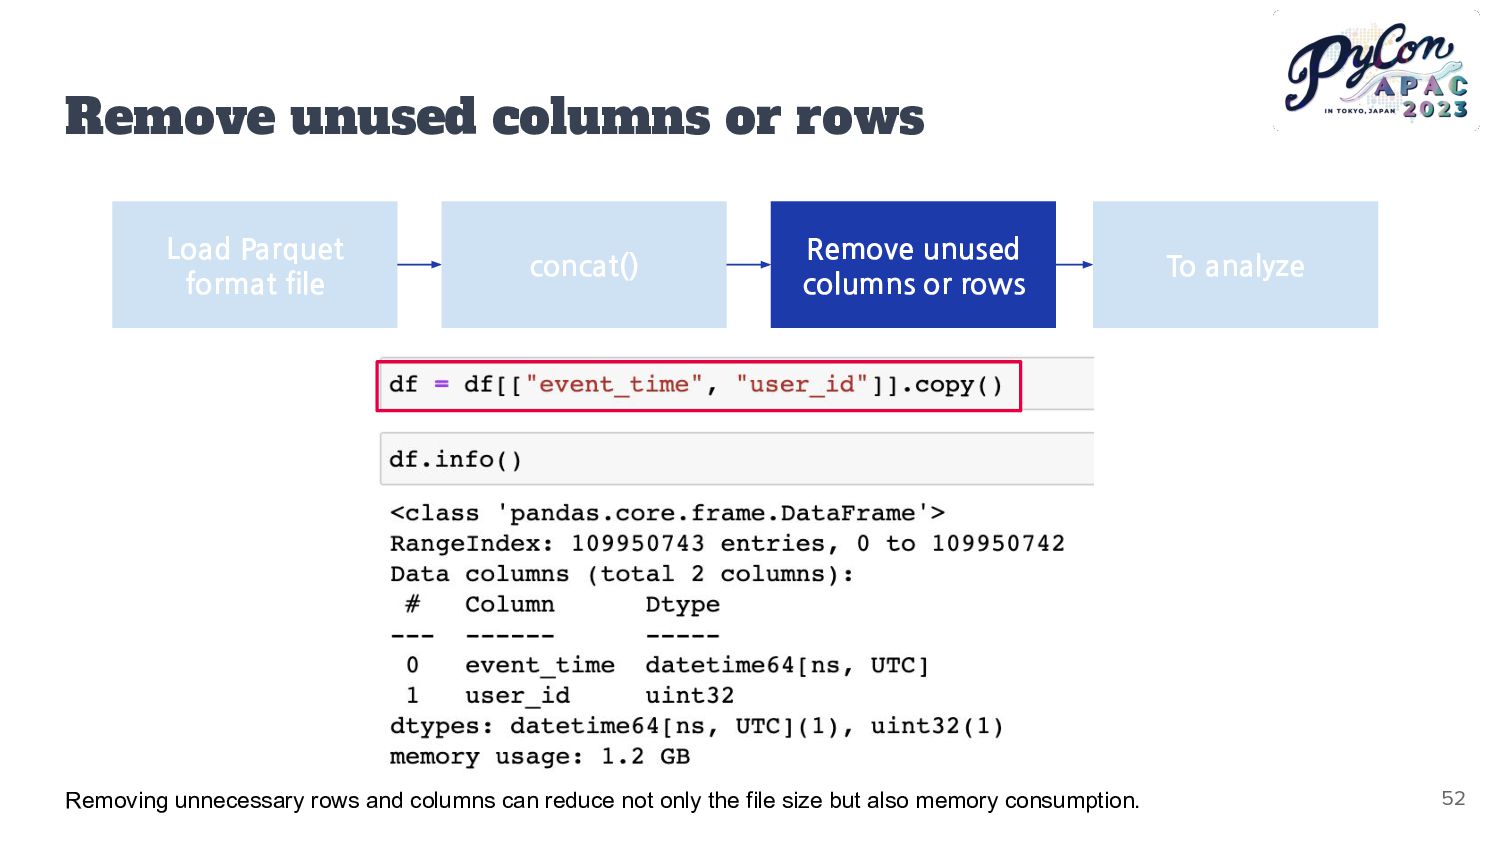
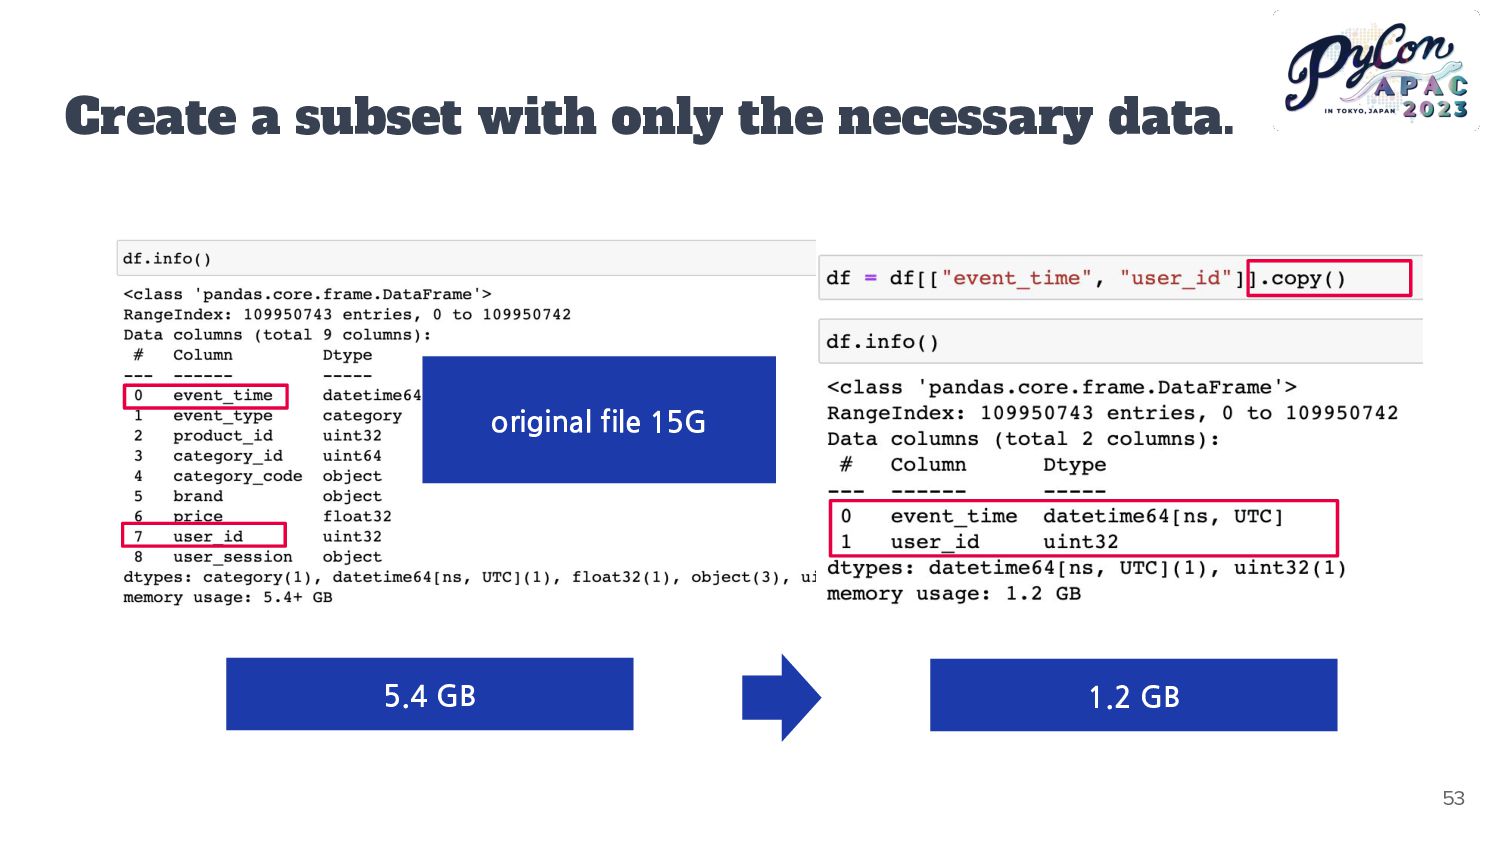
Remove unused columns or rows Removing unnecessary rows and columns
can reduce not only the file size but also memory consumption. Load Parquet format file concat() Remove unused columns or rows To analyze 52 -
Create a subset with only the necessary data. original file
15G 5.4 GB 1.2 GB 53 -
After preprocessing, computation When performing string slicing operations on a
dataframe with over 100 million data points, it takes close to 7 minutes. And when calculating retention using groupby() on a daily basis, it takes over a minute. Of course, the computation is still slow, but without preprocessing, it would have either not finished or resulted in a memory error. 54 -
Calculate weekly retention from 100 million rows. It took about
7 seconds to create a simple date-formatted derived variable from 100 million rows, and around 47 seconds were required for the groupby aggregation operation. 55 -
Visualizing weekly retention for 100 million rows. Load Parquet format
file concat() Remove unused columns or rows To analyze 56 -
Reducing Memory Usage Suggestions 1. Sampling (Reducing the number of
rows) 2. Specific Column Indexing and Selective Loading (Reducing the number of columns) 3. Chunking and Iteration 4. Changing Data Types 5. Compressing Data Using Parquet Format 6. Parallel Processing 7. Distributed Processing Frameworks such as Dask, Vaex, PySpark, etc. 57