& performance :) • Have fun with distributed systems • Slow runner • Spanish who DON’T like siesta Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 3 / 29
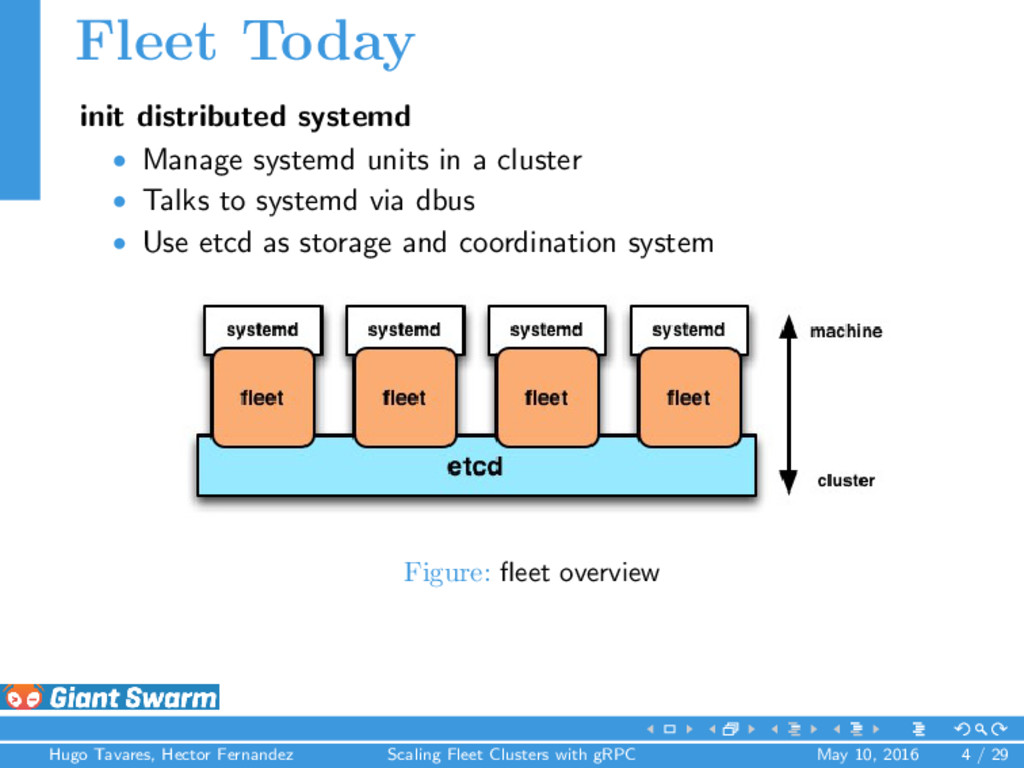
a cluster • Talks to systemd via dbus • Use etcd as storage and coordination system Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 4 / 29
a cluster • Talks to systemd via dbus • Use etcd as storage and coordination system Figure: fleet overview Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 4 / 29
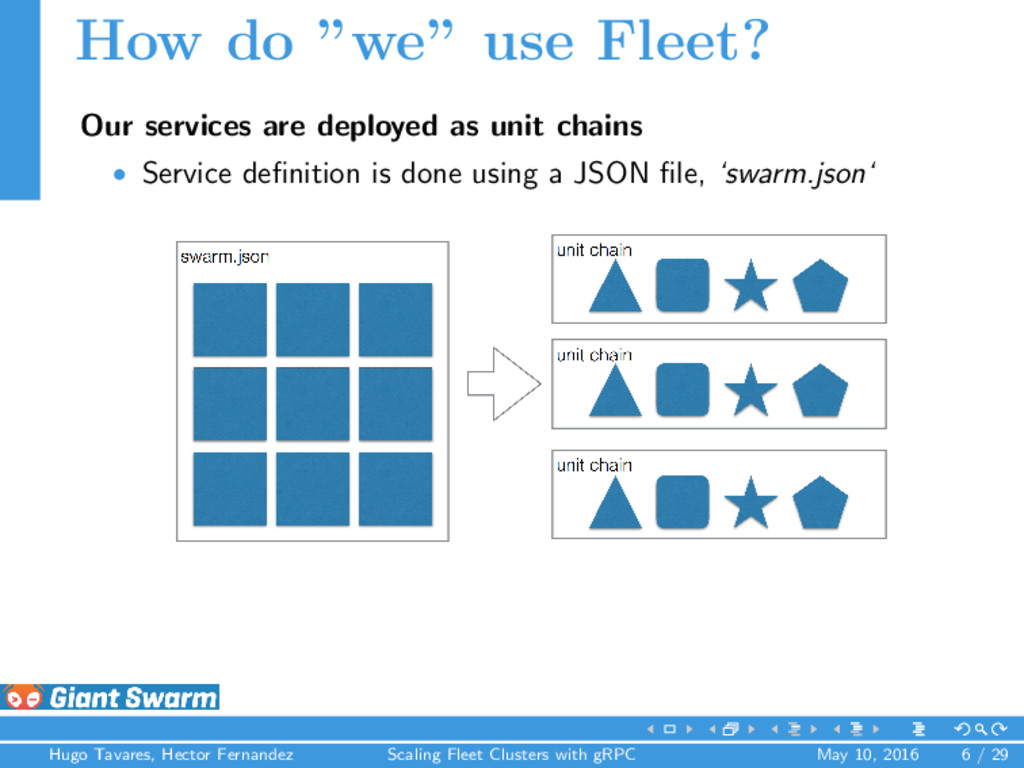
unit chains • Service definition is done using a JSON file, ‘swarm.json‘ Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 6 / 29
actions over units taking forever • etcdctl set command can take 40ms or 1100ms • Fleet out of sync • unresponsive agents • incoherent fleet ‘list-units‘ • Limited scalability • Excessive etcd dependencies: persistent and transient storage • ”If etcd is sad. fleet is sad. We are sad.” • Fail recovery • If etcd goes down, everything falls apart Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 8 / 29
system of our infrastructure What do we love ? • Robustness • Intuitive app definition • Distributed systemd Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 10 / 29
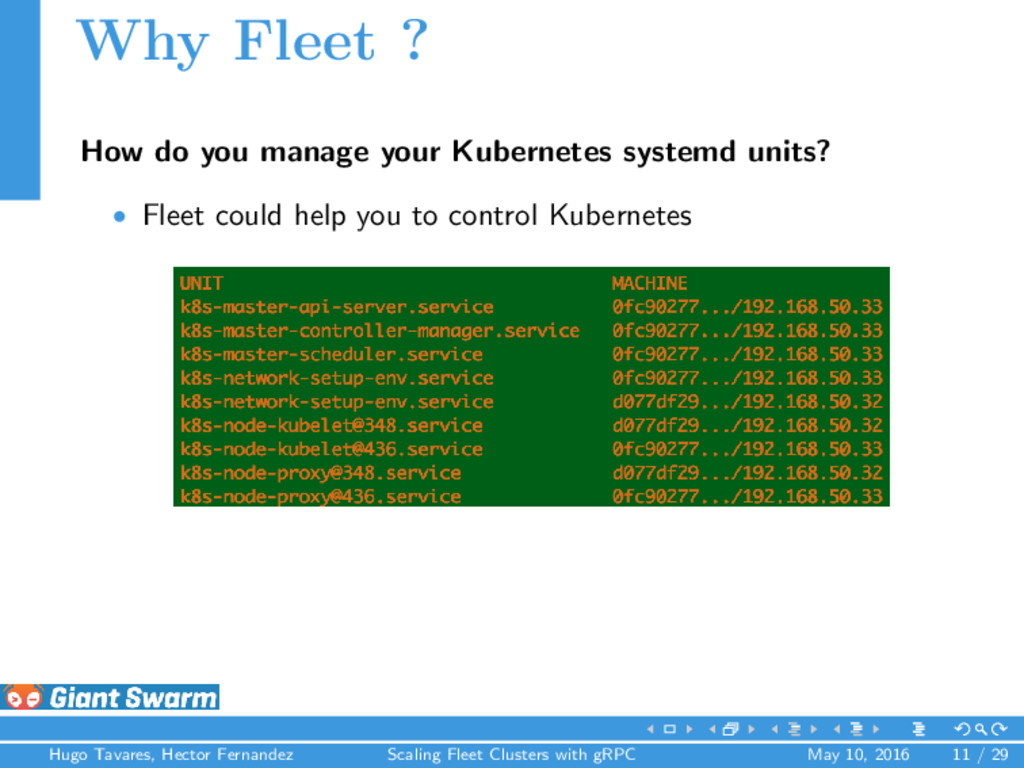
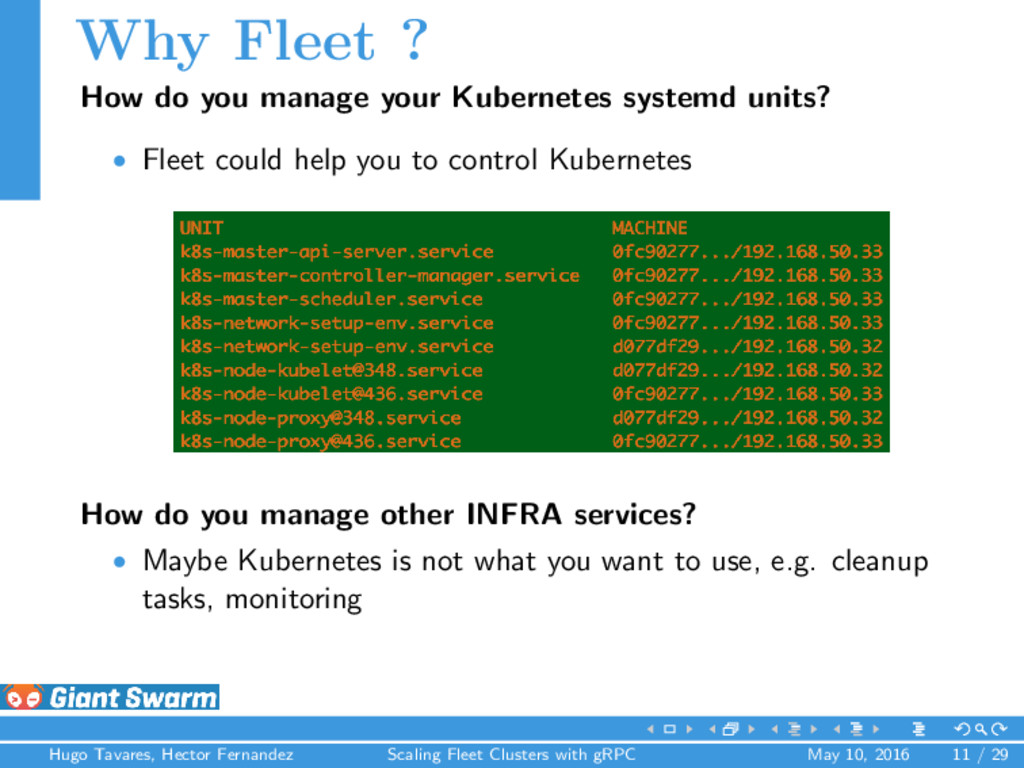
units? • Fleet could help you to control Kubernetes How do you manage other INFRA services? • Maybe Kubernetes is not what you want to use, e.g. cleanup tasks, monitoring Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 11 / 29
the etcd dependencies • Obtain better throughput (units/sec and amount of units) • Improve fail recovery mechanisms • Mitigate the scalability problems Maybe we can use gRPC instead of etcd ! Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 13 / 29
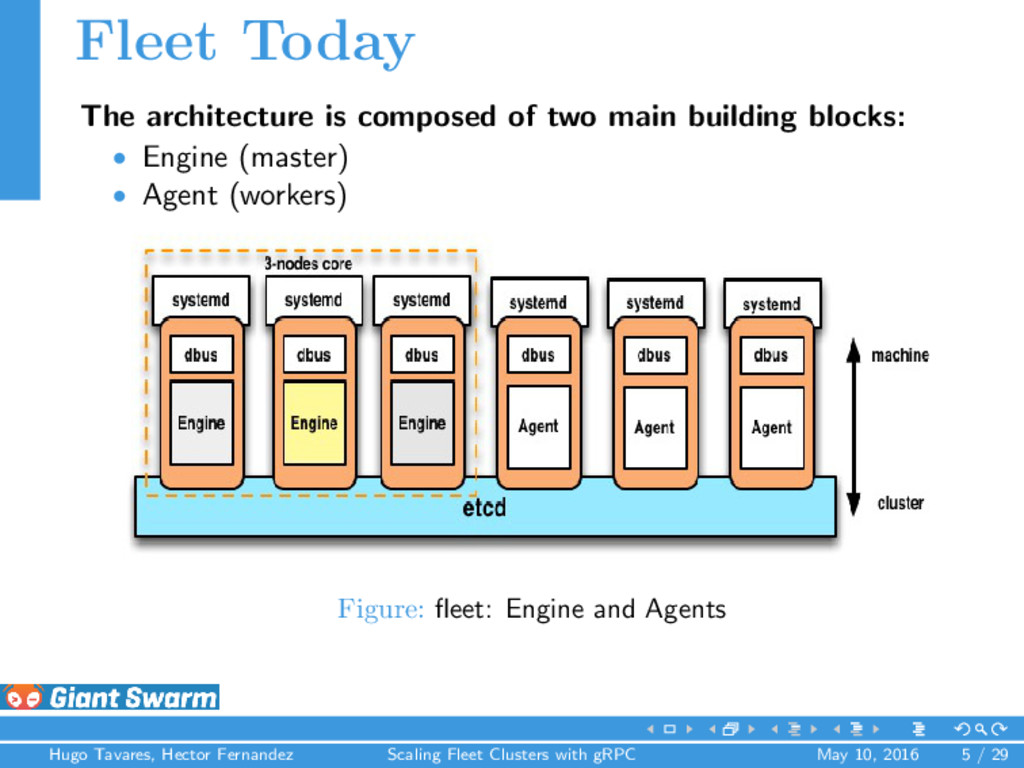
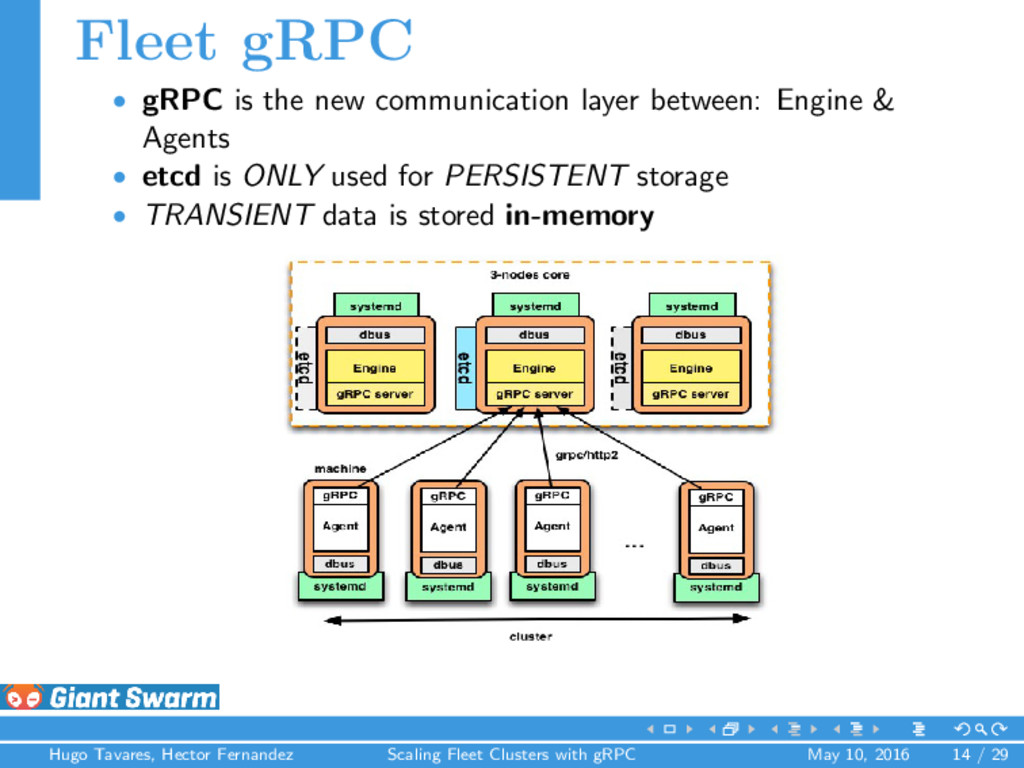
Engine & Agents • etcd is ONLY used for PERSISTENT storage • TRANSIENT data is stored in-memory Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 14 / 29
Engine & Agents • etcd is ONLY used for PERSISTENT storage • TRANSIENT data is stored in-memory Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 14 / 29
to network hiccups • Fallback mechanism (e.g. firewall) • Agent healtchecks • If etcd goes DOWN, we are still operative (on-going) Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 15 / 29
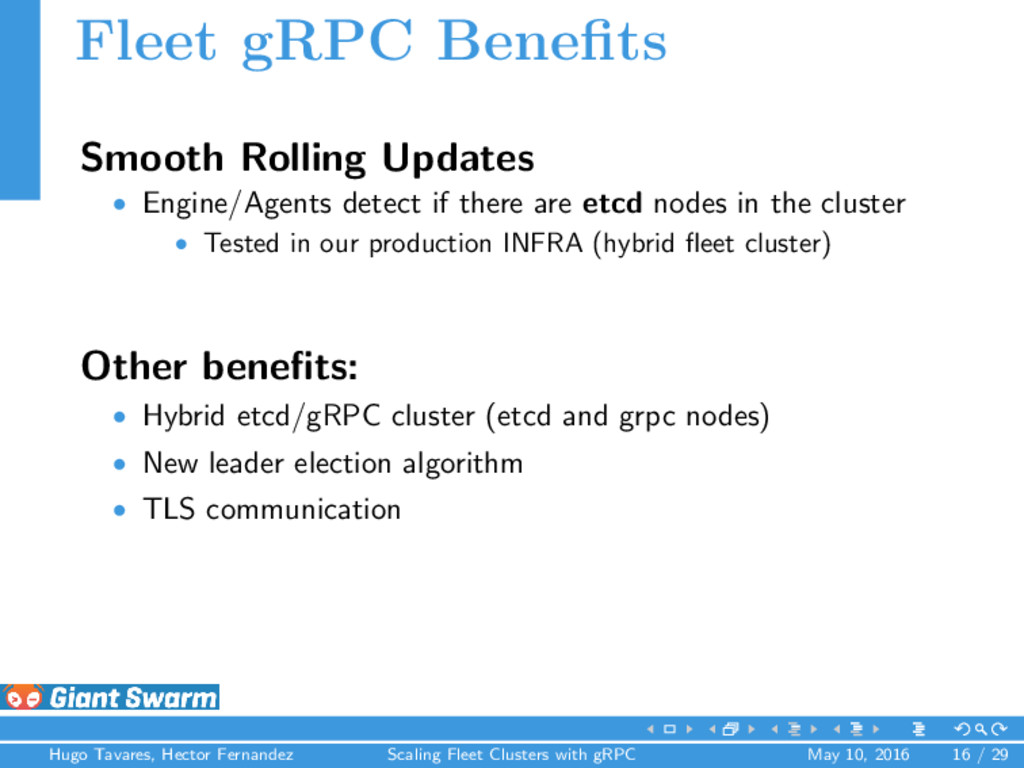
there are etcd nodes in the cluster • Tested in our production INFRA (hybrid fleet cluster) Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 16 / 29
there are etcd nodes in the cluster • Tested in our production INFRA (hybrid fleet cluster) Other benefits: • Hybrid etcd/gRPC cluster (etcd and grpc nodes) • New leader election algorithm • TLS communication Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 16 / 29
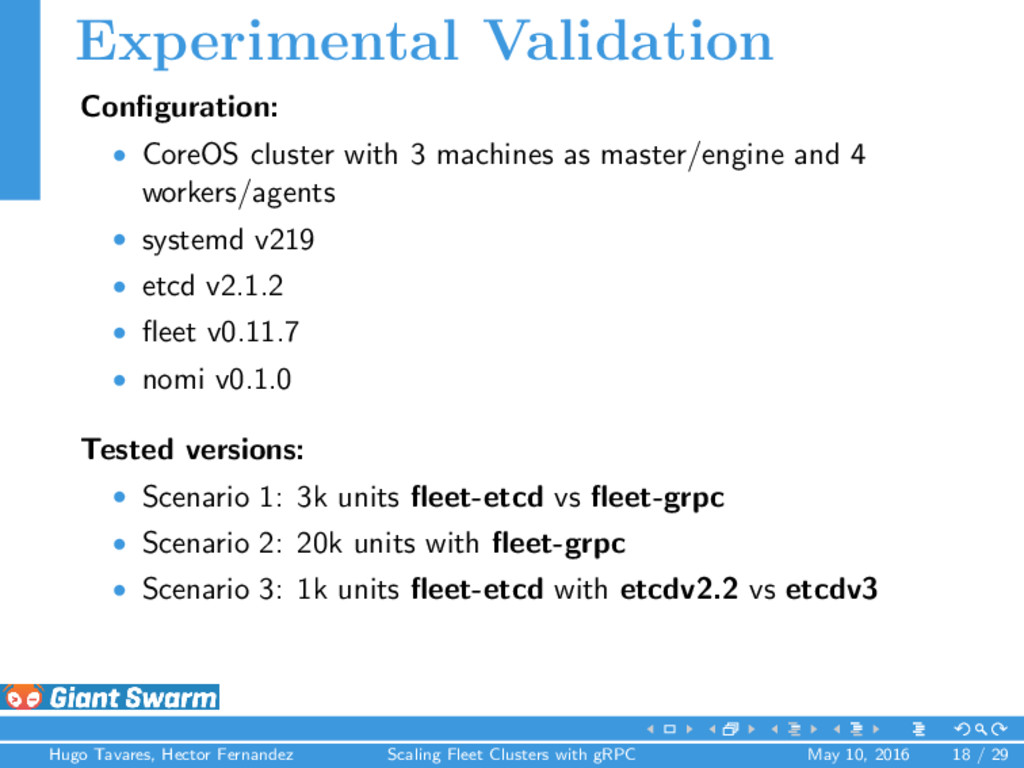
master/engine and 4 workers/agents • systemd v219 • etcd v2.1.2 • fleet v0.11.7 • nomi v0.1.0 Tested versions: • Scenario 1: 3k units fleet-etcd vs fleet-grpc • Scenario 2: 20k units with fleet-grpc • Scenario 3: 1k units fleet-etcd with etcdv2.2 vs etcdv3 Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 18 / 29
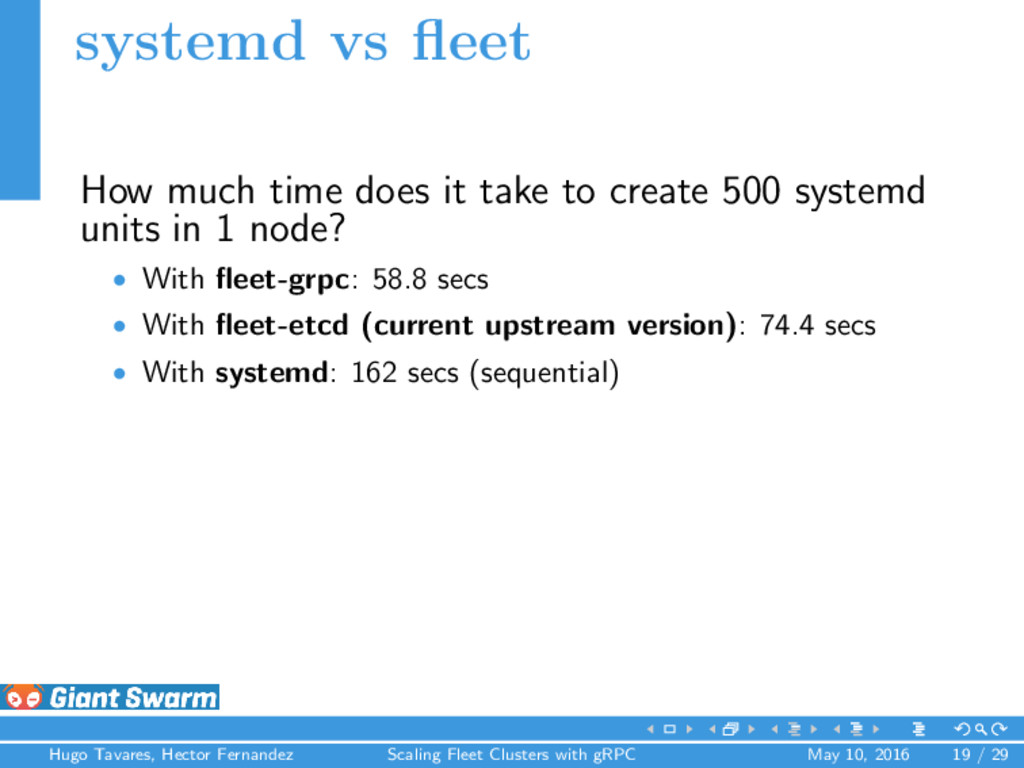
create 500 systemd units in 1 node? Why ? • ‘systemd linking‘ operation is very EXPENSIVE Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 19 / 29
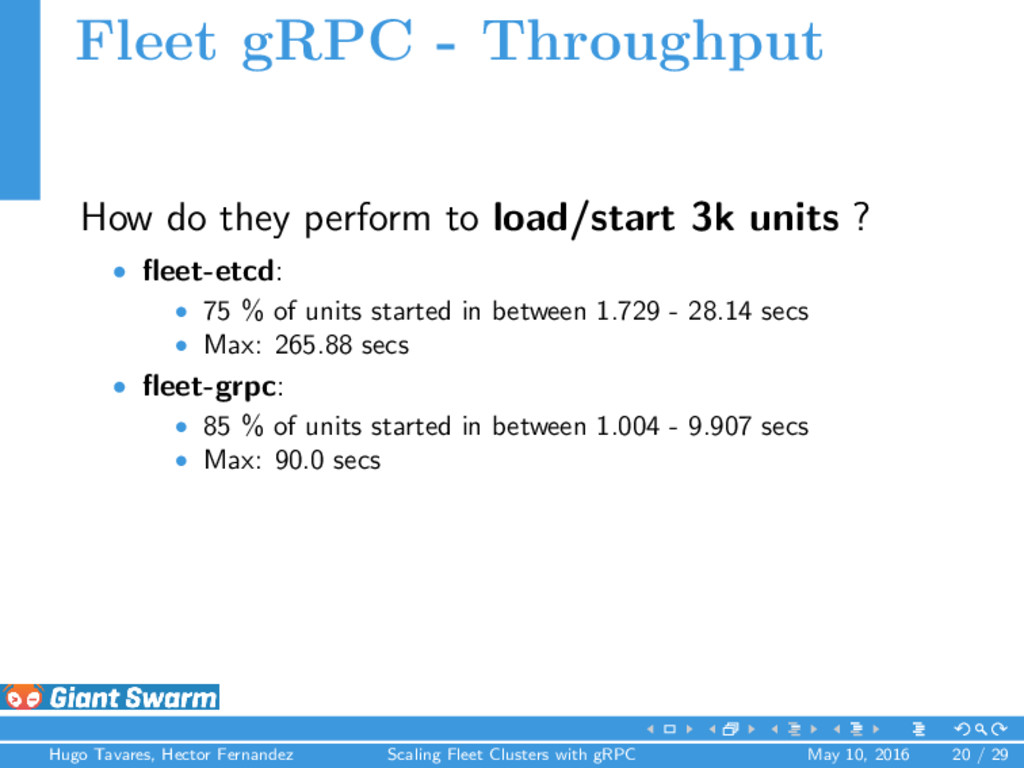
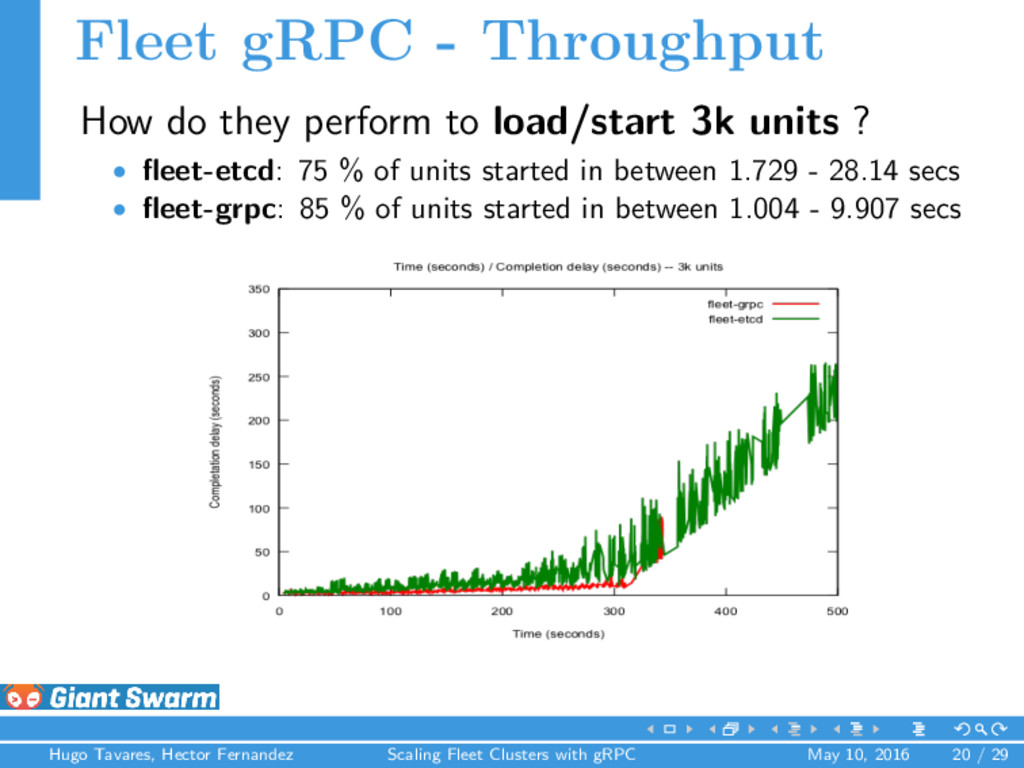
3k units ? • fleet-etcd: • 75 % of units started in between 1.729 - 28.14 secs • Max: 265.88 secs • fleet-grpc: • 85 % of units started in between 1.004 - 9.907 secs • Max: 90.0 secs Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 20 / 29
3k units ? • fleet-etcd: 75 % of units started in between 1.729 - 28.14 secs • fleet-grpc: 85 % of units started in between 1.004 - 9.907 secs Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 20 / 29
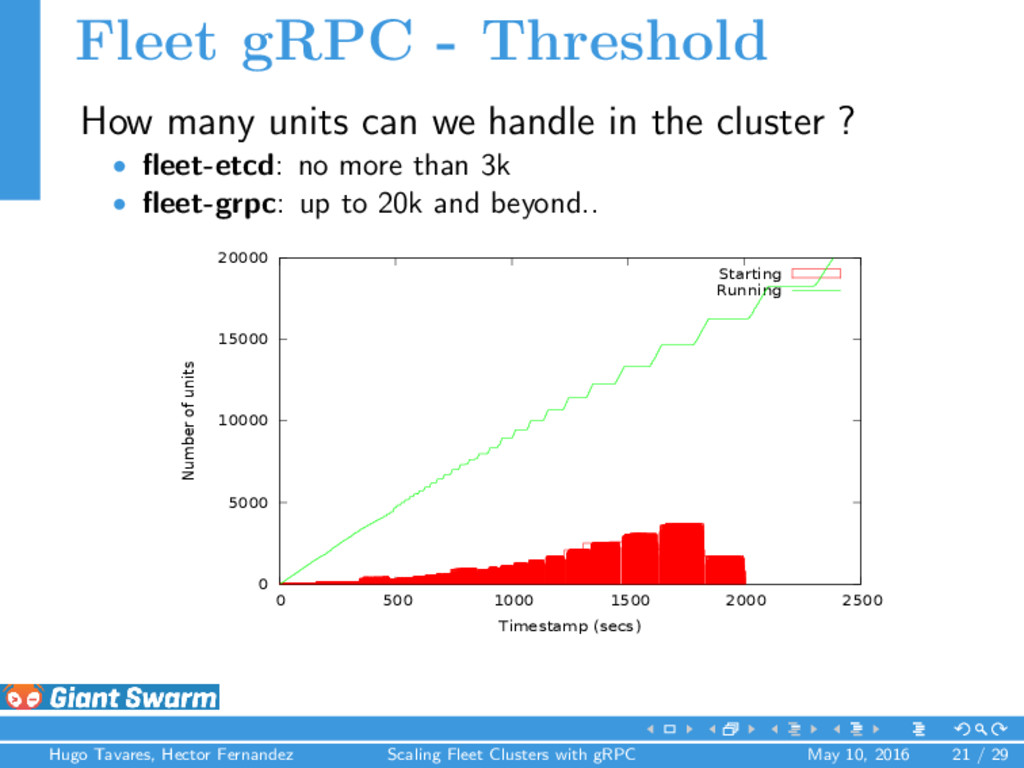
in the cluster ? • fleet-etcd: no more than 3k • fleet-grpc: up to 20k and beyond.. Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 21 / 29
in the cluster ? • fleet-etcd: no more than 3k • fleet-grpc: up to 20k and beyond.. 0 5000 10000 15000 20000 0 500 1000 1500 2000 2500 Number of units Timestamp (secs) Starting Running Figure: fleet-grpc 20k Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 21 / 29
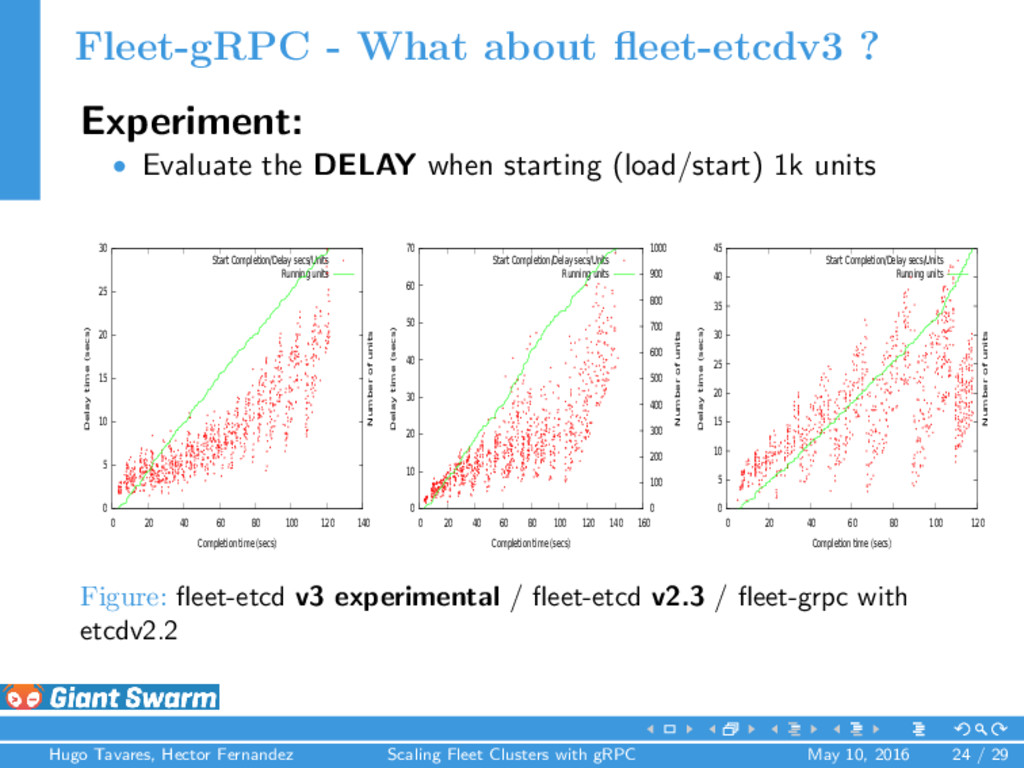
DELAY when starting (load/start) 1k units 0 5 10 15 20 25 30 0 20 40 60 80 100 120 140 Delay time (secs) Number of units Completion time (secs) Start Completion/Delay secs/Units Running units 0 10 20 30 40 50 60 70 0 20 40 60 80 100 120 140 160 0 100 200 300 400 500 600 700 800 900 1000 Delay time (secs) Number of units Completion time (secs) Start Completion/Delay secs/Units Running units 0 5 10 15 20 25 30 35 40 45 0 20 40 60 80 100 120 Delay time (secs) Number of units Completion time (secs) Start Completion/Delay secs/Units Running units Figure: fleet-etcd v3 experimental / fleet-etcd v2.3 / fleet-grpc with etcdv2.2 We used the experimental etcdv3 of few months ago Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 24 / 29
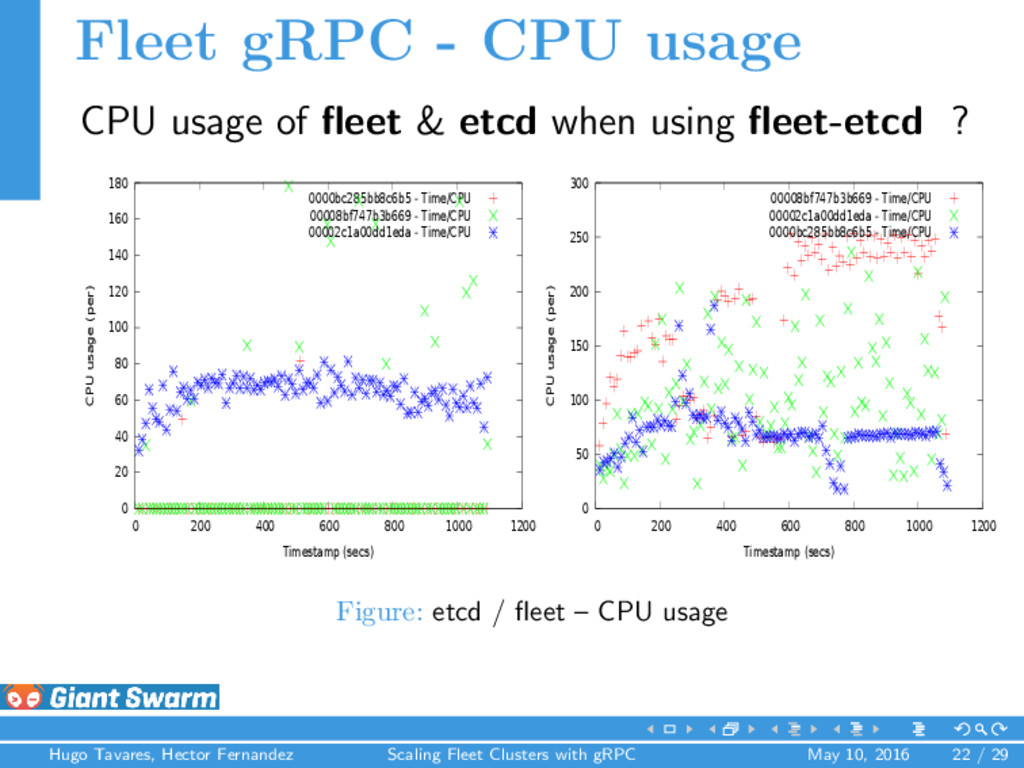
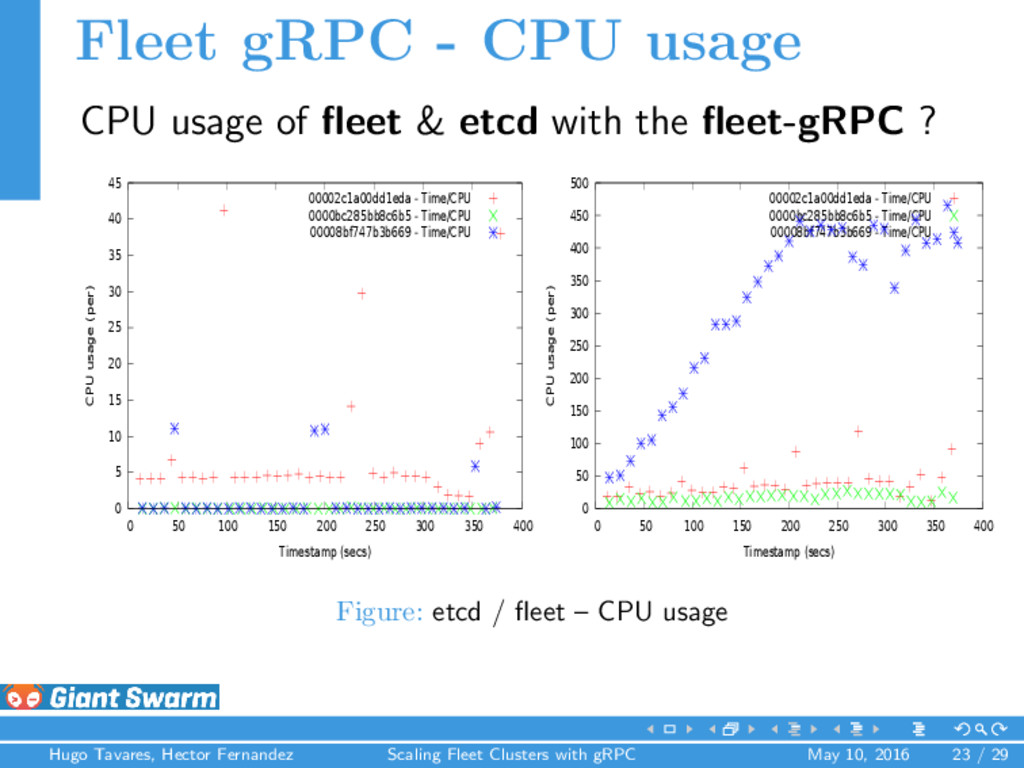
etcd friction • Lower CPU usage in the fleet agents • Secure communication • Improved scalability • No need of frequent cleanup tasks Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 25 / 29
TLS to secure the communication • Improve the unit states transmission between agents-engine, (send what it has changed) • Change the reconciliation loop mechanism • Look at the usage of systemd –user to gain in performance • systemd linking is a quite expensive operation. Hugo Tavares, Hector Fernandez Scaling Fleet Clusters with gRPC May 10, 2016 26 / 29


 ryu1013
 minodriven
 akit37
 koic
 o0h
 prota
 uyuki234
 siroemk
 artoy
 oniak3ibm
 ichirokano2
 kawashimo0
 eileencodes
 katarinadahlin
 bkeepers
 tammyeverts
 thirion
 cassininazir
 danielanewman
 raygrieselhuber
 andyhume
 productmarketing
 destraynor
 sarafernandez