Share
Embed
Reformer Text-to-Speech
Slides for a presentation of the semester project for deep neural networks course at MIM UW (2019-20).
Presentation: https://youtu.be/ckeKsM6obnM
GitHub: https://github.com/kowaalczyk/reformer-tts
Mateusz Olko: https://www.linkedin.com/in/mateusz-olko/
Tomasz Miśków: https://www.linkedin.com/in/tmiskow/
Krzysztof Kowalczyk: https://www.linkedin.com/in/kowaalczyk/
kowaalczyk
June 22, 2020
Transcript
30 slides
-
Reformer Text-To-Speech MATEUSZ OLKO / mo382777 TOMASZ MIŚKÓW / tm385898
KRZYSZTOF KOWALCZYK / kk385830 -
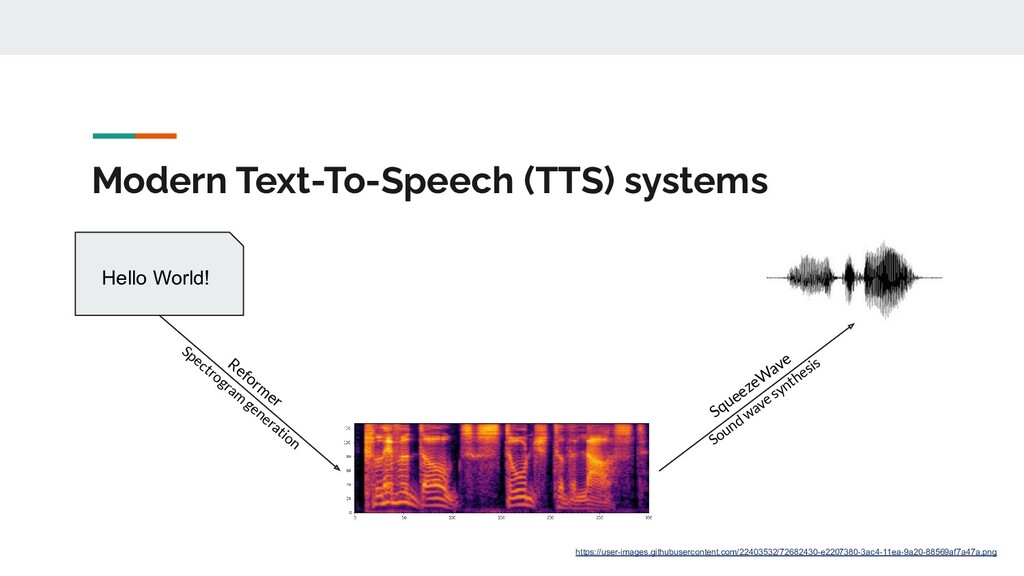
Modern Text-To-Speech (TTS) systems Hello World! Spectrogram generation Sound wave
synthesis Reform er SqueezeW ave https://user-images.githubusercontent.com/22403532/72682430-e2207380-3ac4-11ea-9a20-88569af7a47a.png -
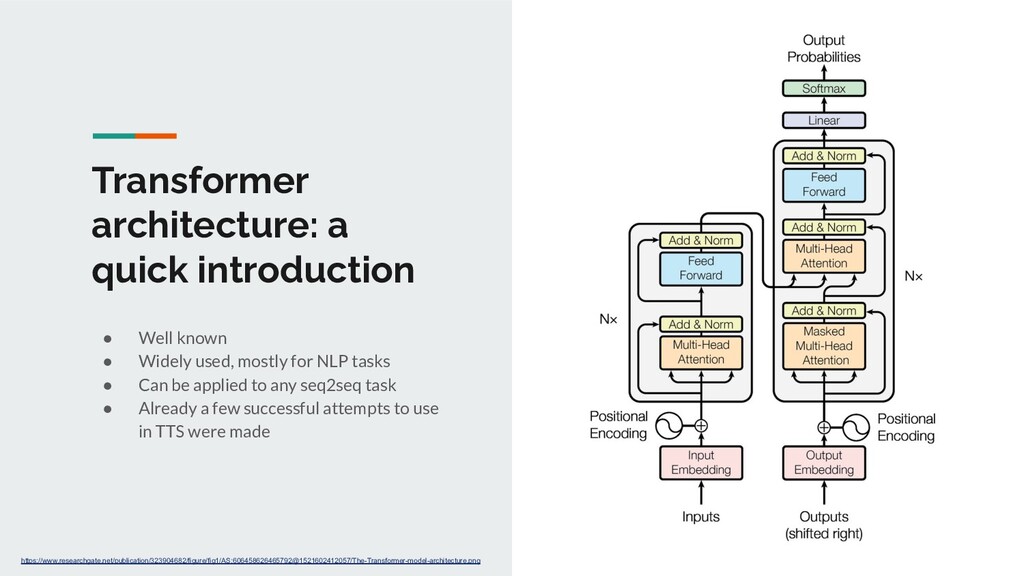
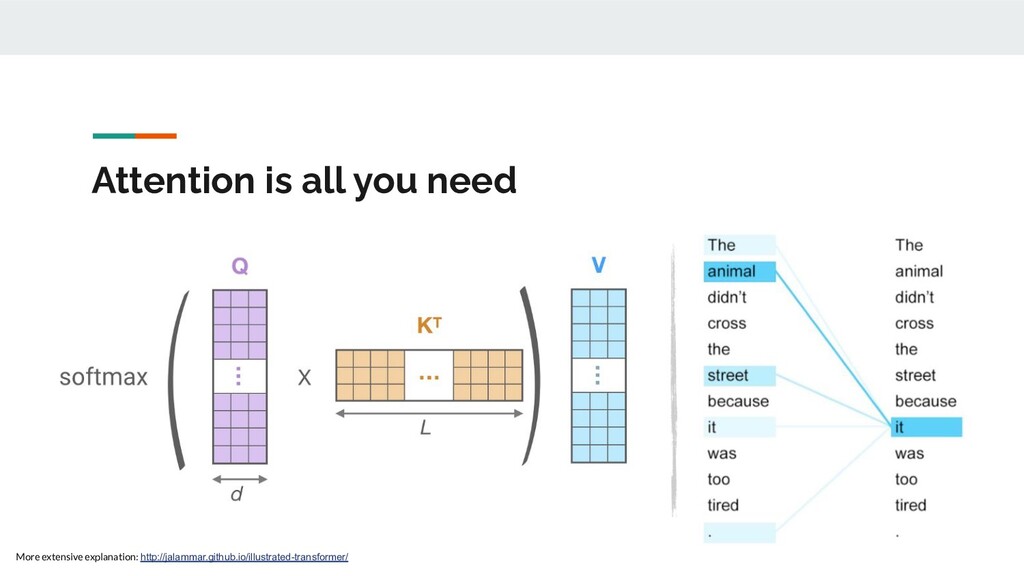
Transformer architecture: a quick introduction • Well known • Widely
used, mostly for NLP tasks • Can be applied to any seq2seq task • Already a few successful attempts to use in TTS were made https://www.researchgate.net/publication/323904682/figure/fig1/AS:606458626465792@1521602412057/The-Transformer-model-architecture.png -
Reformer - a new solution for memory issues Transformer requires
a lot of memory - especially for long sequences (attention matrice size is sequence length squared) To address this problem authors of Reformer architecture use, amongst other tricks, two main components: • Local-Sensitive-Hashing Attention • Reversible layers -
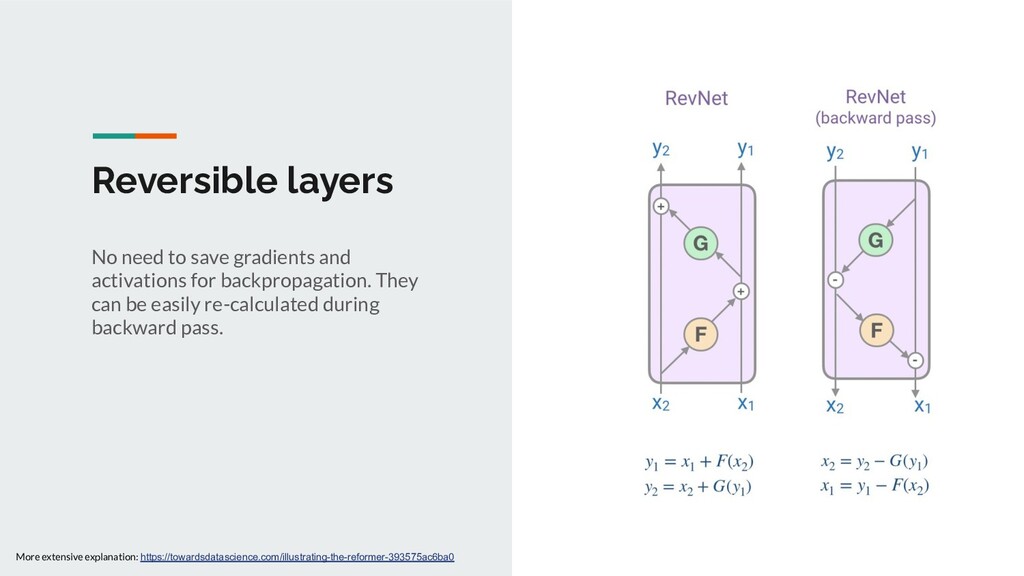
Reversible layers No need to save gradients and activations for
backpropagation. They can be easily re-calculated during backward pass. More extensive explanation: https://towardsdatascience.com/illustrating-the-reformer-393575ac6ba0 -
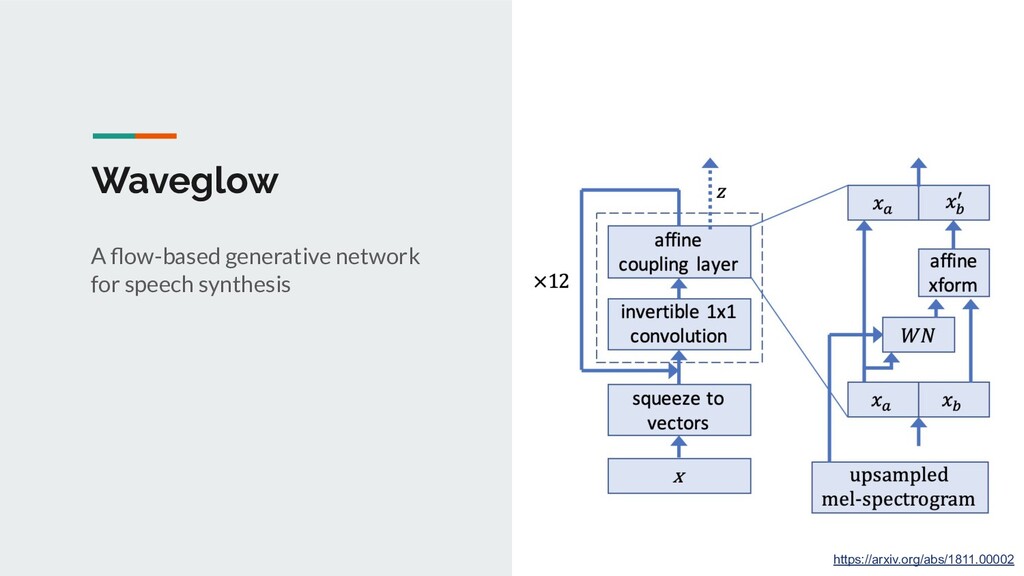
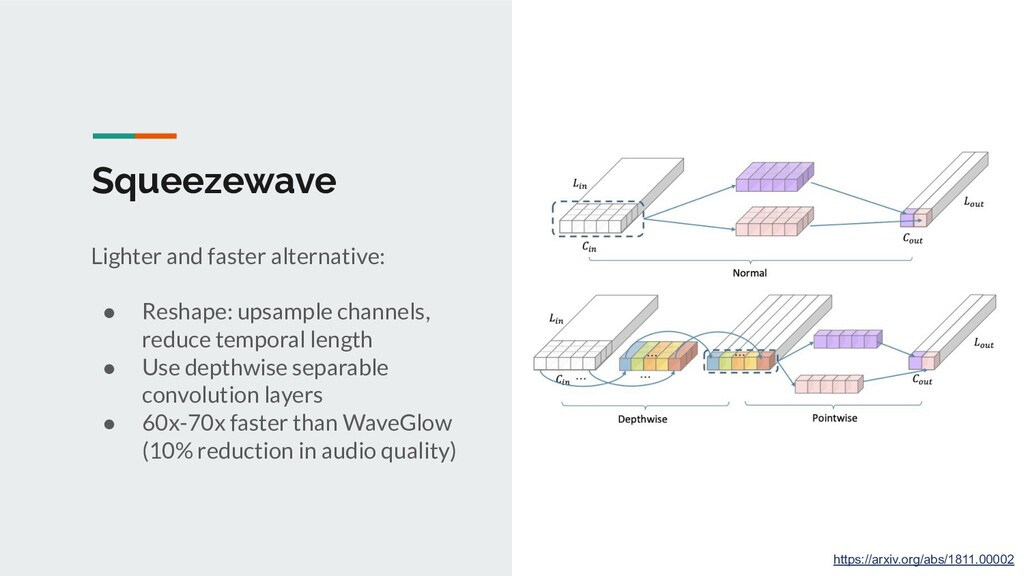
Squeezewave Lighter and faster alternative: • Reshape: upsample channels, reduce
temporal length • Use depthwise separable convolution layers • 60x-70x faster than WaveGlow (10% reduction in audio quality) https://arxiv.org/abs/1811.00002 -
Preprocessing data for experiments Trump Speech Dataset • Audio and
transcripts scraped from rev.com • >12 hours of audio • Sample size from 1s to 45s (clipped) • 1 speaker (others were filtered) LJ Speech Dataset • Most common open dataset for TTS • >25 hours of audio extracted from books • Sample size from 1s to 10s • 1 speaker Common preprocessing and format conversion logic Output: id, text, phonemes, audio file, spectrogram file -
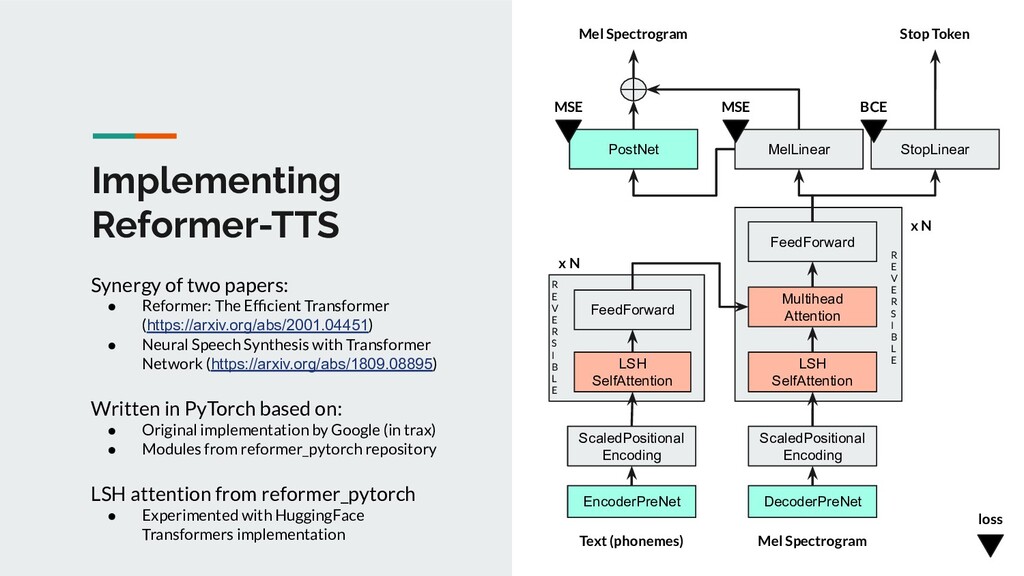
Implementing Reformer-TTS Synergy of two papers: • Reformer: The Efficient
Transformer (https://arxiv.org/abs/2001.04451) • Neural Speech Synthesis with Transformer Network (https://arxiv.org/abs/1809.08895) Written in PyTorch based on: • Original implementation by Google (in trax) • Modules from reformer_pytorch repository LSH attention from reformer_pytorch • Experimented with HuggingFace Transformers implementation EncoderPreNet ScaledPositional Encoding LSH SelfAttention FeedForward DecoderPreNet ScaledPositional Encoding LSH SelfAttention Multihead Attention PostNet x N FeedForward x N MelLinear StopLinear Mel Spectrogram Stop Token Text (phonemes) Mel Spectrogram R E V E R S I B L E R E V E R S I B L E loss BCE MSE MSE -
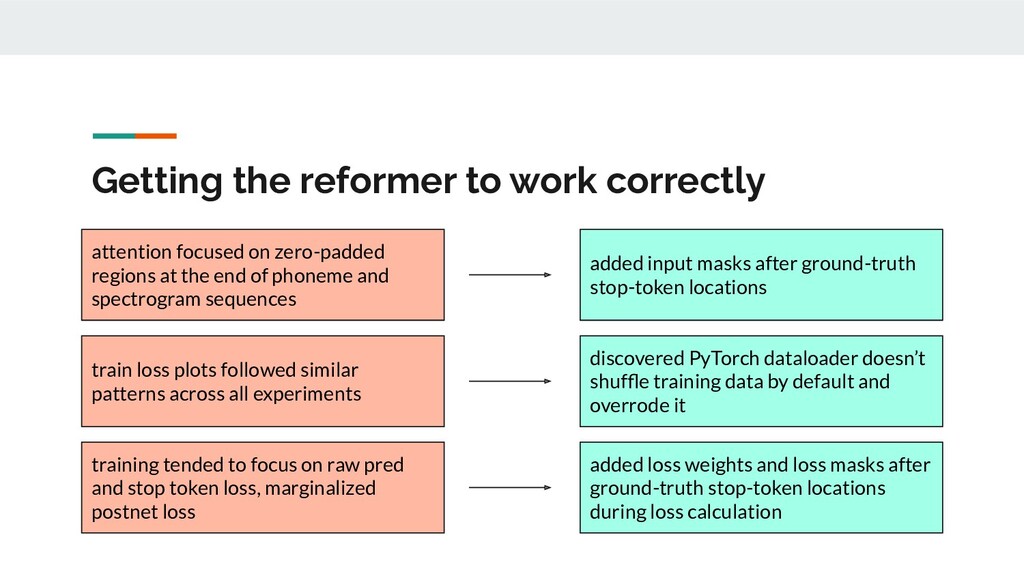
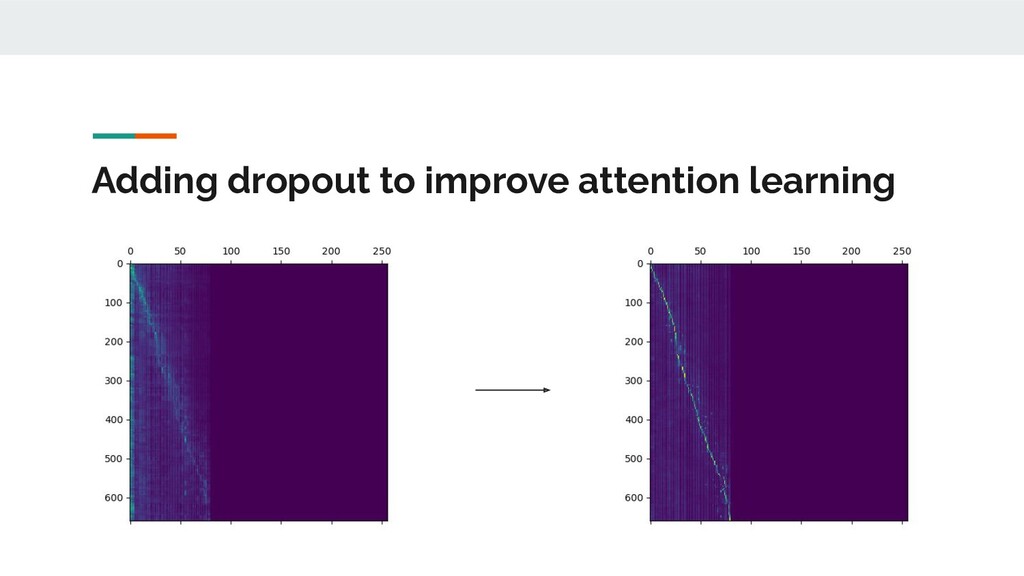
Getting the reformer to work correctly attention focused on zero-padded
regions at the end of phoneme and spectrogram sequences train loss plots followed similar patterns across all experiments training tended to focus on raw pred and stop token loss, marginalized postnet loss added input masks after ground-truth stop-token locations discovered PyTorch dataloader doesn’t shuffle training data by default and overrode it added loss weights and loss masks after ground-truth stop-token locations during loss calculation -
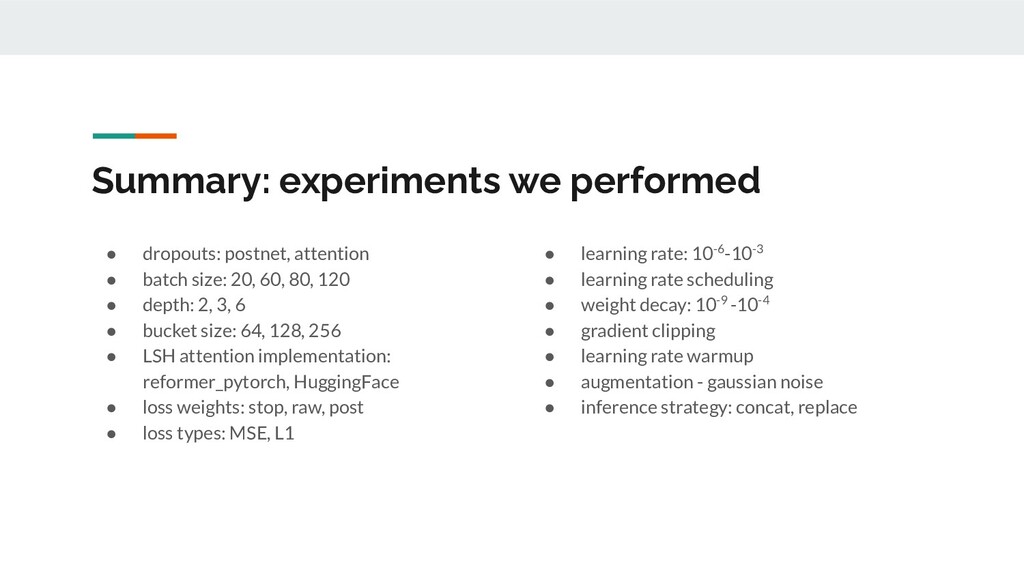
Summary: experiments we performed • dropouts: postnet, attention • batch
size: 20, 60, 80, 120 • depth: 2, 3, 6 • bucket size: 64, 128, 256 • LSH attention implementation: reformer_pytorch, HuggingFace • loss weights: stop, raw, post • loss types: MSE, L1 • learning rate: 10-6-10-3 • learning rate scheduling • weight decay: 10-9 -10-4 • gradient clipping • learning rate warmup • augmentation - gaussian noise • inference strategy: concat, replace -
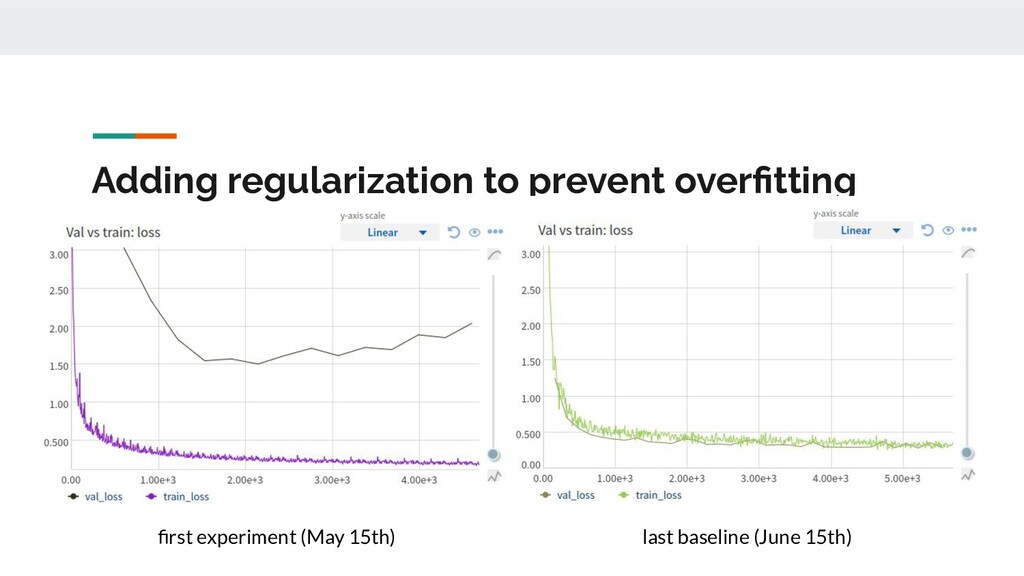
Adding regularization to prevent overfitting first experiment (May 15th) last
baseline (June 15th) -
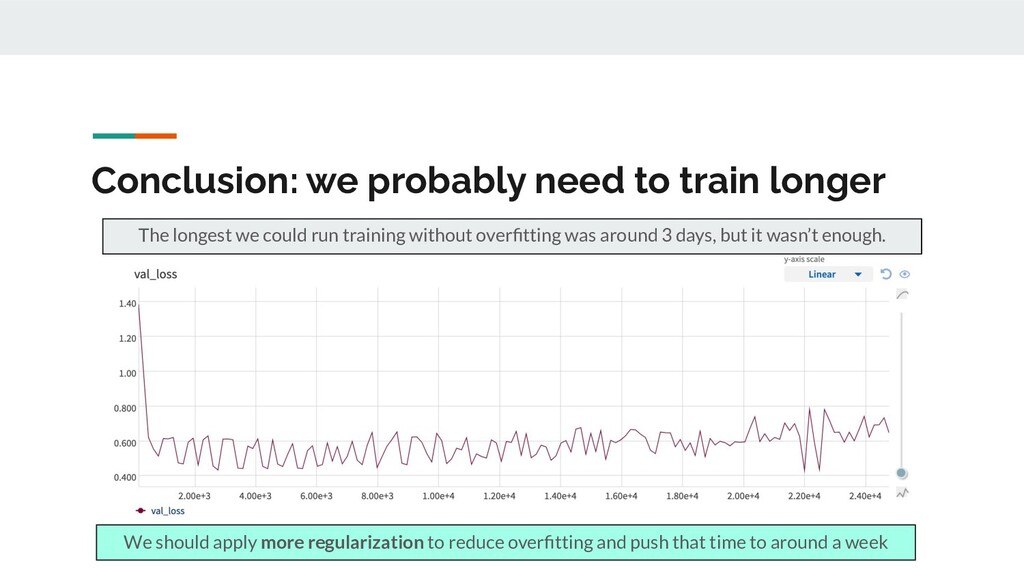
Conclusion: we probably need to train longer We should apply
more regularization to reduce overfitting and push that time to around a week The longest we could run training without overfitting was around 3 days, but it wasn’t enough. -
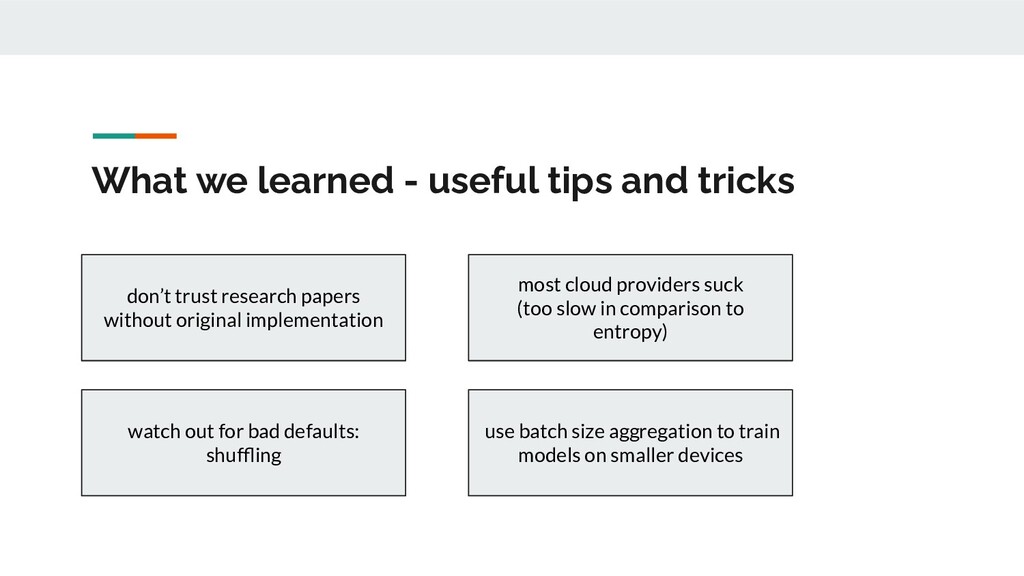
What we learned - useful tips and tricks don’t trust
research papers without original implementation most cloud providers suck (too slow in comparison to entropy) watch out for bad defaults: shuffling use batch size aggregation to train models on smaller devices -
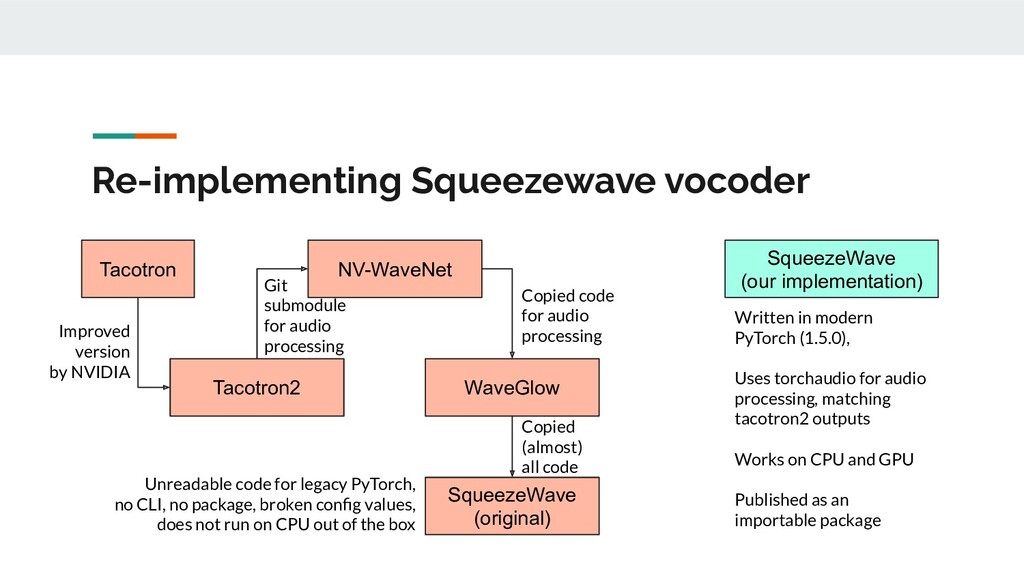
Re-implementing Squeezewave vocoder Tacotron Tacotron2 NV-WaveNet SqueezeWave (original) SqueezeWave (our
implementation) WaveGlow Improved version by NVIDIA Git submodule for audio processing Copied code for audio processing Copied (almost) all code Unreadable code for legacy PyTorch, no CLI, no package, broken config values, does not run on CPU out of the box Written in modern PyTorch (1.5.0), Uses torchaudio for audio processing, matching tacotron2 outputs Works on CPU and GPU Published as an importable package -
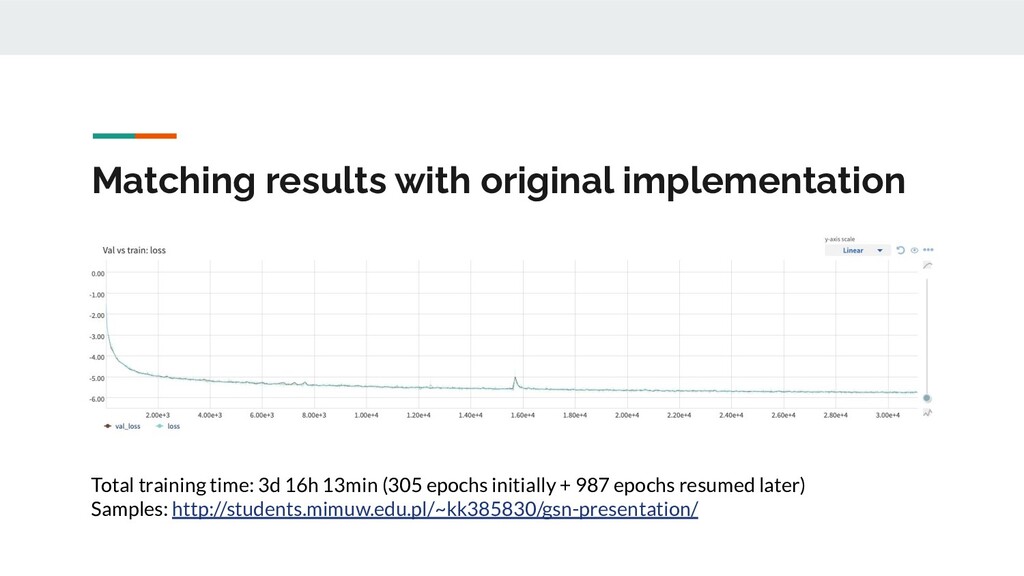
Matching results with original implementation Total training time: 3d 16h
13min (305 epochs initially + 987 epochs resumed later) Samples: http://students.mimuw.edu.pl/~kk385830/gsn-presentation/ -
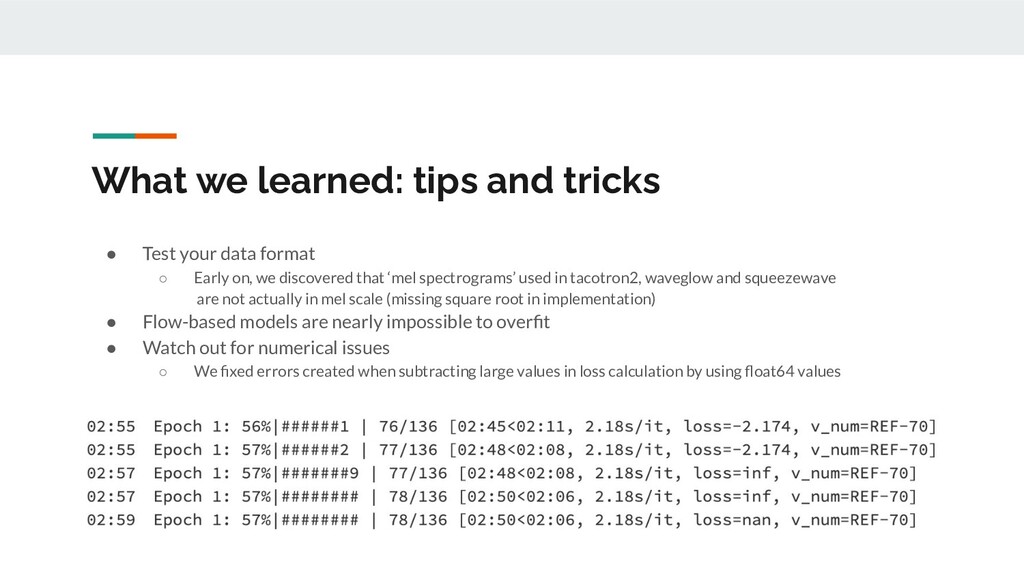
What we learned: tips and tricks • Test your data
format ◦ Early on, we discovered that ‘mel spectrograms’ used in tacotron2, waveglow and squeezewave are not actually in mel scale (missing square root in implementation) • Flow-based models are nearly impossible to overfit • Watch out for numerical issues ◦ We fixed errors created when subtracting large values in loss calculation by using float64 values -
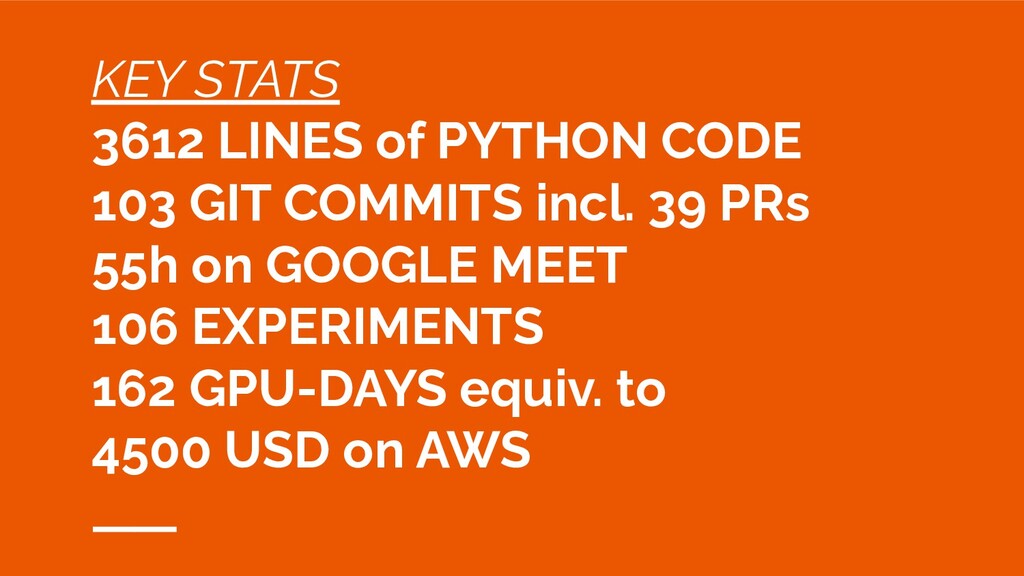
KEY STATS 3612 LINES of PYTHON CODE 103 GIT COMMITS
incl. 39 PRs 55h on GOOGLE MEET 106 EXPERIMENTS 162 GPU-DAYS equiv. to 4500 USD on AWS -
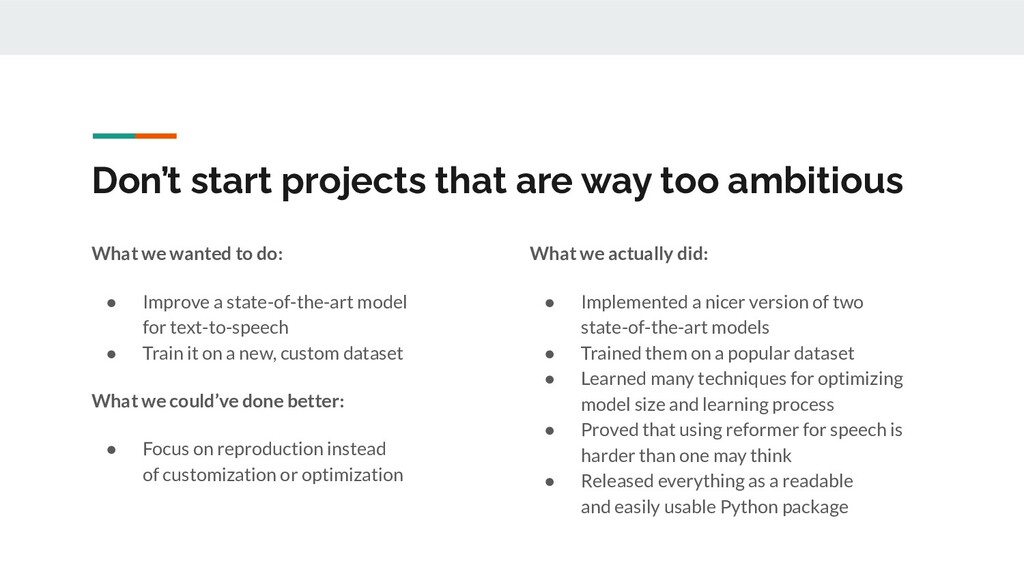
Don’t start projects that are way too ambitious What we
wanted to do: • Improve a state-of-the-art model for text-to-speech • Train it on a new, custom dataset What we could’ve done better: • Focus on reproduction instead of customization or optimization What we actually did: • Implemented a nicer version of two state-of-the-art models • Trained them on a popular dataset • Learned many techniques for optimizing model size and learning process • Proved that using reformer for speech is harder than one may think • Released everything as a readable and easily usable Python package -
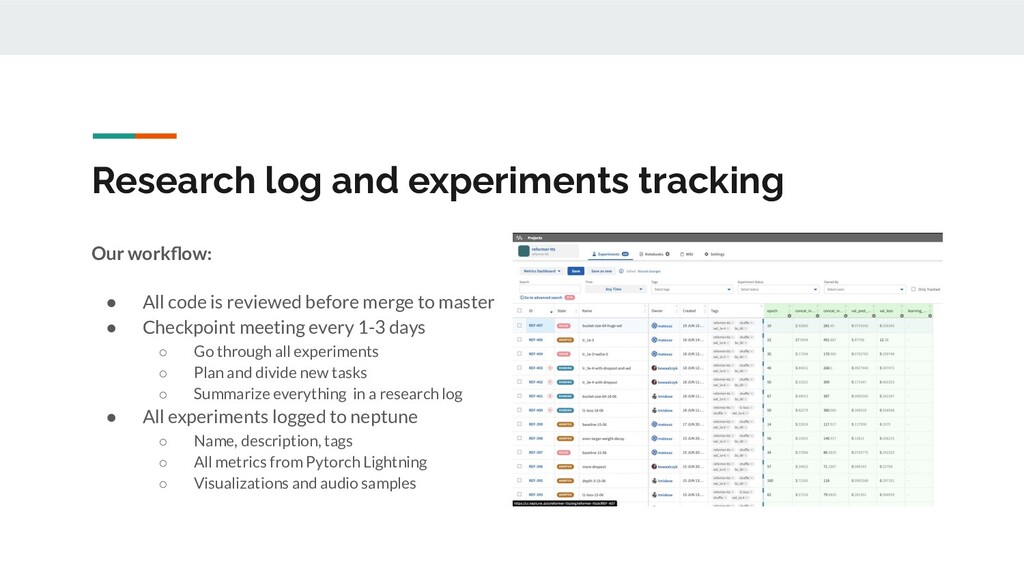
Research log and experiments tracking Our workflow: • All code
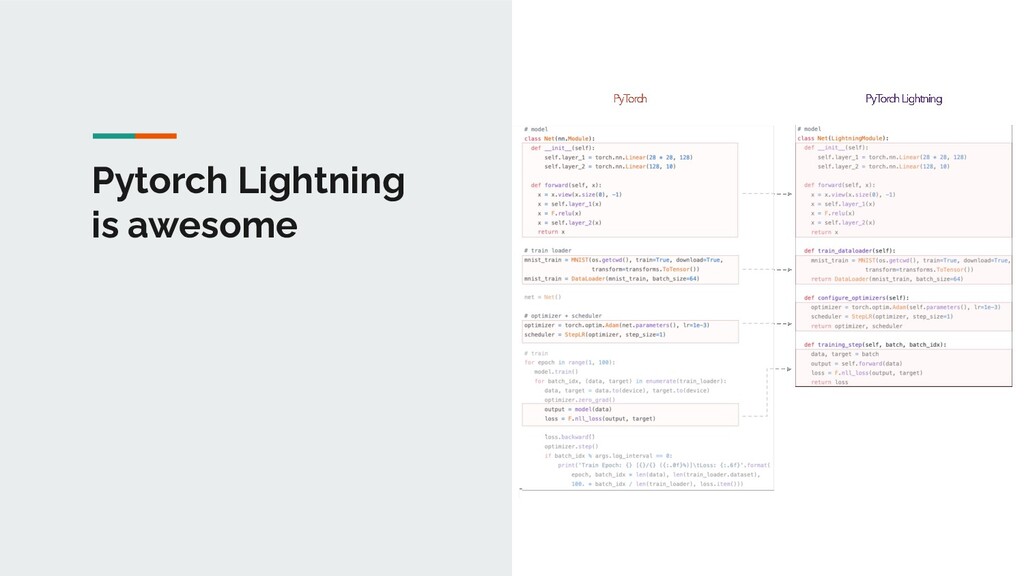
is reviewed before merge to master • Checkpoint meeting every 1-3 days ◦ Go through all experiments ◦ Plan and divide new tasks ◦ Summarize everything in a research log • All experiments logged to neptune ◦ Name, description, tags ◦ All metrics from Pytorch Lightning ◦ Visualizations and audio samples -
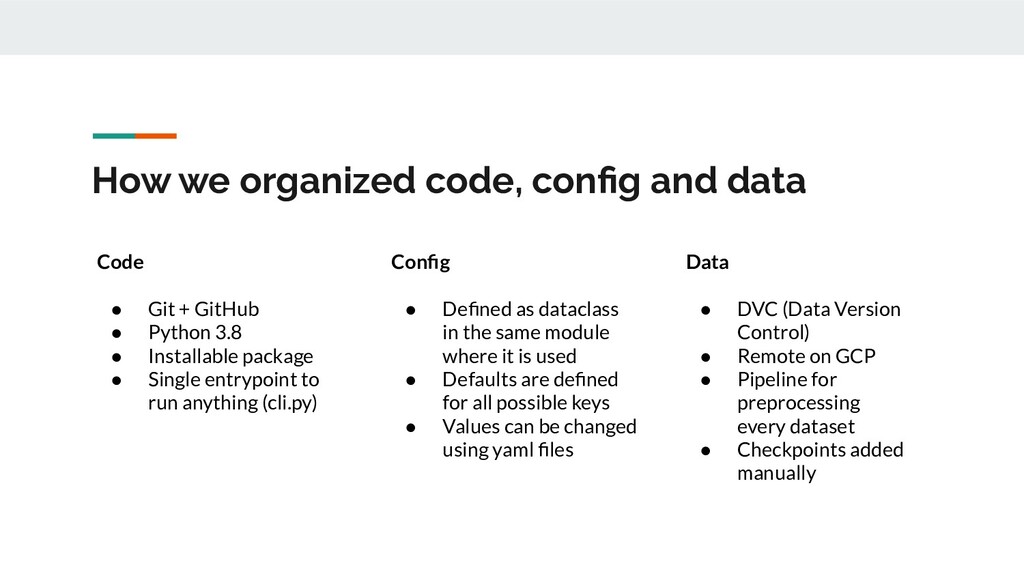
How we organized code, config and data Code • Git
+ GitHub • Python 3.8 • Installable package • Single entrypoint to run anything (cli.py) Config • Defined as dataclass in the same module where it is used • Defaults are defined for all possible keys • Values can be changed using yaml files Data • DVC (Data Version Control) • Remote on GCP • Pipeline for preprocessing every dataset • Checkpoints added manually