長岡技術科学大学 自然言語処理研究室 B4 LY NAM PHONG Proceedings of the Third Linguistic Annotation Workshop, ACL-IJCNLP 2009, pages 182–185, Suntec, Singapore, 6-7 August 2009.
we still lack such kind of corpora. In Vietnamese, there are many ambiguities in sentence analysis, so they systematically applied linguistic techniques to handle them. Annotators are supported by automatic-labeling tools and a tree-editor tool. Raw texts are extracted from Tuoitre, a daily newspaper.
taggers and word segmenters. Vietnamese word order is quite fixed, they choose to use constituency representation of syntactic structures. For Vietnamese, there are three annotation levels including word segmentation, POS tagging and syntactic labeling. Main target: build a corpus of 10,000 syntactically-annotated sentences.
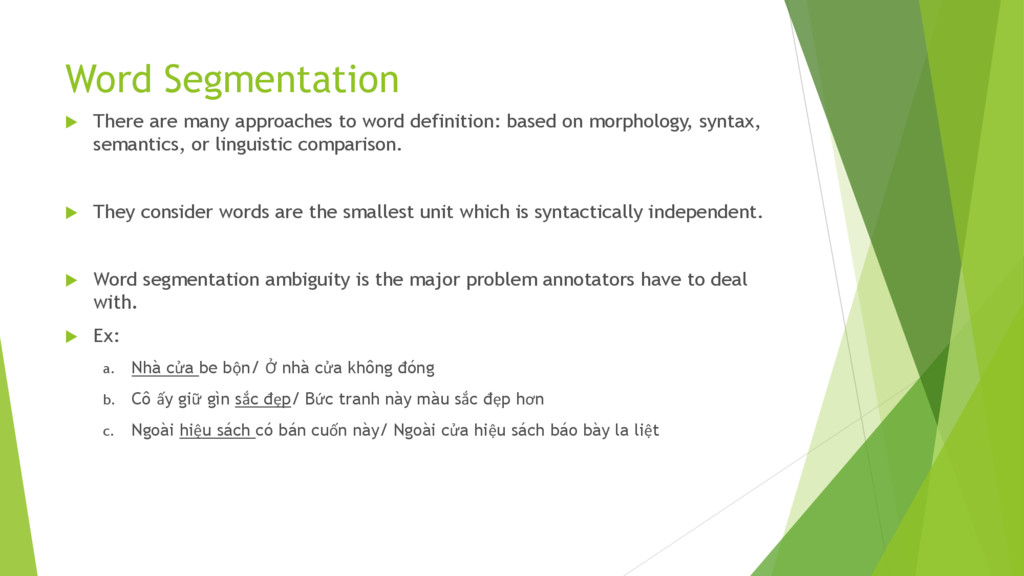
based on morphology, syntax, semantics, or linguistic comparison. They consider words are the smallest unit which is syntactically independent. Word segmentation ambiguity is the major problem annotators have to deal with. Ex: a. Nhà cửa be bộn/ Ở nhà cửa không đóng b. Cô ấy giữ gìn sắc đẹp/ Bức tranh này màu sắc đẹp hơn c. Ngoài hiệu sách có bán cuốn này/ Ngoài cửa hiệu sách báo bày la liệt
are often classified based on their combination ability, syntactic functions, and meaning. They choose first two criteria for POS tag set design. Syntactic Tag set contains three tag types: constituency tags, functional tags, and null-element tags. In sentence and phrase analysis, ambiguity may occur in many steps such as determining phrase’s head, discriminating between complements and adjuncts, etc.
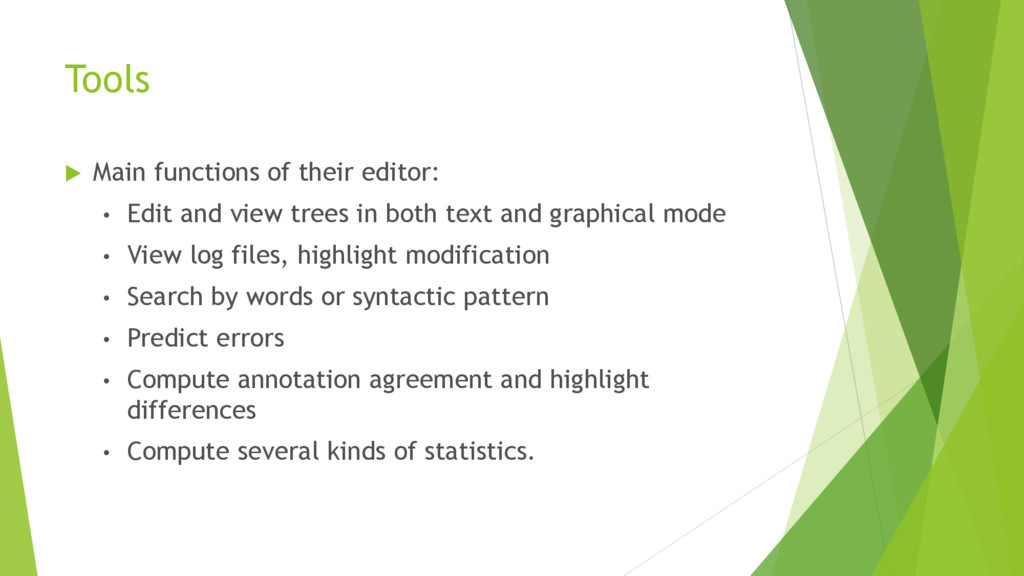
view trees in both text and graphical mode • View log files, highlight modification • Search by words or syntactic pattern • Predict errors • Compute annotation agreement and highlight differences • Compute several kinds of statistics.
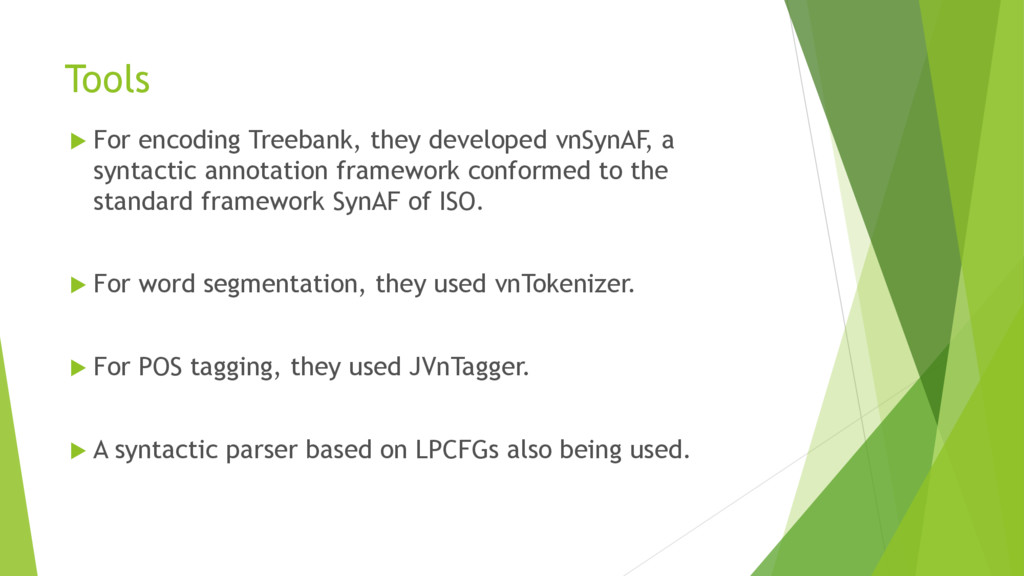
annotation framework conformed to the standard framework SynAF of ISO. For word segmentation, they used vnTokenizer. For POS tagging, they used JVnTagger. A syntactic parser based on LPCFGs also being used.
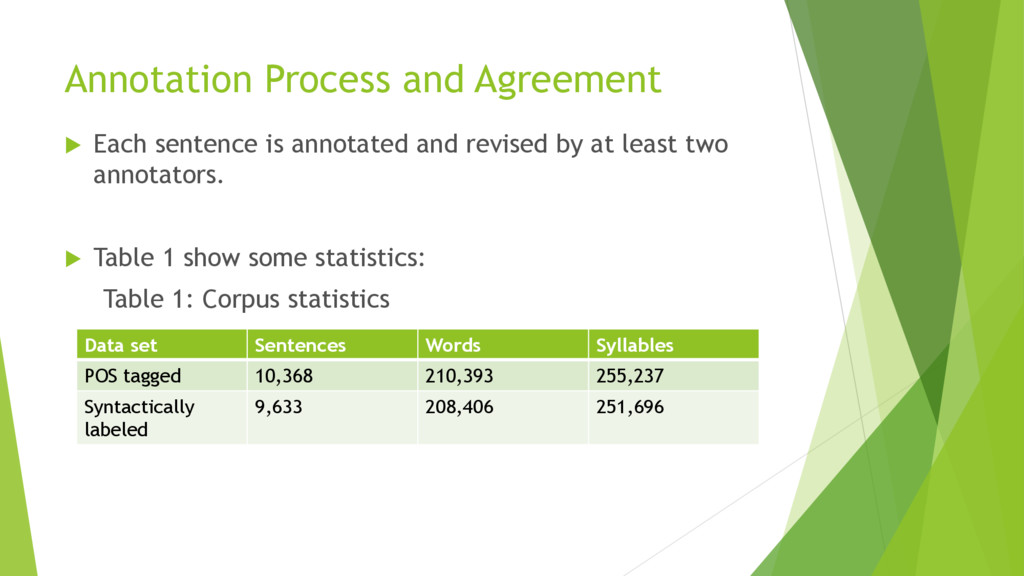
revised by at least two annotators. Table 1 show some statistics: Table 1: Corpus statistics Data set Sentences Words Syllables POS tagged 10,368 210,393 255,237 Syntactically labeled 9,633 208,406 251,696
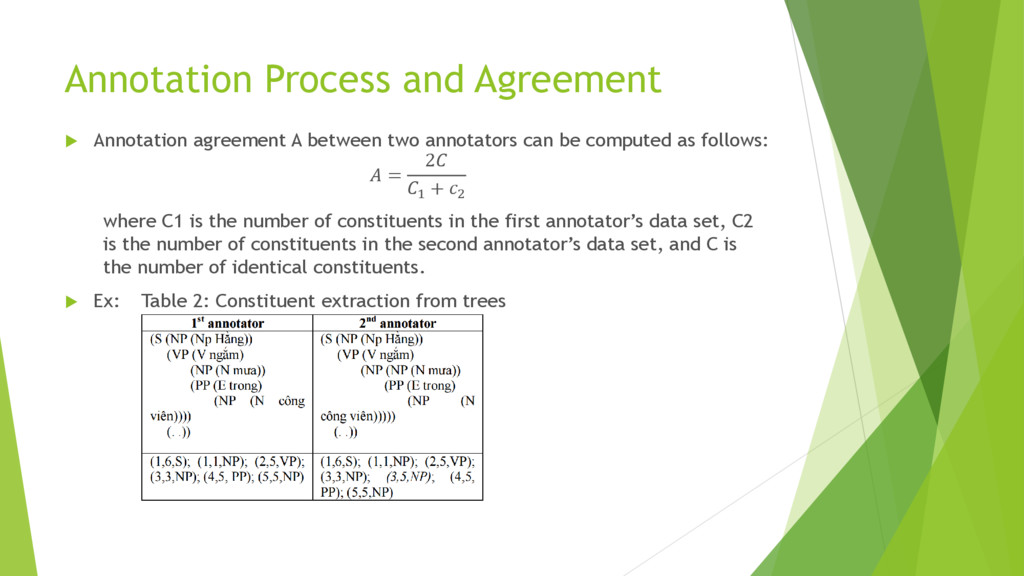
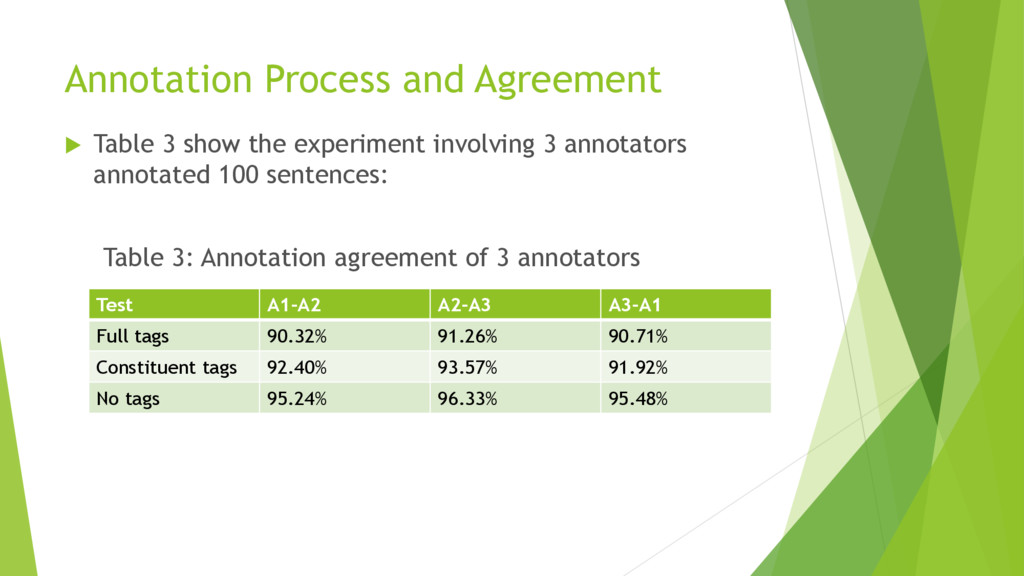
annotators can be computed as follows: = 2 1 + 2 where C1 is the number of constituents in the first annotator’s data set, C2 is the number of constituents in the second annotator’s data set, and C is the number of identical constituents. Ex: Table 2: Constituent extraction from trees
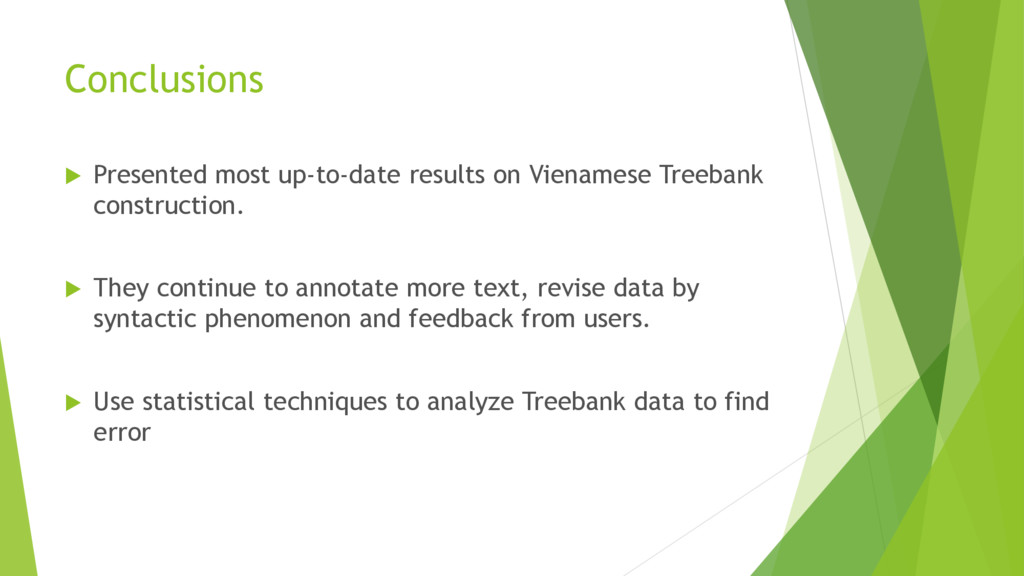
They continue to annotate more text, revise data by syntactic phenomenon and feedback from users. Use statistical techniques to analyze Treebank data to find error


 phong3112
 chriscoyier
 tamaranovitovic
 inesmontani
 retrage
 skipperchong
 addyosmani
 gurzu
 tammyeverts
 lynnandtonic
 bcantrill
 tapps
 michielstock