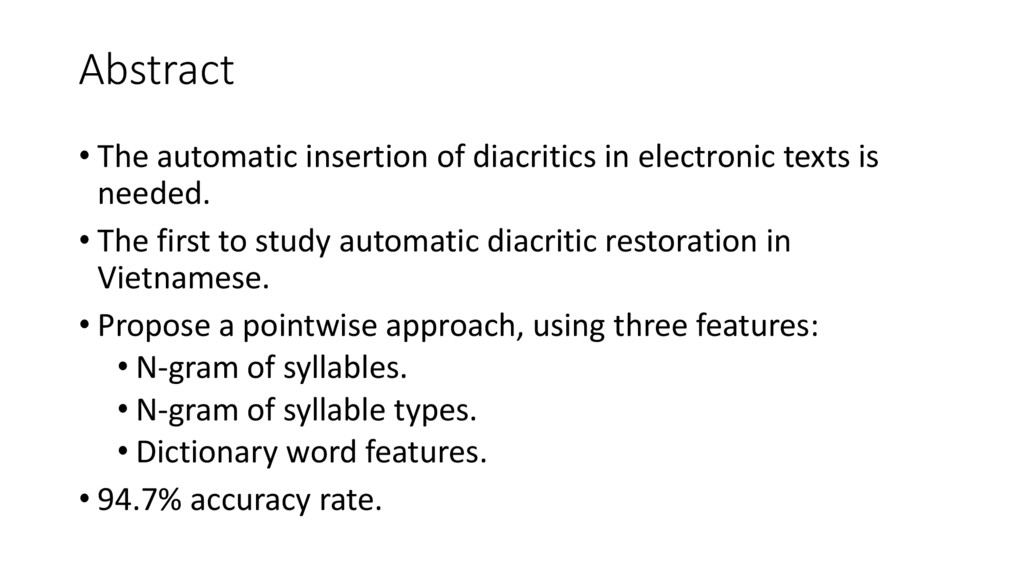
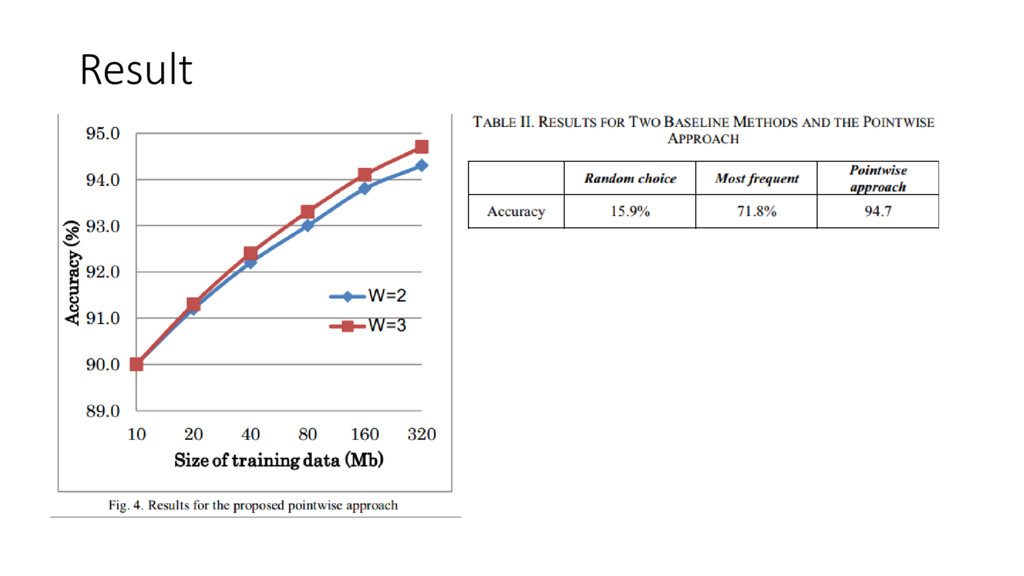
is needed. • The first to study automatic diacritic restoration in Vietnamese. • Propose a pointwise approach, using three features: • N-gram of syllables. • N-gram of syllable types. • Dictionary word features. • 94.7% accuracy rate.
language dependent, require large corpora to build useful model. • Character-based: use language independent algorithms. • Word-based approaches to Vietnamese face two major challenges: • Not enough dictionaries and corpora. • Word segmentations. • Character-based approach is also difficult due to the abundance of diacritics in Vietnamese.
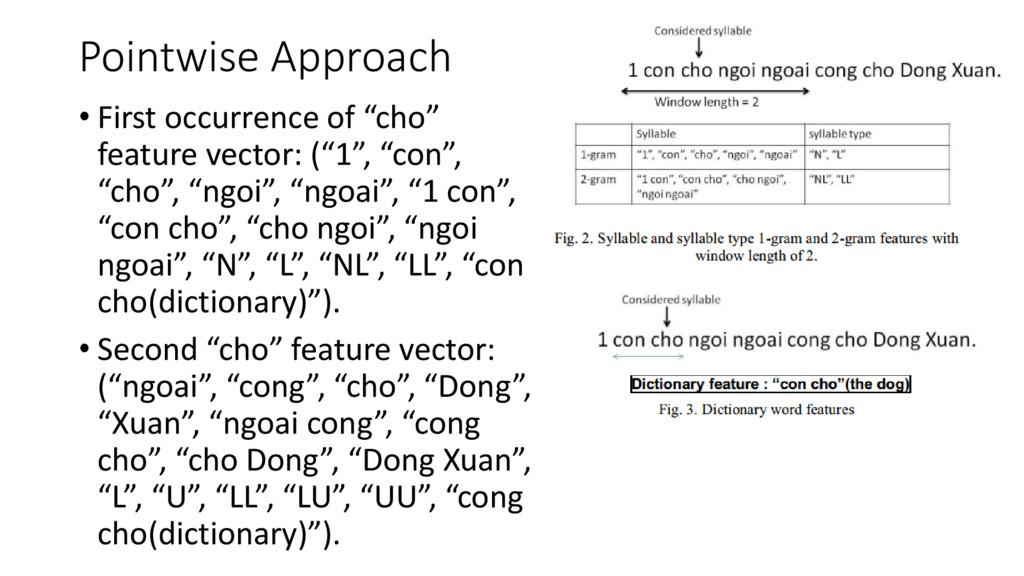
diacritic is independent of decisions about neighboring syllables. • Features for machine learning: • N-grams of syllables: 1-gram and 2-gram. • Window: W word around the target syllables • N-grams of syllable types: U for uppercase, L for lowercase, N for number and O for others, such as a symbol. • Dictionary word features.
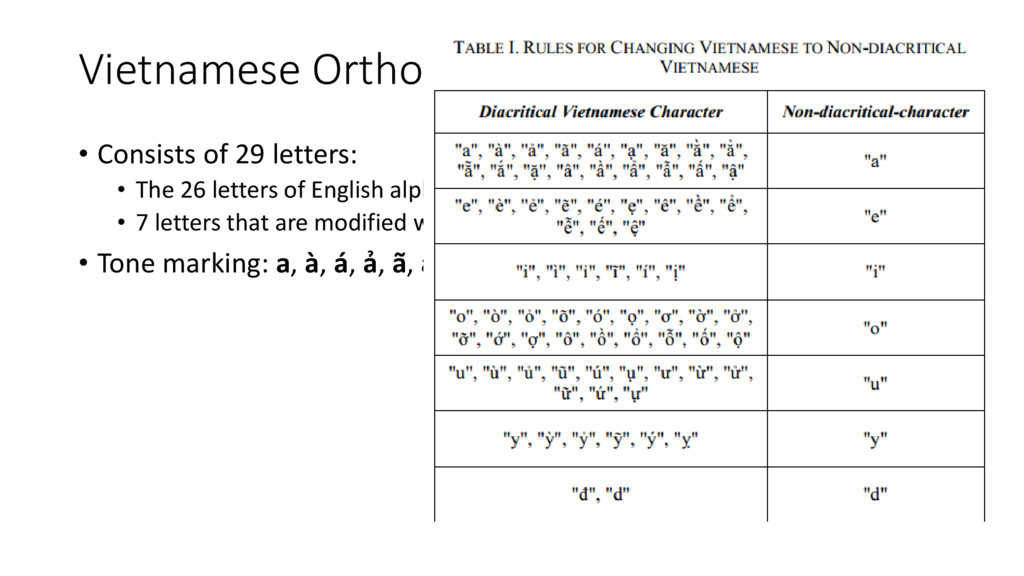
marks. • Used SVM implement in the LIBLINEAR package. • Texts corpus are crawled from journalism and devided into 2 parts: • 320Mb for training and other 15Mb for test. • A classifier build for each non-diacritical string (1525 strings).
Vietnamese texts using pointwise approach. • Negative consequence: files generated for the model were very large, up to 16Gb. • Expect that with proper feature selection, the model’s files can be smaller.


 phong3112
 tessaabrams
 skipperchong
 tamaranovitovic
 sachag
 tammyeverts
 destraynor
 lara
 matthewcrist
 eileencodes
 denniskardys
 ipullrank