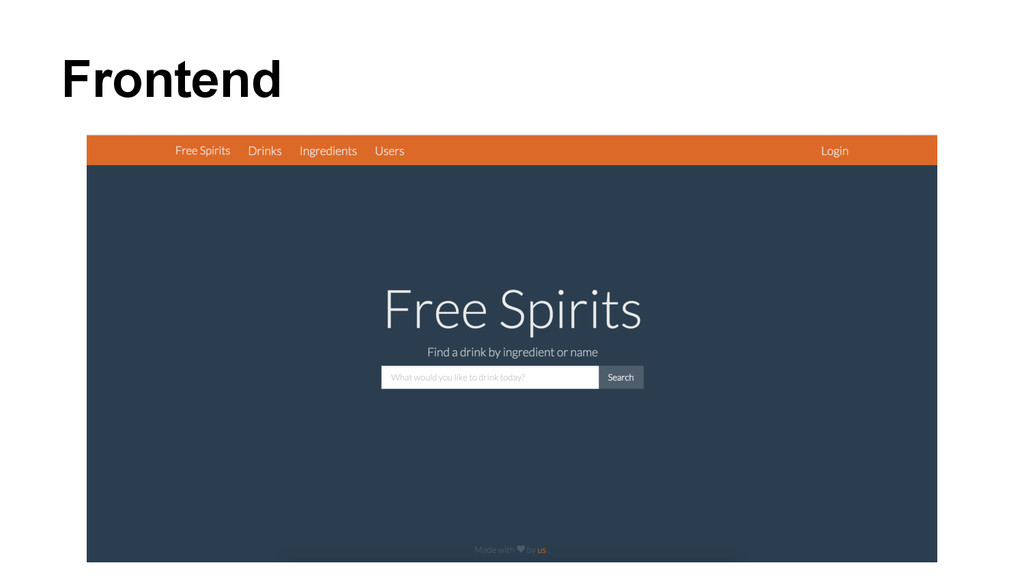
data from drinksmixer.com Outputted the data into data/*.json. Database contains over 15,000 entries Tutorial on how to use Scrapy: http://pybae.github.io/blog/2015/04/27/a-simple- introduction-to-scrapy/
token, as well as providing validators. Flask-Login provides user session management, such as providing a current_user that is accessible in all the models. We also use Gravatar to get profile pictures
an index of possible queries to models, and searches manually if not. We ran into issues since Flask-Whooshsearch used Python 2, and thus had to use a port.
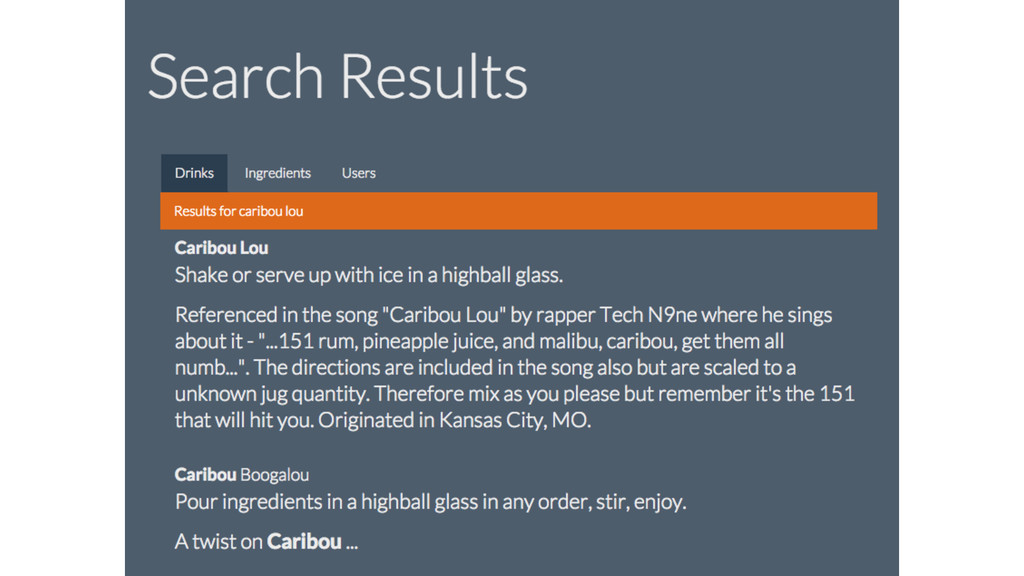
results Only implemented on the index page, as we couldn’t find a way to cleanly pass variables to the parent template. Also had issues with content wrapping
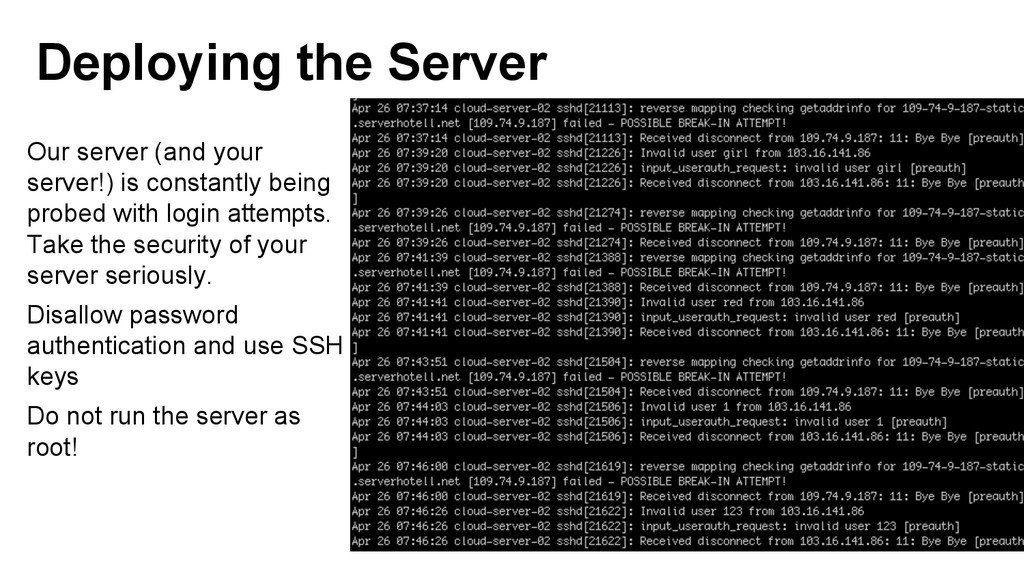
being probed with login attempts. Take the security of your server seriously. Disallow password authentication and use SSH keys Do not run the server as root!
is defined in api.py Most are GET requests, but we have two POST requests: favoriting and unfavoriting. These are validated with the current user, therefore ensuring that the user must be signed in for the POST request to succeed.
validation and forms. Our search functionality is also well done, though our contextualized results could provide better context. We had to learn a lot to complete this project. Every step of the project required research to complete, and it was often marred by incomplete (or incorrect) documentation. In these cases, we sometimes had to even review the source code of the libraries we used to figure out why the implementation wasn’t working as intended. The design of the website was intended to be simple, but it could come across as flat. None of our group members are true website designers at heart, but we did our best to make everything look clean. Our Google Images query also lead to some dubious results.
The dataset is well-maintained, but is too small. Search isn’t contextualized and is often incorrect. Search is susceptible to errors in input, such as the character ‘;’ will give faulty results as well. Search seems to be implemented by a simple ilike matching, which wouldn’t scale for larger databases. Occasionally leads to Jinja errors when should be giving 404, such as superheroes-idb.tk/character/-1


 tammyeverts
 kimpetersen
 ammeep
 bcantrill
 charlesmeaden
 marktimemedia
 yeseniaperezcruz
 tenderlove
 baasie
 geshan
 helenjbeal
 jonyablonski