Share
Embed
Introduction to Machine Learning
I was given a presentation on the Introduction to Machine Learning and how it works at Developer student club (DSC VVP) webinar.
uday kiran
November 17, 2020
Transcript
22 slides
-
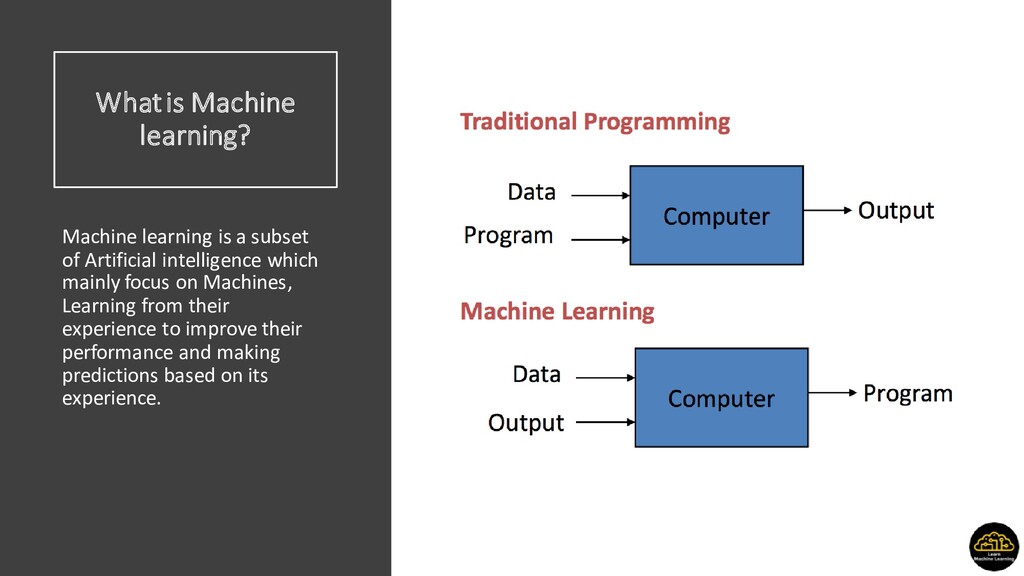
What is Machine learning? Machine learning is a subset of
Artificial intelligence which mainly focus on Machines, Learning from their experience to improve their performance and making predictions based on its experience. -
What does Machine learning do? • It enables the computers
or the machines to make data-driven decisions rather than being explicitly programmed for carrying out a certain task. • These programs or algorithms are designed in a way that they learn and improve over time when are exposed to new data. • In simple terms it find the patterns in the data. -
WHY IS MACHINE LEARNING NEEDED? Not everything can be coded
explicitly. Even if we had a good idea about how to do it, the program might become really complicated. Scalability - Ability to perform on large amounts of information. -
Why now? Lot of available data Increasing computational power More
advanced algorithms Increasing support from industries -
When to use Machine learning? When a problem is complex
and can't be solved using a traditional programing method. Human expertise does not exist (navigating on Mars) Humans can’t explain their expertise (speech recognition) Models must be customized (personalized shopping) Models are based on huge amounts of data (genomics). You don't need to use ML where learning is not required like calculating payroll. -
Applications of Machine learning • Virtual personal assistant • Predictions
while commuting • Video surveillance • Social media services • Email span and malware filtering • Online customer support • Search engine • Personalization • Fraud detection -
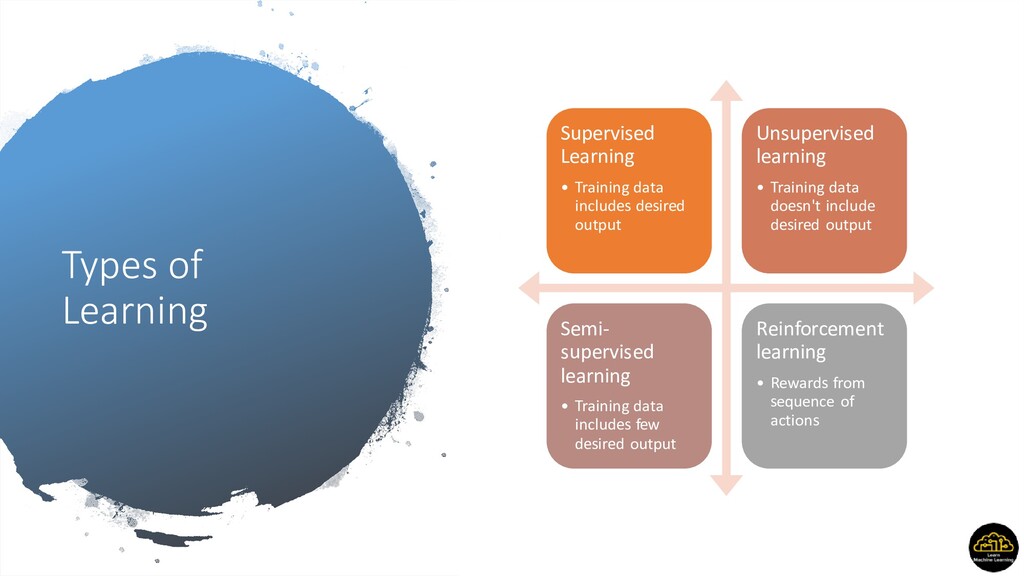
Types of Learning Supervised Learning • Training data includes desired
output Unsupervised learning • Training data doesn't include desired output Semi- supervised learning • Training data includes few desired output Reinforcement learning • Rewards from sequence of actions -
SUPERVISED LEARNING • Given input and output (X1,Y1), (X2,Y2), (X3,Y3)…...(Xn,Yn).
• The goal of supervised learning is to find an unknown function which maps the relation between input and output. • Y = f(X) + e; f(X) = function, Y = output, X = input and e = irreducible error. • Using the input data we generate a function which maps the input and output. • 2 types of supervised learning • Regression • Classification -
Unsupervised learning • Given only input without output. • Goal
of unsupervised learning is to model the underlying structure or hidden structure or distribution in the data in order to learn more about the data. • Here algorithms are left to their devises to discover and present the interesting structure in the data. • Two types of Unsupervised learning algorithms • Clustering • Association -
Semi supervised learning • It is in between of supervised
and unsupervised learning. • Mostly we will have a combination of labeled and unlabeled data. • You can use unsupervised learning to discover and learn the structure in the input data. • You can also use supervised learning to make predictions of unlabeled data using transfer learning or classic algorithms techniques and feed them back to the supervised learning algorithm to improve the performance. -
How Machine learning works? • ML algorithms are described as
learning the target function that maps the input and output. Y = f(X) + e • Here the function f which maps the relation between input and output is generally unknown. We estimate f based on the observed data. • 2 ways to estimate f • Parametric methods • Non-Parametric methods -
Parametric methods A model the summarizes the data with a
set of parameters of fixed size. No matter how much data you throw it doesn’t change its mind. Examples Linear regression Logistic regression Linear SVM Simple NN's -
Advantages of Parametric methods Simple: These methods are easier to
understand and interpret Speed: Very fast Less data: Woks well with less data as well -
Disadvantages of Parametric methods Constrained: By choosing a functional form
these methods are highly constrained to the specified form Limited complex: These methods are more suited to simpler forms Poor fit: In practice the methods are unlikely to match the underlying mapping function. -
Non- Parametric methods When you have a lot of data
and have no prior knowledge about it or when you don't want to worry about the feature selection. No of parameters is infinite and complexity of the model grows with the increase in training data. Examples KNN Decision trees Kernal SVM -
Advantages of Non-PM Flexibility: Capability of fitting many functional forms
Power: No assumptions about the underlying functions Performance: Can result in higher performance models for prediction. -
Disadvantages of Non-PM More data: Require more data Slower: Slower
to train. because of more parameters. Overfitting: Risk of overfitting -
Loss functions. These are the methods which are used to
evaluate how well your algorithm models your dataset. It will be high if your model is poor. Vice versa If you make any changes to the algorithm loss function will help you to say where you are going. We use optimization functions like Gradient descent which helps loss functions to learn to reduce the error in predictions. -
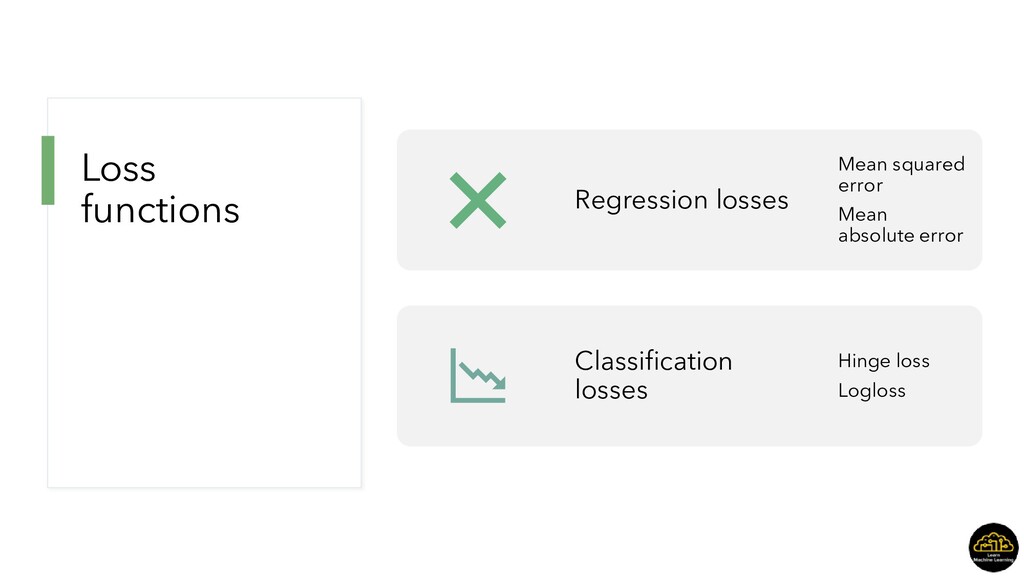
Loss functions Regression losses Mean squared error Mean absolute error
Classification losses Hinge loss Logloss