Share
Embed
Virtual Lab: Building an Open Data Lakehouse with Presto, Hudi and AWS S3
Learn how to build an open data lakehouse stack using Presto, Apache Hudi and AWS S3 in this free hands-on lab.
Ahana
August 12, 2022
Transcript
43 slides
-
HANDS-ON VIRTUAL LAB Building an Open Data Lakehouse with Presto,
Hudi, and AWS S3 1 -
WELCOME TO THE AHANA HANDS-ON VIRTUAL LAB Jalpreet Singh Nanda
Software Engineer [email protected] Sivabalan Narayanan Software Engineer [email protected] Your Lab Guides -
Over the next 90 minutes you will: Explore and understand
how to build a Data Lakehouse using Presto, Hudi, and S3 in a Hands-On Lab Environment Objective for Today 3 -
Agenda 1) Understand the Technology (20-25 mins) a) What is
a Data Lakehouse? b) Presto and Hudi overview 2) Getting your hands dirty (90 mins) a) Set up Hudi on Presto (Nothing to do, ships out of the box) b) Write and Read data using Spark in HUDI format c) Apply inserts, updates and delete to HUDI d) Query HUDI data in S3 data with Presto e) Set up Data streamer utility to ingest data seamlessly (auto pilot) 3) Summary and Close Out (5 - 10 mins) 4 -
The Open Data Lakehouse SQL Query Processing Reporting & Dashboarding
Data Science In-Data Lake Transformation Cloud Data Lake TBs -> PBs Open Data Lake Security, Reliability, and Governance -
What is Presto? • Open source, distributed MPP SQL query
engine • Query in Place • Federated Querying • ANSI SQL Compliant • Designed ground up for fast analytic queries against data of any size • Originally developed at Facebook • Proven on petabytes of data • SQL-On-Anything • Federated pluggable architecture to support many connector • Opensource, hosted on github • https://github.com/prestodb 7 -
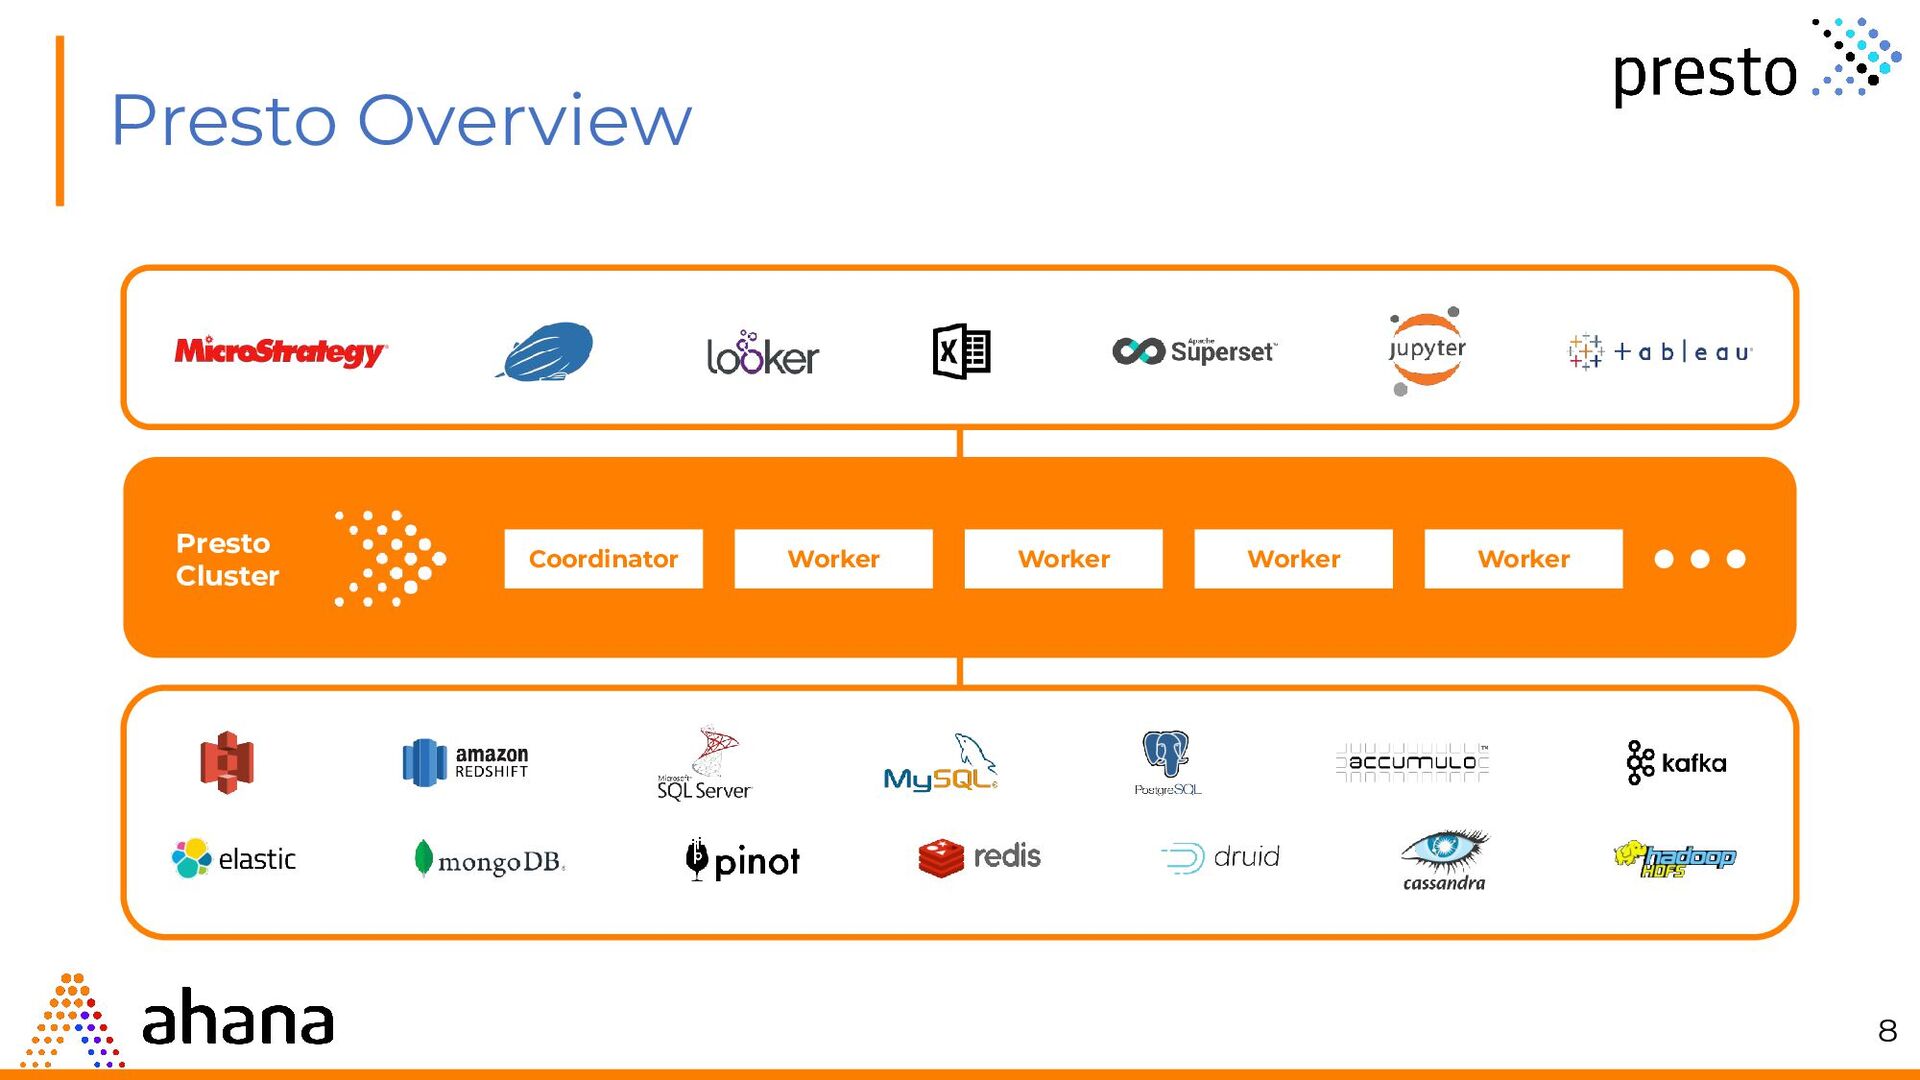
Presto Use Cases Data Lakehouse analytics Reporting & dashboarding Interactive
ad hoc querying Transformation using SQL (ETL) Federated querying across data sources 9 -
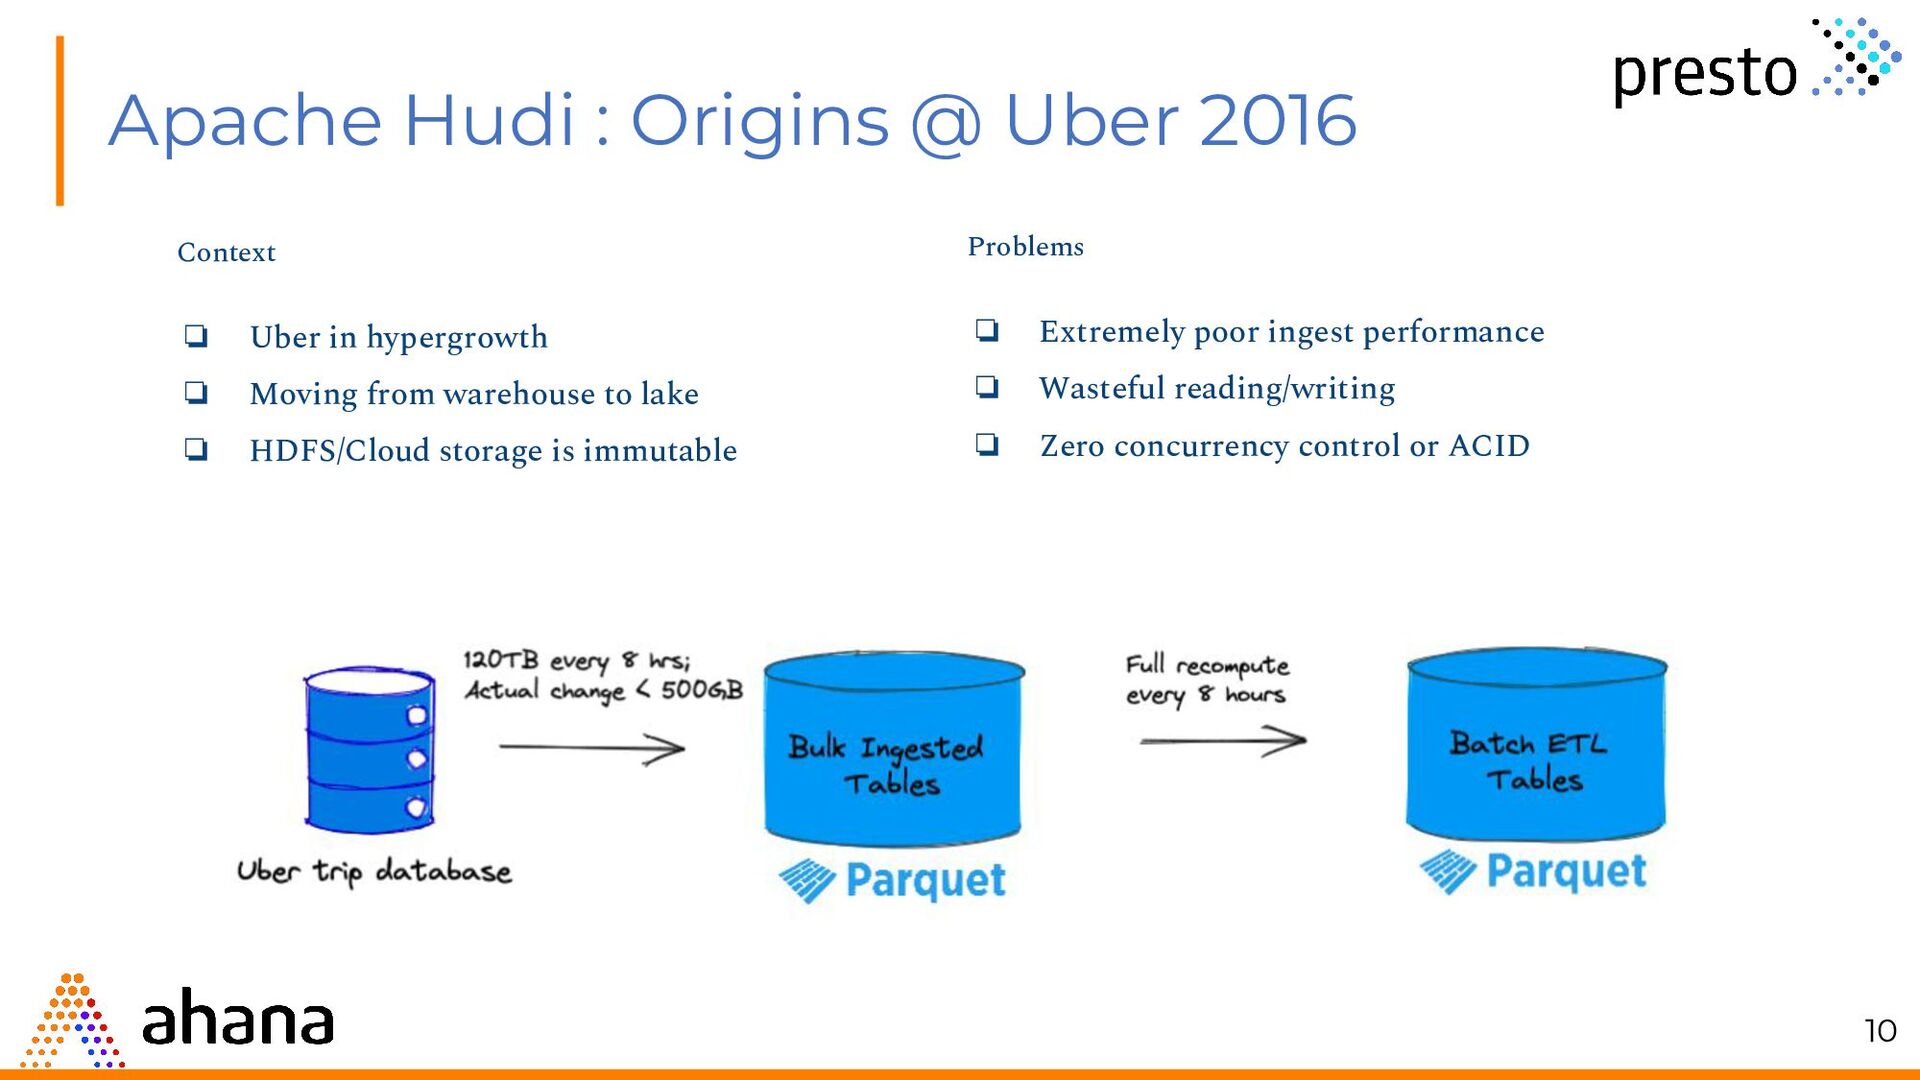
Apache Hudi : Origins @ Uber 2016 10 Context ❏
Uber in hypergrowth ❏ Moving from warehouse to lake ❏ HDFS/Cloud storage is immutable Problems ❏ Extremely poor ingest performance ❏ Wasteful reading/writing ❏ Zero concurrency control or ACID -
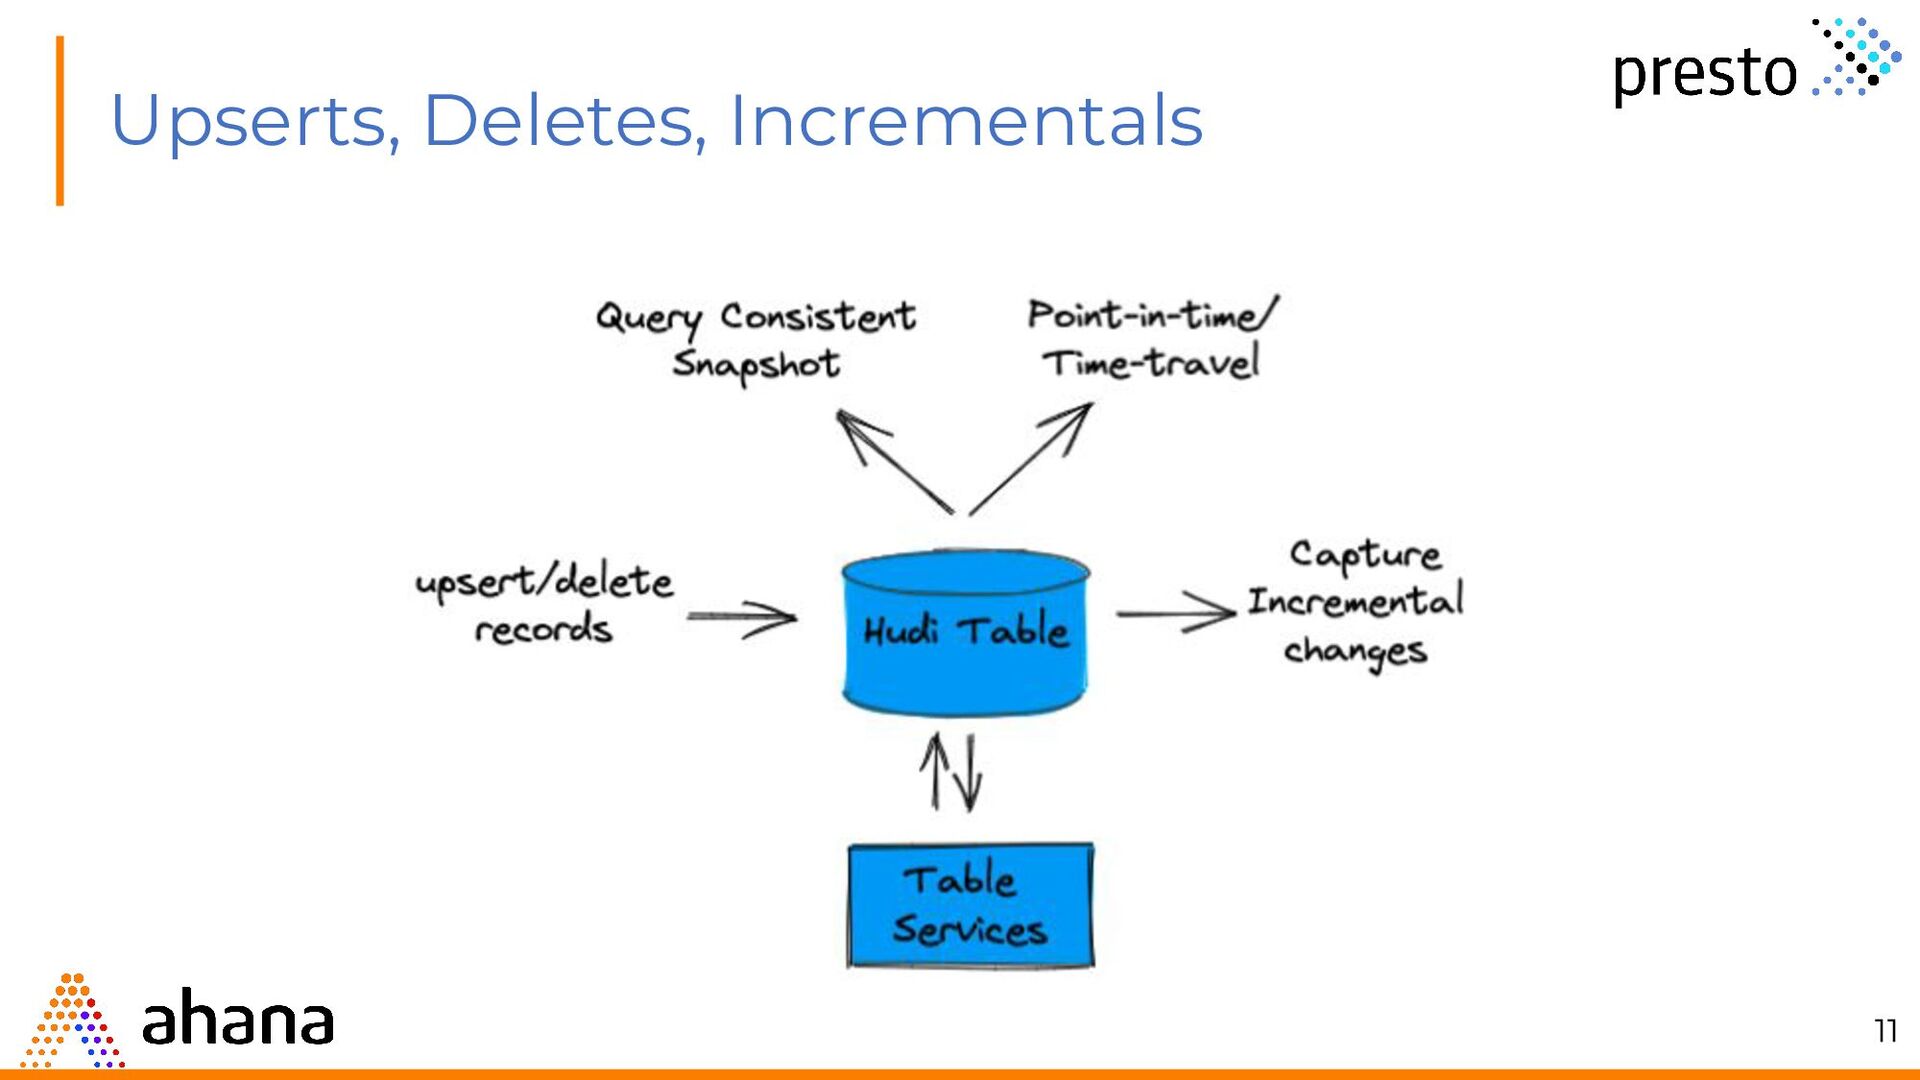
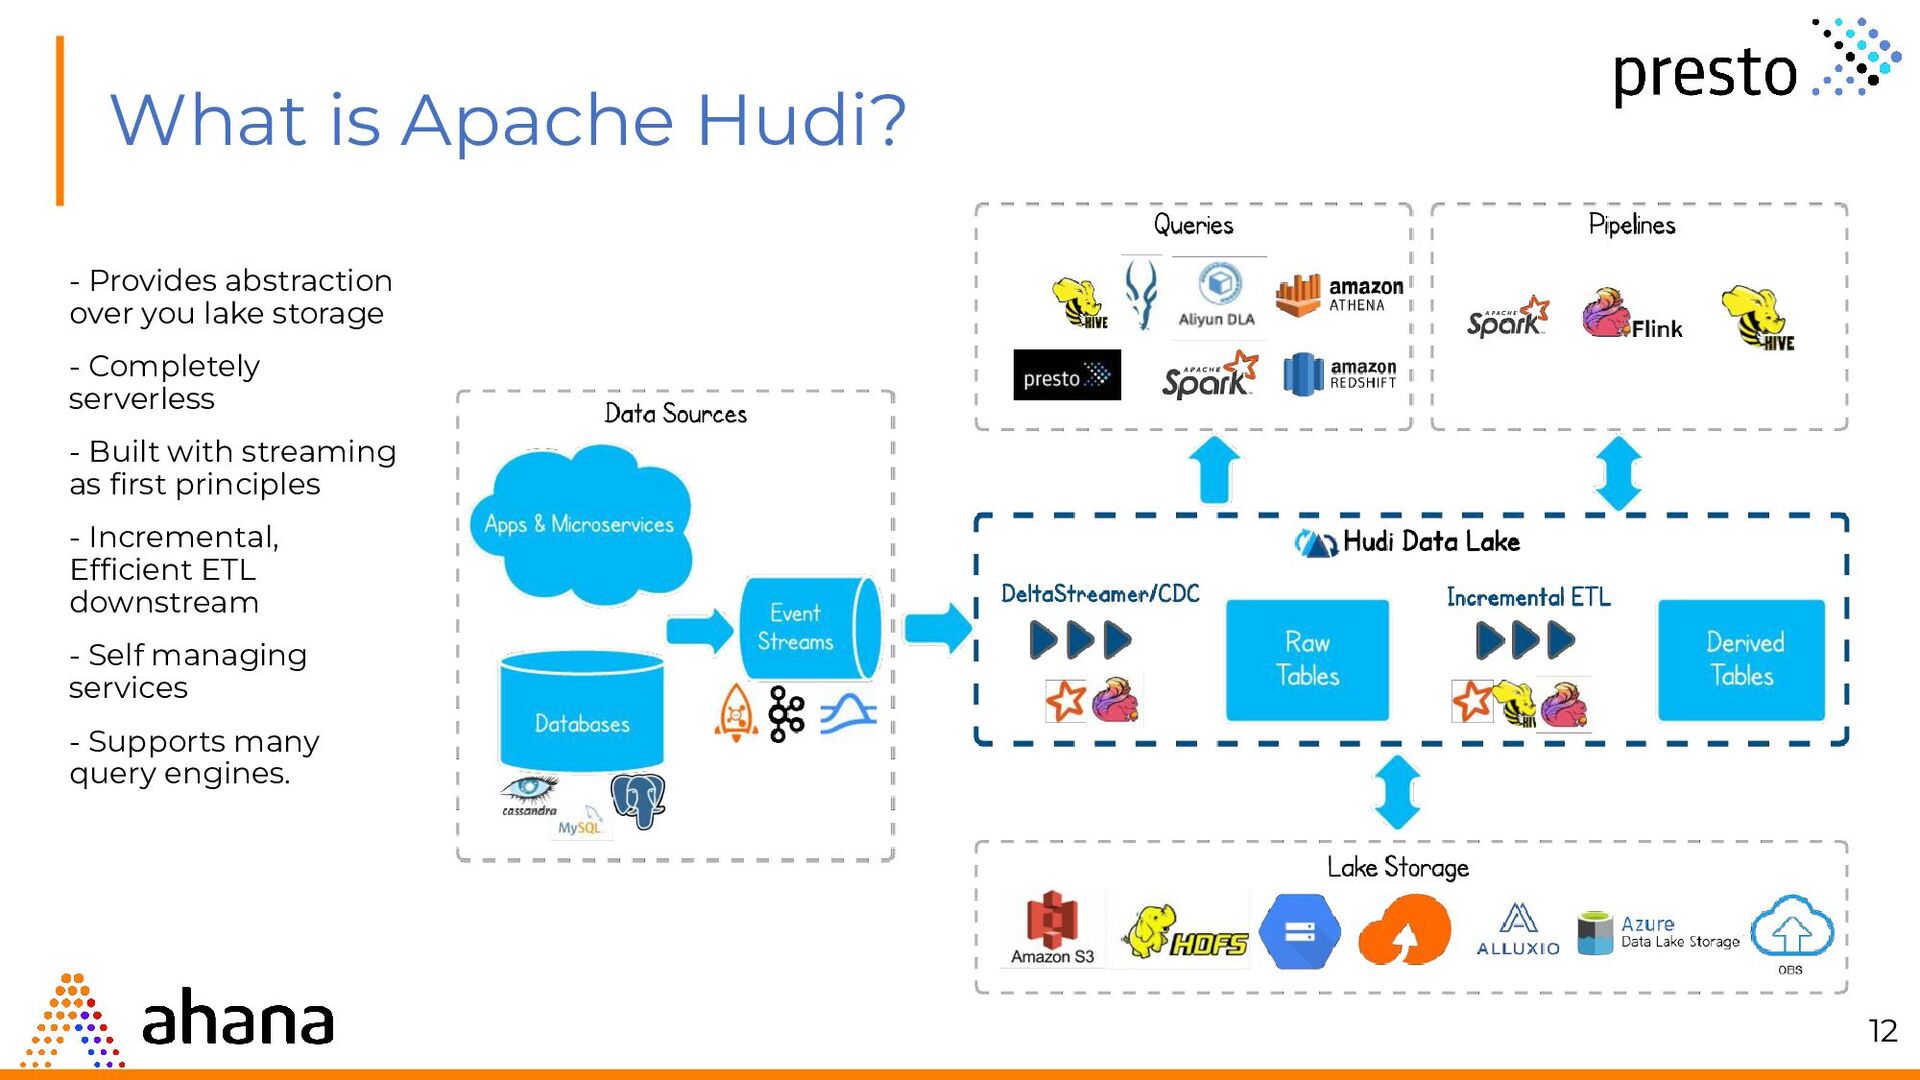
What is Apache Hudi? - Provides abstraction over you lake
storage - Completely serverless - Built with streaming as first principles - Incremental, Efficient ETL downstream - Self managing services - Supports many query engines. 12 -
Hudi for Data lake . 13 Hudi Table Type Queries
supported Copy-On-Write Snapshot, Incremental Merge-On-Read Snapshot, Incremental, Read Optimized Supports two table types Copy on Write (COW) Merge on Read (MOR) -
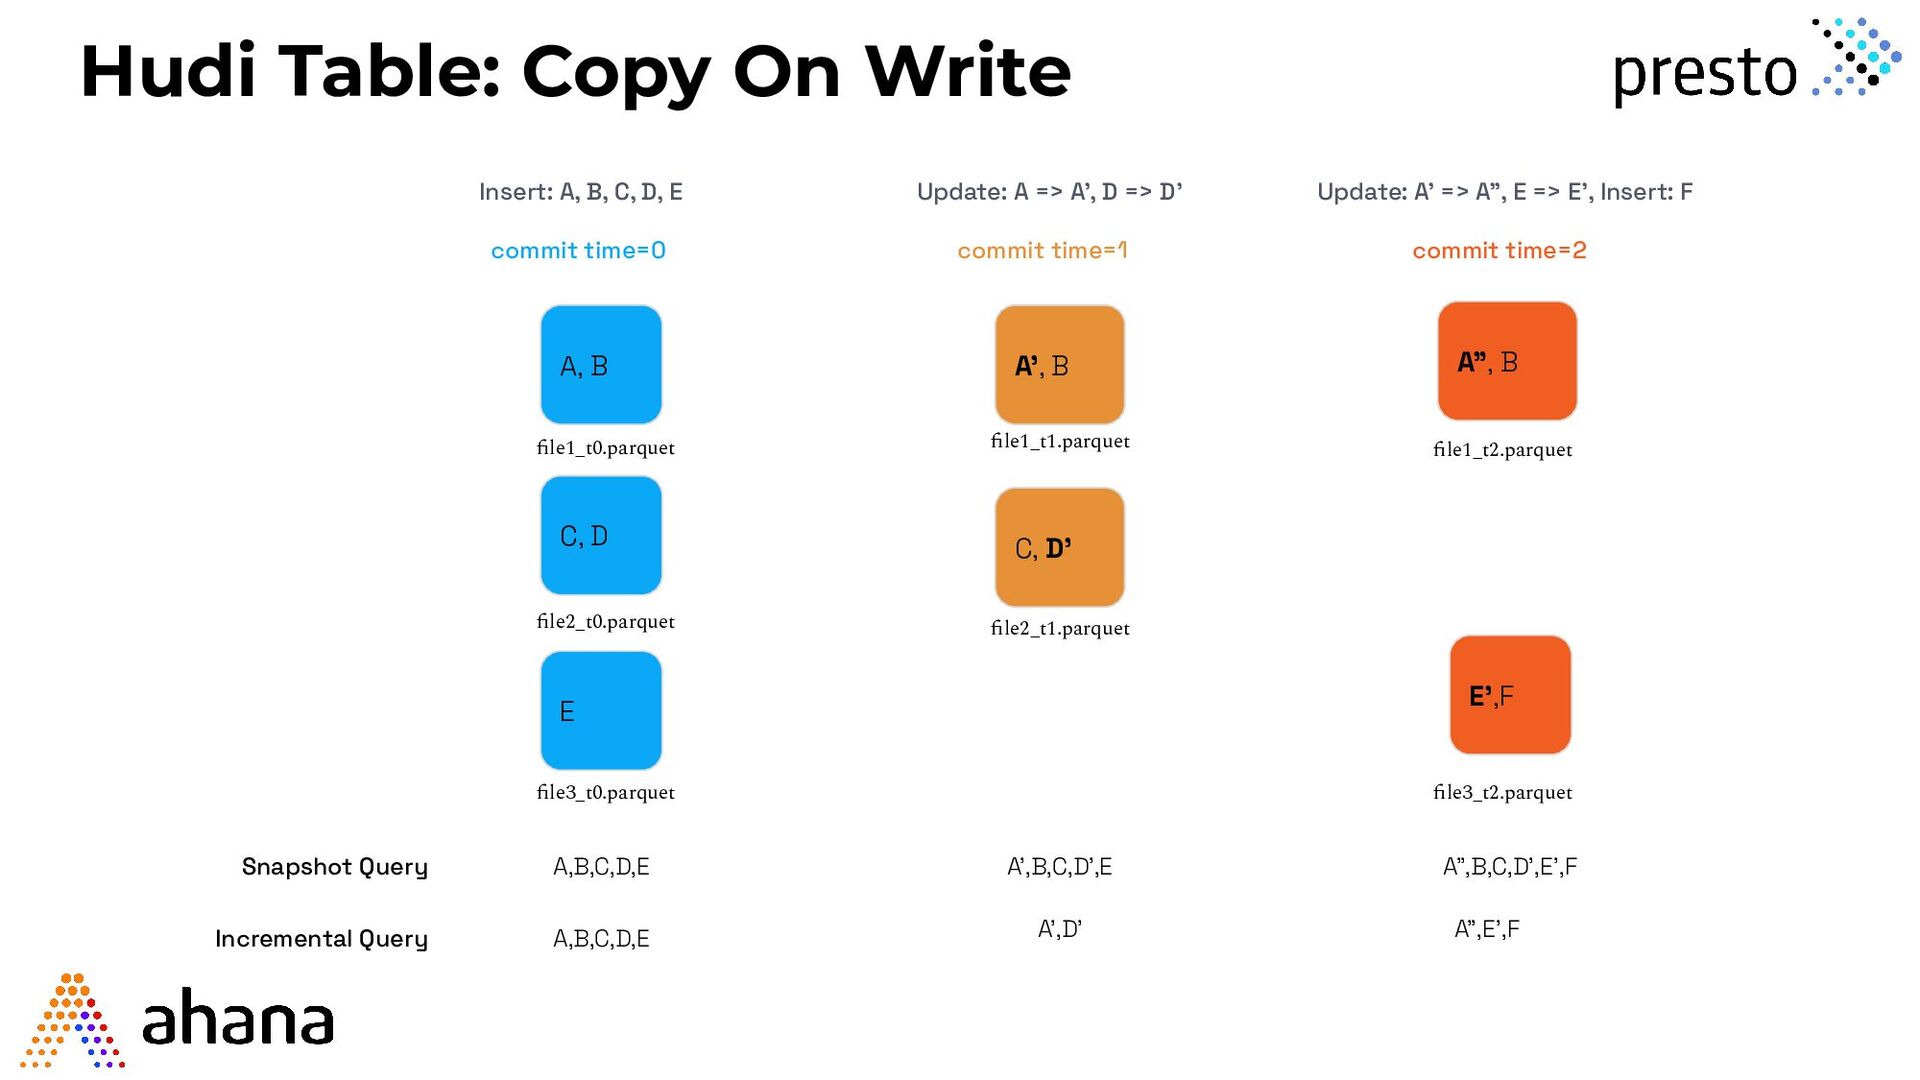
Hudi Table: Copy On Write Snapshot Query Incremental Query Insert:
A, B, C, D, E Update: A => A’, D => D’ Update: A’ => A”, E => E’, Insert: F commit time=0 commit time=1 commit time=2 A, B C, D E file1_t0.parquet file2_t0.parquet file3_t0.parquet A’, B C, D’ file1_t1.parquet file2_t1.parquet A”, B E’,F file1_t2.parquet file3_t2.parquet A,B,C,D,E A,B,C,D,E A’,B,C,D’,E A”,B,C,D’,E’,F A’,D’ A”,E’,F -
Hudi Table: Merge On Read Snapshot Query Incremental Query Insert:
A, B, C, D, E Update: A => A’, D => D’ Update: A’=>A”, E=>E’,Insert: F commit time=0 commit time=1 commit time=2 A, B C, D E file1_t0.parquet file2_t0.parquet file3_t0.parquet A’ D’ .file1_t1.log .file2_t1.log A” E’ .file1_t2.log .file3_t2.log A,B,C,D,E A,B,C,D,E A’,B,C,D’,E A”,B,C,D’,E’,F A’,D’ A”,E’,F Read Optimized Query A,B,C,D,E Compaction commit time=3 A”, B C, D’ E’,F file1_t3.parquet file2_t3.parquet file3_t3.parquet A”,B,C,D’,E’,F A”,E’,F A”,B,C,D’,E’,F A,B,C,D,E A,B,C,D,E -
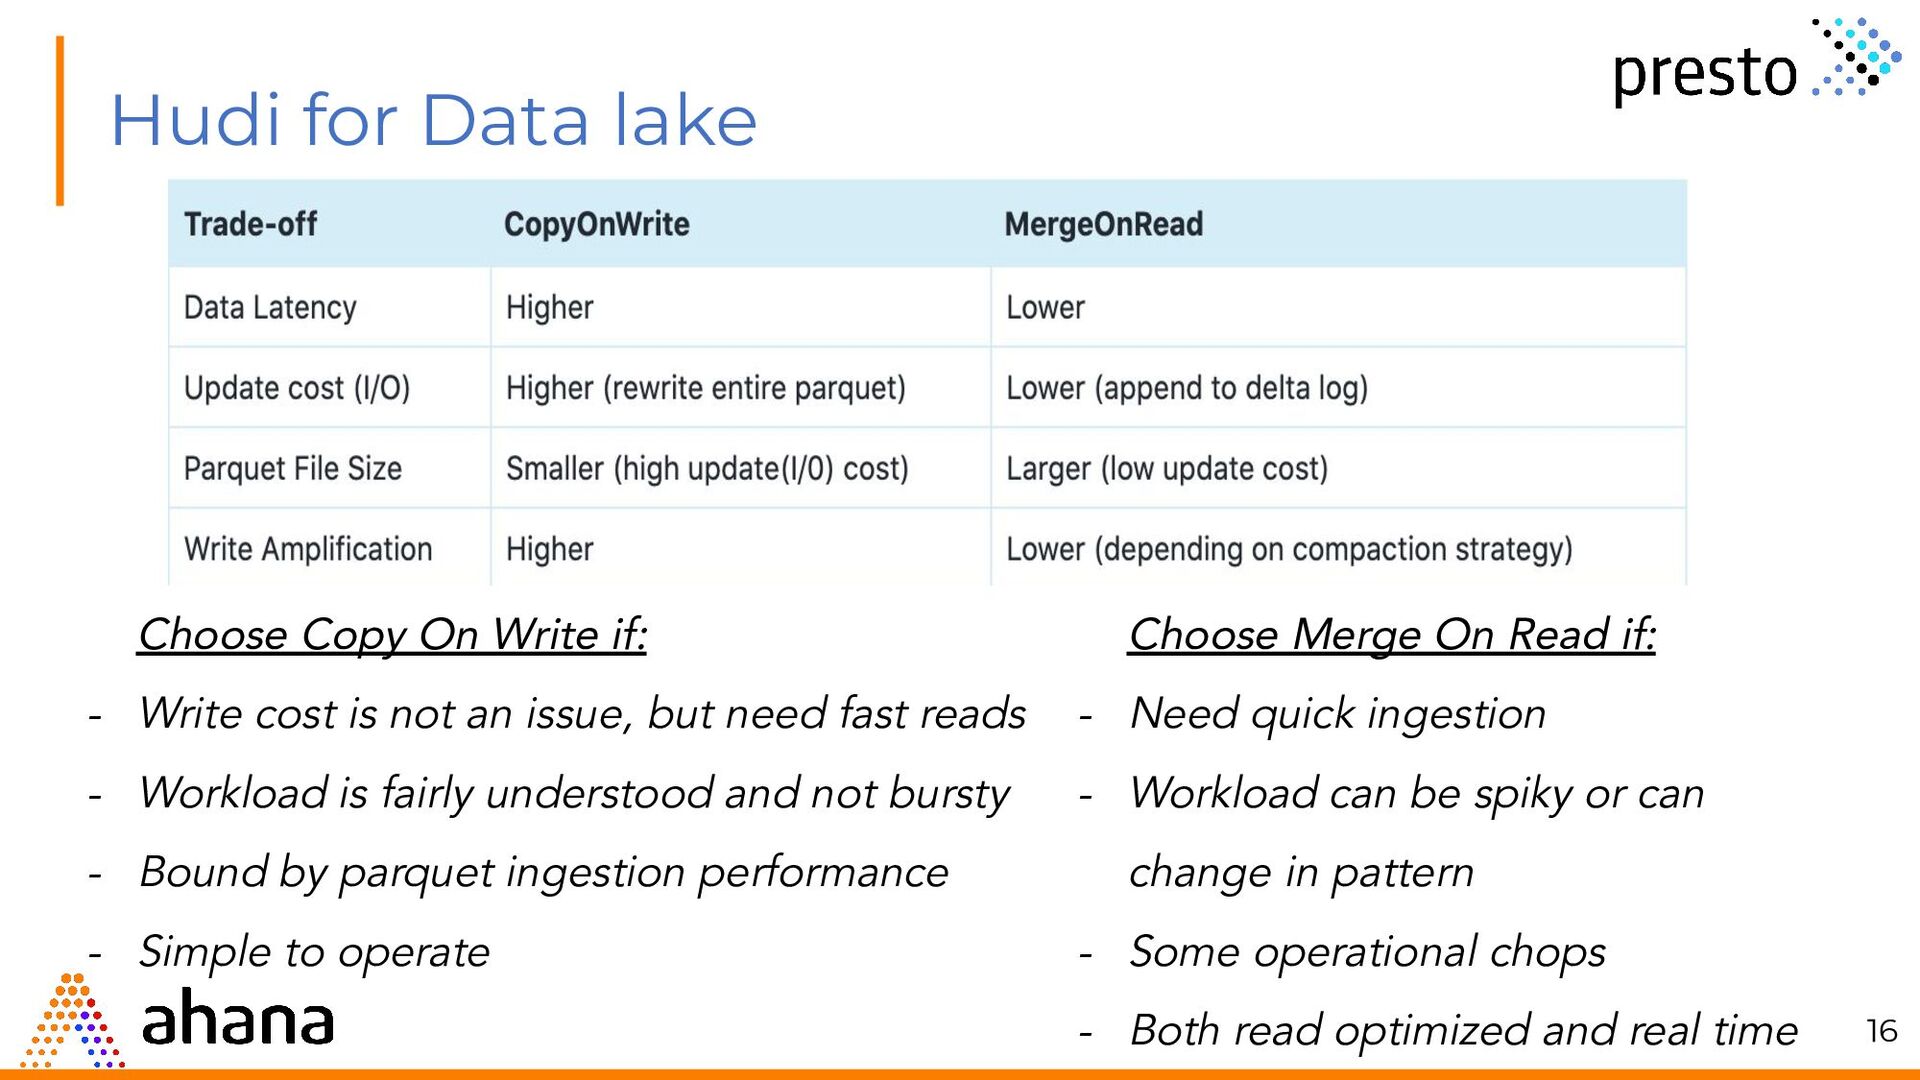
Hudi for Data lake 16 Choose Copy On Write if:
- Write cost is not an issue, but need fast reads - Workload is fairly understood and not bursty - Bound by parquet ingestion performance - Simple to operate Choose Merge On Read if: - Need quick ingestion - Workload can be spiky or can change in pattern - Some operational chops - Both read optimized and real time -
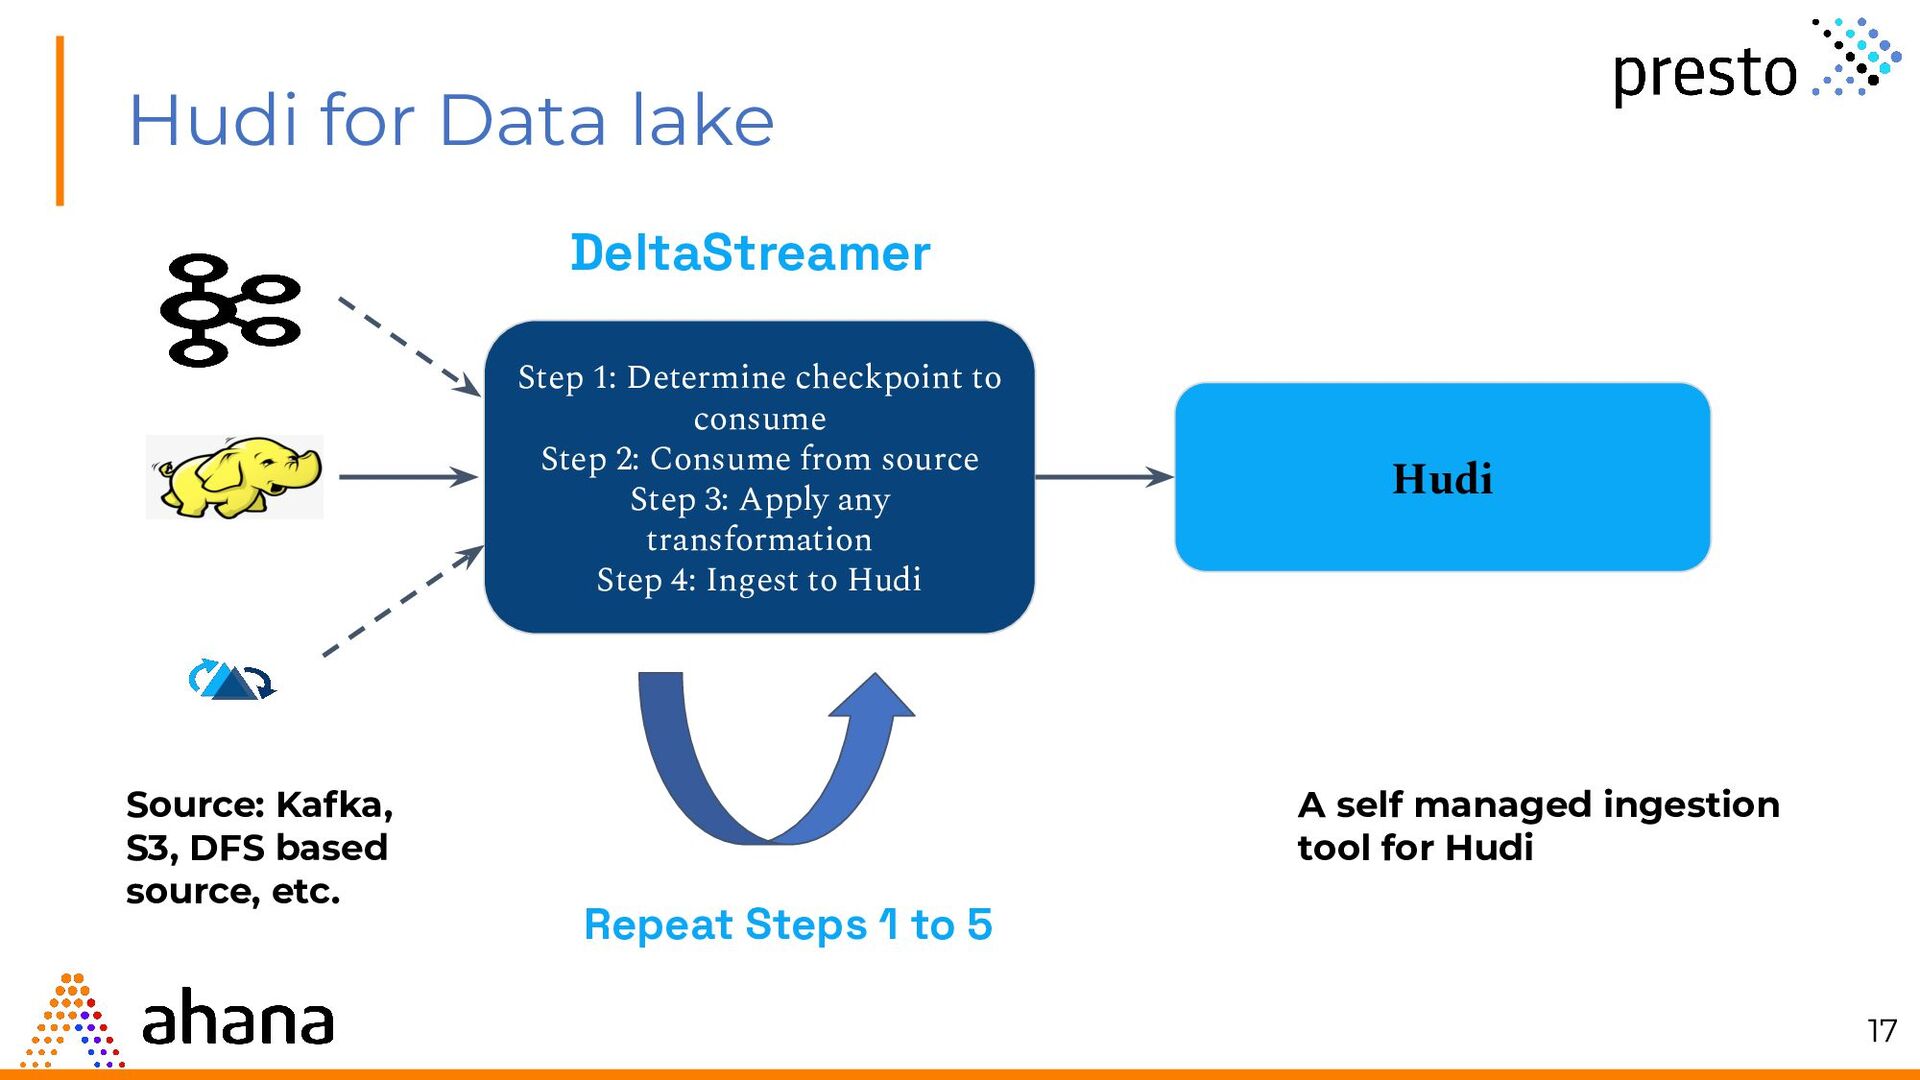
17 Hudi Step 1: Determine checkpoint to consume Step 2:
Consume from source Step 3: Apply any transformation Step 4: Ingest to Hudi DeltaStreamer Repeat Steps 1 to 5 Source: Kafka, S3, DFS based source, etc. A self managed ingestion tool for Hudi Hudi for Data lake -
Data streamer utility 18 A Self Managed Ingestion tool to
ingest data into Hudi - Checkpointing - Various connectors like Kafka, DFS Log Files, Upstream tables … - Fault tolerant and reliable (auto rollbacks) - Automatic cleaning and compaction. - Filtering & SQL based transformation - Multi table ingestion - Sync Once or Continuous Mode -
The Hudi Platform 19 Lake Storage (Cloud Object Stores, HDFS,
…) Open File/Data Formats (Parquet, HFile, Avro, Orc, …) Concurrency Control (OCC, MVCC, Non-blocking, Lock providers, Orchestration, Scheduling...) Table Services (cleaning, compaction, clustering, indexing, file sizing,...) Indexes (Bloom filter, HBase, Bucket index, Hash based, Lucene..) Table Format (Schema, File listings, Stats, Evolution, …) Lake Cache (Columnar, transactional, mutable, WIP,...) Metaserver (Stats, table service coordination,...) SQL Query Engines (Spark, Flink, Hive, Presto, Trino, Impala, Redshift, BigQuery, Snowflake,..) Platform Services (Streaming/Batch ingest, various sources, Catalog sync, Admin CLI, Data Quality,...) Transactional Database Layer Execution/Runtimes -
Ahana Cloud For Presto 1. Zero to Presto in 30
Minutes. Managed cloud service: No installation and configuration. 2. Built for data teams of all experience level. 3. Moderate level of control of deployment without complexity. 4. Dedicated support from Presto experts. -
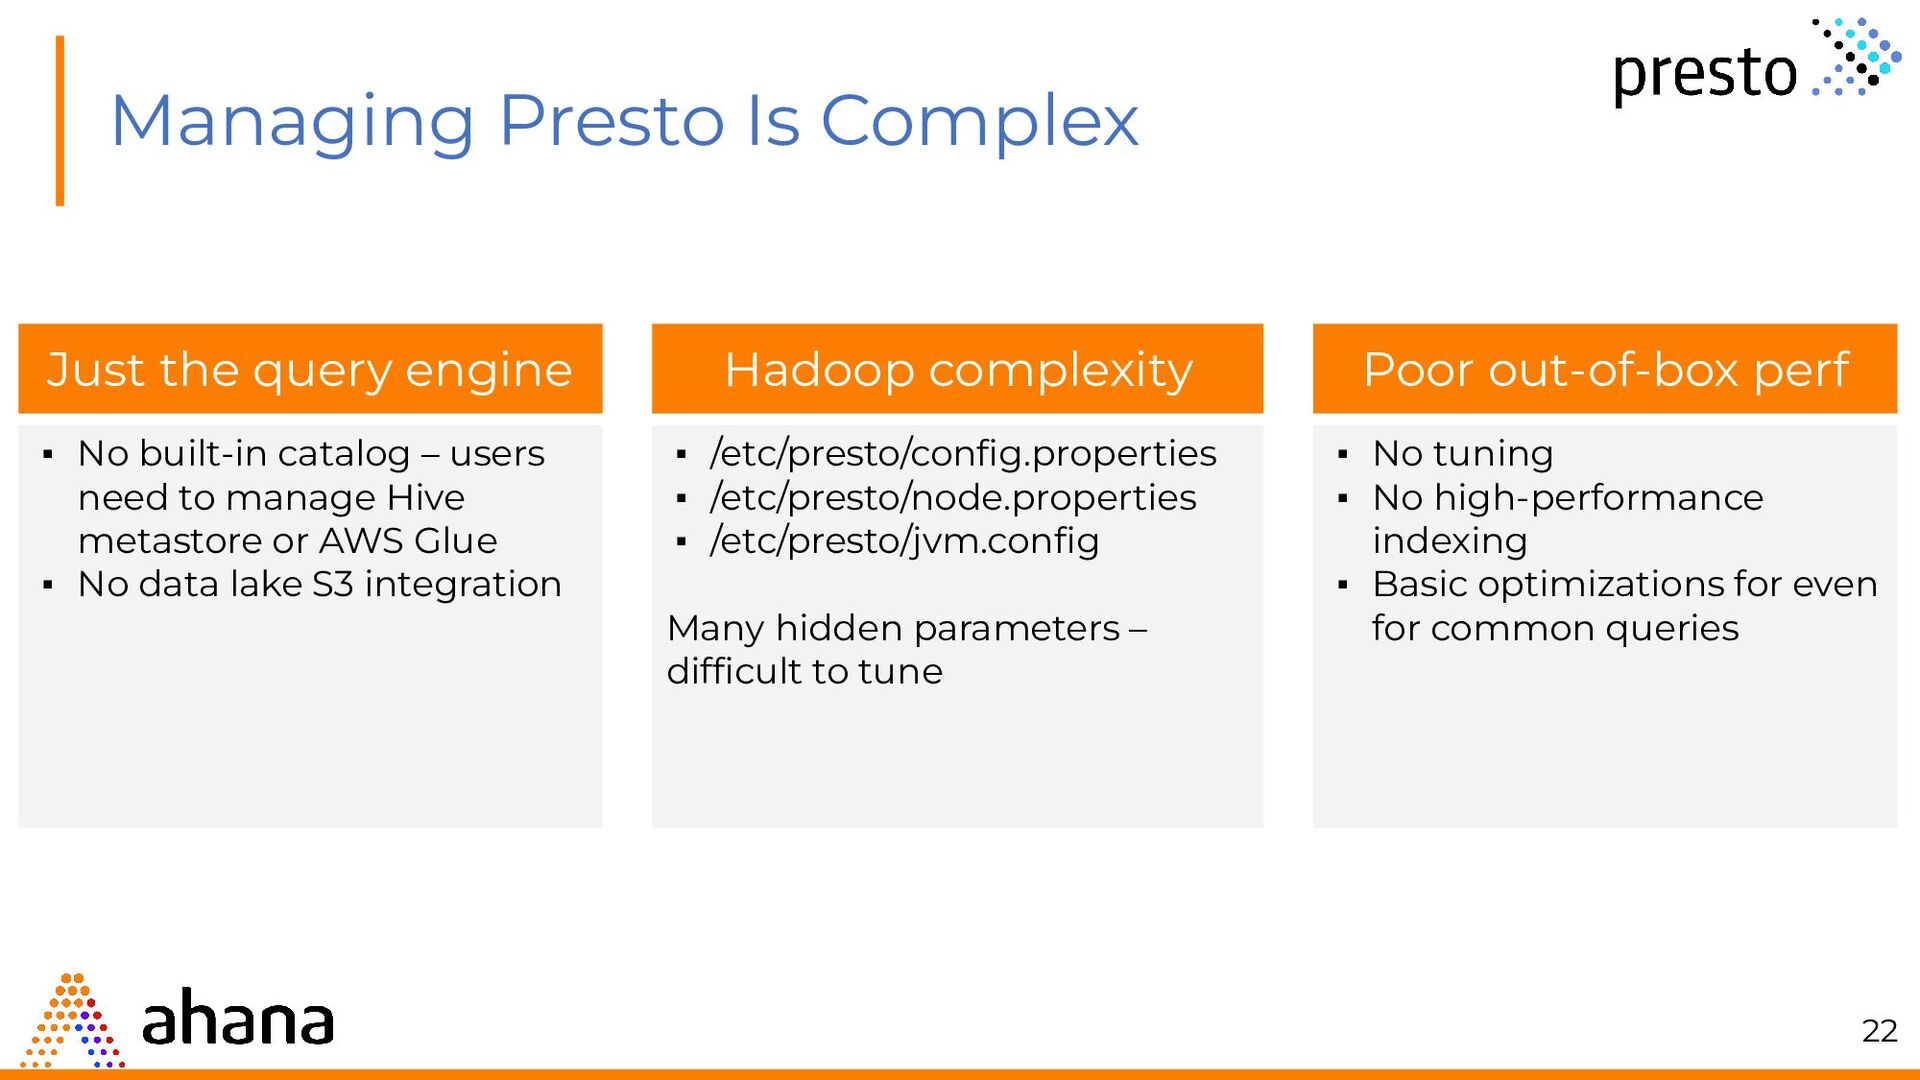
Managing Presto Is Complex Hadoop complexity ▪ /etc/presto/config.properties ▪ /etc/presto/node.properties
▪ /etc/presto/jvm.config Many hidden parameters – difficult to tune Just the query engine ▪ No built-in catalog – users need to manage Hive metastore or AWS Glue ▪ No data lake S3 integration Poor out-of-box perf ▪ No tuning ▪ No high-performance indexing ▪ Basic optimizations for even for common queries 22 -
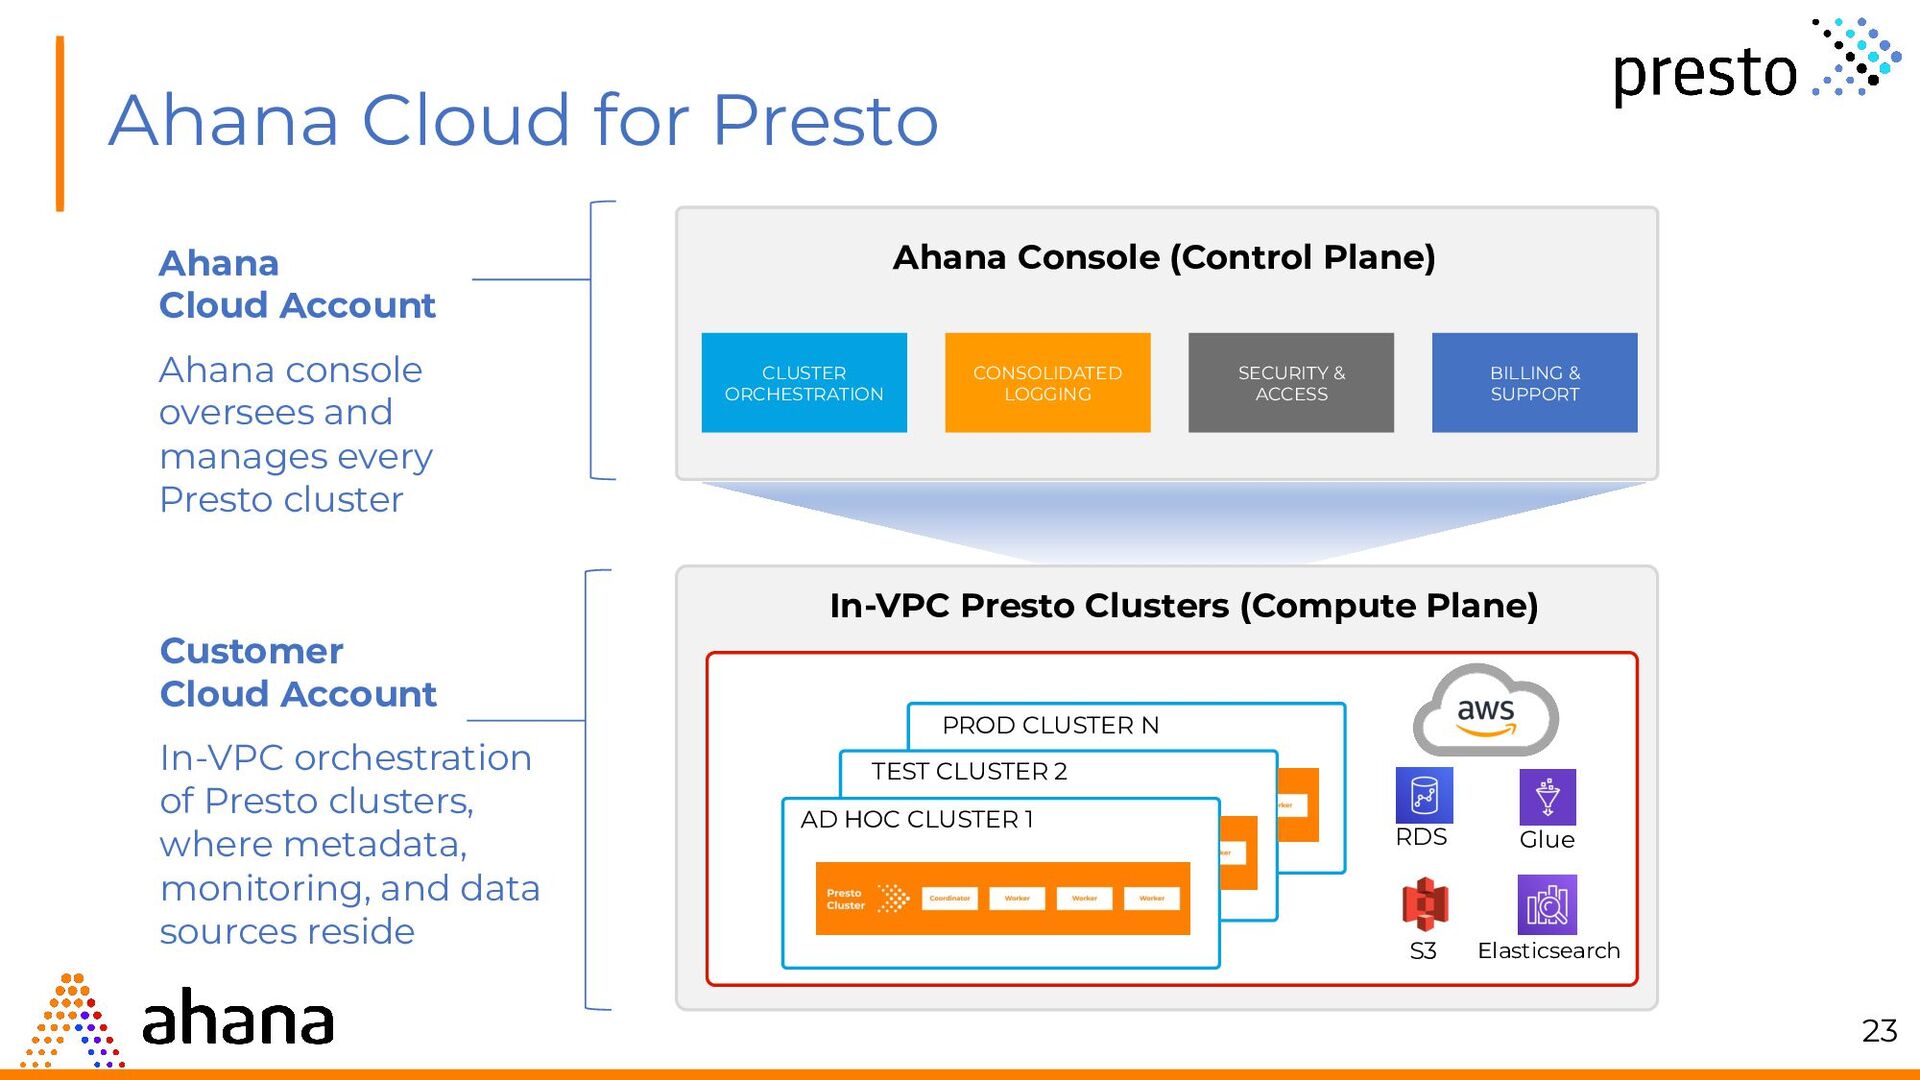
Ahana Console (Control Plane) CLUSTER ORCHESTRATION CONSOLIDATED LOGGING SECURITY &
ACCESS BILLING & SUPPORT In-VPC Presto Clusters (Compute Plane) AD HOC CLUSTER 1 TEST CLUSTER 2 PROD CLUSTER N Glue S3 RDS Elasticsearch Ahana Cloud Account Ahana console oversees and manages every Presto cluster Customer Cloud Account In-VPC orchestration of Presto clusters, where metadata, monitoring, and data sources reside Ahana Cloud for Presto 23 -
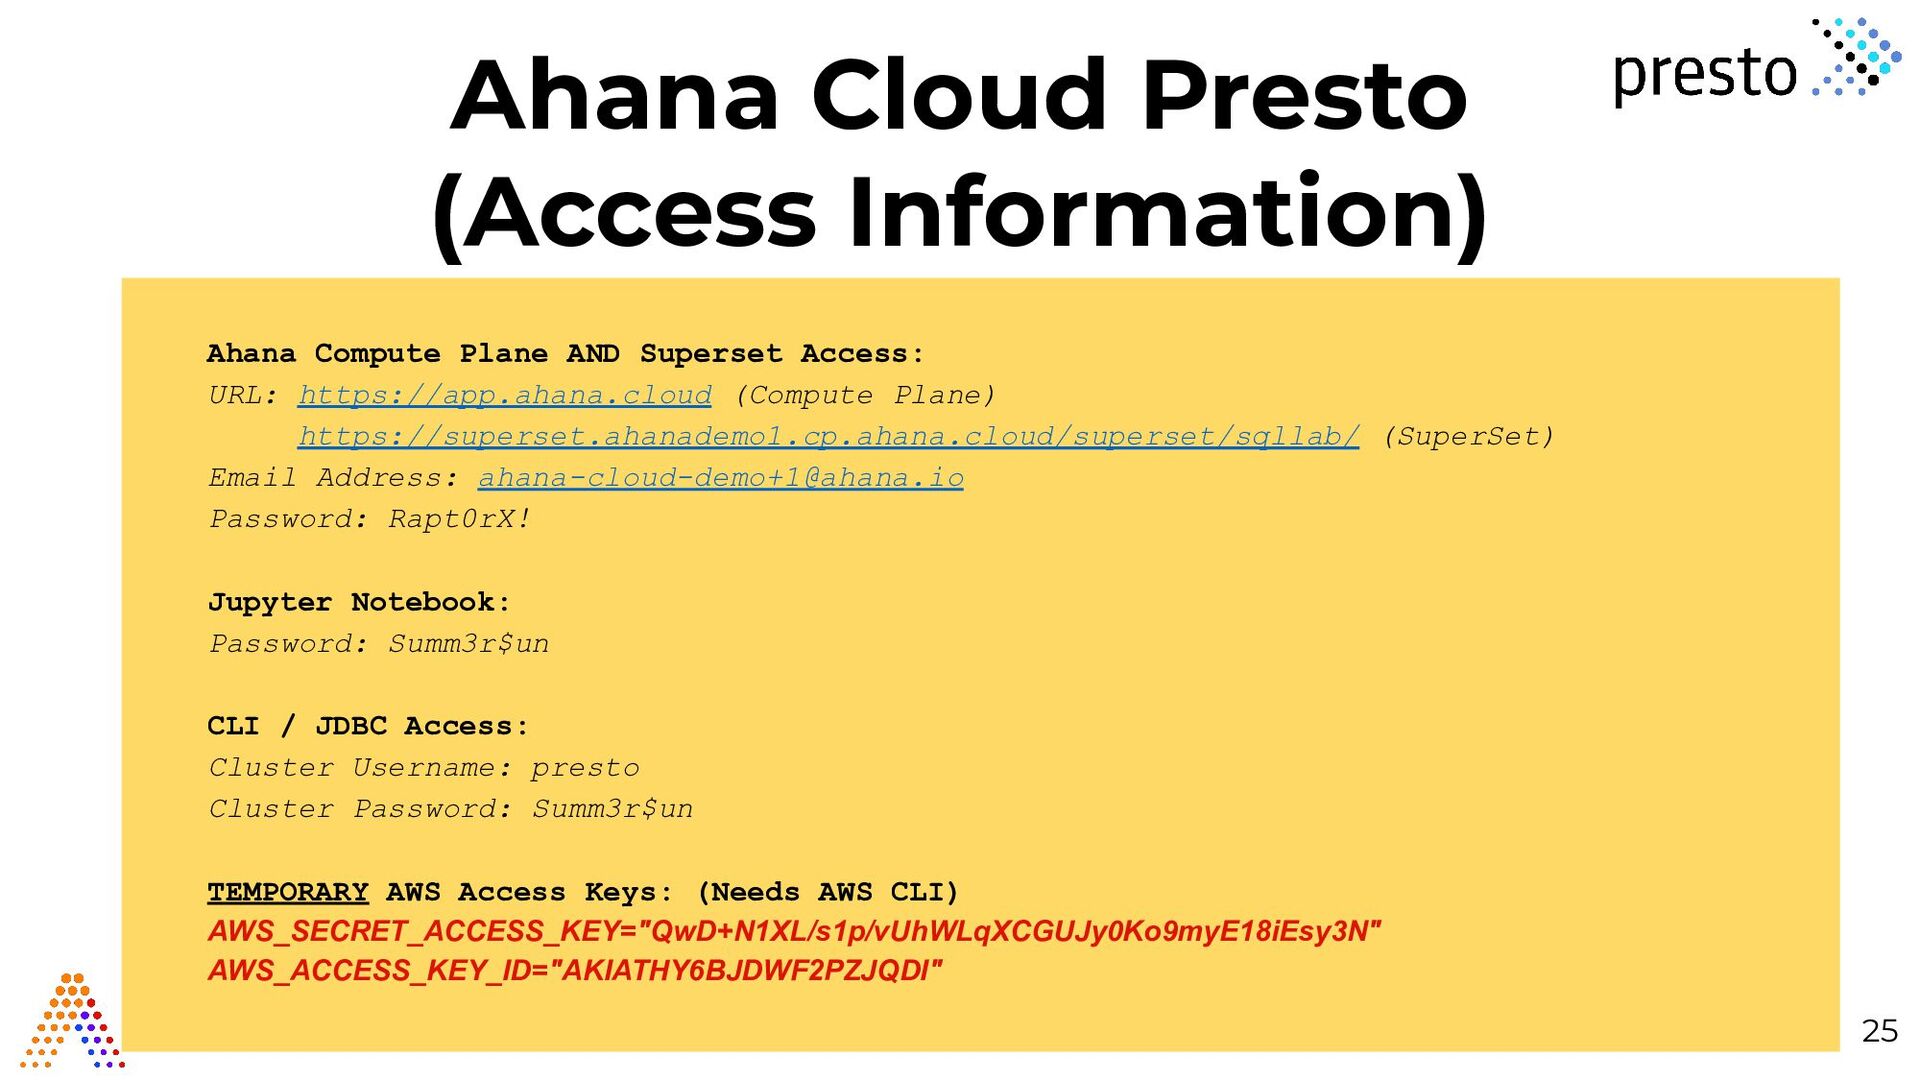
Ahana Cloud Presto (Access Information) 25 Ahana Compute Plane AND
Superset Access: URL: https://app.ahana.cloud (Compute Plane) https://superset.ahanademo1.cp.ahana.cloud/superset/sqllab/ (SuperSet) Email Address: [email protected] Password: Rapt0rX! Jupyter Notebook: Password: Summ3r$un CLI / JDBC Access: Cluster Username: presto Cluster Password: Summ3r$un TEMPORARY AWS Access Keys: (Needs AWS CLI) AWS_SECRET_ACCESS_KEY="QwD+N1XL/s1p/vUhWLqXCGUJy0Ko9myE18iEsy3N" AWS_ACCESS_KEY_ID="AKIATHY6BJDWF2PZJQDI" -
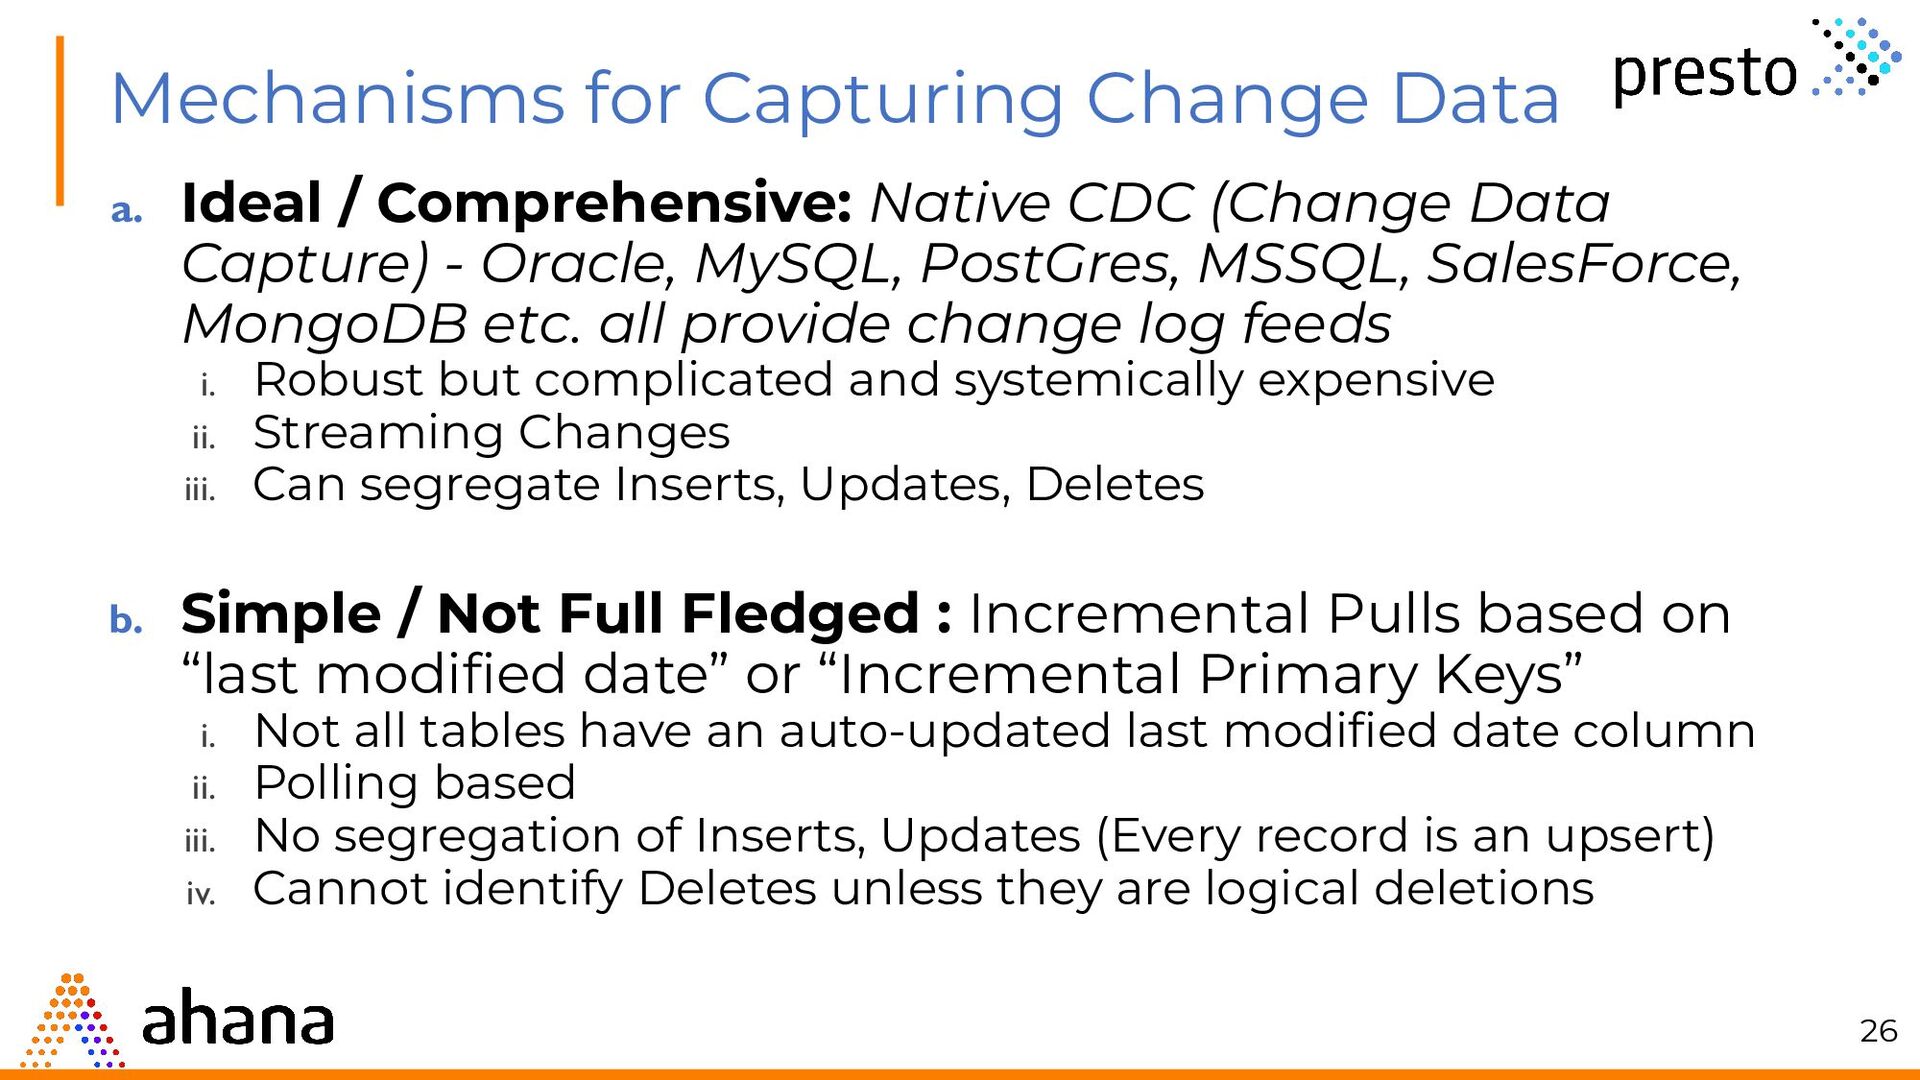
Mechanisms for Capturing Change Data a. Ideal / Comprehensive: Native
CDC (Change Data Capture) - Oracle, MySQL, PostGres, MSSQL, SalesForce, MongoDB etc. all provide change log feeds i. Robust but complicated and systemically expensive ii. Streaming Changes iii. Can segregate Inserts, Updates, Deletes b. Simple / Not Full Fledged : Incremental Pulls based on “last modified date” or “Incremental Primary Keys” i. Not all tables have an auto-updated last modified date column ii. Polling based iii. No segregation of Inserts, Updates (Every record is an upsert) iv. Cannot identify Deletes unless they are logical deletions 26 -
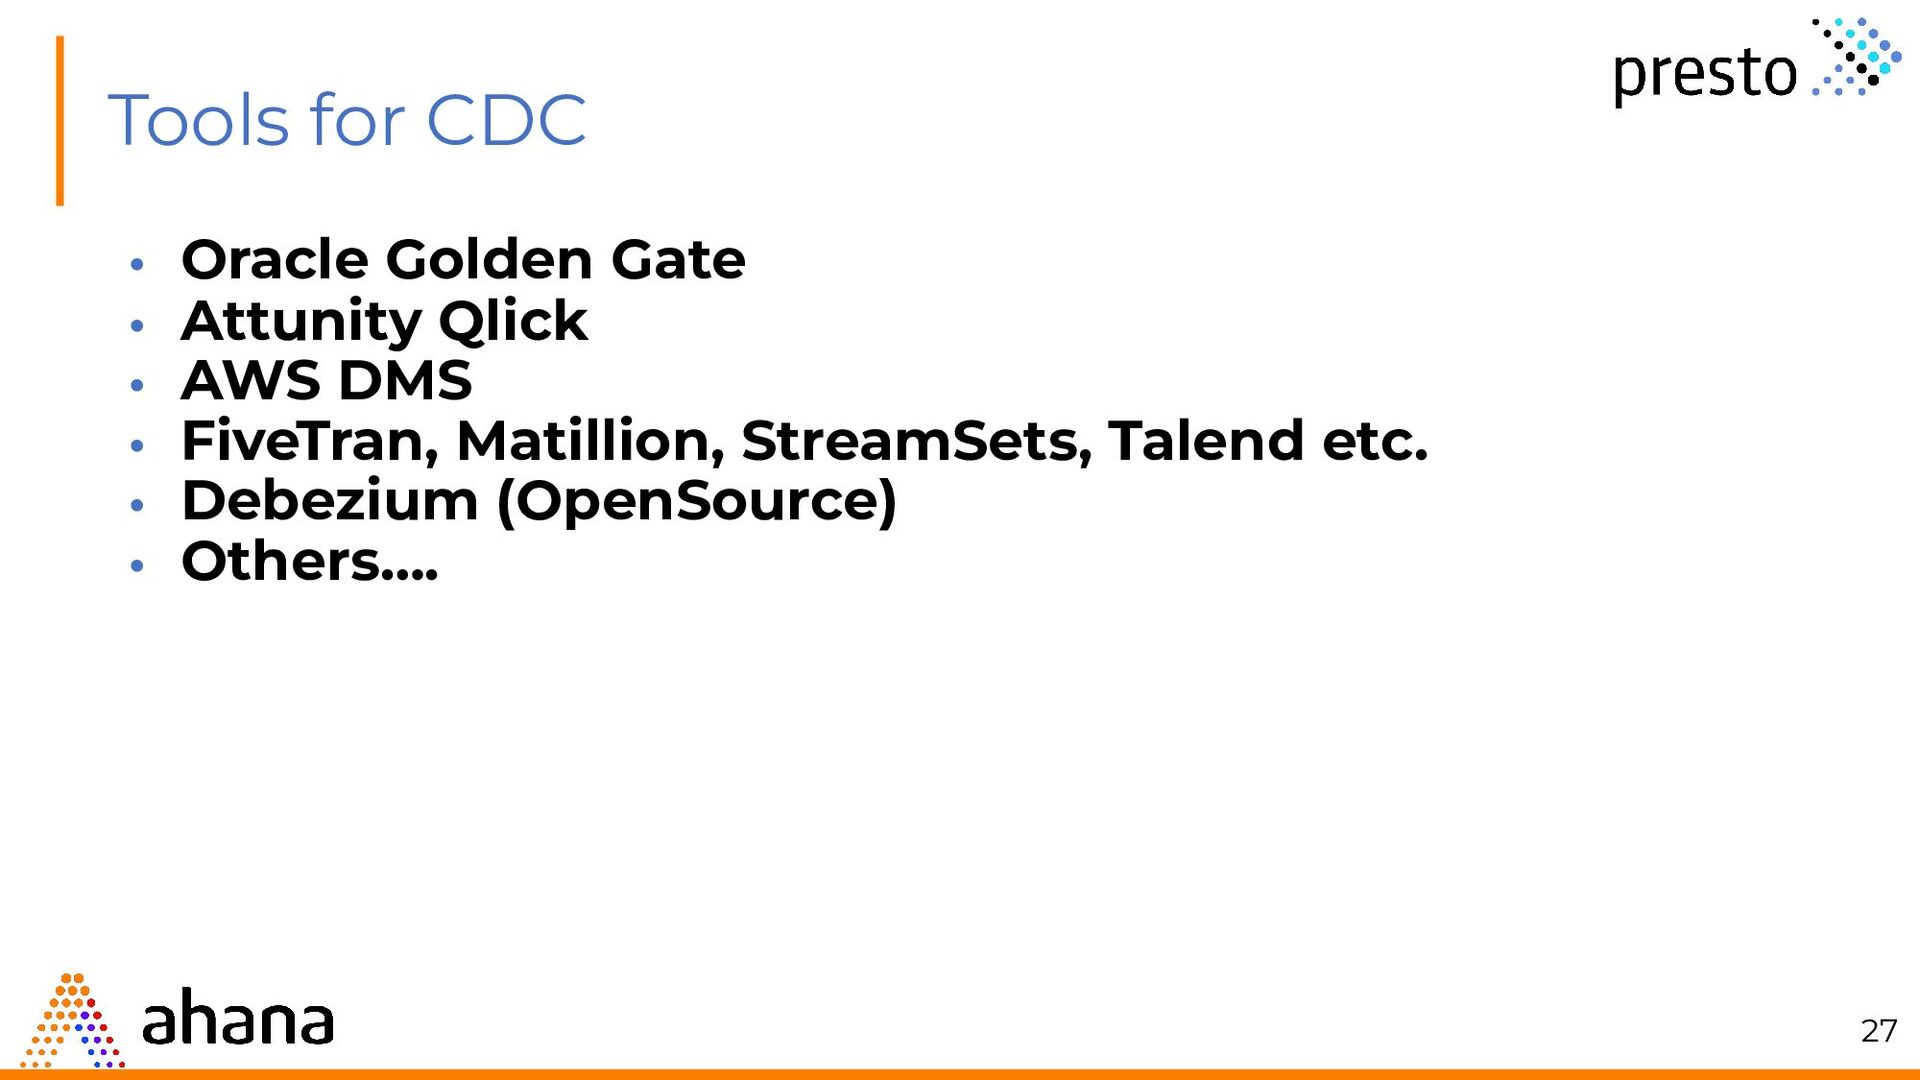
Tools for CDC • Oracle Golden Gate • Attunity Qlick
• AWS DMS • FiveTran, Matillion, StreamSets, Talend etc. • Debezium (OpenSource) • Others…. 27 -
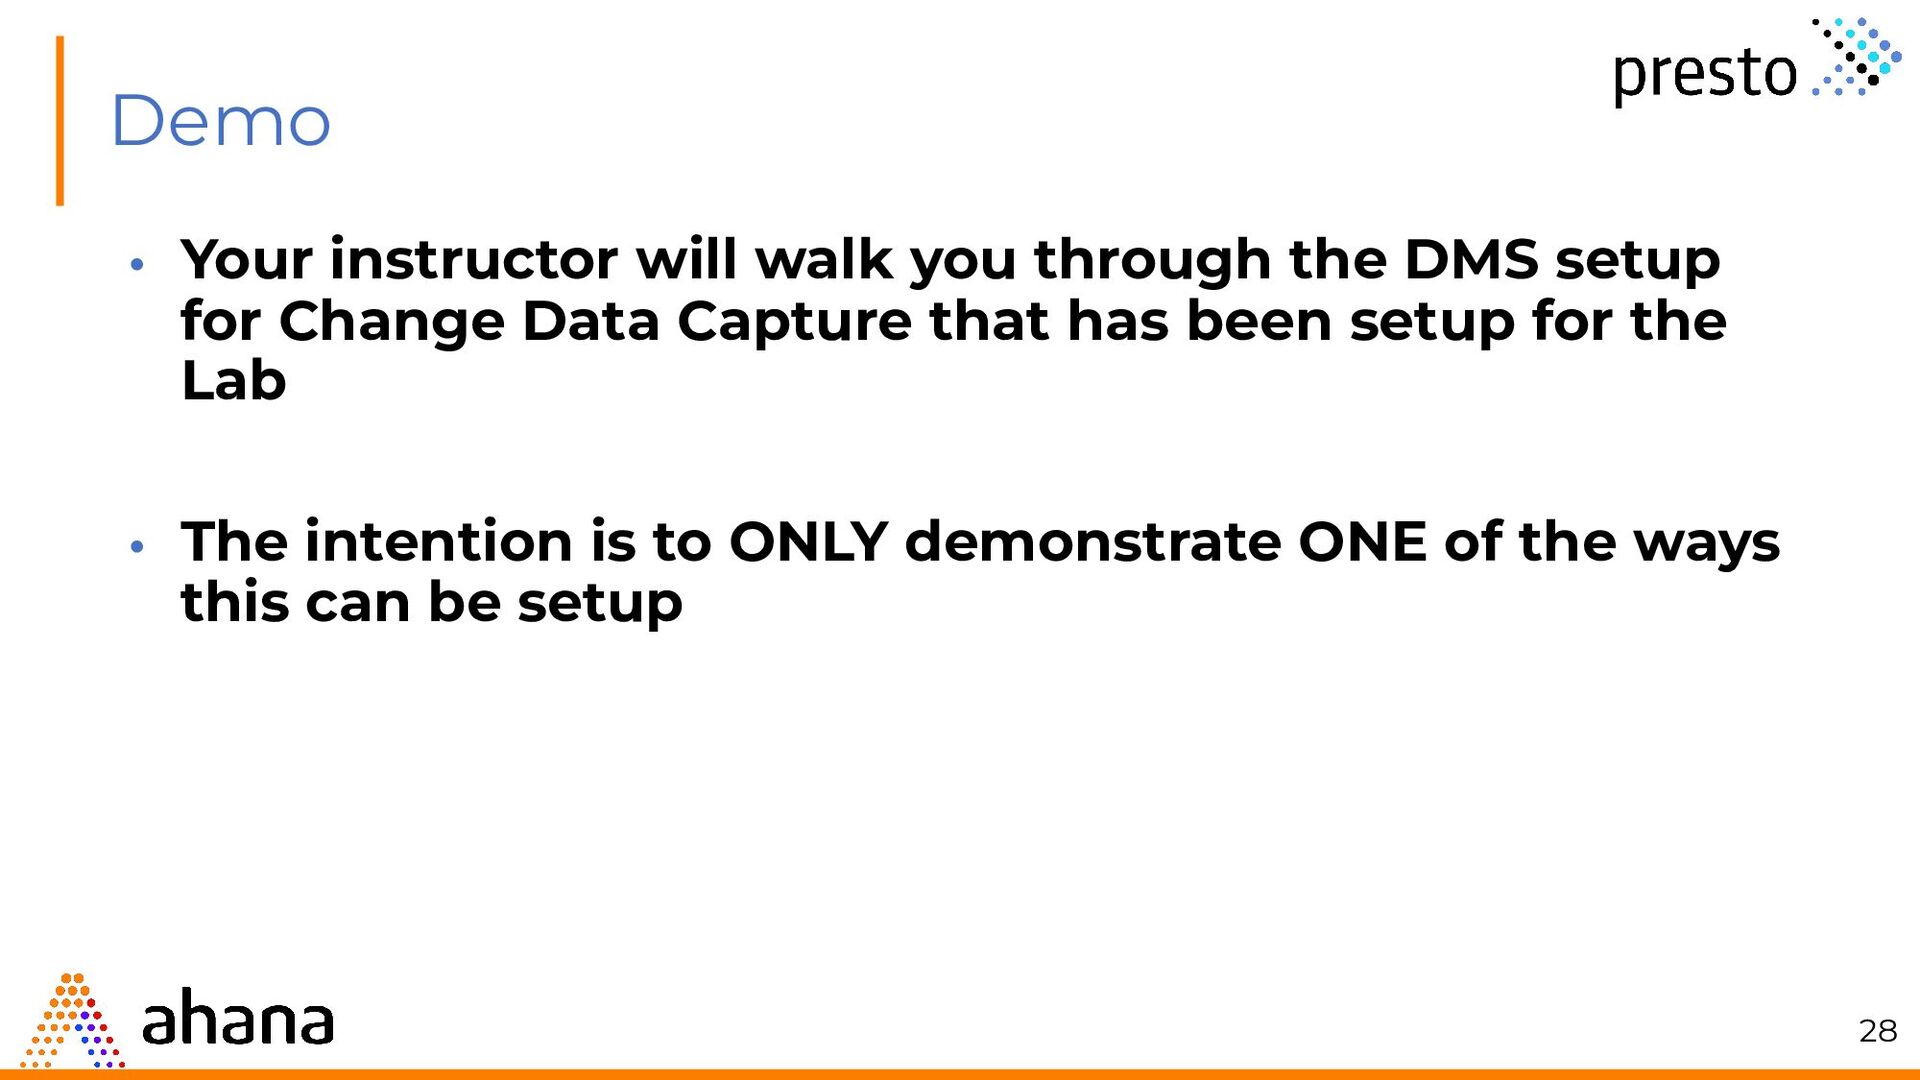
Demo • Your instructor will walk you through the DMS
setup for Change Data Capture that has been setup for the Lab • The intention is to ONLY demonstrate ONE of the ways this can be setup 28 -
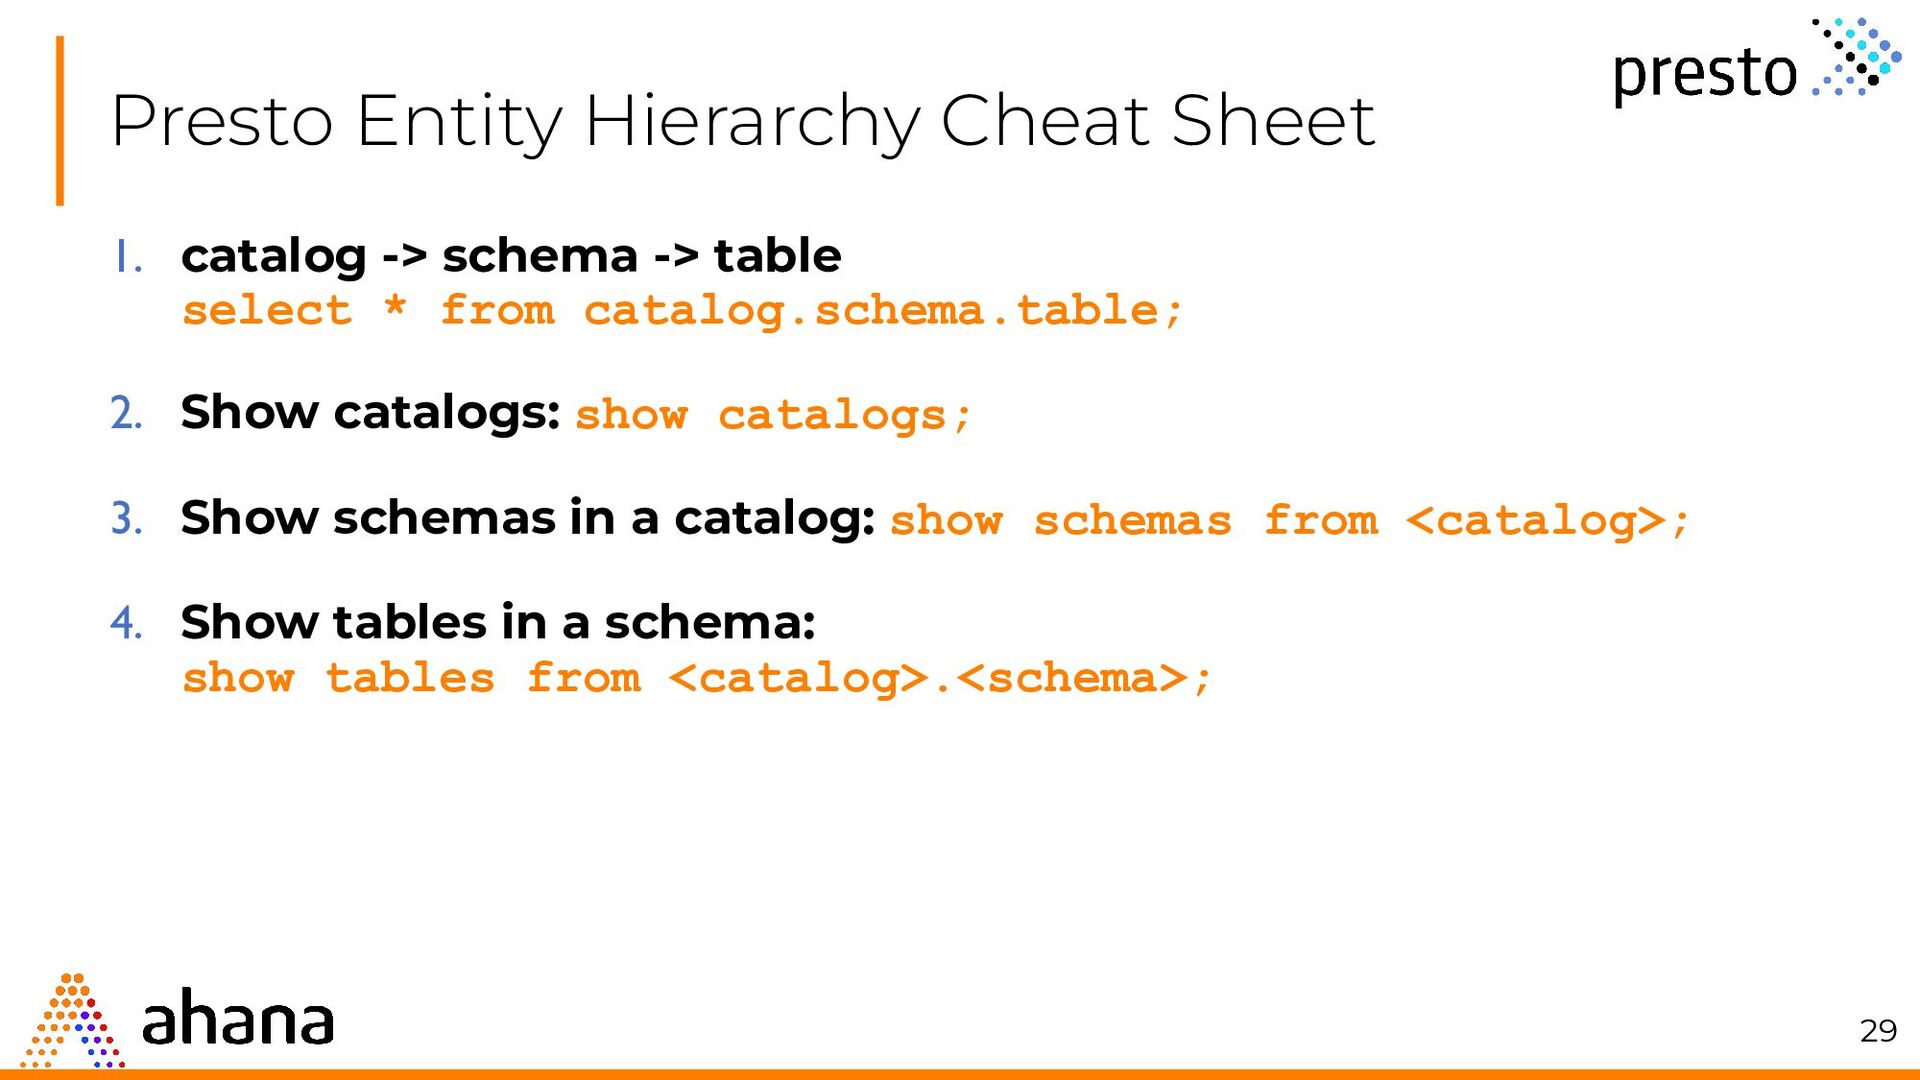
Presto Entity Hierarchy Cheat Sheet 29 1. catalog -> schema
-> table select * from catalog.schema.table; 2. Show catalogs: show catalogs; 3. Show schemas in a catalog: show schemas from <catalog>; 4. Show tables in a schema: show tables from <catalog>.<schema>; -
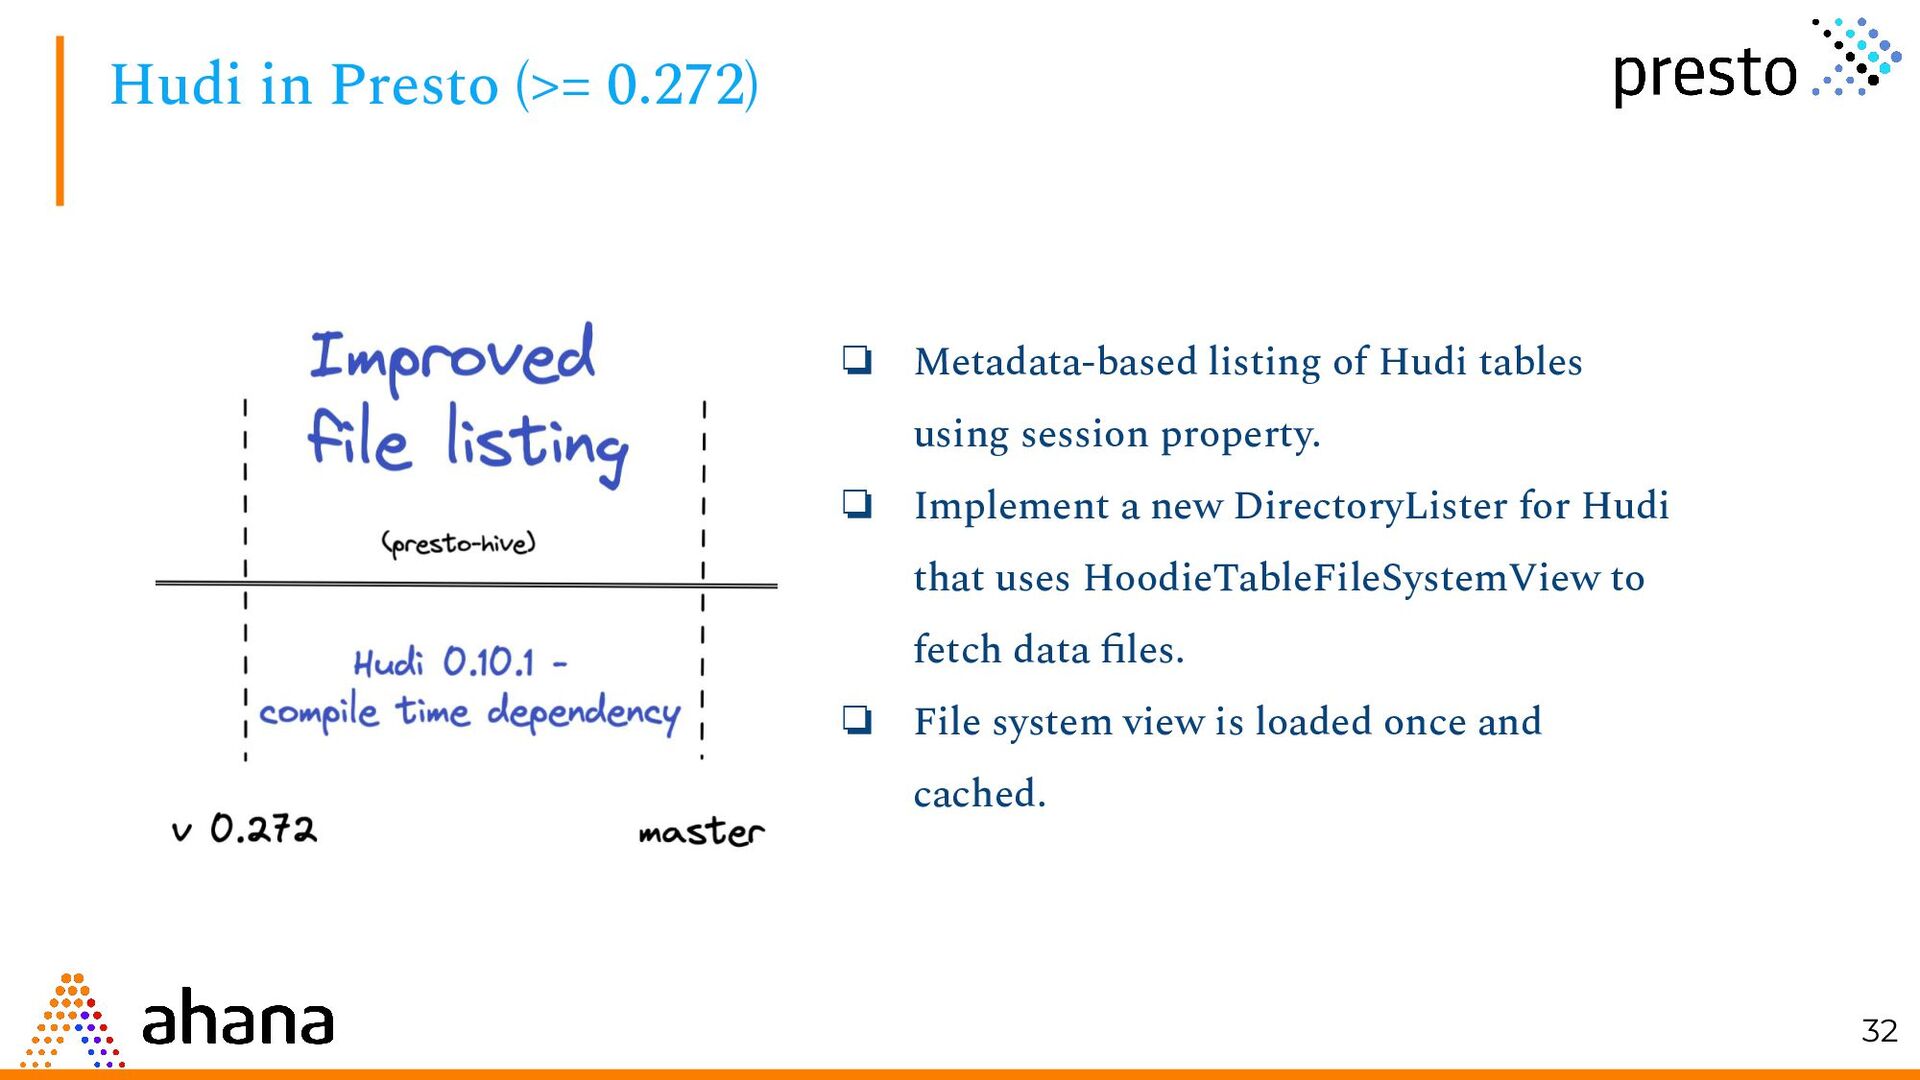
Hudi in Presto (>= 0.272) 32 ❏ Metadata-based listing of
Hudi tables using session property. ❏ Implement a new DirectoryLister for Hudi that uses HoodieTableFileSystemView to fetch data files. ❏ File system view is loaded once and cached. -
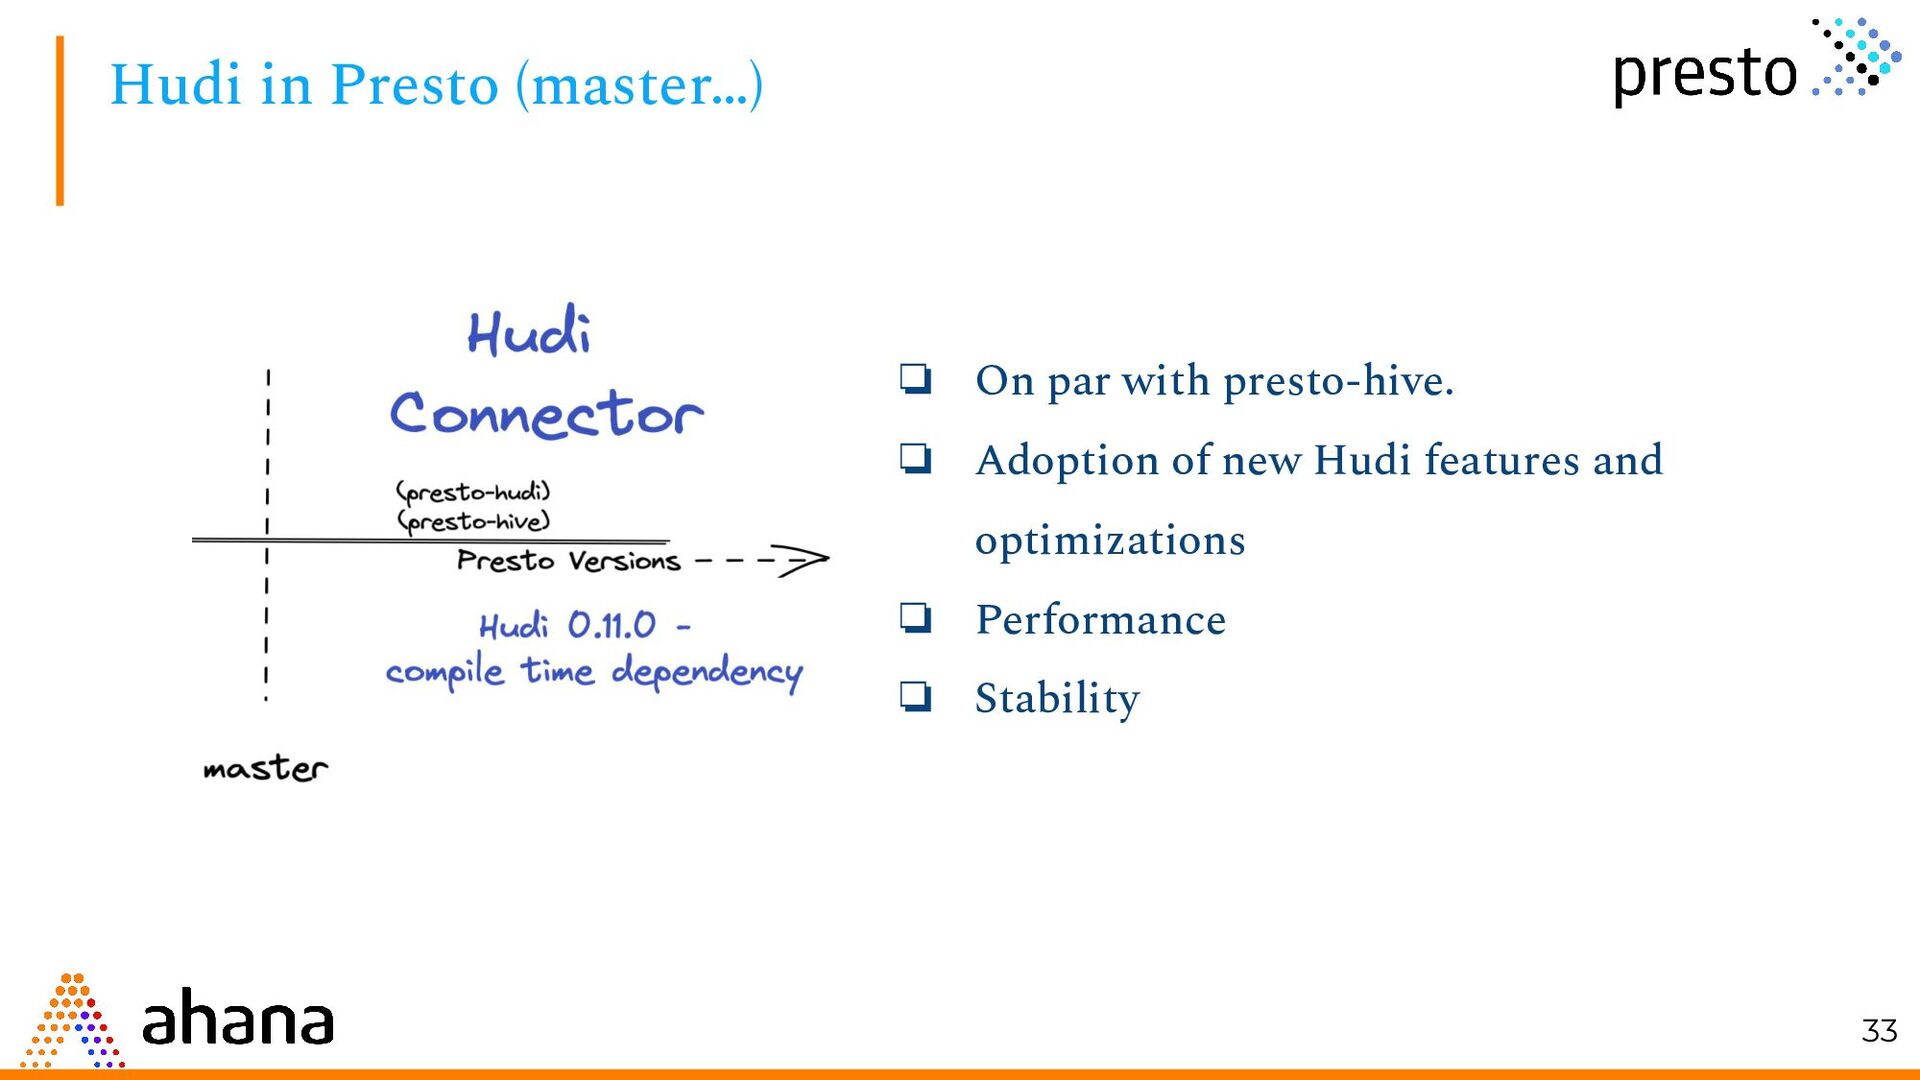
Hudi in Presto (master…) 33 ❏ On par with presto-hive.
❏ Adoption of new Hudi features and optimizations ❏ Performance ❏ Stability -
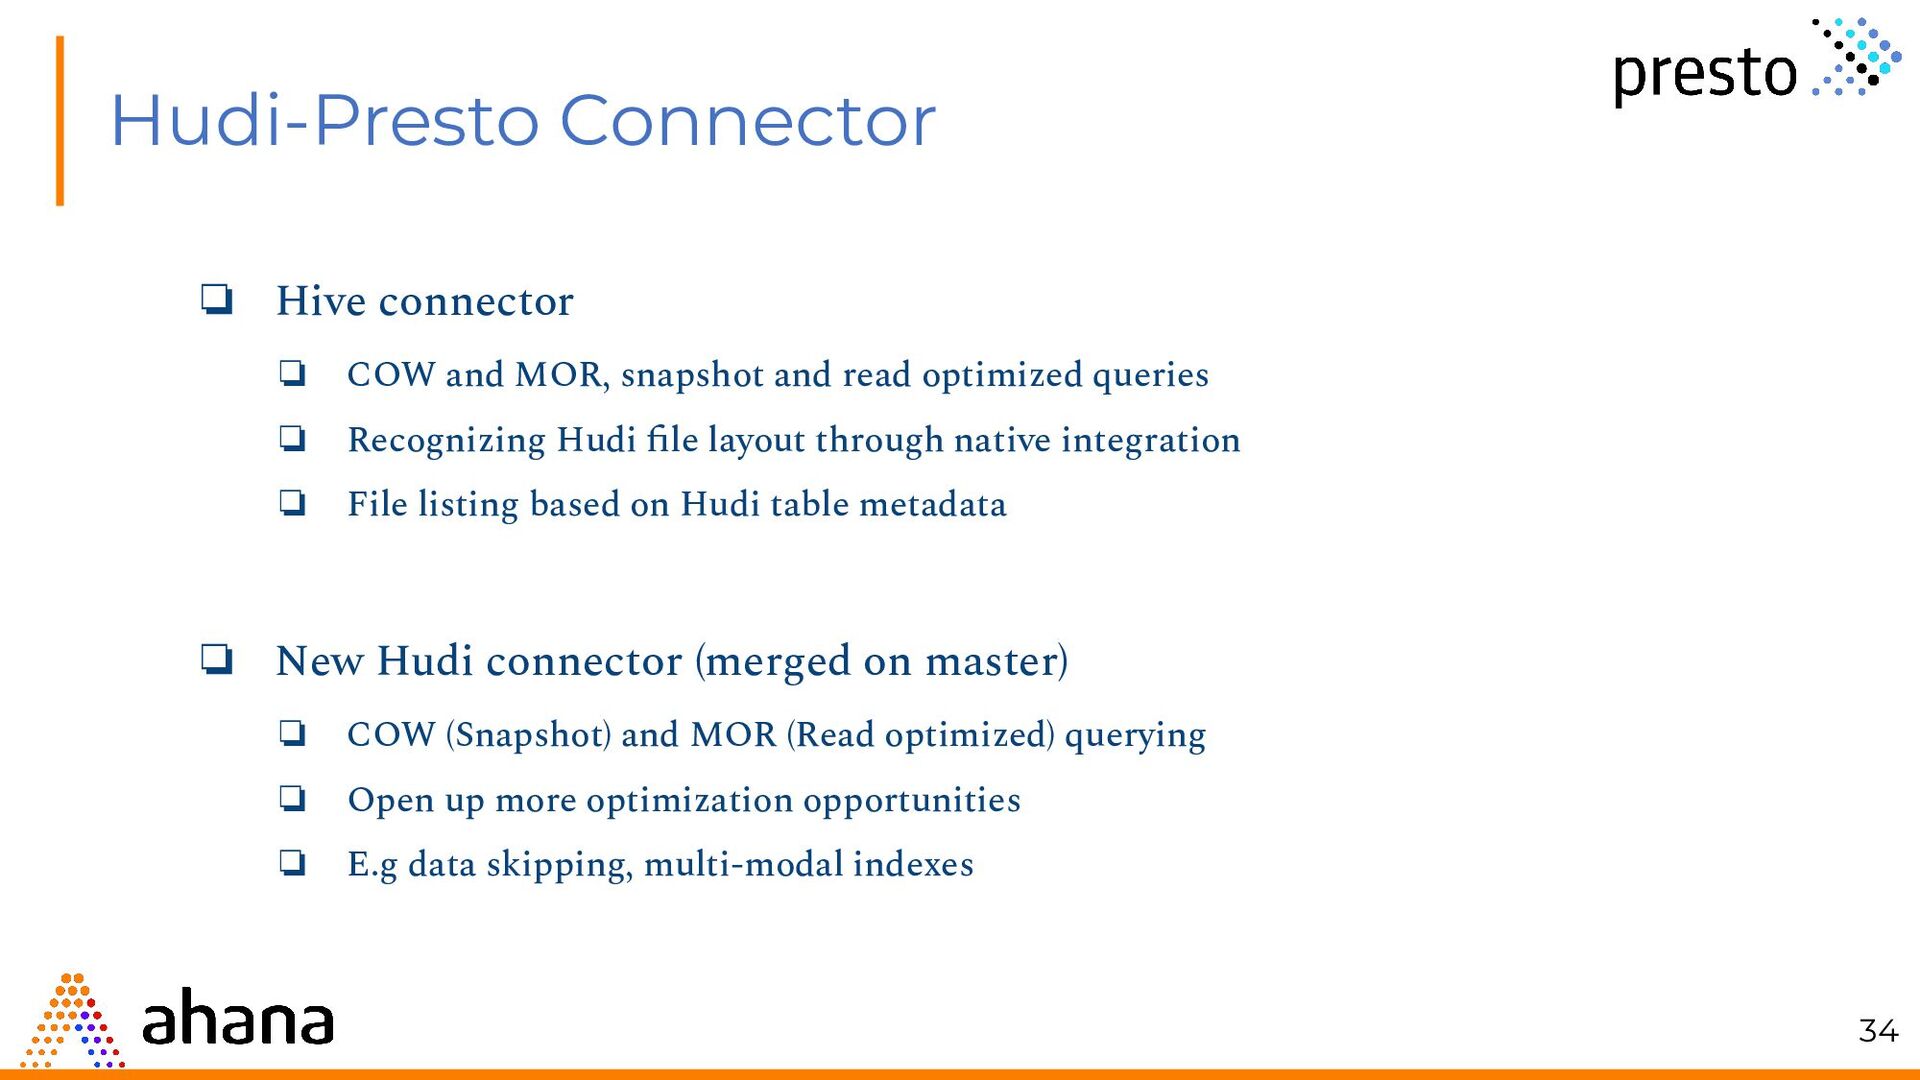
Hudi-Presto Connector ❏ Hive connector ❏ COW and MOR, snapshot
and read optimized queries ❏ Recognizing Hudi file layout through native integration ❏ File listing based on Hudi table metadata ❏ New Hudi connector (merged on master) ❏ COW (Snapshot) and MOR (Read optimized) querying ❏ Open up more optimization opportunities ❏ E.g data skipping, multi-modal indexes 34 -
Adoption of new Hudi features Metadata Table - Efficient metadata
fetching - Uses HFile for faster scans - Eliminate recursive file listing operations - Pruning using column stats Clustering (Optimize data layout alongside ingestion) - Problem 1: faster ingestion -> smaller file sizes - Problem 2: data locality for query (e.g., by city) ≠ ingestion order (e.g., trips by time) - Auto sizing, reorg data, no compromise on ingestion - Fancy space curves able to show 90% reduction in # rows scanned 35 -
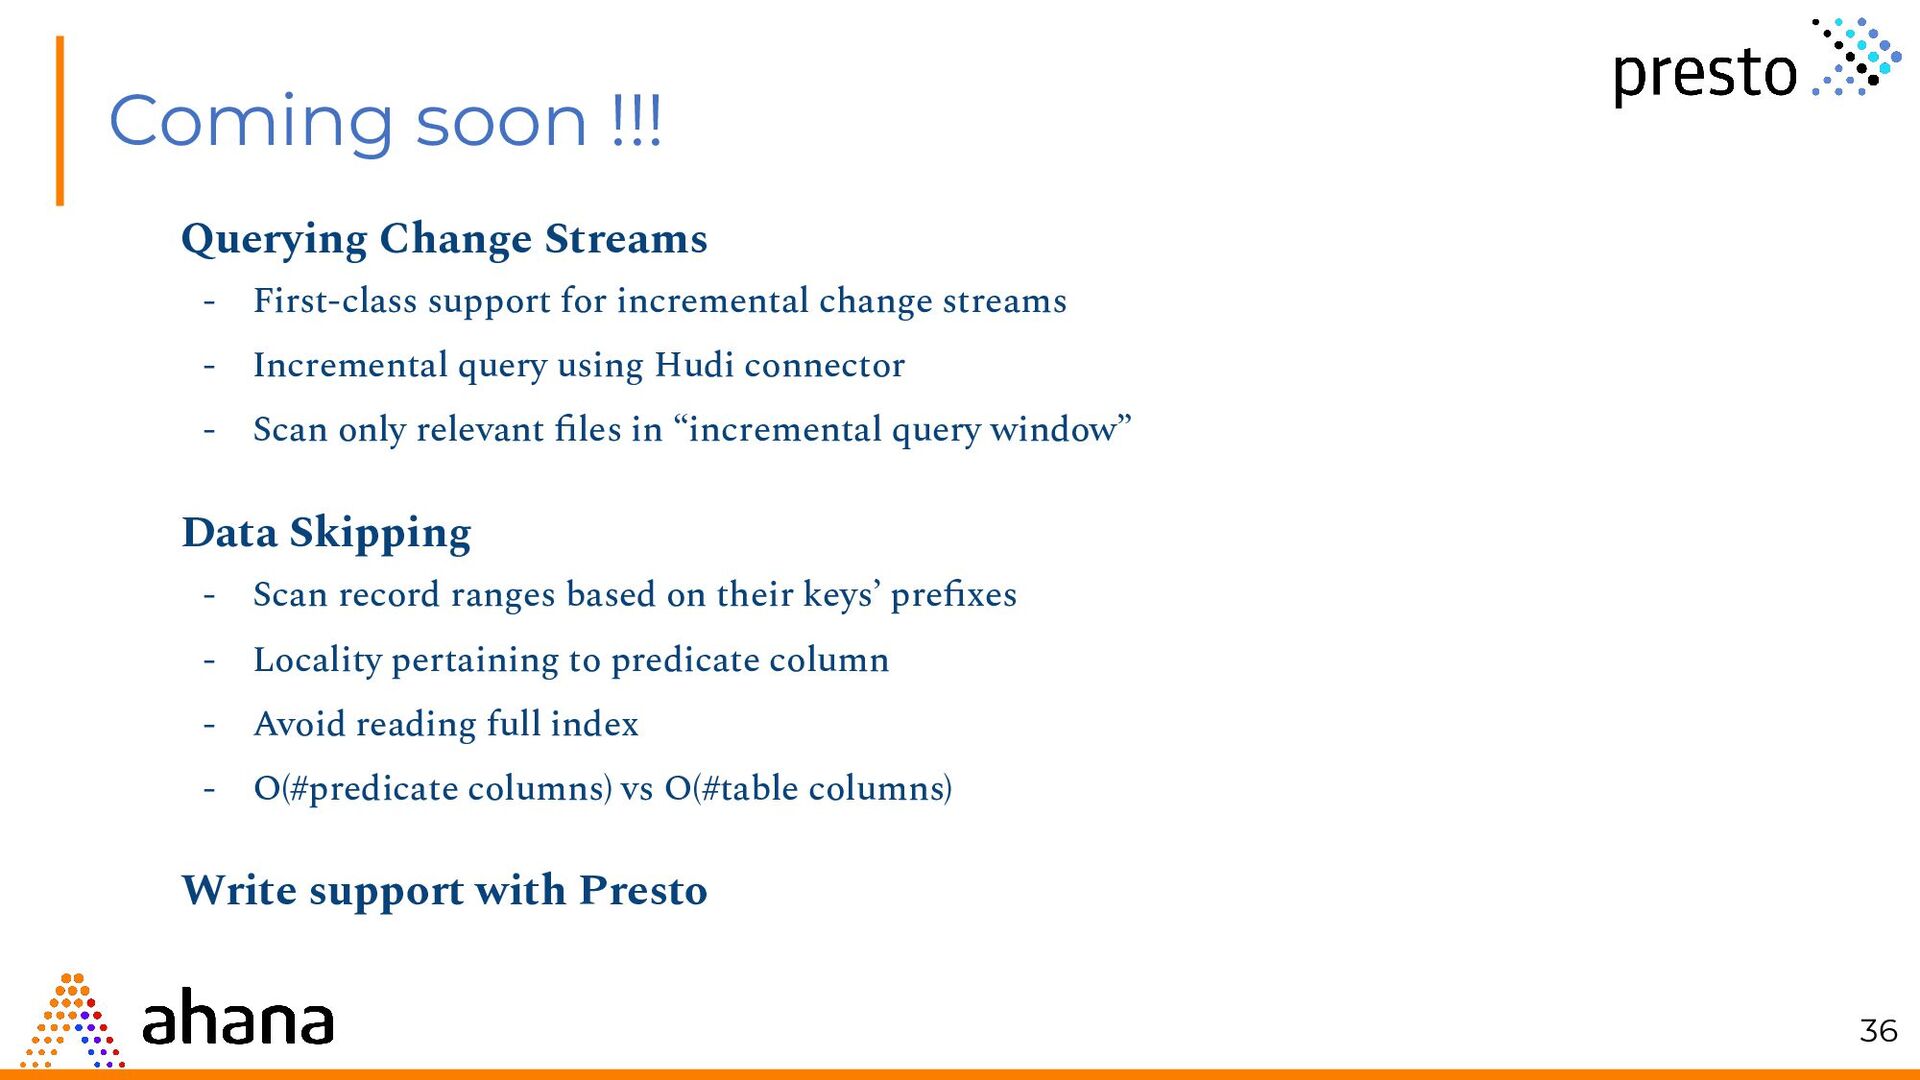
Coming soon !!! Querying Change Streams - First-class support for
incremental change streams - Incremental query using Hudi connector - Scan only relevant files in “incremental query window” Data Skipping - Scan record ranges based on their keys’ prefixes - Locality pertaining to predicate column - Avoid reading full index - O(#predicate columns) vs O(#table columns) Write support with Presto 36 -
Engage with the community User Docs : https://hudi.apache.org Technical Wiki
: https://cwiki.apache.org/confluence/display/HUDI Github : https://github.com/apache/hudi/ Twitter : https://twitter.com/apachehudi Mailing list(s) : [email protected] (send an empty email to subscribe) [email protected] (actual mailing list) Slack : https://join.slack.com/t/apache-hudi/signup Community Syncs : https://hudi.apache.org/community/syncs 37 -
Note about creating HUDI tables to Glue 1. To interact
directly via Glue ETL / Spark you need Glue HUDI connector from the Marketplace (Free) https://aws.amazon.com/marketplace/pp/prodview-6r ofemcq6erku 2. Alternatively you can create HUDI tables in Glue using: a. Glue API b. AWS Glue Command Line : https://docs.aws.amazon.com/cli/latest/reference/glue/create-ta ble.html c. Athena Web Console 38 -
Conclusion In this hands-on workshop you have: 1. Learned about
Ahana Cloud the easiest to use Presto experience in the cloud 2. Learned the Why and Hows of HUDI 39 -
Next Steps for You... • Ahana Cloud is available on
the AWS Marketplace • Try the sample code for your own tables • Sign-up for a 14-day free trial here: https://ahana.io/sign-up 40 -
How to get involved with Presto Join the Slack channel!
prestodb.slack.com Write a blog for prestodb.io! prestodb.io/blog Join the virtual meetup group & present! meetup.com/prestodb Contribute to the project! github.com/prestodb 42