Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Finetuning LLMs on consumer GPUs
Search
Aniket Maurya
November 07, 2023
Programming
190
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Finetuning LLMs on consumer GPUs
Aniket Maurya
November 07, 2023
More Decks by Aniket Maurya
See All by Aniket Maurya
Building RAG powered applications - PyData London 2nd April
aniketmaurya
0
68
Contributing to Lightning AI OSS
aniketmaurya
0
95
Other Decks in Programming
See All in Programming
残高管理から台帳サービスへの進化
artoy
1
200
APNsからLive Activityを開始する話
yumnumm
0
170
Agentic Software Factoryに、すごく賢いIF文を。 / super smart IF statement into the Agentic Software Factory.
rkaga
8
2.2k
Apple Intelligence を用いた個人情報誤送信防止、及びユーザーリクエスト体験の改善について
yukiny
0
350
動作中のプログラムの中身をリアルタイムに覗く / Realtime Debugger for CSharp with Roslyn
prota
1
1.9k
Next.js: The final boss of Web Performance
guaca
0
250
Compiling a real-world CLI tool to native with Static Hermes
tmikov2023
0
120
When benchmarks go bad - what I learned from measuring performance wrong
hollycummins
0
220
現場と育てるRailsモデリング 〜Spreadsheetから始めたモデル設計〜
siroemk
2
590
作れる、でも消せるか?──安全に「枯らして消す」機能削除術 / Drain, Then Delete
chobishiba
2
640
SREの越境 / SRE Collaboration
y0hgi
2
310
JAWS-UG 東京支部が始める、JAWS-UG支部コラボ / JAWS-UG lunchtime LT Collaboration
y0hgi
0
270
Featured
See All Featured
Thoughts on Productivity
jonyablonski
76
5.4k
Tips & Tricks on How to Get Your First Job In Tech
honzajavorek
1
800
How STYLIGHT went responsive
nonsquared
100
6.3k
A better future with KSS
kneath
240
18k
Design in an AI World
tapps
1
350
The agentic SEO stack - context over prompts
schlessera
0
970
Bootstrapping a Software Product
garrettdimon
PRO
306
120k
Avoiding the “Bad Training, Faster” Trap in the Age of AI
tmiket
0
270
Bridging the Design Gap: How Collaborative Modelling removes blockers to flow between stakeholders and teams @FastFlow conf
baasie
0
730
It's Worth the Effort
3n
188
29k
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
360
Easily Structure & Communicate Ideas using Wireframe
afnizarnur
194
17k
Transcript
November 2023 1. Finetuning LLMs on consumer GPUs 2. LLM
Evaluation framework and datasets 3. Deep Dive into Transformers 4. Effortlessly analyze multifaceted financial documents with LlamaIndex
Finetuning LLMs on custom datasets Aniket Maurya, Developer Advocate at
Lightning AI November 2023 X.com/aniketmaurya linkedin.com/in/aniketmaurya
• Overview of LLMs • Parameter efficient finetuning with instruction
dataset • Training on consumer GPUs Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 3 Agenda
What are LLMs Lightning AI ©2023 Proprietary and Confidential. All
Rights Reserved. 4
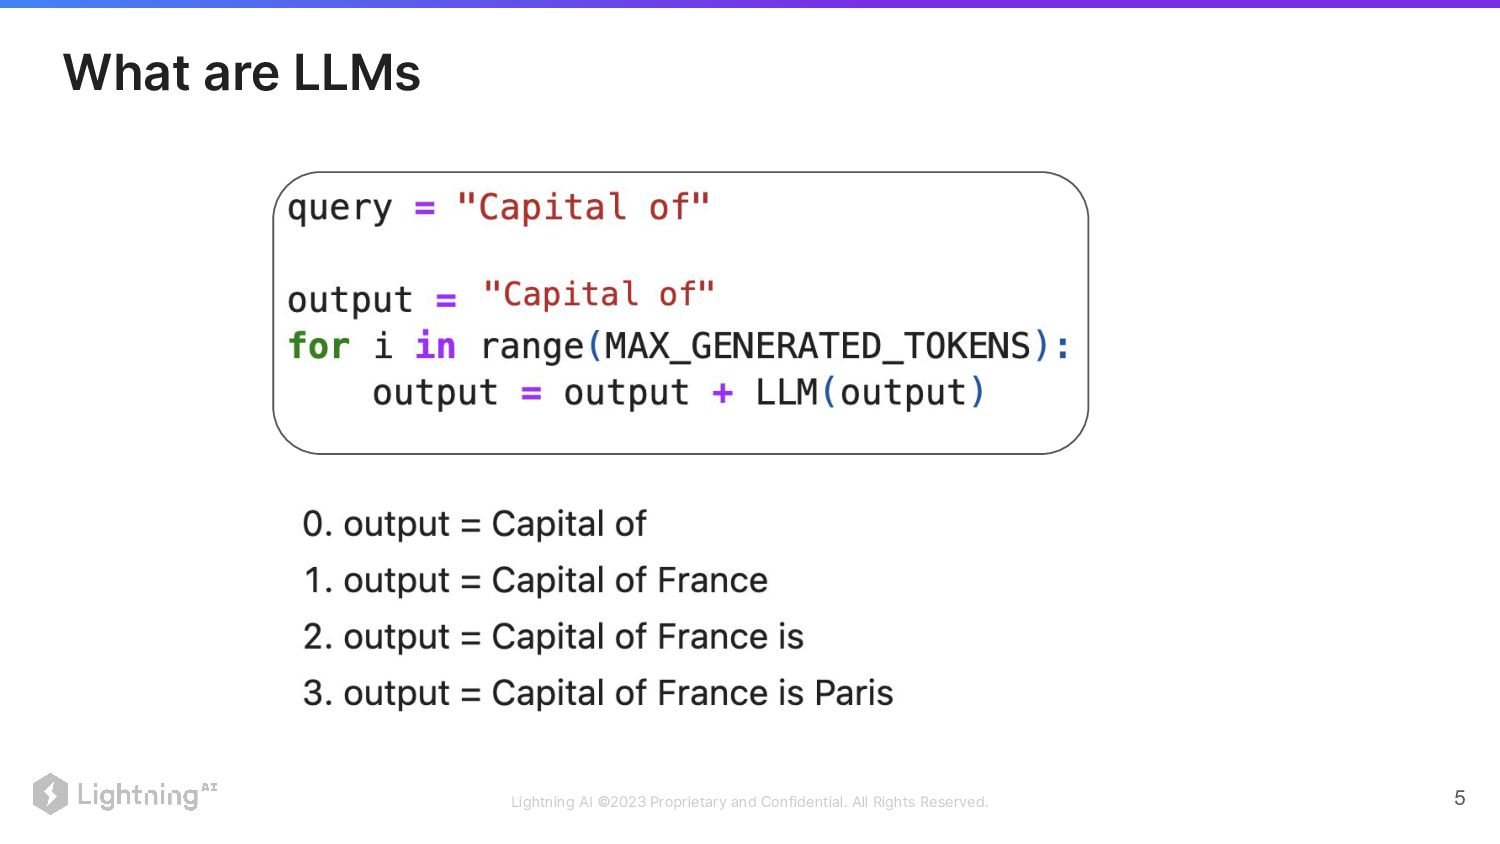
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 5
What are LLMs
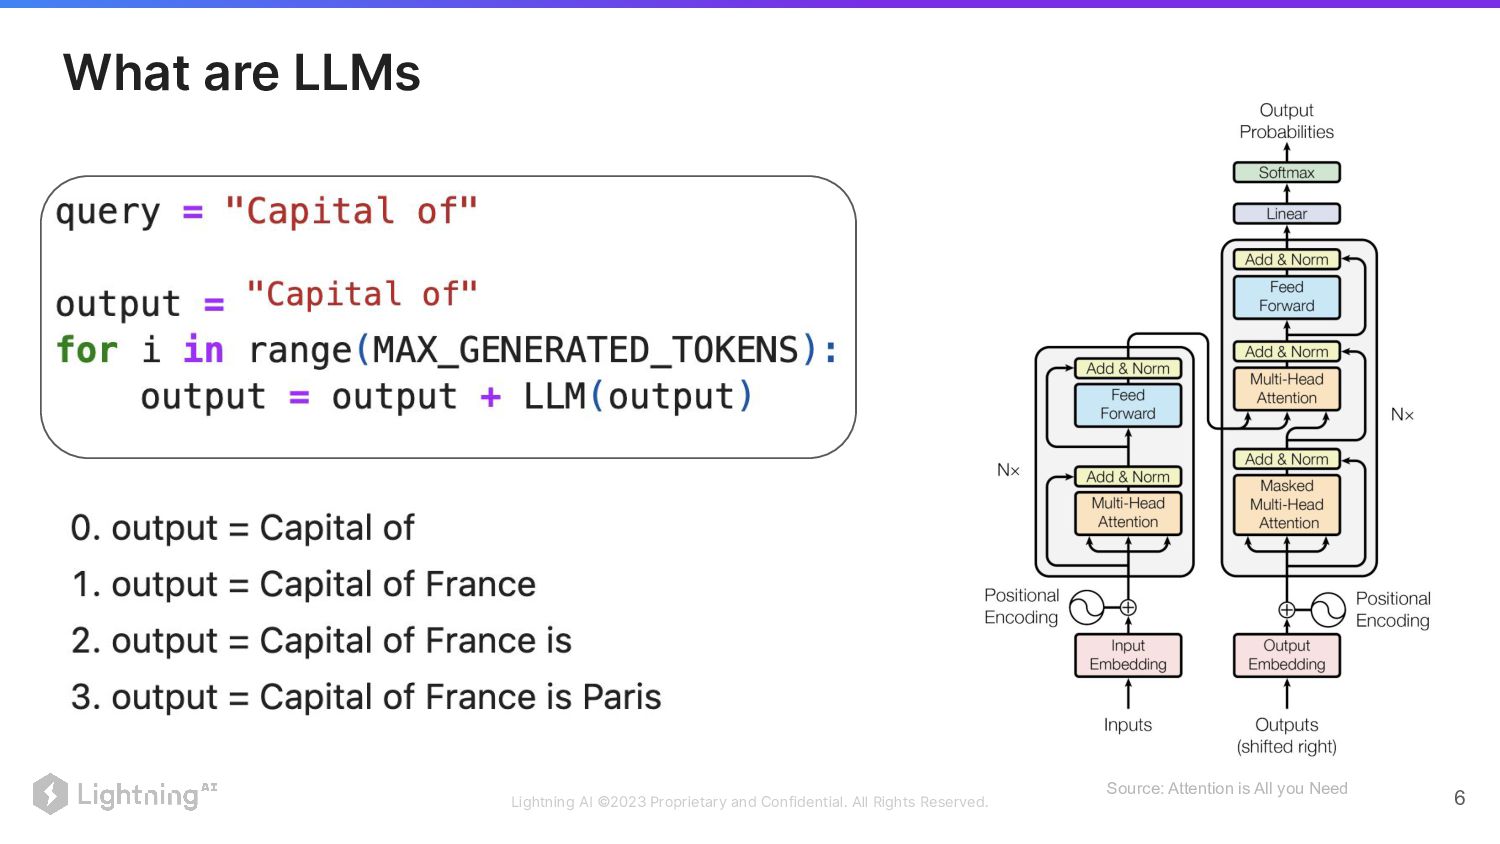
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 6
What are LLMs Source: Attention is All you Need
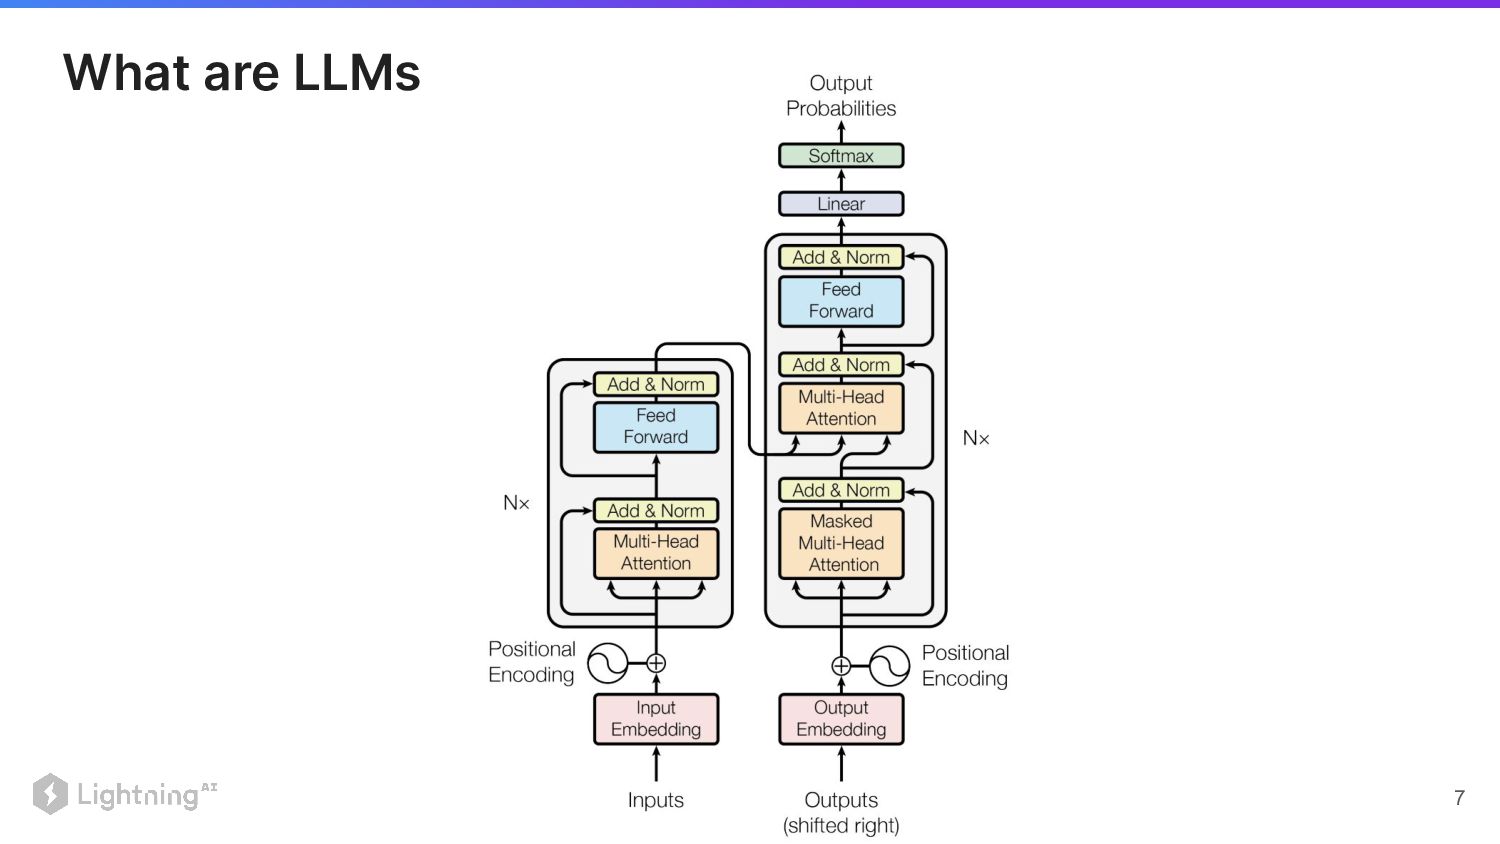
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 7
What are LLMs
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 8
What are LLMs
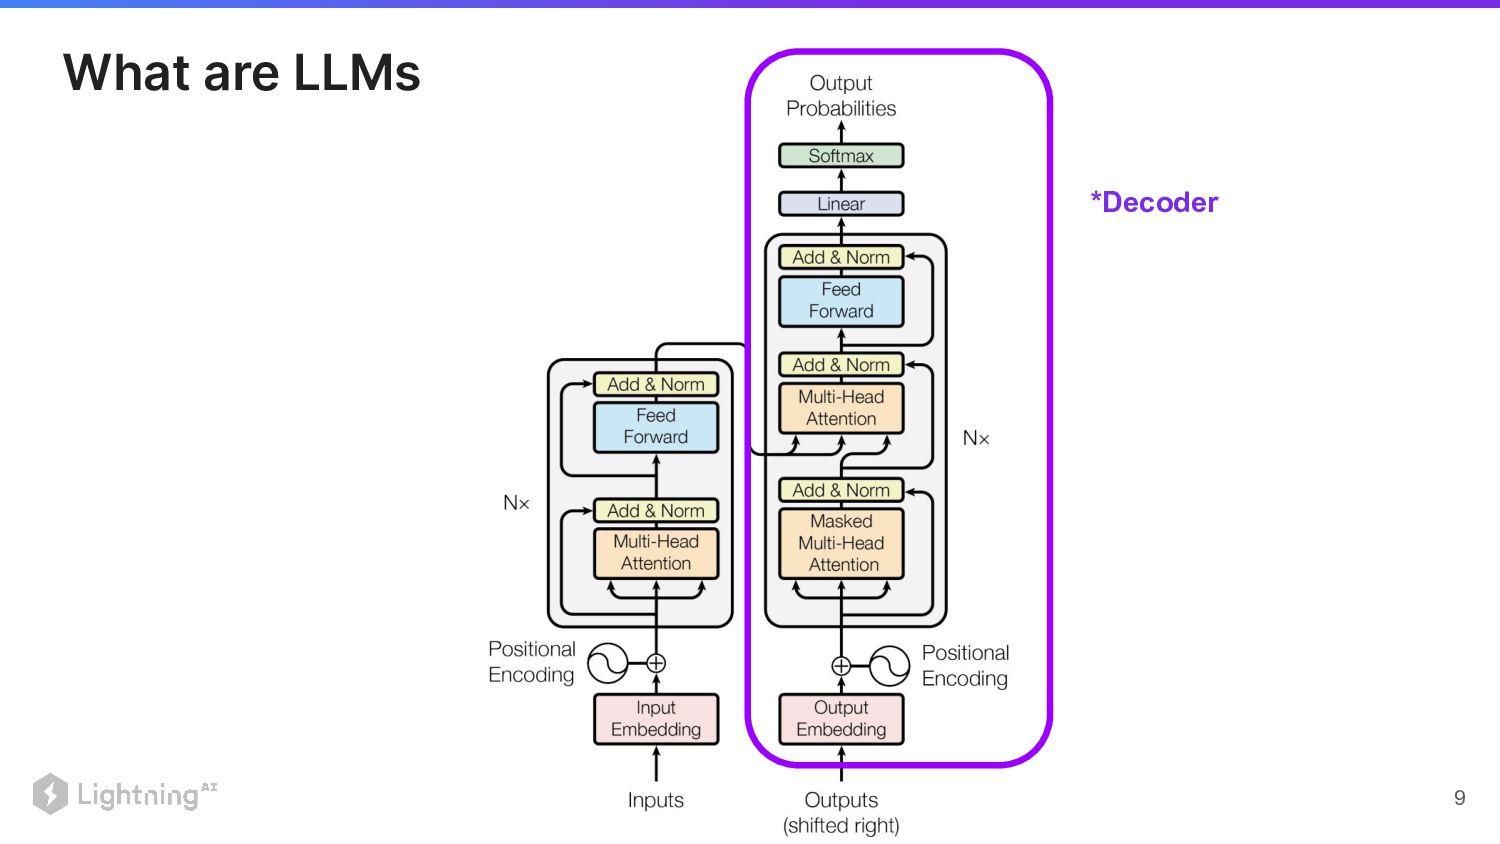
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 9
What are LLMs *Decoder
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 10
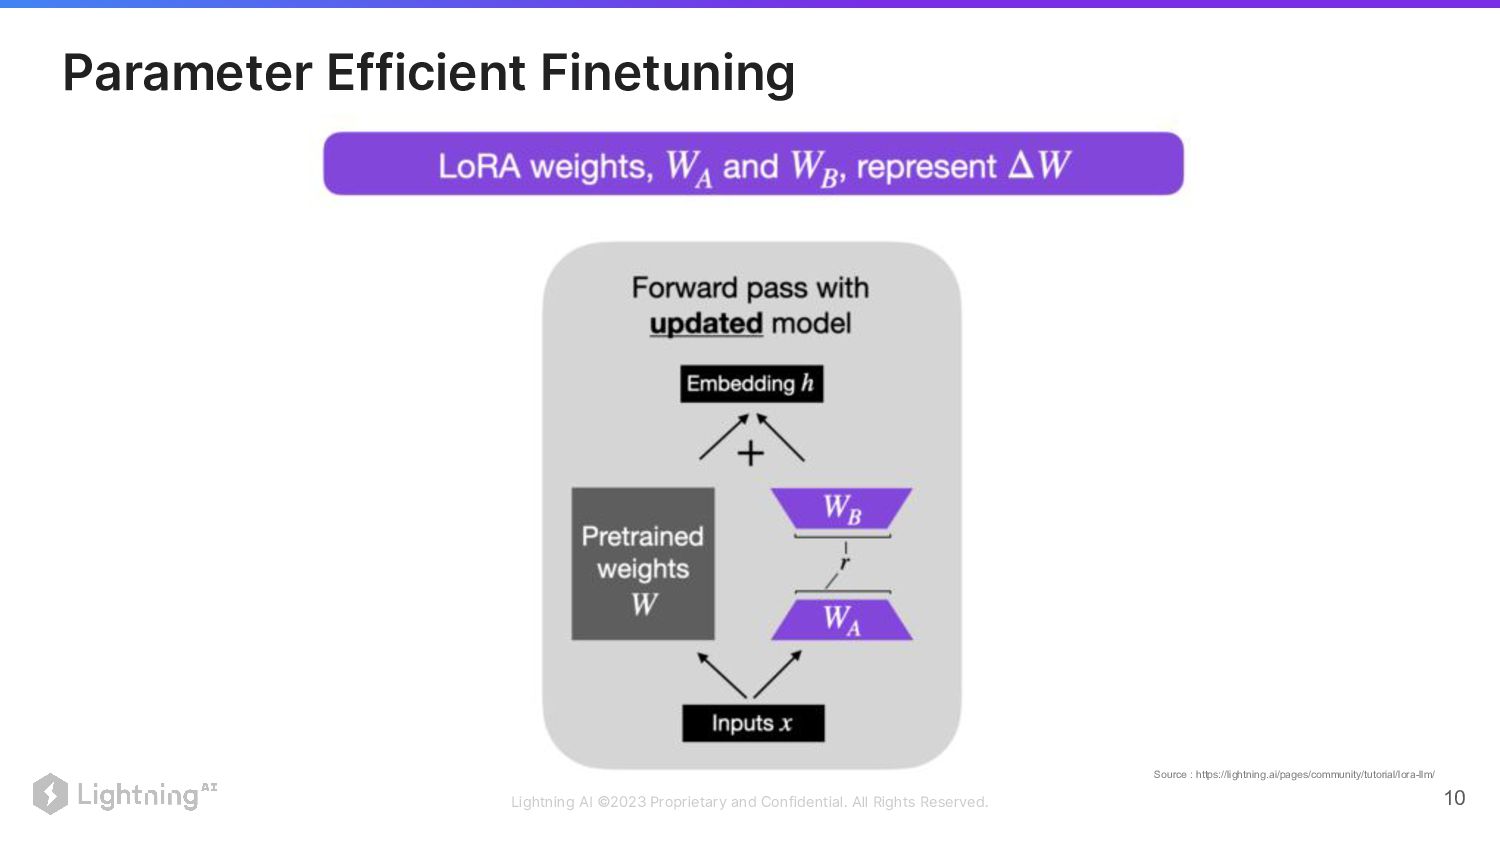
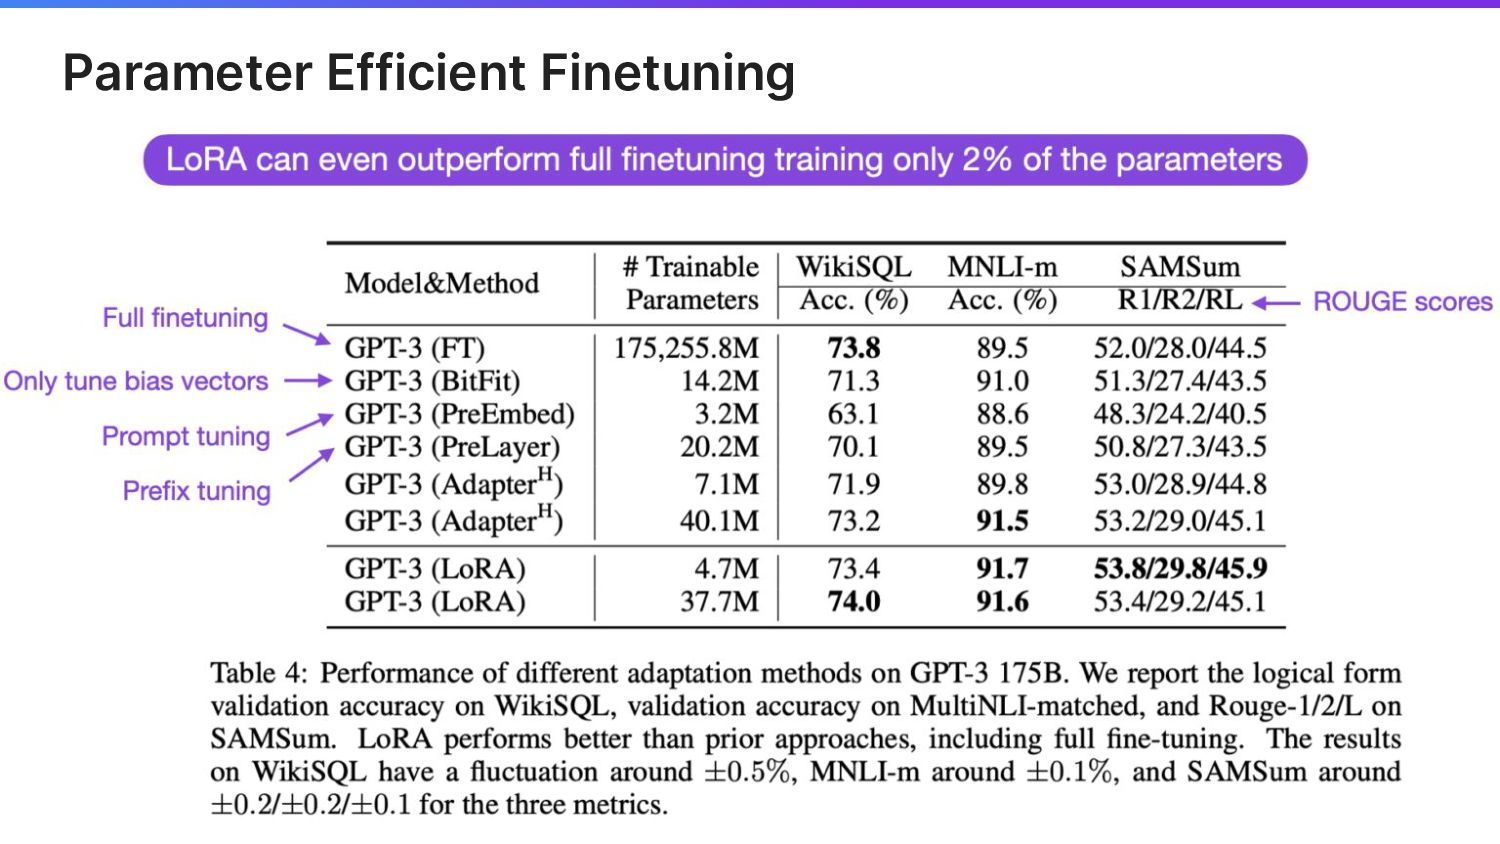
Parameter Efficient Finetuning Source : https://lightning.ai/pages/community/tutorial/lora-llm/
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 11
Parameter Efficient Finetuning
• Remove untruthfulness and toxicity • Customize the output and
tone of language • Privacy and control Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 12 Why Finetune LLMs
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 13
Finetuning LLMs on instruction dataset
• Setup model • Prepare data • Finetune the model
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 14 Finetuning LLMs
• Setup model • Prepare data • Finetune the model
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 15 Finetuning LLMs
• Setup model • Prepare data • Finetune the model
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 16 Finetuning LLMs
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 17
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 18
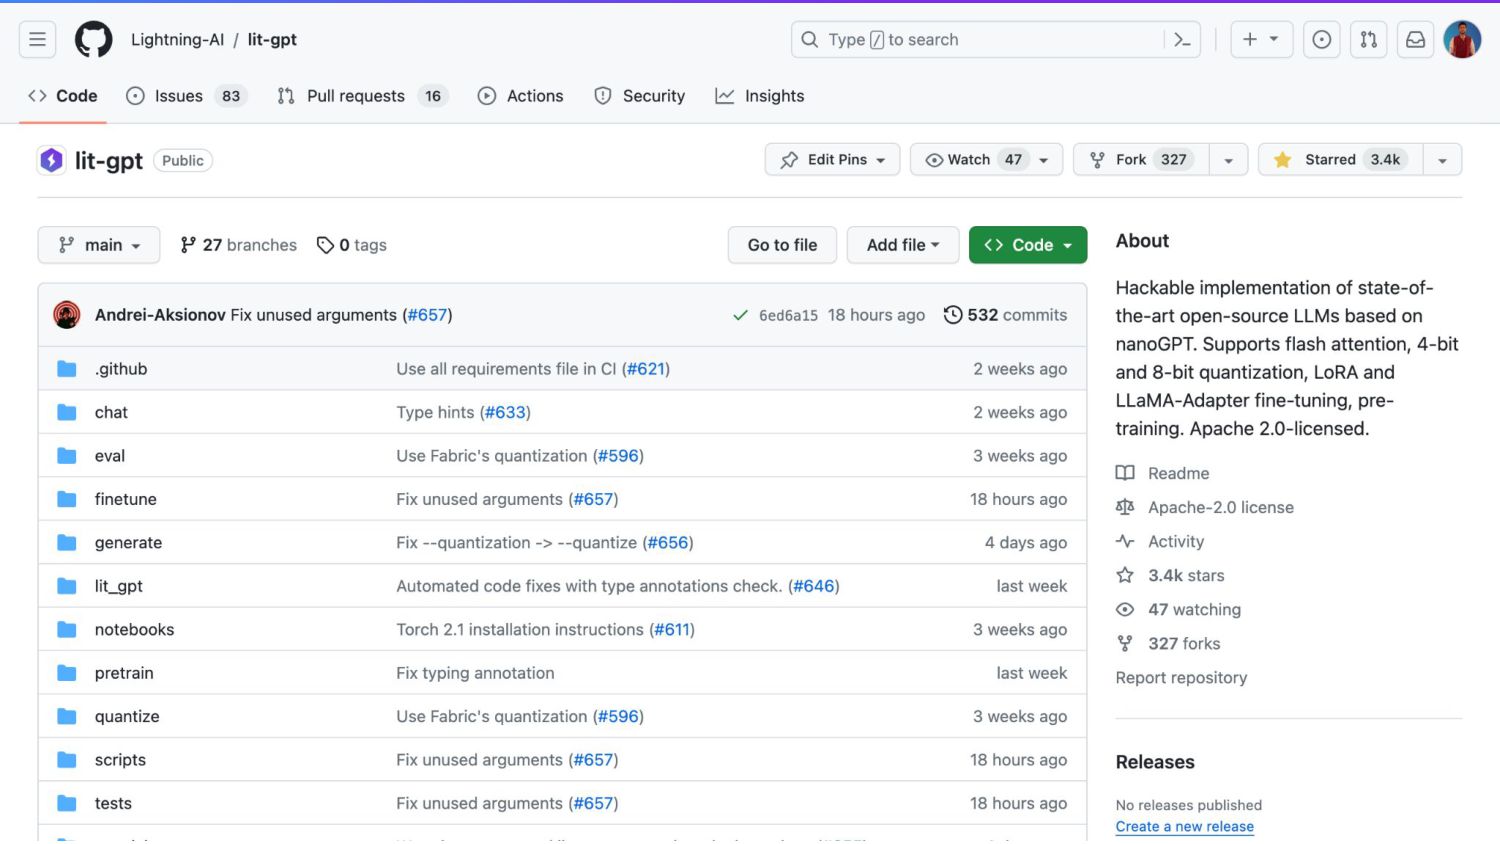
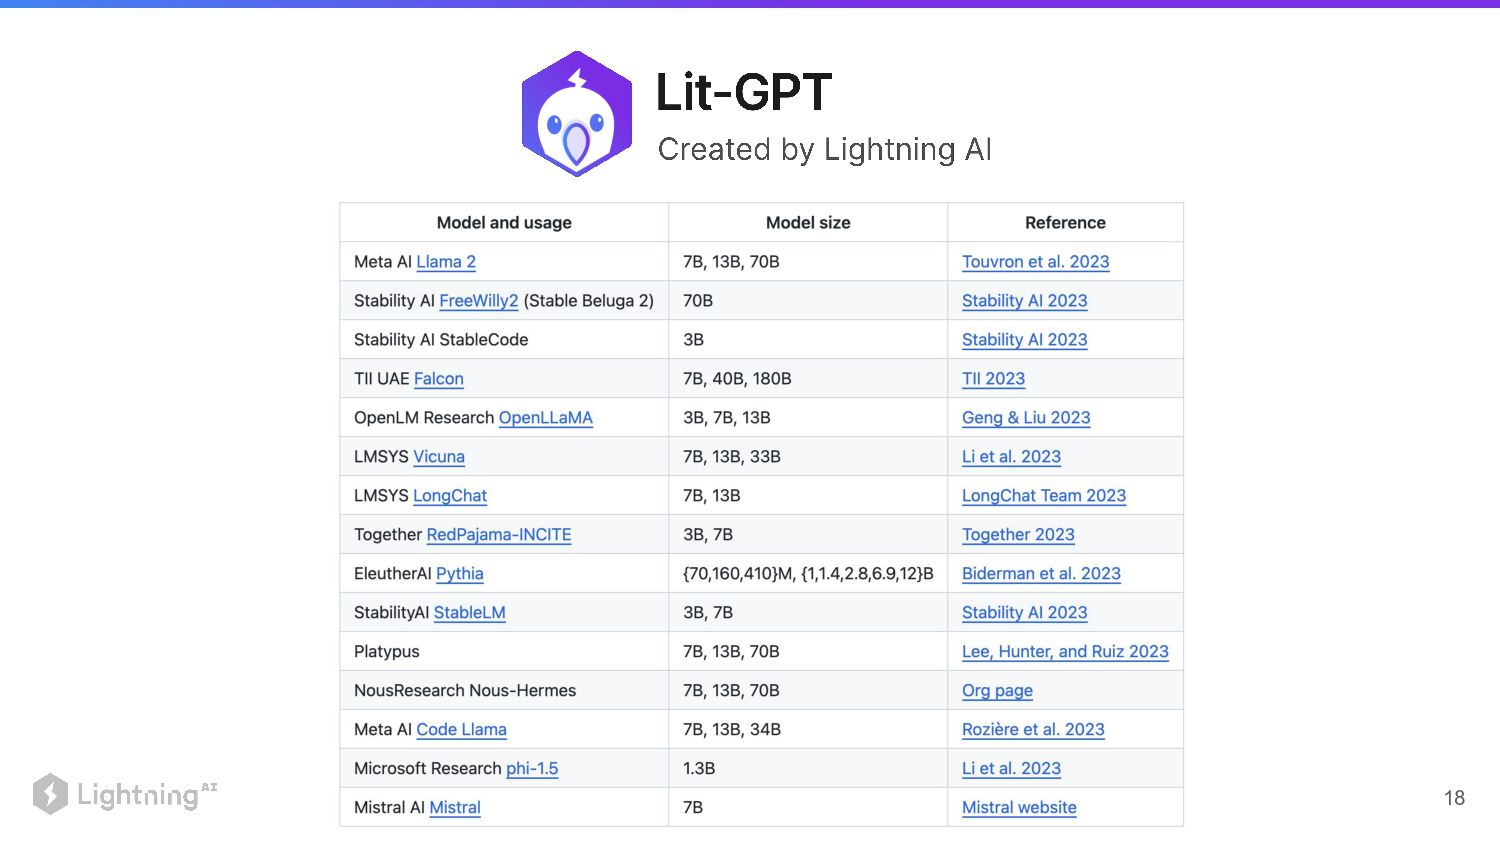
• 4-bit quantized finetuning and inference • Minimal code, easy
to debug and hack • TPU support • Flash-Attention 2 Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 19 Lit-GPT
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 20
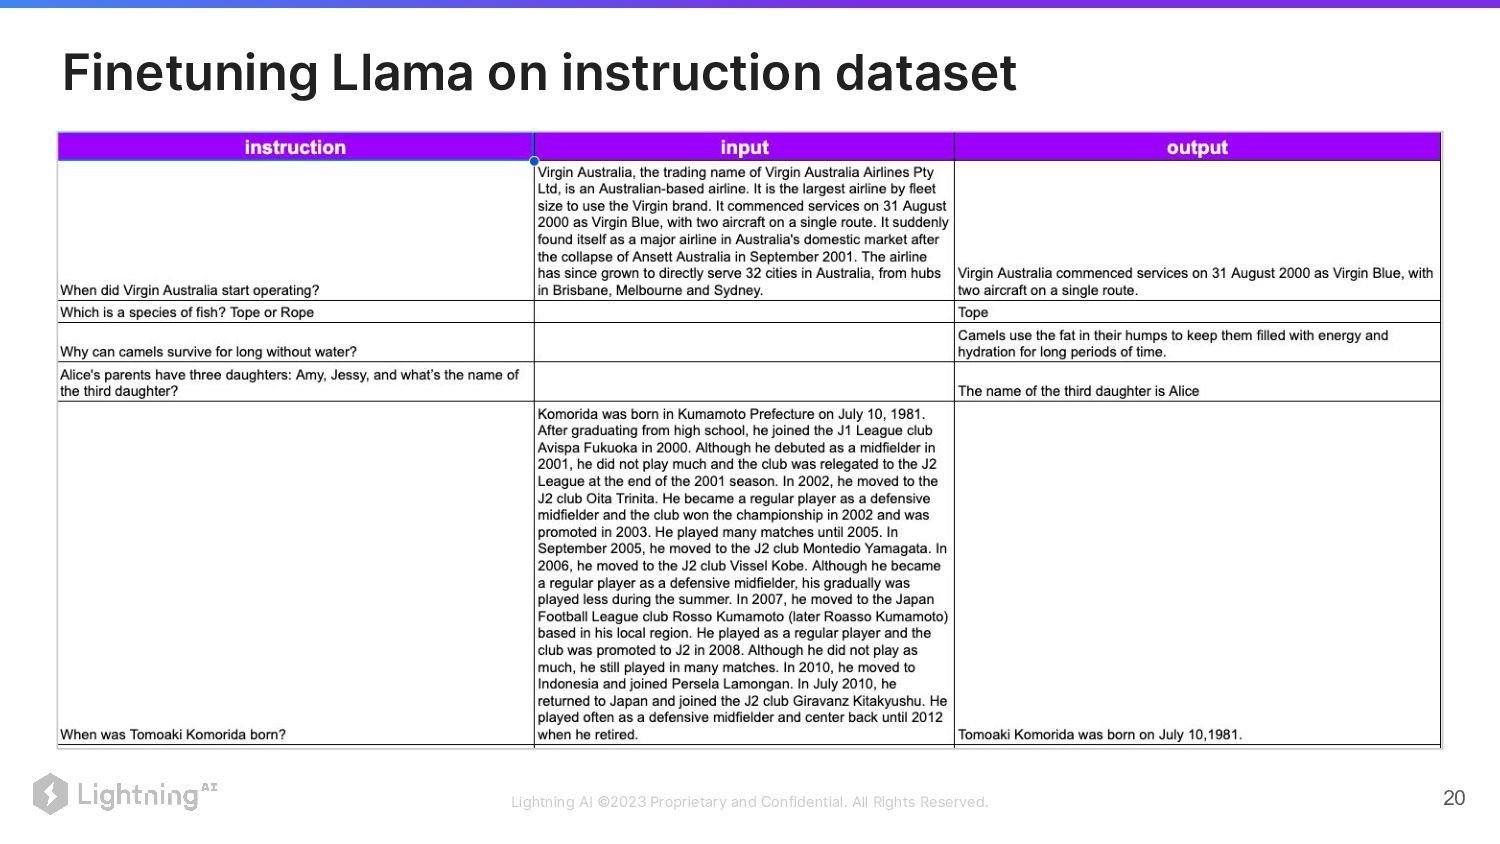
Finetuning Llama on instruction dataset
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 21
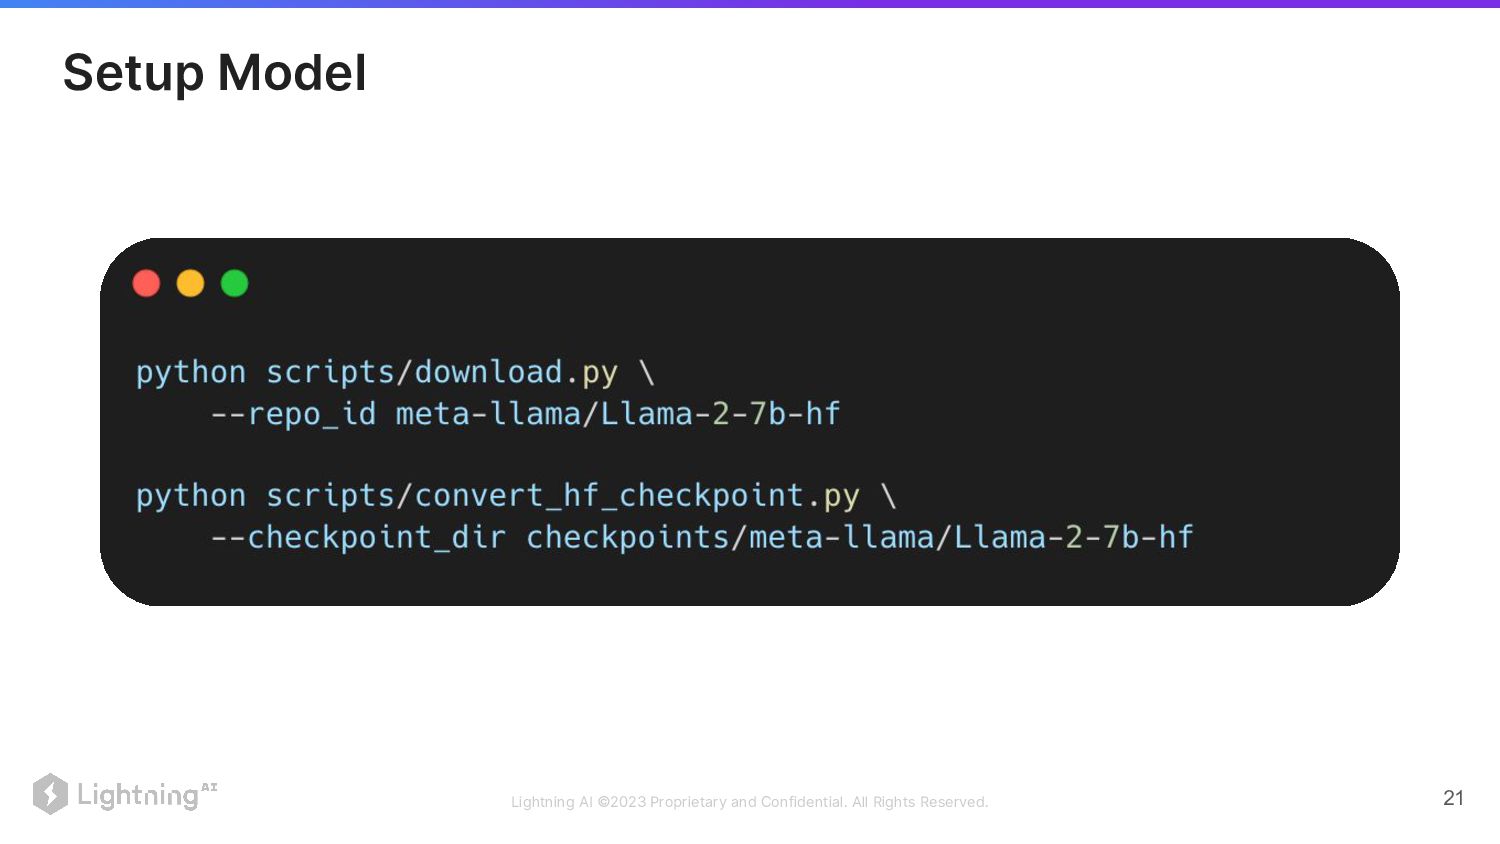
Setup Model
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 22
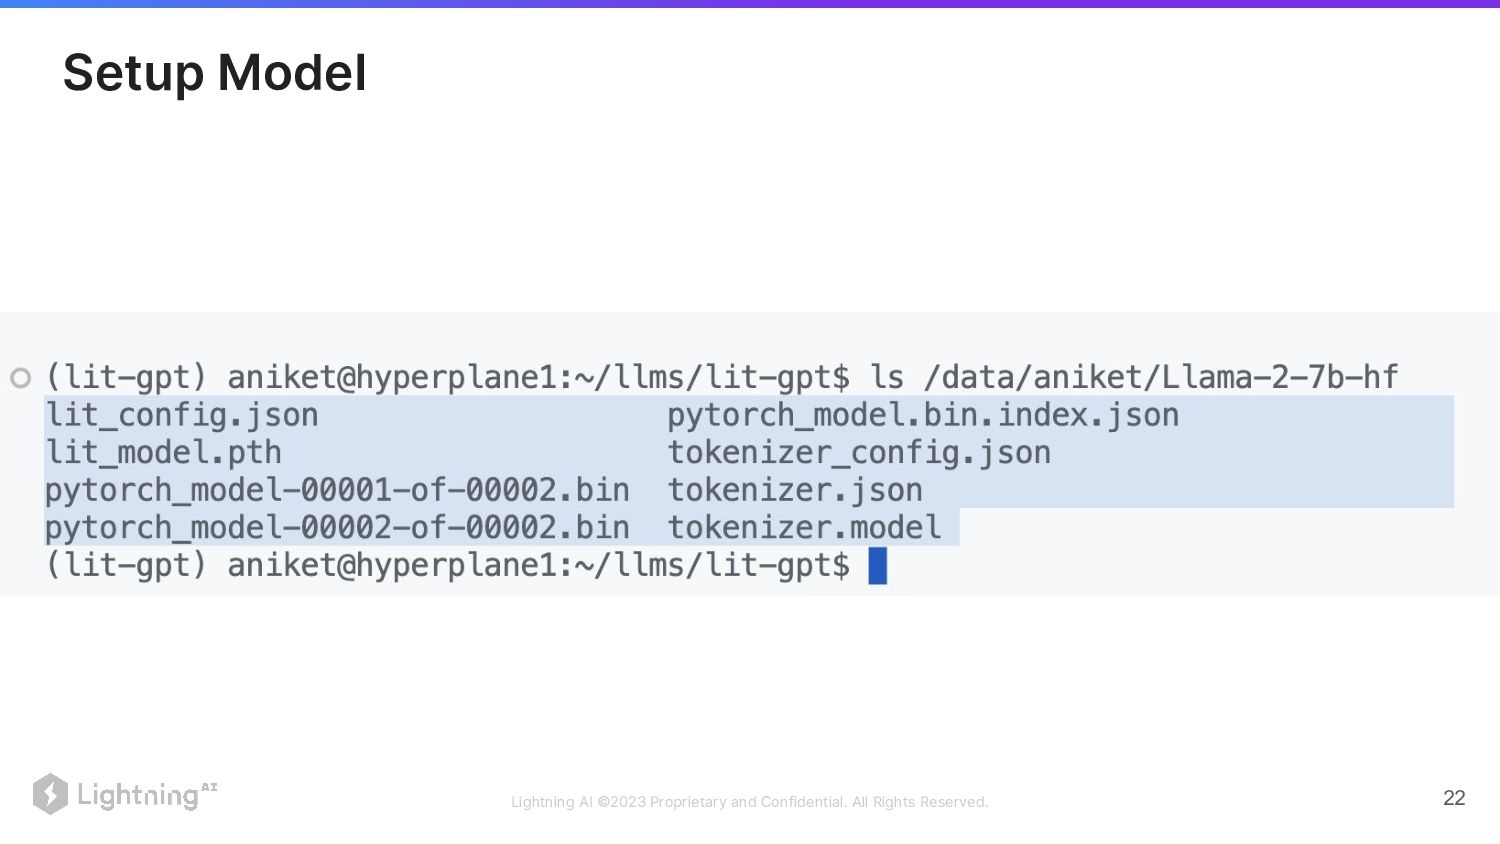
Setup Model
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 23
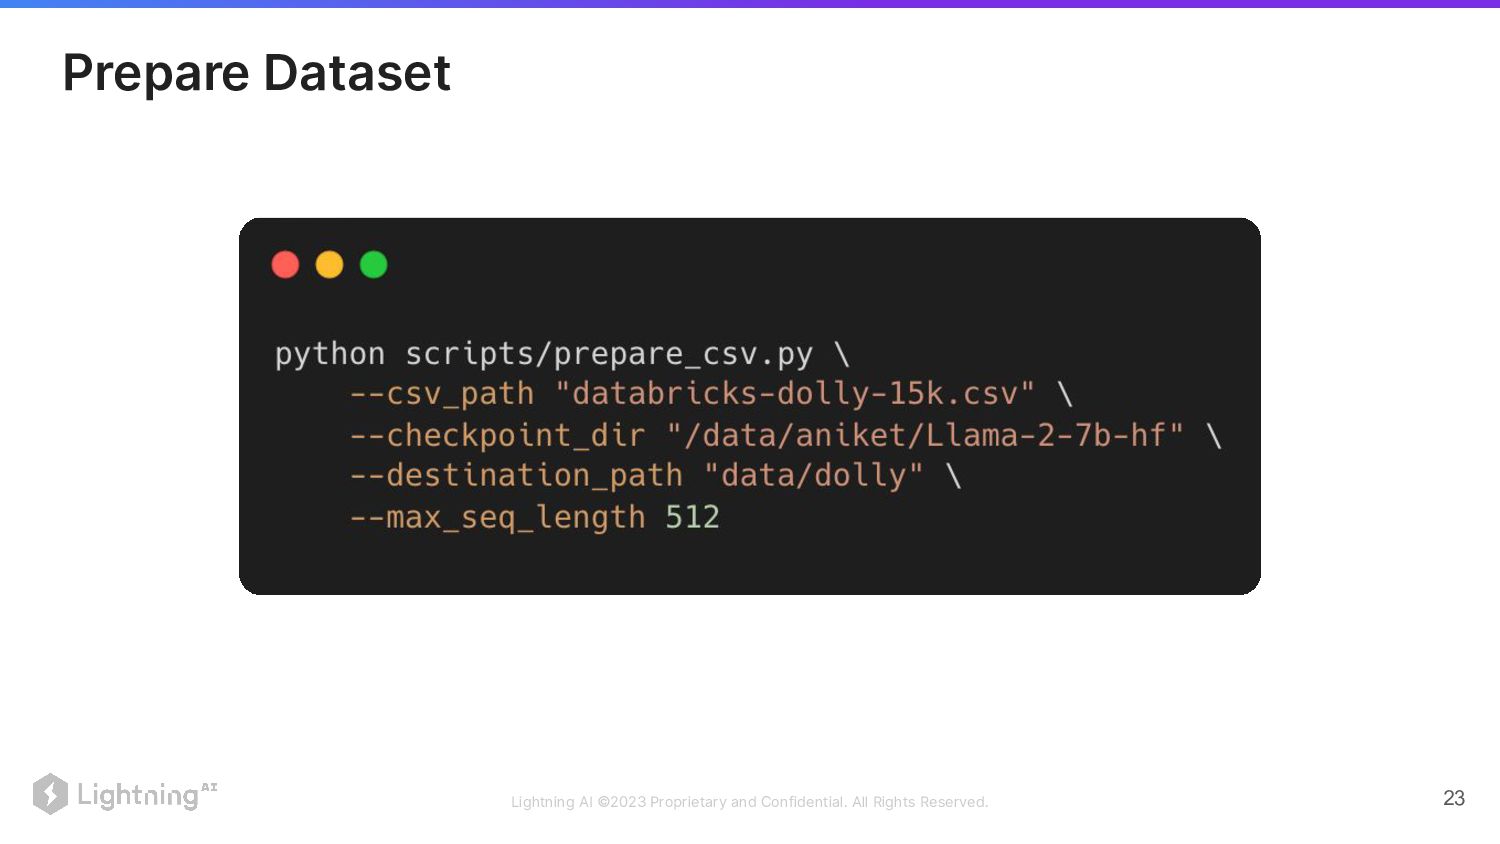
Prepare Dataset
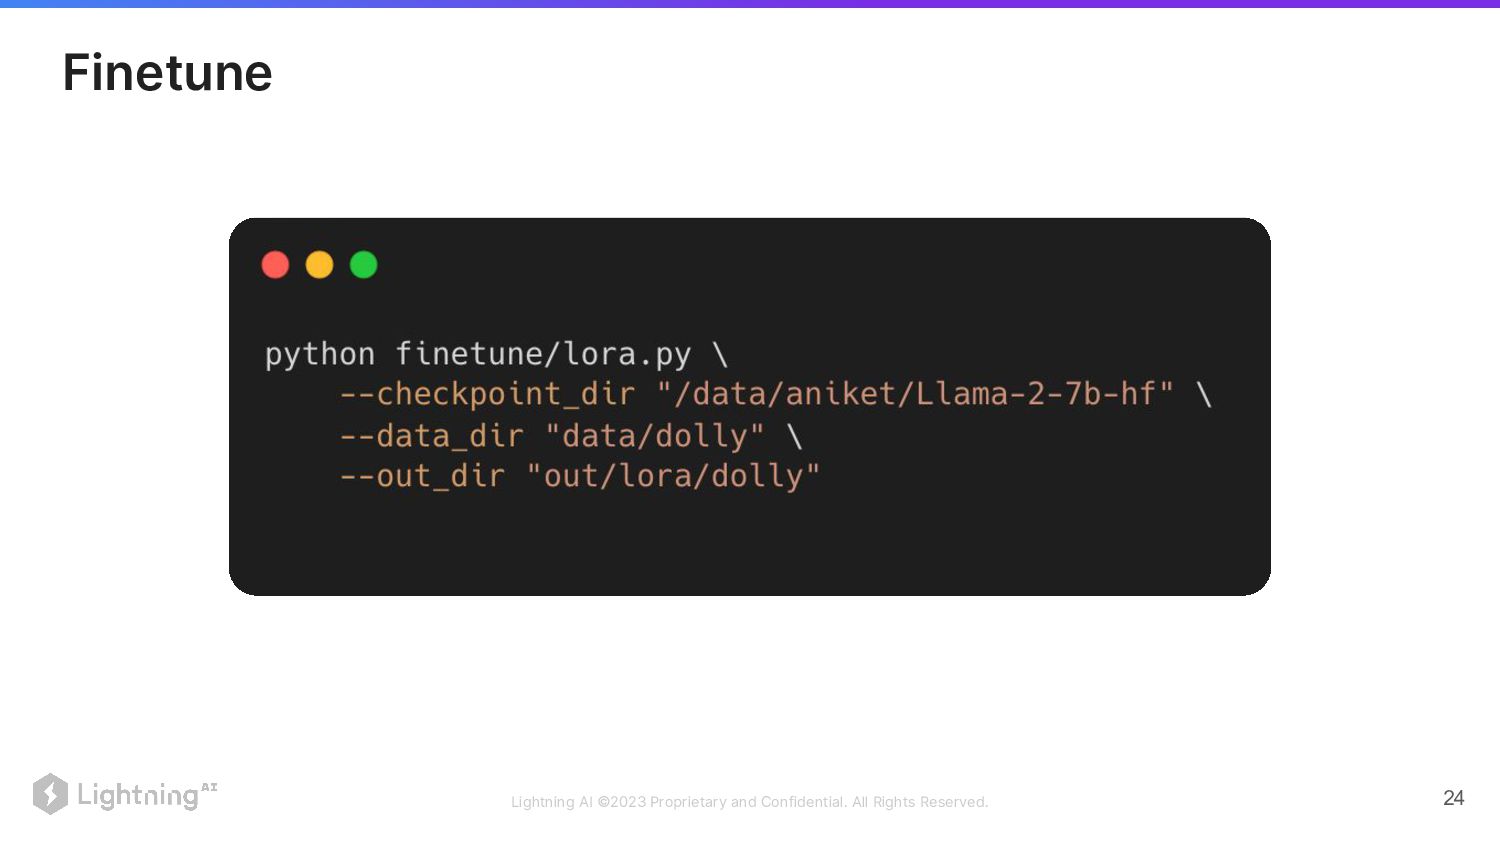
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 24
Finetune
CUDA Out Of Memory Lightning AI ©2023 Proprietary and Confidential.
All Rights Reserved. 25
• Llama 7B, fp32: ~28GB • Llama 7B, fp16: ~14GB
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 26 Memory Required to load Llama
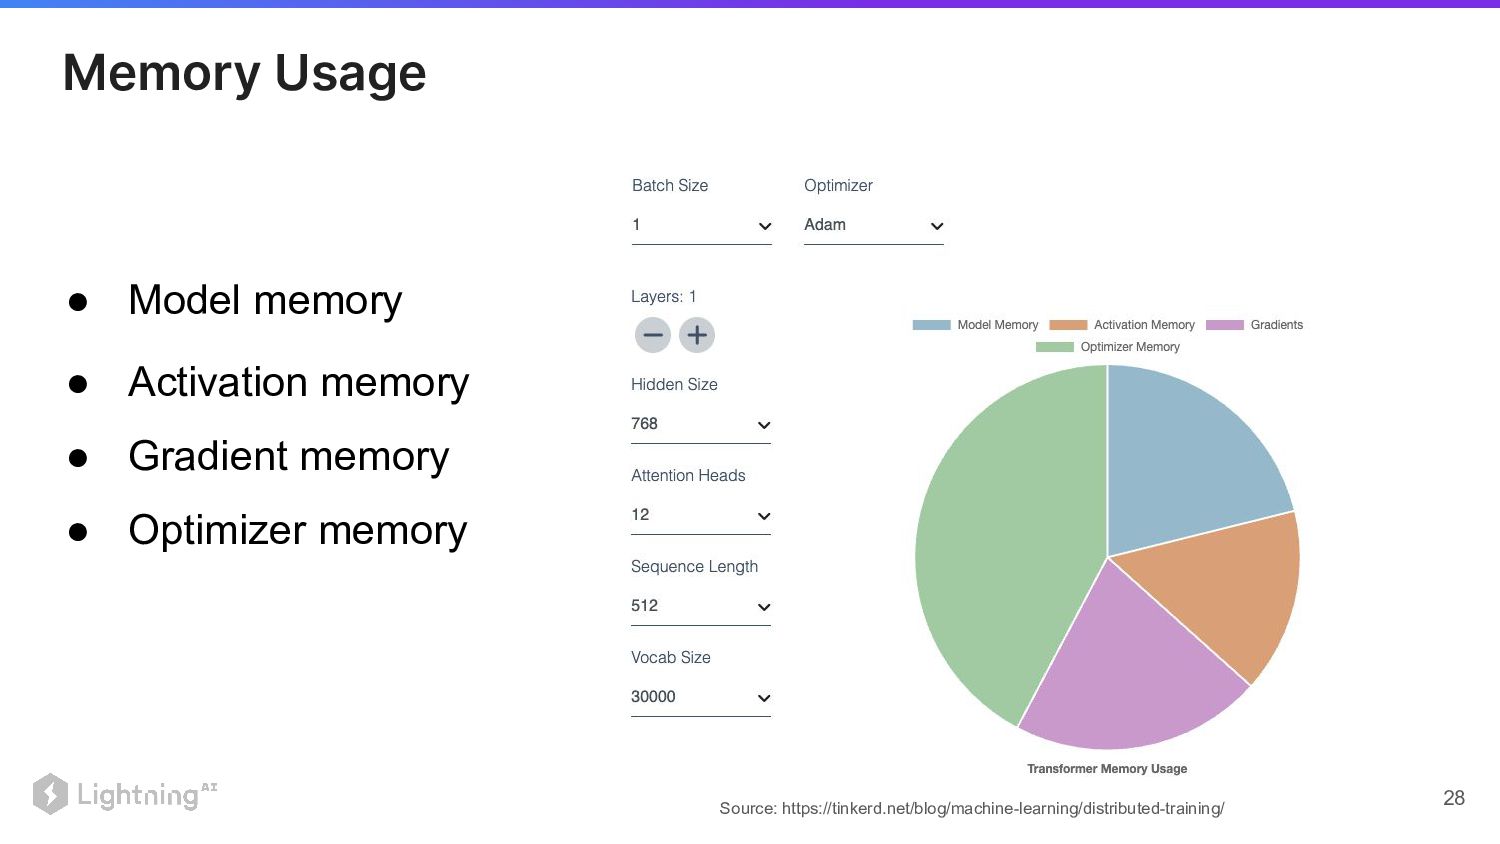
• Activation memory • Gradient memory • Optimizer memory •
Model memory Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 27 Memory Usage
• Activation memory • Gradient memory • Optimizer memory •
Model memory Source: https://tinkerd.net/blog/machine-learning/distributed-training/ 28 Memory Usage
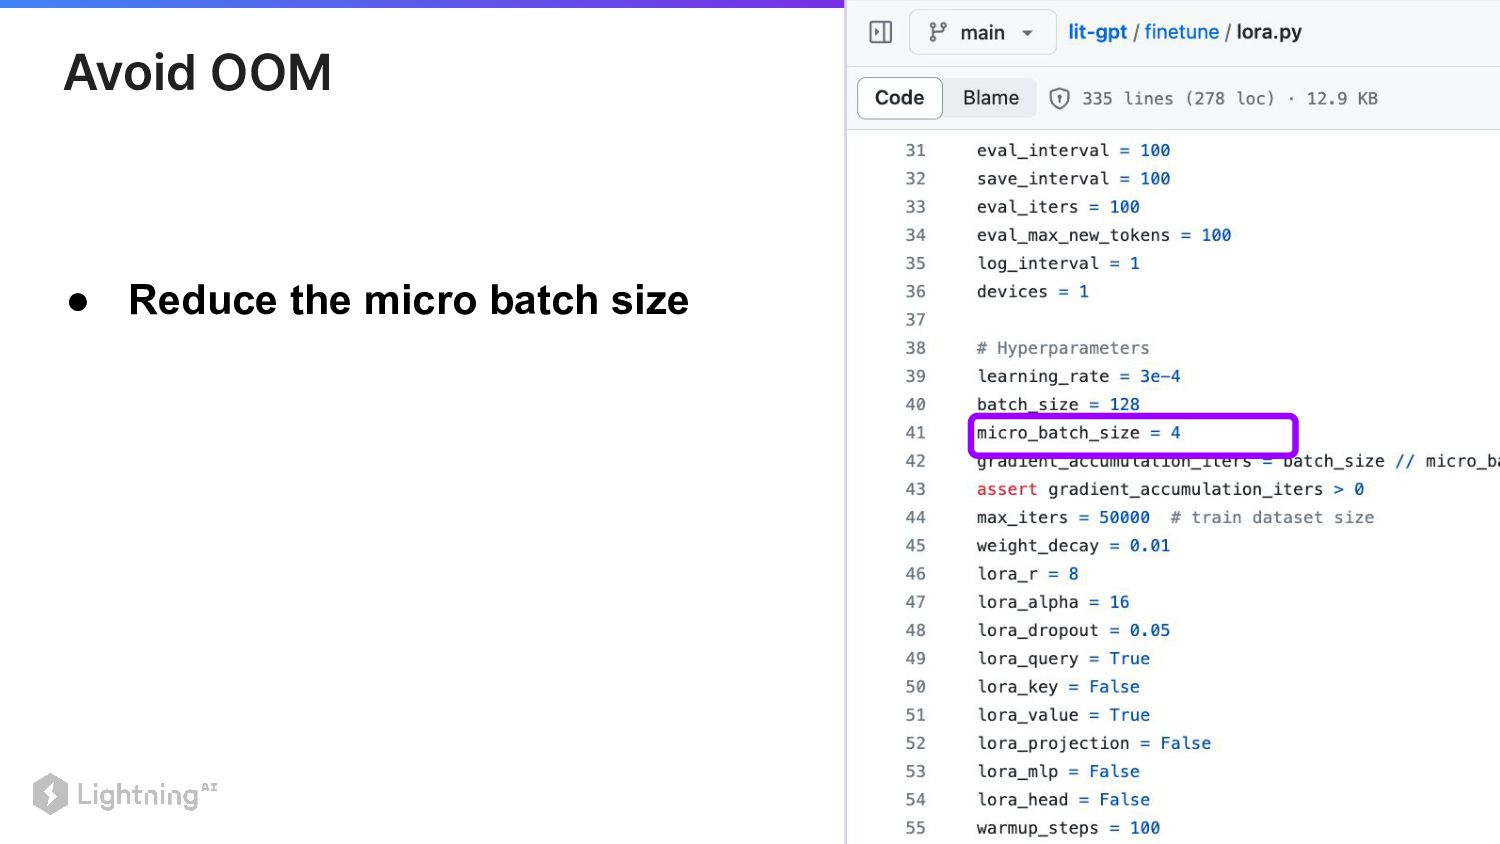
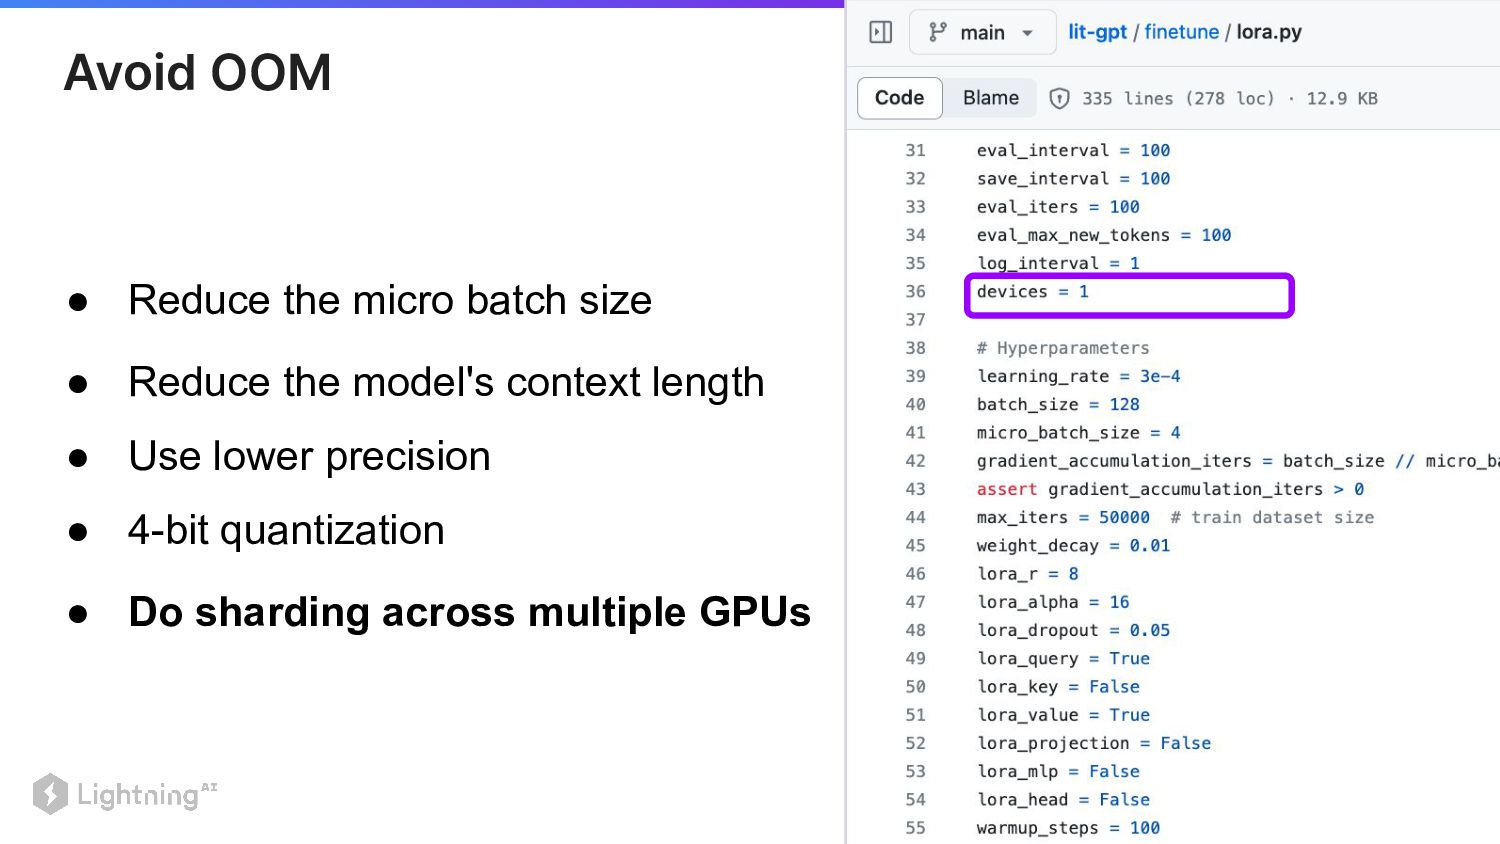
29 • Reduce the micro batch size Avoid OOM
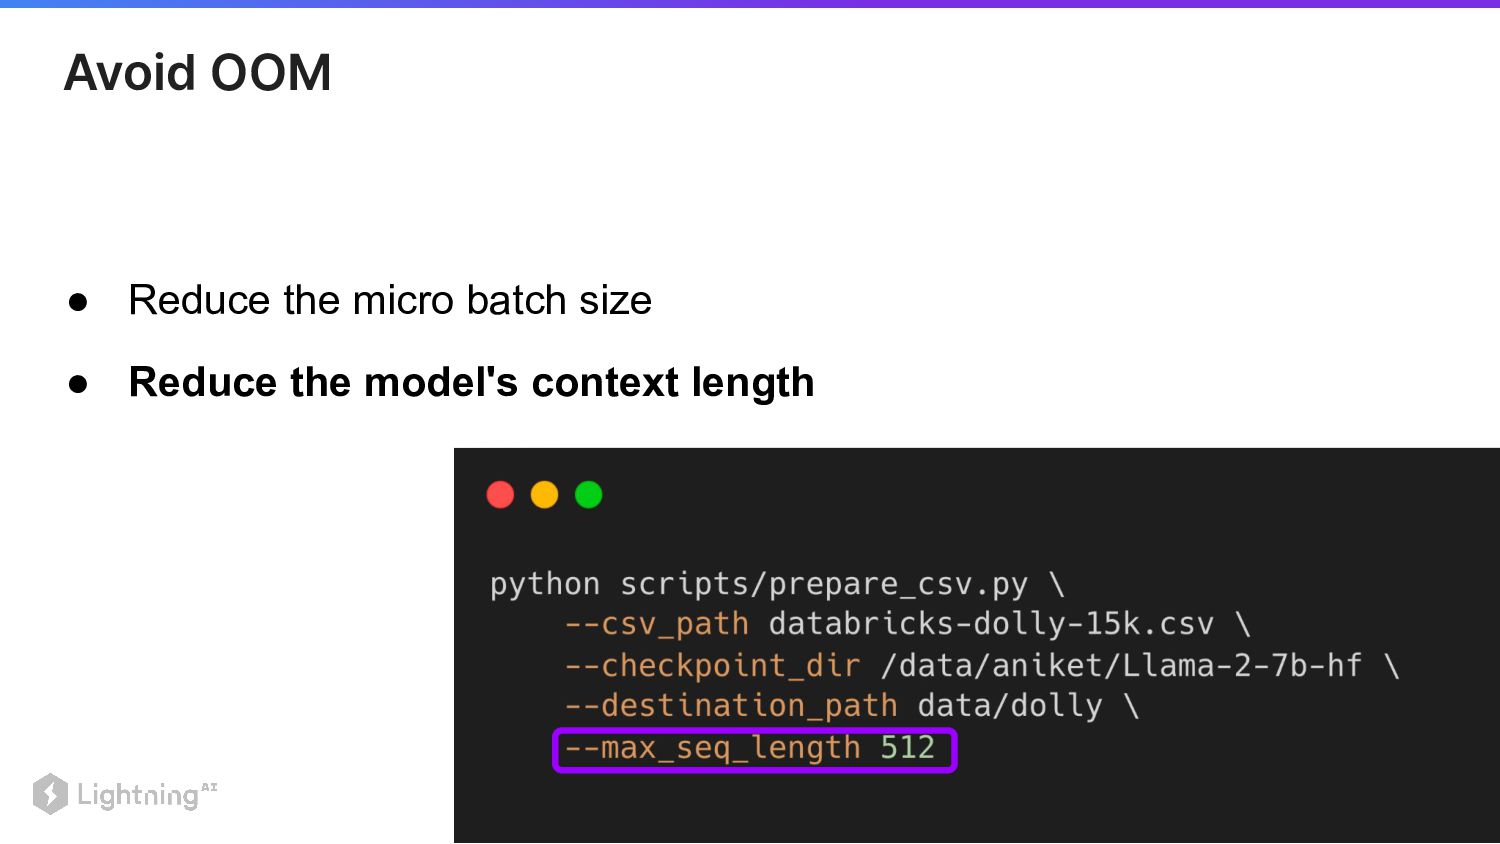
30 • Reduce the model's context length • Reduce the
micro batch size Avoid OOM
31 • Reduce the model's context length • Use lower
precision • Reduce the micro batch size Avoid OOM
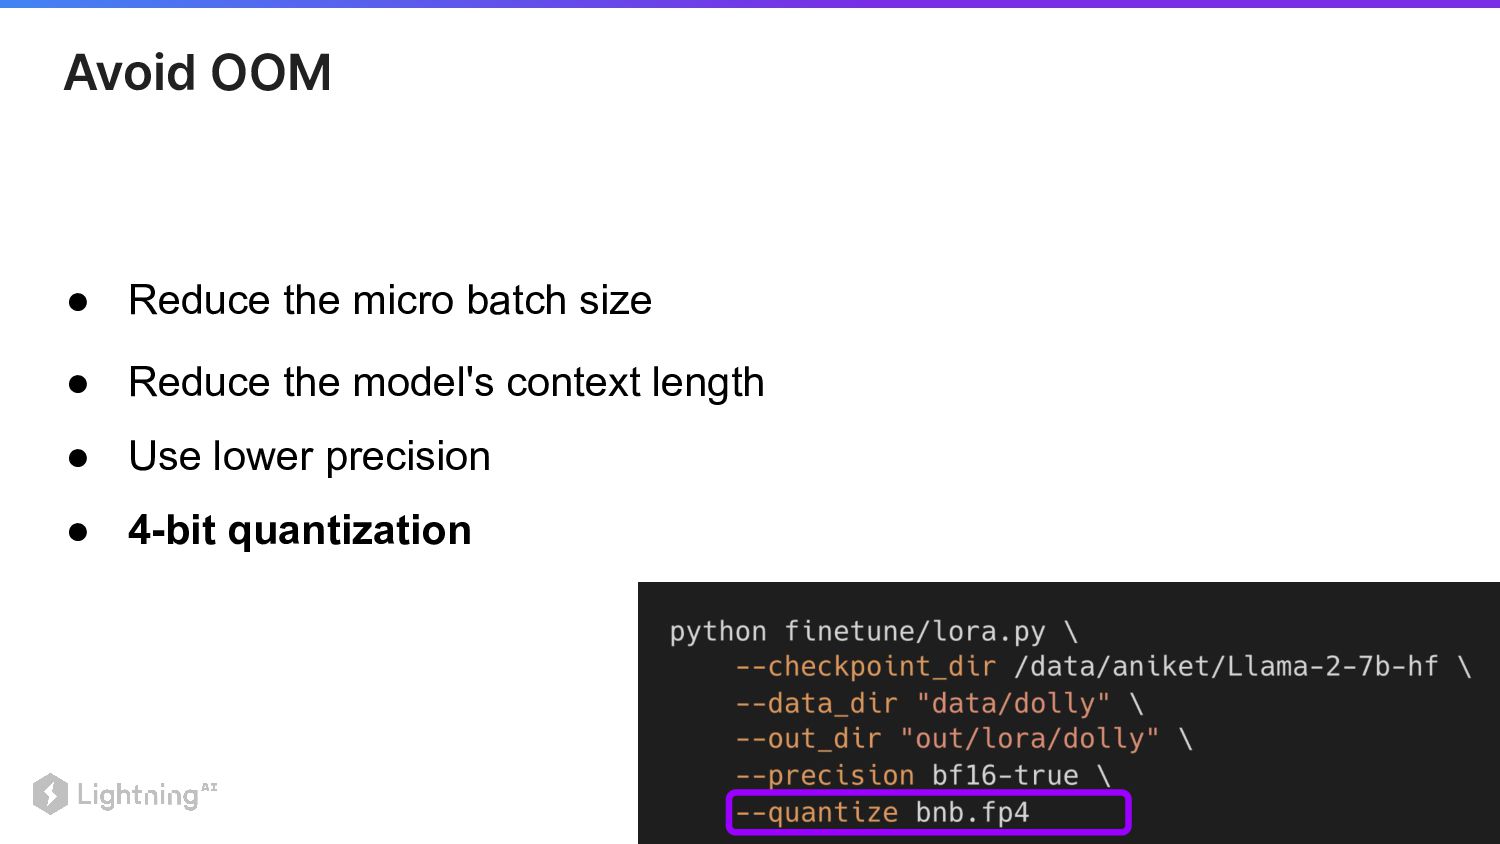
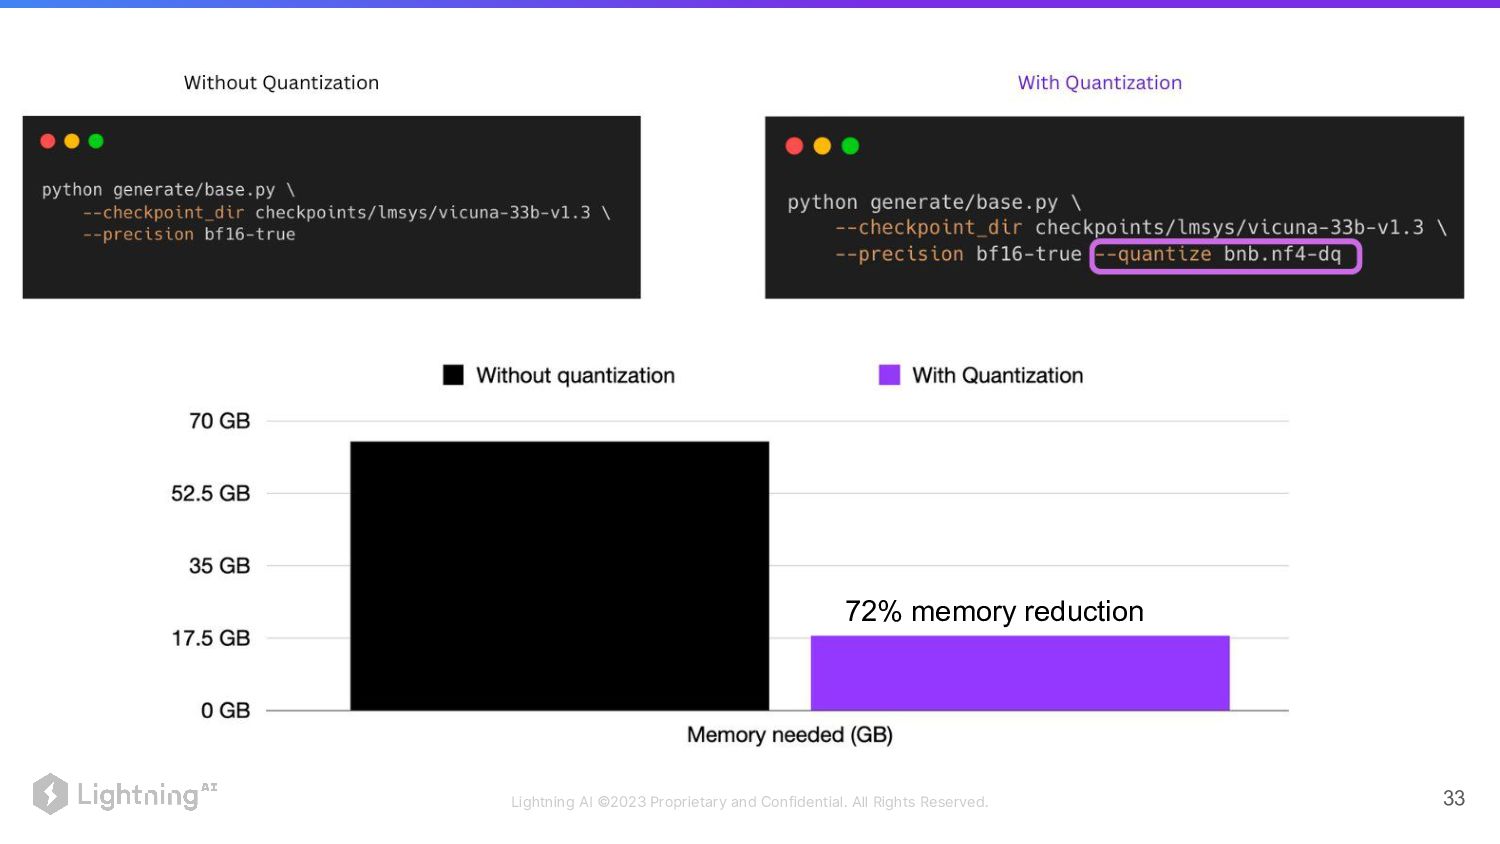
• 4-bit quantization 32 • Reduce the model's context length
• Use lower precision • Reduce the micro batch size Avoid OOM
72% memory reduction Lightning AI ©2023 Proprietary and Confidential. All
Rights Reserved. 33
34 • Reduce the model's context length • Use lower
precision • 4-bit quantization • Do sharding across multiple GPUs • Reduce the micro batch size Avoid OOM
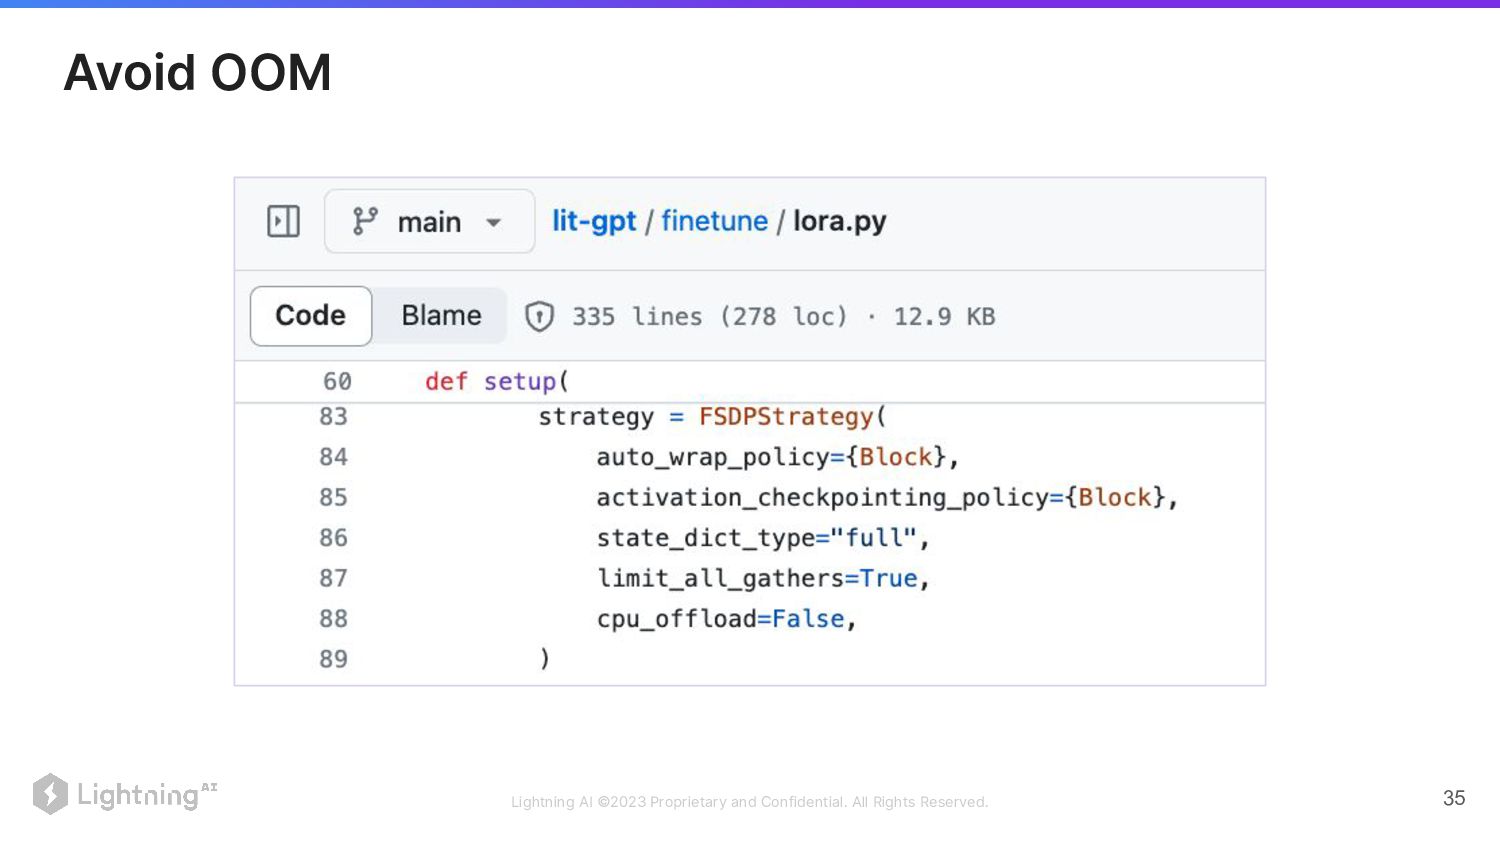
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 35
Avoid OOM
• Lit-GPT with LoRA finetuning • Lower Precision and 4-bit
quantization • Distributed training and activation checkpointing Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 36 Conclusion
Lightning AI ©2023 Proprietary and Confidential. All Rights Reserved. 37
Aniket Maurya


 aniketmaurya
 artoy
 yumnumm
 rkaga
 yukiny
 prota
 guaca
 tmikov2023
 hollycummins
 siroemk
 chobishiba
 y0hgi
 jonyablonski
 honzajavorek
 nonsquared
 kneath
 tapps
 schlessera
 garrettdimon
 tmiket
 baasie
 3n
 helenjbeal
 afnizarnur