Upgrade to Pro — share decks privately, control downloads, hide ads and more …

AI Test Teammates: Agents That Test, Think and ...

Avatar for Asif Waquar Asif Waquar
September 03, 2026

AI Test Teammates: Agents That Test, Think and Adapt

We are building applications powered by AI agents but traditional testing approaches weren't designed for applications that reason, adapt, and make decisions.
What happens when we give an AI agent the job of testing another AI-powered application?

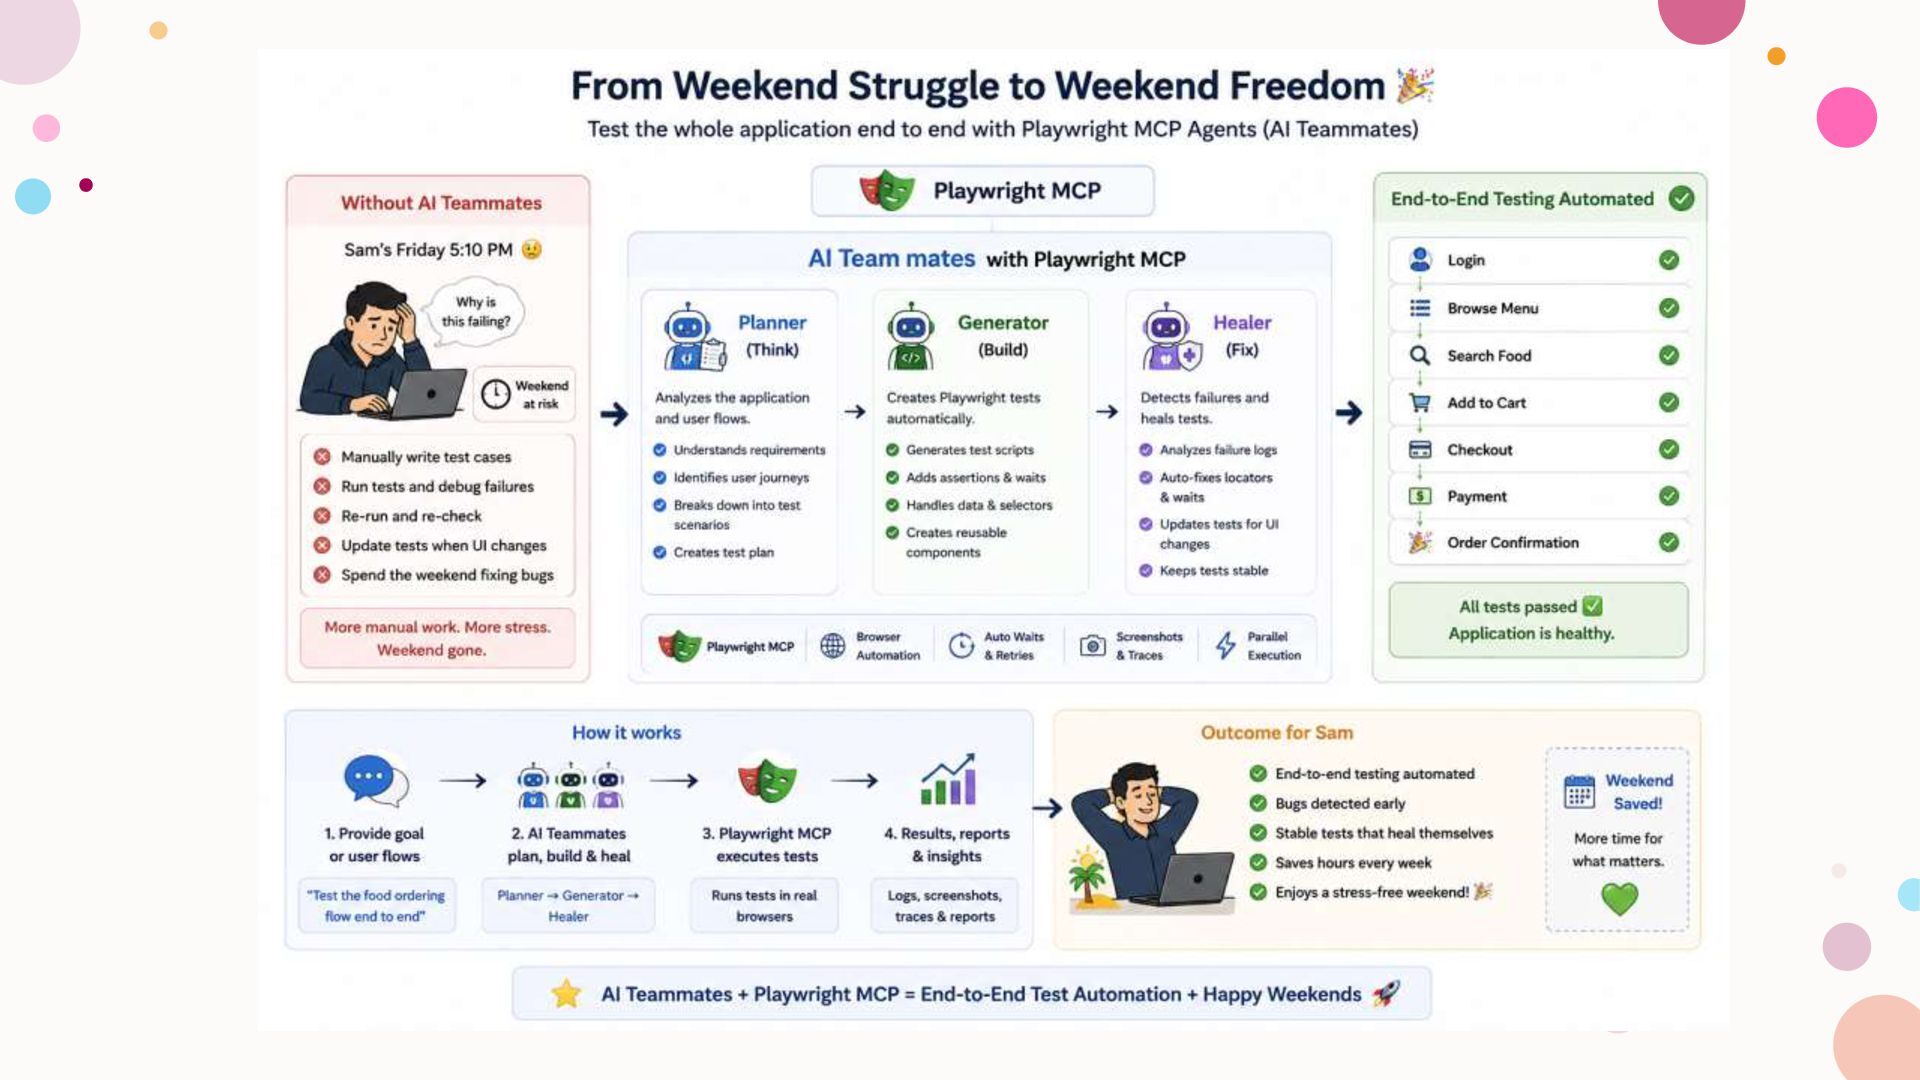
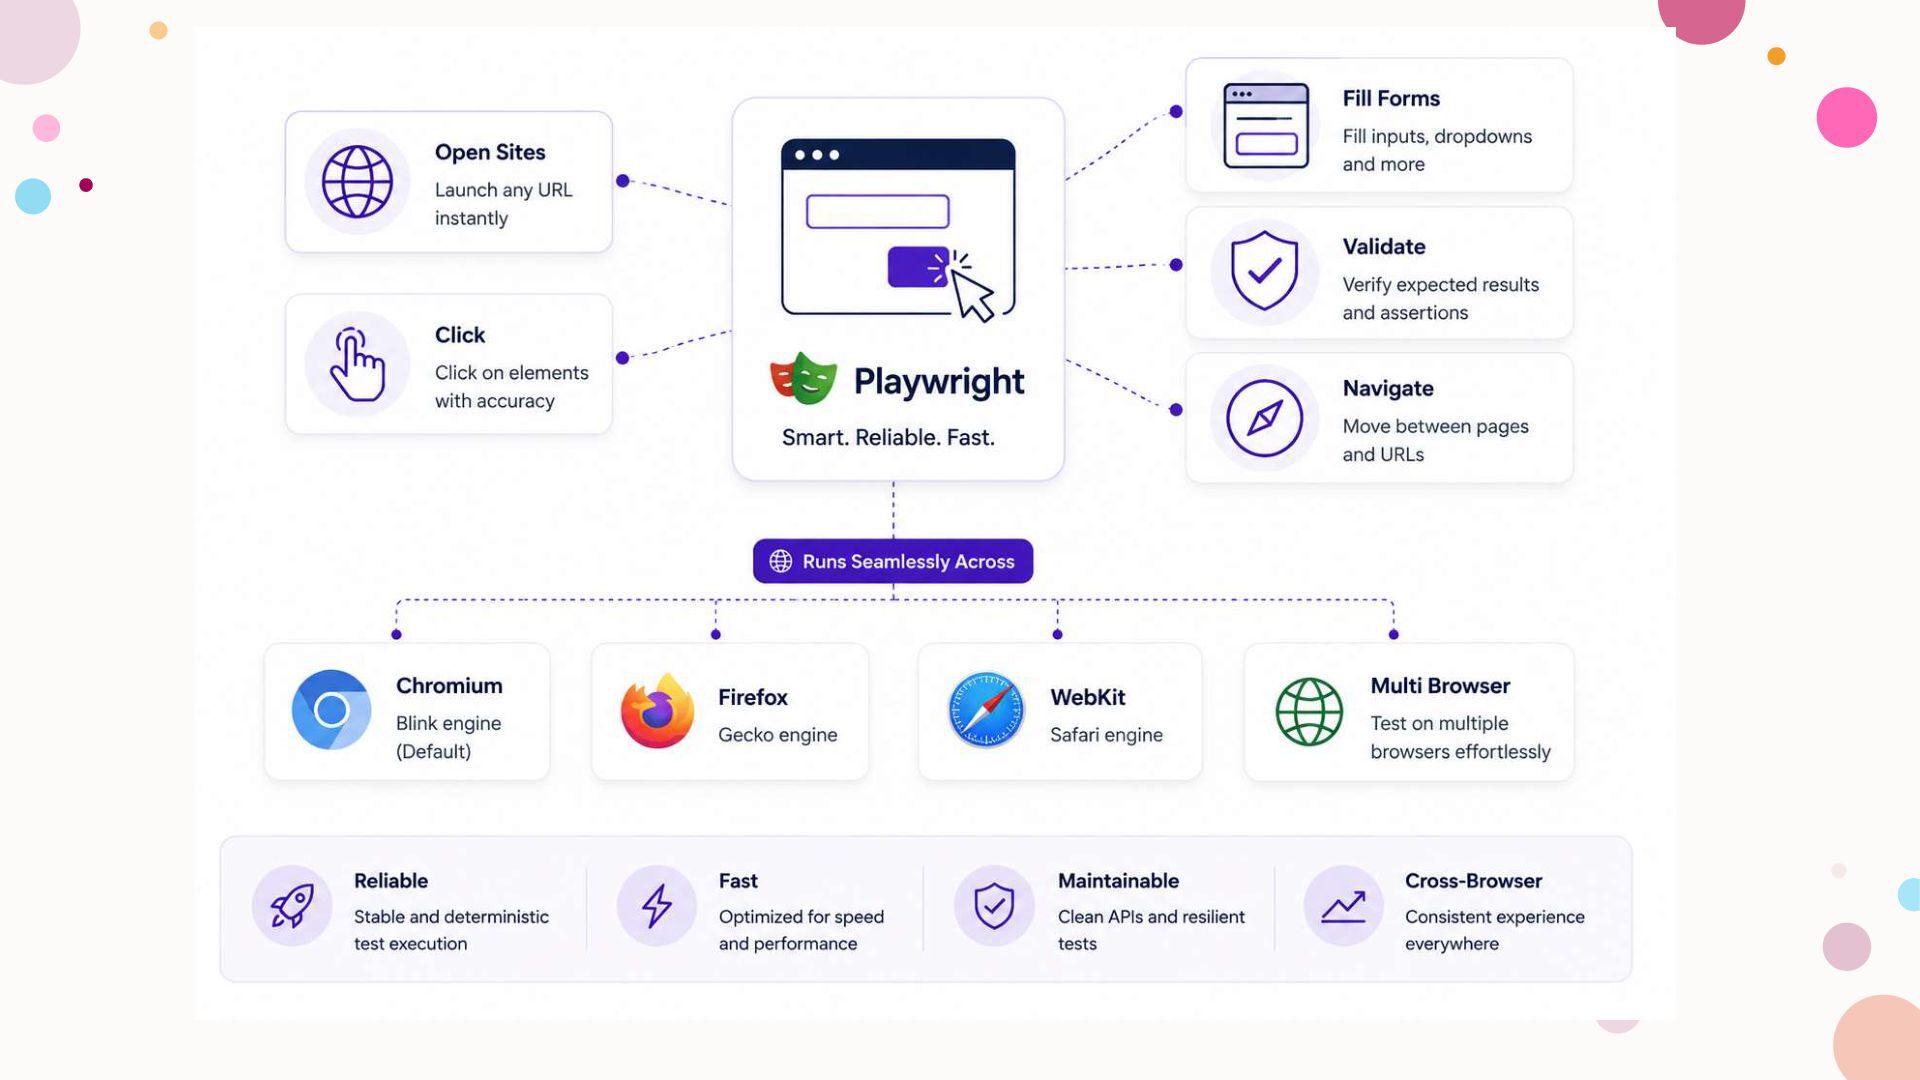
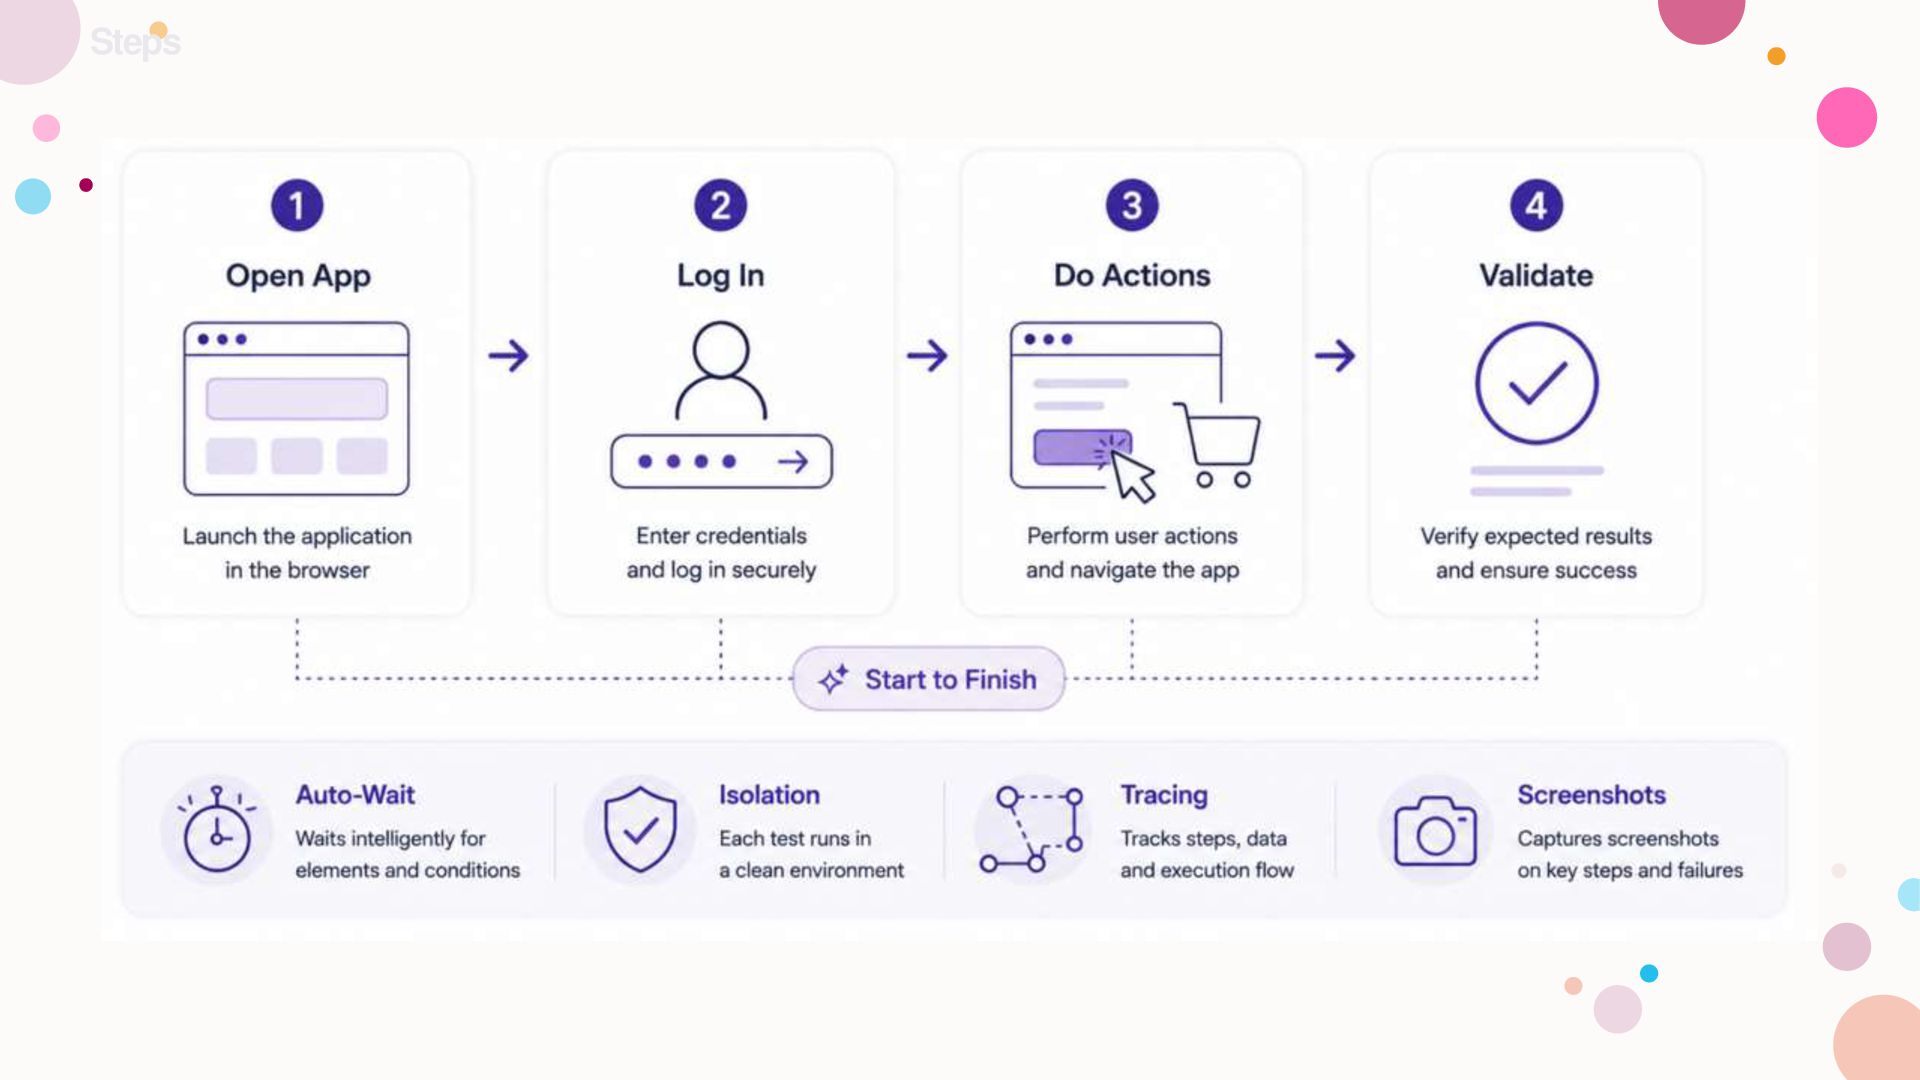
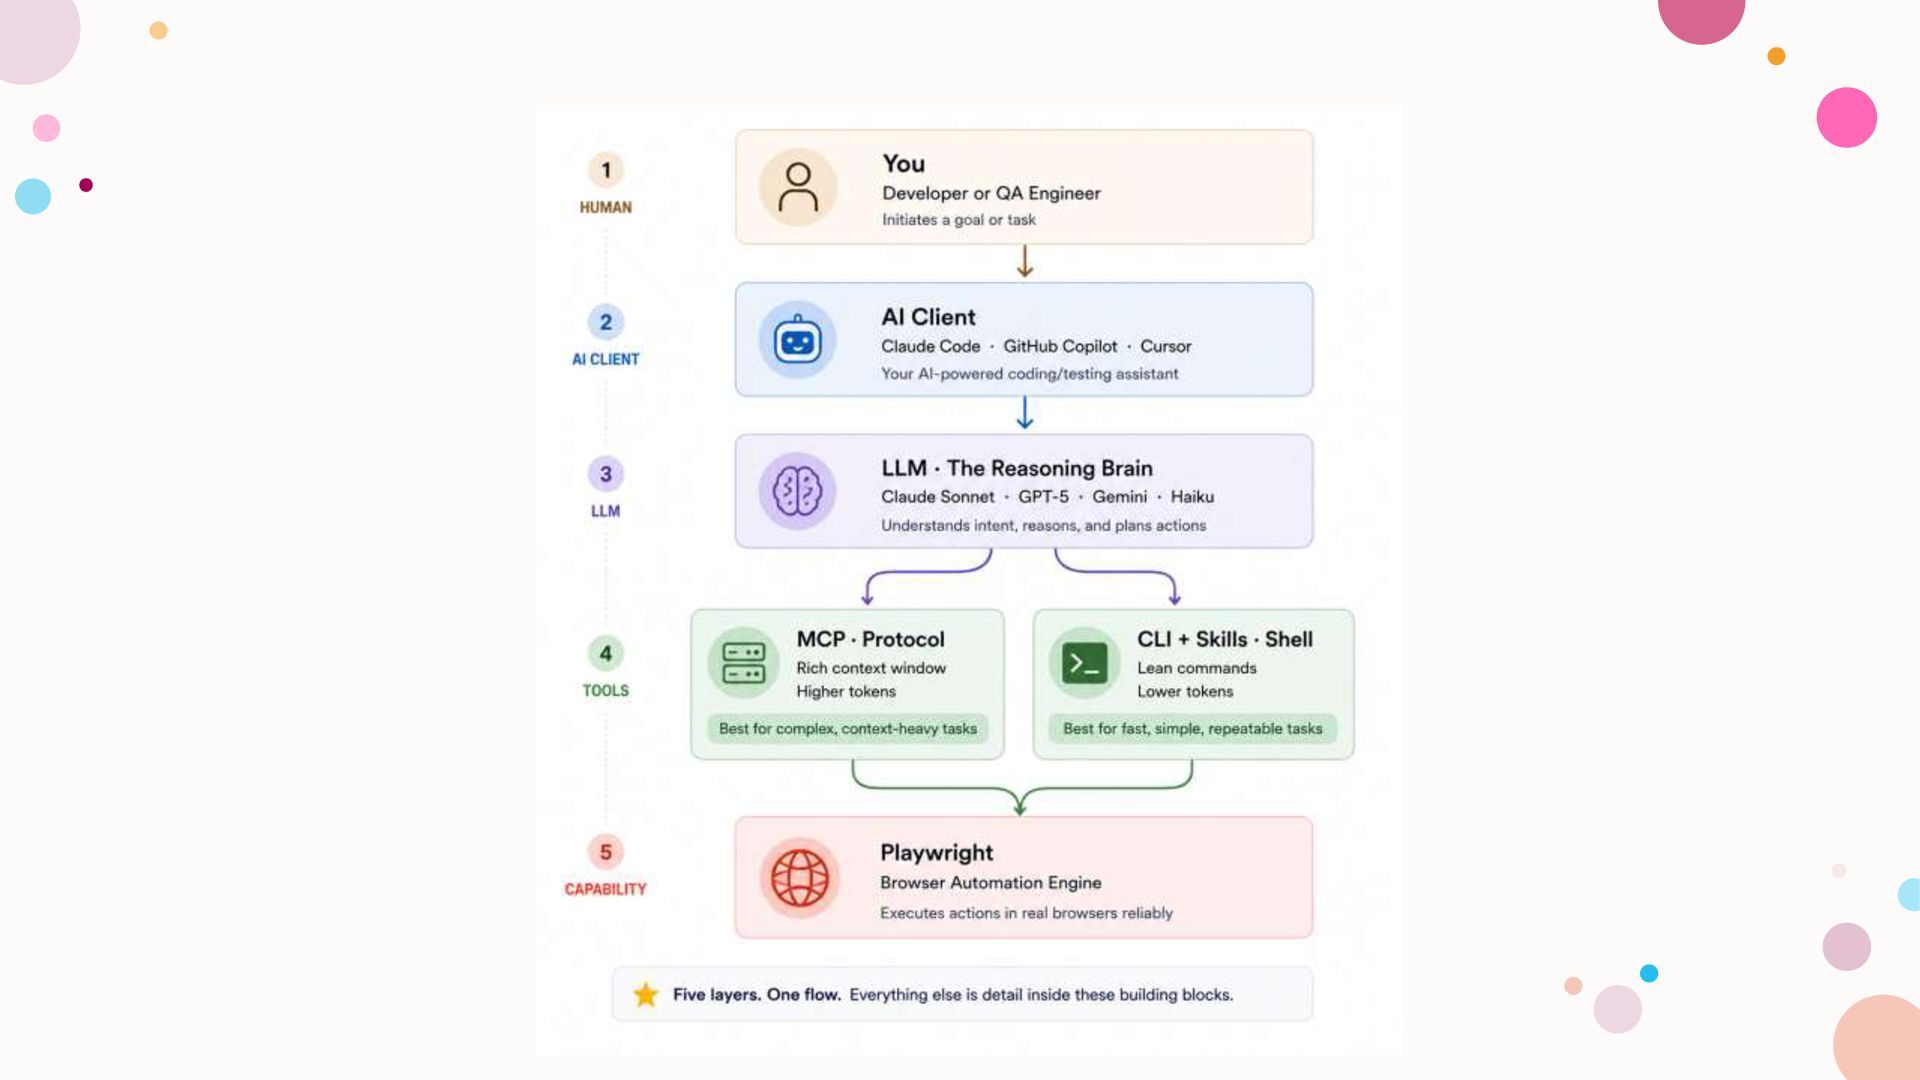
In this session, we explored agentic test automation with Playwright MCP, combining browser automation, AI reasoning, and reusable testing skills. Instead of writing every interaction as a rigid script, we'll show how an AI testing agent can understand a scenario, interact with the application, validate expected behavior, investigate failures, and produce meaningful test evidence.

We had discussed a practical demonstration of how Playwright MCP + AI agents + skills can create a new generation of adaptive test automation and the guardrails needed to make it reliable enough for real-world applications.

Avatar for Asif Waquar

Asif Waquar

September 03, 2026

More Decks by Asif Waquar

Other Decks in Technology

Transcript

  1. ABOUT THE SPEAKER Asif Waquar [ Solution Architect, Munich Re

    Singapore ] I am Asif Waquar, a Solutions Architect at Munich Re based in Singapore, where I design AI, cloud, and data platforms for reinsurance markets across APAC and the Middle East. I have been a Microsoft MVP for Azure and AI since 2021 and co-organise the Singapore Microsoft Tech Community, so I spend a lot of time in the space. This talk is based on the journey from the Copilot Chat era to Agentic AI what actually works, what doesn't, and what I wish someone had told me sooner.. [ Microsoft Azure MVP] [ linkedin.com/in/asifwaquar ] [ [email protected] ] [ asifwaquar.com ] EXPERTS LIVE MELBOURNE · [ DATE ] · [ MELBOURNE ] 03
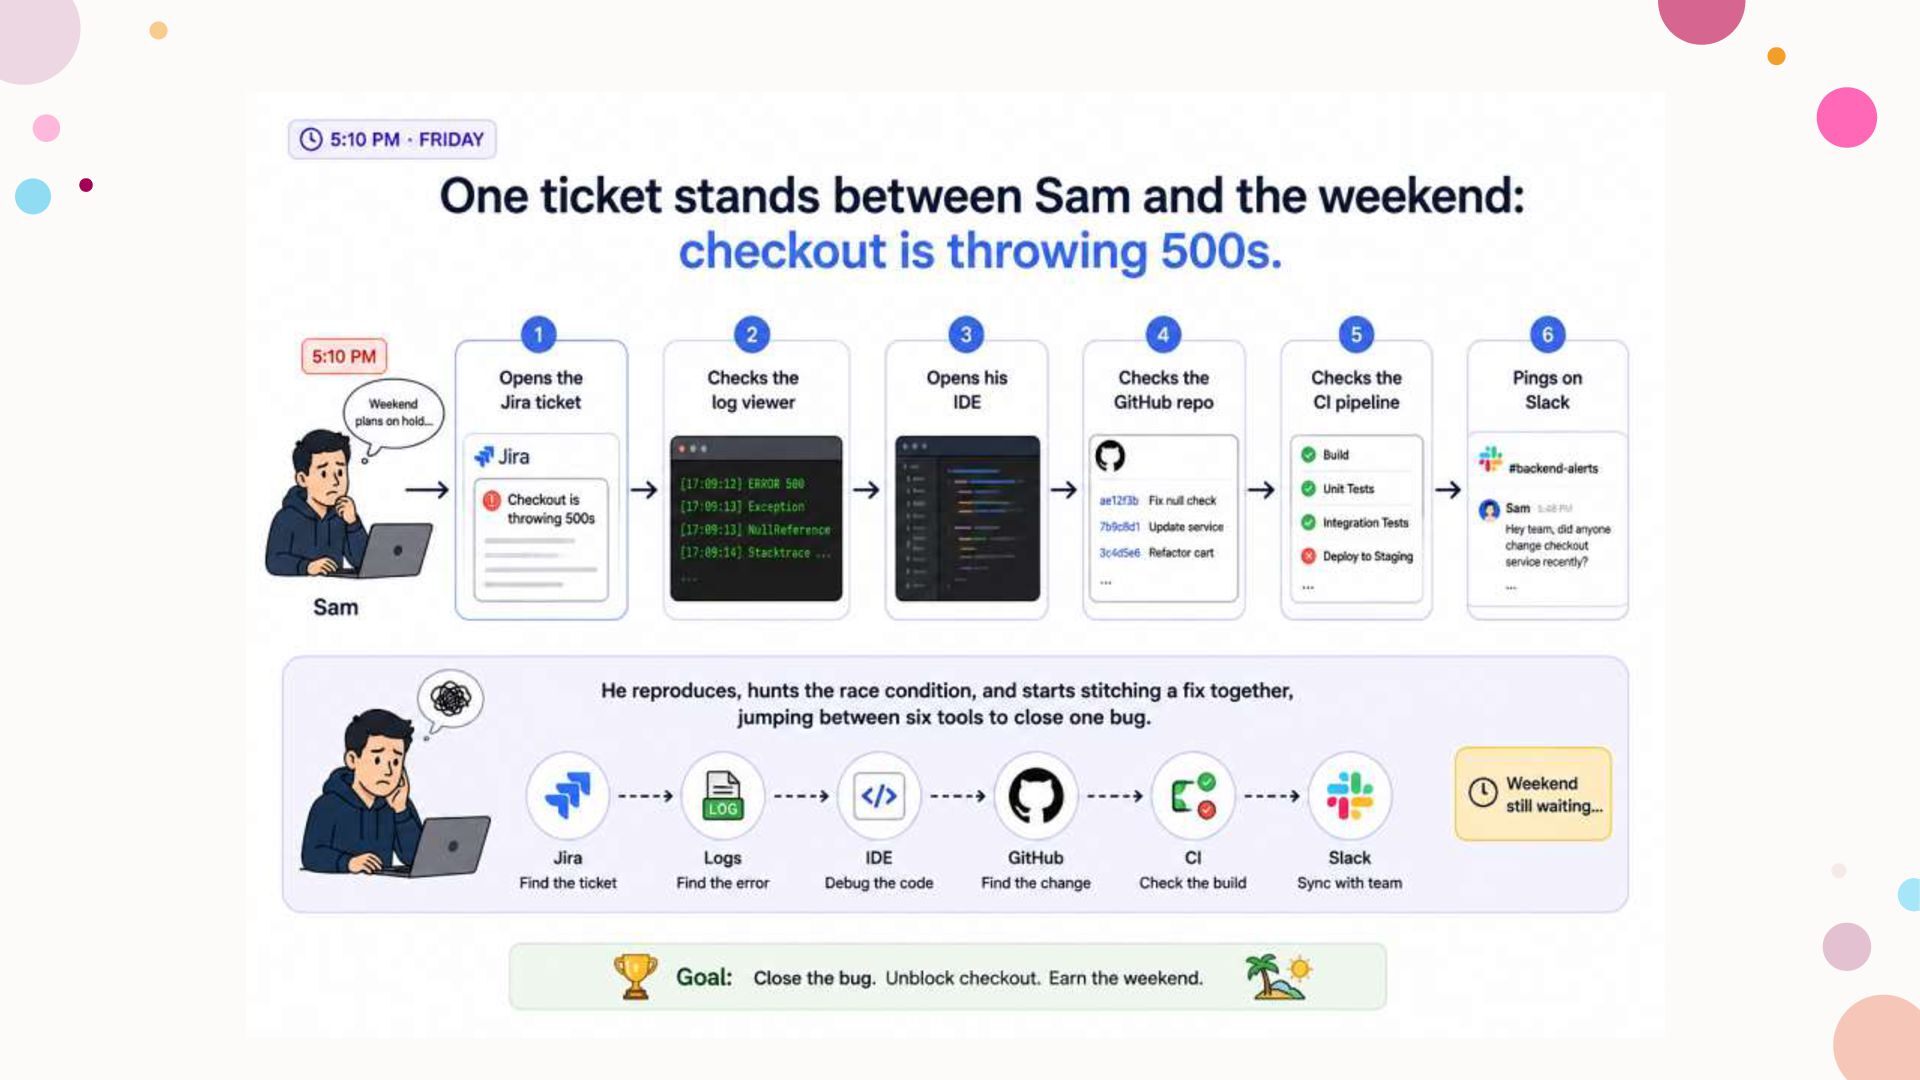
  2. Copilot finished the line. It didn't close the ticket. For

    three years we have made AI that suggests. The value Sam actually needed was not the autocompleted line - it was everything that happens after the line: reproduce, test, PR, ticket, review.
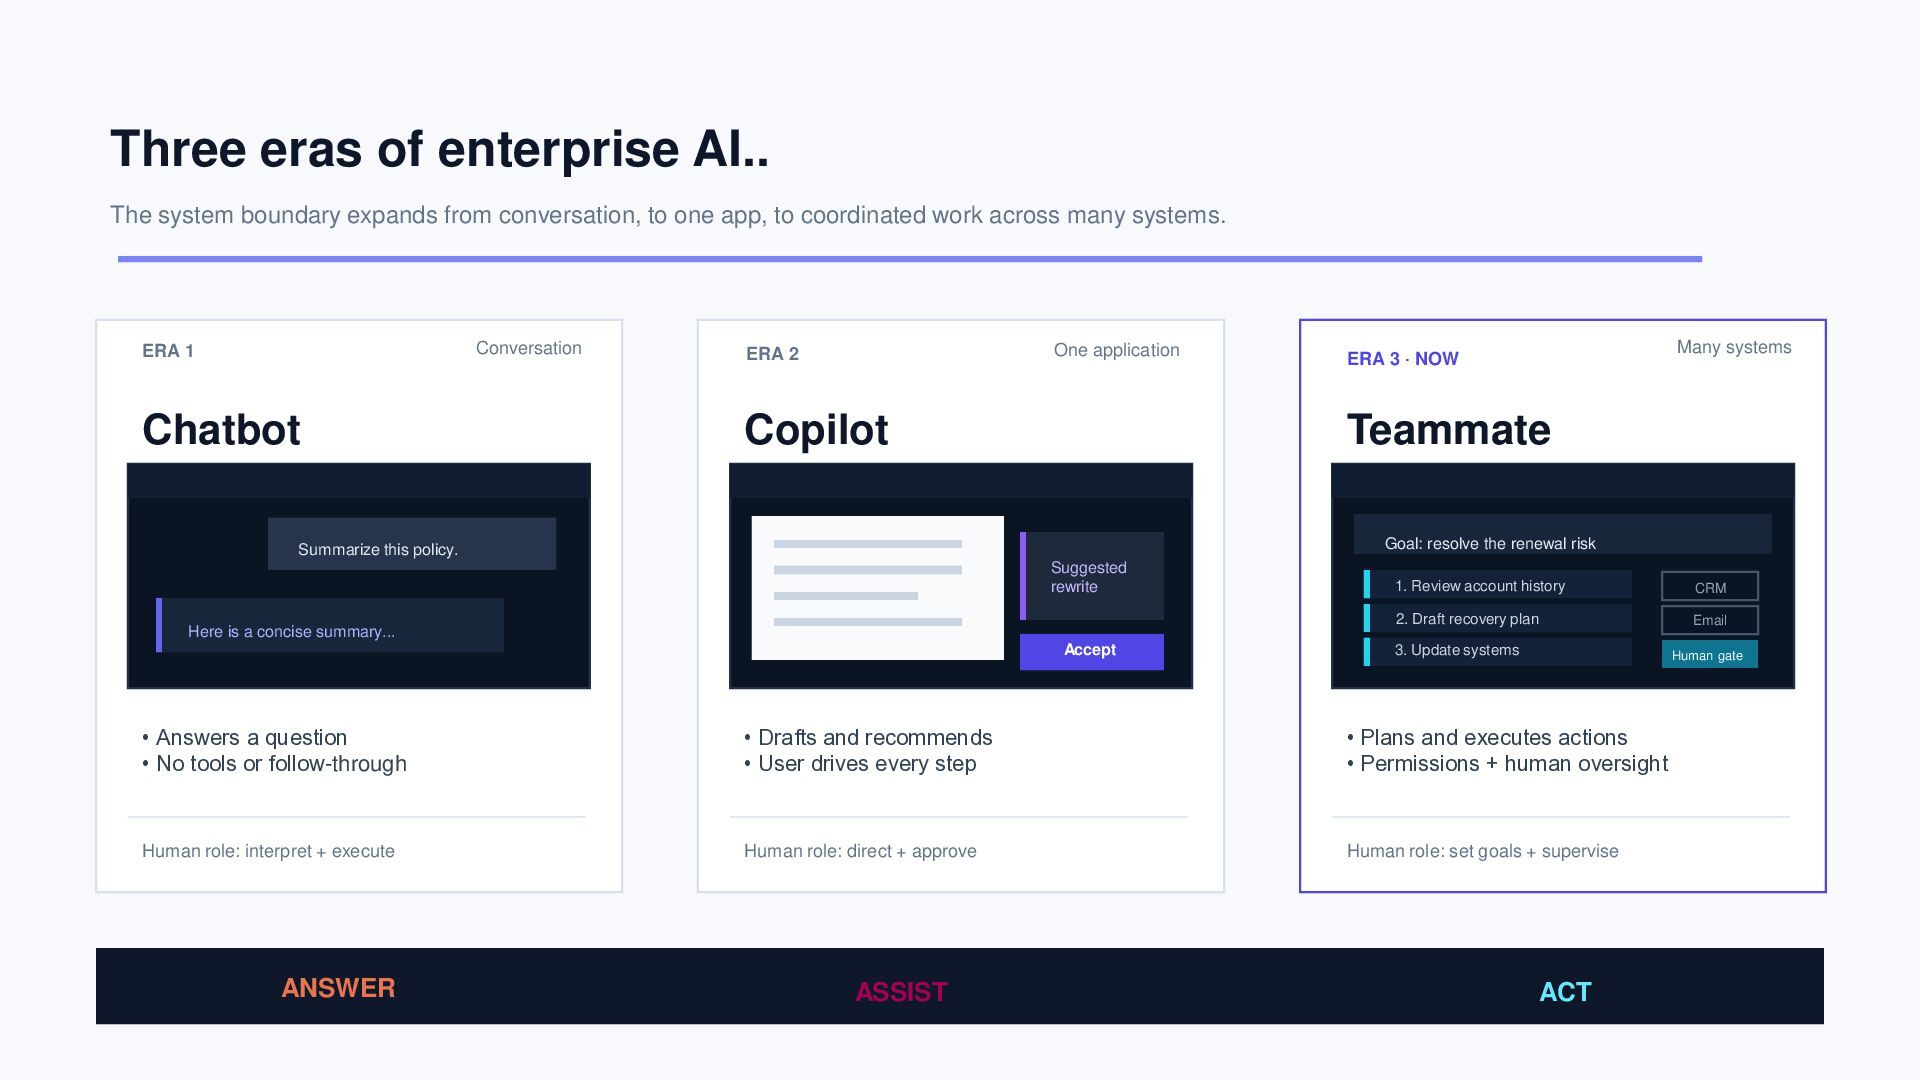
  3. Three eras of enterprise AI.. The system boundary expands from

    conversation, to one app, to coordinated work across many systems. Conversation ERA 1 Chatbot One application ERA 2 Copilot Many systems ERA 3 · NOW Teammate Goal: resolve the renewal risk Summarize this policy. Suggested rewrite Here is a concise summary... Accept 1. Review account history CRM 2. Draft recovery plan Email 3. Update systems Human gate • Answers a question • No tools or follow-through • Drafts and recommends • User drives every step • Plans and executes actions • Permissions + human oversight Human role: interpret + execute Human role: direct + approve Human role: set goals + supervise ANSWER ASSIST ACT
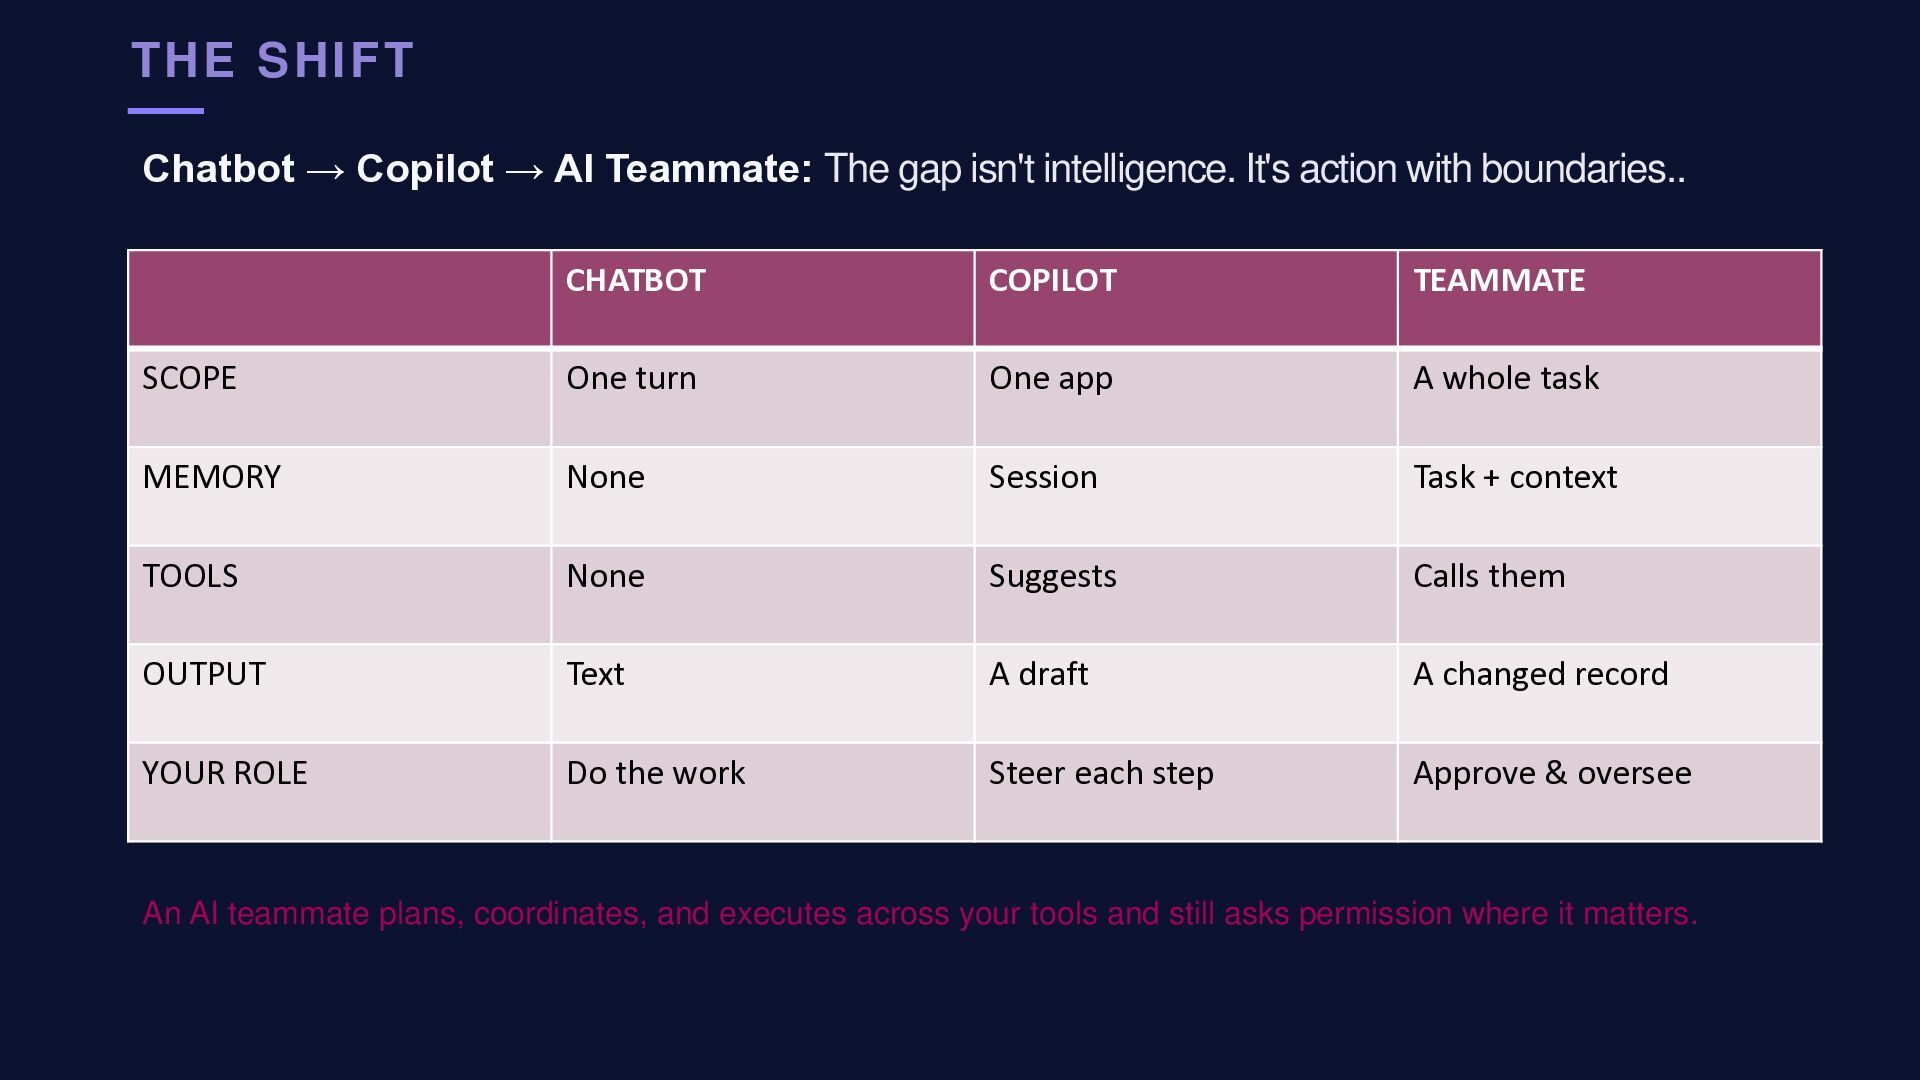
  4. THE SHIFT Chatbot → Copilot → AI Teammate: The gap

    isn't intelligence. It's action with boundaries.. CHATBOT COPILOT TEAMMATE SCOPE One turn One app A whole task MEMORY None Session Task + context TOOLS None Suggests Calls them OUTPUT Text A draft A changed record YOUR ROLE Do the work Steer each step Approve & oversee An AI teammate plans, coordinates, and executes across your tools and still asks permission where it matters.
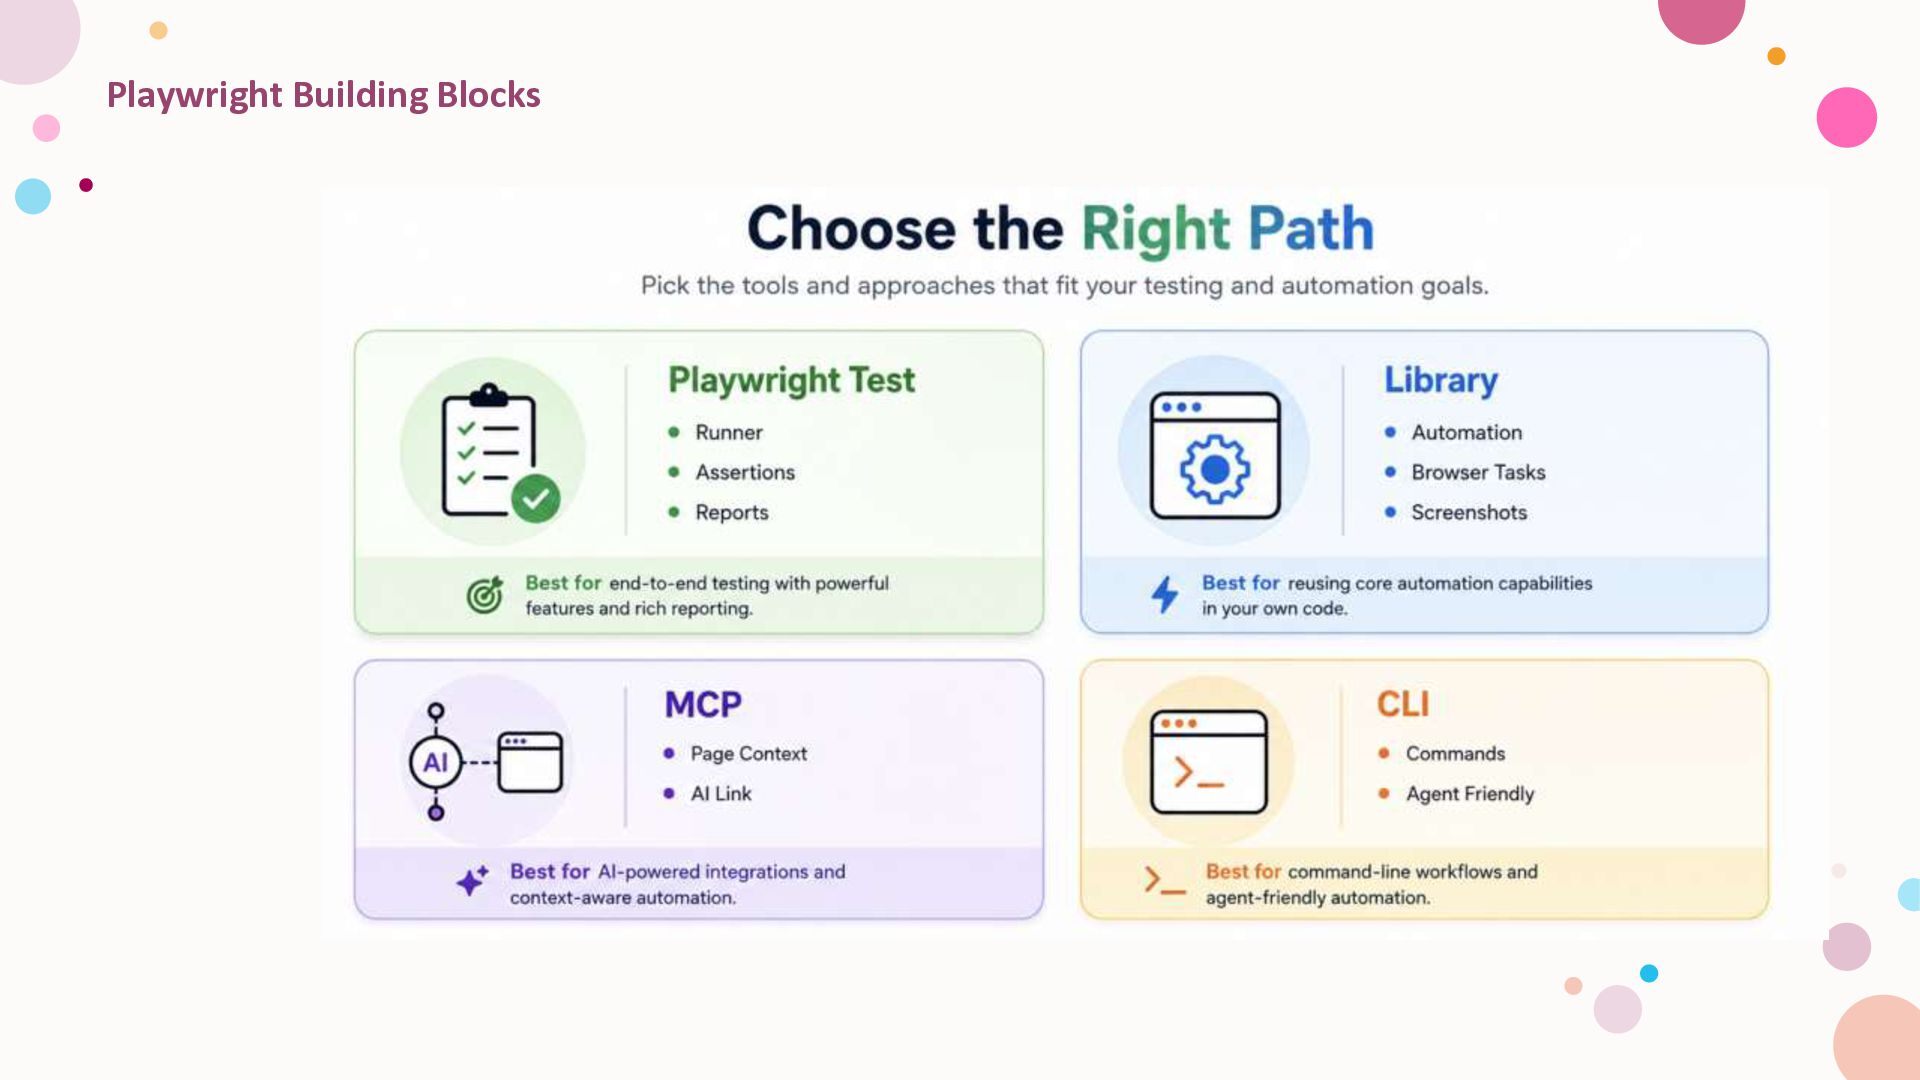
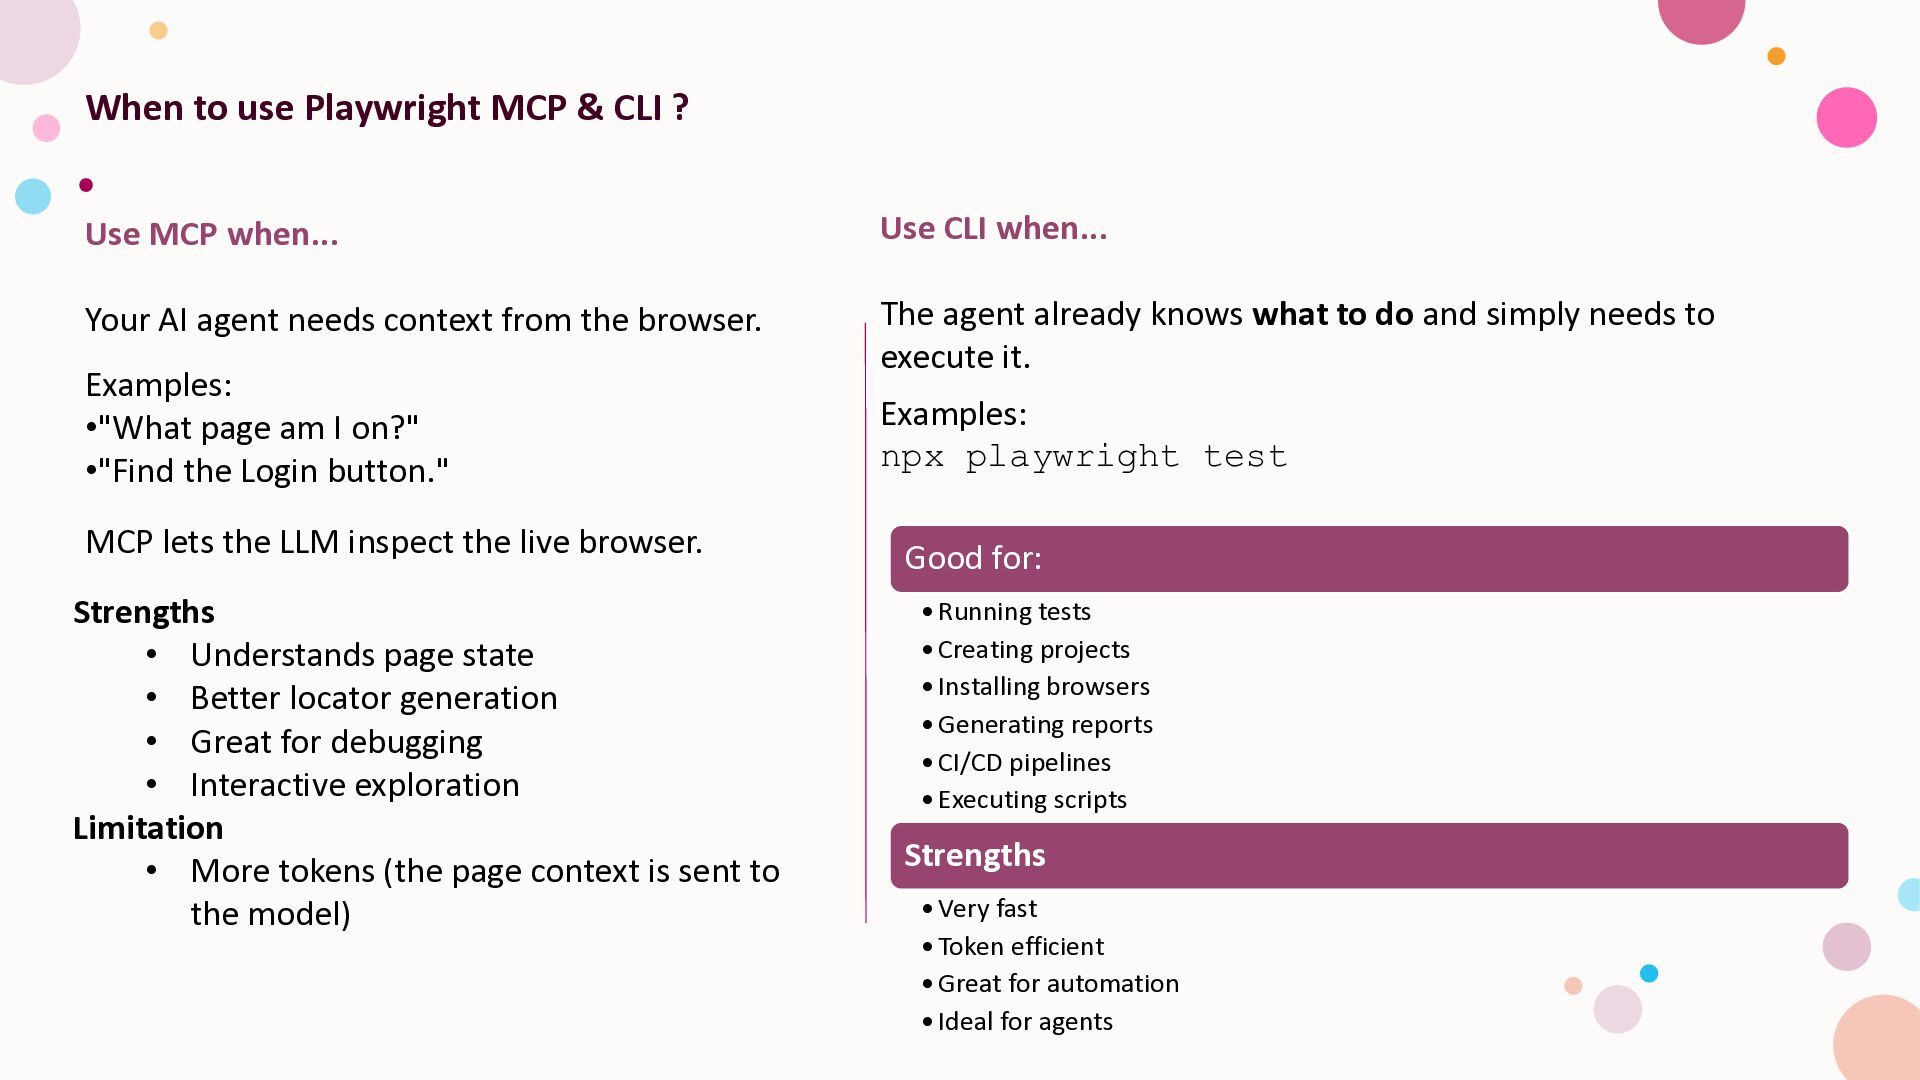
  5. When to use Playwright MCP & CLI ? Use MCP

    when... Use CLI when... Your AI agent needs context from the browser. The agent already knows what to do and simply needs to execute it. Examples: •"What page am I on?" •"Find the Login button." MCP lets the LLM inspect the live browser. Strengths • Understands page state • Better locator generation • Great for debugging • Interactive exploration Limitation • More tokens (the page context is sent to the model) Examples: npx playwright test Good for: • Running tests • Creating projects • Installing browsers • Generating reports • CI/CD pipelines • Executing scripts Strengths • Very fast • Token efficient • Great for automation • Ideal for agents
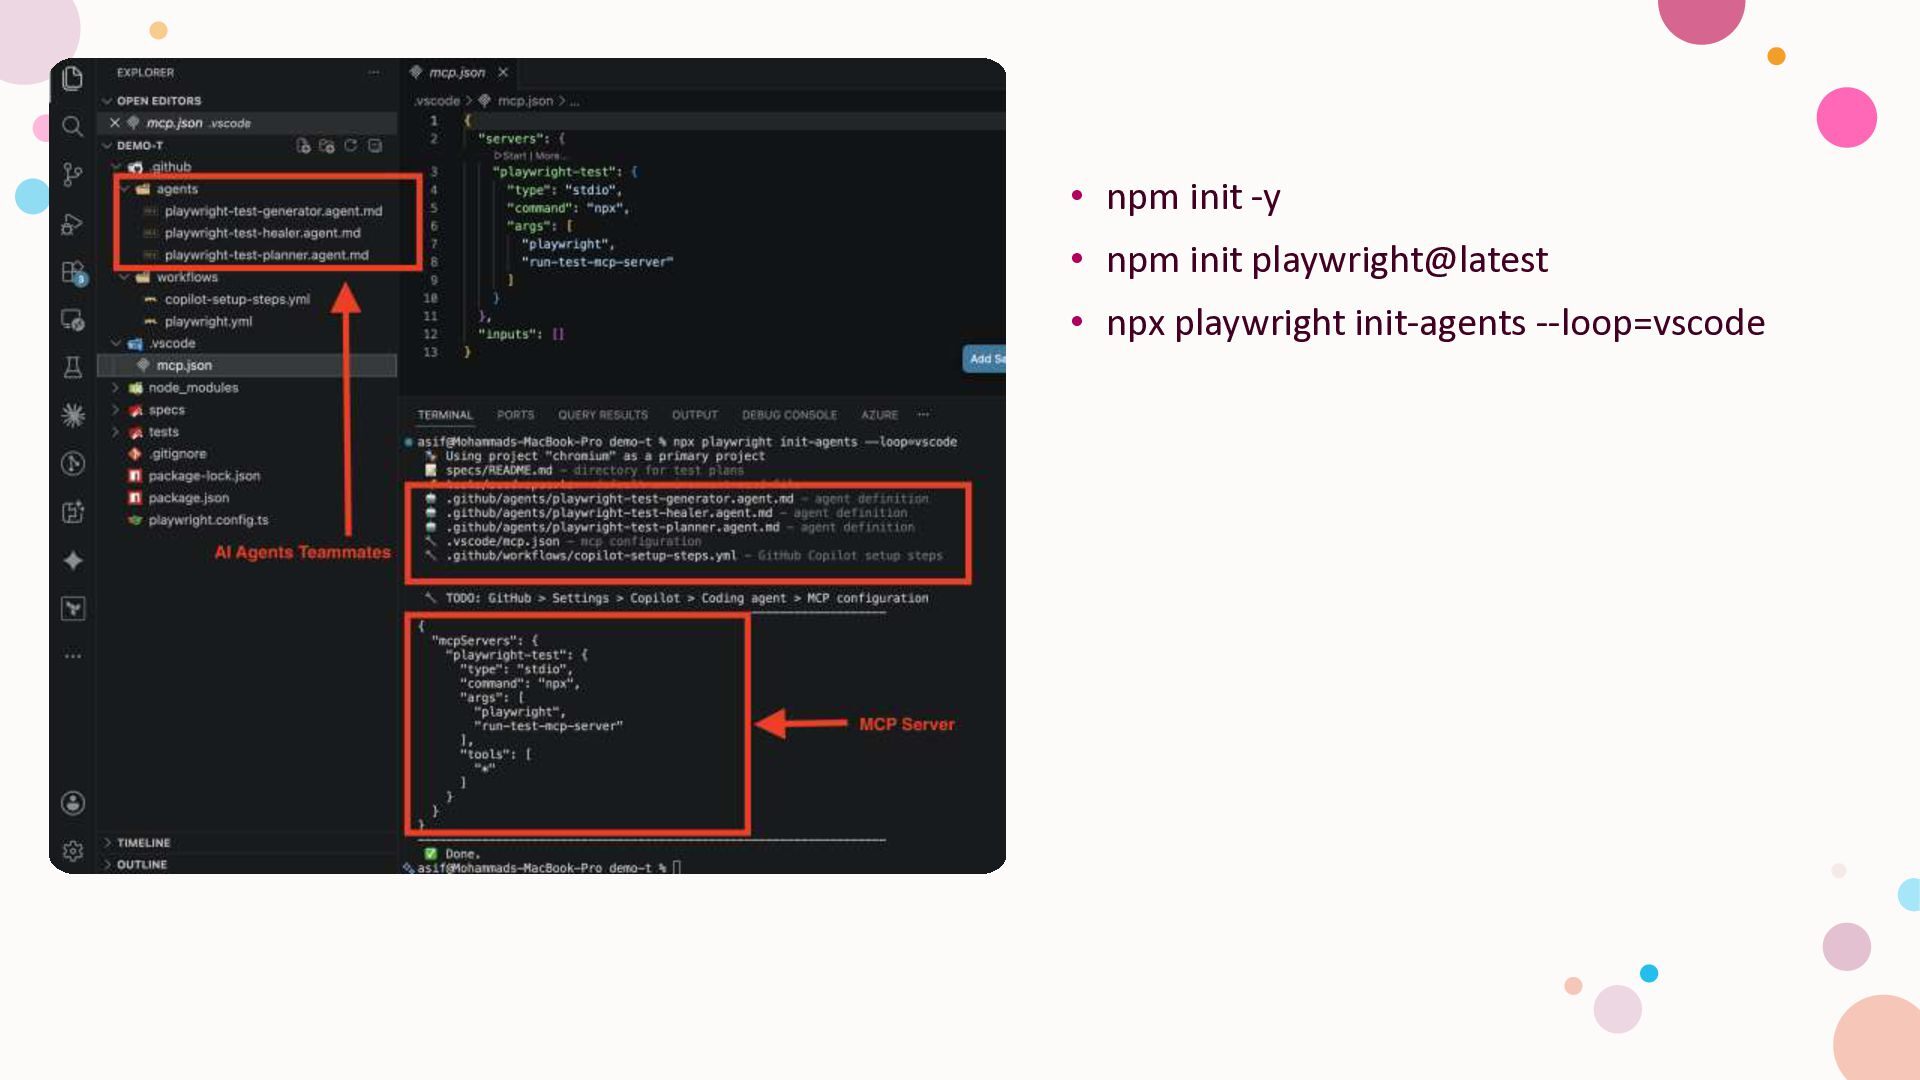
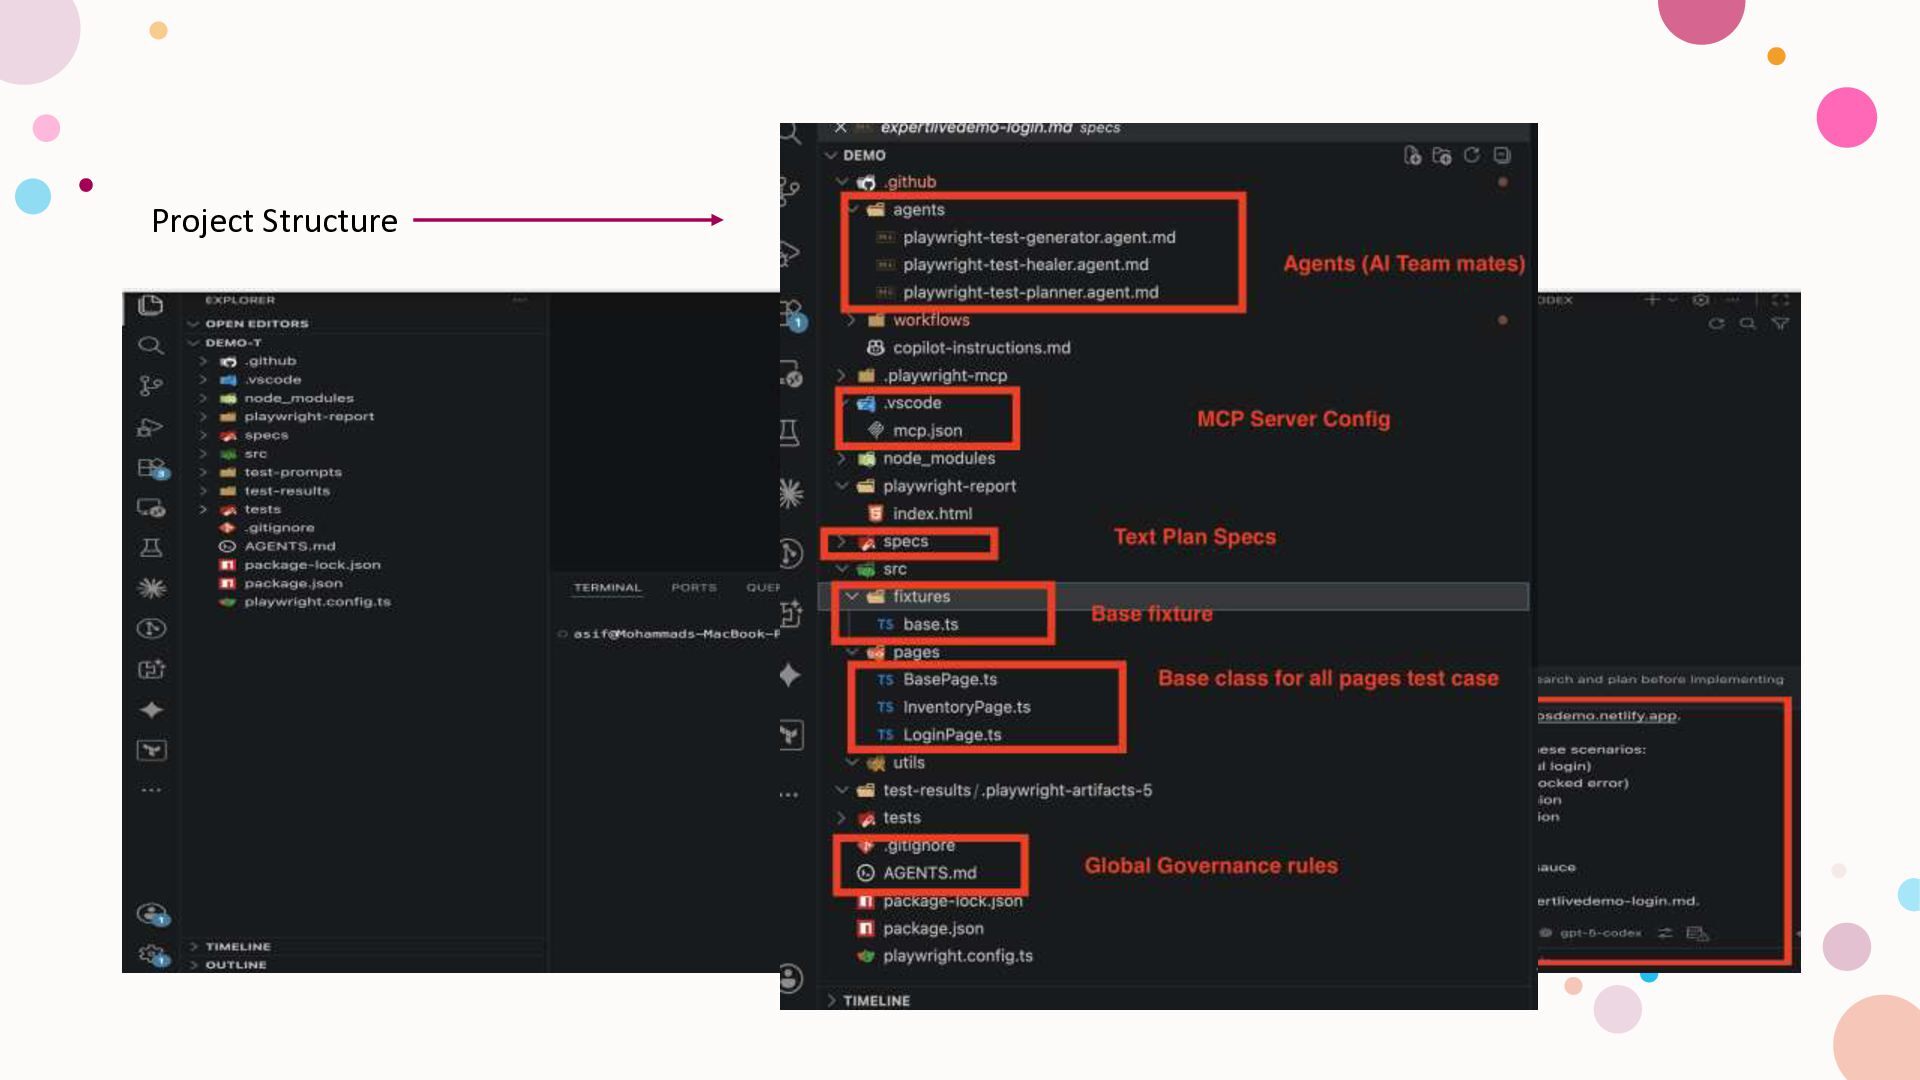
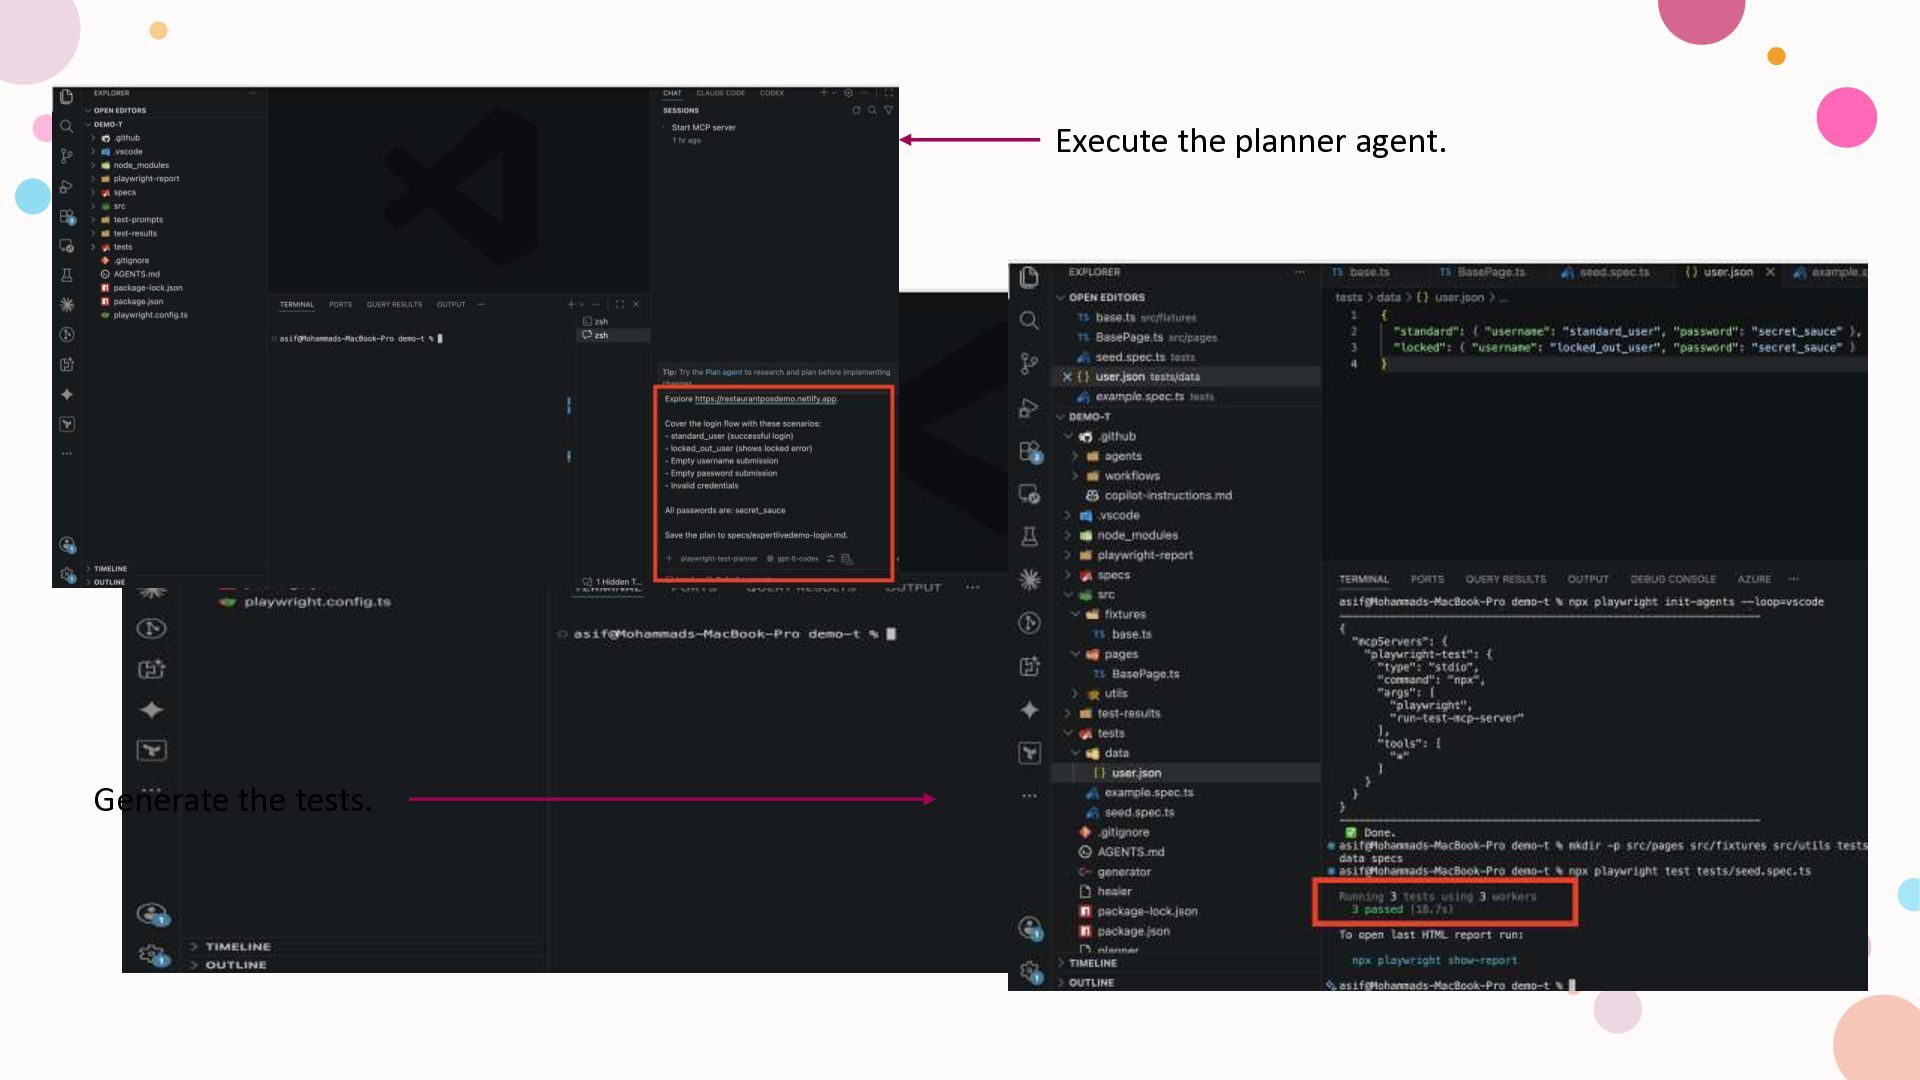
  6. • npm init -y • npm init playwright@latest • npx

    playwright init-agents --loop=vscode
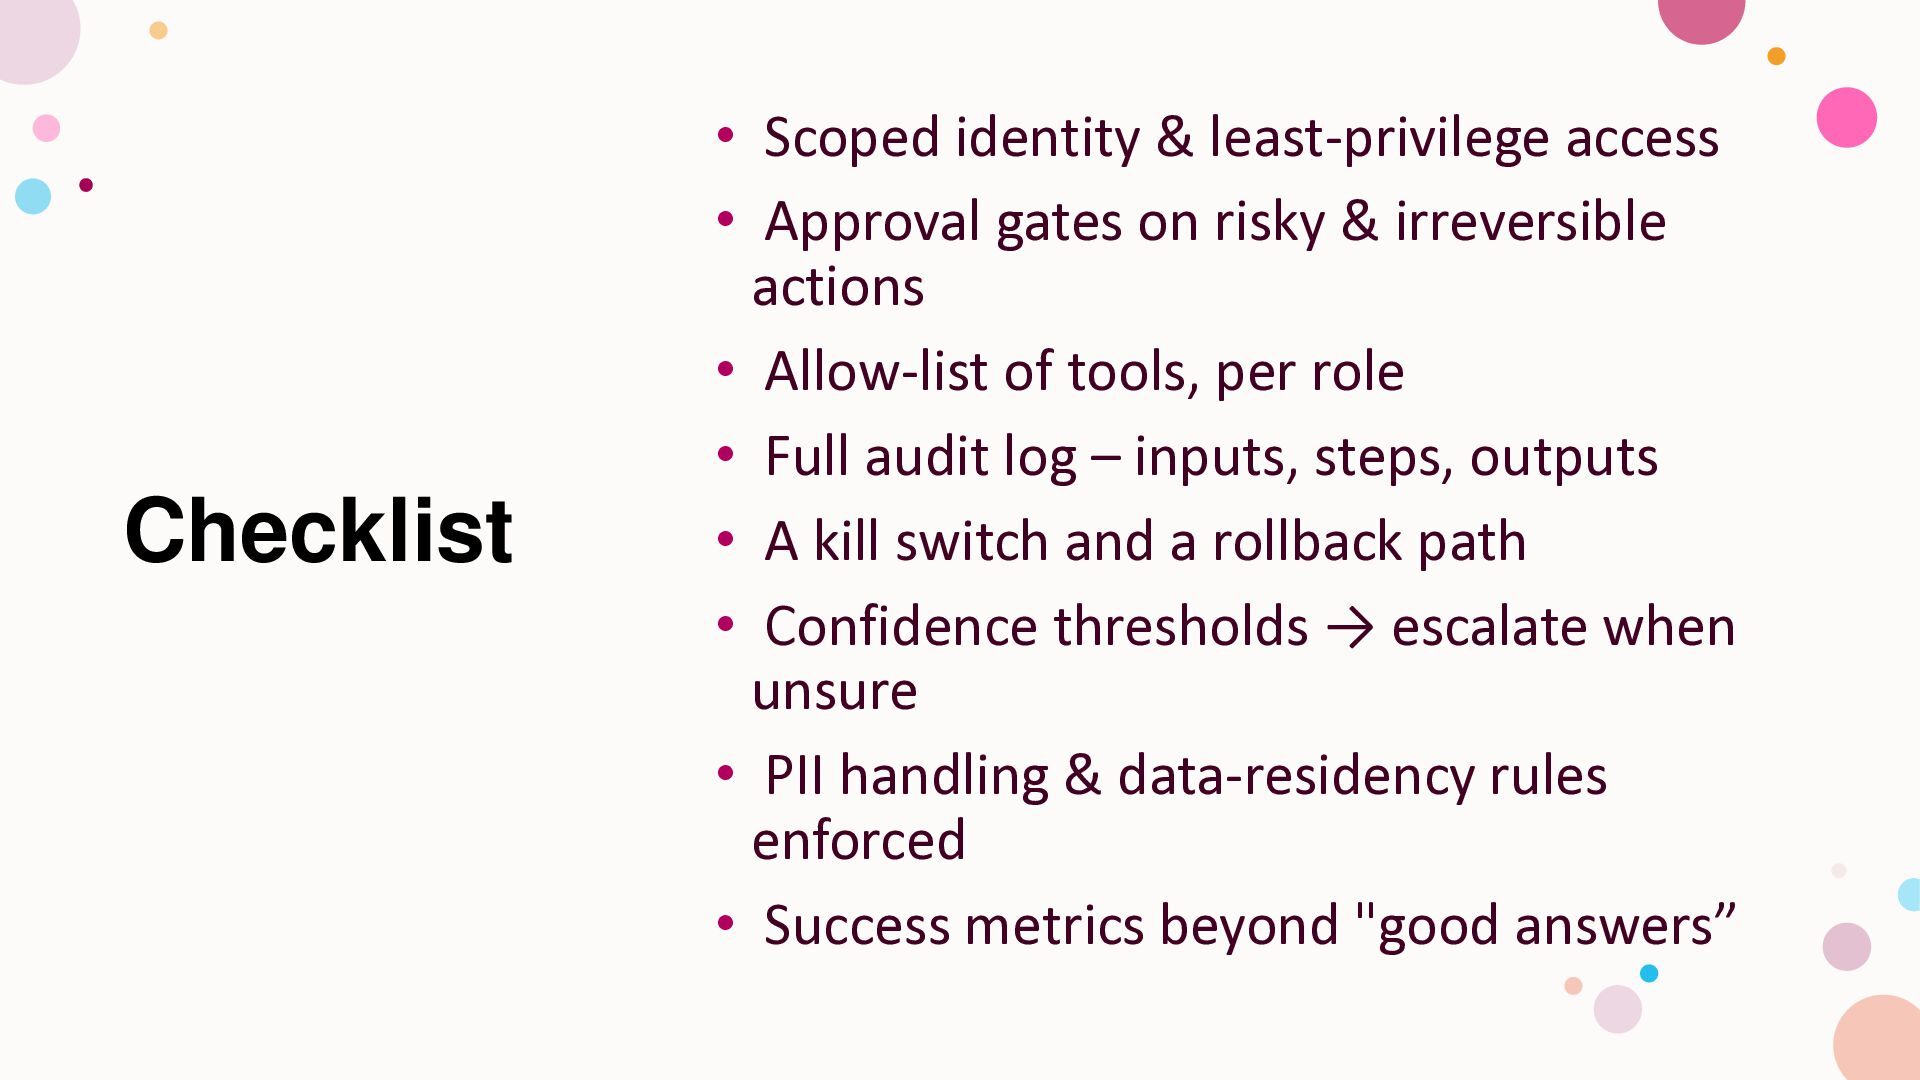
  7. Checklist • Scoped identity & least-privilege access • Approval gates

    on risky & irreversible actions • Allow-list of tools, per role • Full audit log – inputs, steps, outputs • A kill switch and a rollback path • Confidence thresholds → escalate when unsure • PII handling & data-residency rules enforced • Success metrics beyond "good answers”
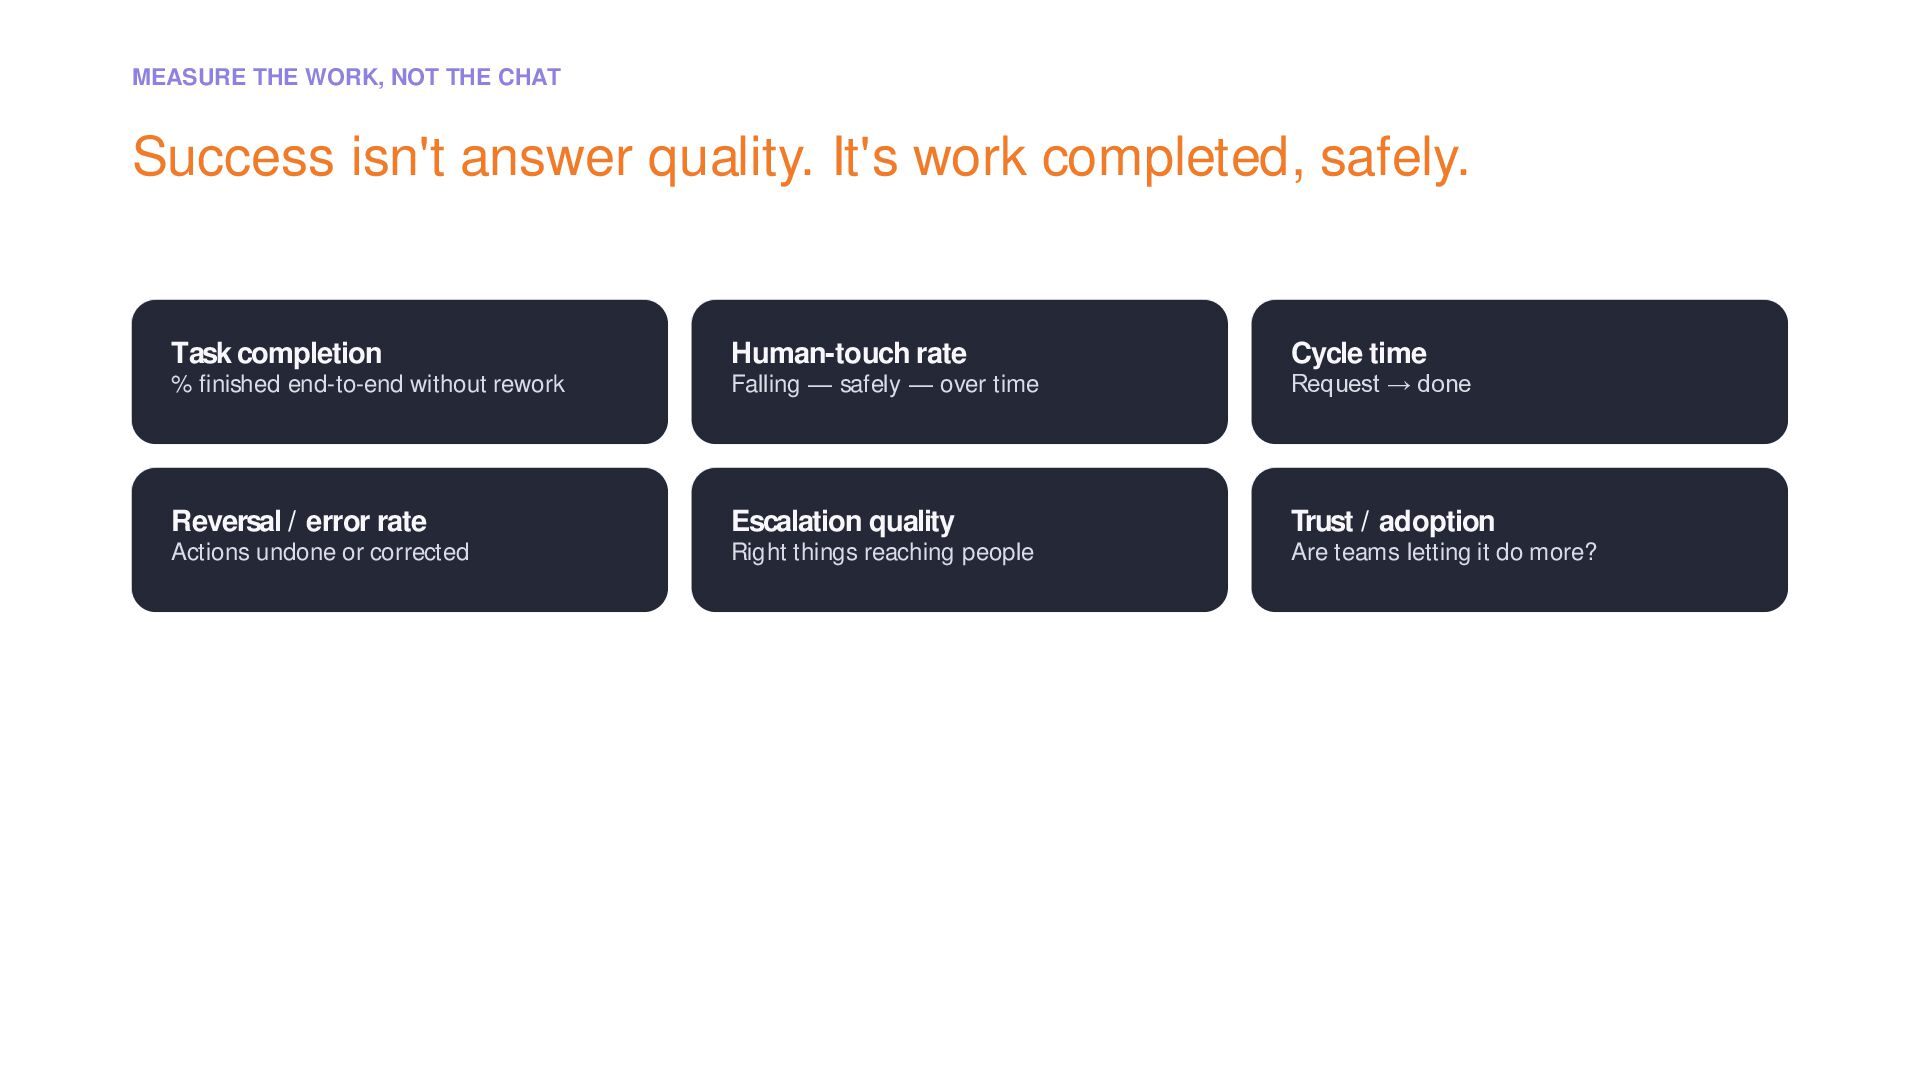
  8. MEASURE THE WORK, NOT THE CHAT Success isn't answer quality.

    It's work completed, safely. Task completion Human-touch rate Cycle time % finished end-to-end without rework Falling — safely — over time Request → done Reversal / error rate Escalation quality Trust / adoption Actions undone or corrected Right things reaching people Are teams letting it do more?
  9. The winners won't have the smartest model. They will have

    the bestmanaged teammate. AI is becoming a teammate. Your job is to be the manager: set the goal, set the guardrails, and stay on the line. Give it boundaries and trust it inside them.
  10. Q/A