Share
Embed
BrownBag presentation of Paris MongoDBDays 2013
Vmeyet
December 17, 2013
Transcript
48 slides
-
Mission: Give the best tools to handle challenges of today
use of data. Designed for how we build and run application today. MongoDB Meetup at Free online formation: Mongo University 5.000.000+ Download MongoDB Management Service (MMS) ◦ Cloud based suite ◦ Monitoring & Backup -
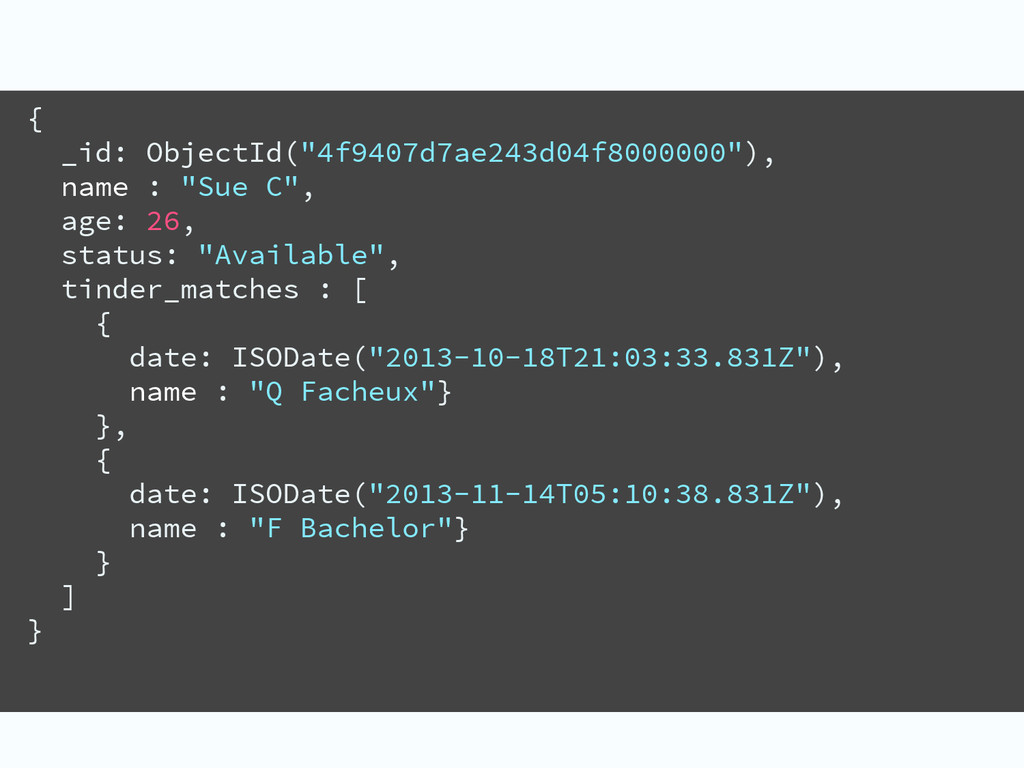
{ _id: ObjectId("4f9407d7ae243d04f8000000"), name : "Sue C", age: 26, status:
"Available", tinder_matches : [ { date: ISODate("2013-10-18T21:03:33.831Z"), name : "Q Facheux"} }, { date: ISODate("2013-11-14T05:10:38.831Z"), name : "F Bachelor"} } ] } -
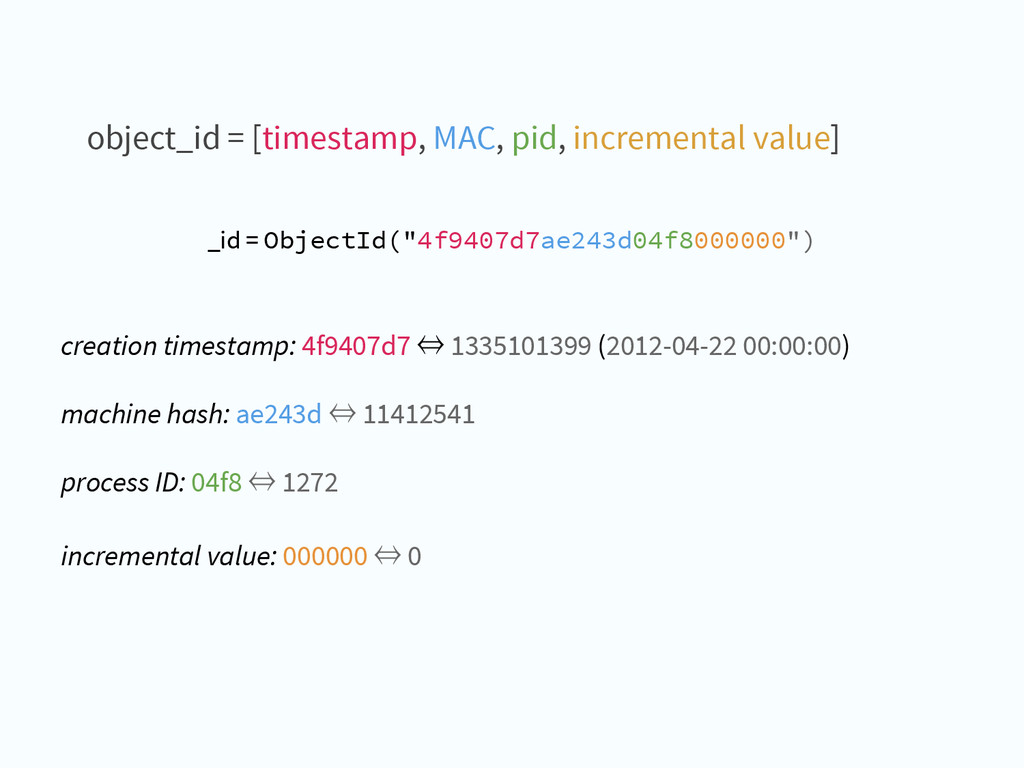
_id = ObjectId("4f9407d7ae243d04f8000000") creation timestamp: 4f9407d7 ⇔ 1335101399 (2012-04-22 00:00:00)
machine hash: ae243d ⇔ 11412541 process ID: 04f8 ⇔ 1272 incremental value: 000000 ⇔ 0 object_id = [timestamp, MAC, pid, incremental value] -
Mongo is Schemaless but ... Success comes from a great
data structure RDBMS focus on data storage MongoDB focus on data use storage is cheap anyway We start building the app and let the schema evolve -
Mongo is Relationless but ... Embedding crazy fast reading /
slow writing / data integrity issues Referencing slow reading / flexible / data integrity -
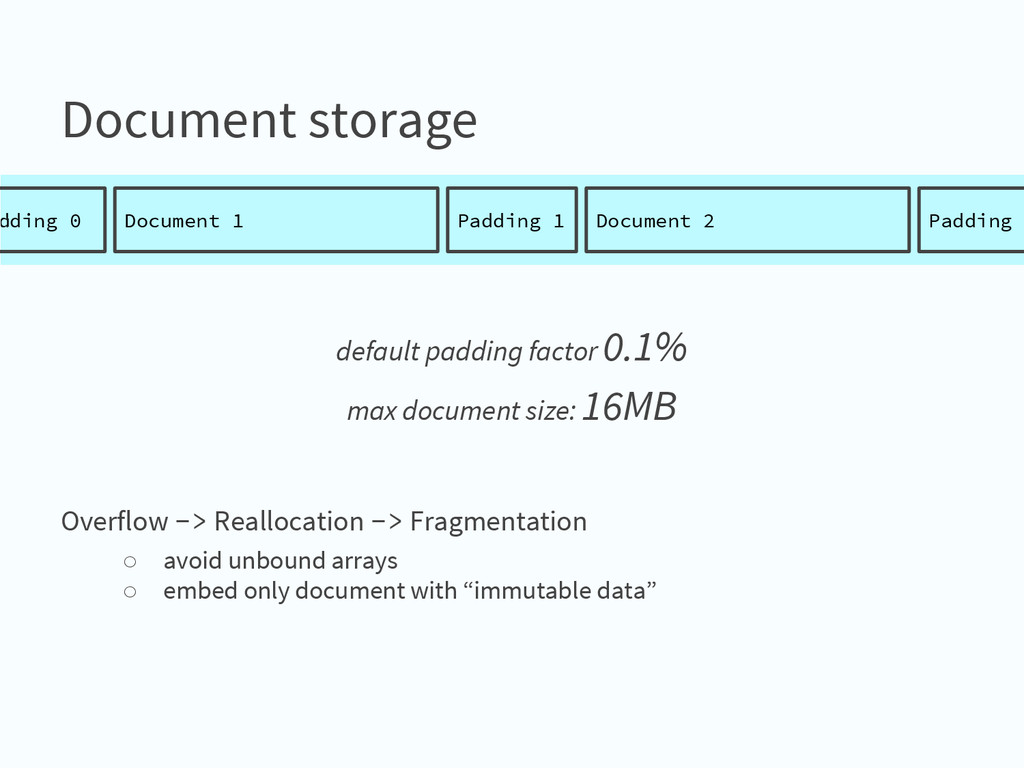
Document storage default padding factor 0.1% max document size: 16MB
Overflow -> Reallocation -> Fragmentation ◦ avoid unbound arrays ◦ embed only document with “immutable data” Padding 1 Document 1 Document 2 Padding dding 0 -
Schema migration Migrate all Migrate on demand (preferred) migrate the
document at use time No migration let code handles it -
Whut ? Why ? Node Failure Network Latency Down Time
Rolling Upgrade start with secondary, primary last -
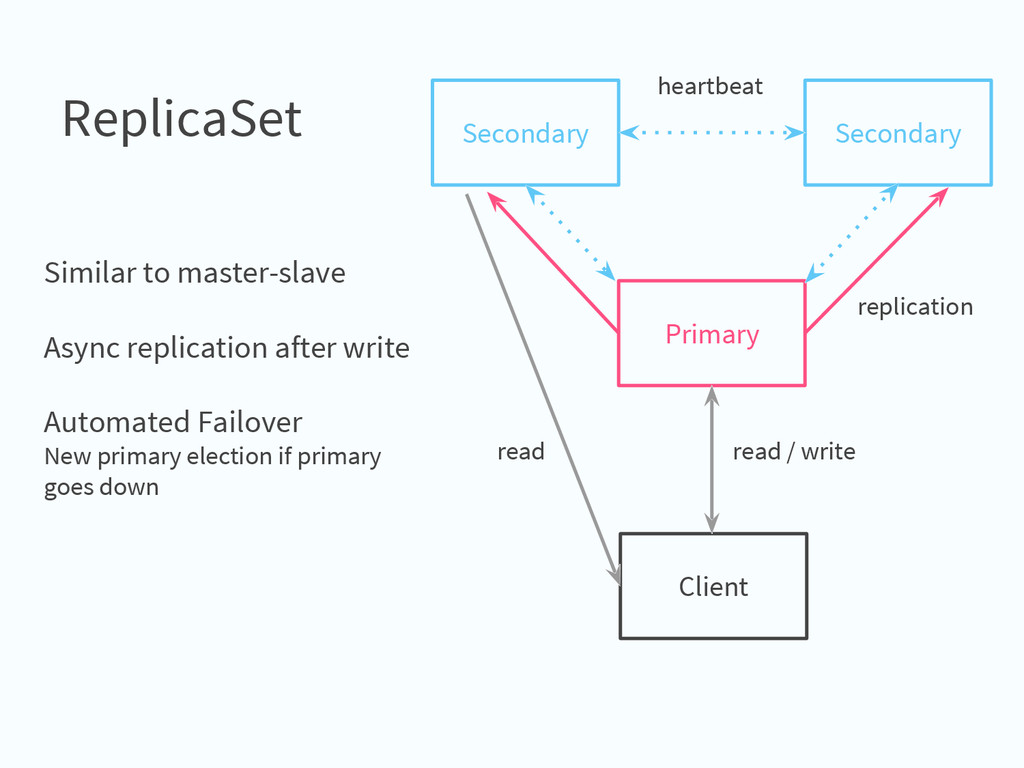
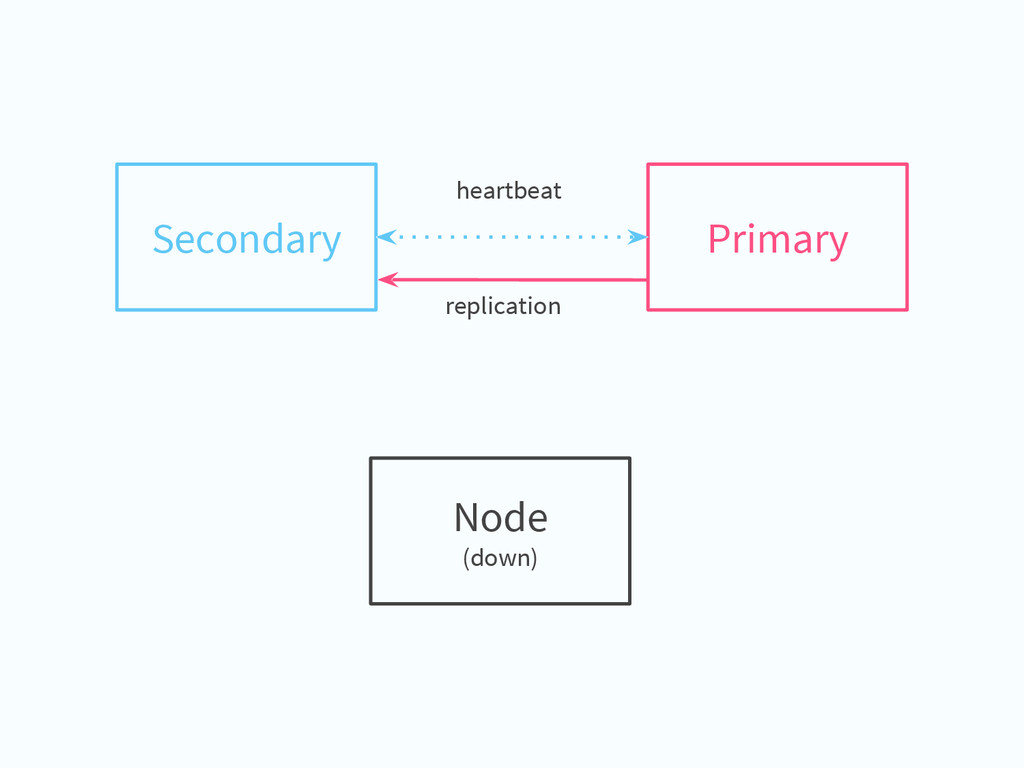
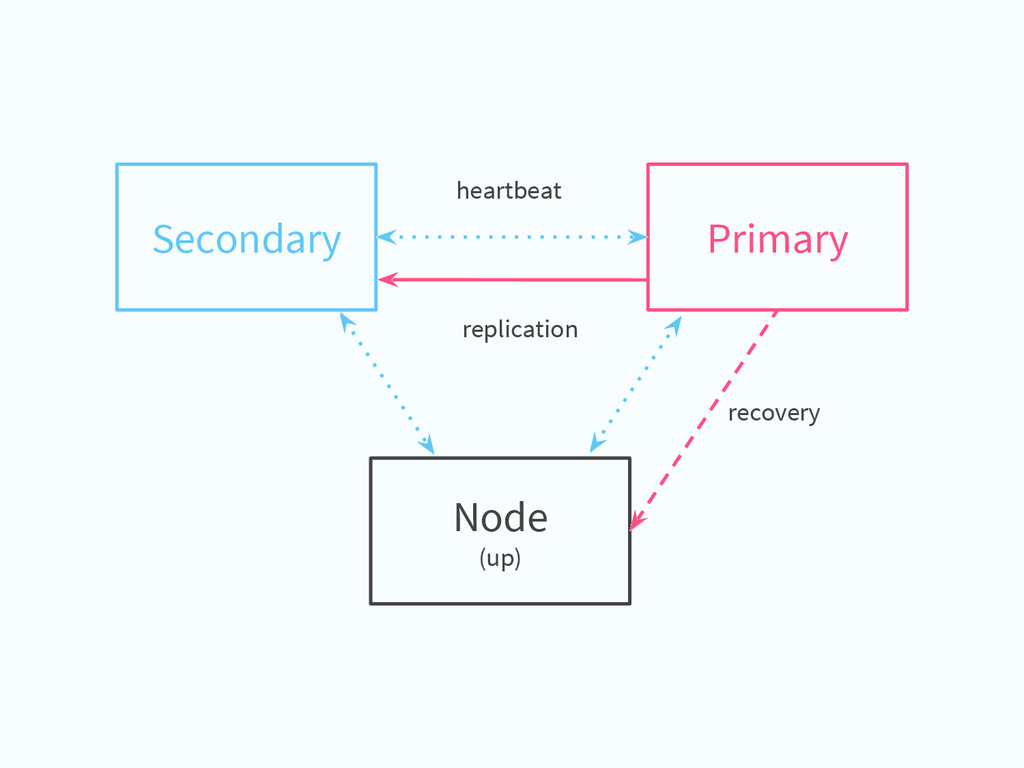
Secondary Secondary Primary heartbeat read / write Client replication read
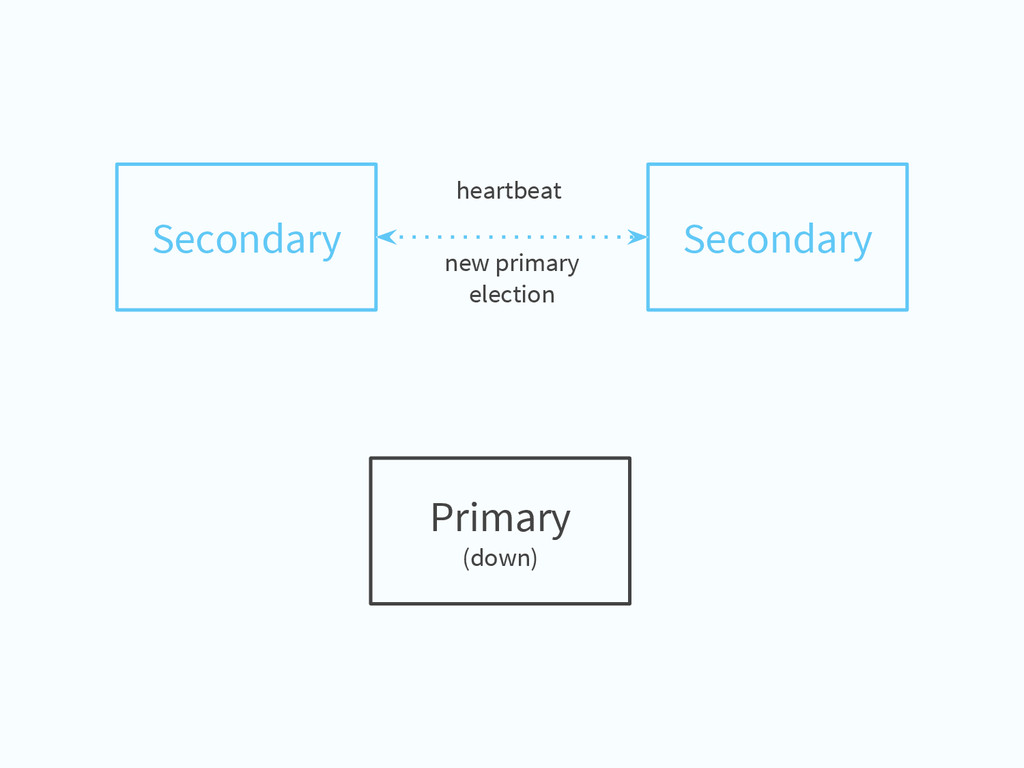
ReplicaSet Similar to master-slave Async replication after write Automated Failover New primary election if primary goes down -
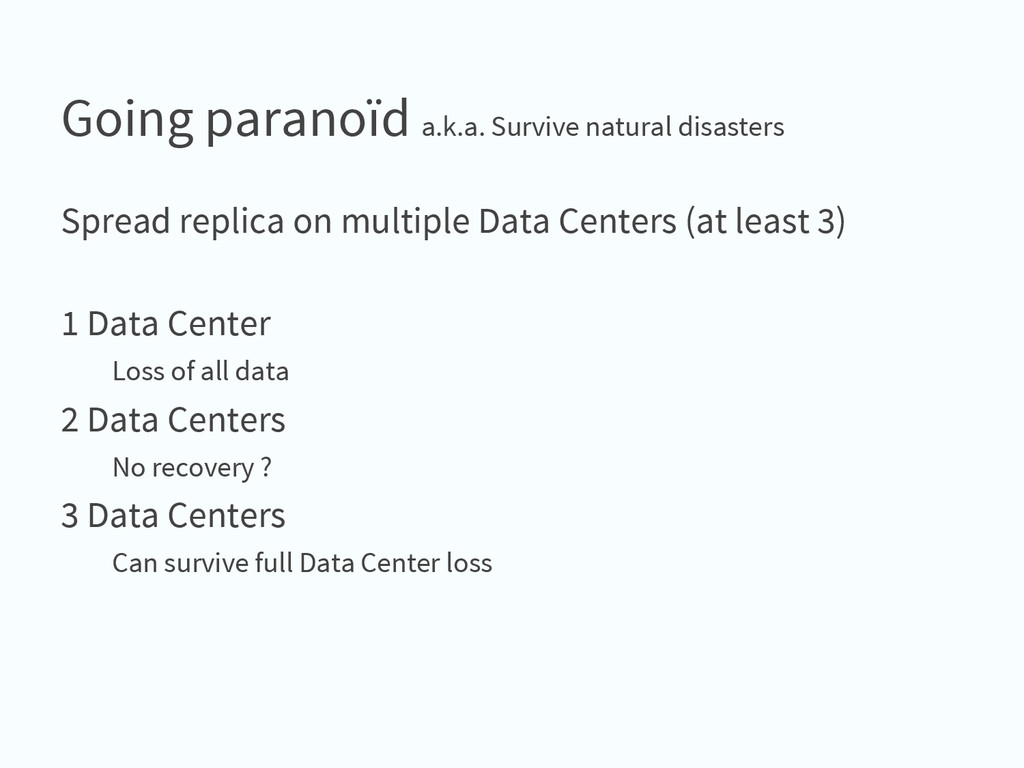
Going paranoïd a.k.a. Survive natural disasters Spread replica on multiple
Data Centers (at least 3) 1 Data Center Loss of all data 2 Data Centers No recovery ? 3 Data Centers Can survive full Data Center loss -
Configuration Read Preference Primary / PrimaryPreferred / SecondaryPreferred / Secondary
If several possibilities, take the nearest Read from secondary might be delay in data -
Configuration Write Concern Network acknowledgment (unacknowledged) Wait for error Wait
for Journal Sync (good consistency) Wait for Replication -
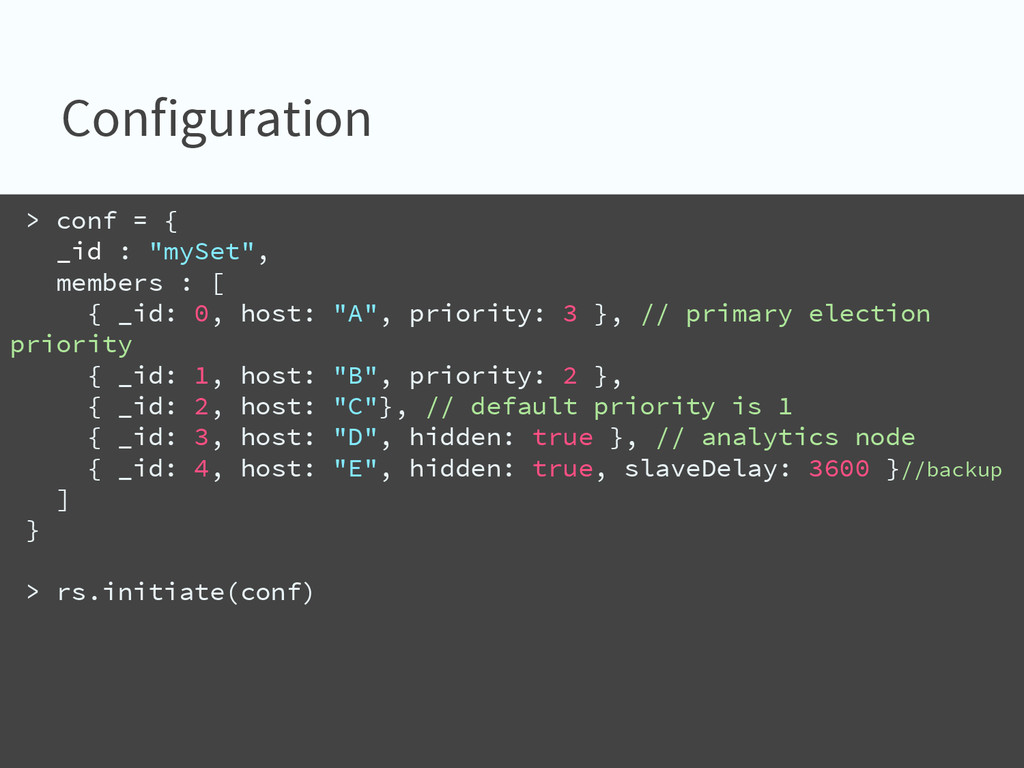
> conf = { _id : "mySet", members : [
{ _id: 0, host: "A", priority: 3 }, // primary election priority { _id: 1, host: "B", priority: 2 }, { _id: 2, host: "C"}, // default priority is 1 { _id: 3, host: "D", hidden: true }, // analytics node { _id: 4, host: "E", hidden: true, slaveDelay: 3600 }//backup ] } > rs.initiate(conf) Configuration -
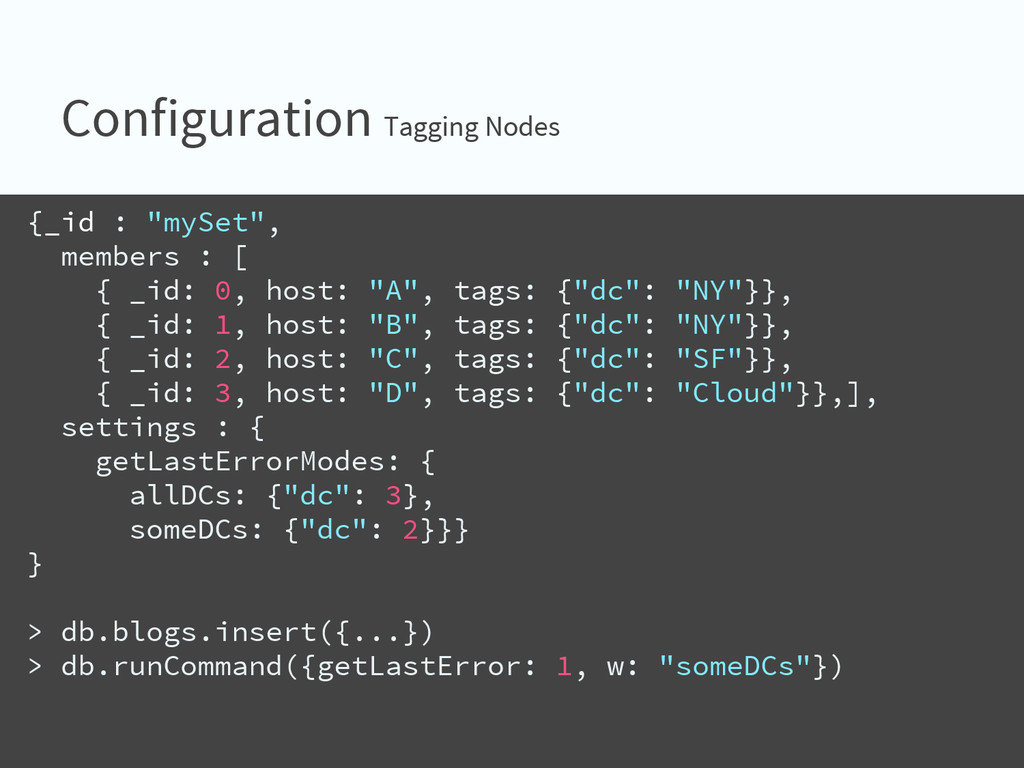
{_id : "mySet", members : [ { _id: 0, host:
"A", tags: {"dc": "NY"}}, { _id: 1, host: "B", tags: {"dc": "NY"}}, { _id: 2, host: "C", tags: {"dc": "SF"}}, { _id: 3, host: "D", tags: {"dc": "Cloud"}},], settings : { getLastErrorModes: { allDCs: {"dc": 3}, someDCs: {"dc": 2}}} } > db.blogs.insert({...}) > db.runCommand({getLastError: 1, w: "someDCs"}) Configuration Tagging Nodes -
Redundancy: ◦ In 'local' database ◦ Capped Can be read
and used. (Used for secondary update) 1Go ~ 5h history Oplog, keep records of the db ops ! -
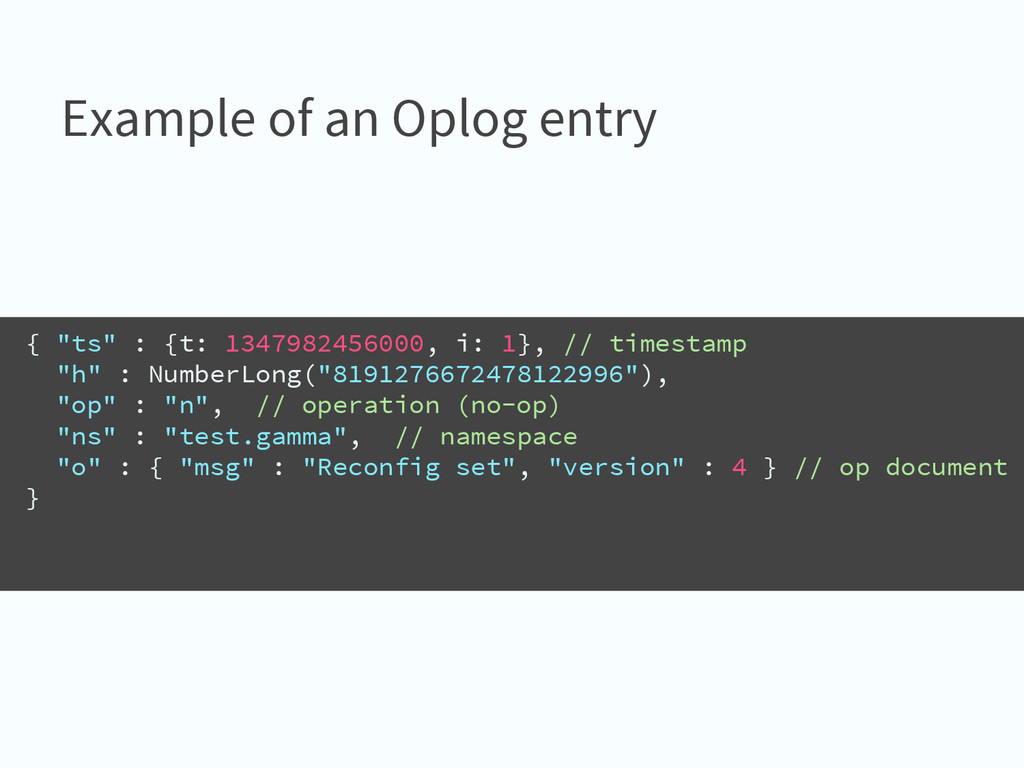
Example of an Oplog entry { "ts" : {t: 1347982456000,
i: 1}, // timestamp "h" : NumberLong("8191276672478122996"), "op" : "n", // operation (no-op) "ns" : "test.gamma", // namespace "o" : { "msg" : "Reconfig set", "version" : 4 } // op document } -
Do I need a shard? Horizontally scalable & Application independent
Read/Write throughput > I/O i.e Working set > RAM -
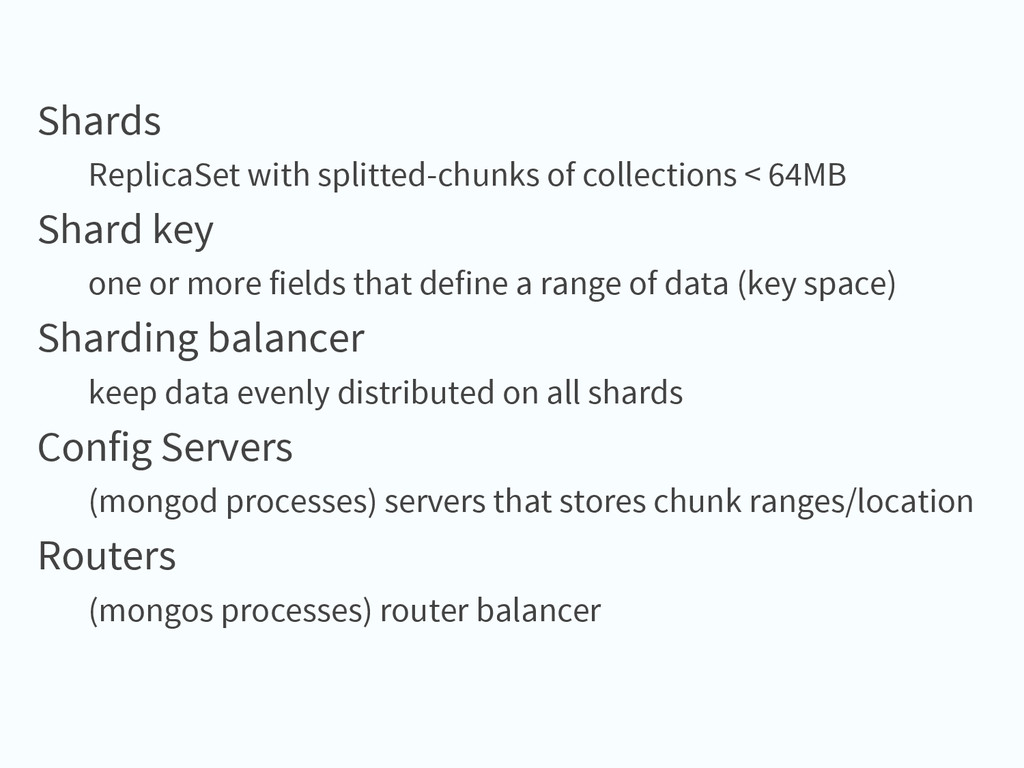
Shards ReplicaSet with splitted-chunks of collections < 64MB Shard key
one or more fields that define a range of data (key space) Sharding balancer keep data evenly distributed on all shards Config Servers (mongod processes) servers that stores chunk ranges/location Routers (mongos processes) router balancer -
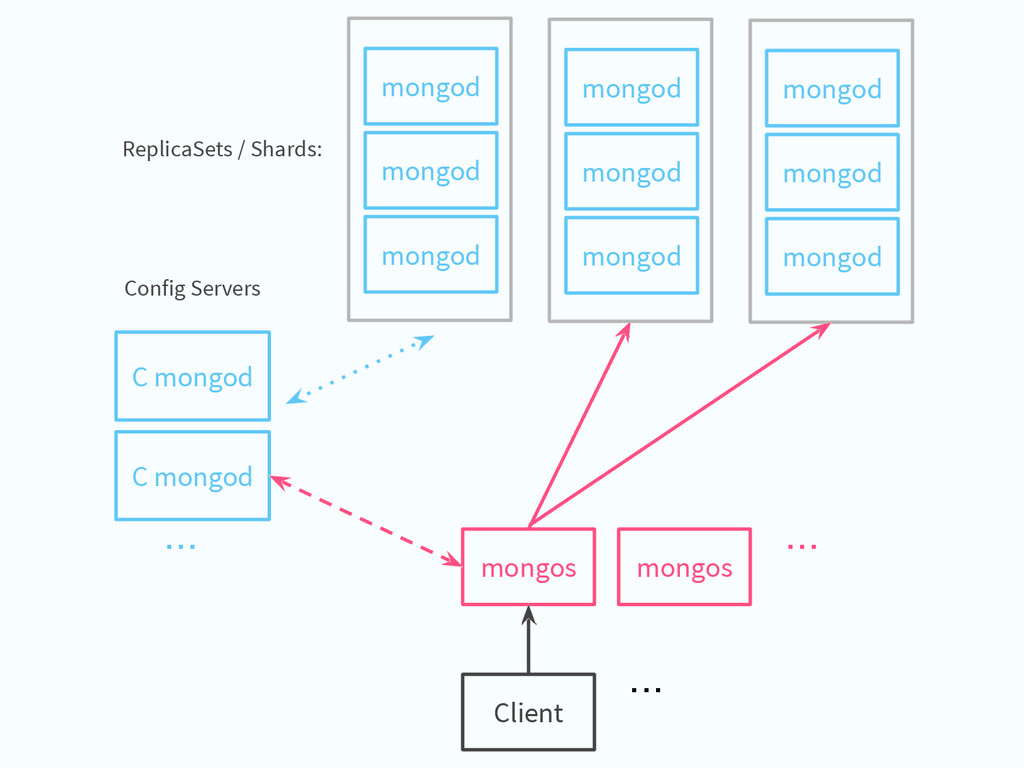
C mongod mongos Client Config Servers ReplicaSets / Shards: mongos
C mongod mongod mongod mongod mongod mongod mongod mongod mongod mongod ... ... ... -
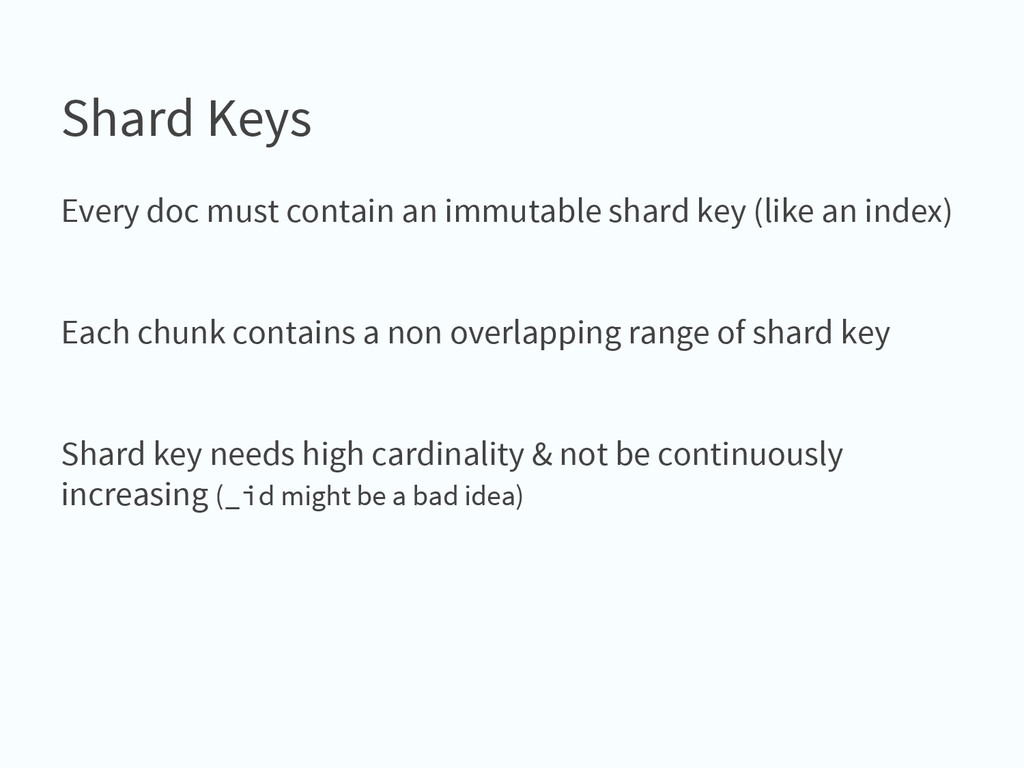
Shard Keys Every doc must contain an immutable shard key
(like an index) Each chunk contains a non overlapping range of shard key Shard key needs high cardinality & not be continuously increasing (_id might be a bad idea) -
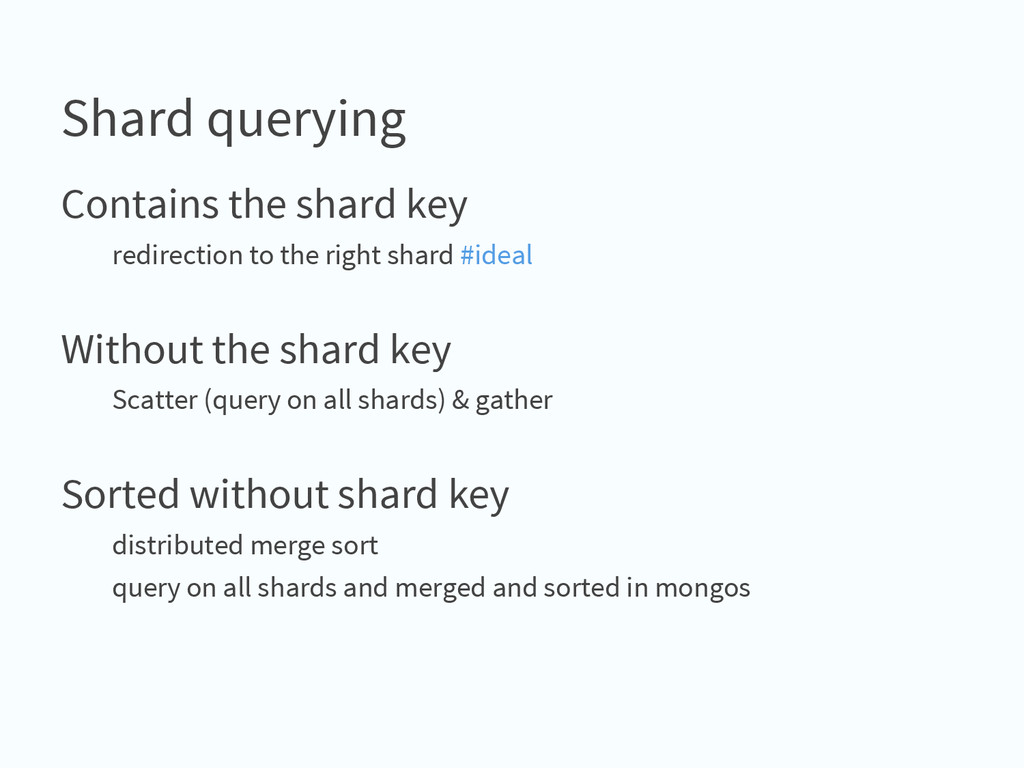
Shard querying Contains the shard key redirection to the right
shard #ideal Without the shard key Scatter (query on all shards) & gather Sorted without shard key distributed merge sort query on all shards and merged and sorted in mongos -
Indexing & Optimization or How things can go very bad
! BY Thomas Rückstieß -
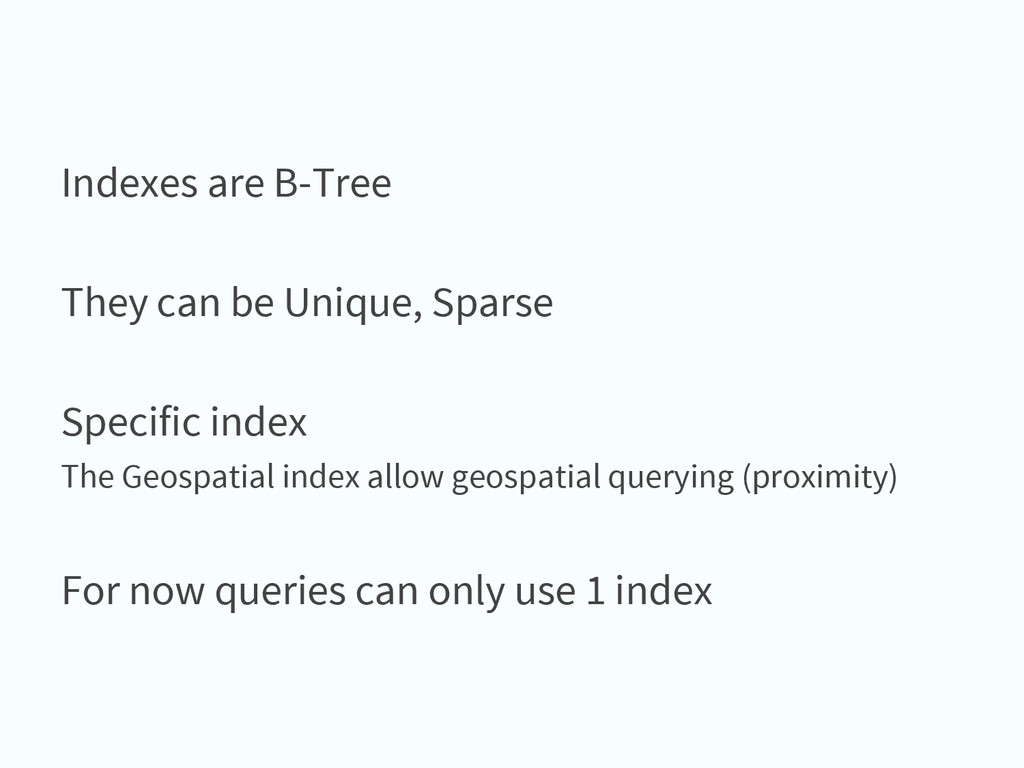
Indexes are B-Tree They can be Unique, Sparse Specific index
The Geospatial index allow geospatial querying (proximity) For now queries can only use 1 index -
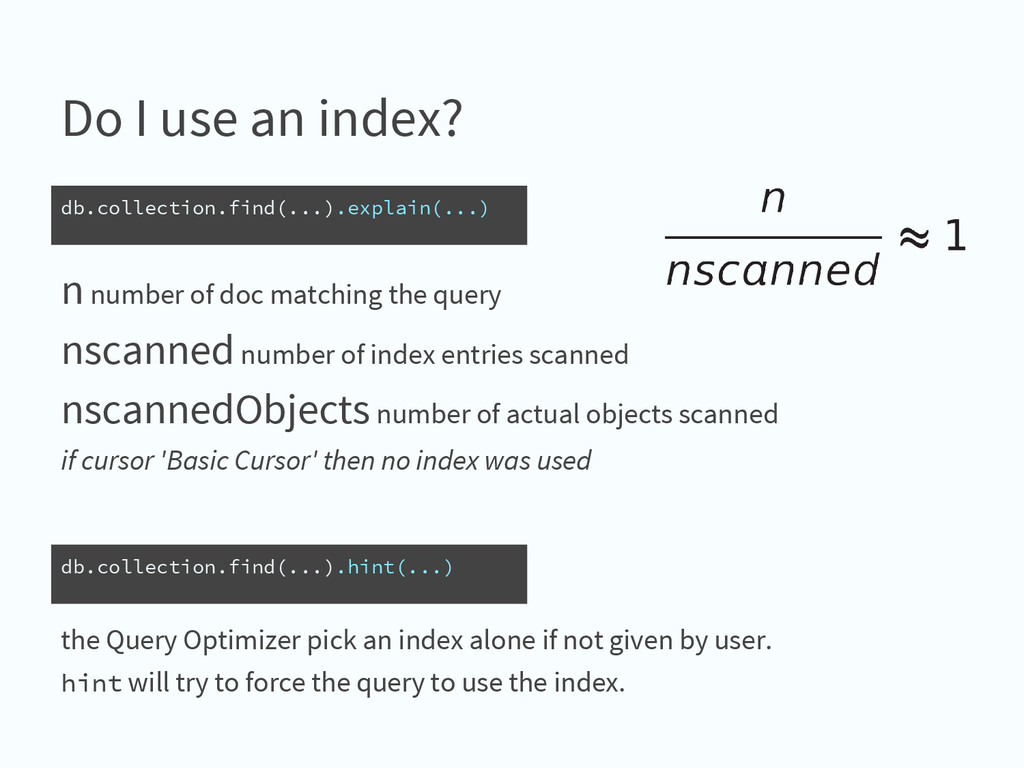
the Query Optimizer pick an index alone if not given
by user. hint will try to force the query to use the index. Do I use an index? db.collection.find(...).hint(...) n number of doc matching the query nscanned number of index entries scanned nscannedObjects number of actual objects scanned if cursor 'Basic Cursor' then no index was used db.collection.find(...).explain(...) -
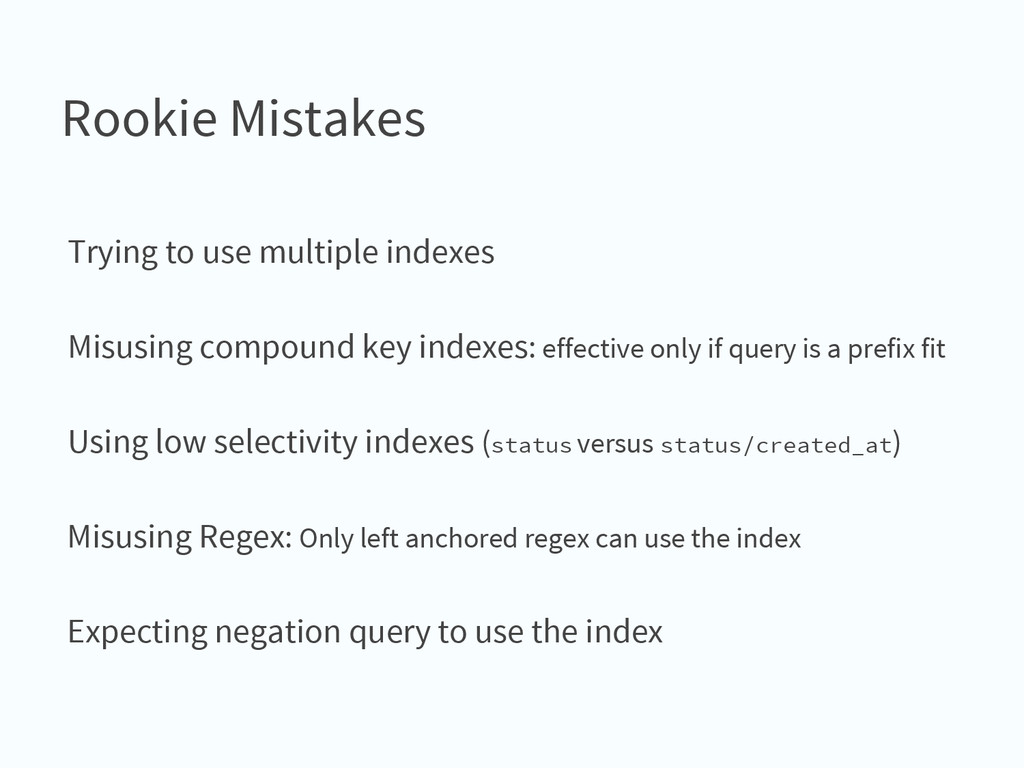
Rookie Mistakes Trying to use multiple indexes Misusing compound key
indexes: effective only if query is a prefix fit Using low selectivity indexes (status versus status/created_at) Misusing Regex: Only left anchored regex can use the index Expecting negation query to use the index -
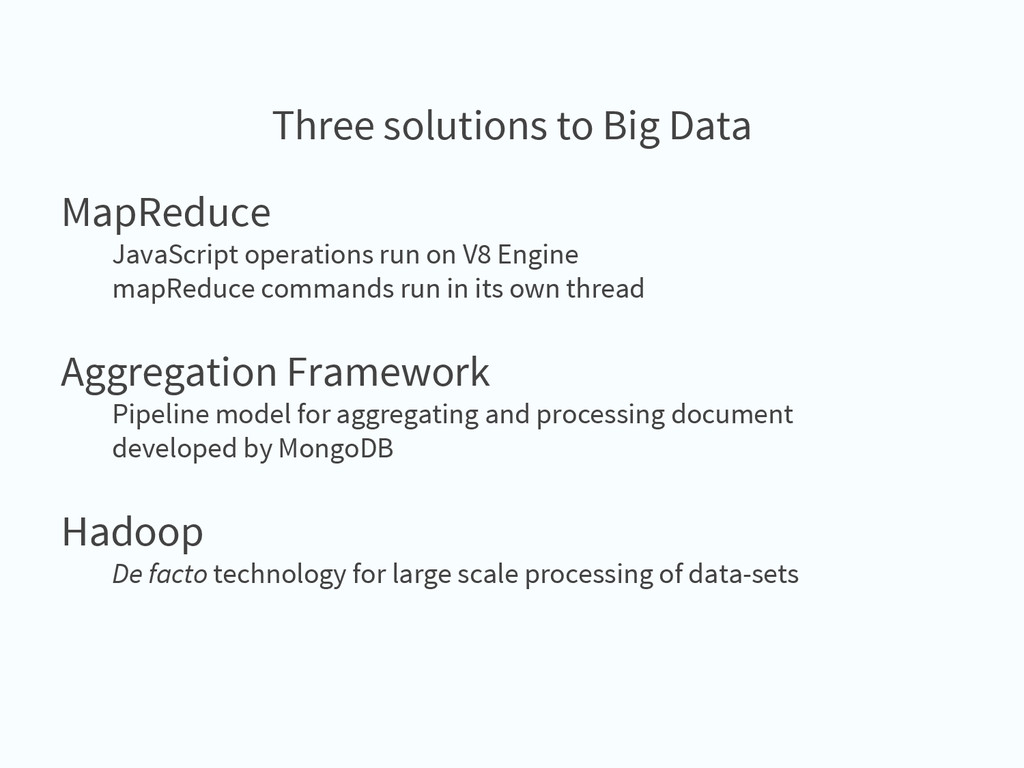
Three solutions to Big Data MapReduce JavaScript operations run on
V8 Engine mapReduce commands run in its own thread Aggregation Framework Pipeline model for aggregating and processing document developed by MongoDB Hadoop De facto technology for large scale processing of data-sets -
MapReduce Aggregation FW Hadoop Real-Time Output to collection Local data
Real-time Very simple & Powerful (pipeline) Declared in JSON (no JS/C++ translation) Local data Leverage existing data processing infrastructure Horizontally scale data processing Load to DB Challenging debug Expensive operation translation JS/C++ Add load to DB Limited set of operation Data output limited to 16MB Away from data store Offline Batch Sync between store & processor Complex setup -
Near term... New update operators Background indexing on secondary servers
TextSearch Capped arrays Aggregation Framework ◦ Write to collection as output ◦ Set operators -
... and beyond Bulk writes Use more than one index
per query Collection level authentication Schema validation (so on and so forth)