How do you monitor a distributed system with emergent properties? Thoughtful Chaos Engineering experiments help us build confidence that our monitoring and dashboards will give us the data we need when it matters most.
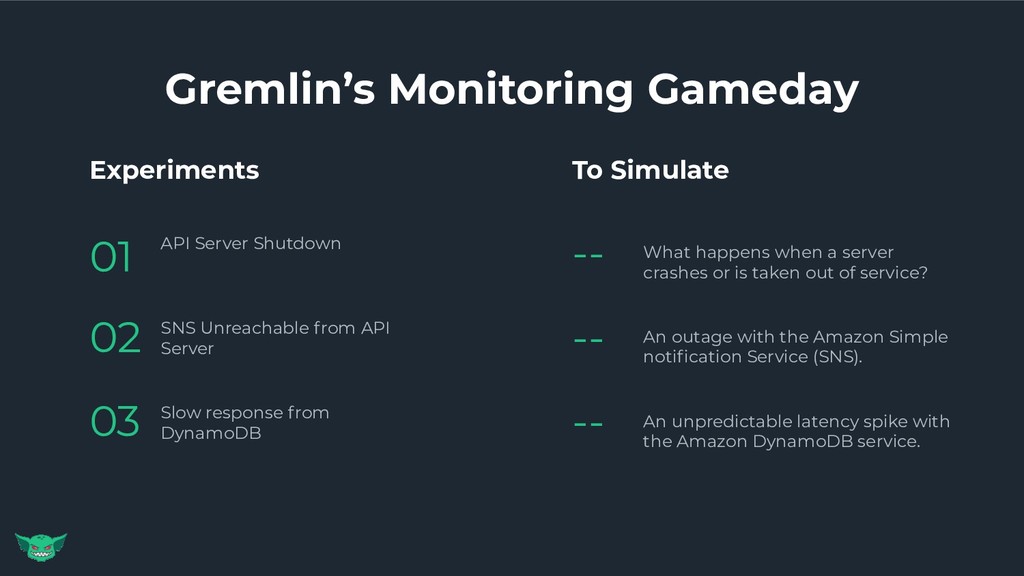
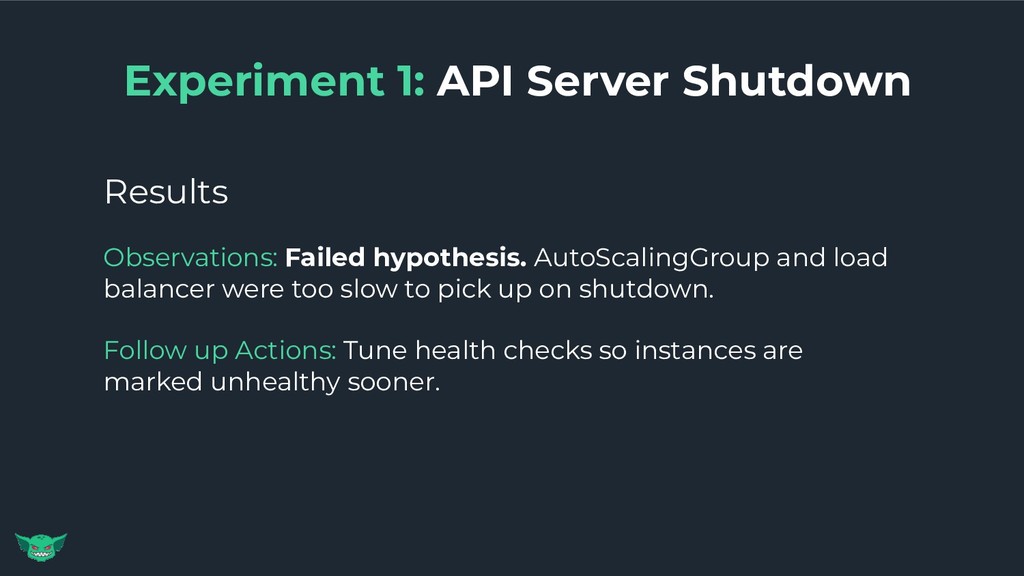
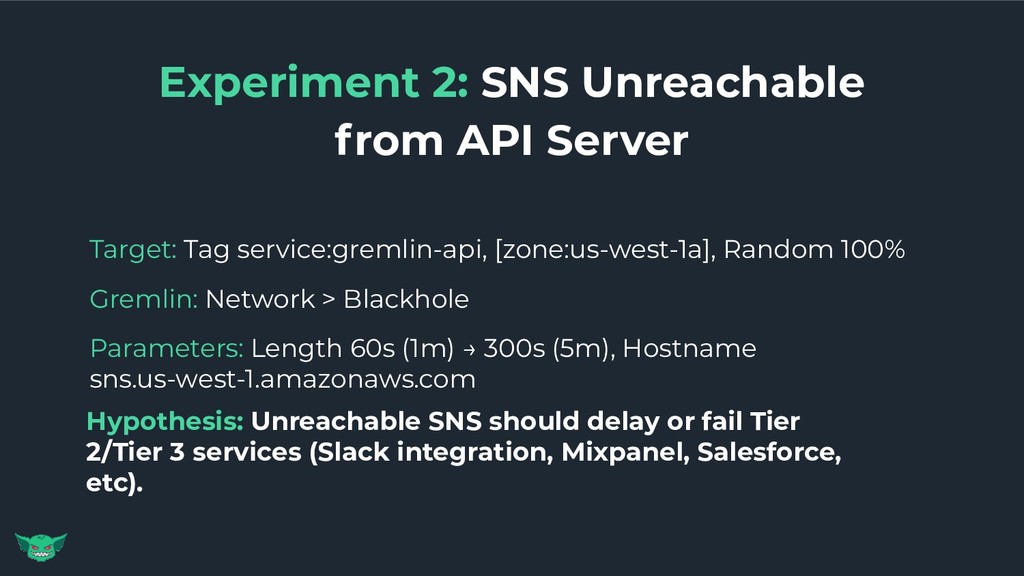
from API Server Slow response from DynamoDB Experiments To Simulate -- -- -- What happens when a server crashes or is taken out of service? An outage with the Amazon Simple notification Service (SNS). An unpredictable latency spike with the Amazon DynamoDB service. 01
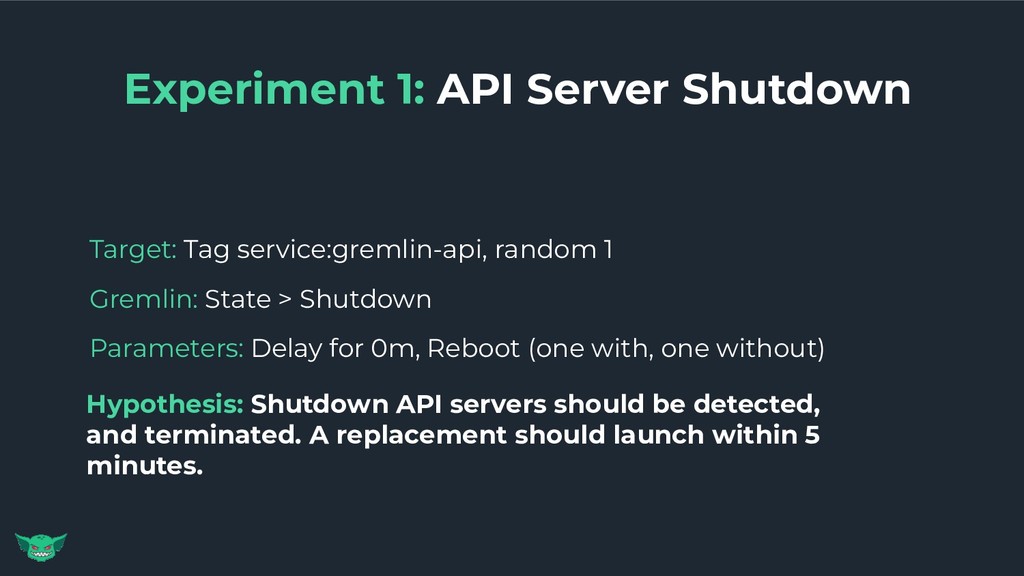
Gremlin: State > Shutdown Parameters: Delay for 0m, Reboot (one with, one without) Hypothesis: Shutdown API servers should be detected, and terminated. A replacement should launch within 5 minutes.
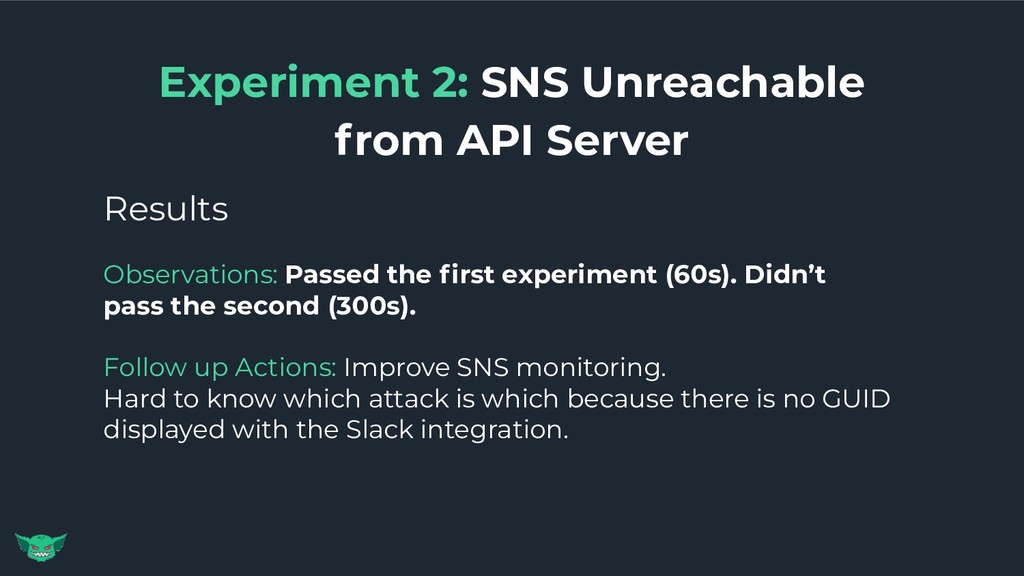
the first experiment (60s). Didn’t pass the second (300s). Follow up Actions: Improve SNS monitoring. Hard to know which attack is which because there is no GUID displayed with the Slack integration.
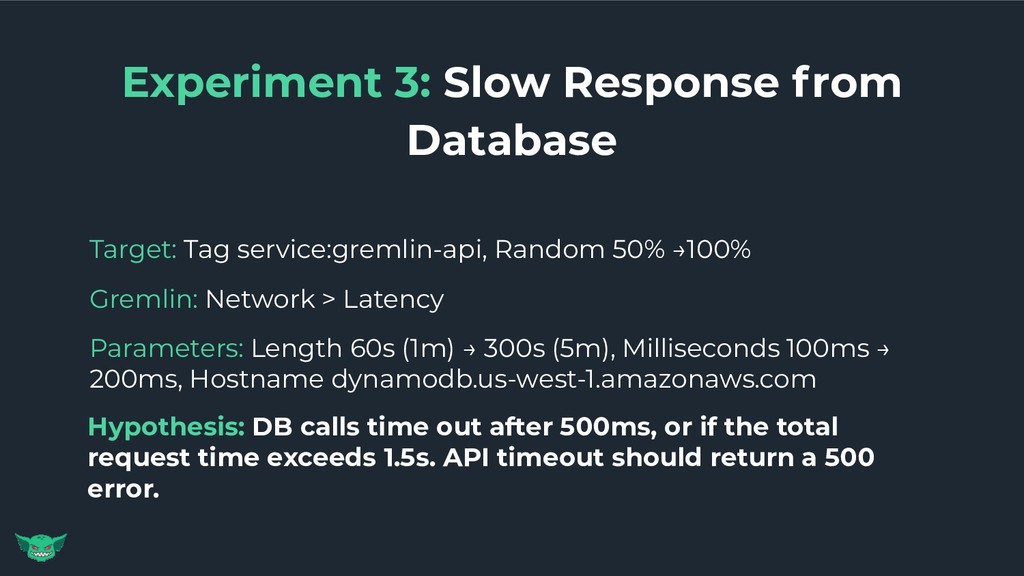
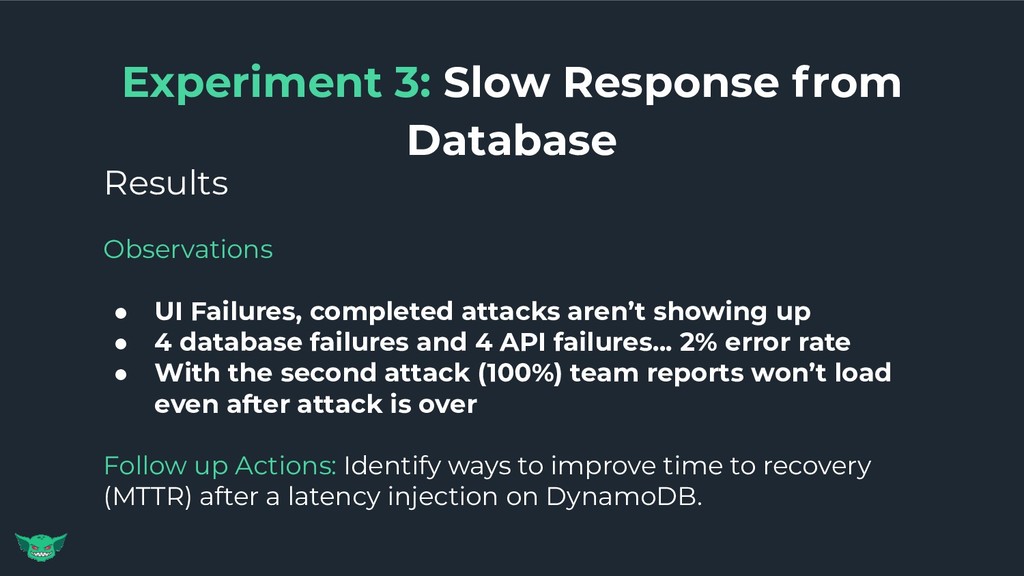
50% →100% Gremlin: Network > Latency Parameters: Length 60s (1m) → 300s (5m), Milliseconds 100ms → 200ms, Hostname dynamodb.us-west-1.amazonaws.com Hypothesis: DB calls time out after 500ms, or if the total request time exceeds 1.5s. API timeout should return a 500 error.
Failures, completed attacks aren’t showing up • 4 database failures and 4 API failures... 2% error rate • With the second attack (100%) team reports won’t load even after attack is over Follow up Actions: Identify ways to improve time to recovery (MTTR) after a latency injection on DynamoDB.


 kaminashi
 willnet
 gionn
 kentarofujii
 bitkey
 greenmidori
 kentapapa
 gogutan
 kairim0
 odashi
 persolserverworks
 camiha
 skipperchong
 aleyda
 lauravandoore
 sarafernandez
 dougneiner
 katarinadahlin
 tammyeverts
 ryanjones
 marcelosomers
 3n
 nikkihalliwell