The three generations of Big Data processing by...
Sponsored
·
 Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→

Share
Embed
The three generations of Big Data processing by RUBÉN CASADO at Big Data Spain 2013
Big Data is often characterized by the 3 “Vs”: variety, volume and velocity. While variety refers to the nature of the information (multiple sources, schema-less data, etc), both volume and velocity refer to processing issues that have to be addressed by different processing paradigms.
Session presented at Big Data Spain 2013 Conference
7th Nov 2013
Kinépolis Madrid
http://www.bigdataspain.org
Event promoted by http://www.paradigmatecnologico.com
Abstract: http://www.bigdataspain.org/2013/conference/the-three-generations-of-big-data-processing

Big Data Spain
November 14, 2013
Transcript
89 slides
-
1. Big Data processing 2. Batch processing 3. Real-time processing
4. Hybrid computation model 5. Conclusions Agenda -
PhD in Software Engineering MSc in Computer Science
BSc in Computer Science Academics Work Experience -
Treelogic is an R&D intensive company with the mission of
creating, boosting, developing and adapting scientific and technological knowledge to improve quality standards in our daily life -
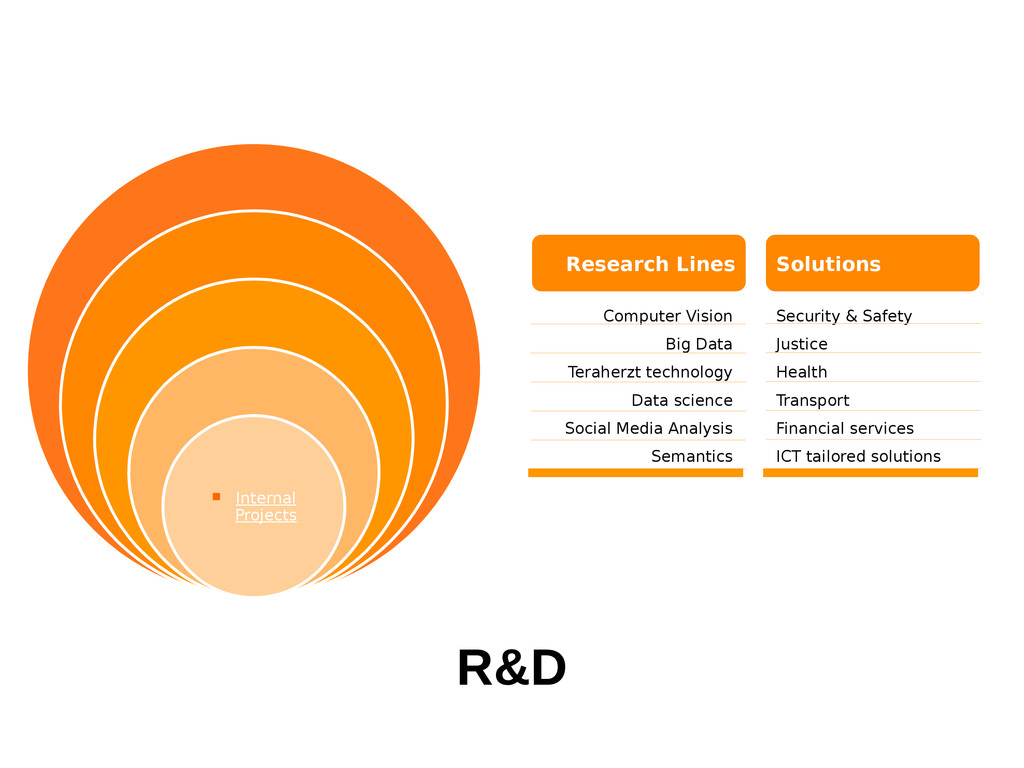
International Projects National Projects Regional Projects
R&D Manag. System Internal Projects Research Lines Computer Vision Big Data Teraherzt technology Data science Social Media Analysis Semantics Security & Safety Justice Health Transport Financial services ICT tailored solutions Solutions R&D -
7 ongoing FP7 projects ICT, SEC, OCEAN Coordinating 5 of
them 3 ongoing Eurostars projects Coordinating all of them -
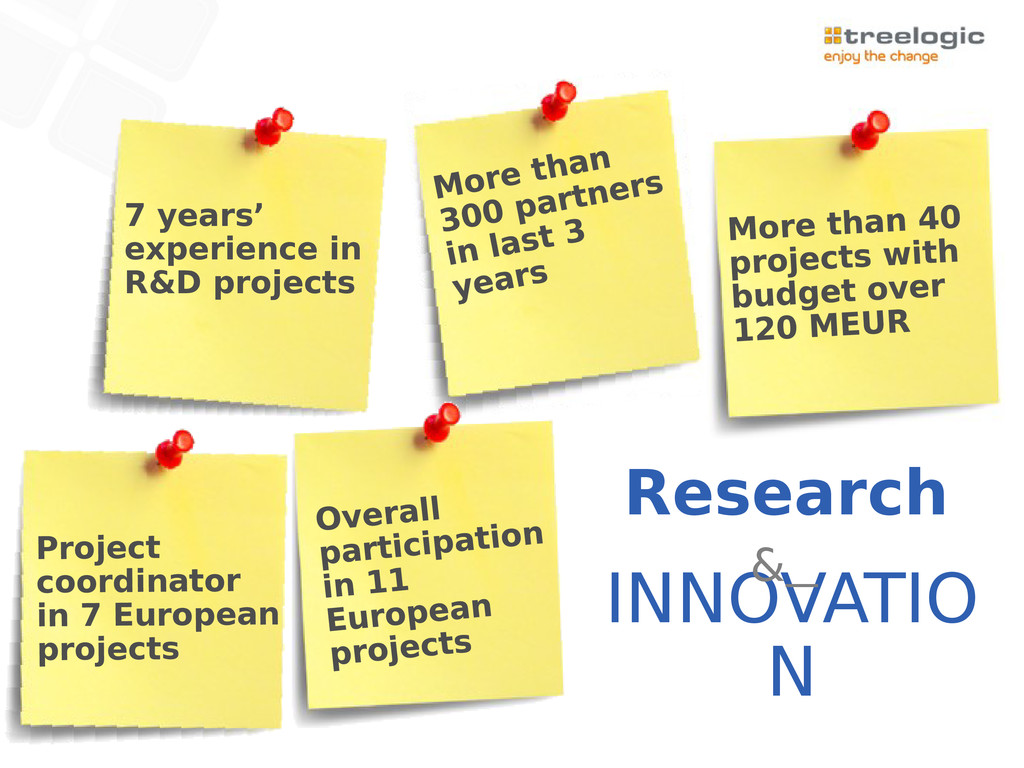
Research INNOVATIO N & 7 years’ experience in R&D projects
Project coordinator in 7 European projects -
1. Big Data processing 2. Batch processing 3. Real-time processing
4. Hybrid computation model 5. Conclusions Agenda -
A massive volume of both structured and unstructured data that
is so large to process with traditional database and software techniques What is Big Data? -
Big Data are high-volume, high-velocity, and/or high-variety information assets that
require new forms of processing to enable enhanced decision making, insight discovery and process optimization How is Big Data? - Gartner IT Glossary - -
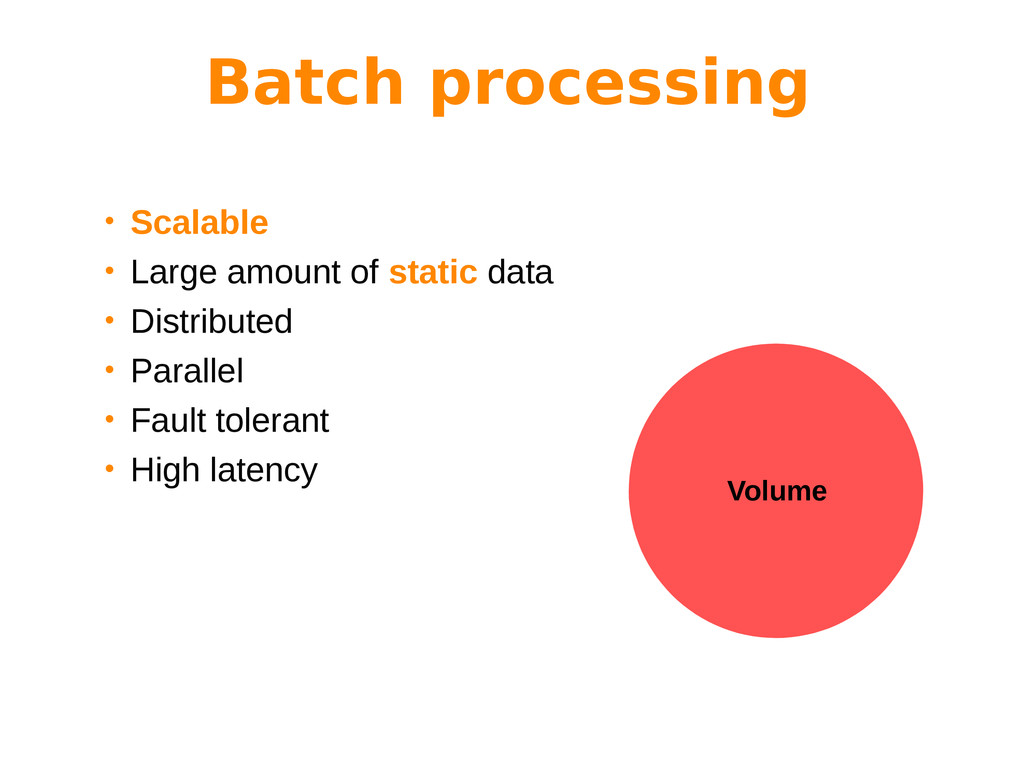
• Scalable • Large amount of static data • Distributed
• Parallel • Fault tolerant • High latency Batch processing Volume -
• Low latency • Continuous unbounded streams of data •
Distributed • Parallel • Fault-tolerant Real-time processing Velocity -
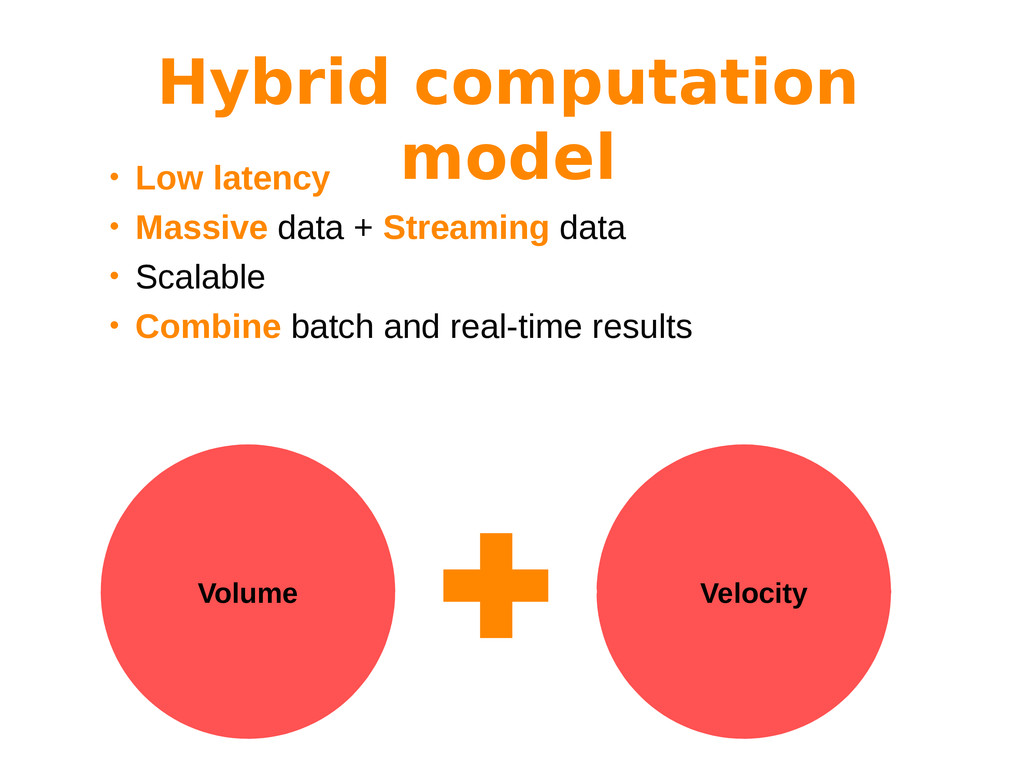
• Low latency • Massive data + Streaming data •
Scalable • Combine batch and real-time results Hybrid computation model Volume Velocity -
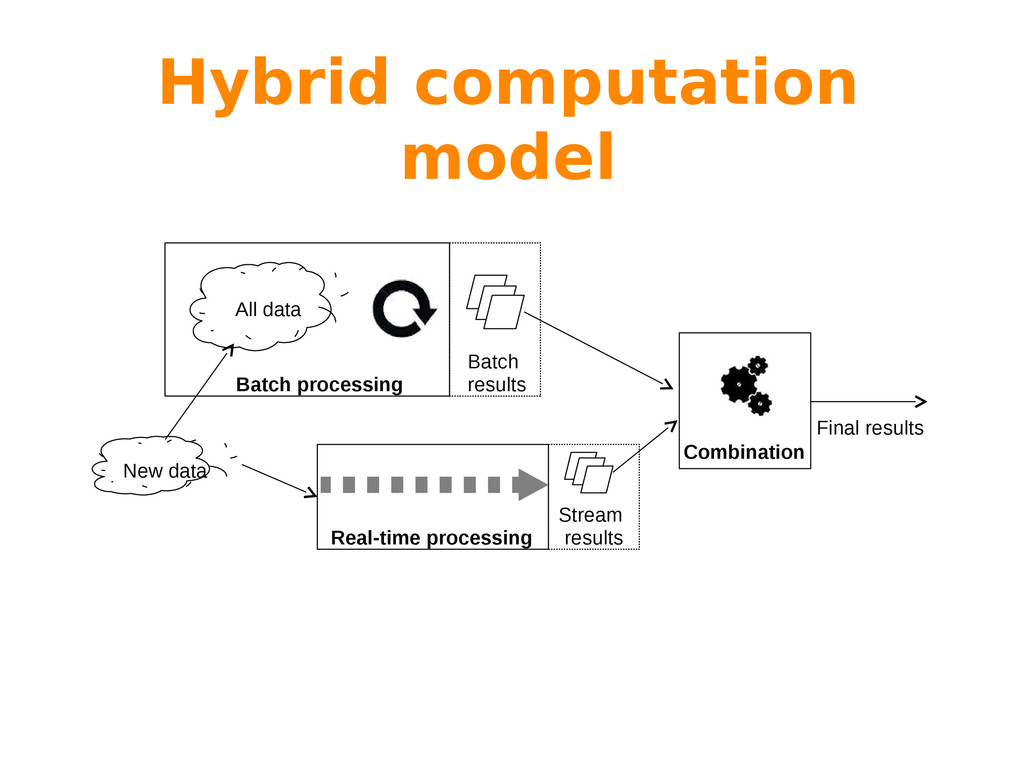
All data New data Batch processing Real-time processing Batch results
Stream results Combination Final results Hybrid computation model -
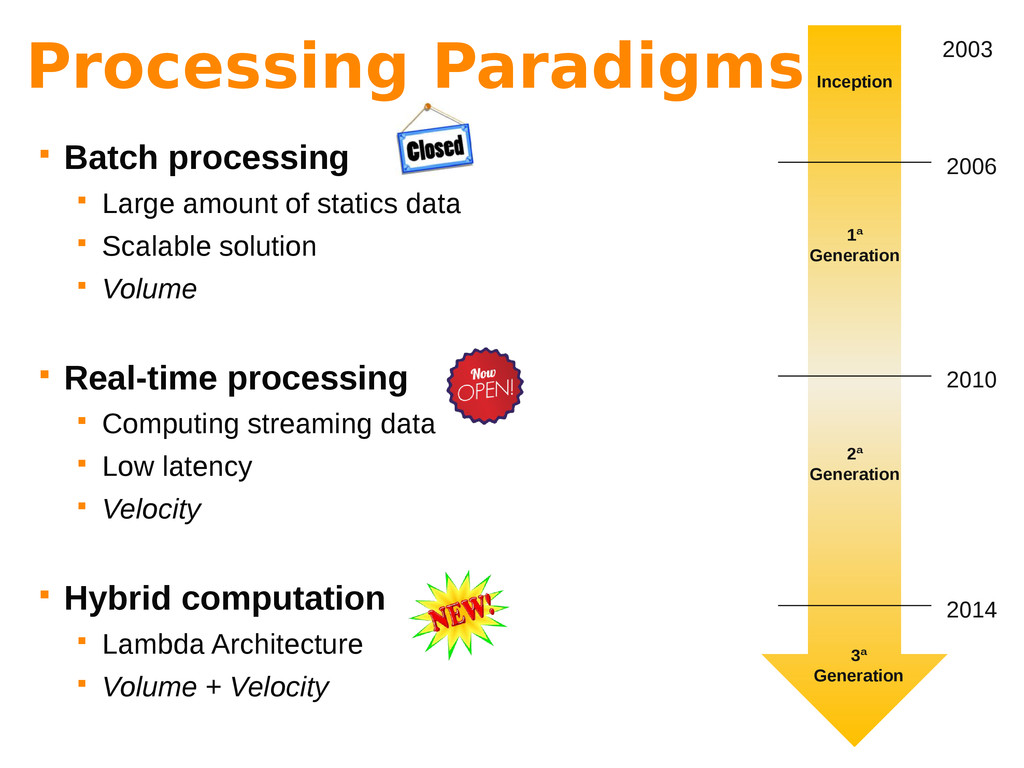
Batch processing Large amount of statics data
Scalable solution Volume Real-time processing Computing streaming data Low latency Velocity Hybrid computation Lambda Architecture Volume + Velocity 2006 2010 2014 1ª Generation 2ª Generation 3ª Generation Inception 2003 Processing Paradigms -
Batch 10 years of Big Data processing technologies 2003 2004
2005 2013 2011 2010 2008 The Google File System MapReduce: Simplified Data Processing on Large Clusters Doug Cutting starts developing Hadoop 2006 Yahoo! starts working on Hadoop Apache Hadoop is in production Nathan Marz creates Storm Yahoo! creates S4 2009 Facebook creates Hive Yahoo! creates Pig Google publishes MillWheel: Fault-Tolerant Stream Processing at Internet Scale LinkedIn presents Samza LinkedIn! presents KafkA Cloudera presents Flume 2012 Nathan Marz defines the Lambda Architecture Real-Time Hybrid -
Static stations and mobile sensors in Asturias sending streaming
data Historical data of > 10 years Monitoring, trends identification, predictions Air Quality case study -
1. Big Data processing overview 2. Batch processing 3. Real-time
processing 4. Hybrid computation model 5. Conclusions Agenda -
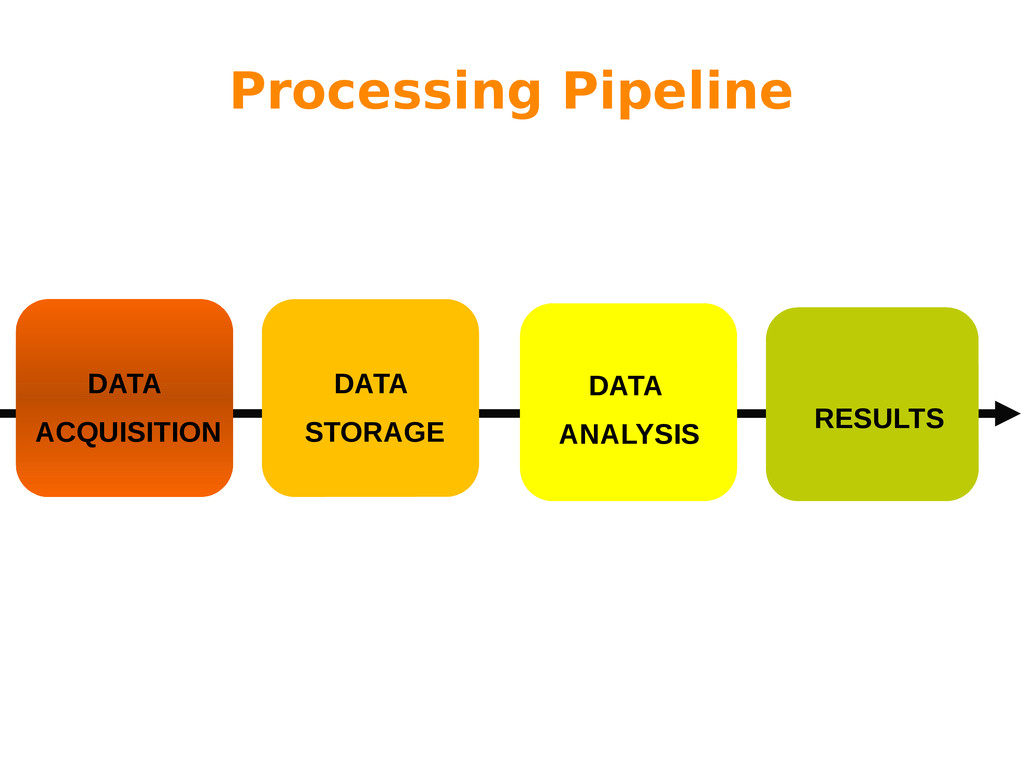
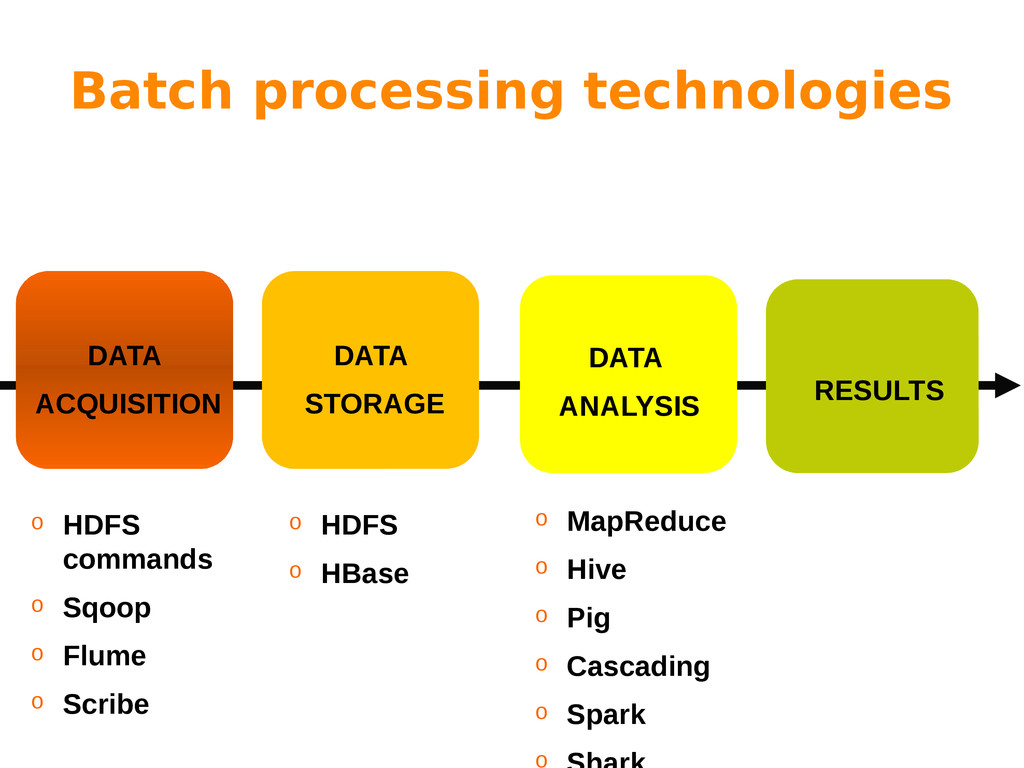
Batch processing technologies DATA ACQUISITION DATA STORAGE DATA ANALYSIS RESULTS
o HDFS commands o Sqoop o Flume o Scribe o HDFS o HBase o MapReduce o Hive o Pig o Cascading o Spark o -
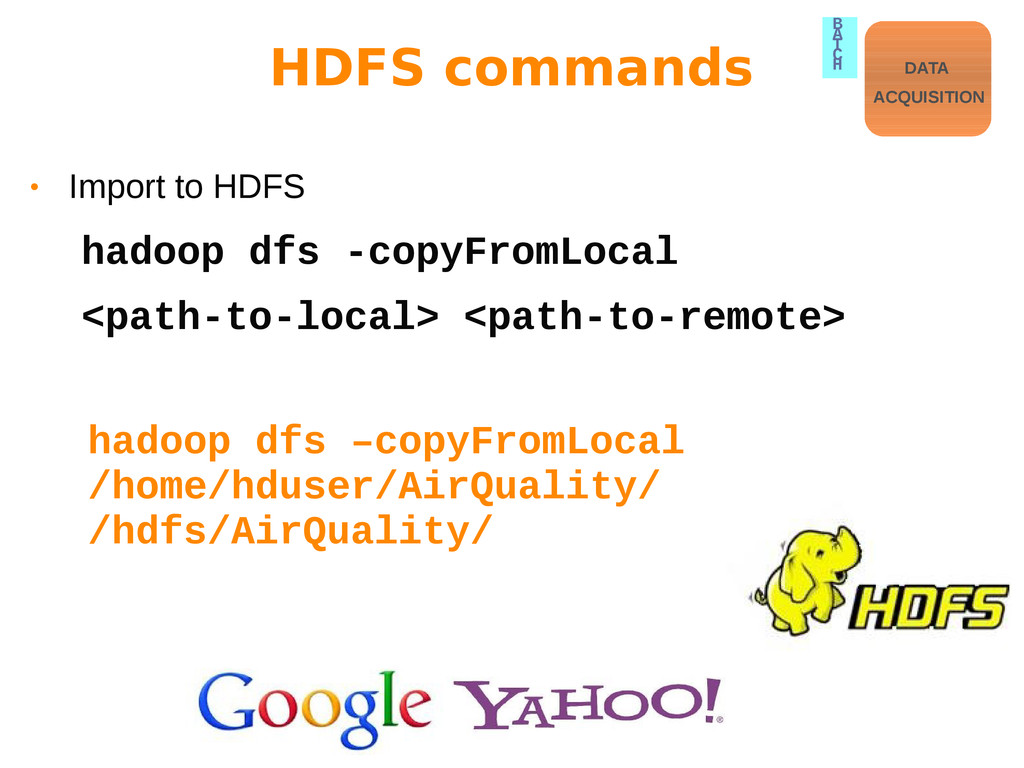
• Import to HDFS hadoop dfs -copyFromLocal <path-to-local> <path-to-remote> hadoop
dfs –copyFromLocal /home/hduser/AirQuality/ /hdfs/AirQuality/ HDFS commands DATA ACQUISITION B A T C H -
• Tool designed for transferring data between HDFS/HBase and structural
datastores • Based in MapReduce • Includes connectors for multiple databases o MySQL, o PostgreSQL, o Oracle, o SQL Server and o DB2 o Generic JDBC connector • Java API Sqoop DATA ACQUISITION B A T C H -
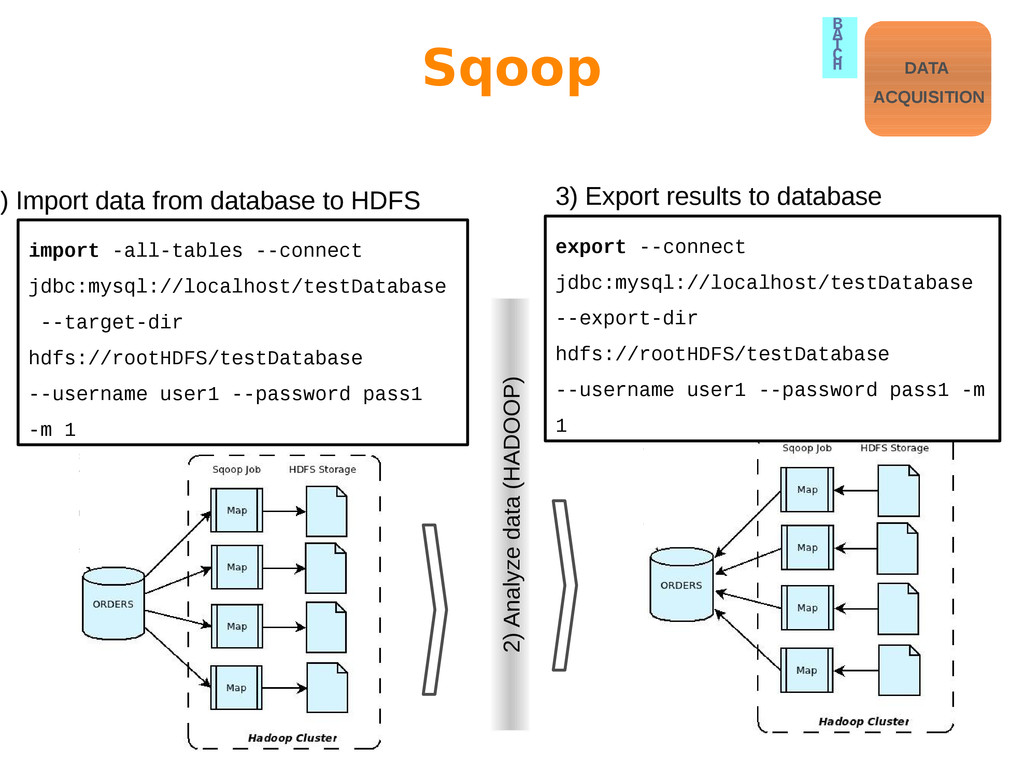
import -all-tables --connect jdbc:mysql://localhost/testDatabase --target-dir hdfs://rootHDFS/testDatabase --username user1 --password pass1
-m 1 1) Import data from database to HDFS export --connect jdbc:mysql://localhost/testDatabase --export-dir hdfs://rootHDFS/testDatabase --username user1 --password pass1 -m 1 3) Export results to database 2) Analyze data (HADOOP) Sqoop DATA ACQUISITION B A T C H -
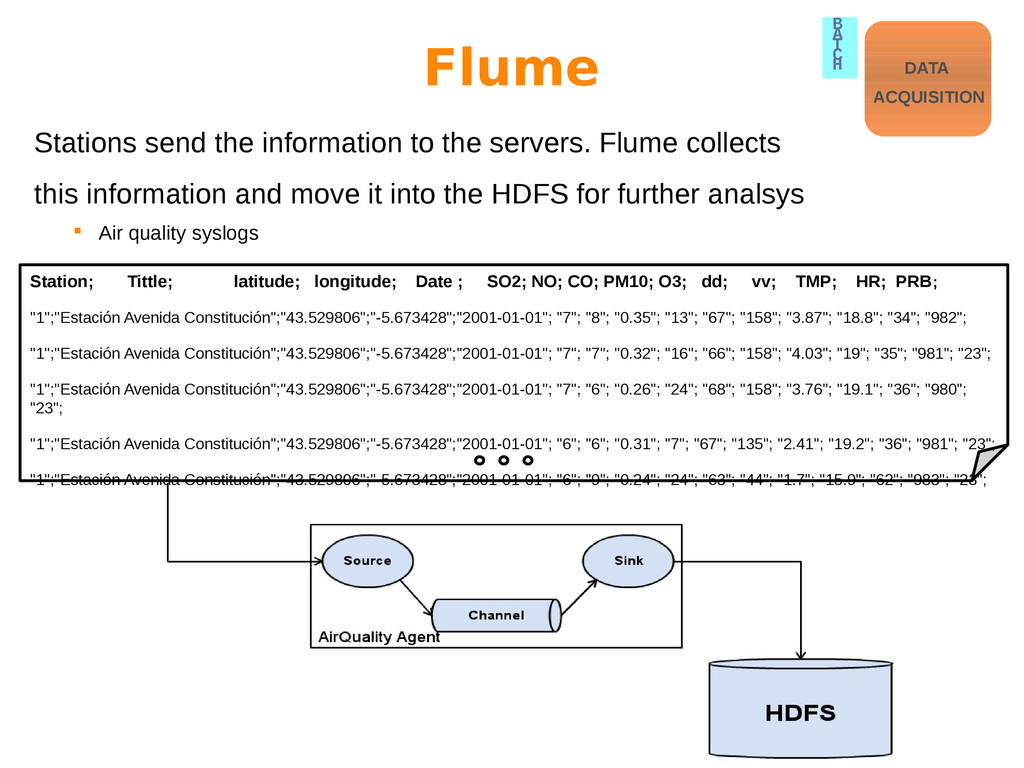
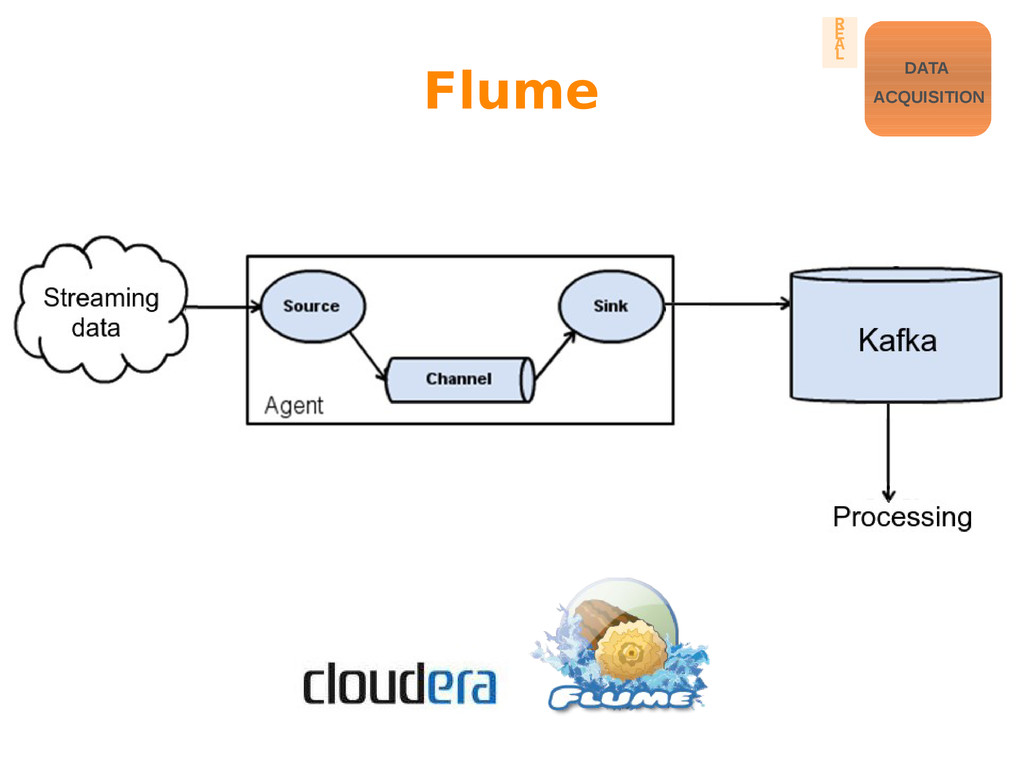
• Service for collecting, aggregating, and moving large amounts of
log data • Simple and flexible architecture based on streaming data flows • Reliability, scalability, extensibility, manageability • Support log stream types • Avro • Syslog • Netcast Flume DATA ACQUISITION B A T C H -
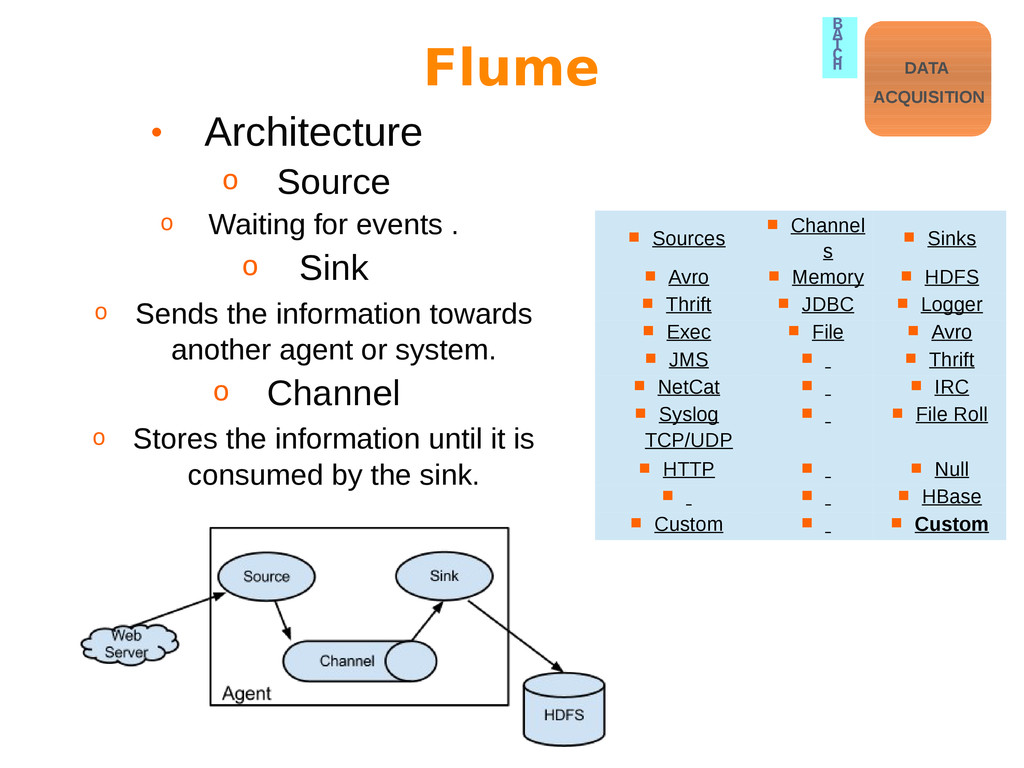
Sources Channel s Sinks Avro
Memory HDFS Thrift JDBC Logger Exec File Avro JMS Thrift NetCat IRC Syslog TCP/UDP File Roll HTTP Null HBase Custom Custom • Architecture o Source o Waiting for events . o Sink o Sends the information towards another agent or system. o Channel o Stores the information until it is consumed by the sink. Flume DATA ACQUISITION B A T C H -
Stations send the information to the servers. Flume collects this
information and move it into the HDFS for further analsys Air quality syslogs Flume DATA ACQUISITION B A T C H Station; Tittle; latitude; longitude; Date ; SO2; NO; CO; PM10; O3; dd; vv; TMP; HR; PRB; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "8"; "0.35"; "13"; "67"; "158"; "3.87"; "18.8"; "34"; "982"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "7"; "0.32"; "16"; "66"; "158"; "4.03"; "19"; "35"; "981"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "6"; "0.26"; "24"; "68"; "158"; "3.76"; "19.1"; "36"; "980"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "6"; "0.31"; "7"; "67"; "135"; "2.41"; "19.2"; "36"; "981"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "9"; "0.24"; "24"; "63"; "44"; "1.7"; "15.9"; "62"; "983"; "23"; -
• Server for aggregating log data streamed in real time
from a large number of servers • There is a scribe server running on every node in the system, configured to aggregate messages and send them to a central scribe server (or servers) in larger groups. • The central scribe server(s) can write the messages to the files that are their final destination Scribe DATA ACQUISITION B A T C H -
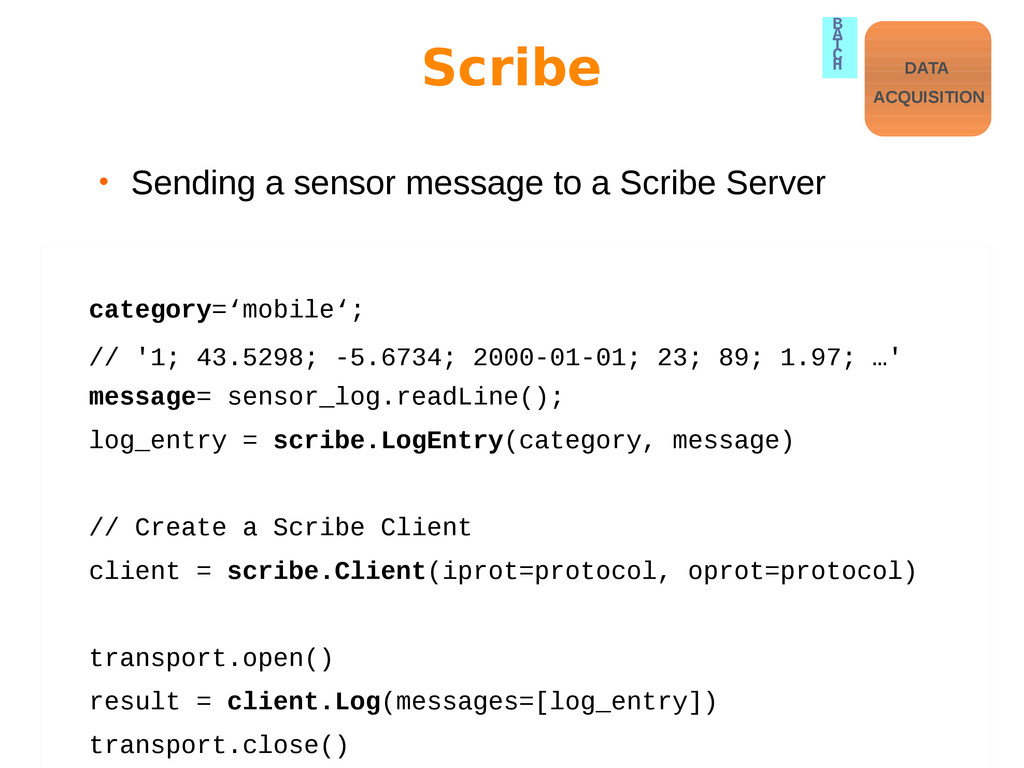
category=‘mobile‘; // '1; 43.5298; -5.6734; 2000-01-01; 23; 89; 1.97; …'
message= sensor_log.readLine(); log_entry = scribe.LogEntry(category, message) // Create a Scribe Client client = scribe.Client(iprot=protocol, oprot=protocol) transport.open() result = client.Log(messages=[log_entry]) transport.close() • Sending a sensor message to a Scribe Server Scribe DATA ACQUISITION B A T C H -
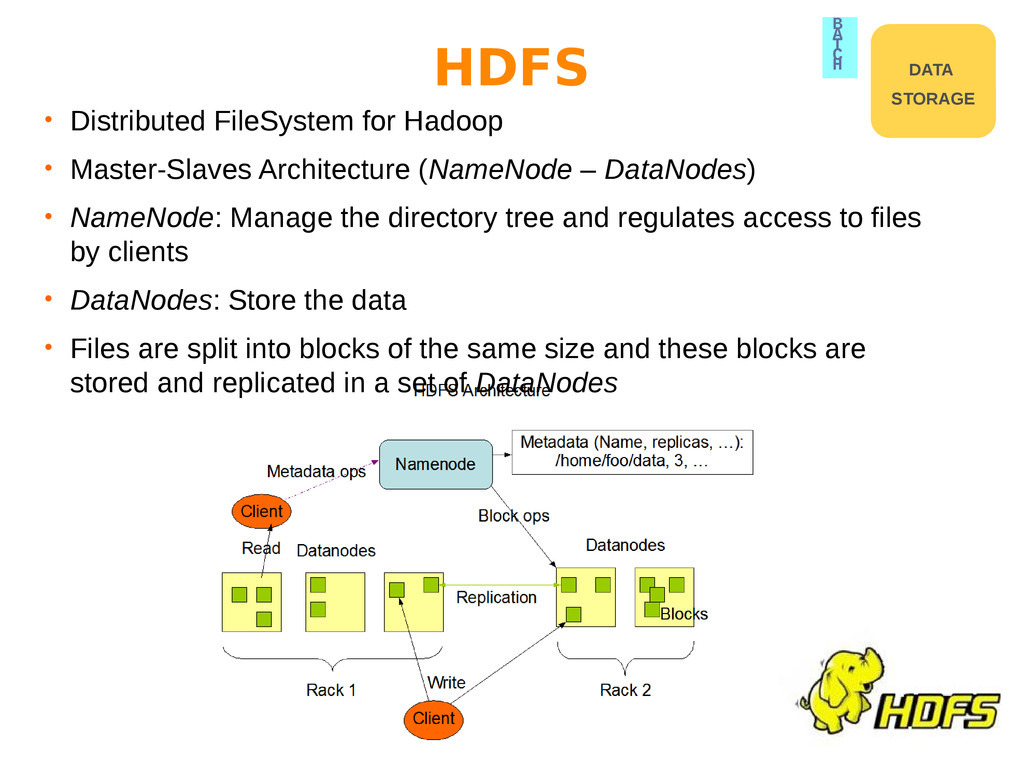
• Distributed FileSystem for Hadoop • Master-Slaves Architecture (NameNode –
DataNodes) • NameNode: Manage the directory tree and regulates access to files by clients • DataNodes: Store the data • Files are split into blocks of the same size and these blocks are stored and replicated in a set of DataNodes HDFS DATA STORAGE B A T C H -
• Open-source non-relational distributed column-oriented database modeled after Google’s BigTable.
• Random, realtime read/write access to the data. • Not a relational database. • Very light «schema» • Rows are stored in sorted order. DATA STORAGE B A T C H HBase -
• Framework for processing large amount of data in parallel
across a distributed cluster • Slightly inspired in the Divide and Conquer (D&C) classic strategy • Developer has to implement Map and Reduce functions: • Map: It takes the input, partitions it up into smaller sub-problems, and distributes them to worker nodes parsed to the format <K, V> • Reduce: It collects the <K, List(V)> and generates the results MapReduce DATA ANALYTICS B A T C H -
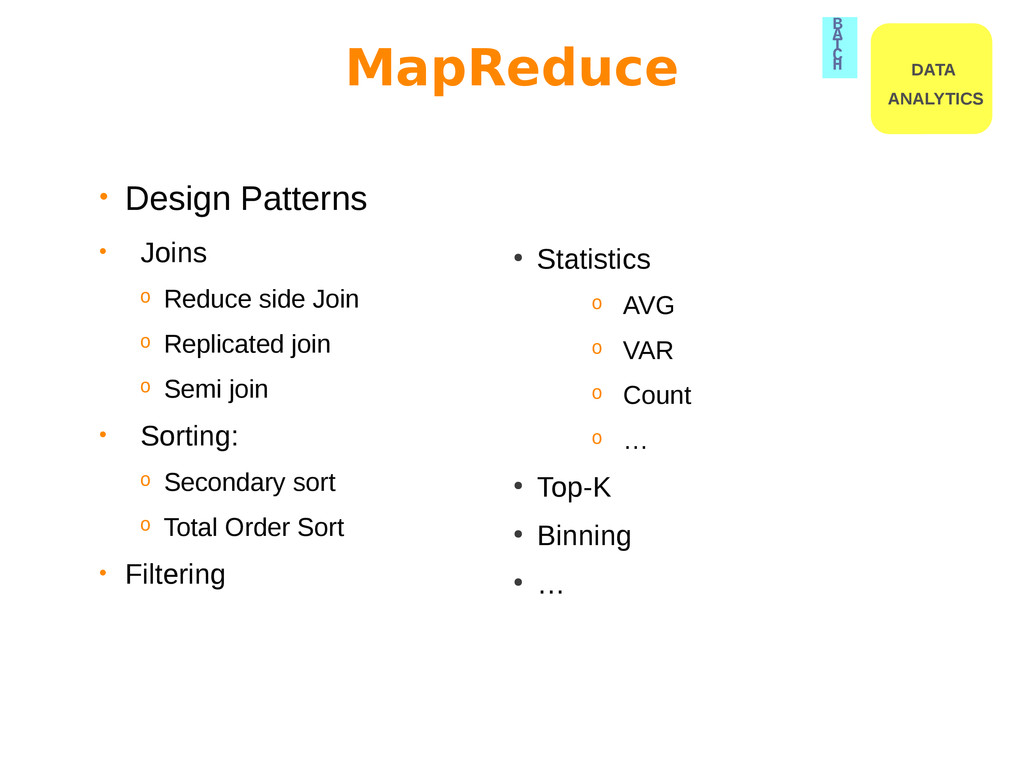
• Design Patterns • Joins o Reduce side Join o
Replicated join o Semi join • Sorting: o Secondary sort o Total Order Sort • Filtering MapReduce • Statistics o AVG o VAR o Count o … • Top-K • Binning • … DATA ANALYTICS B A T C H -
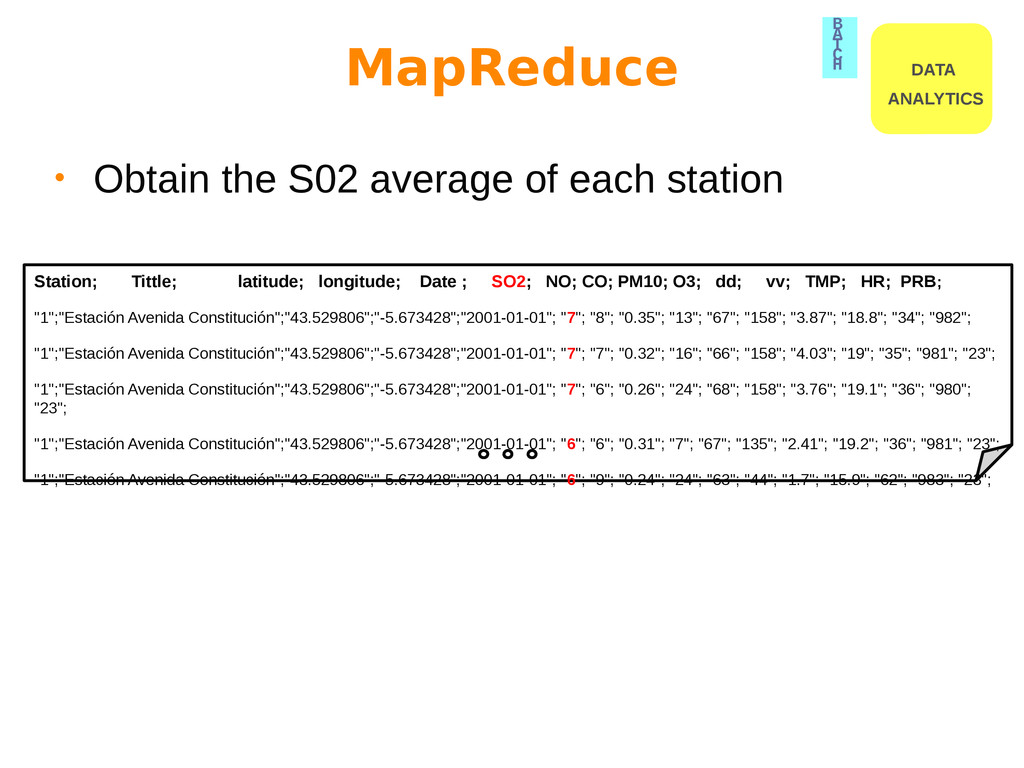
• Obtain the S02 average of each station MapReduce Station;
Tittle; latitude; longitude; Date ; SO2; NO; CO; PM10; O3; dd; vv; TMP; HR; PRB; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "8"; "0.35"; "13"; "67"; "158"; "3.87"; "18.8"; "34"; "982"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "7"; "0.32"; "16"; "66"; "158"; "4.03"; "19"; "35"; "981"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "6"; "0.26"; "24"; "68"; "158"; "3.76"; "19.1"; "36"; "980"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "6"; "0.31"; "7"; "67"; "135"; "2.41"; "19.2"; "36"; "981"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "9"; "0.24"; "24"; "63"; "44"; "1.7"; "15.9"; "62"; "983"; "23"; DATA ANALYTICS B A T C H -
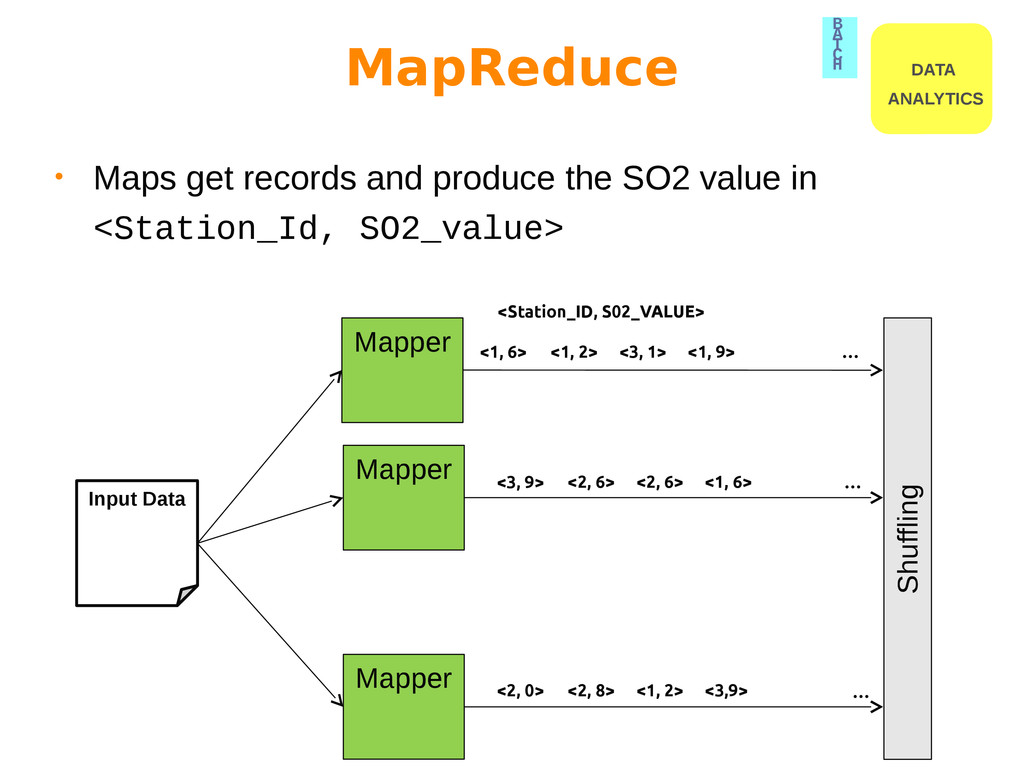
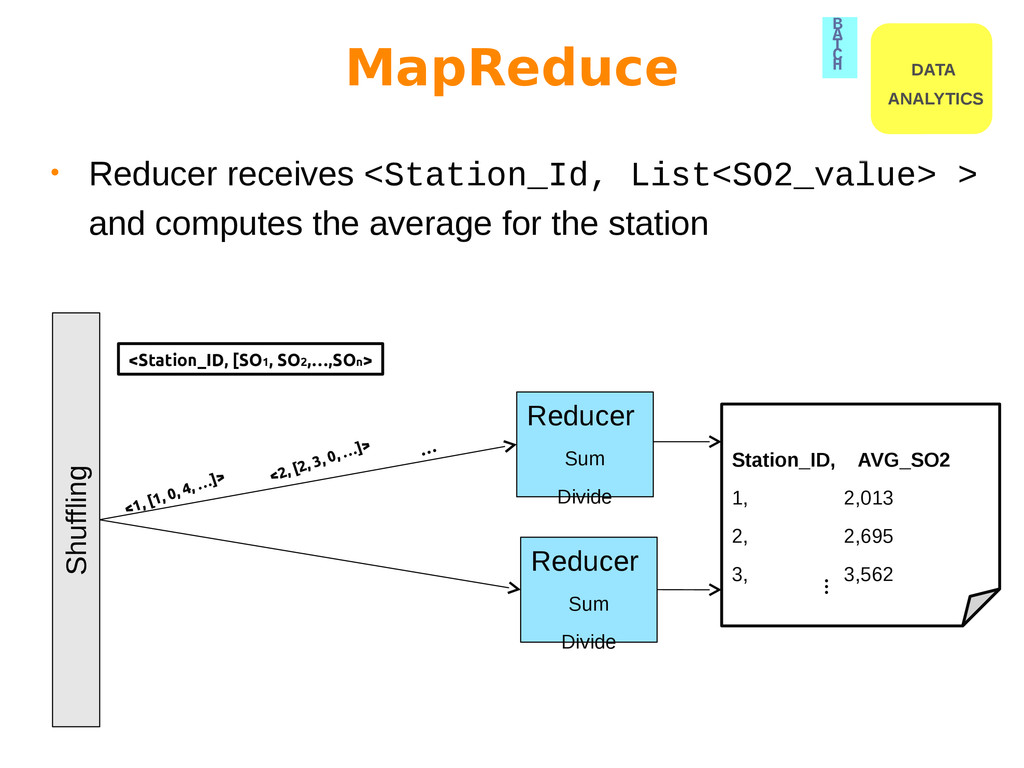
Input Data Mapper Mapper Mapper <1, 6> … … …
Shuffling <1, 2> <3, 1> <1, 9> <3, 9> <2, 6> <2, 6> <1, 6> <2, 0> <2, 8> <1, 2> <3,9> <Station_ID, S02_VALUE> MapReduce DATA ANALYTICS B A T C H • Maps get records and produce the SO2 value in <Station_Id, SO2_value> -
Station_ID, AVG_SO2 1, 2,013 2, 2,695 3, 3,562 Reducer Sum
Divide <2, [2, 3, 0, …]> <1, [1, 0, 4, …]> Shuffling Reducer Sum Divide … … <Station_ID, [SO1, SO2,…,SOn> • Reducer receives <Station_Id, List<SO2_value> > and computes the average for the station MapReduce DATA ANALYTICS B A T C H -
Hive • Hive is a data warehouse system for Hadoop
that facilitates easy data summarization, ad-hoc queries, and the analysis of large datasets • Abstraction layer on top of MapReduce • SQL-like language called HiveQL. • Metastore: Central repository of Hive metadata. DATA ANALYTICS B A T C H -
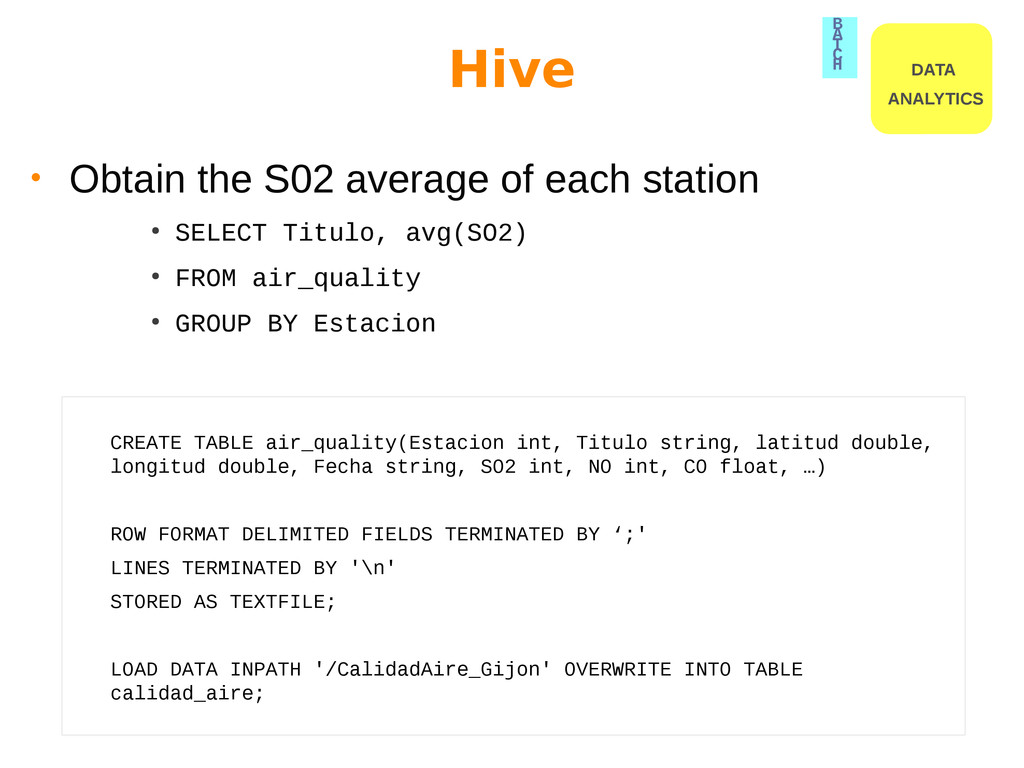
CREATE TABLE air_quality(Estacion int, Titulo string, latitud double, longitud double,
Fecha string, SO2 int, NO int, CO float, …) ROW FORMAT DELIMITED FIELDS TERMINATED BY ‘;' LINES TERMINATED BY '\n' STORED AS TEXTFILE; LOAD DATA INPATH '/CalidadAire_Gijon' OVERWRITE INTO TABLE calidad_aire; Hive • Obtain the S02 average of each station • SELECT Titulo, avg(SO2) • FROM air_quality • GROUP BY Estacion DATA ANALYTICS B A T C H -
• Platform for analyzing large data sets • High-level language
for expressing data analysis programs. Pig Latin. Data flow programming language. • Abstraction layer on top of MapReduce • Procedural language Pig DATA ANALYTICS B A T C H -
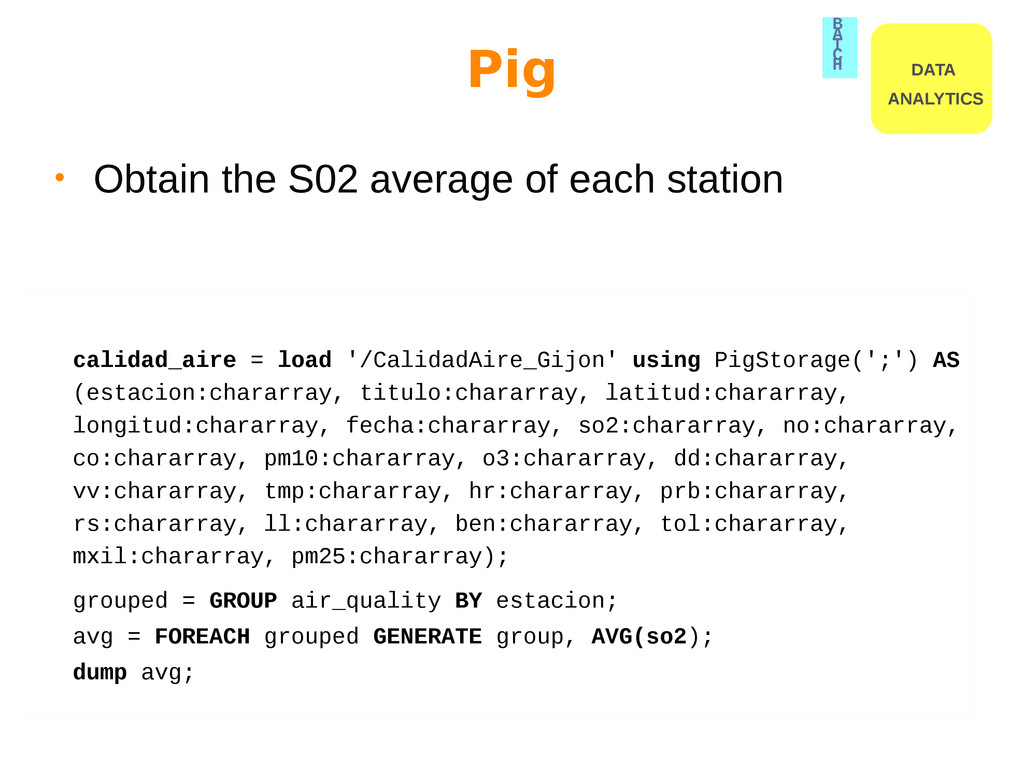
Pig DATA ANALYTICS B A T C H • Obtain
the S02 average of each station calidad_aire = load '/CalidadAire_Gijon' using PigStorage(';') AS (estacion:chararray, titulo:chararray, latitud:chararray, longitud:chararray, fecha:chararray, so2:chararray, no:chararray, co:chararray, pm10:chararray, o3:chararray, dd:chararray, vv:chararray, tmp:chararray, hr:chararray, prb:chararray, rs:chararray, ll:chararray, ben:chararray, tol:chararray, mxil:chararray, pm25:chararray); grouped = GROUP air_quality BY estacion; avg = FOREACH grouped GENERATE group, AVG(so2); dump avg; -
• Cascading is a data processing API and processing query
planner used for defining, sharing, and executing data-processing workflows • Makes development of complex Hadoop MapReduce workflows easy • In the same way that Pig DATA ANALYTICS B A T C H Cascading -
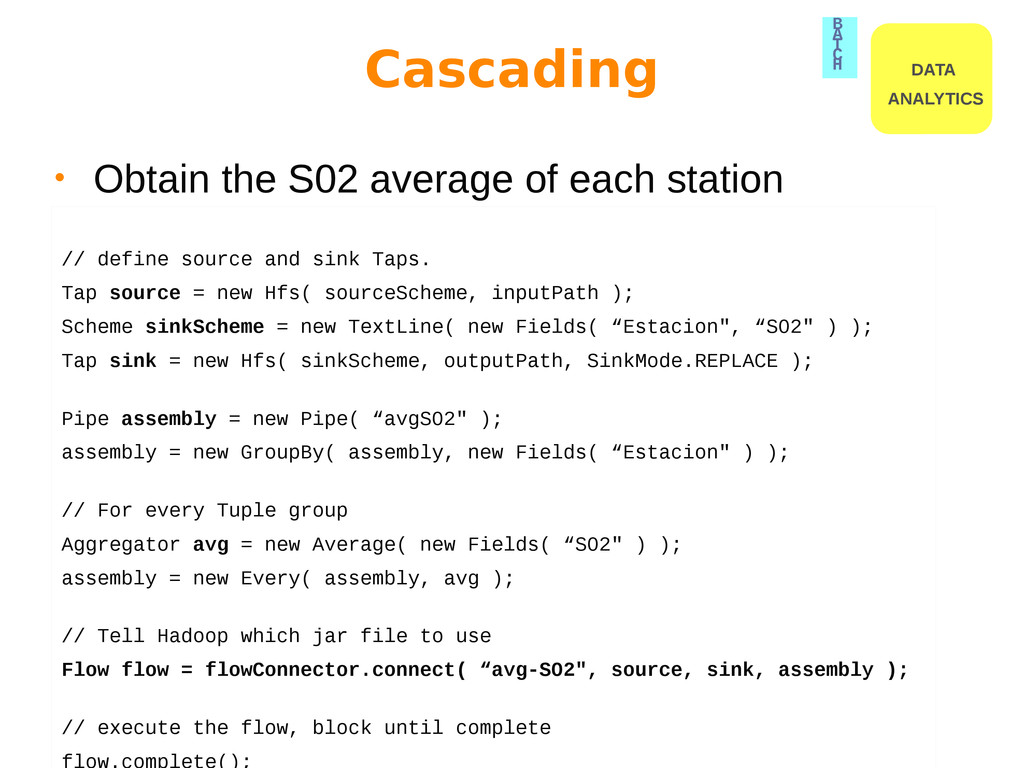
// define source and sink Taps. Tap source = new
Hfs( sourceScheme, inputPath ); Scheme sinkScheme = new TextLine( new Fields( “Estacion", “SO2" ) ); Tap sink = new Hfs( sinkScheme, outputPath, SinkMode.REPLACE ); Pipe assembly = new Pipe( “avgSO2" ); assembly = new GroupBy( assembly, new Fields( “Estacion" ) ); // For every Tuple group Aggregator avg = new Average( new Fields( “SO2" ) ); assembly = new Every( assembly, avg ); // Tell Hadoop which jar file to use Flow flow = flowConnector.connect( “avg-SO2", source, sink, assembly ); // execute the flow, block until complete flow.complete(); DATA ANALYTICS B A T C H • Obtain the S02 average of each station Cascading -
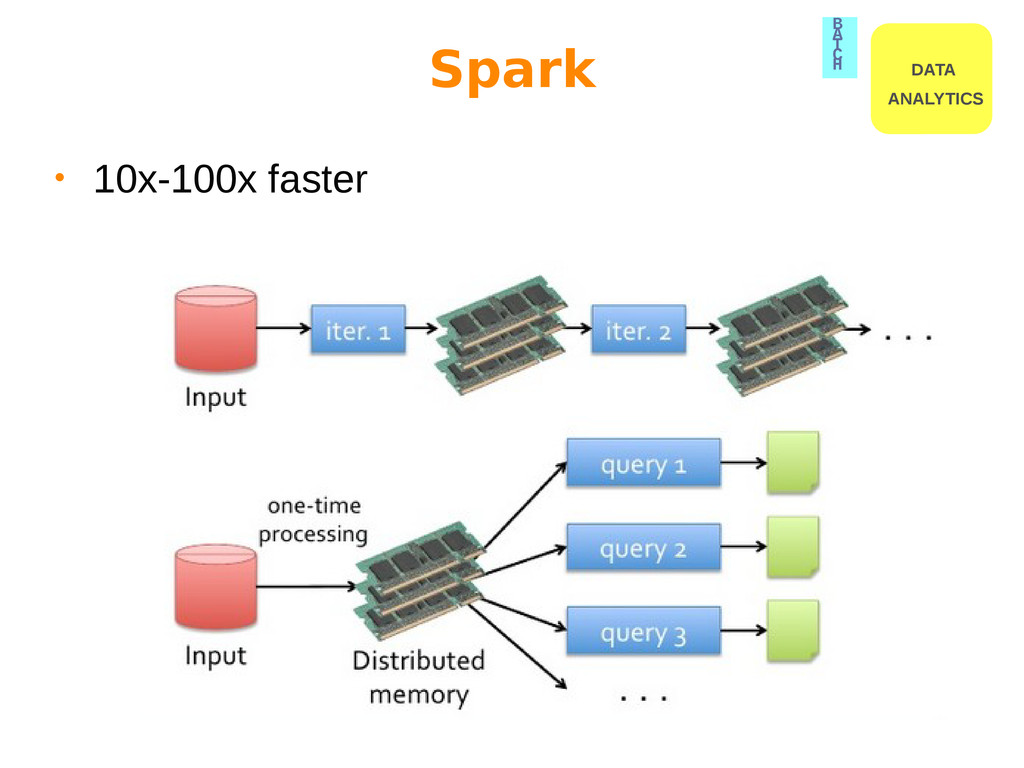
Spark • Cluster computing systems for faster data analytics •
Not a modified version of Hadoop • Compatible with HDFS • In-memory data storage for very fast iterative processing • MapReduce-like engine • API in Scala, Java and Python DATA ANALYTICS B A T C H -
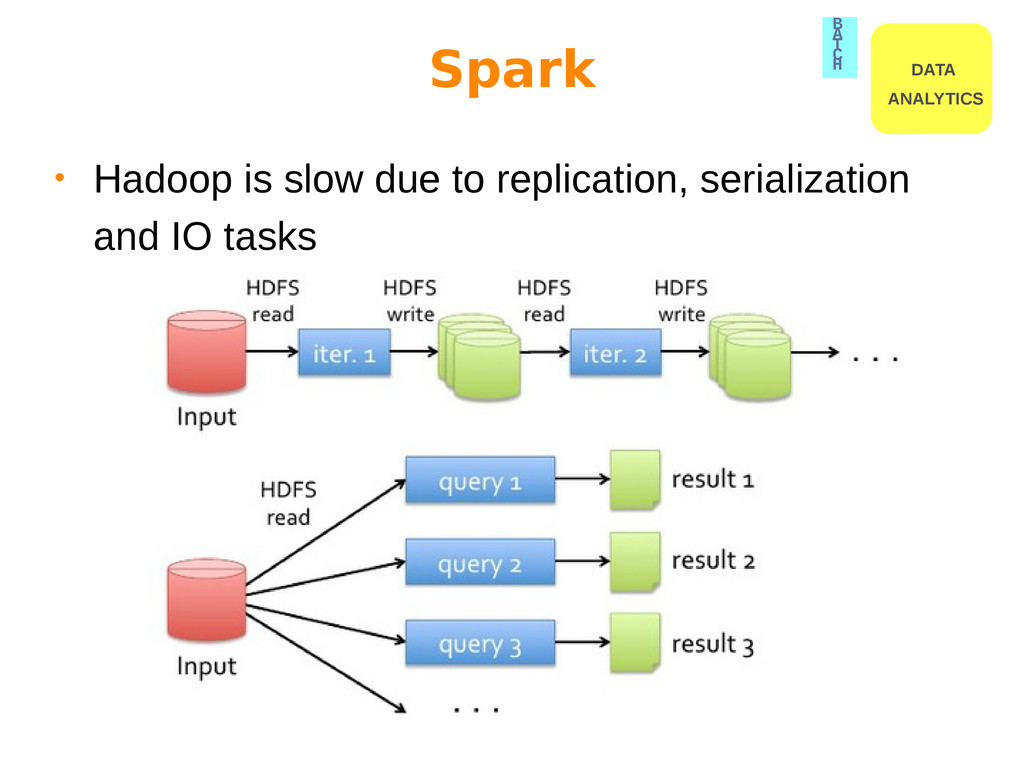
Spark DATA ANALYTICS B A T C H • Hadoop
is slow due to replication, serialization and IO tasks -
Shark • Large-scale data warehouse system for Spark • SQL
on top of Spark • Actually Hive QL over Spark • Up to 100 x faster than Hive DATA ANALYTICS B A T C H -
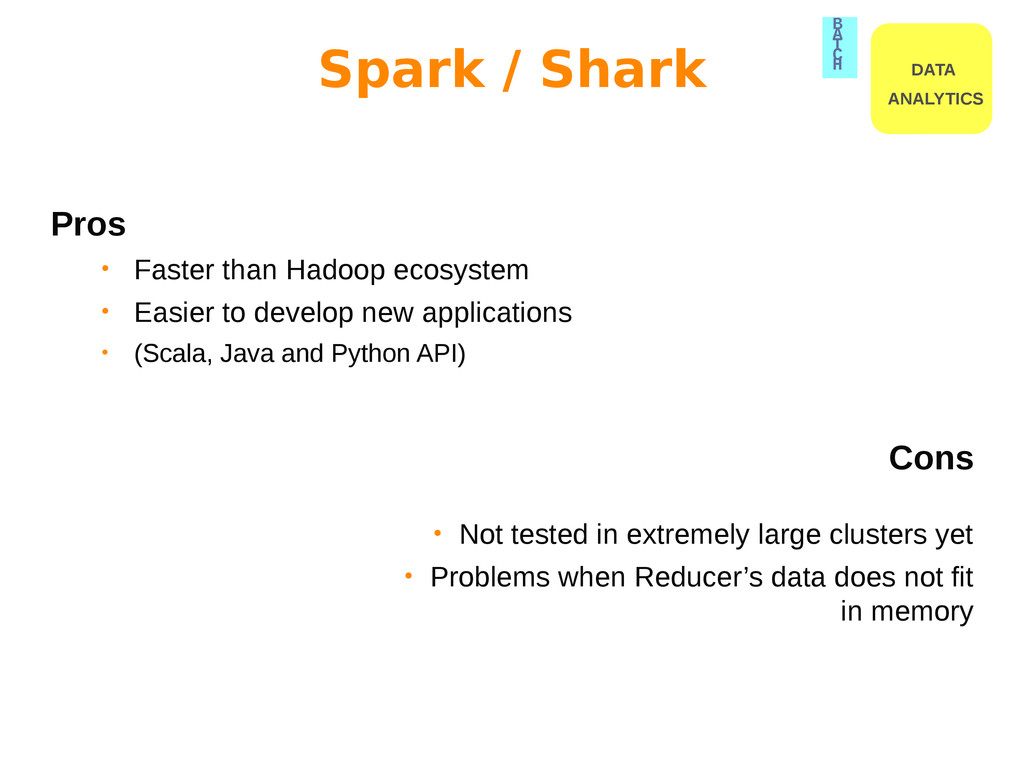
Pros • Faster than Hadoop ecosystem • Easier to develop
new applications • (Scala, Java and Python API) Cons • Not tested in extremely large clusters yet • Problems when Reducer’s data does not fit in memory DATA ANALYTICS B A T C H Spark / Shark -
1. Big Data processing 2. Batch processing 3. Real-time processing
4. Hybrid computation model 5. Conclusions Agenda -
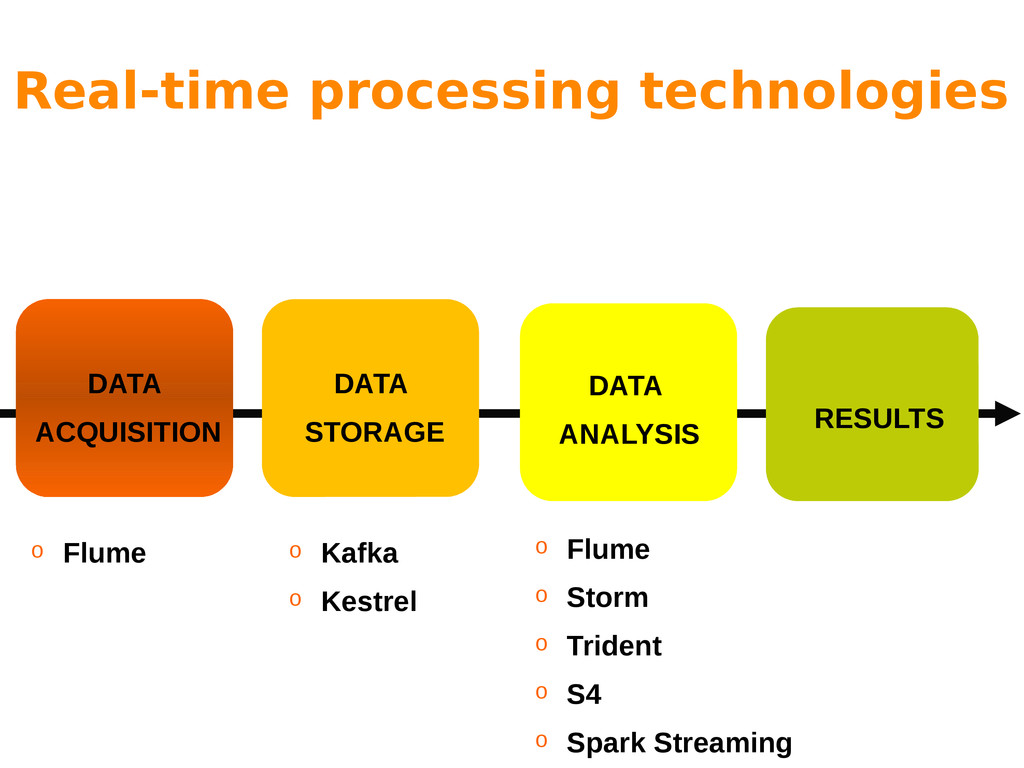
Real-time processing technologies DATA ACQUISITION DATA STORAGE DATA ANALYSIS RESULTS
o Flume o Kafka o Kestrel o Flume o Storm o Trident o S4 o Spark Streaming -
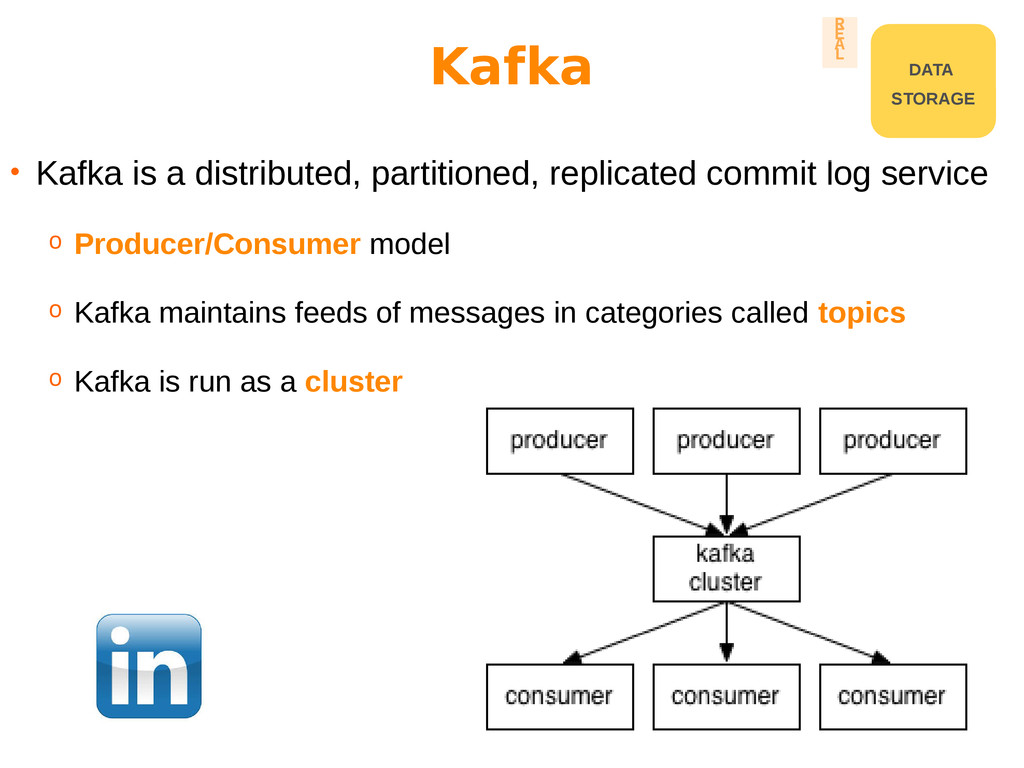
• Kafka is a distributed, partitioned, replicated commit log service
o Producer/Consumer model o Kafka maintains feeds of messages in categories called topics o Kafka is run as a cluster Kafka DATA STORAGE R E A L -
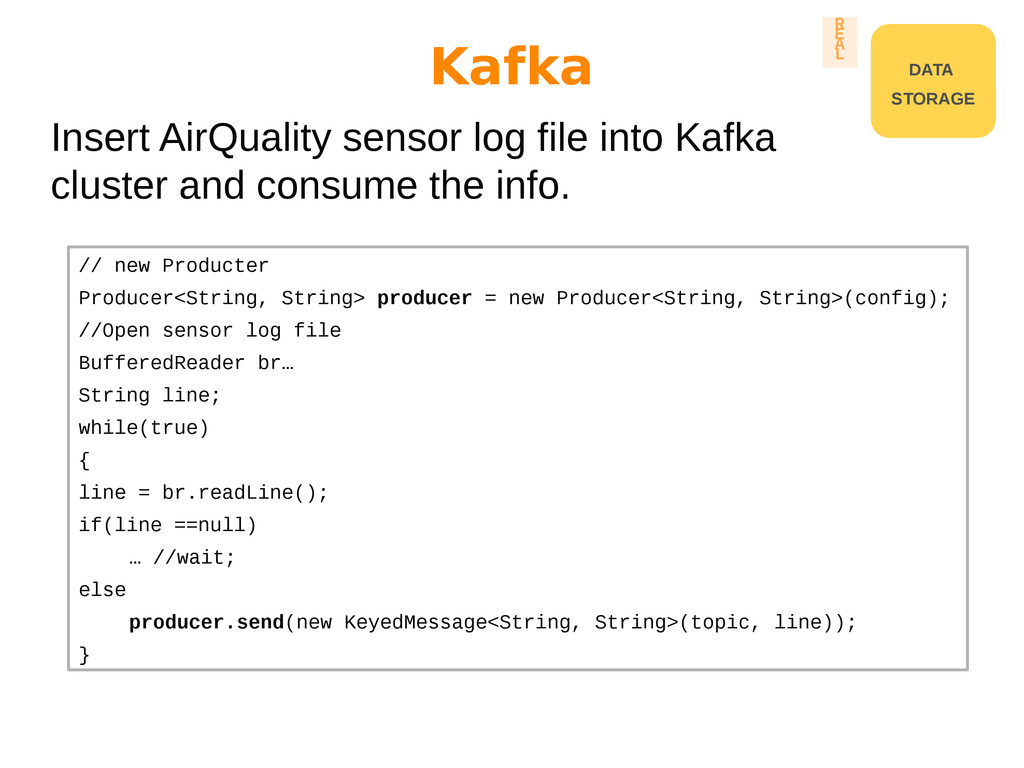
Insert AirQuality sensor log file into Kafka cluster and consume
the info. // new Producter Producer<String, String> producer = new Producer<String, String>(config); //Open sensor log file BufferedReader br… String line; while(true) { line = br.readLine(); if(line ==null) … //wait; else producer.send(new KeyedMessage<String, String>(topic, line)); } Kafka DATA STORAGE R E A L -
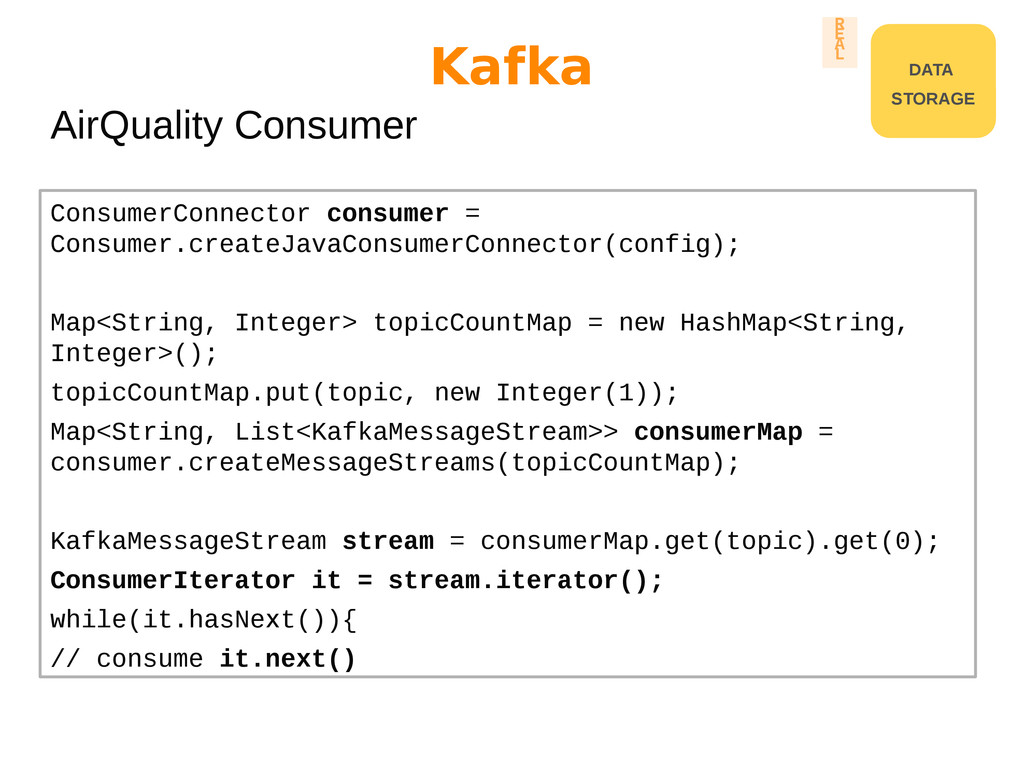
AirQuality Consumer ConsumerConnector consumer = Consumer.createJavaConsumerConnector(config); Map<String, Integer> topicCountMap =
new HashMap<String, Integer>(); topicCountMap.put(topic, new Integer(1)); Map<String, List<KafkaMessageStream>> consumerMap = consumer.createMessageStreams(topicCountMap); KafkaMessageStream stream = consumerMap.get(topic).get(0); ConsumerIterator it = stream.iterator(); while(it.hasNext()){ // consume it.next() Kafka DATA STORAGE R E A L -
• Simple distributed message queue • A single Kestrel server
has a set of queues (strictly-ordered FIFO) • On a cluster of Kestrel servers, they don’t know about each other and don’t do any cross communication • Kestrel vs Kafka o Kafka consumers cheaper (basically just the bandwidth usage) o Kestrel does not depend on Zookeeper which means it is operationally less complex if you don't already have a zookeeper installation. o Kafka has significantly better throughput. o Kestrel does not support ordered consumption Kestrel DATA STORAGE R E A L -
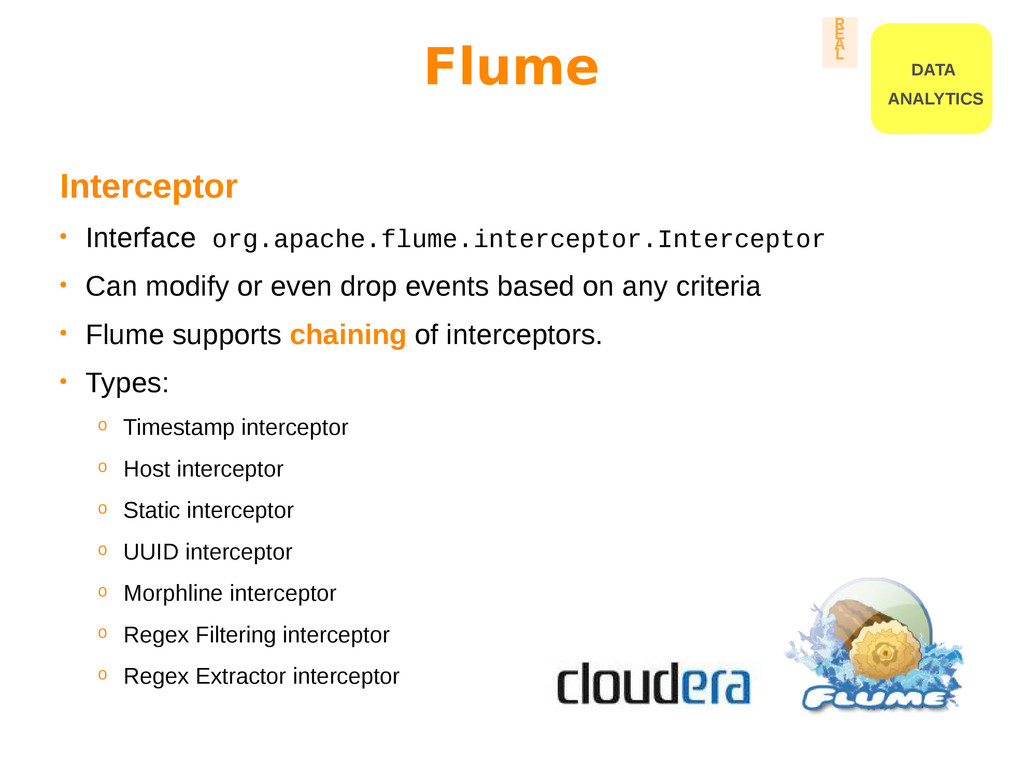
Interceptor • Interface org.apache.flume.interceptor.Interceptor • Can modify or even drop
events based on any criteria • Flume supports chaining of interceptors. • Types: o Timestamp interceptor o Host interceptor o Static interceptor o UUID interceptor o Morphline interceptor o Regex Filtering interceptor o Regex Extractor interceptor DATA ANALYTICS R E A L Flume -
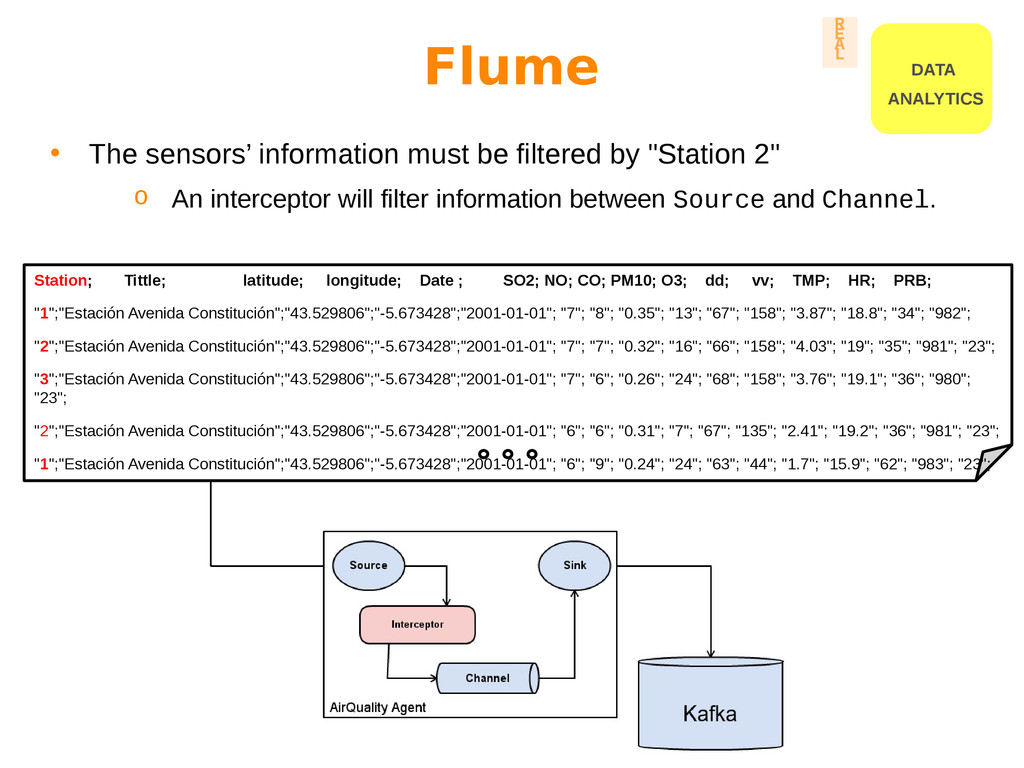
• The sensors’ information must be filtered by "Station 2"
o An interceptor will filter information between Source and Channel. Station; Tittle; latitude; longitude; Date ; SO2; NO; CO; PM10; O3; dd; vv; TMP; HR; PRB; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "8"; "0.35"; "13"; "67"; "158"; "3.87"; "18.8"; "34"; "982"; "2";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "7"; "0.32"; "16"; "66"; "158"; "4.03"; "19"; "35"; "981"; "23"; "3";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "7"; "6"; "0.26"; "24"; "68"; "158"; "3.76"; "19.1"; "36"; "980"; "23"; "2";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "6"; "0.31"; "7"; "67"; "135"; "2.41"; "19.2"; "36"; "981"; "23"; "1";"Estación Avenida Constitución";"43.529806";"-5.673428";"2001-01-01"; "6"; "9"; "0.24"; "24"; "63"; "44"; "1.7"; "15.9"; "62"; "983"; "23"; DATA ANALYTICS R E A L Flume -
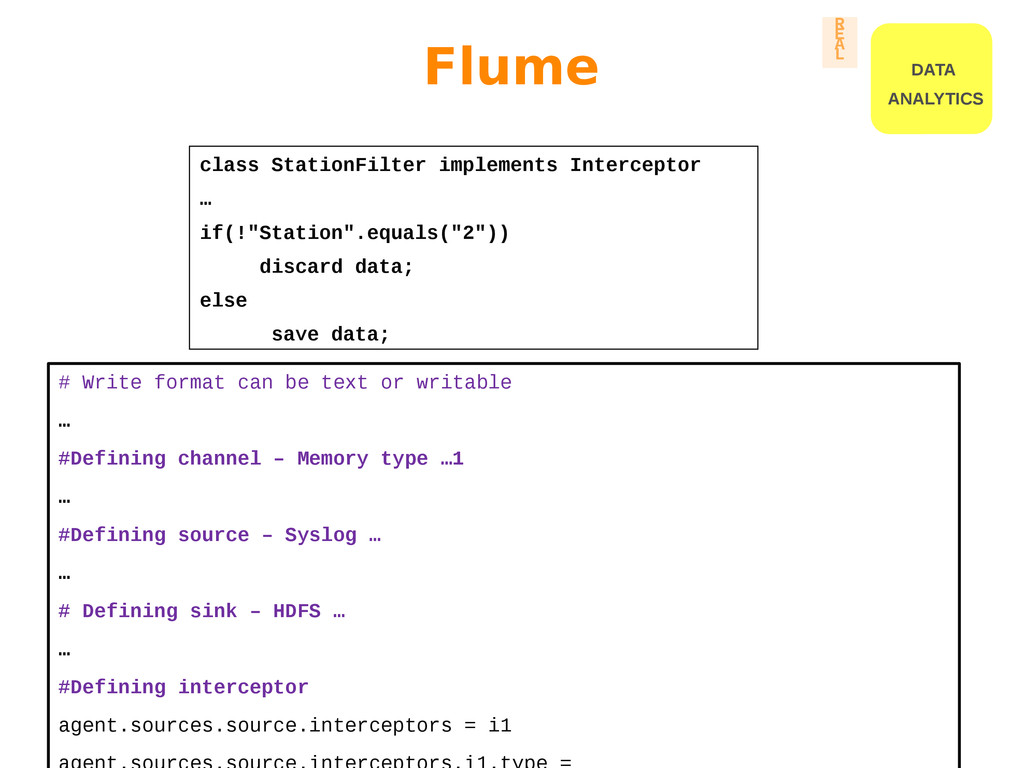
# Write format can be text or writable … #Defining
channel – Memory type …1 … #Defining source – Syslog … … # Defining sink – HDFS … … #Defining interceptor agent.sources.source.interceptors = i1 class StationFilter implements Interceptor … if(!"Station".equals("2")) discard data; else save data; DATA ANALYTICS R E A L Flume -
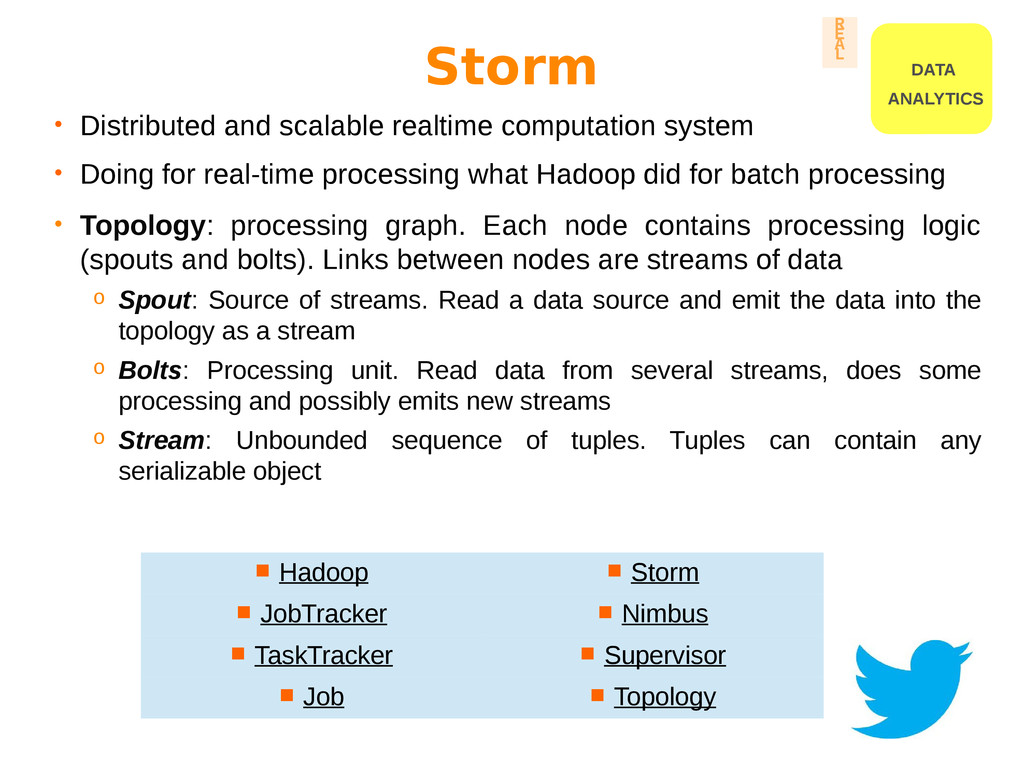
Hadoop Storm JobTracker Nimbus TaskTracker
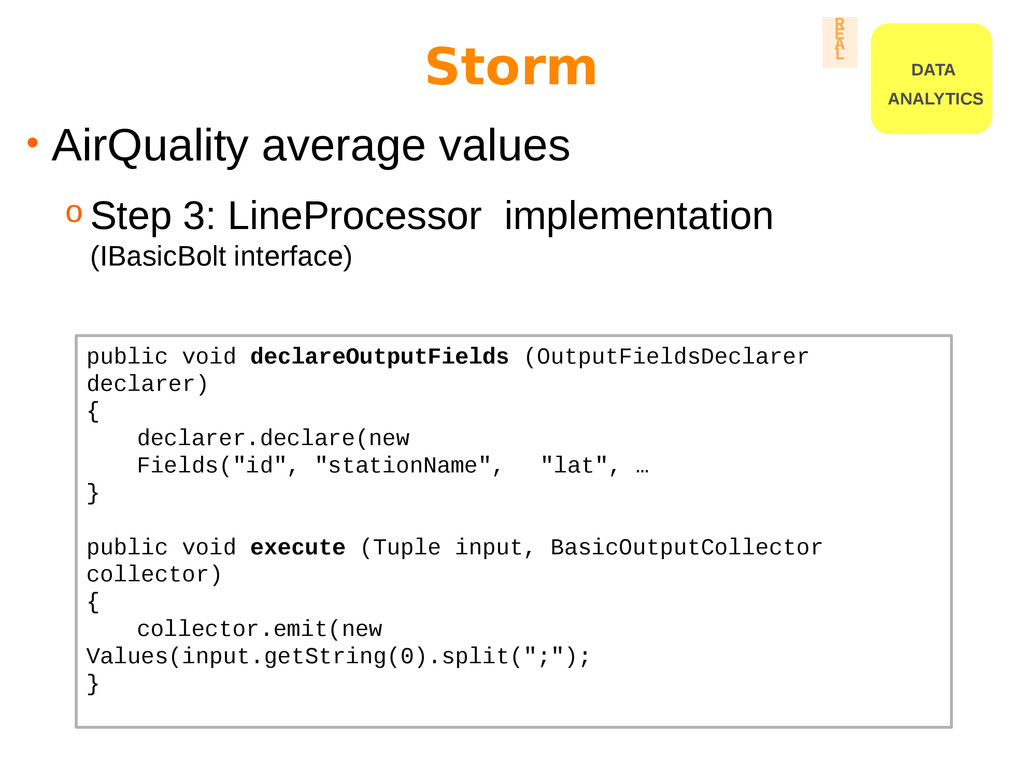
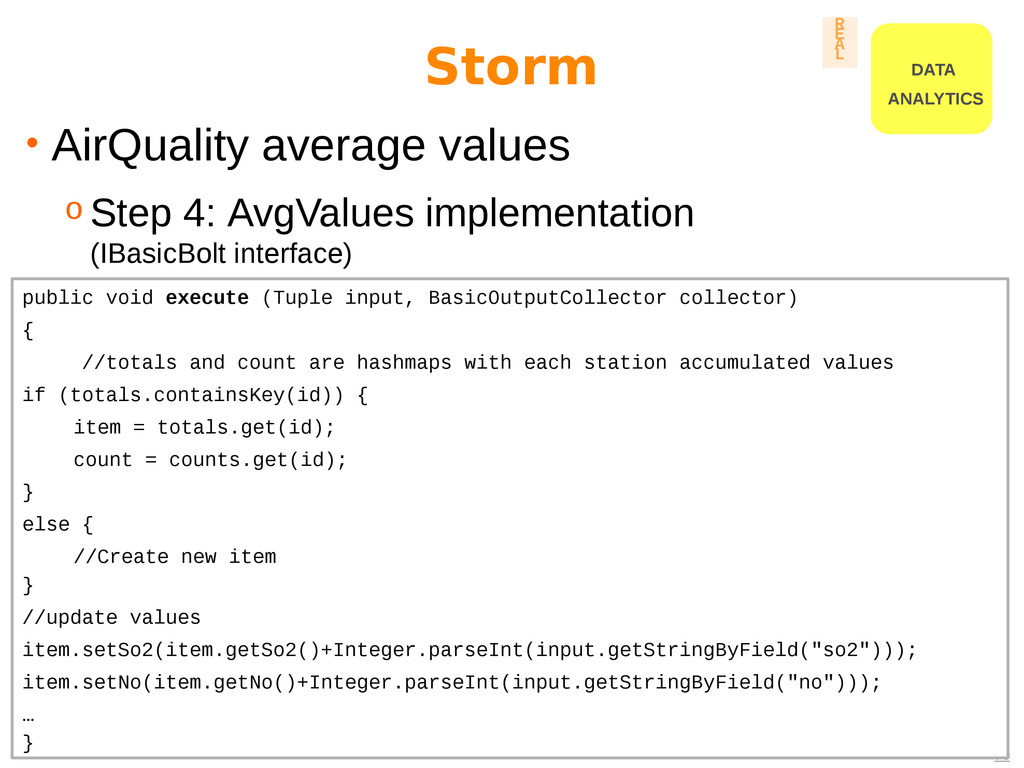
Supervisor Job Topology • Distributed and scalable realtime computation system • Doing for real-time processing what Hadoop did for batch processing • Topology: processing graph. Each node contains processing logic (spouts and bolts). Links between nodes are streams of data o Spout: Source of streams. Read a data source and emit the data into the topology as a stream o Bolts: Processing unit. Read data from several streams, does some processing and possibly emits new streams o Stream: Unbounded sequence of tuples. Tuples can contain any serializable object Storm DATA ANALYTICS R E A L -
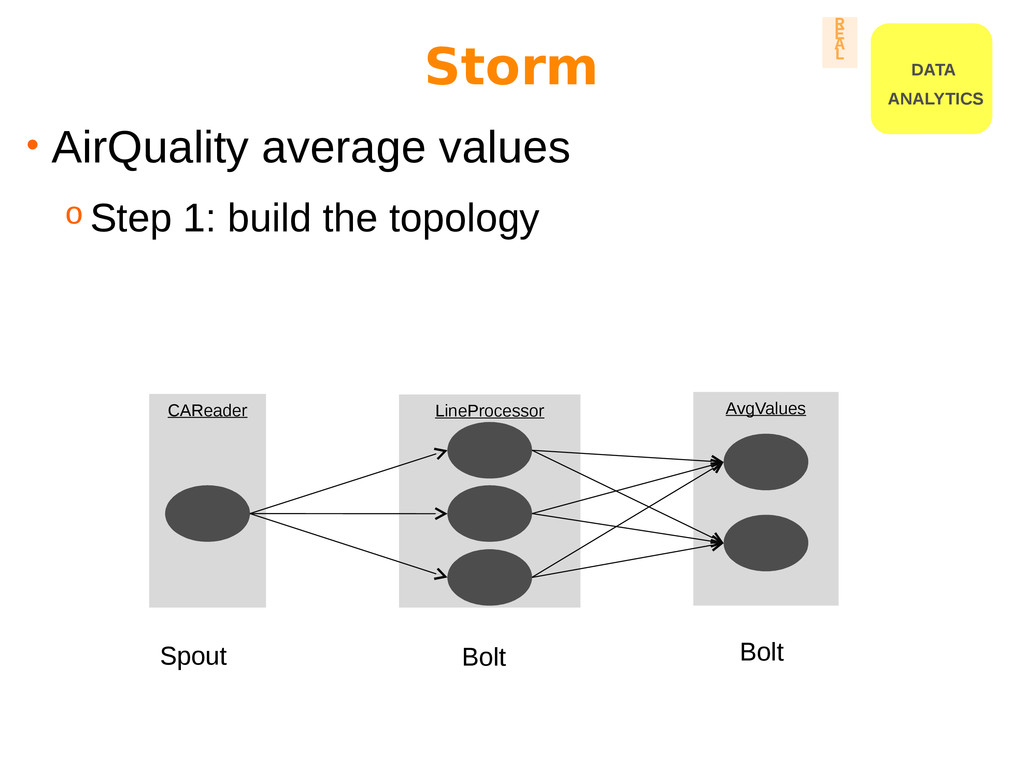
CAReader LineProcessor AvgValues • AirQuality average values o Step 1:
build the topology Storm DATA ANALYTICS R E A L Spout Bolt Bolt -
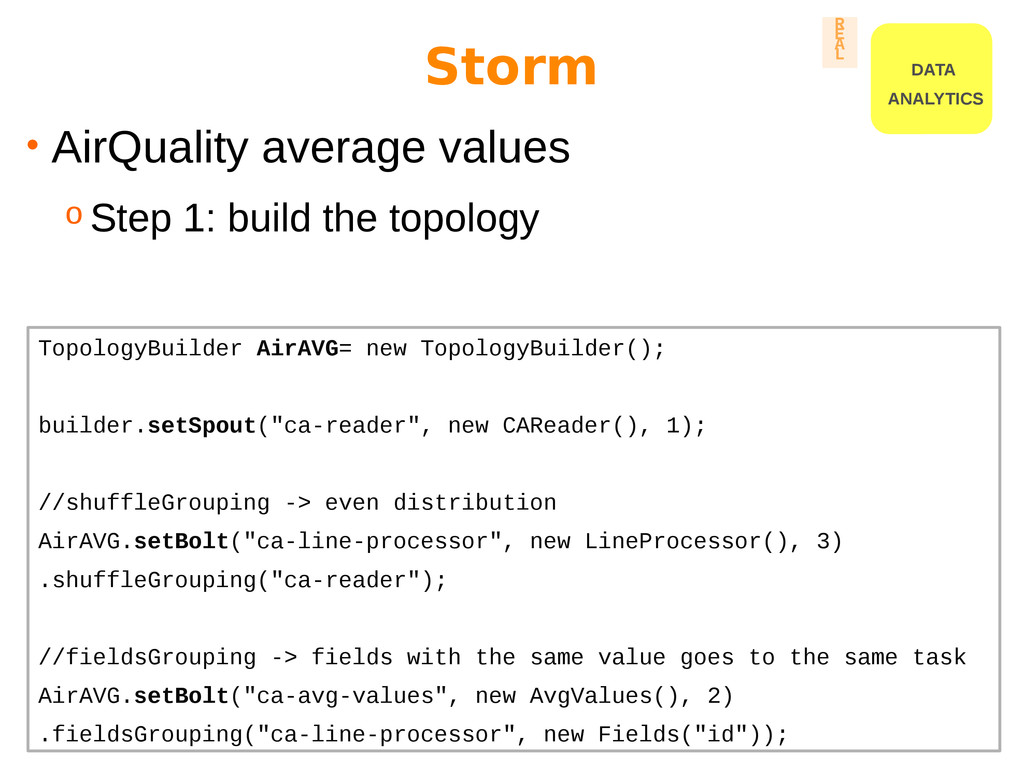
• AirQuality average values o Step 1: build the topology
TopologyBuilder AirAVG= new TopologyBuilder(); builder.setSpout("ca-reader", new CAReader(), 1); //shuffleGrouping -> even distribution AirAVG.setBolt("ca-line-processor", new LineProcessor(), 3) .shuffleGrouping("ca-reader"); //fieldsGrouping -> fields with the same value goes to the same task AirAVG.setBolt("ca-avg-values", new AvgValues(), 2) .fieldsGrouping("ca-line-processor", new Fields("id")); Storm DATA ANALYTICS R E A L -
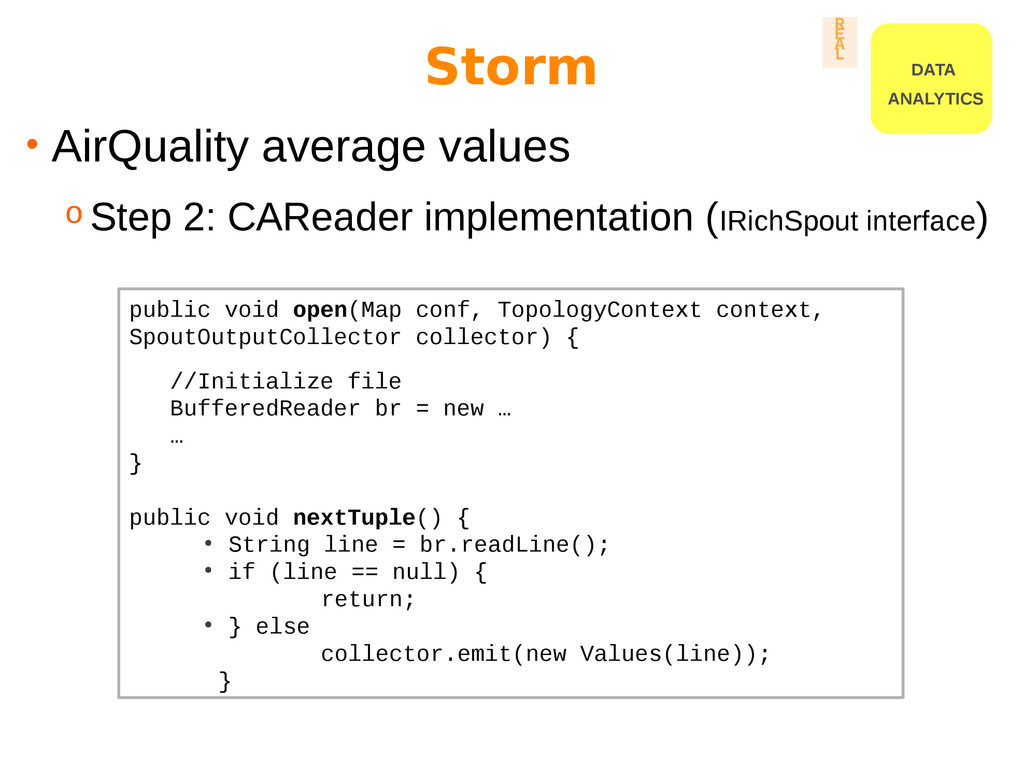
public void open(Map conf, TopologyContext context, SpoutOutputCollector collector) { //Initialize
file BufferedReader br = new … … } public void nextTuple() { • String line = br.readLine(); • if (line == null) { return; • } else collector.emit(new Values(line)); } Storm • AirQuality average values o Step 2: CAReader implementation (IRichSpout interface) DATA ANALYTICS R E A L -
public void declareOutputFields (OutputFieldsDeclarer declarer) { declarer.declare(new Fields("id", "stationName", "lat",
… } public void execute (Tuple input, BasicOutputCollector collector) { collector.emit(new Values(input.getString(0).split(";"); } Storm • AirQuality average values o Step 3: LineProcessor implementation (IBasicBolt interface) DATA ANALYTICS R E A L -
70 public void execute (Tuple input, BasicOutputCollector collector) { //totals
and count are hashmaps with each station accumulated values if (totals.containsKey(id)) { item = totals.get(id); count = counts.get(id); } else { //Create new item } //update values item.setSo2(item.getSo2()+Integer.parseInt(input.getStringByField("so2"))); item.setNo(item.getNo()+Integer.parseInt(input.getStringByField("no"))); … } Storm • AirQuality average values o Step 4: AvgValues implementation (IBasicBolt interface) DATA ANALYTICS R E A L -
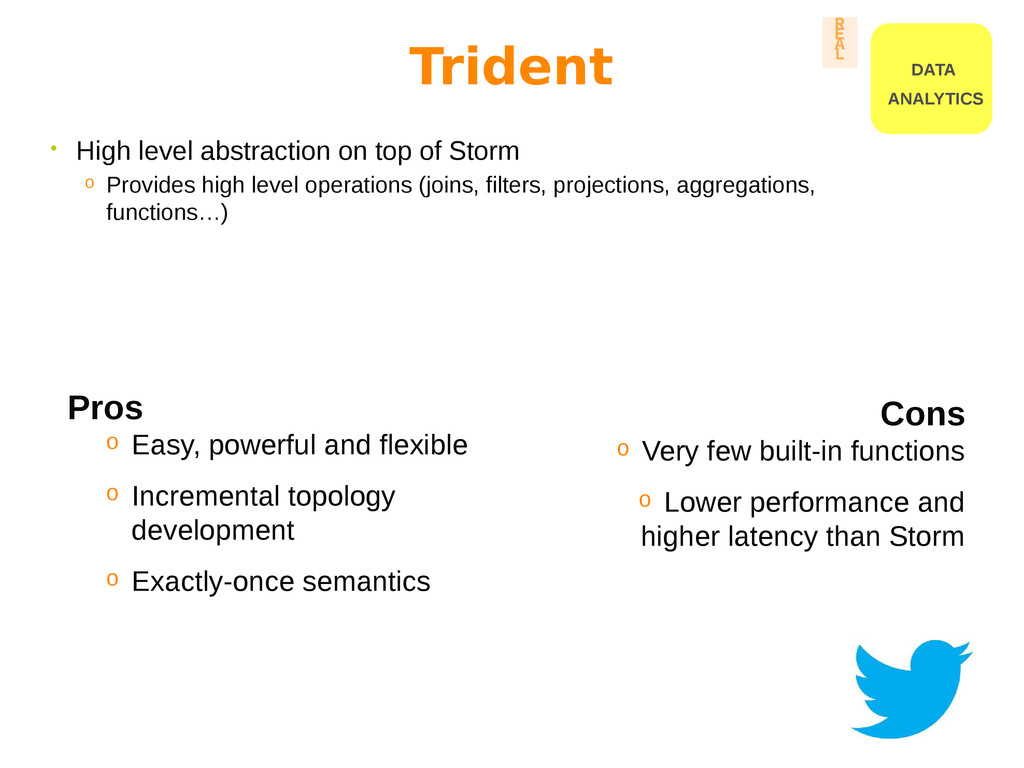
• High level abstraction on top of Storm o Provides
high level operations (joins, filters, projections, aggregations, functions…) Pros o Easy, powerful and flexible o Incremental topology development o Exactly-once semantics Cons o Very few built-in functions o Lower performance and higher latency than Storm Trident DATA ANALYTICS R E A L -
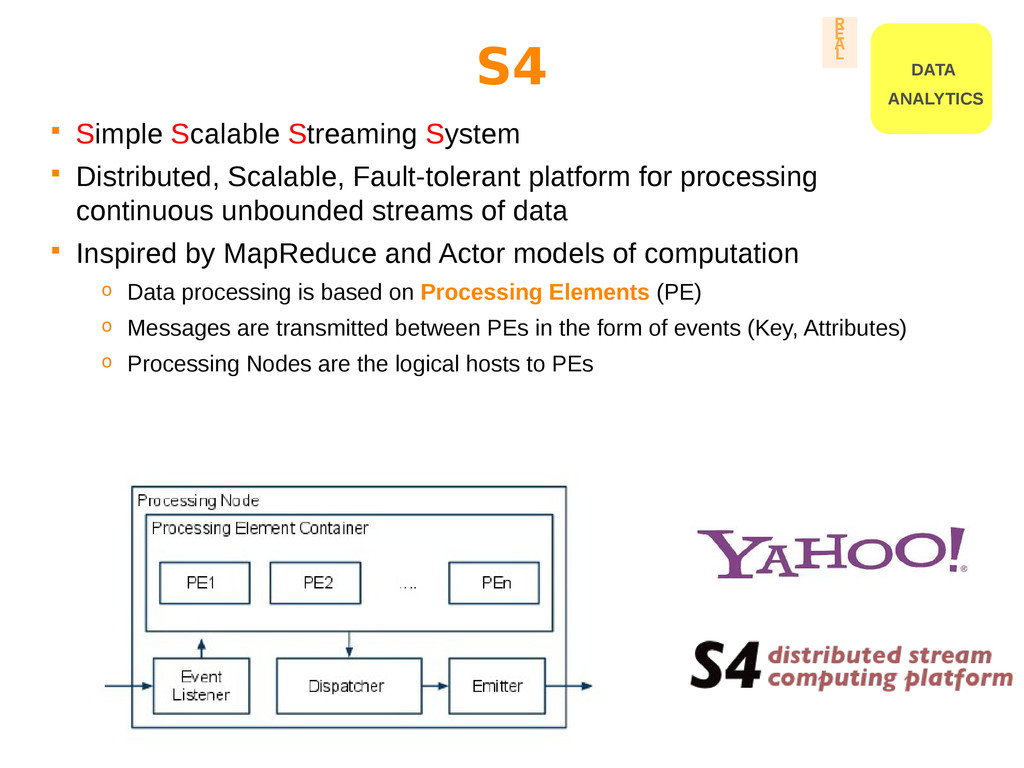
Simple Scalable Streaming System Distributed, Scalable, Fault-tolerant platform
for processing continuous unbounded streams of data Inspired by MapReduce and Actor models of computation o Data processing is based on Processing Elements (PE) o Messages are transmitted between PEs in the form of events (Key, Attributes) o Processing Nodes are the logical hosts to PEs DATA ANALYTICS R E A L S4 -
… <bean id="split" class="SplitPE"> <property name="dispatcher" ref="dispatcher"/> <property name="keys"> <!--
Listen for both words and sentences --> <list> <value>LogLines *</value> </list> </property> </bean> <bean id="average" class="AveragePE"> <property name="keys"> <list> <value>CAItem stationId</value> </list> </property> </bean> • AirQuality average values S4 DATA ANALYTICS R E A L -
Spark Streaming • Spark for real-time processing • Streaming computation
as a series of very short batch jobs (windows) • Keep state in memory • API similar to Spark DATA ANALYTICS R E A L -
1. Big Data processing 2. Batch processing 3. Real-time processing
4. Hybrid computation model 5. Conclusions Agenda -
• We are in the beginning of this generation •
Short-term Big Data processing goal • Abstraction layer over the Lambda Architecture • Promising technologies o SummingBird o Lambdoop Hybrid Computation Model -
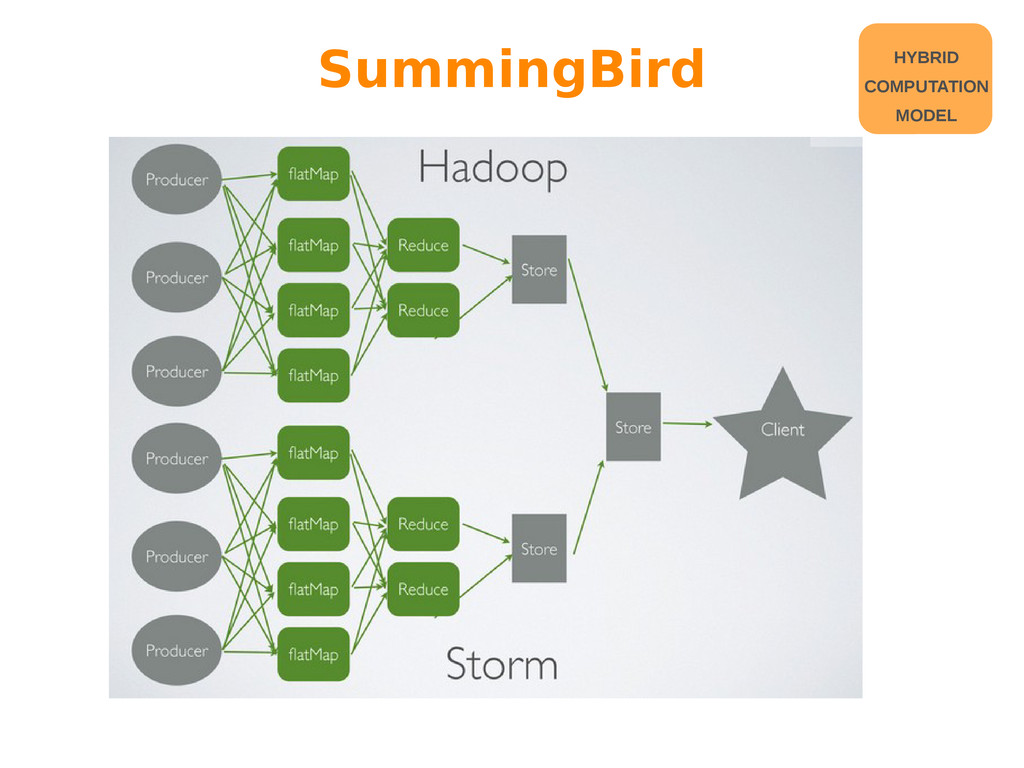
SummingBird • Library to write MapReduce-like process that can be
executed on Hadoop, Storm or hybrid model • Scala syntaxis • Same logic can be executed in batch, real-time and hybrid bath/real mode HYBRID COMPUTATION MODEL -
Pros • Hybrid computation model • Same programing model for
all proccesing paradigms • Extensible Cons • MapReduce-like programing • Scala • Not as abstract as some users would like SummingBird HYBRID COMPUTATION MODEL -
Software abstraction layer over Open Source technologies o Hadoop,
HBase, Sqoop, Flume, Kafka, Storm, Trident Common patterns and operations (aggregation, filtering, statistics…) already implemented. No MapReduce-like process Same single API for the three processing paradigms o Batch processing similar to Pig / Cascading o Real time processing using built-in functions easier than Trident o Hybrid computation model transparent for the developer Lambdoop HYBRID COMPUTATION MODEL -
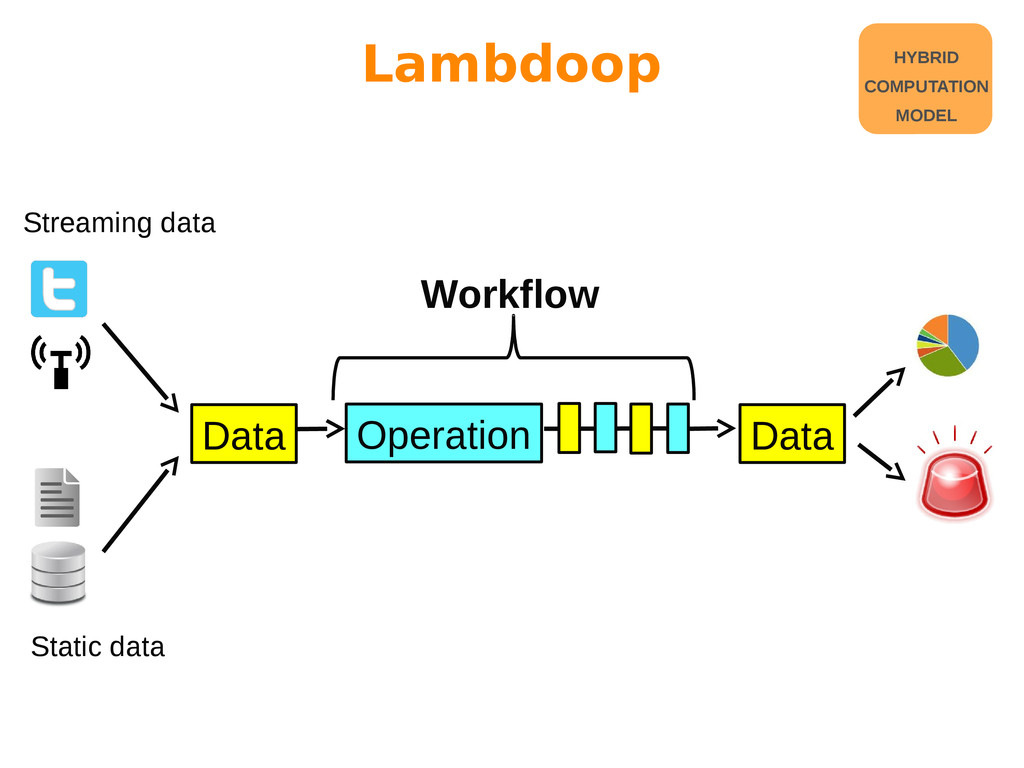
Lambdoop Data Operation Data Workflow Streaming data Static data HYBRID
COMPUTATION MODEL -
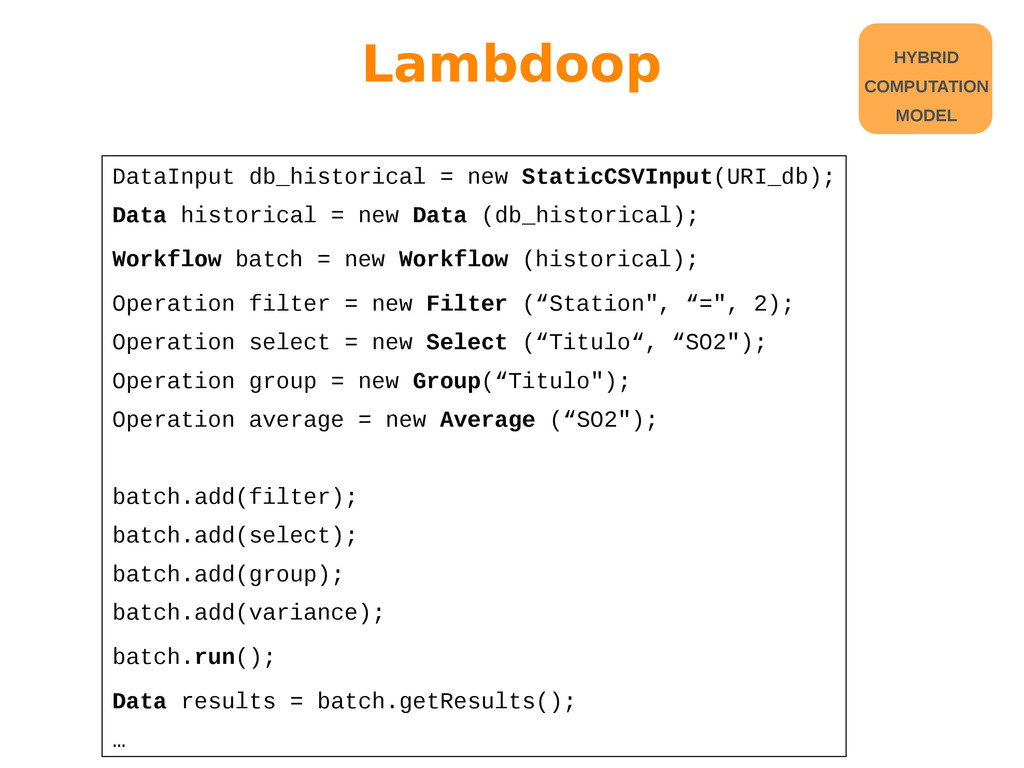
DataInput db_historical = new StaticCSVInput(URI_db); Data historical = new Data
(db_historical); Workflow batch = new Workflow (historical); Operation filter = new Filter (“Station", “=", 2); Operation select = new Select (“Titulo“, “SO2"); Operation group = new Group(“Titulo"); Operation average = new Average (“SO2"); batch.add(filter); batch.add(select); batch.add(group); batch.add(variance); batch.run(); Data results = batch.getResults(); … Lambdoop HYBRID COMPUTATION MODEL -
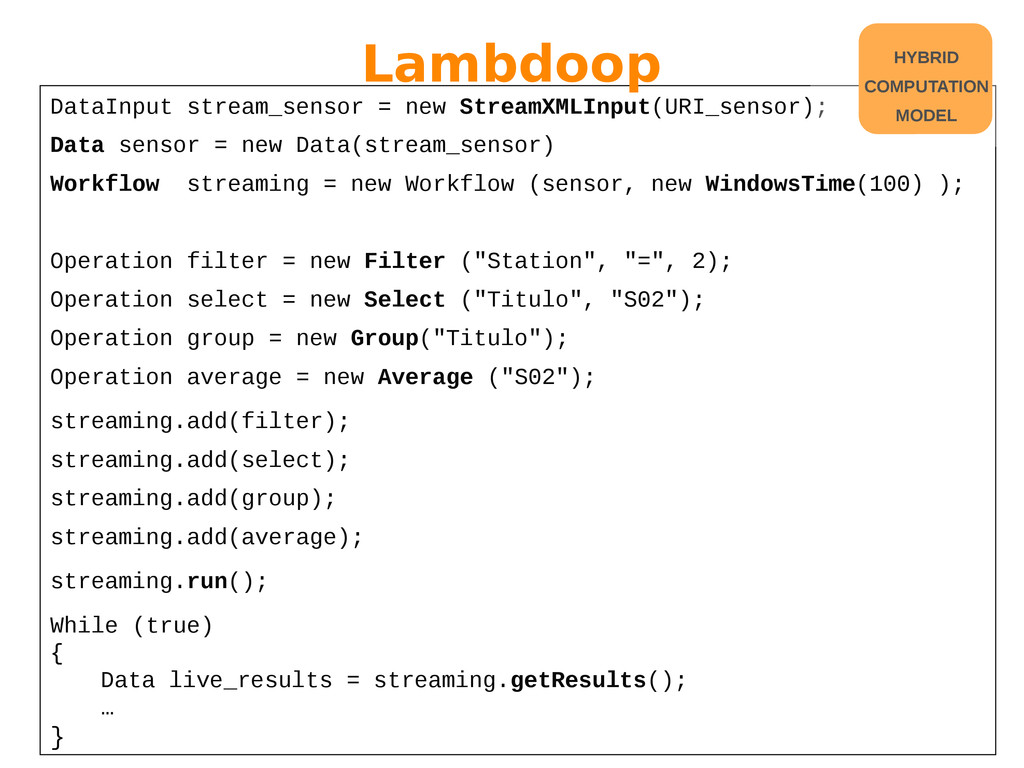
DataInput stream_sensor = new StreamXMLInput(URI_sensor); Data sensor = new Data(stream_sensor)
Workflow streaming = new Workflow (sensor, new WindowsTime(100) ); Operation filter = new Filter ("Station", "=", 2); Operation select = new Select ("Titulo", "S02"); Operation group = new Group("Titulo"); Operation average = new Average ("S02"); streaming.add(filter); streaming.add(select); streaming.add(group); streaming.add(average); streaming.run(); While (true) { Data live_results = streaming.getResults(); … } Lambdoop HYBRID COMPUTATION MODEL -
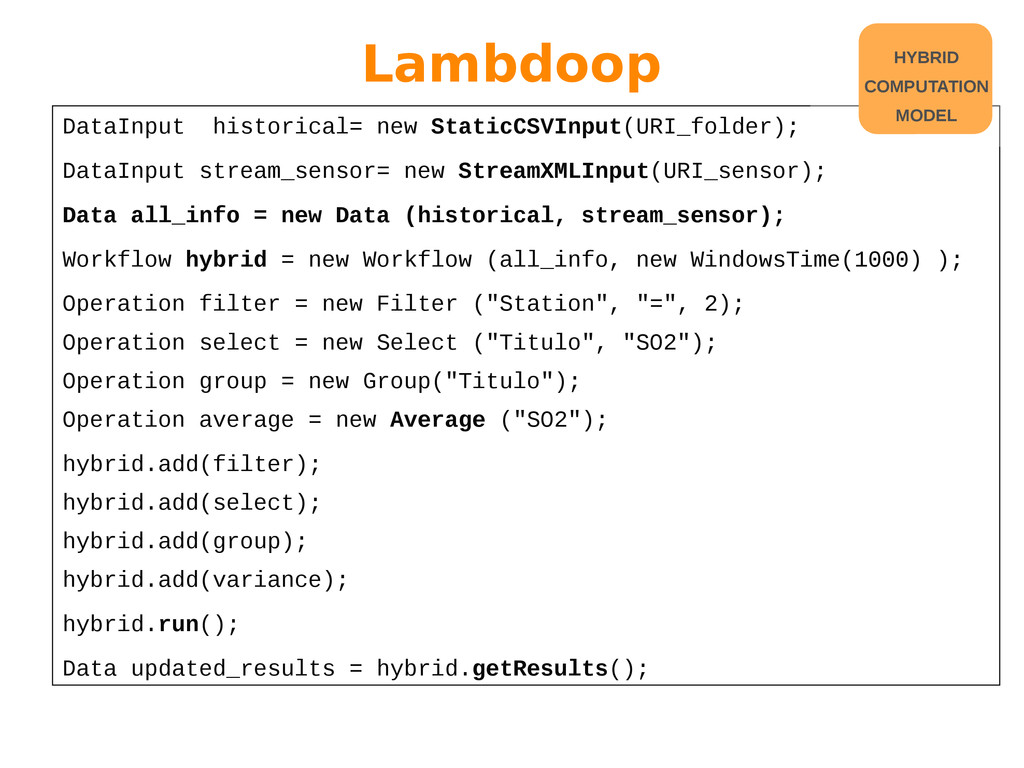
DataInput historical= new StaticCSVInput(URI_folder); DataInput stream_sensor= new StreamXMLInput(URI_sensor); Data all_info
= new Data (historical, stream_sensor); Workflow hybrid = new Workflow (all_info, new WindowsTime(1000) ); Operation filter = new Filter ("Station", "=", 2); Operation select = new Select ("Titulo", "SO2"); Operation group = new Group("Titulo"); Operation average = new Average ("SO2"); hybrid.add(filter); hybrid.add(select); hybrid.add(group); hybrid.add(variance); hybrid.run(); Data updated_results = hybrid.getResults(); Lambdoop HYBRID COMPUTATION MODEL -
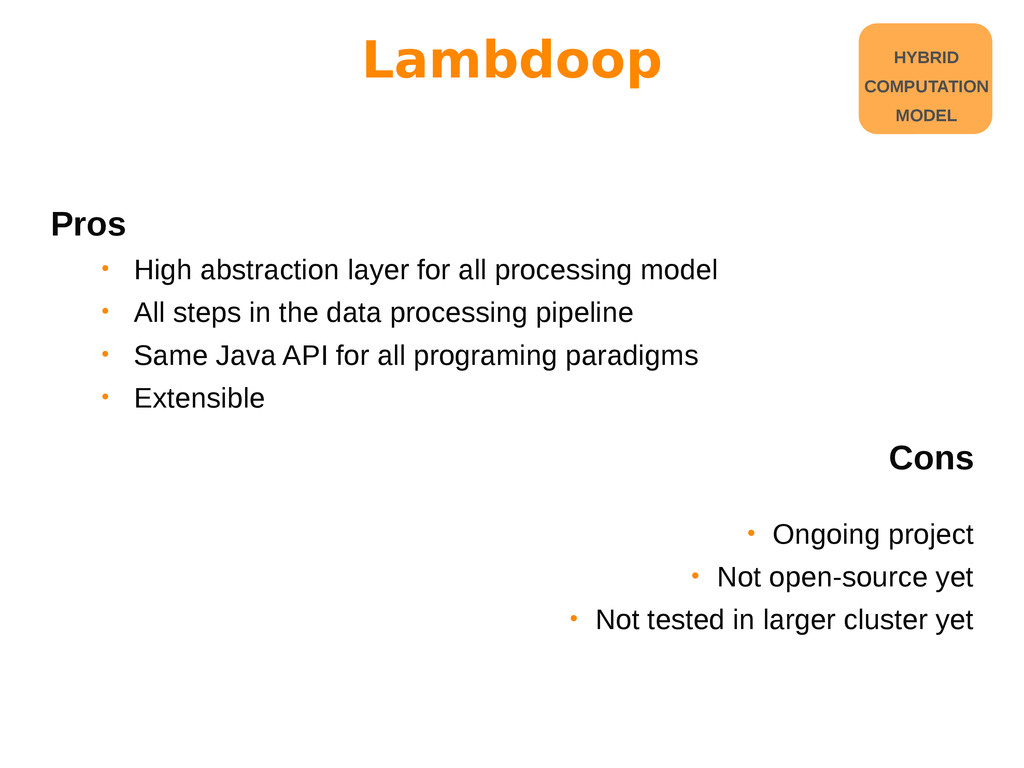
Pros • High abstraction layer for all processing model •
All steps in the data processing pipeline • Same Java API for all programing paradigms • Extensible Cons • Ongoing project • Not open-source yet • Not tested in larger cluster yet Lambdoop HYBRID COMPUTATION MODEL -
1. Big Data processing 2. Batch processing 3. Real-time processing
4. Hybrid computation model 5. Conclusions Agenda -
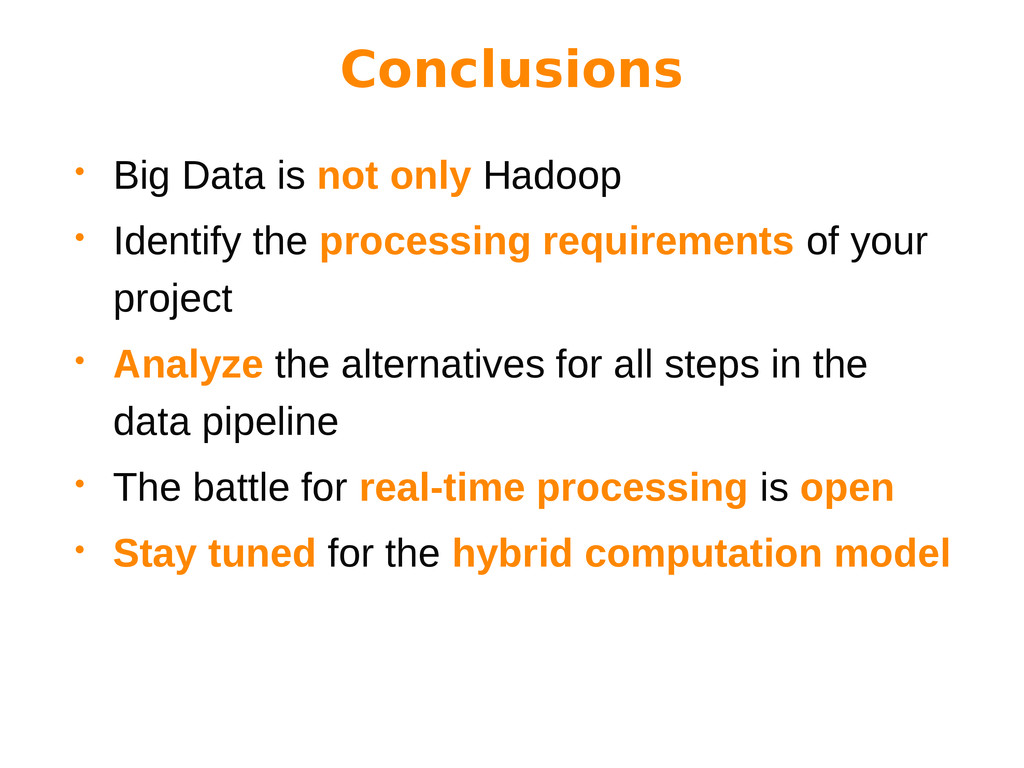
Conclusions • Big Data is not only Hadoop • Identify
the processing requirements of your project • Analyze the alternatives for all steps in the data pipeline • The battle for real-time processing is open • Stay tuned for the hybrid computation model -
Thanks for your attention! www.datadopter.com www.treelogic.com Contact us: [email protected] [email protected]
MADRID Avda. de Manoteras, 38 Oficina D507 28050 Madrid · España ASTURIAS Parque Tecnológico de Asturias Parcela 30 33428 Llanera - Asturias · España 902 286 386
 bigdataspain
 chrislema
 csswizardry
 apolaine
 davidcarrasco
 jonoalderson
 malarkey
 uxyall
 jonyablonski
 samanthasiow
 auna
 reverentgeek
 chriscoyier