of Energy Exploiting Hierarchical Parallelism in an Astrophysical Equation of State using OpenACC and OpenMP Bronson Messer1,2,3 Tom Papatheodore1 1) Oak Ridge Leadership Computing Facility Oak Ridge National Laboratory 2) Theoretical Physics Group Oak Ridge National Laboratory 3) Department of Physics & Astronomy University of Tennessee ParCo 2017 Bologna
to run on the upcoming (CORAL) Summit supercomputer at ORNL • Summit – IBM POWER9 + NVIDIA Volta FLASH – adaptive-mesh, multi-physics simulation code widely used in astrophysics This research used resources of the Oak Ridge Leadership Computing Facility at the Oak Ridge National Laboratory, which is supported by the Office of Science of the U.S. Department of Energy under Contract No. DE-AC05-00OR22725.
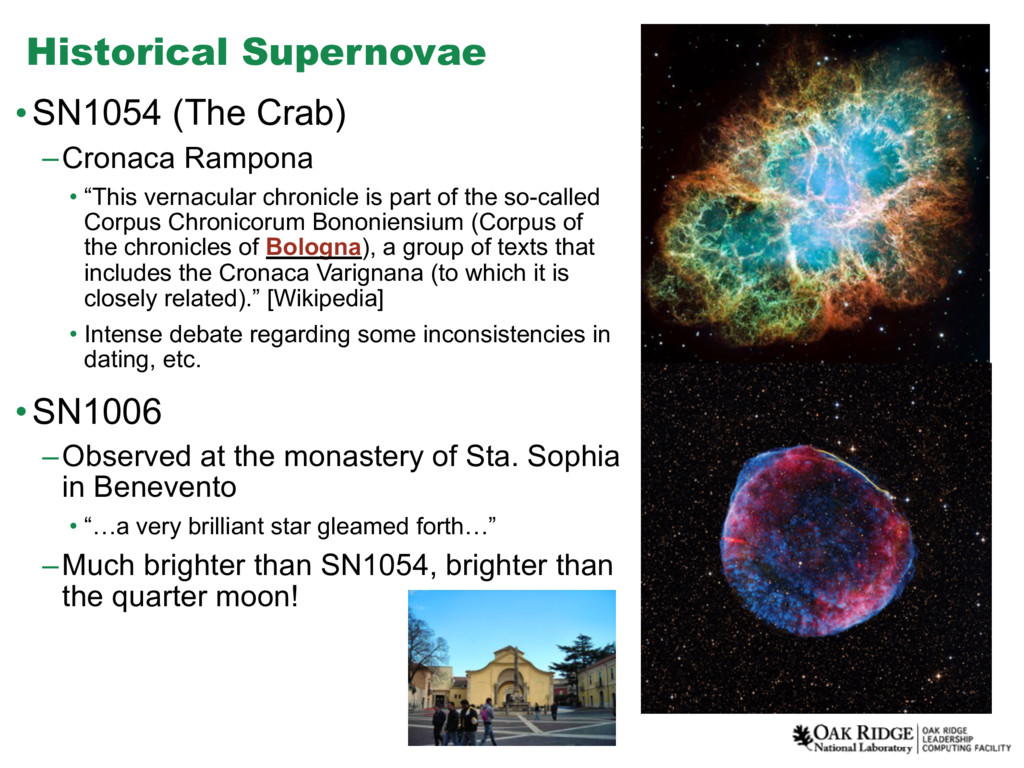
chronicle is part of the so-called Corpus Chronicorum Bononiensium (Corpus of the chronicles of Bologna), a group of texts that includes the Cronaca Varignana (to which it is closely related).” [Wikipedia] • Intense debate regarding some inconsistencies in dating, etc. •SN1006 –Observed at the monastery of Sta. Sophia in Benevento • “…a very brilliant star gleamed forth…” –Much brighter than SN1054, brighter than the quarter moon!
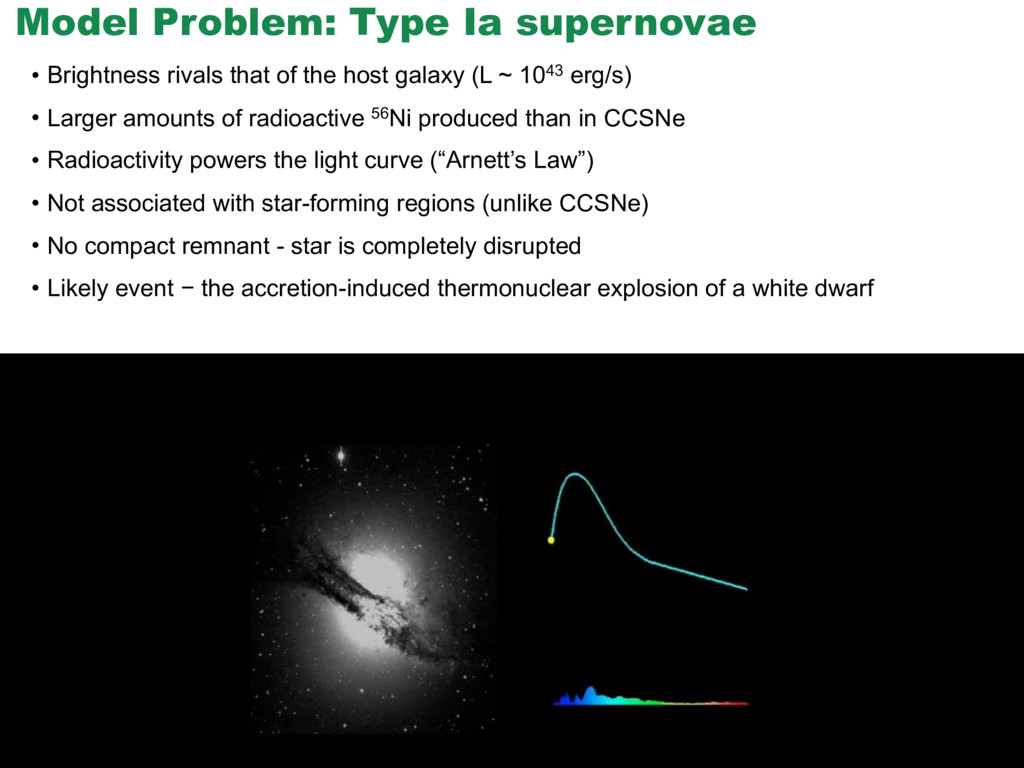
the host galaxy (L ~ 1043 erg/s) • Larger amounts of radioactive 56Ni produced than in CCSNe • Radioactivity powers the light curve (“Arnett’s Law”) • Not associated with star-forming regions (unlike CCSNe) • No compact remnant - star is completely disrupted • Likely event − the accretion-induced thermonuclear explosion of a white dwarf
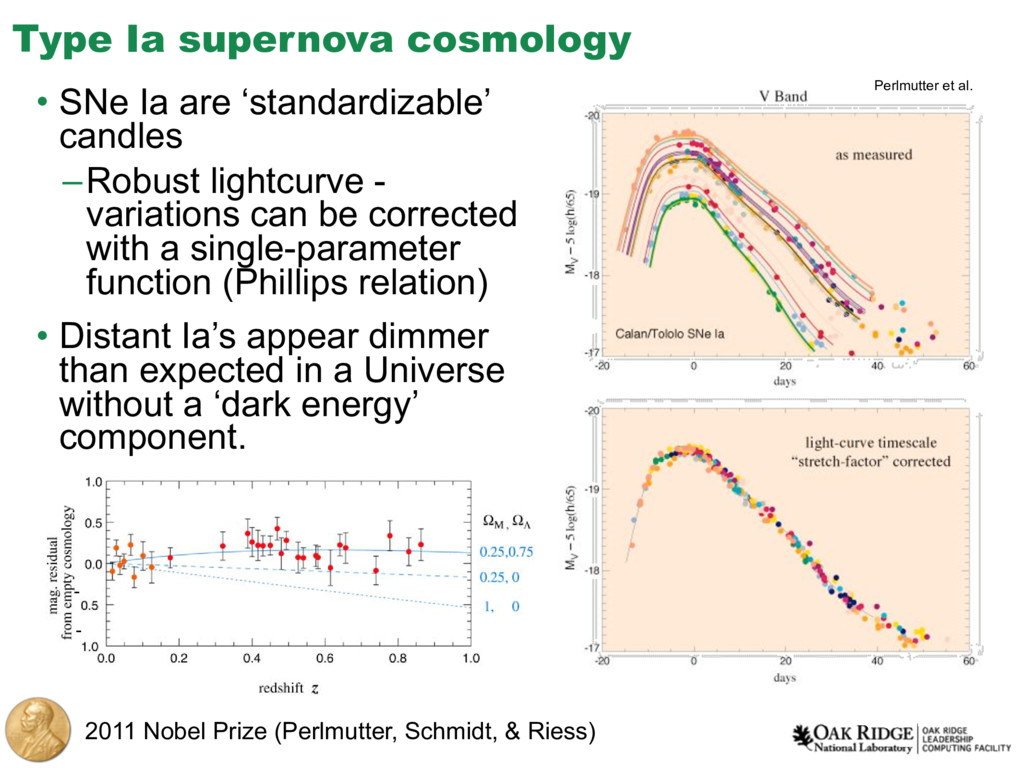
–Robust lightcurve - variations can be corrected with a single-parameter function (Phillips relation) • Distant Ia’s appear dimmer than expected in a Universe without a ‘dark energy’ component. Perlmutter et al. The ASC/Alliances Center for Astrophysical Thermonuclear Flashes The University of Chicago Discovery of Dark Energy Type Ia supernovae appear dimmer in the Universe with non-zero ! " This led to discovery that rate of expansion of universe is accelerating – and thus to discovery of dark energy - - 2011 Nobel Prize (Perlmutter, Schmidt, & Riess)
parallel, adaptive mesh refinement (AMR) code that has been used on a variety of parallel platforms. • The code has been used to simulate a variety of phenomenon, including • thermonuclear and core-collapse supernovae, • galaxy cluster formation, • classical novae, • formation of proto-planetary disks, and • high-energy-density physics. • FLASH’s multi-physics and AMR capabilities make it an ideal numerical laboratory for investigations of nucleosynthesis in supernovae. Targeted for CAAR 1.Nuclear kinetics (burn unit) threading and vectorization, including Jacobian formation and solution using GPU-enabled libraries 2.Equation of State (EOS) threading and vectorization 3.Hydrodynamics module performance
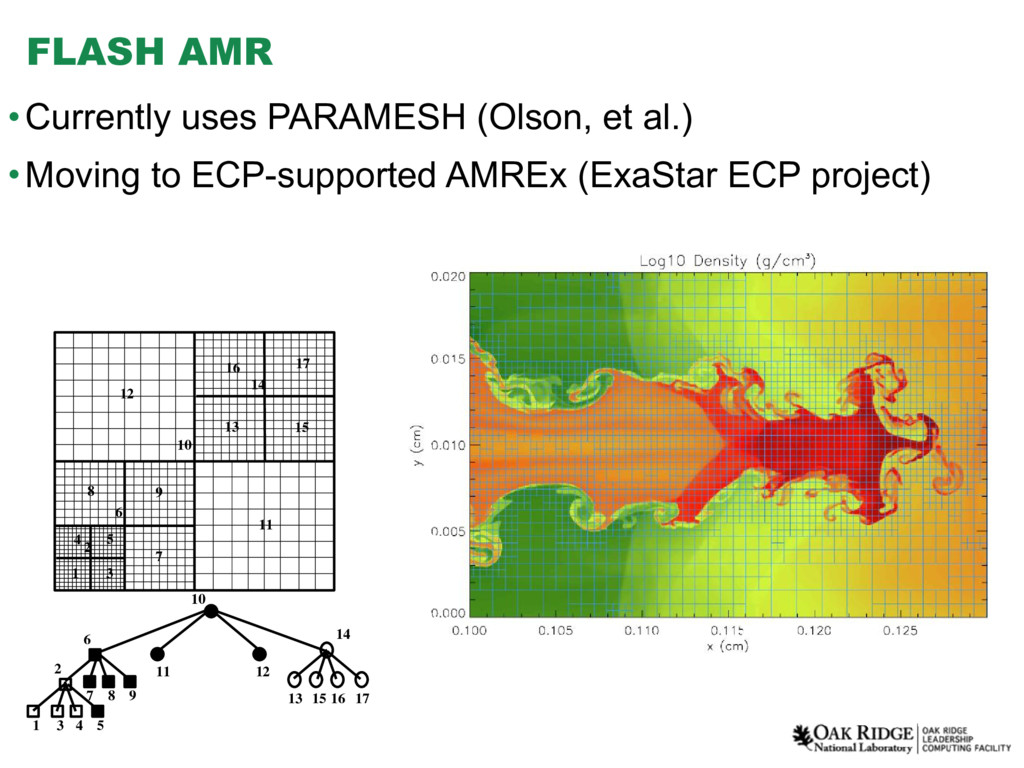
al.) •Moving to ECP-supported AMREx (ExaStar ECP project) 1 3 4 5 2 8 7 6 9 10 12 11 13 15 16 17 14 1 3 4 5 2 7 8 9 6 11 12 10 14 13 15 16 17 FLASH: ADAPTIVE MESH HYDRODYNAMICS CODE 277 lined in bold) that cover a Ðxed domain. The interior cells within the blocks are also shown. Each block in this example ions the cell size is a factor of 2 smaller in each dimension when compared to its parent block, but each block has
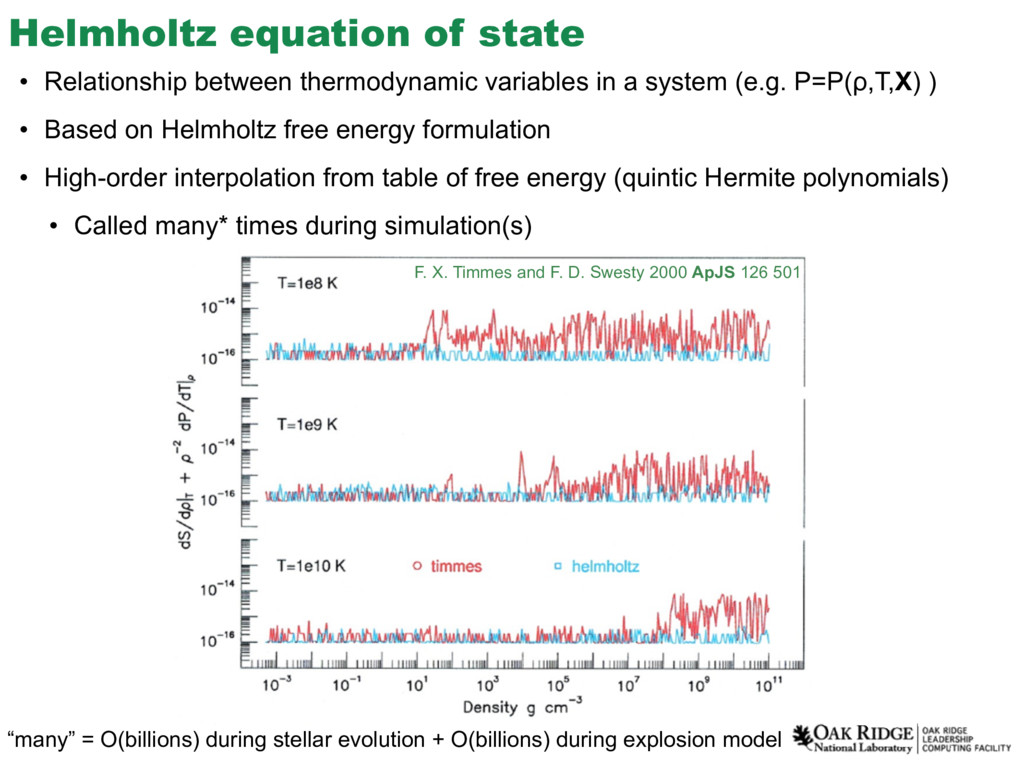
a system (e.g. P=P(ρ,T,X) ) • Based on Helmholtz free energy formulation • High-order interpolation from table of free energy (quintic Hermite polynomials) • Called many* times during simulation(s) “many” = O(billions) during stellar evolution + O(billions) during explosion model F. X. Timmes and F. D. Swesty 2000 ApJS 126 501
FLASH, we created driver program • Mimics AMR block structure and time stepping in FLASH – Loops through several time steps • Change the number of total grid zones • Fill these zones with new data • Calculate interpolation in all grid zones • How many AMR blocks should we calculate (i.e. call the EOS on) at once per MPI rank? • FLASH currently only works on vectors (i.e. rows from AMR blocks) at once. • Does this expose enough parallelism?
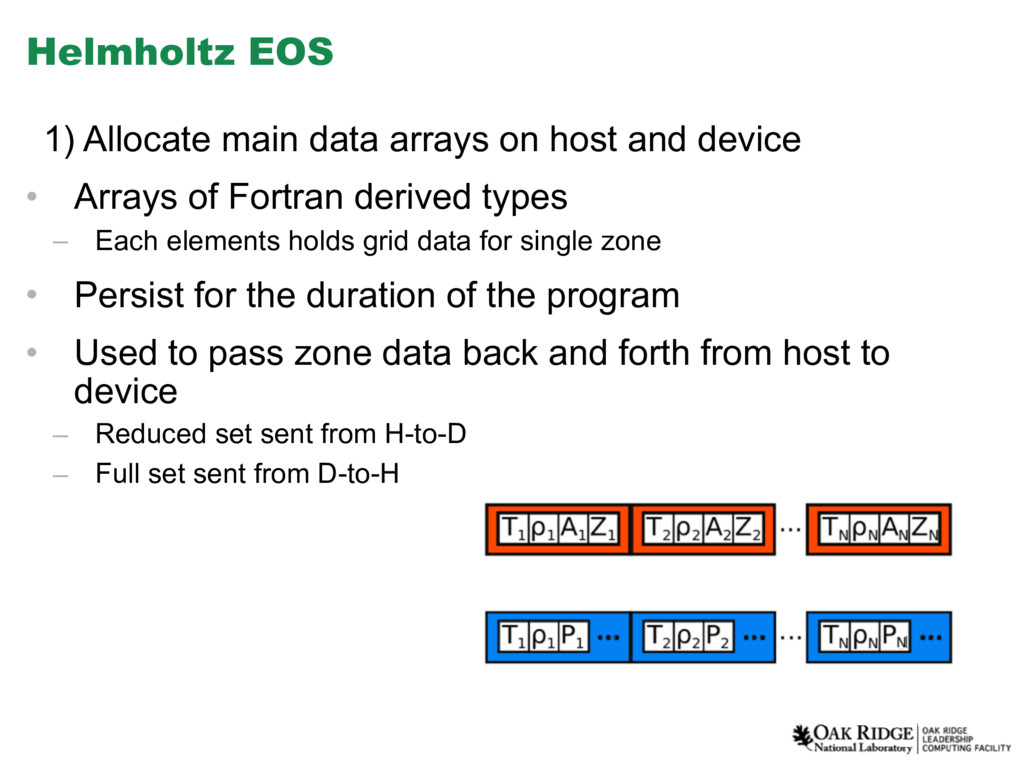
device • Arrays of Fortran derived types – Each elements holds grid data for single zone • Persist for the duration of the program • Used to pass zone data back and forth from host to device – Reduced set sent from H-to-D – Full set sent from D-to-H
of AMR blocks • ± roughly 5%, consistent with variation encountered in production simulations at high rank count • Update device with new grid data • Launch EOS kernel: calculate all interpolated quantities for all grid zones • Update host with newly calculated quantities
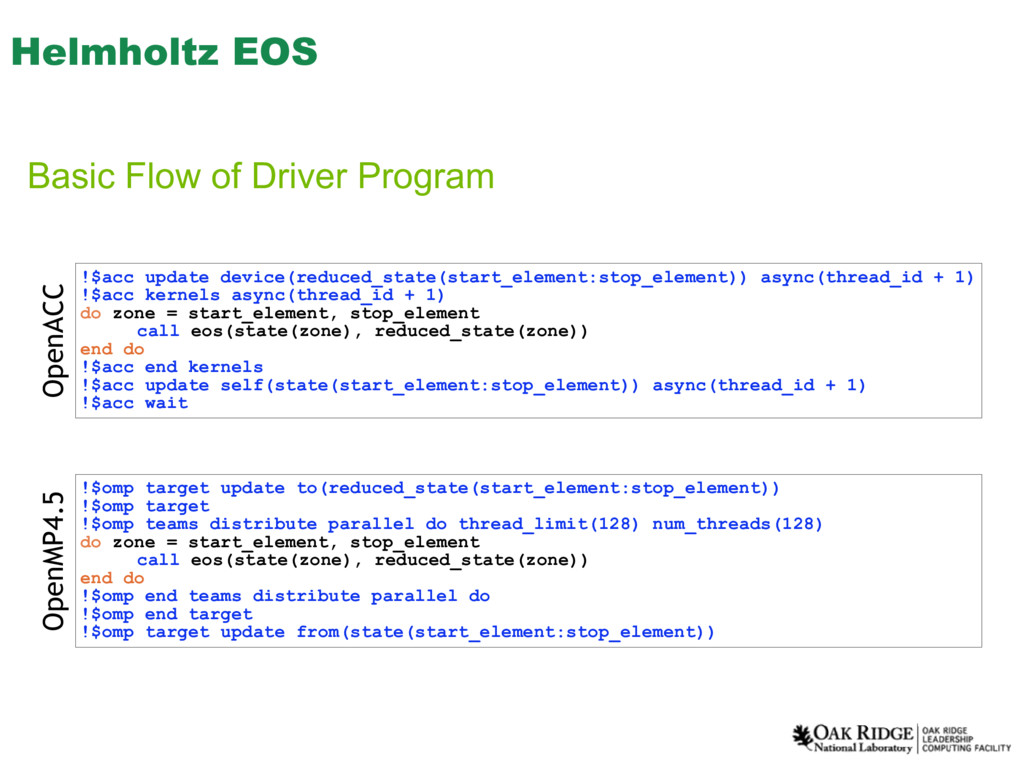
async(thread_id + 1) !$acc kernels async(thread_id + 1) do zone = start_element, stop_element call eos(state(zone), reduced_state(zone)) end do !$acc end kernels !$acc update self(state(start_element:stop_element)) async(thread_id + 1) !$acc wait !$omp target update to(reduced_state(start_element:stop_element)) !$omp target !$omp teams distribute parallel do thread_limit(128) num_threads(128) do zone = start_element, stop_element call eos(state(zone), reduced_state(zone)) end do !$omp end teams distribute parallel do !$omp end target !$omp target update from(state(start_element:stop_element)) OpenACC OpenMP4.5
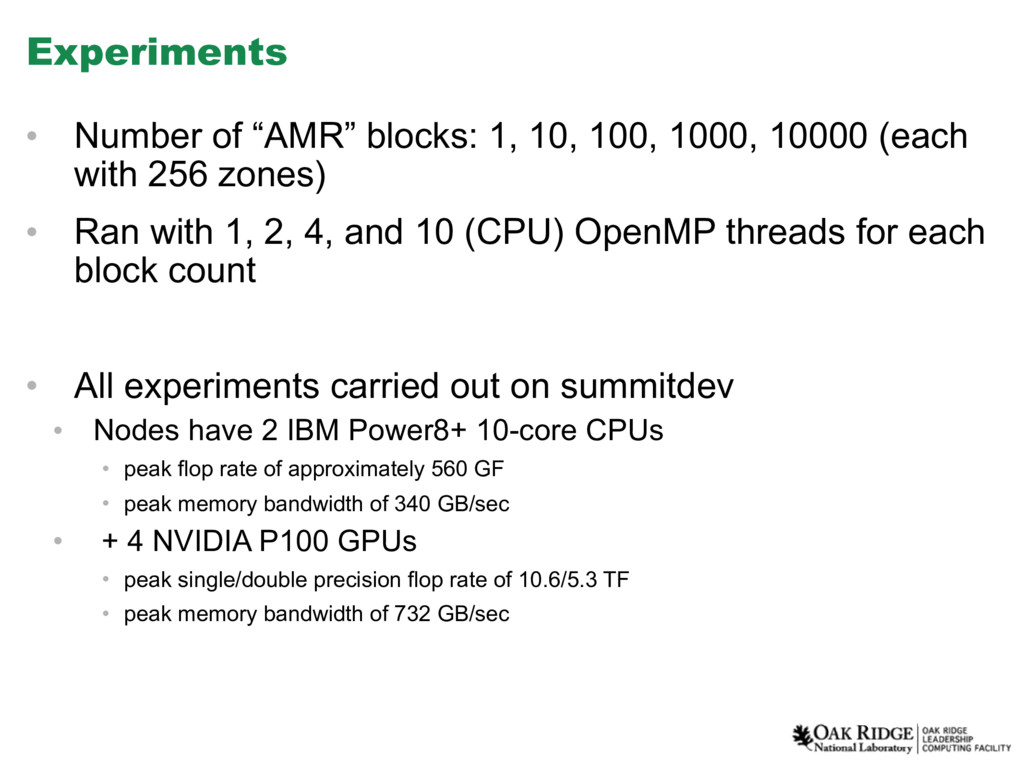
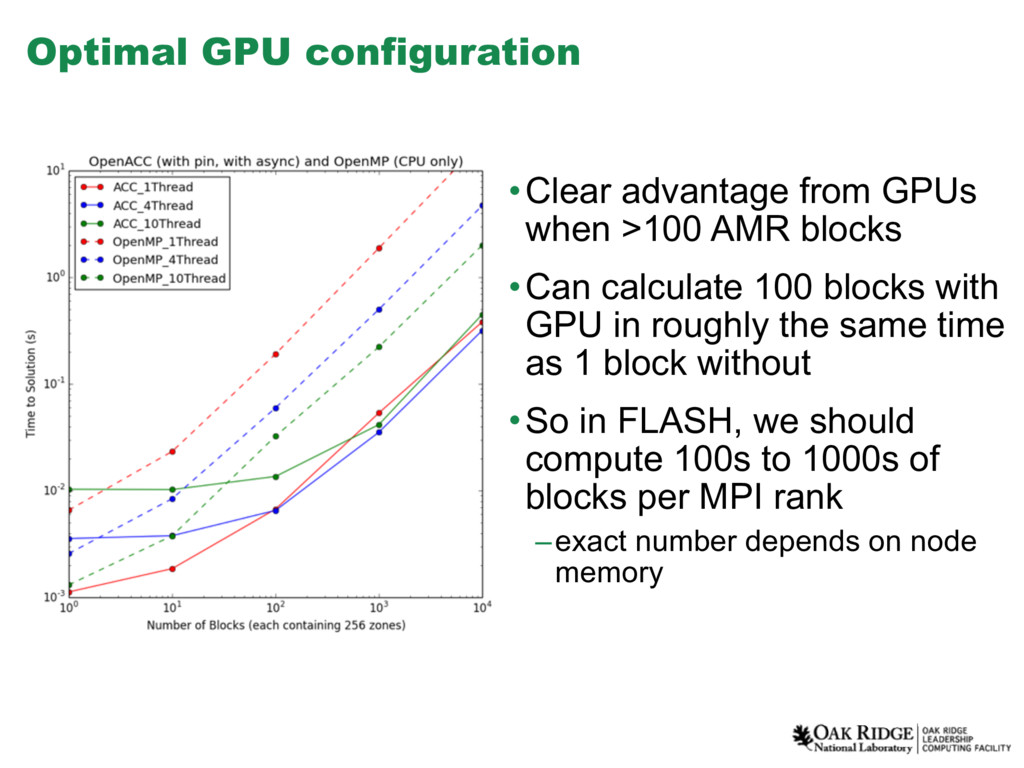
10000 (each with 256 zones) • Ran with 1, 2, 4, and 10 (CPU) OpenMP threads for each block count • All experiments carried out on summitdev • Nodes have 2 IBM Power8+ 10-core CPUs • peak flop rate of approximately 560 GF • peak memory bandwidth of 340 GB/sec • + 4 NVIDIA P100 GPUs • peak single/double precision flop rate of 10.6/5.3 TF • peak memory bandwidth of 732 GB/sec
mature API (version 16.10) • IBM’s XL Fortran implementation of OpenMP 4.5 (version 16.1) – This is still a beta version of the compiler. – Does not currently allow pinned memory or asynchronous data transfers / kernel execution
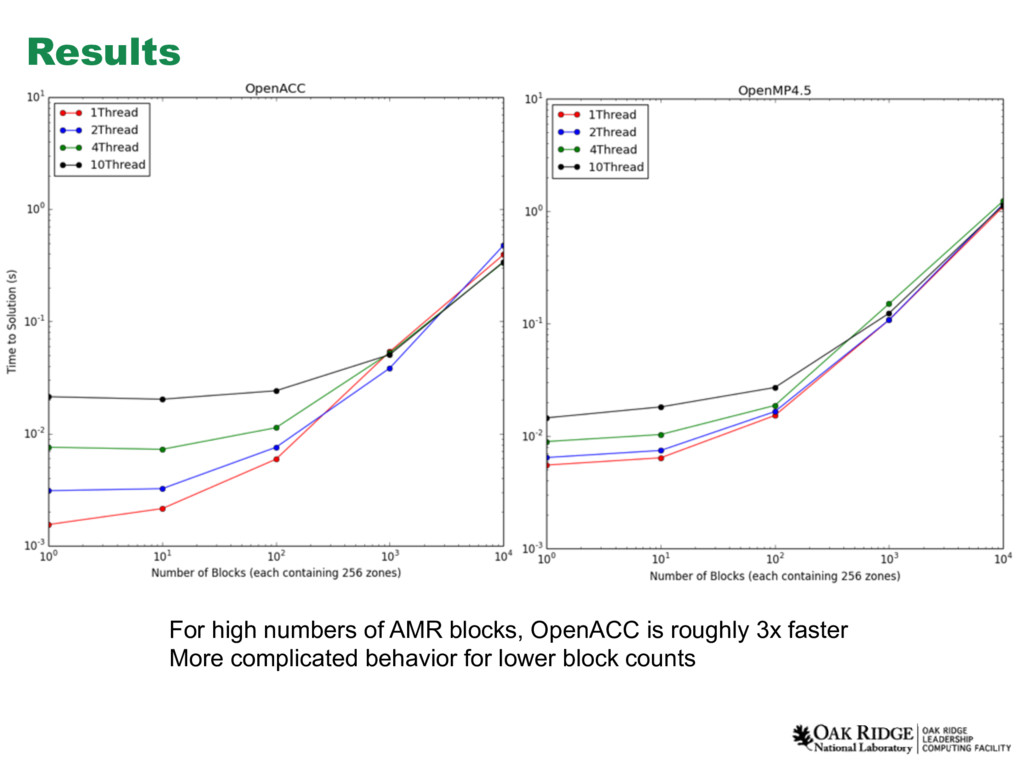
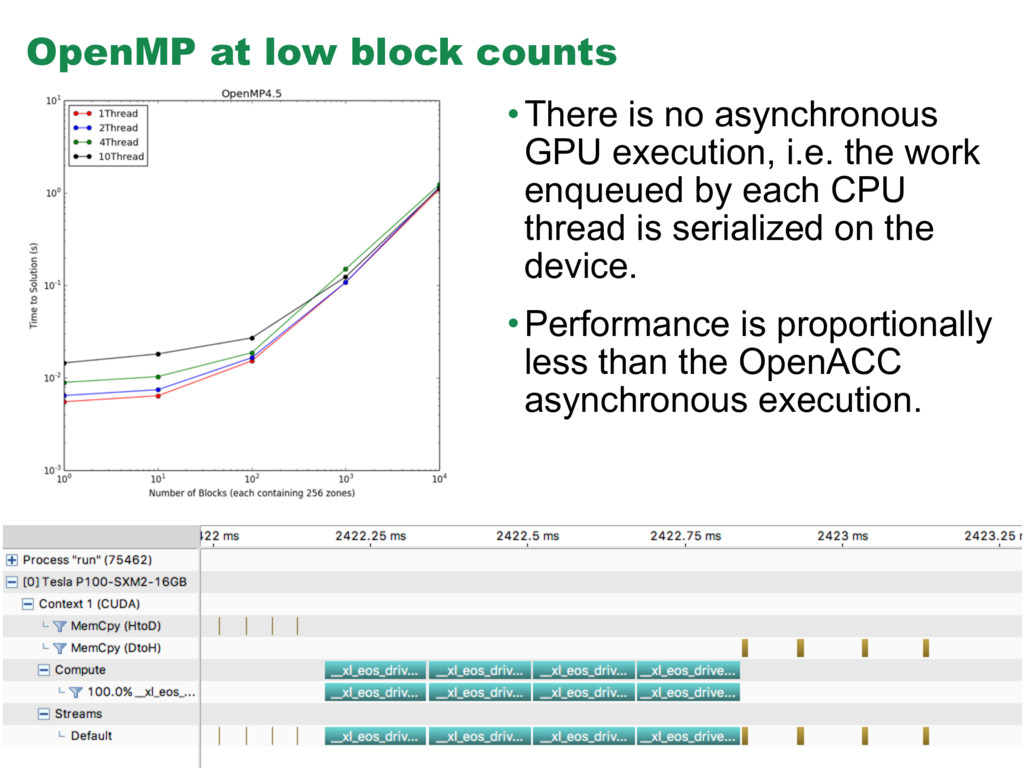
execution, i.e. the work enqueued by each CPU thread is serialized on the device. •Performance is proportionally less than the OpenACC asynchronous execution.
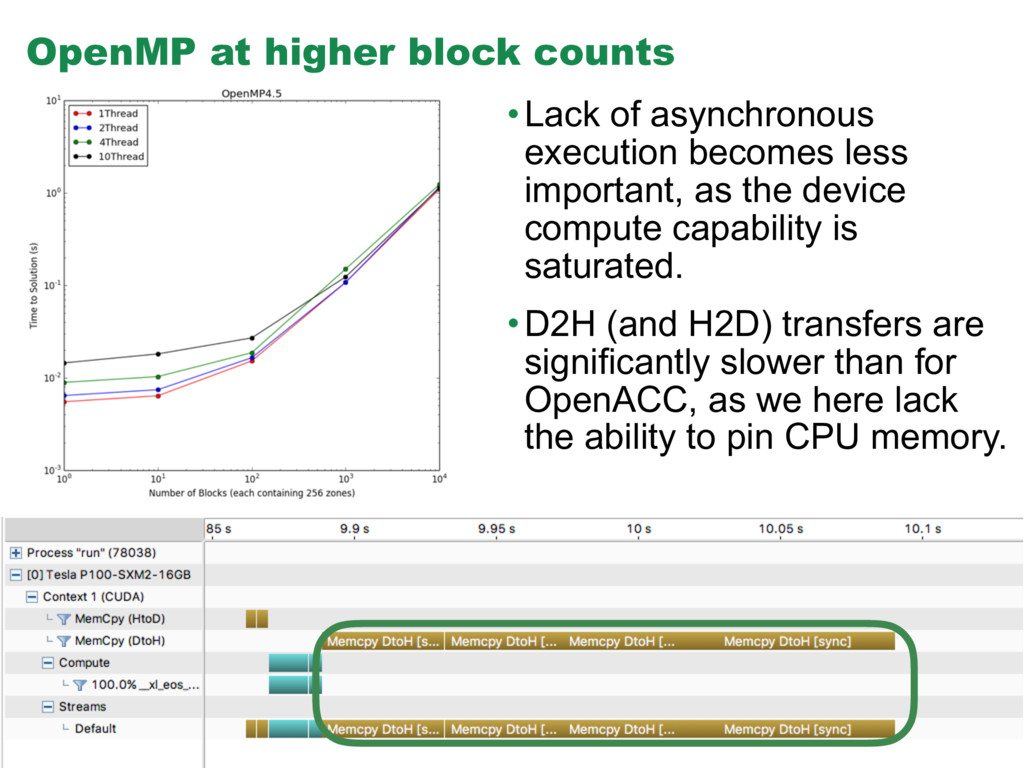
less important, as the device compute capability is saturated. •D2H (and H2D) transfers are significantly slower than for OpenACC, as we here lack the ability to pin CPU memory.
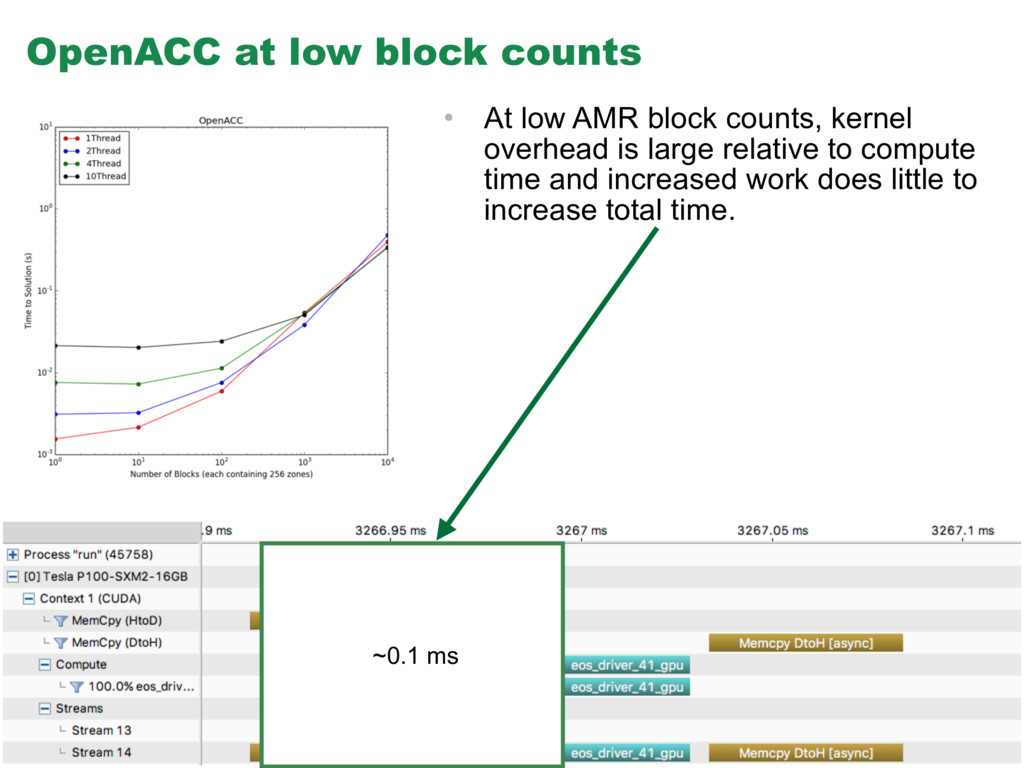
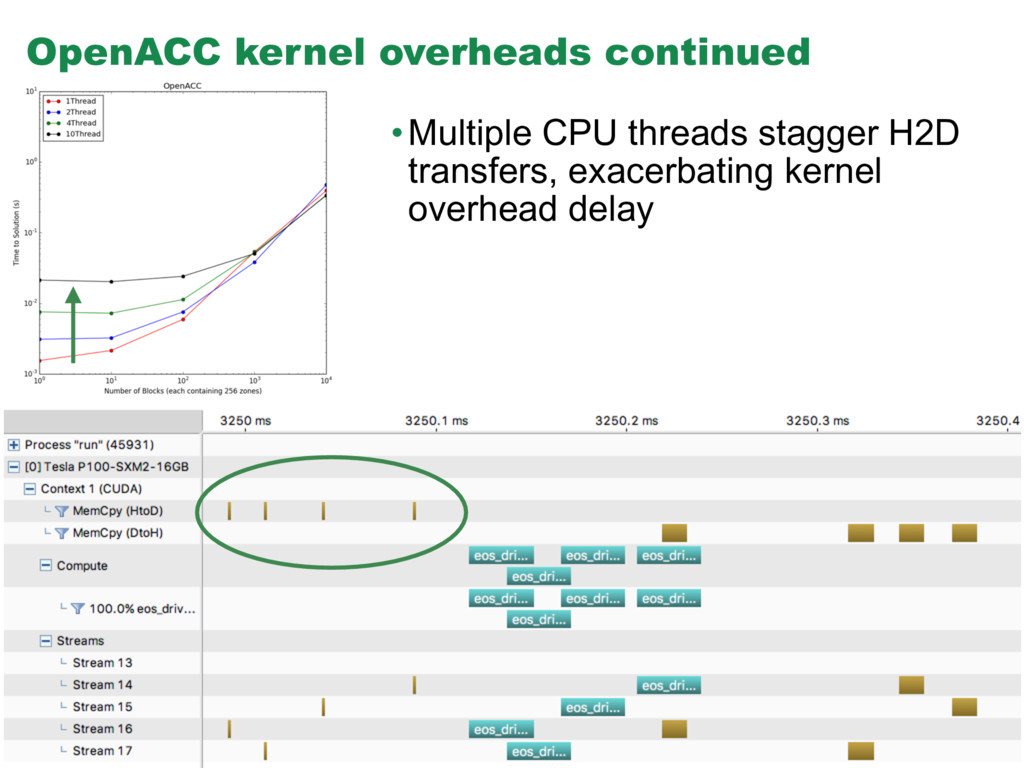
blocks •Can calculate 100 blocks with GPU in roughly the same time as 1 block without •So in FLASH, we should compute 100s to 1000s of blocks per MPI rank –exact number depends on node memory
portability, so despite the current lower performance, we plan to use the OpenMP 4.5 implementation in FLASH production. • Primary factors affecting current OpenMP performance are the serialization of kernels on the device and high data transfer times associated with having to use pageable memory when using OpenMP 4.5. These are technical problems that are certainly surmountable. • In general, we find that the best balance between CPU threads and block number occurs at and above 2-4 CPU threads and roughly 1,000 blocks. We can retire all 1,000 of these EOS evaluations in a time less than 10x the fastest 100-block calculation for both OpenACC and OpenMP. • This mode is congruent with our planned production use of FLASH on the OLCF Summit machine, where we will place 3 MPI ranks on each CPU socket, each bound to one of the three available, closely coupled GPUs.


 bronsonmesser
 konakalab
 naospon
 sshimizu2006
 ykiyota
 trycycle
 institudelelevage
 tagtag
 bonotake
 kiyoshi
 tomoaki0705
 helenjbeal
 tmiket
 jct
 jonoalderson
 jlugia
 deanohume
 orderedlist
 aarron
 tamaranovitovic
 tammyeverts
 retrage