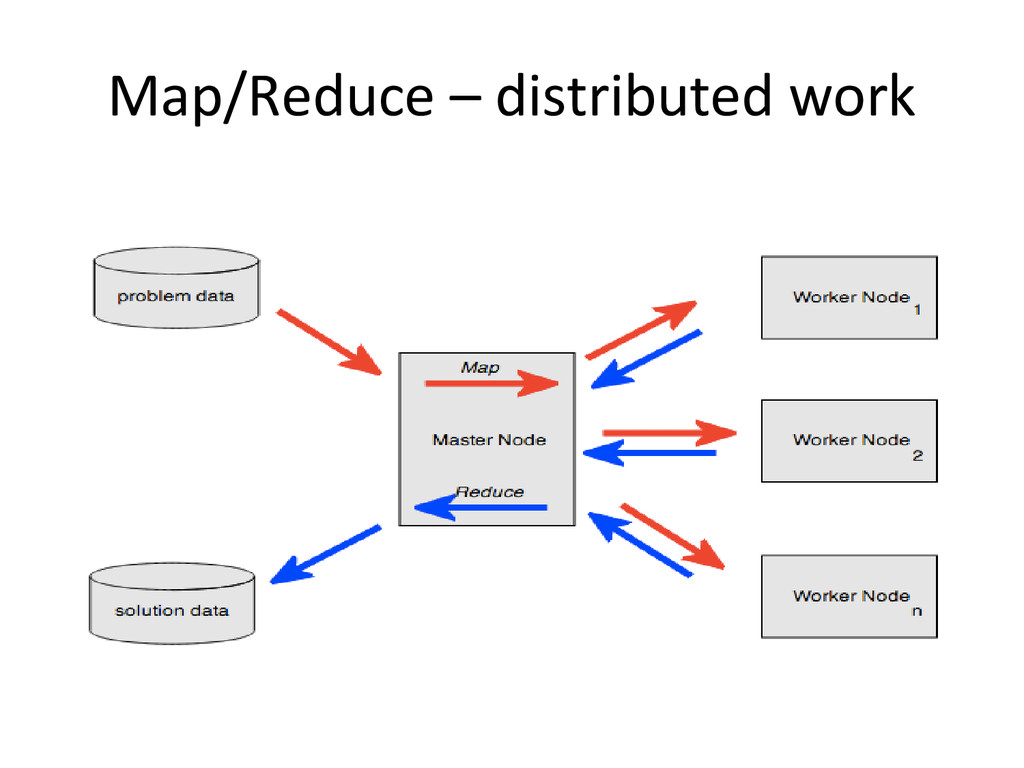
All these large data sets are so big its difficult to manage with traditional tools. Distributing computing is an approach to solve that problem! First the data needs to be mapped, then it can be analyzed or reduced.
large data sets • All of them are so large its difficult to manage with traditional tools • Distributed computing is an approach to solve that problem • First the data needs to be Mapped • Then it can be analyzed – or Reduced
experiments to find the Higgs Boson • 200 Petabytes per year • 200,000 CPU days / day on hundreds of partner grids and clouds • Montecarlo simulations (CPU intensive)
which they clone • A set of coordinator servers, which scales the worker nodes up and down via provisioning API (clone, puppet config) • Coordinator servers manages workload on each worker node doing Montecarlo simulations • Federated cloud brokers such as Enstratus and Slipstream • Self healing architecture – uptime of a worker node is not critical; just spin up a new worker node instance
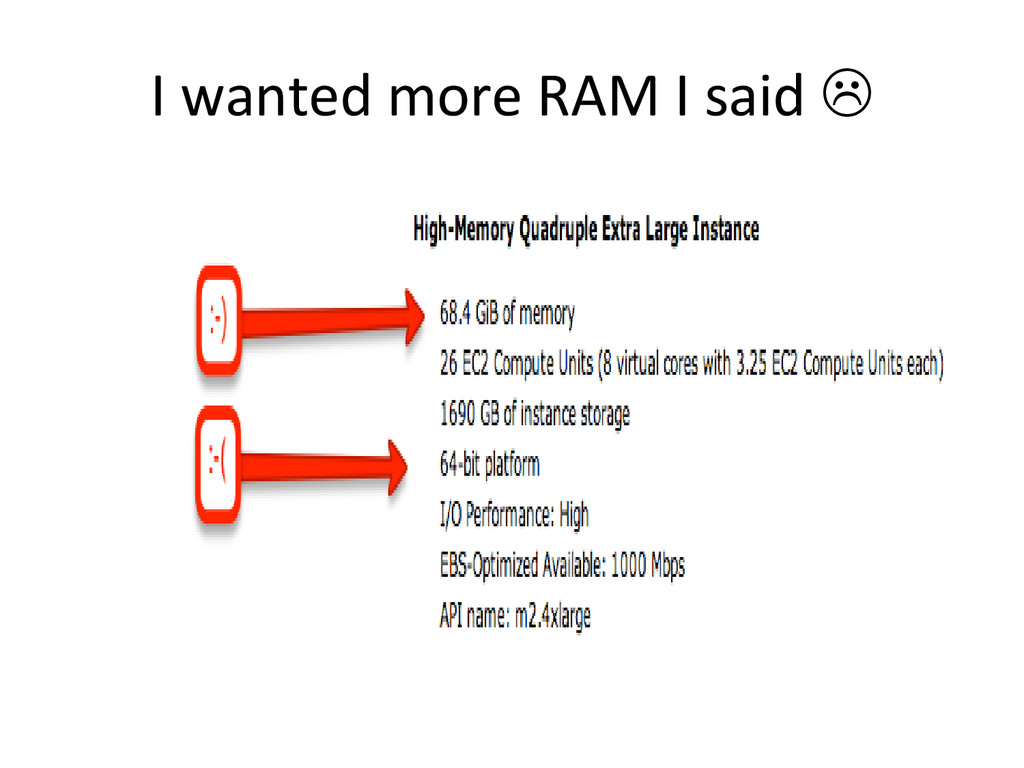
programs • Plain vanilla Hadoop Map/Reduce: • Chef and Puppet to deploy and config worker nodes • Lots of RAM, little CPU • Self healing architecture – uptime of a worker node is not critical; just spin up a new worker node instance
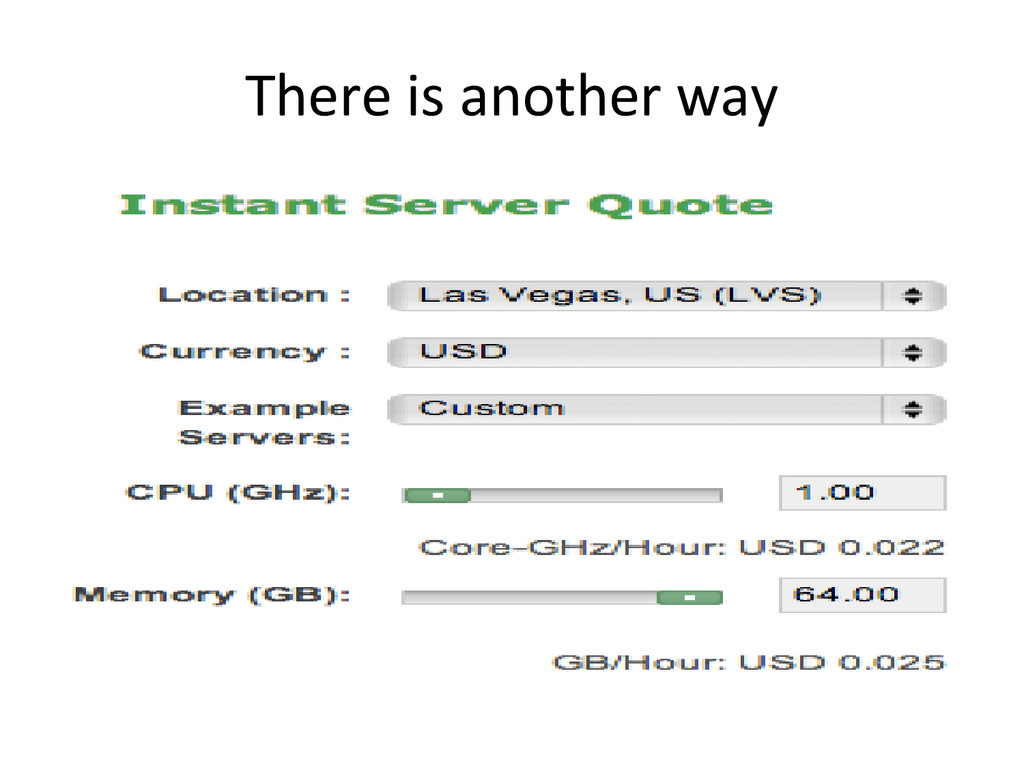
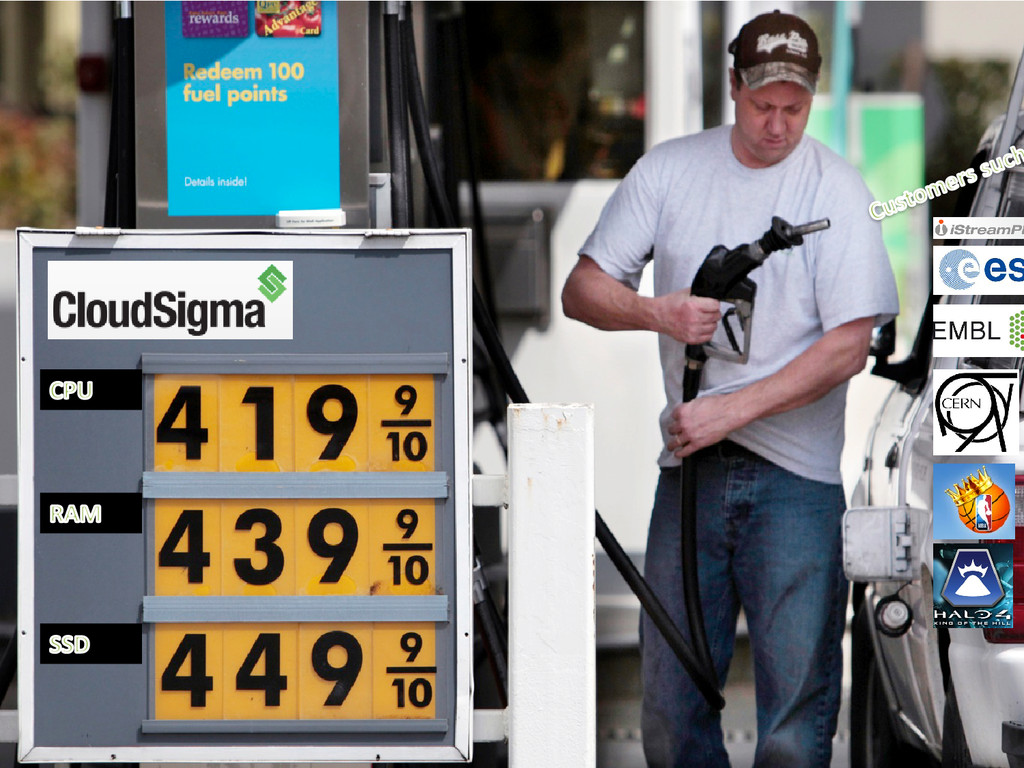
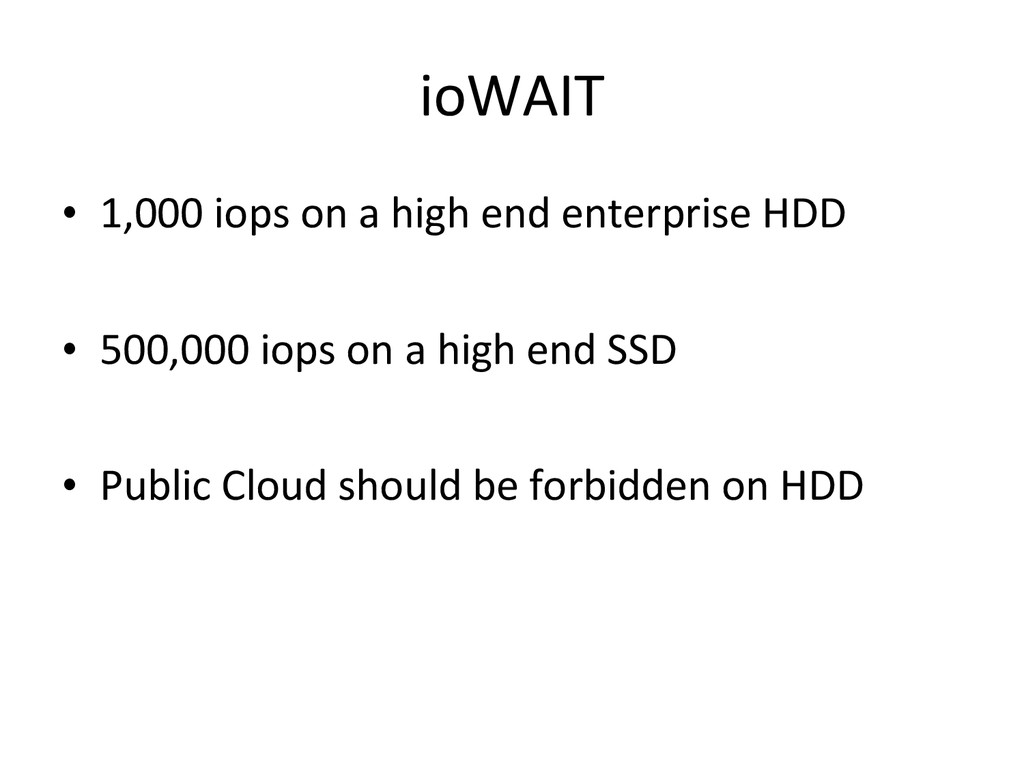
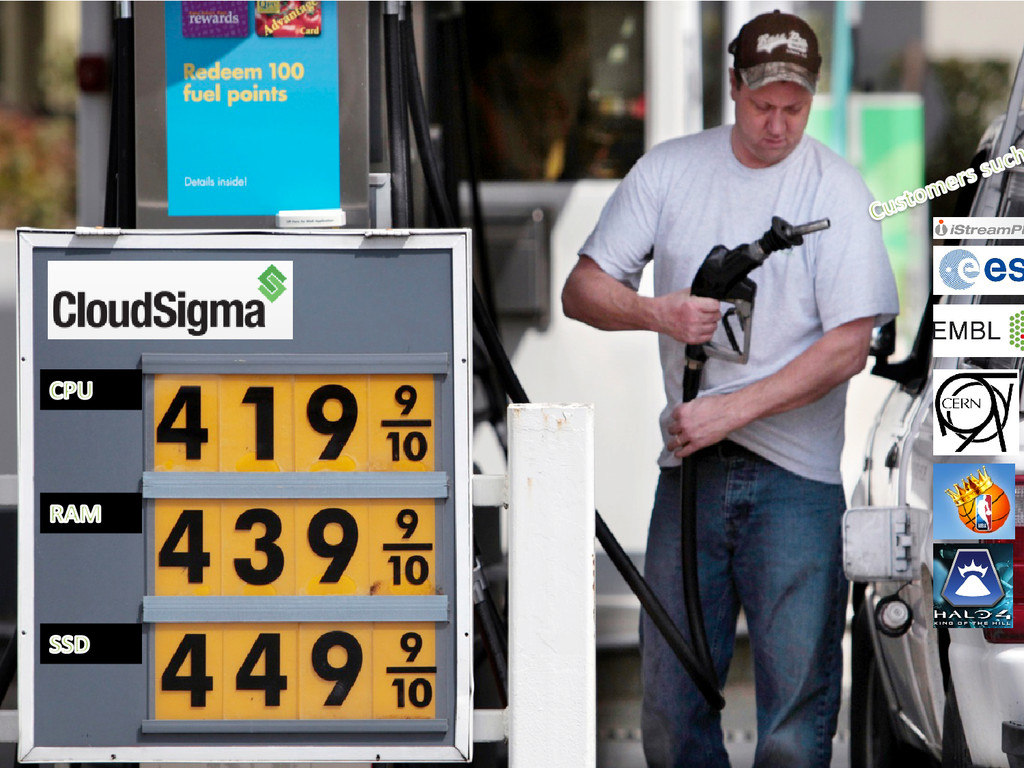
cycles • New equipment: what’s your life cycle? • SSD as compute storage • Allows cross connects from your equipment in the DC • CloudSigma, ElasticHost, ProfitBricks to mention a few


 cloudsigma
 makocchi
 riyaamemiya
 maimyyym
 syuchimu
 sh_fk2
 pfn
 tetsuya28
 kairim0
 camiha
 carta_engineering
 yuuuuuuu168
 takahashim
 marktimemedia
 sonatard
 codingconduct
 tmiket
 techseoconnect
 jonoalderson
 jacobian
 smashingmag
 lemiorhan
 leimatthew05
 palkan
 holman