Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
mysql tunning
Search
kenshin
June 06, 2013
Programming
150
4
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
mysql tunning
kenshin
June 06, 2013
Other Decks in Programming
See All in Programming
Are APIs Still Relevant in the AI Era?
soyuka
0
390
Webの地図
yosuke_furukawa
PRO
6
5k
AGENTS.md Is Not Enough: Build Skills, Don't Download Them
lx_t
0
130
IBM Bob Dojo #1 仕様駆動開発入門
oniak3ibm
PRO
0
320
wkhtmltopdfの次どうするか問題2026
willnet
2
1.8k
巨大モノリシックアプリ モダン化大作戦
ktcryomm
1
1.2k
Java 27新機能 / Java 27 new features
kishida
2
190
App Storeの外へ──日本のiOSサイドローディング入門 for iOSDC Japan 2026
yuukiw00w
0
280
すこし踏み込む CancellationToken
htkym
2
1.5k
iOS 27でニュースアプリはどう変わる!? 〜日経電子版の新機能対応と、開発事例から〜
lynnswap
7
13k
半永久的に提供し続けられるプライベートクラウドを目指して ― 利用者の認知負荷を抑えるAPI抽象化とハードウェア世代交代の基盤設計
tomokon
0
380
難しいけど、読めた。- OSSの入口に立った話。
sts11142
0
130
Featured
See All Featured
Save Time (by Creating Custom Rails Generators)
garrettdimon
PRO
33
5k
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
First, design no harm
axbom
PRO
2
1.3k
Visualization
eitanlees
153
17k
The Art of Delivering Value - GDevCon NA Keynote
reverentgeek
16
2.2k
Building Better People: How to give real-time feedback that sticks.
wjessup
370
20k
Skip the Path - Find Your Career Trail
mkilby
1
240
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
420
Stewardship and Sustainability of Urban and Community Forests
pwiseman
0
540
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
We Are The Robots
honzajavorek
0
380
The AI Search Optimization Roadmap by Aleyda Solis
aleyda
1
6.3k
Transcript
© 2011 绿盟科技 www.nsfocus.com nsfocus.com www.nsfocus.com
nsfocus.com MYSQL性能优化
• 寻找问题 要优化数据库,先得知道数据库存在哪些问题,对症下药
问题包括下面三类,分而治之 • 硬件
• 软件 • MySQL
硬 件
与数据库性能相关的硬件资源 • CPU • Memory • Disk • Network
必知必会的几个监控工具 • vmstat • iostat • netstat • dstat •
top • ifconfig
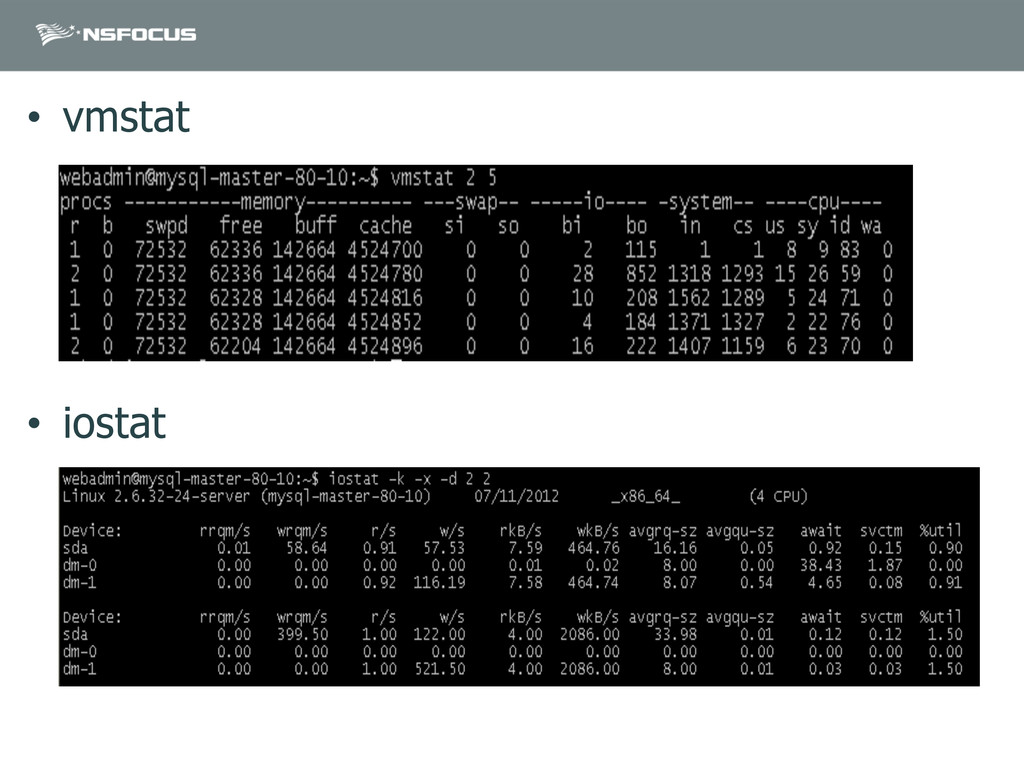
• vmstat • iostat
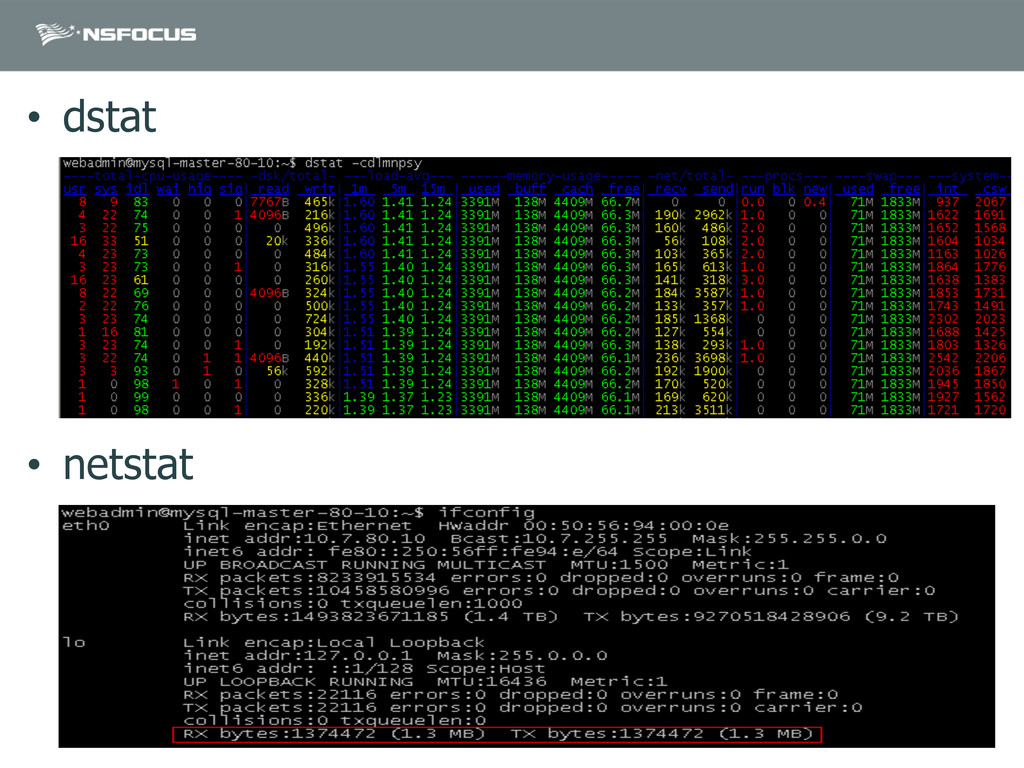
• dstat • netstat
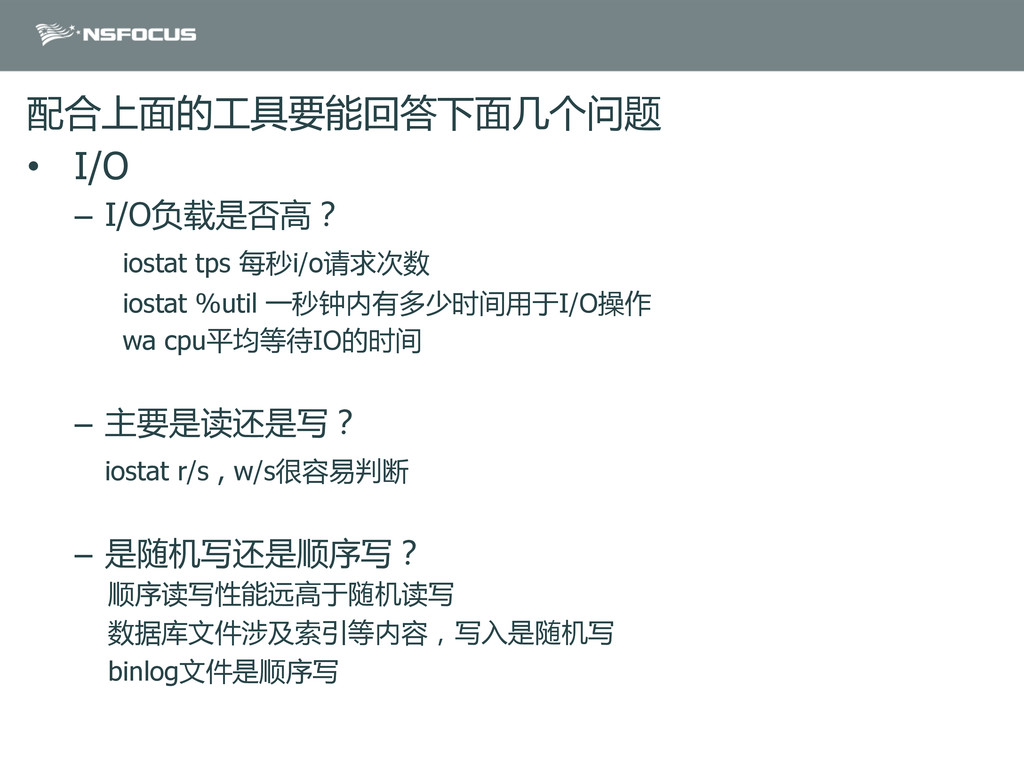
配合上面的工具要能回答下面几个问题 • I/O – I/O负载是否高? iostat tps 每秒i/o请求次数 iostat %util
一秒钟内有多少时间用于I/O操作 wa cpu平均等待IO的时间 – 主要是读还是写? iostat r/s , w/s很容易判断 – 是随机写还是顺序写? 顺序读写性能远高于随机读写 数据库文件涉及索引等内容,写入是随机写 binlog文件是顺序写
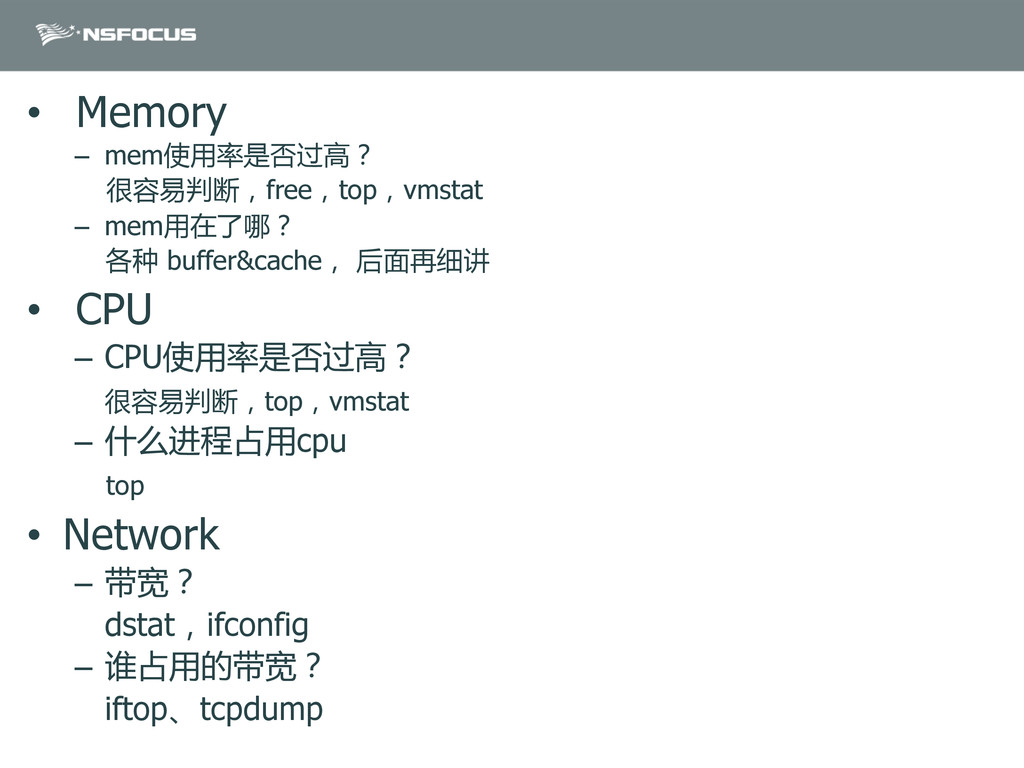
• Memory – mem使用率是否过高? 很容易判断,free,top,vmstat – mem用在了哪?
各种 buffer&cache, 后面再细讲 • CPU – CPU使用率是否过高? 很容易判断,top,vmstat – 什么进程占用cpu top • Network – 带宽? dstat,ifconfig – 谁占用的带宽? iftop、tcpdump
软 件
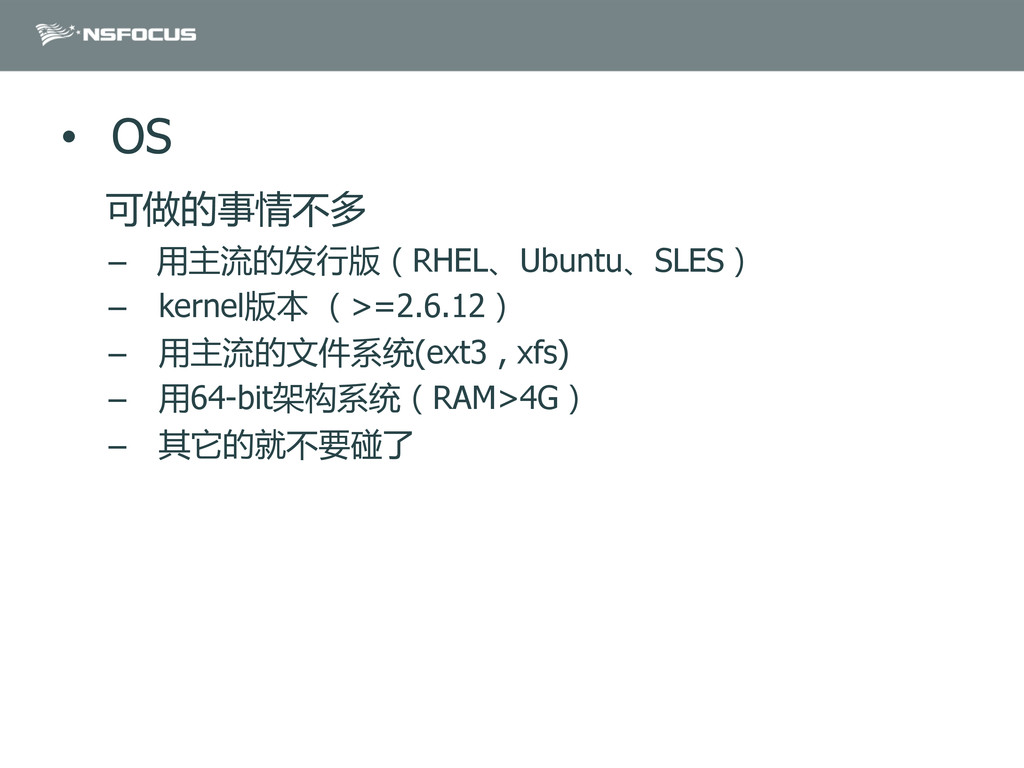
• OS 可做的事情不多 – 用主流的发行版(RHEL、Ubuntu、SLES) – kernel版本 (>=2.6.12) – 用主流的文件系统(ext3
, xfs) – 用64-bit架构系统(RAM>4G) – 其它的就不要碰了
MySQL
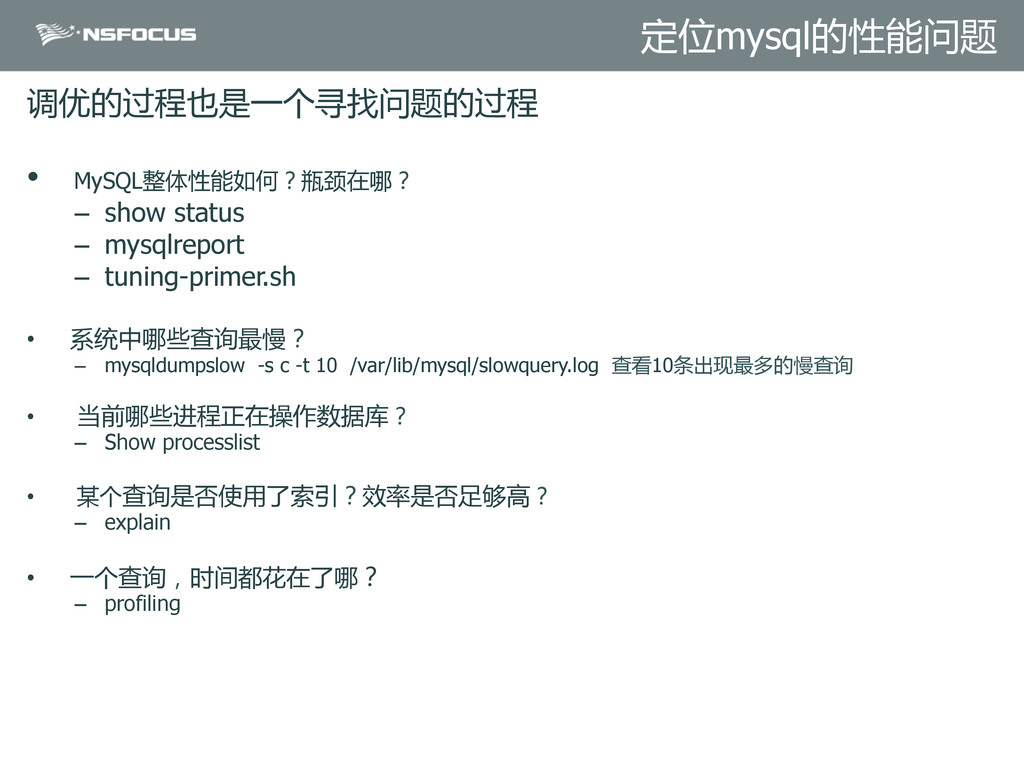
调优的过程也是一个寻找问题的过程 • MySQL整体性能如何?瓶颈在哪? – show status – mysqlreport – tuning-primer.sh
• 系统中哪些查询最慢? – mysqldumpslow -s c -t 10 /var/lib/mysql/slowquery.log 查看10条出现最多的慢查询 • 当前哪些进程正在操作数据库? – Show processlist • 某个查询是否使用了索引?效率是否足够高? – explain • 一个查询,时间都花在了哪? – profiling 定位mysql的性能问题
寻找问题只是开始,更重要的还是解决问题。 下面才是我们的重点,涉及MySQL性能优化的诸多细节。
• 服务器调优 • Shcema设计 • 查询优化 • 存储引擎优化 • 架构设计
目录
• 服务器调优
• Tips • 所有MySQL服务器调优的参数,都在my.cnf中设置。 • 所有参数的值都可以通过show variables查看 。 •
所有参数设置是否合理,都可以通过show status来判断。 也可以通过mysqlreport这样的工具帮助分析。 • 与性能相关的参数主要是log,以及各种buffer & cache
log
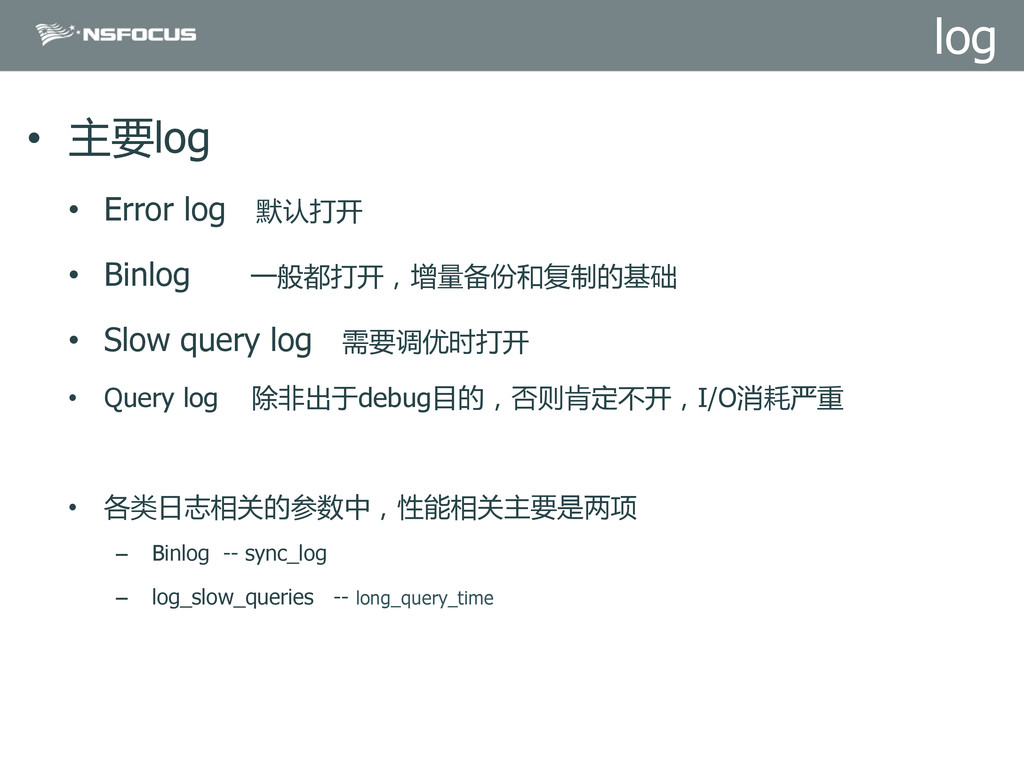
• 主要log • Error log 默认打开 • Binlog 一般都打开,增量备份和复制的基础 •
Slow query log 需要调优时打开 • Query log 除非出于debug目的,否则肯定不开,I/O消耗严重 • 各类日志相关的参数中,性能相关主要是两项 – Binlog -- sync_log – log_slow_queries -- long_query_time log
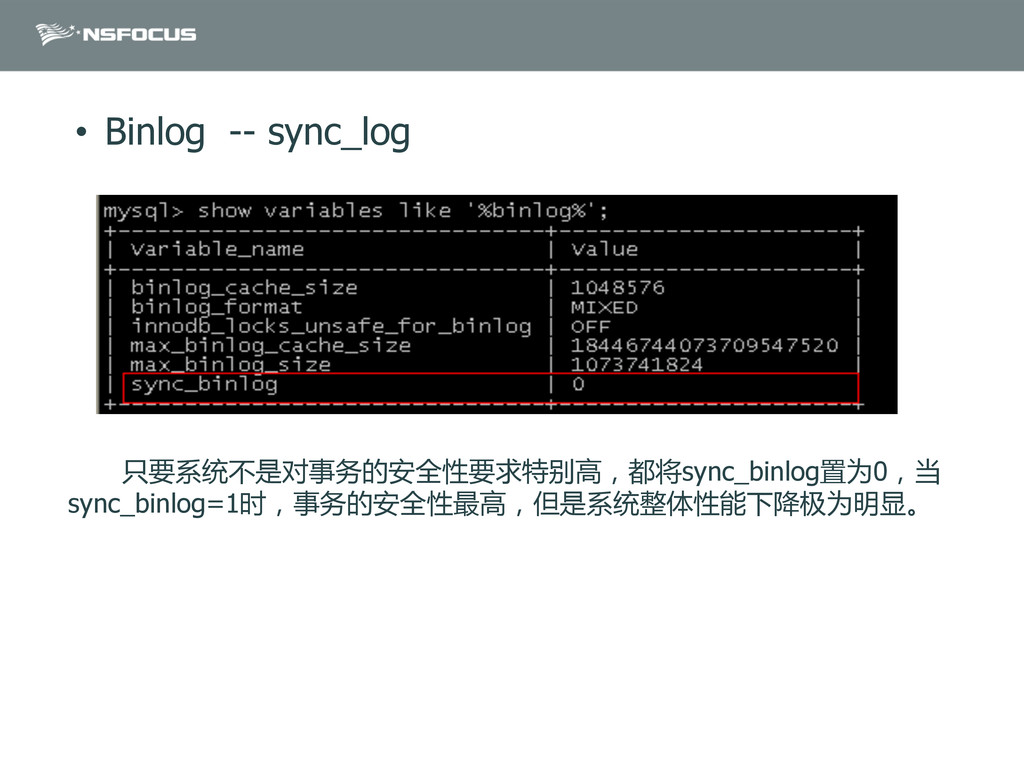
• Binlog -- sync_log 只要系统不是对事务的安全性要求特别高,都将sync_binlog置为0,当 sync_binlog=1时,事务的安全性最高,但是系统整体性能下降极为明显。
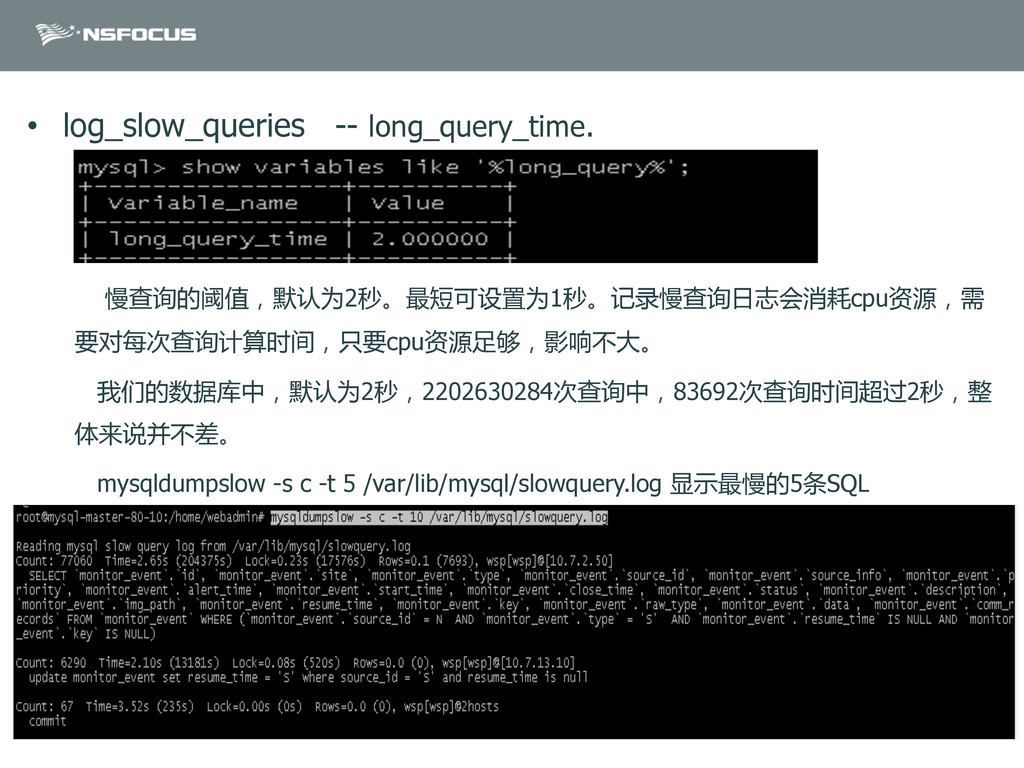
• log_slow_queries -- long_query_time. 慢查询的阈值,默认为2秒。最短可设置为1秒。记录慢查询日志会消耗cpu资源,需 要对每次查询计算时间,只要cpu资源足够,影响不大。 我们的数据库中,默认为2秒,2202630284次查询中,83692次查询时间超过2秒,整 体来说并不差。 mysqldumpslow -s
c -t 5 /var/lib/mysql/slowquery.log 显示最慢的5条SQL
Buffer & cache
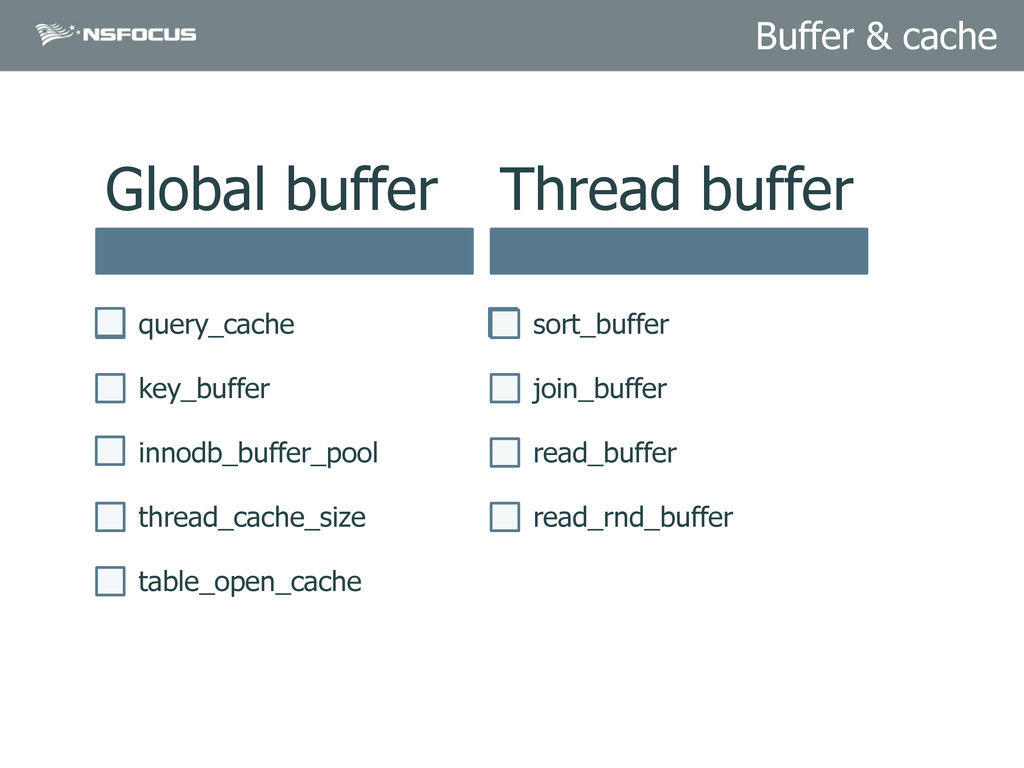
Buffer & cache Global buffer query_cache key_buffer
innodb_buffer_pool thread_cache_size table_open_cache Thread buffer sort_buffer join_buffer read_buffer read_rnd_buffer
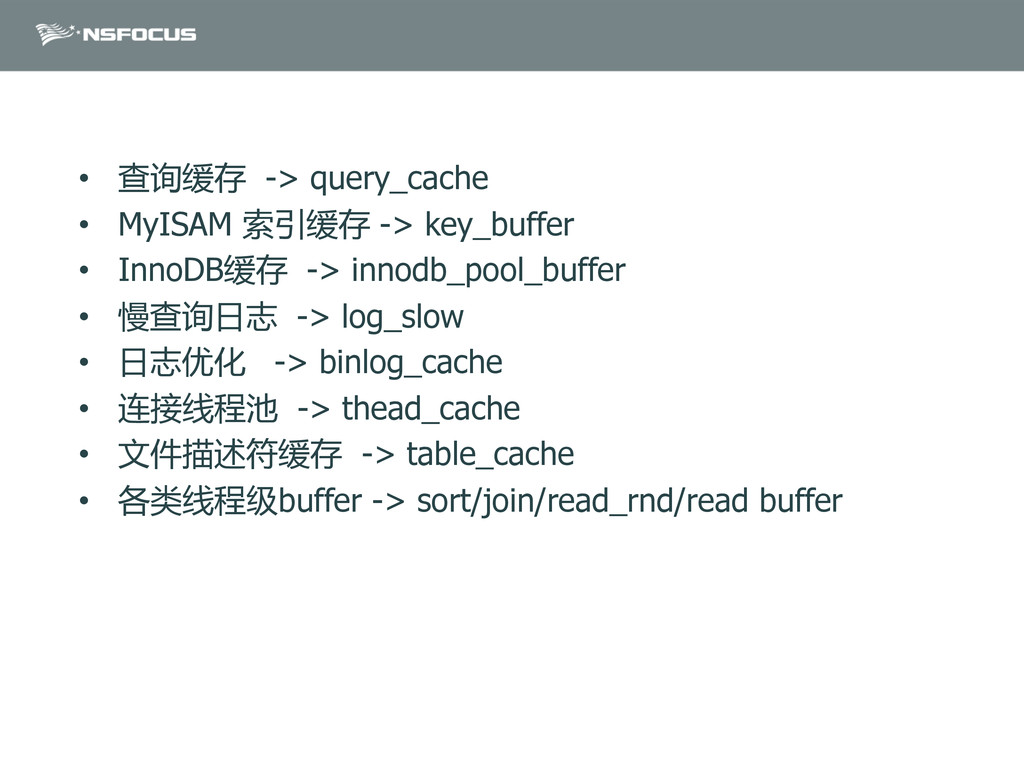
• 查询缓存 -> query_cache • MyISAM 索引缓存 -> key_buffer
• InnoDB缓存 -> innodb_pool_buffer • 慢查询日志 -> log_slow • 日志优化 -> binlog_cache • 连接线程池 -> thead_cache • 文件描述符缓存 -> table_cache • 各类线程级buffer -> sort/join/read_rnd/read buffer
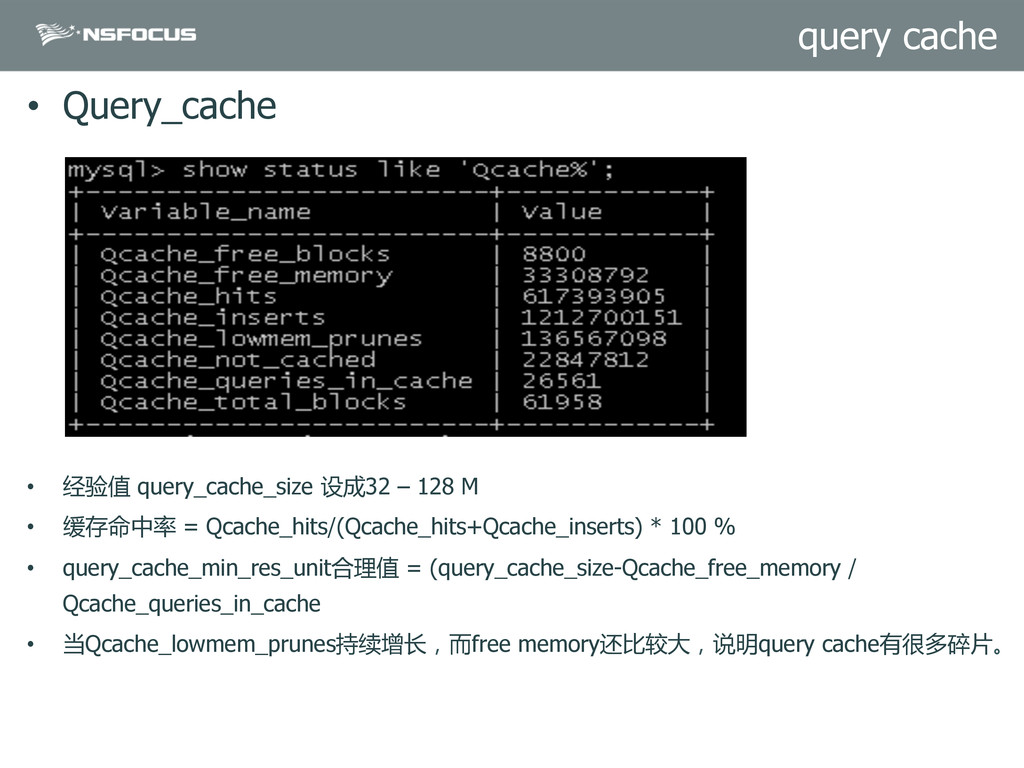
• Query_cache • 经验值 query_cache_size 设成32 – 128 M
• 缓存命中率 = Qcache_hits/(Qcache_hits+Qcache_inserts) * 100 % • query_cache_min_res_unit合理值 = (query_cache_size-Qcache_free_memory / Qcache_queries_in_cache • 当Qcache_lowmem_prunes持续增长,而free memory还比较大,说明query cache有很多碎片。 query cache
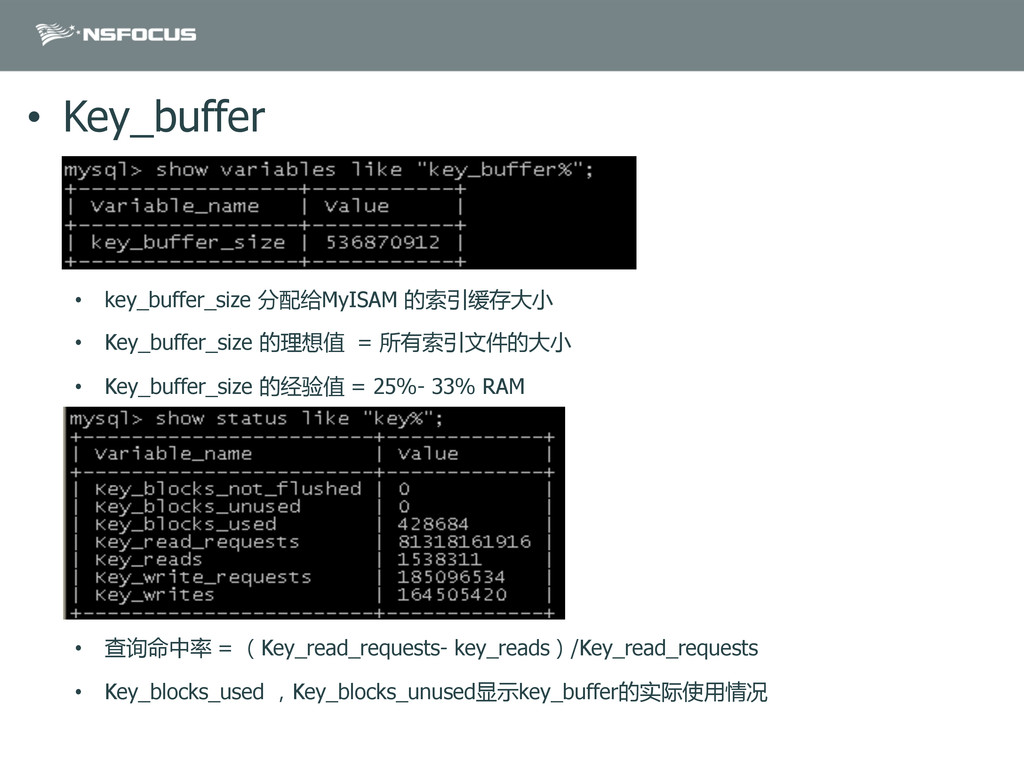
• Key_buffer • key_buffer_size 分配给MyISAM 的索引缓存大小 • Key_buffer_size 的理想值
= 所有索引文件的大小 • Key_buffer_size 的经验值 = 25%- 33% RAM • 查询命中率 = (Key_read_requests- key_reads)/Key_read_requests • Key_blocks_used ,Key_blocks_unused显示key_buffer的实际使用情况
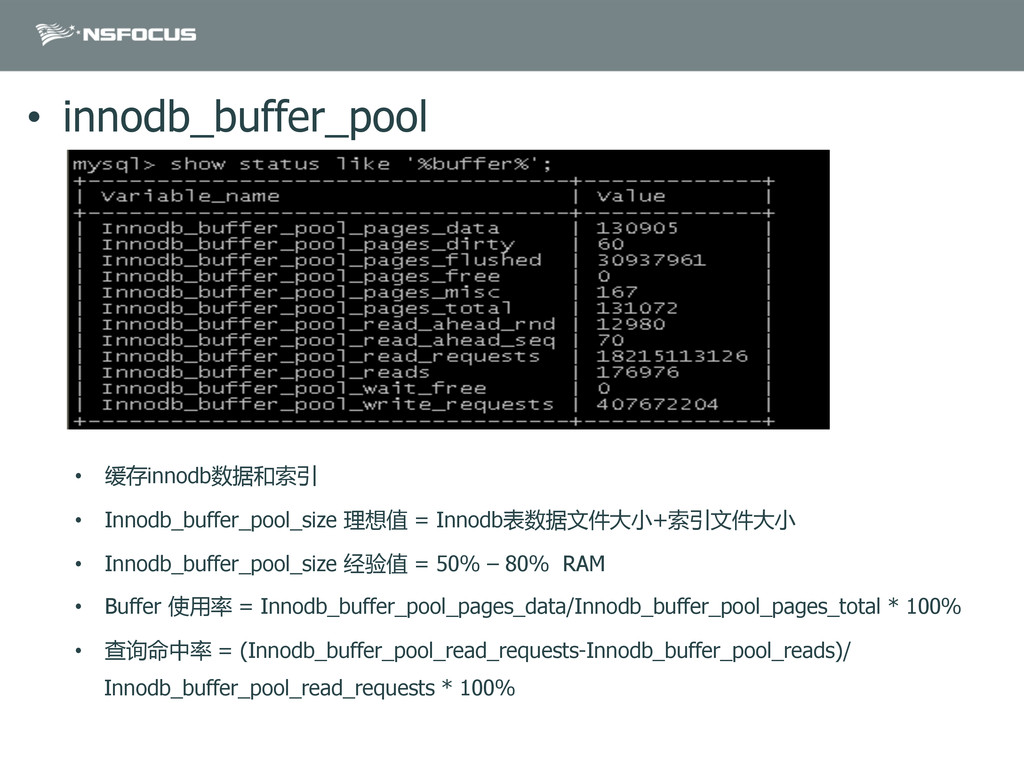
• innodb_buffer_pool • 缓存innodb数据和索引 • Innodb_buffer_pool_size 理想值 = Innodb表数据文件大小+索引文件大小 •
Innodb_buffer_pool_size 经验值 = 50% – 80% RAM • Buffer 使用率 = Innodb_buffer_pool_pages_data/Innodb_buffer_pool_pages_total * 100% • 查询命中率 = (Innodb_buffer_pool_read_requests-Innodb_buffer_pool_reads)/ Innodb_buffer_pool_read_requests * 100%
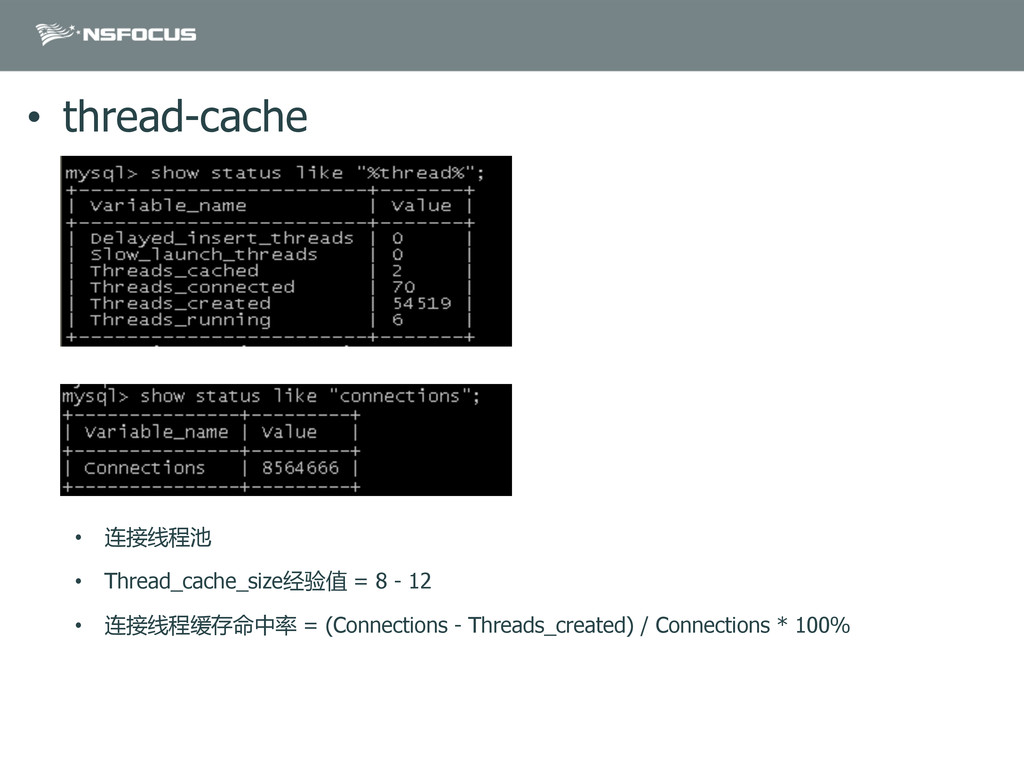
• thread-cache • 连接线程池 • Thread_cache_size经验值 = 8 - 12
• 连接线程缓存命中率 = (Connections - Threads_created) / Connections * 100%
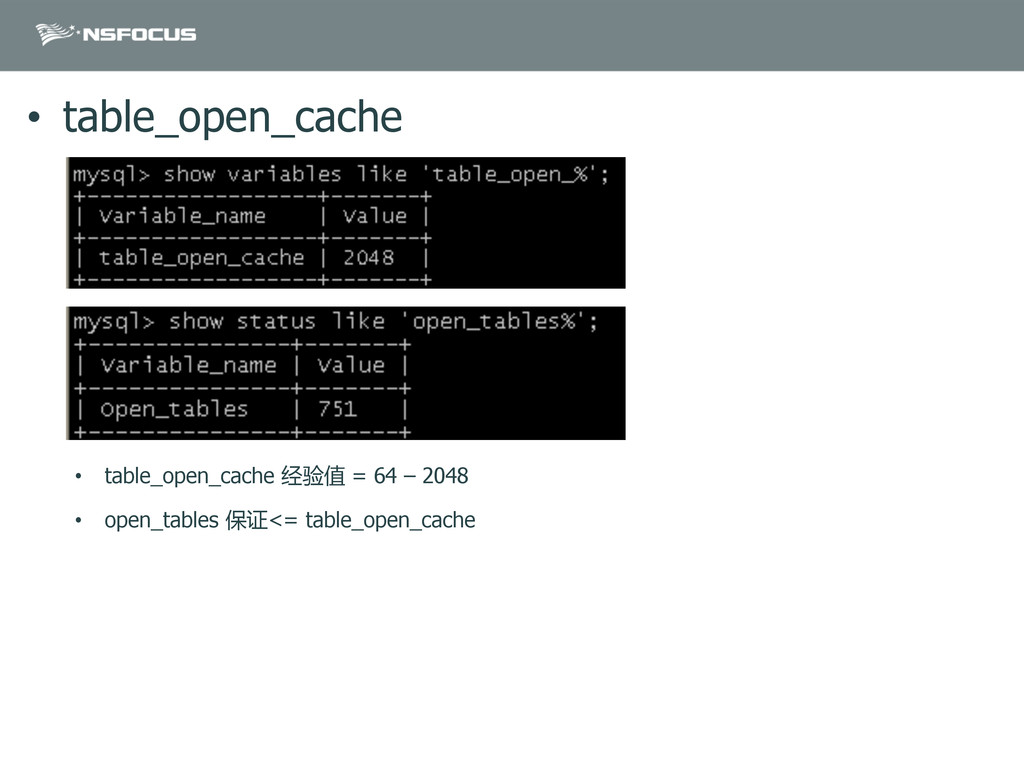
• table_open_cache • table_open_cache 经验值 = 64 – 2048 •
open_tables 保证<= table_open_cache
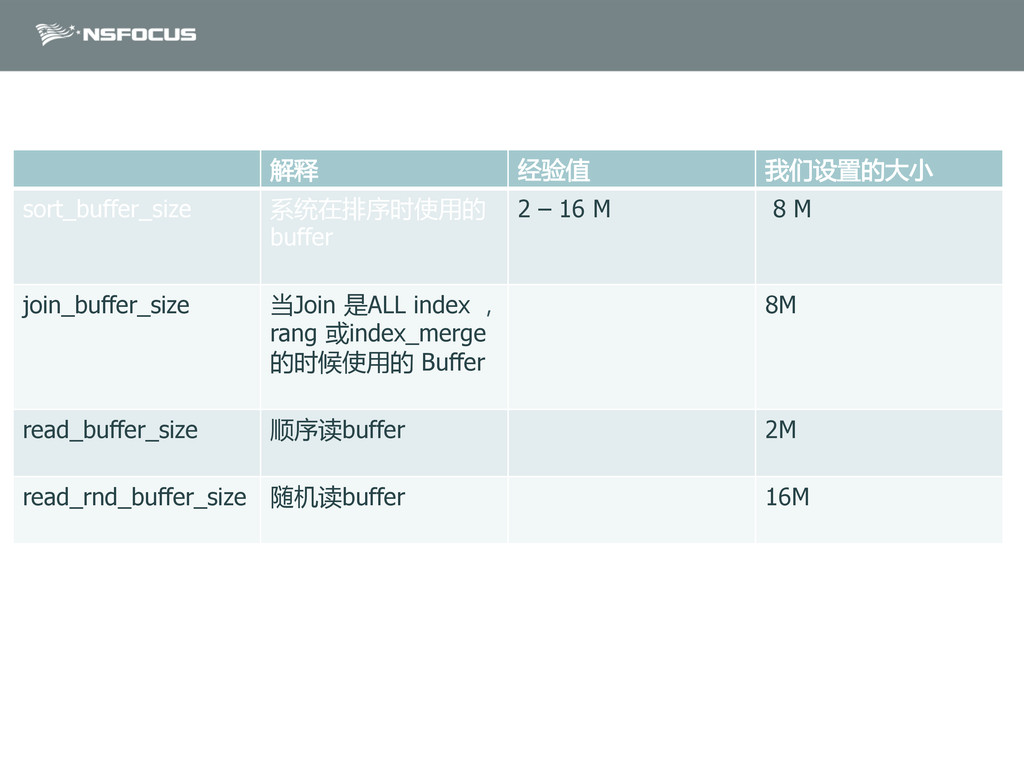
解释 经验值 我们设置的大小 sort_buffer_size 系统在排序时使用的 buffer
2 – 16 M 8 M join_buffer_size 当Join 是ALL index , rang 或index_merge 的时候使用的 Buffer 8M read_buffer_size 顺序读buffer 2M read_rnd_buffer_size 随机读buffer 16M
• Schema 设计
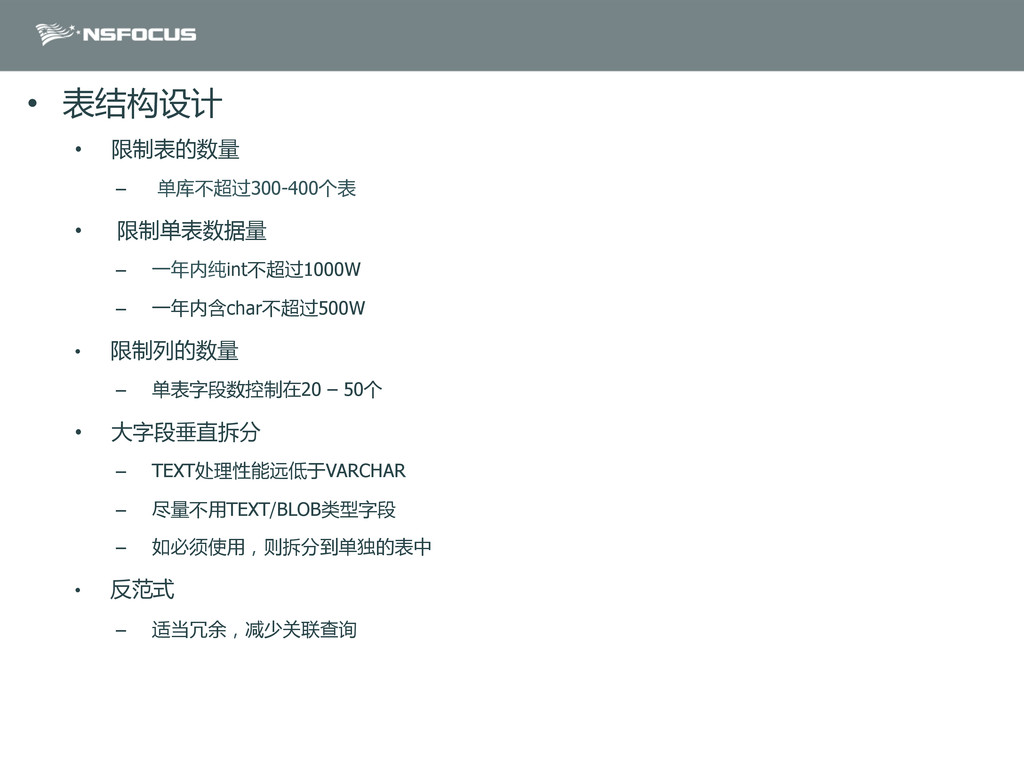
• 表结构设计 • 限制表的数量 – 单库不超过300-400个表 • 限制单表数据量 –
一年内纯int不超过1000W – 一年内含char不超过500W • 限制列的数量 – 单表字段数控制在20 – 50个 • 大字段垂直拆分 – TEXT处理性能远低于VARCHAR – 尽量不用TEXT/BLOB类型字段 – 如必须使用,则拆分到单独的表中 • 反范式 – 适当冗余,减少关联查询
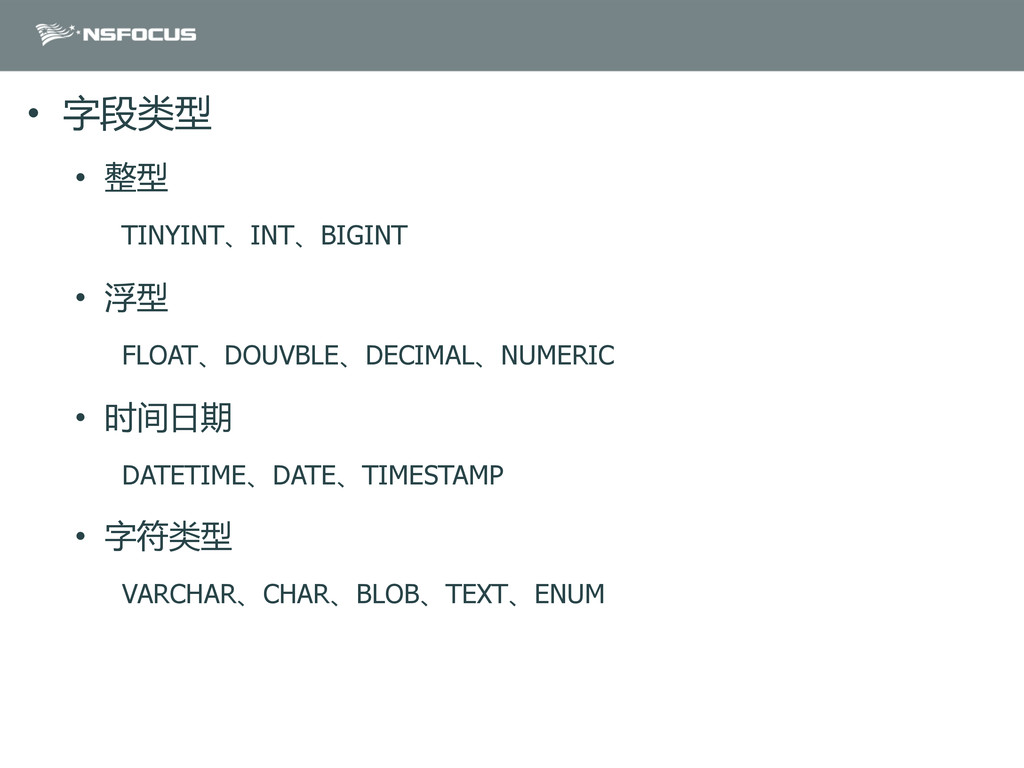
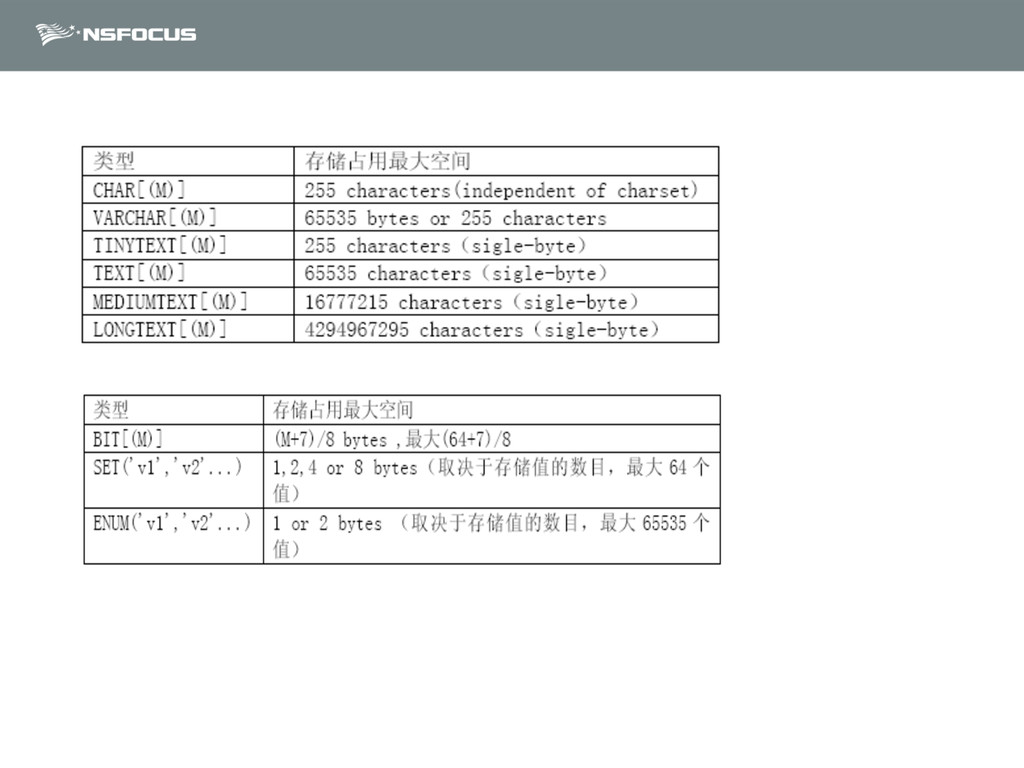
• 字段类型 • 整型 TINYINT、INT、BIGINT • 浮型 FLOAT、DOUVBLE、DECIMAL、NUMERIC • 时间日期
DATETIME、DATE、TIMESTAMP • 字符类型 VARCHAR、CHAR、BLOB、TEXT、ENUM
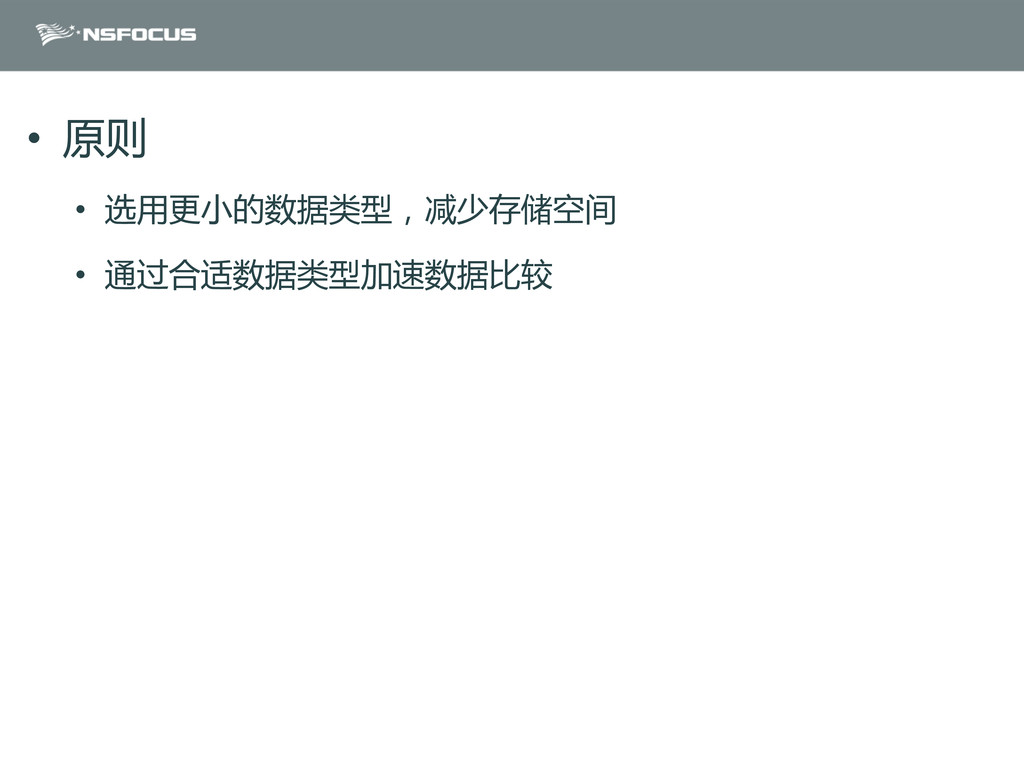
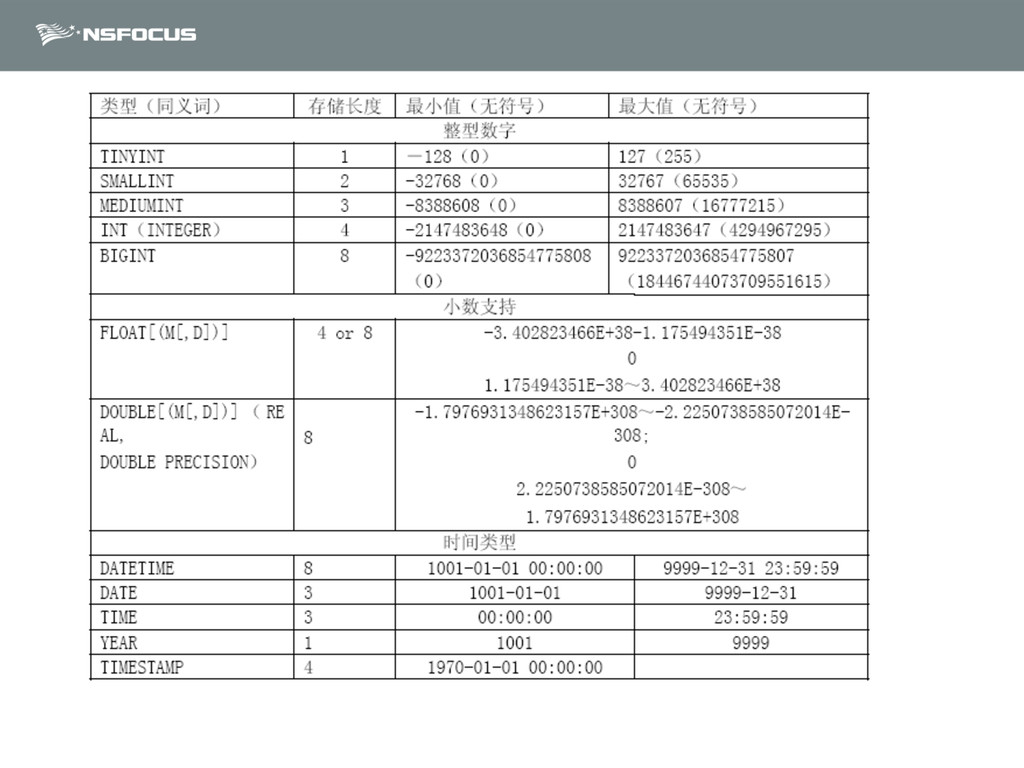
• 原则 • 选用更小的数据类型,减少存储空间 • 通过合适数据类型加速数据比较
None
None
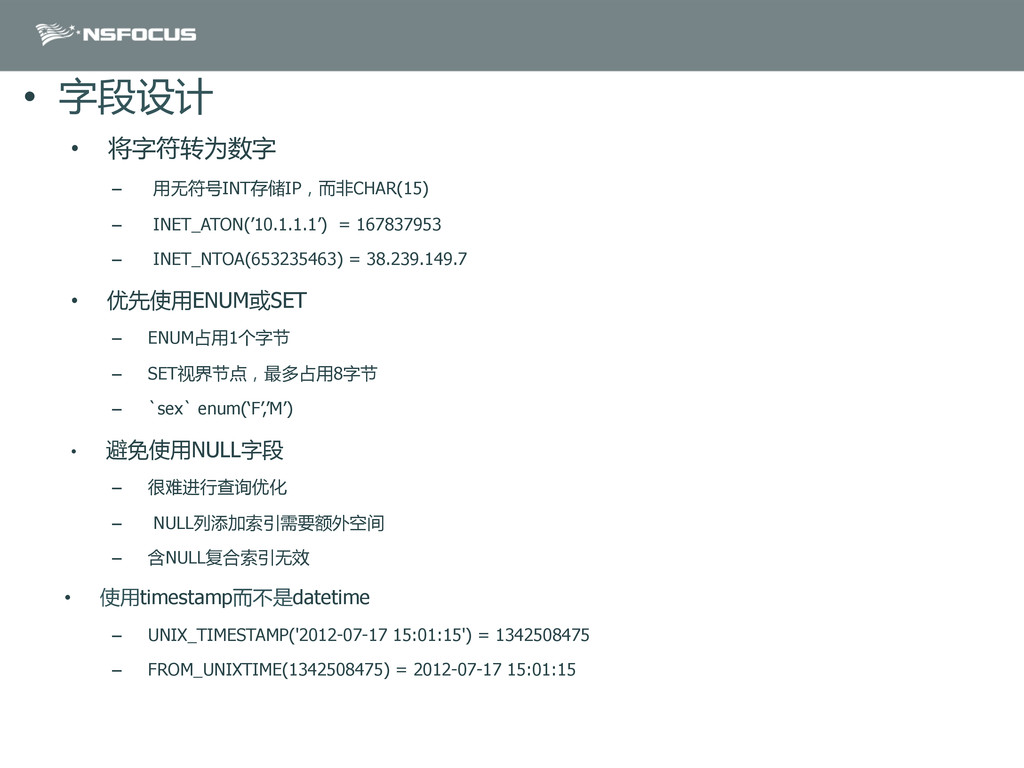
• 字段设计 • 将字符转为数字 – 用无符号INT存储IP,而非CHAR(15) – INET_ATON(’10.1.1.1’) = 167837953
– INET_NTOA(653235463) = 38.239.149.7 • 优先使用ENUM或SET – ENUM占用1个字节 – SET视界节点,最多占用8字节 – `sex` enum(‘F’,’M’) • 避免使用NULL字段 – 很难进行查询优化 – NULL列添加索引需要额外空间 – 含NULL复合索引无效 • 使用timestamp而不是datetime – UNIX_TIMESTAMP('2012-07-17 15:01:15') = 1342508475 – FROM_UNIXTIME(1342508475) = 2012-07-17 15:01:15
• SQL语句优化
• 索引 • 小结果集驱动大结果集 • http://vdisk.weibo.com/s/SMRp • http://vdisk.weibo.com/s/4sEw- • http://vdisk.weibo.com/s/gYYQ
• 存储引擎
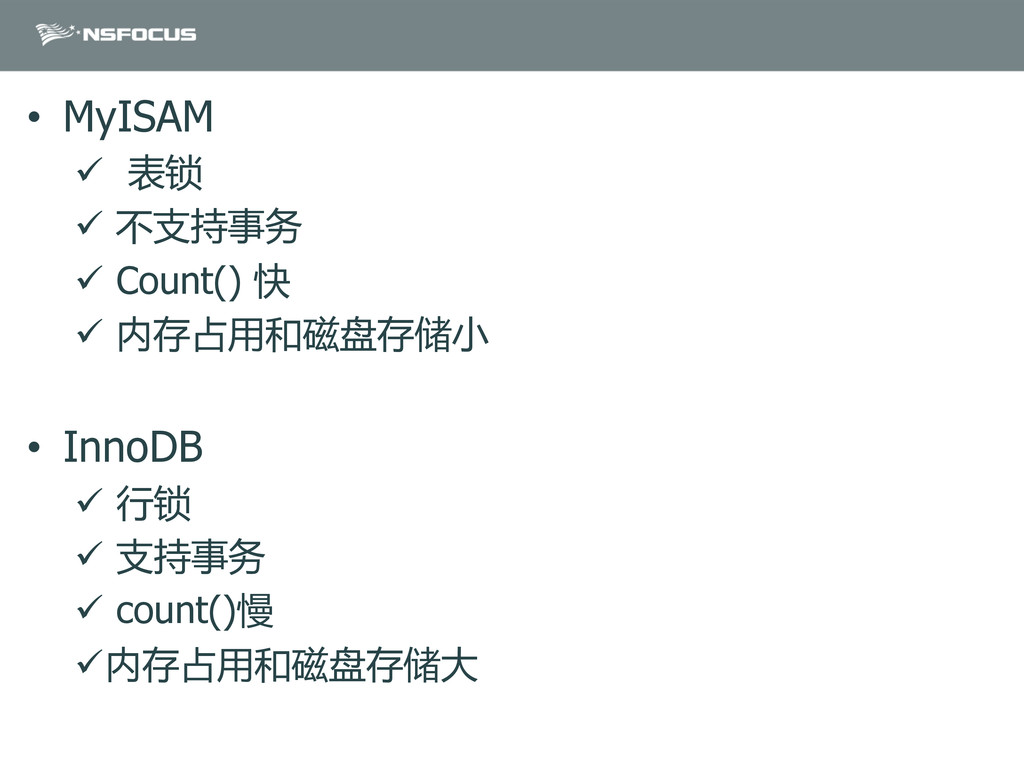
• MyISAM ü 表锁 ü 不支持事务 ü Count() 快 ü
内存占用和磁盘存储小 • InnoDB ü 行锁 ü 支持事务 ü count()慢 ü 内存占用和磁盘存储大
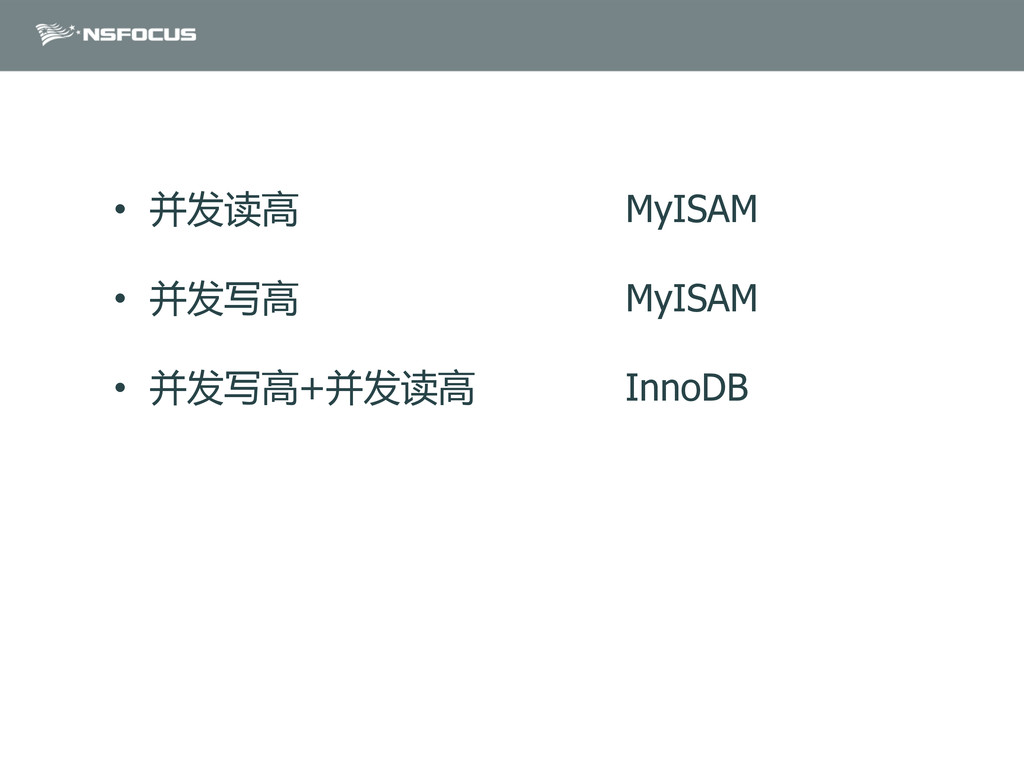
• 并发读高 MyISAM • 并发写高
MyISAM • 并发写高+并发读高 InnoDB
• 架构设计
• Scalability • HA
• Scale Up • Scale Out ü Replication ü Sharding
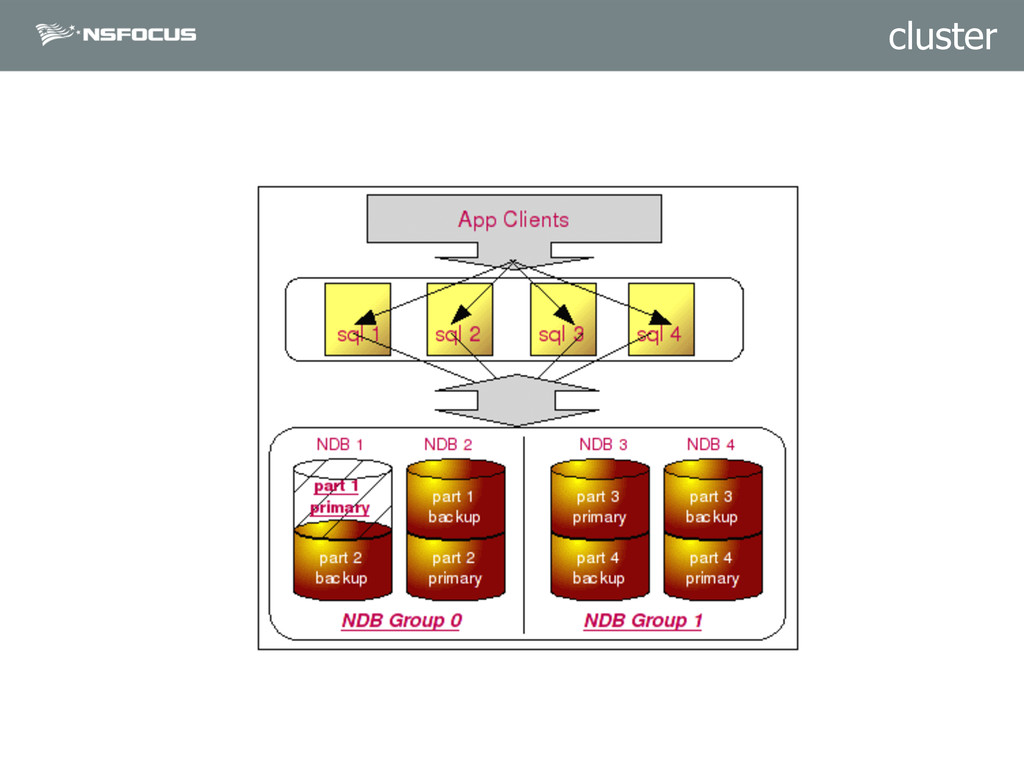
ü Cluster scalability
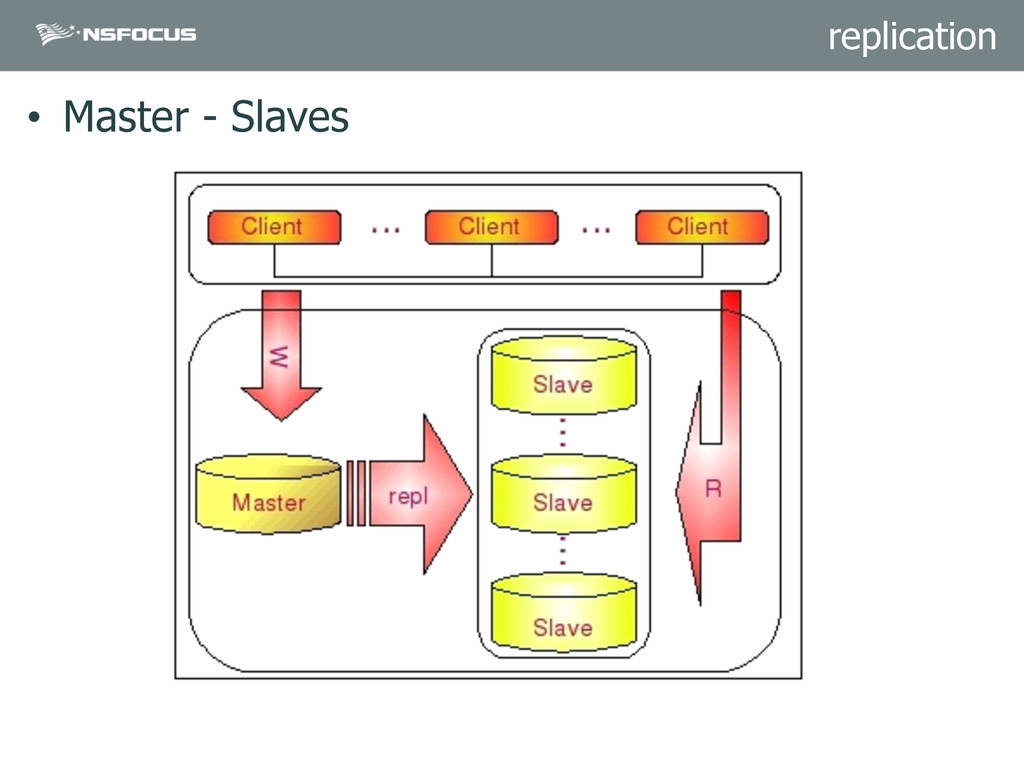
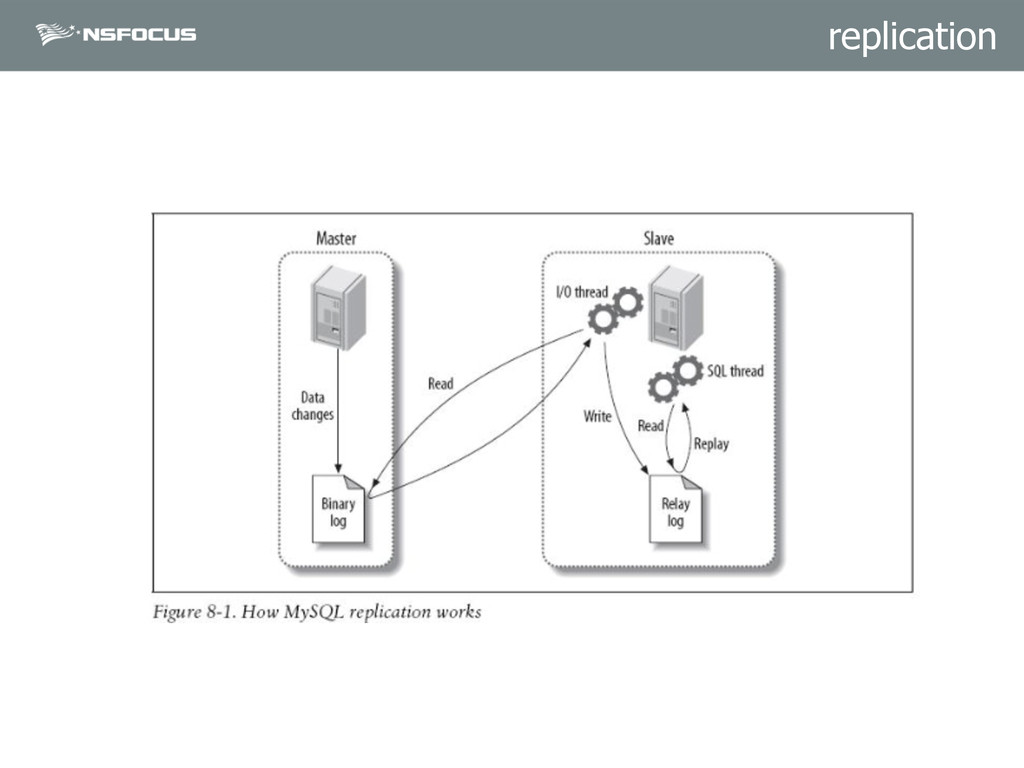
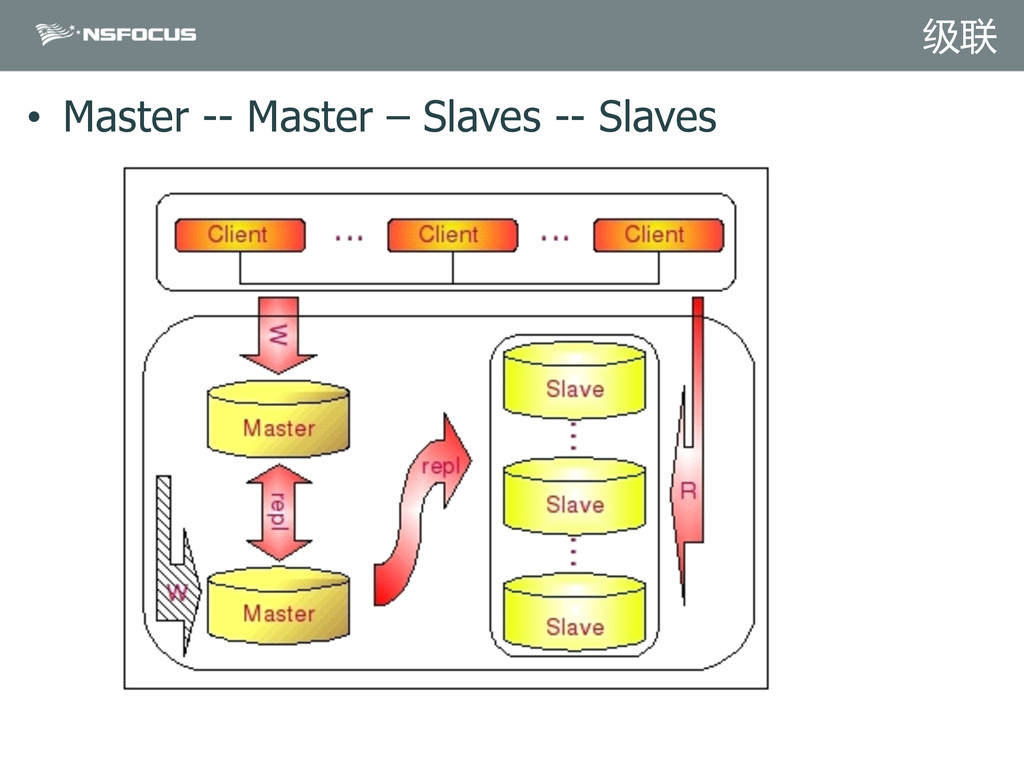
• Master - Slaves replication
replication
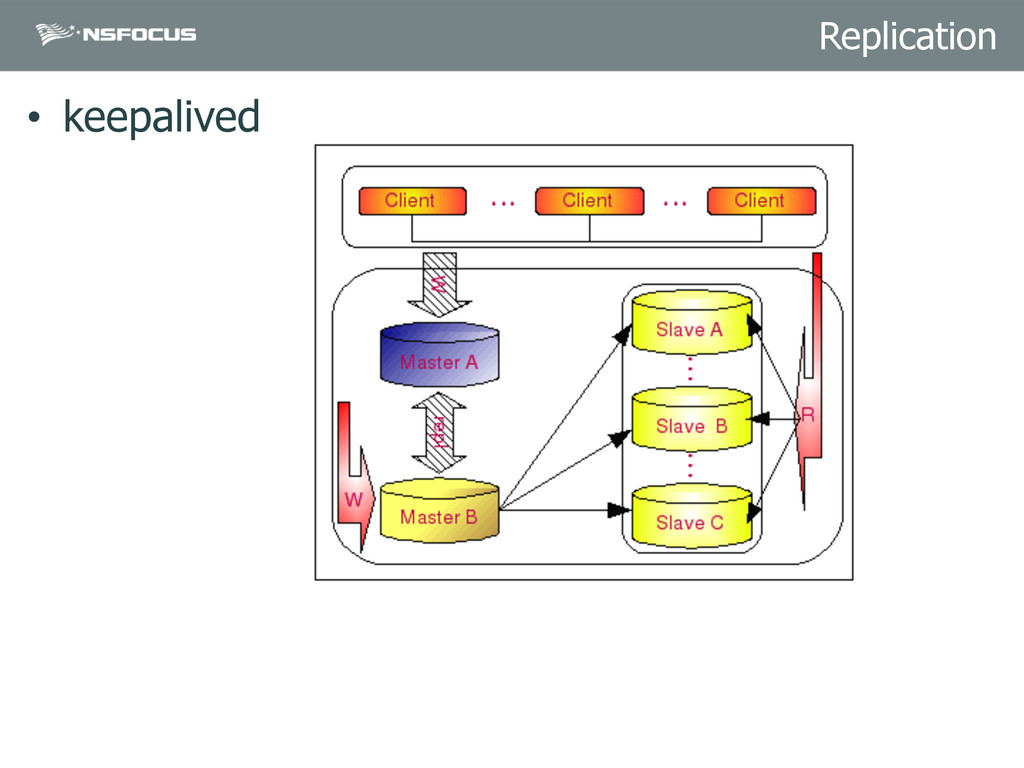
• Master -- Master – Slaves -- Slaves 级联
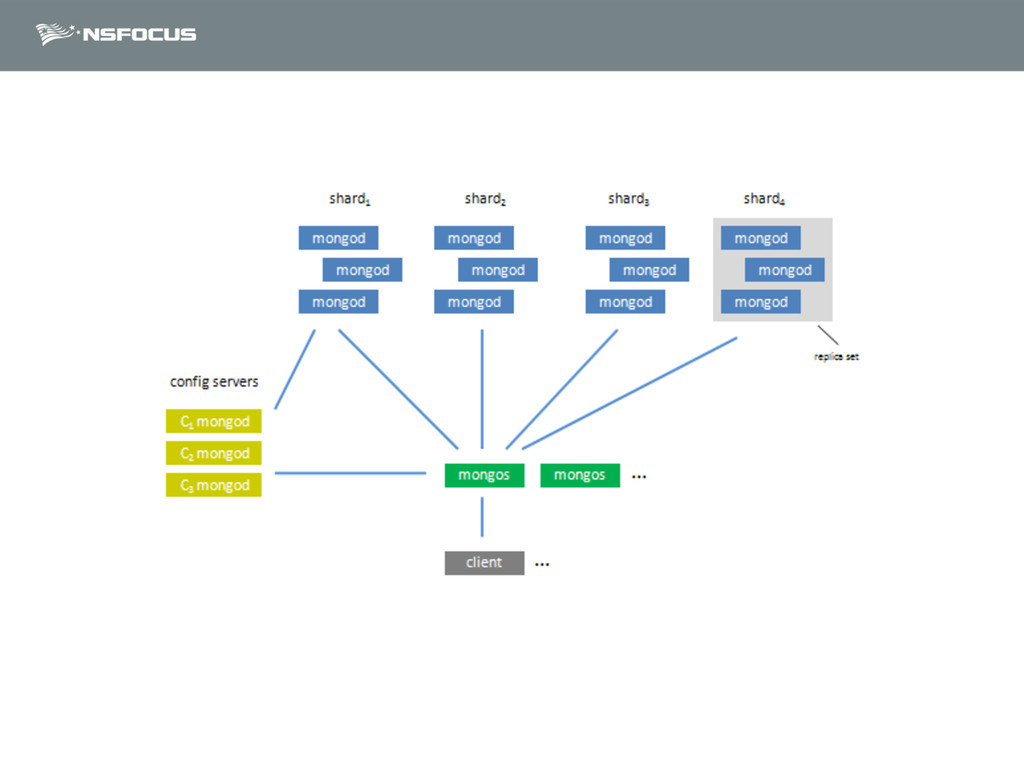
• Sharding ü 垂直分区 ü 水平分区 sharding
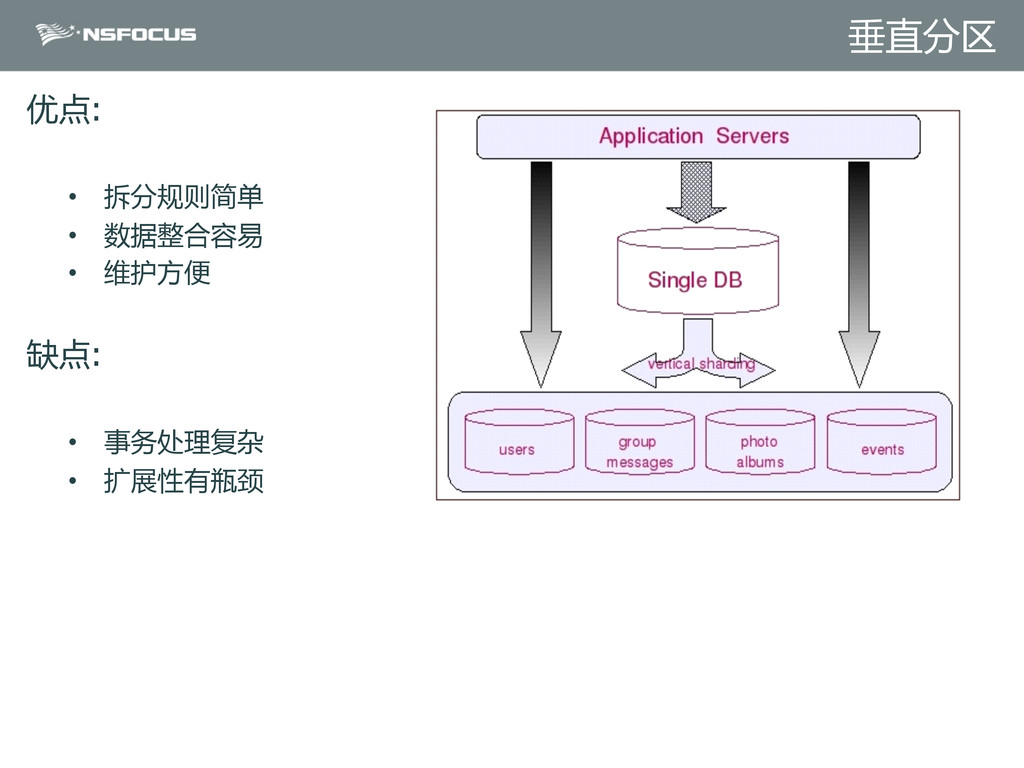
垂直分区 优点: • 拆分规则简单 • 数据整合容易
• 维护方便 缺点: • 事务处理复杂 • 扩展性有瓶颈
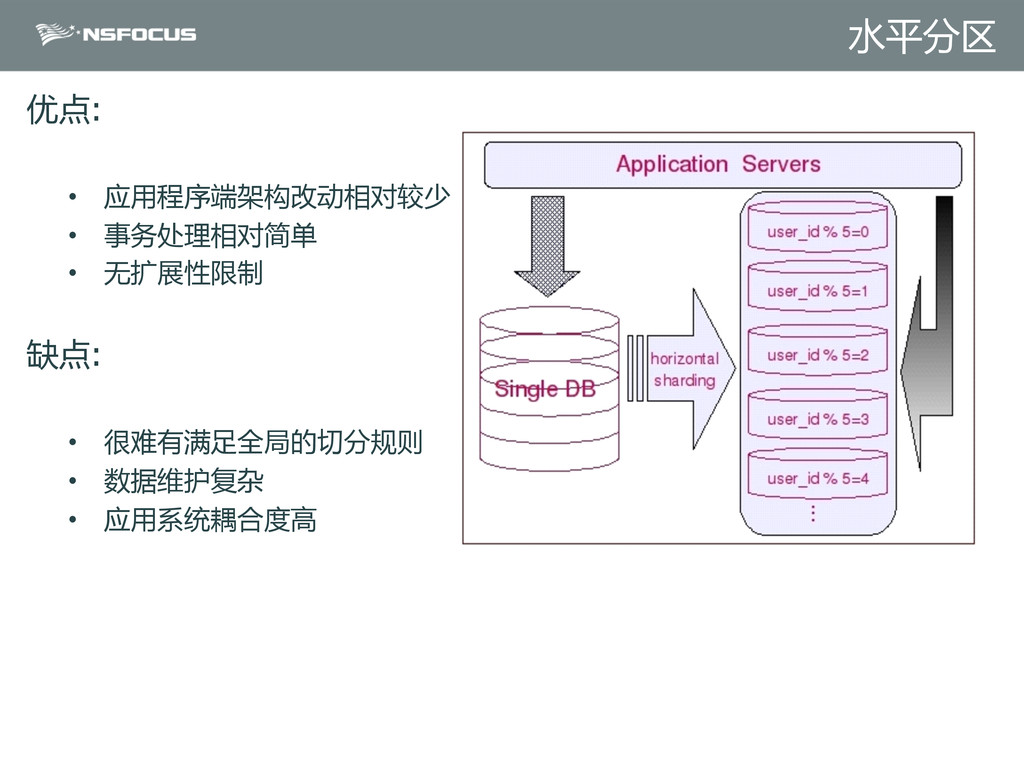
水平分区 优点: • 应用程序端架构改动相对较少 • 事务处理相对简单 • 无扩展性限制 缺点:
• 很难有满足全局的切分规则 • 数据维护复杂 • 应用系统耦合度高
• 数据整合 ü 自行研发 ü MySQL Proxy ü Amoeba 数据整合
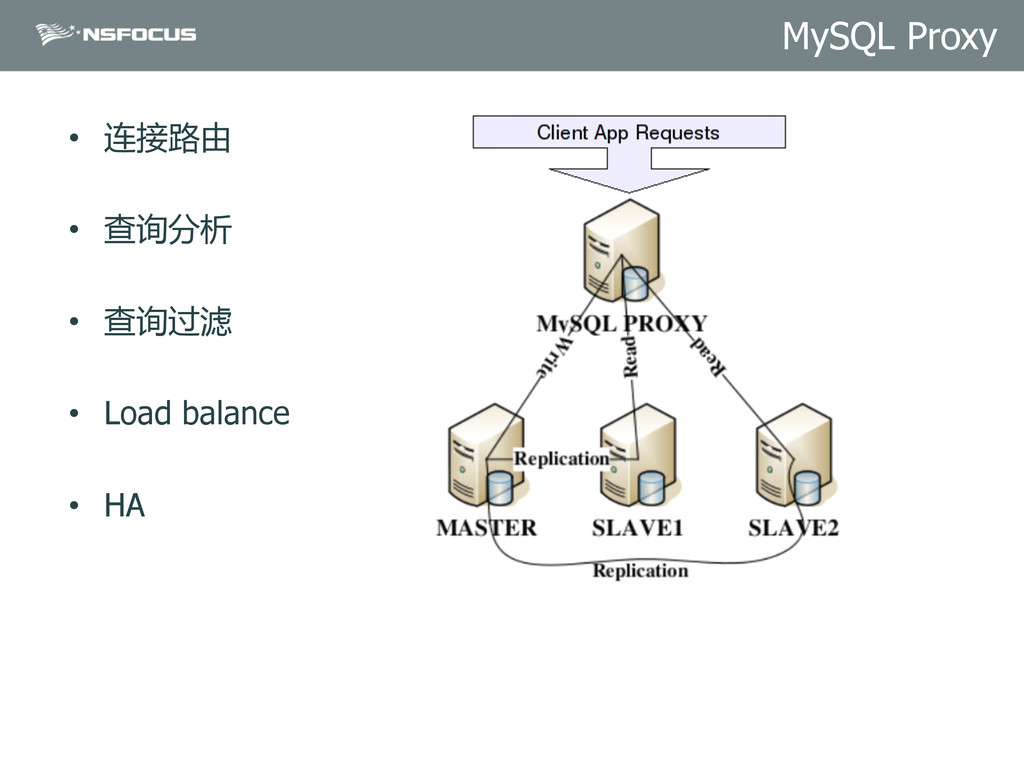
MySQL Proxy • 连接路由 • 查询分析 • 查询过滤 •
Load balance • HA
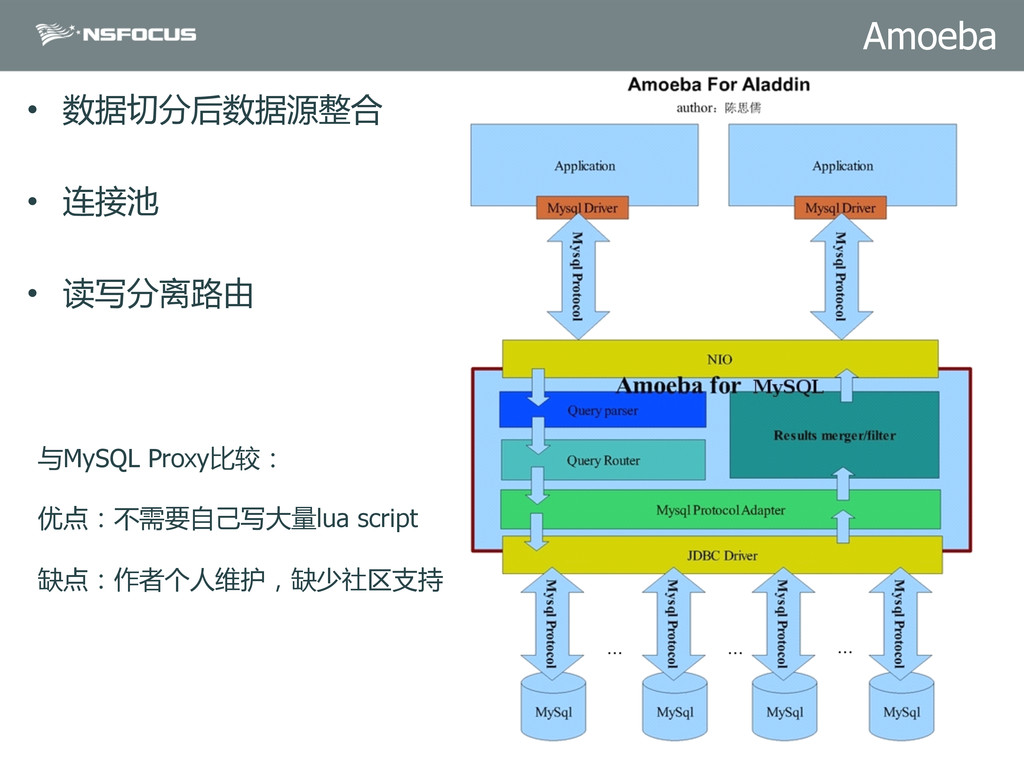
Amoeba • 数据切分后数据源整合 • 连接池 • 读写分离路由 与MySQL
Proxy比较: 优点:不需要自己写大量lua script 缺点:作者个人维护,缺少社区支持
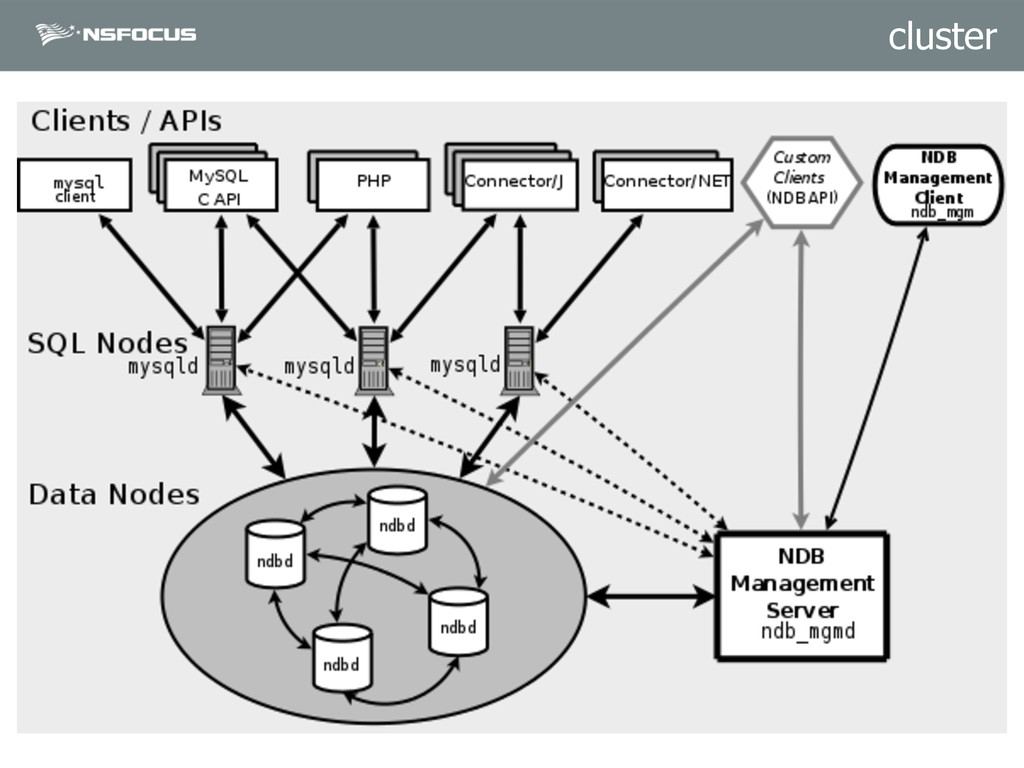
cluster
None
• HA ü 数据备份 ü Fail-over HA
• keepalived Replication
cluster
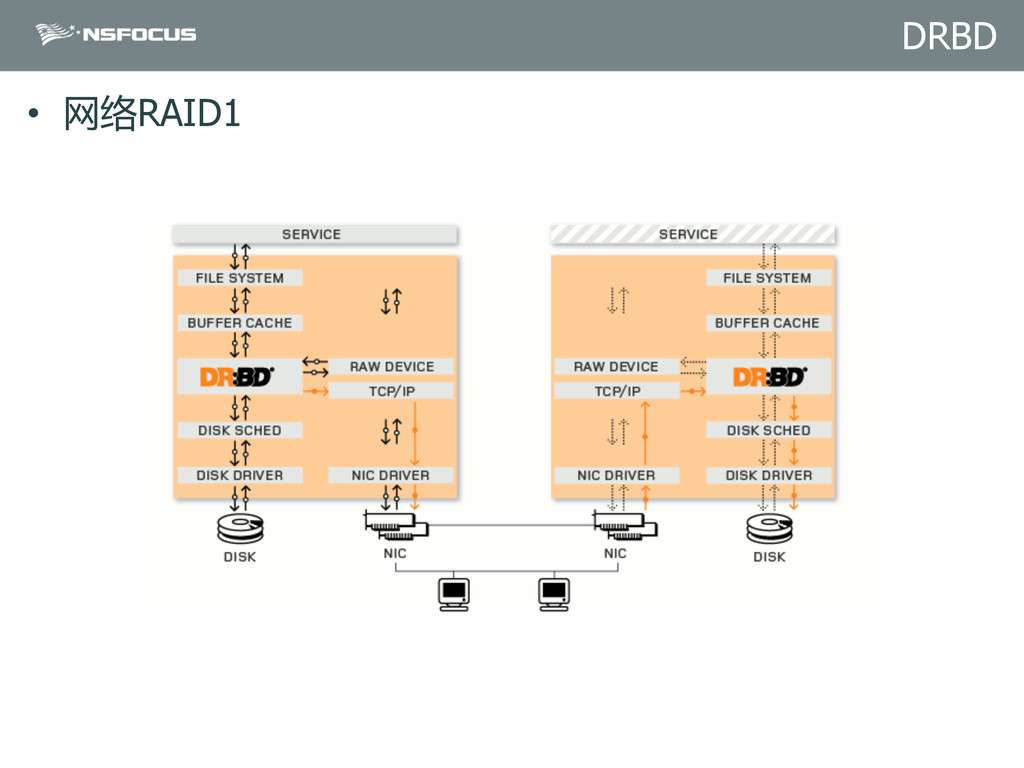
• 网络RAID1 DRBD
谢谢!


 soyuka
 yosuke_furukawa
 lx_t
 oniak3ibm
 willnet
 ktcryomm
 kishida
 yuukiw00w
 htkym
 lynnswap
 tomokon
 sts11142
 garrettdimon
 samlambert
 axbom
 eitanlees
 reverentgeek
 wjessup
 mkilby
 marketingsoph
 pwiseman
 aarron
 honzajavorek
 aleyda