Share
Embed
Scalability and EDA for LINE Shopping platform
Jaekyun Yoo
LINE Plus Commerce Development 2 Server Side Engineer
https://linedevday.linecorp.com/2020/ja/sessions/0522
https://linedevday.linecorp.com/2020/en/sessions/0522
LINE DevDay 2020
November 25, 2020
Transcript
42 slides
-
Agenda › Introduction to LINE Shopping › Change in data
processing method › Scalability and high availability › Summary -
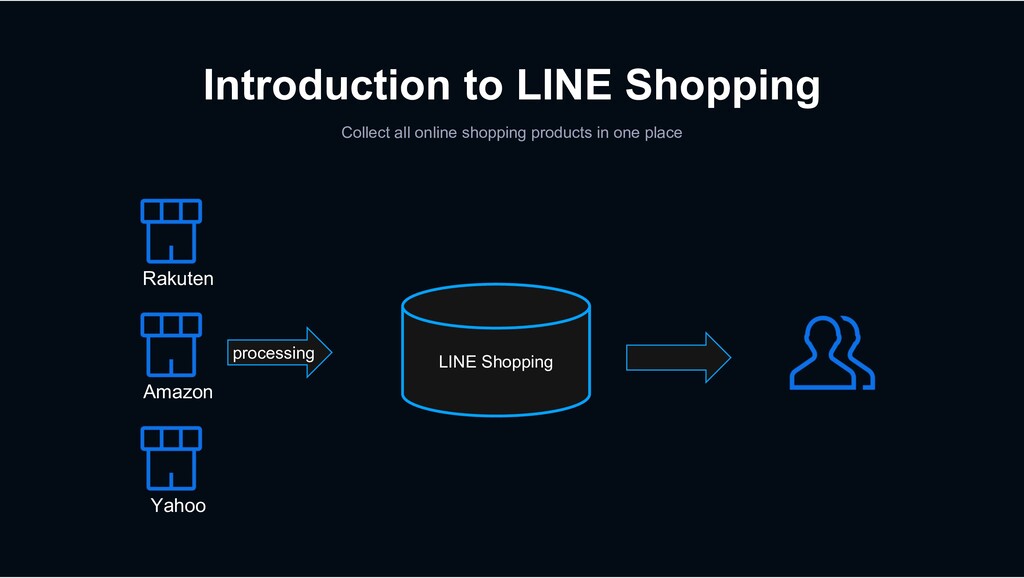
Introduction to LINE Shopping Collect all online shopping products in
one place Rakuten Amazon Yahoo LINE Shopping processing -
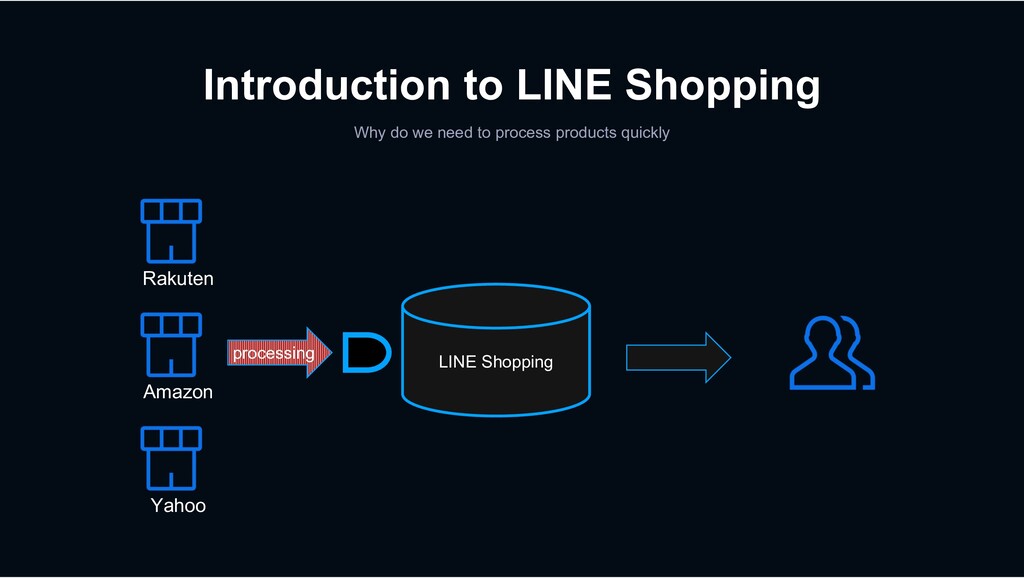
Why do we need to process products quickly Rakuten Amazon
Yahoo LINE Shopping processing Introduction to LINE Shopping -
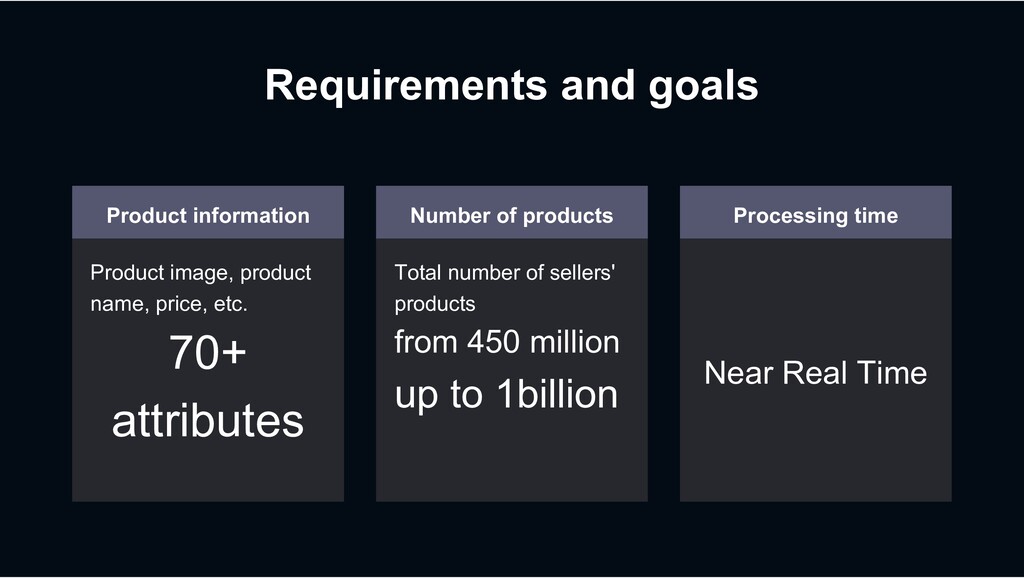
Requirements and goals Product information Product image, product name, price,
etc. 70+ attributes Number of products Total number of sellers' products from 450 million up to 1billion Processing time Near Real Time -
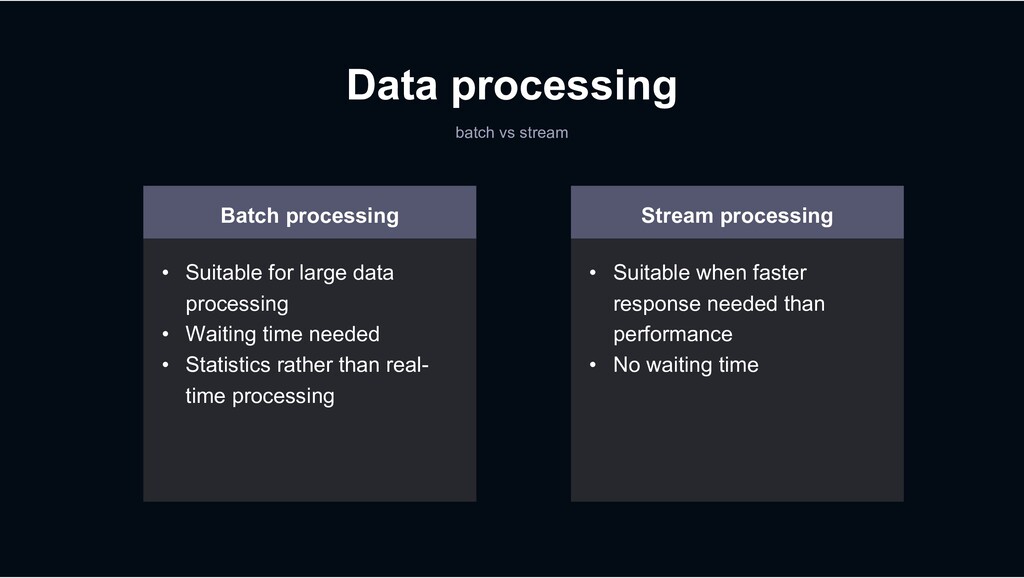
Data processing batch vs stream Batch processing • Suitable for
large data processing • Waiting time needed • Statistics rather than real- time processing Stream processing • Suitable when faster response needed than performance • No waiting time -
Data processing Which method is suitable for receiving and processing
products? Batch processing • Suitable for large data processing • Waiting time needed • Statistics rather than real- time processing Stream processing • Suitable when faster response needed than performance • No waiting time -
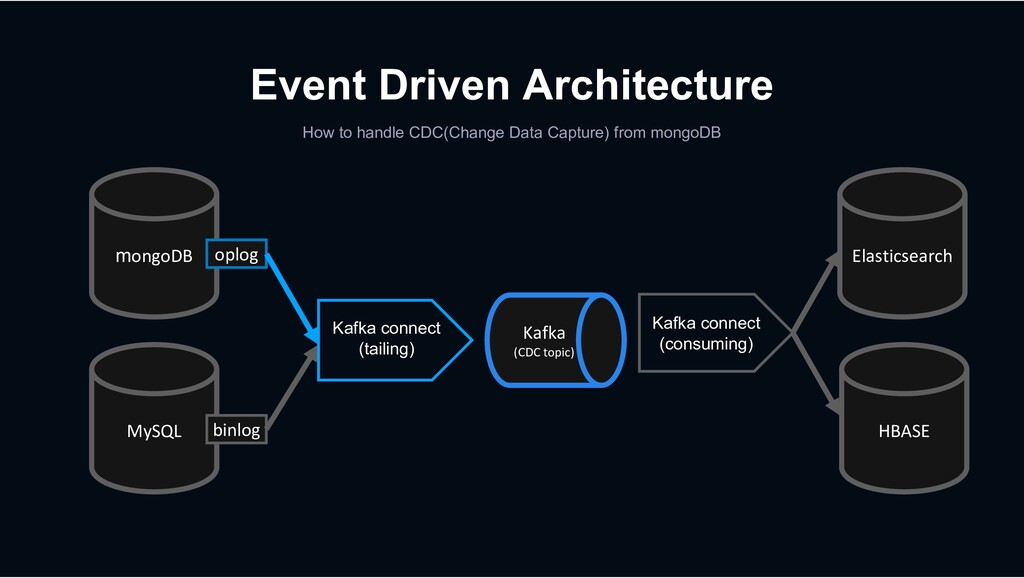
Event Driven Architecture Kafka connect & mongoDB OPlog Kafka connect
Kafka Connect is a tool for scalably and reliably streaming data between Apache Kafka and other data systems. It makes it simple to quickly define connectors that move large data sets into and out of Kafka. -
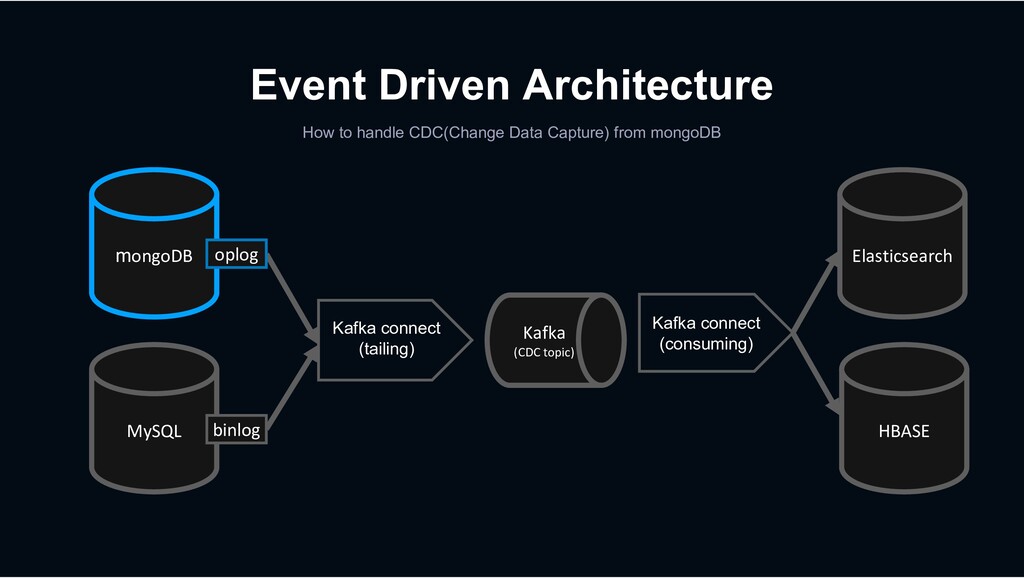
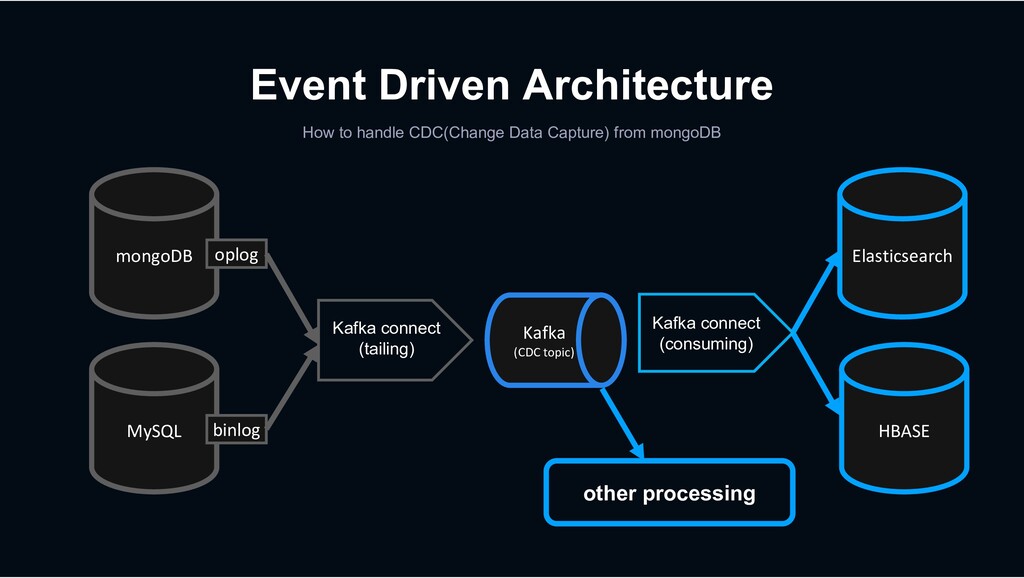
mongoDB MySQL Event Driven Architecture How to handle CDC(Change Data
Capture) from mongoDB Kafka connect (tailing) Kafka connect (consuming) oplog binlog Kafka (CDC topic) Elasticsearch HBASE -
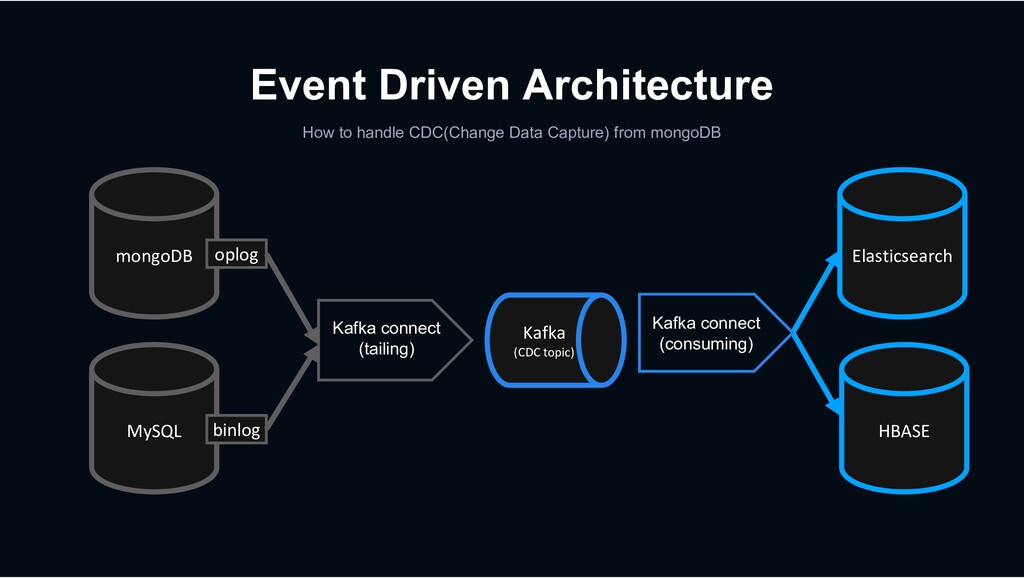
Event Driven Architecture How to handle CDC(Change Data Capture) from
mongoDB mongoDB MySQL oplog binlog Elasticsearch HBASE Kafka (CDC topic) Kafka connect (tailing) Kafka connect (consuming) -
Event Driven Architecture How to handle CDC(Change Data Capture) from
mongoDB mongoDB MySQL oplog binlog Elasticsearch HBASE Kafka (CDC topic) Kafka connect (tailing) Kafka connect (consuming) -
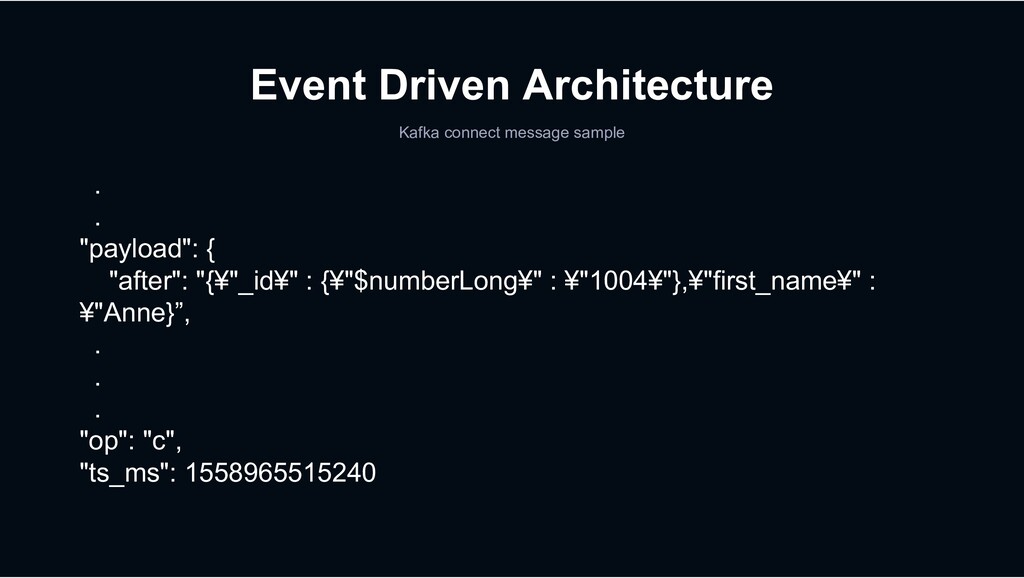
Event Driven Architecture Kafka connect message sample . . "payload":
{ "after": "{¥"_id¥" : {¥"$numberLong¥" : ¥"1004¥"},¥"first_name¥" : ¥"Anne}”, . . . "op": "c", "ts_ms": 1558965515240 -
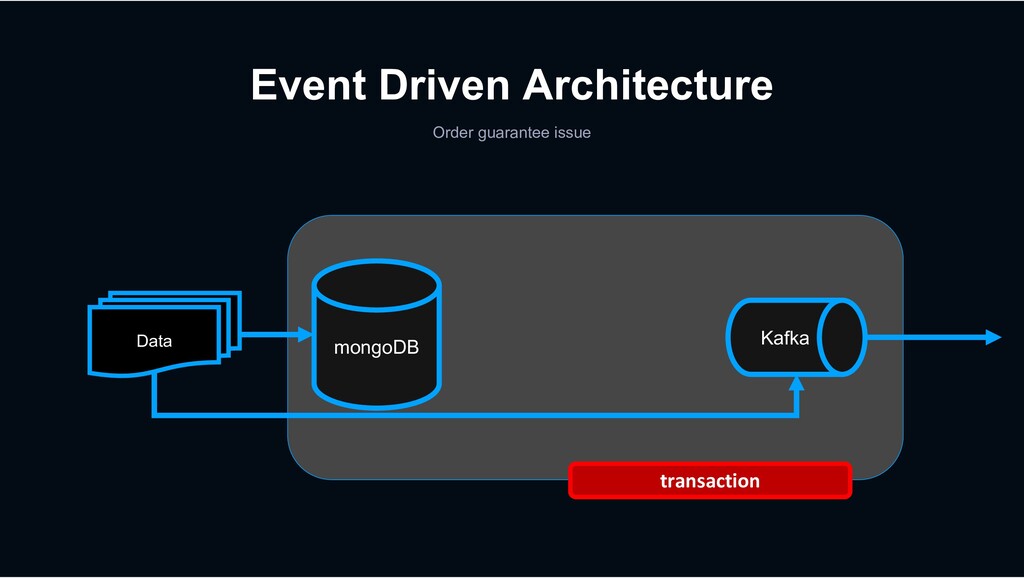
Event Driven Architecture • UPDATE table_A SET column_A=‘value1’ WHERE age>20;
• affected rows : 12237 -
Event Driven Architecture How to handle CDC(Change Data Capture) from
mongoDB mongoDB MySQL oplog binlog Kafka (CDC topic) Elasticsearch HBASE other processing Kafka connect (tailing) Kafka connect (consuming) -
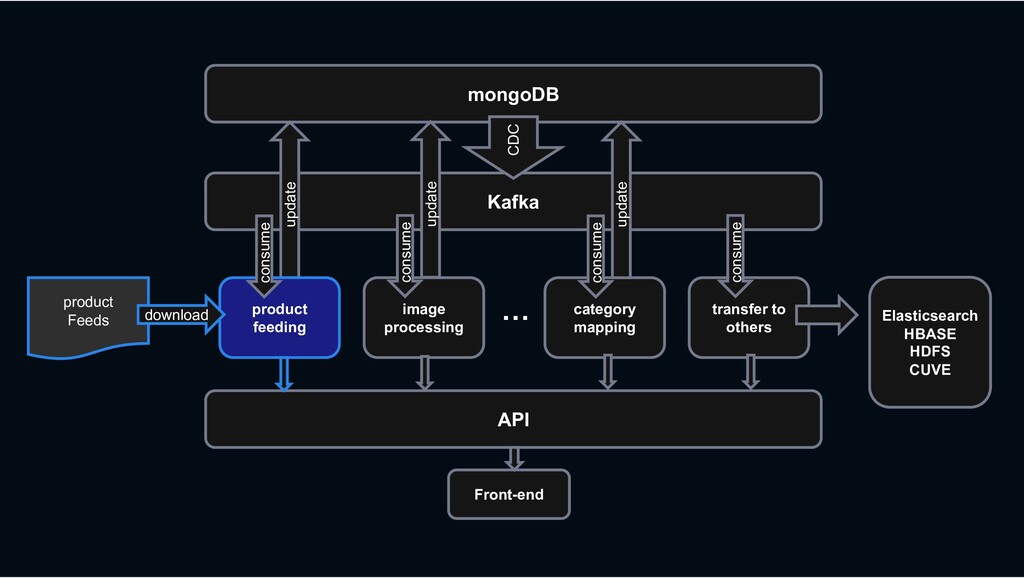
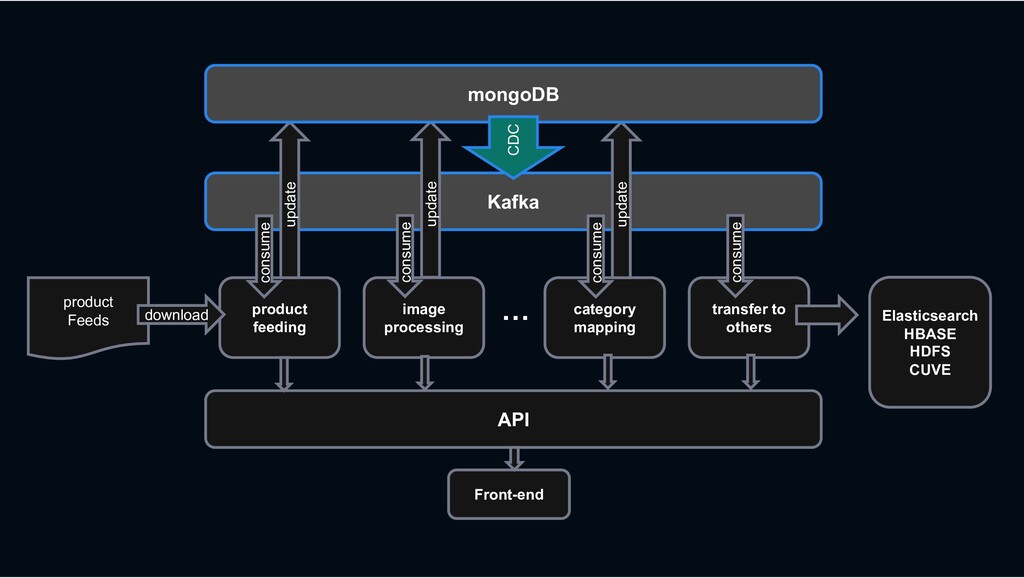
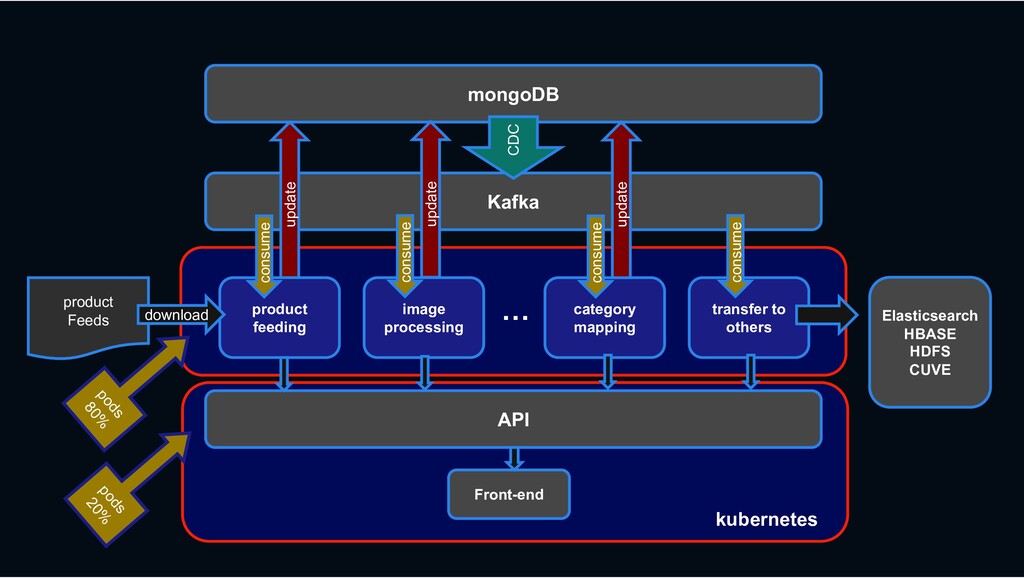
mongoDB Kafka API CDC update product Feeds product feeding image
processing category mapping transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end … -
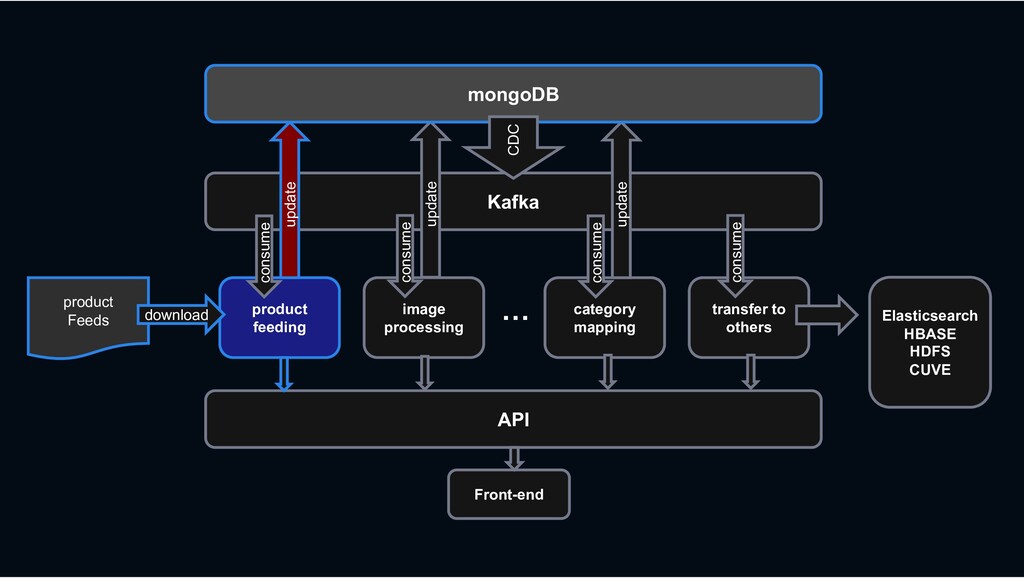
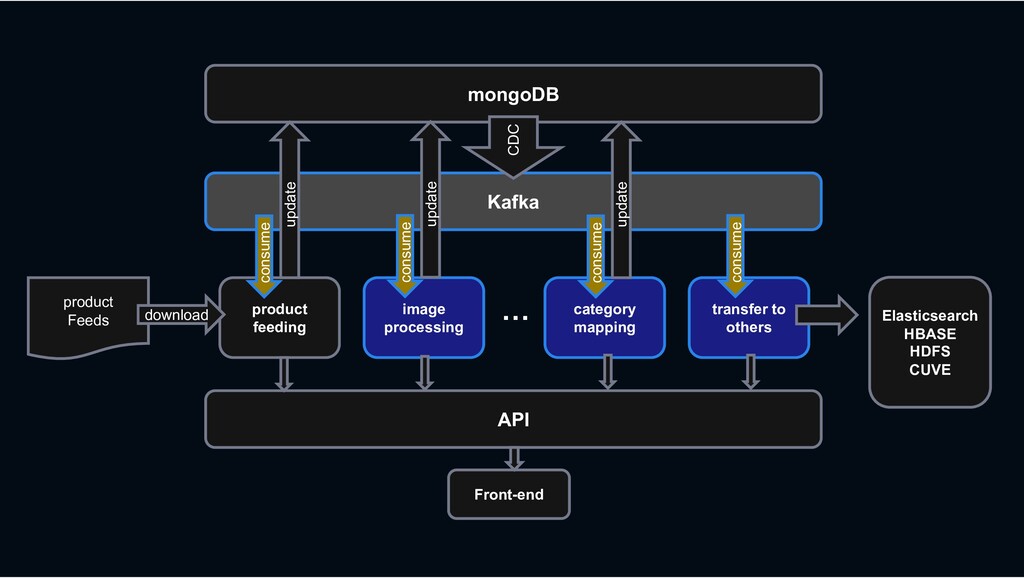
Kafka API product Feeds product feeding image processing category mapping
transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end update mongoDB … CDC -
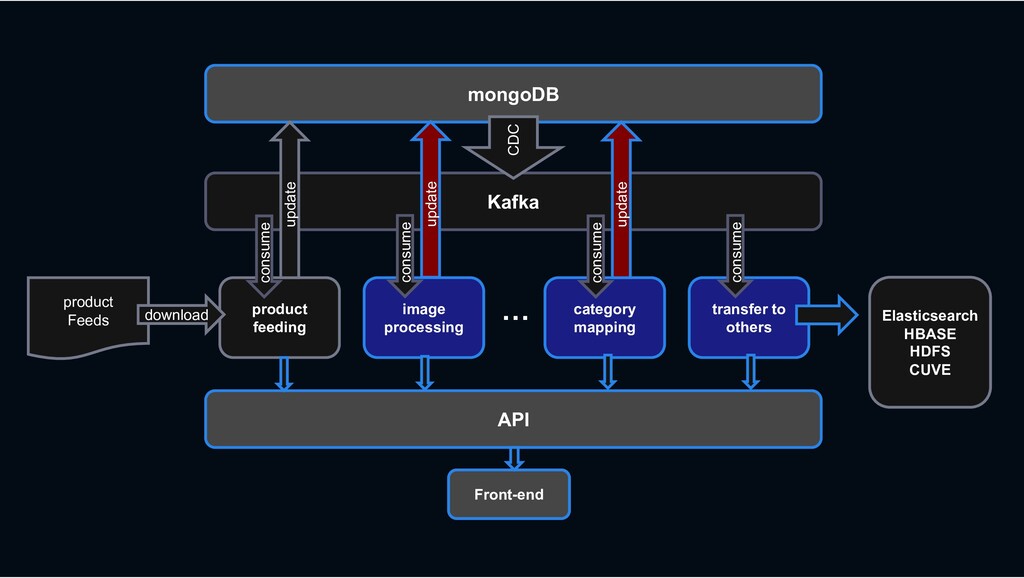
Kafka API product Feeds product feeding image processing category mapping
transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end update mongoDB CDC … -
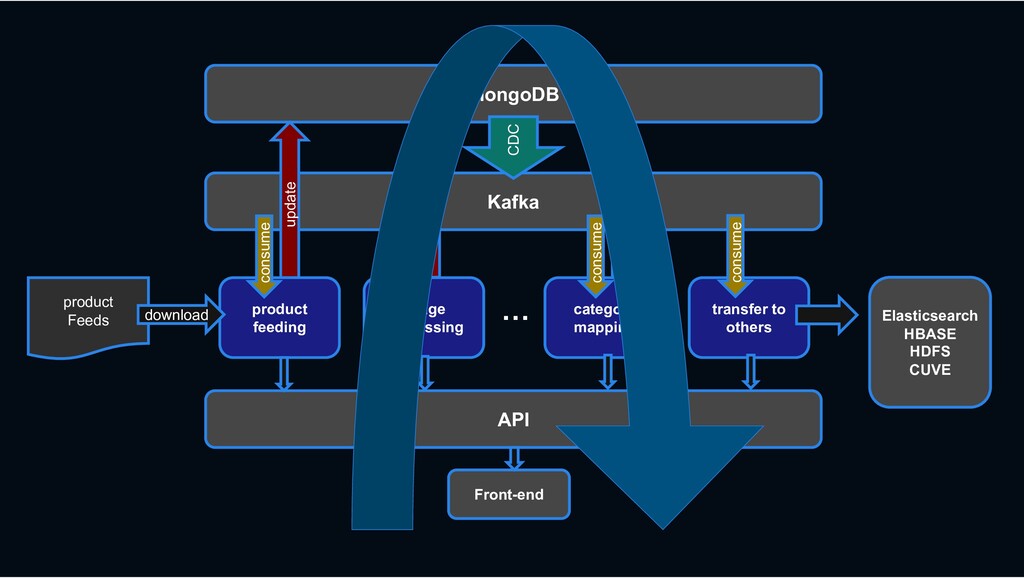
image processing category mapping transfer to others API product Feeds
product feeding download Elasticsearch HBASE HDFS CUVE Front-end mongoDB Kafka CDC consume consume consume consume update update update … -
mongoDB image processing category mapping transfer to others product Feeds
product feeding download Elasticsearch HBASE HDFS CUVE Front-end Kafka CDC consume consume consume consume update update update API Front-end … -
mongoDB Kafka API CDC update product Feeds product feeding image
processing category mapping transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end … -
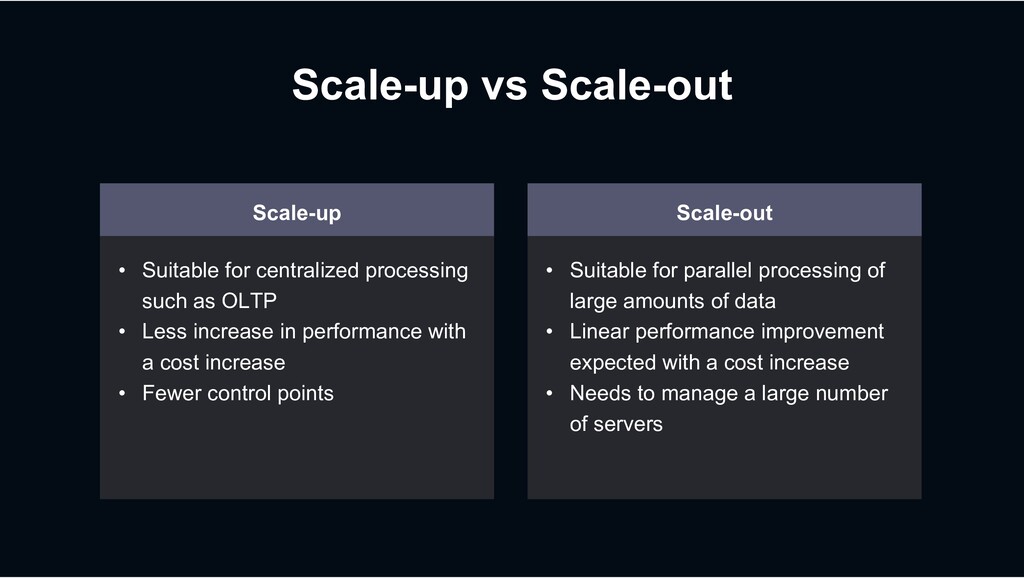
Scale-up vs Scale-out Scale-up • Suitable for centralized processing such
as OLTP • Less increase in performance with a cost increase • Fewer control points Scale-out • Suitable for parallel processing of large amounts of data • Linear performance improvement expected with a cost increase • Needs to manage a large number of servers -
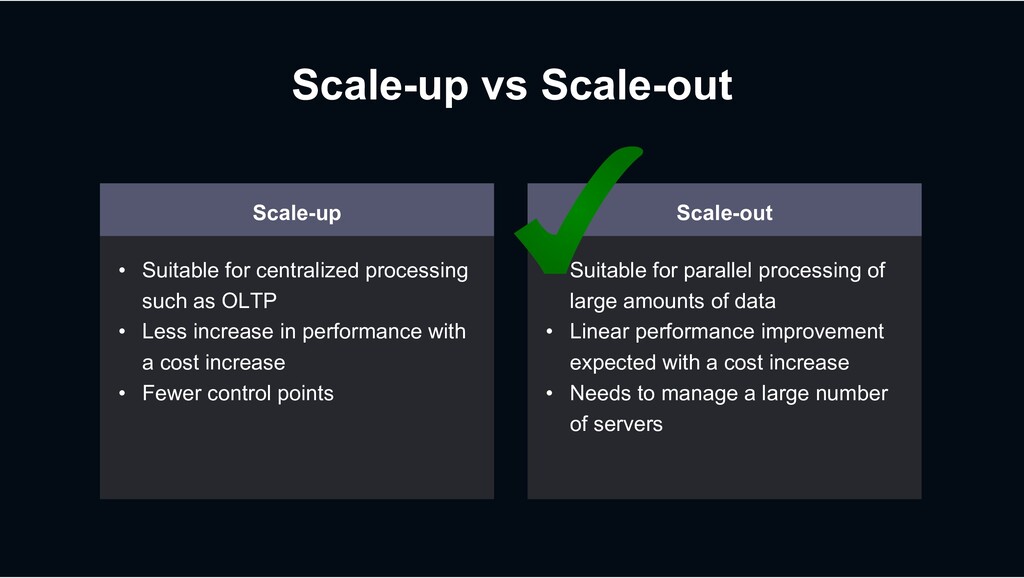
Scale-up vs Scale-out Scale-up • Suitable for centralized processing such
as OLTP • Less increase in performance with a cost increase • Fewer control points Scale-out • Suitable for parallel processing of large amounts of data • Linear performance improvement expected with a cost increase • Needs to manage a large number of servers -
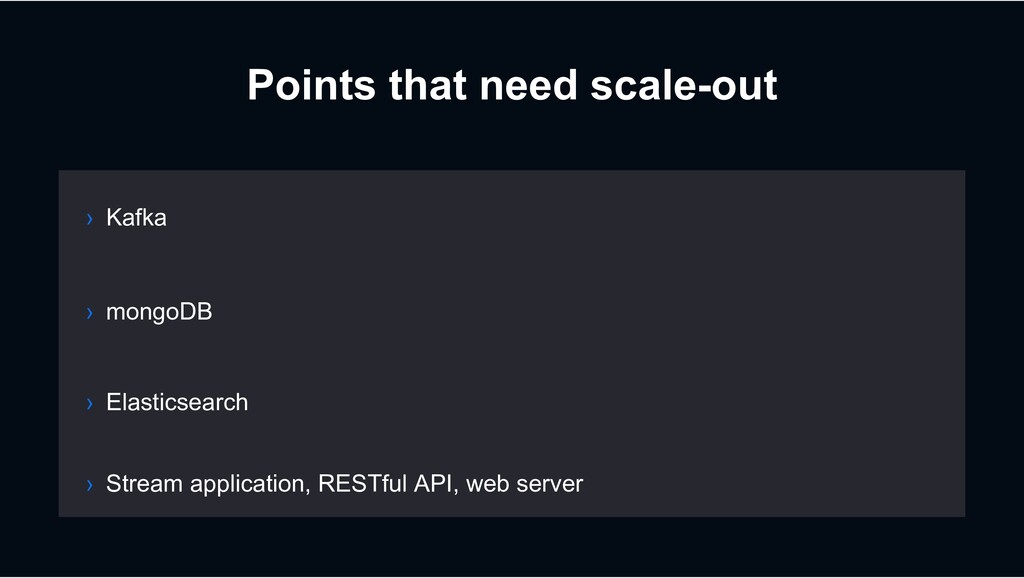
Points that need scale-out › mongoDB › Elasticsearch › Kafka
› Stream application, RESTful API, web server -
Points that need scale-out › mongoDB › Elasticsearch › Kafka
› Stream application, RESTful API, web server -
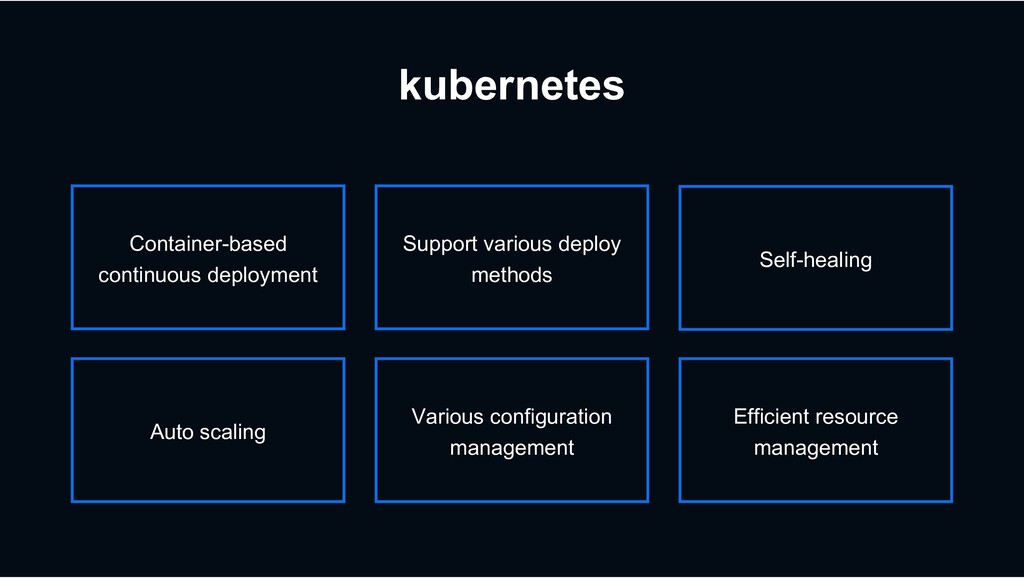
kubernetes Efficient resource management Support various deploy methods Various configuration
management Auto scaling Self-healing Container-based continuous deployment -
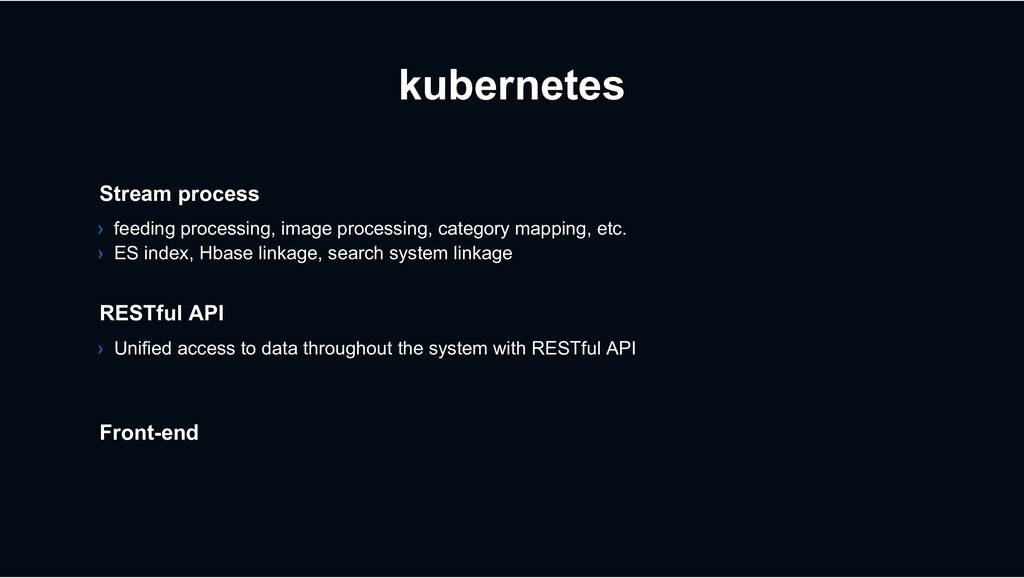
kubernetes › Unified access to data throughout the system with
RESTful API RESTful API Front-end Stream process › feeding processing, image processing, category mapping, etc. › ES index, Hbase linkage, search system linkage -
mongoDB Kafka API CDC update product Feeds product feeding image
processing category mapping transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end kubernetes … -
mongoDB Kafka API CDC update product Feeds product feeding image
processing category mapping transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end kubernetes pods 80% pods 20% … -
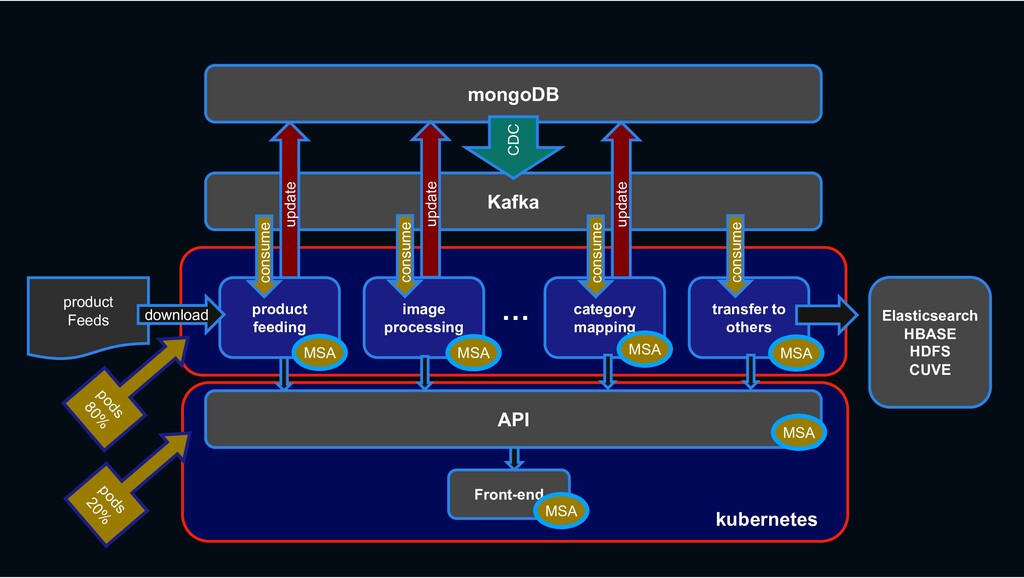
mongoDB Kafka API CDC update product Feeds product feeding image
processing category mapping transfer to others consume update consume update consume consume download Elasticsearch HBASE HDFS CUVE Front-end kubernetes pods 80% pods 20% MSA MSA MSA MSA MSA MSA … -
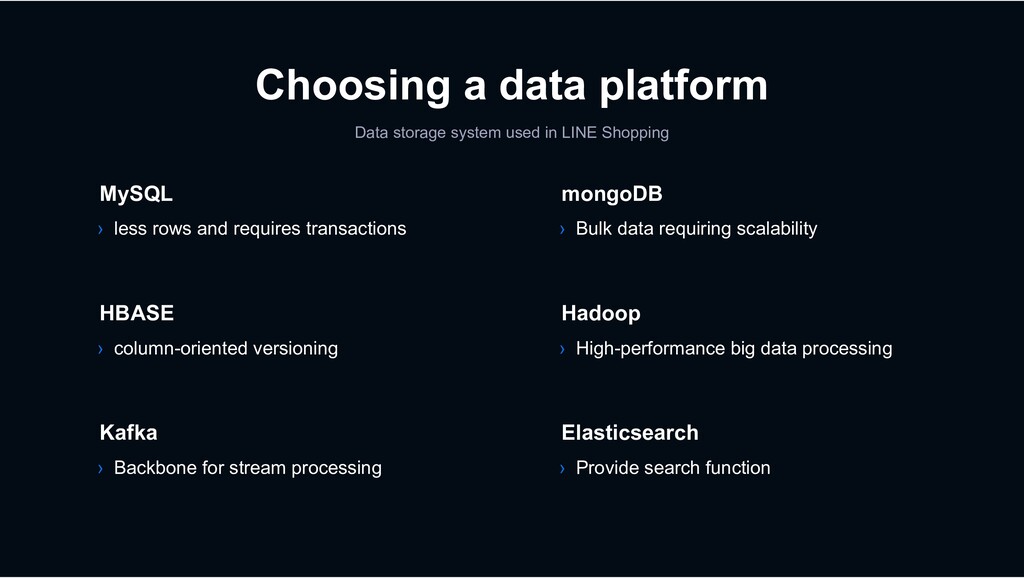
Choosing a data platform Data storage system used in LINE
Shopping › less rows and requires transactions MySQL › column-oriented versioning › Backbone for stream processing HBASE Kafka › Bulk data requiring scalability mongoDB › High-performance big data processing › Provide search function Hadoop Elasticsearch -
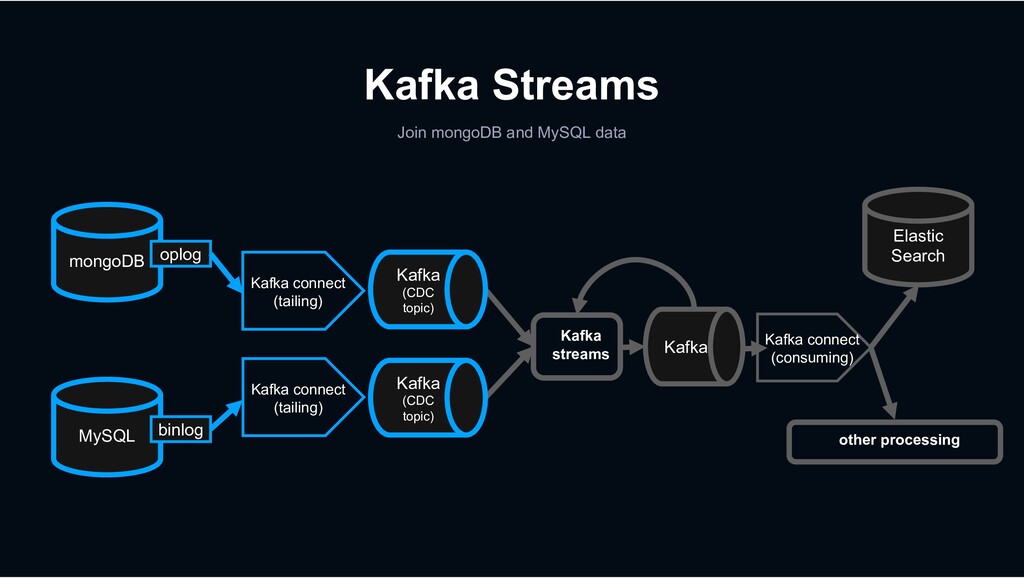
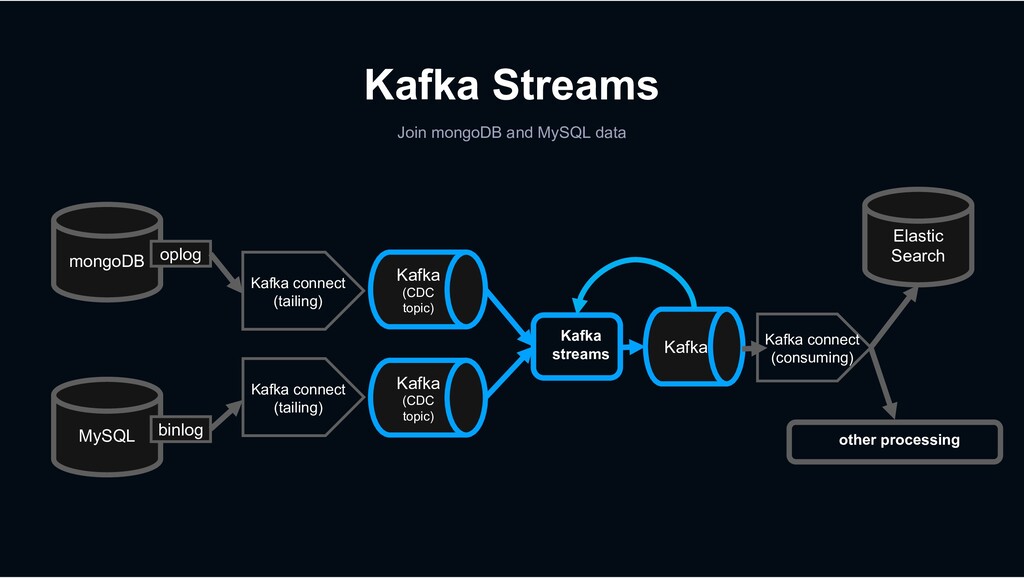
Kafka Streams Join mongoDB and MySQL data mongoDB MySQL oplog
binlog Kafka connect (tailing) Kafka (CDC topic) Kafka connect (tailing) Kafka (CDC topic) Kafka streams Kafka Kafka connect (consuming) Elastic Search other processing -
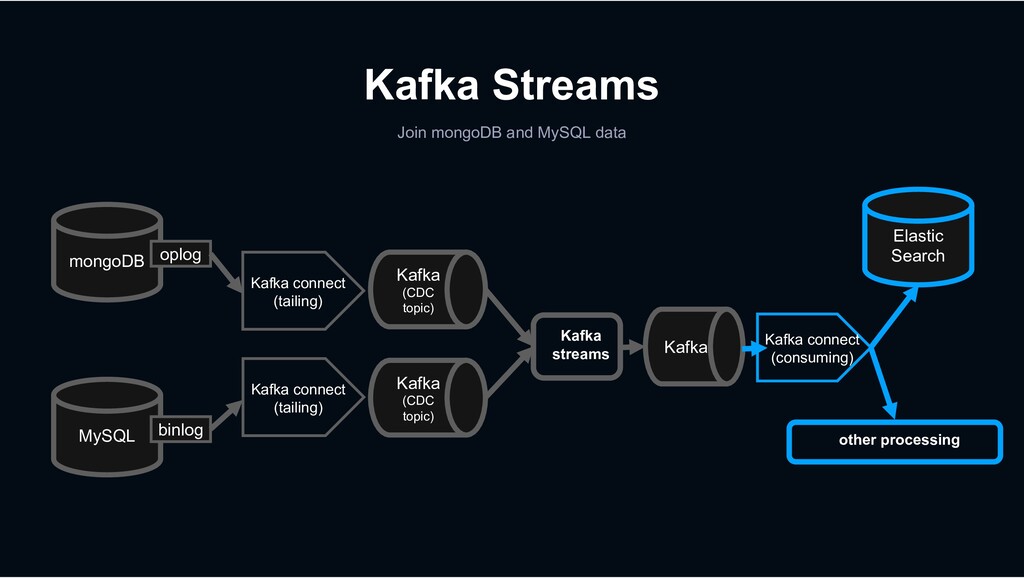
Kafka Streams Join mongoDB and MySQL data mongoDB MySQL oplog
binlog Kafka connect (tailing) Kafka (CDC topic) Kafka connect (tailing) Kafka (CDC topic) Kafka streams Kafka Kafka connect (consuming) Elastic Search other processing -
Kafka Streams Join mongoDB and MySQL data mongoDB MySQL oplog
binlog Kafka connect (tailing) Kafka (CDC topic) Kafka connect (tailing) Kafka (CDC topic) Kafka streams Kafka Kafka connect (consuming) Elastic Search other processing -
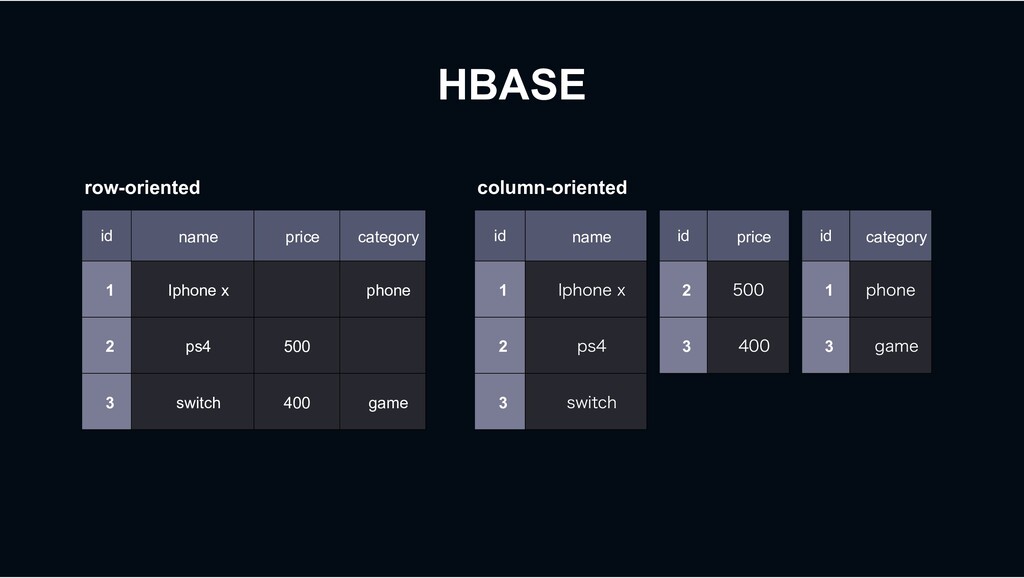
HBASE id name price category 1 Iphone x phone 2
ps4 500 3 switch 400 game row-oriented id name 1 *QIPOF Y 2 QT 3 TXJUDI column-oriented id price 2 3 id category 1 QIPOF 3 HBNF -
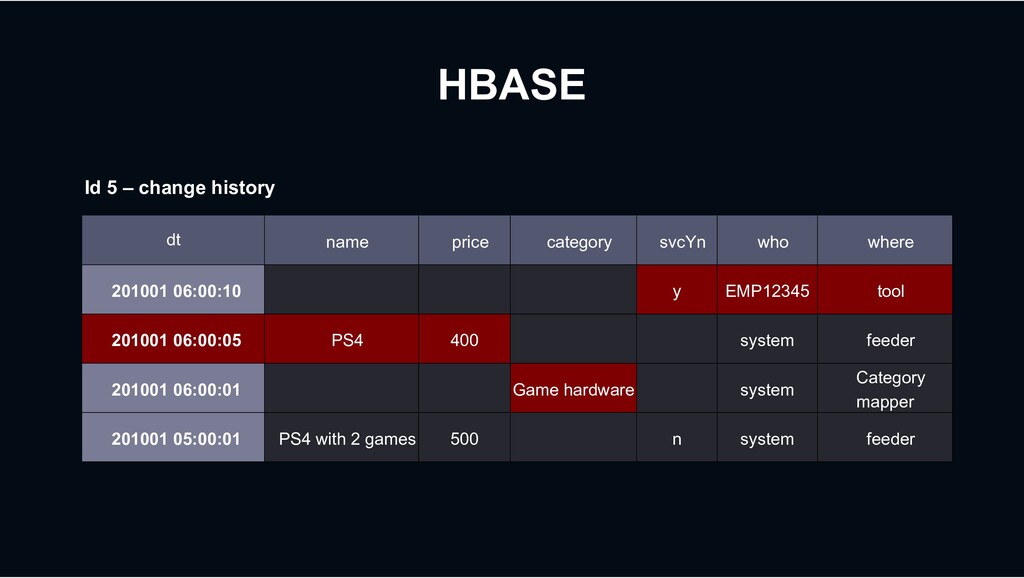
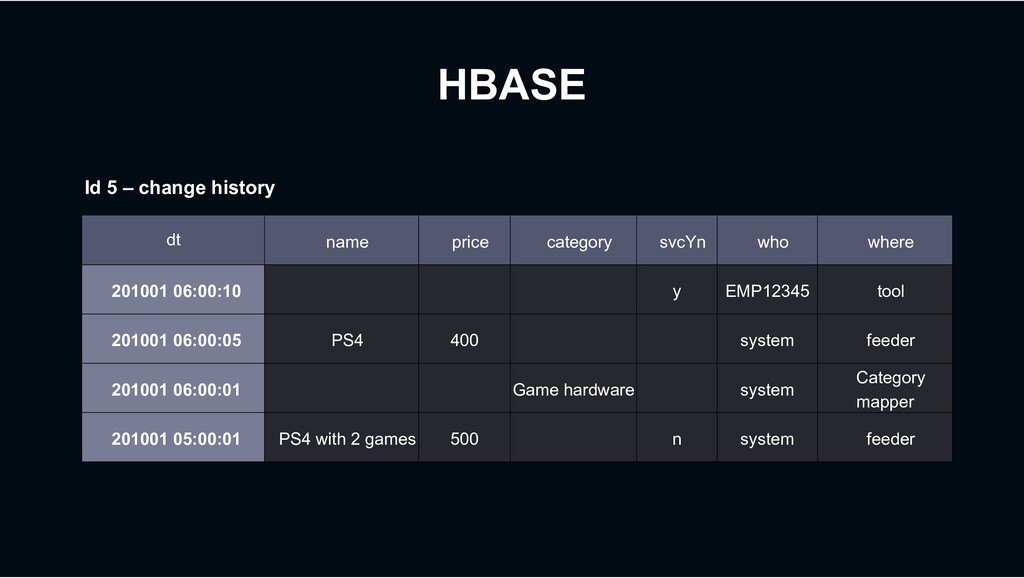
HBASE dt name price category svcYn who where 201001 06:00:10
y EMP12345 tool 201001 06:00:05 PS4 400 system feeder 201001 06:00:01 Game hardware system Category mapper 201001 05:00:01 PS4 with 2 games 500 n system feeder Id 5 – change history -
HBASE dt name price category svcYn who where 201001 06:00:10
y EMP12345 tool 201001 06:00:05 PS4 400 system feeder 201001 06:00:01 Game hardware system Category mapper 201001 05:00:01 PS4 with 2 games 500 n system feeder Id 5 – change history