Share
Embed
Introduction of LINE’s initiatives in the field of Artificial Intelligence
Masahito Togami (Manager of Speech Team, LINE Corporation)
Industrial Day at IJCAI-PRICAI Yokohama2020
https://ijcai20.org/industry-day/
LINE Developers
February 22, 2021
Transcript
30 slides
-
Masahito Togami, Ph.D. / LINE Speech Team Introduction of LINE's
initiatives in the field of Artificial Intelligence -
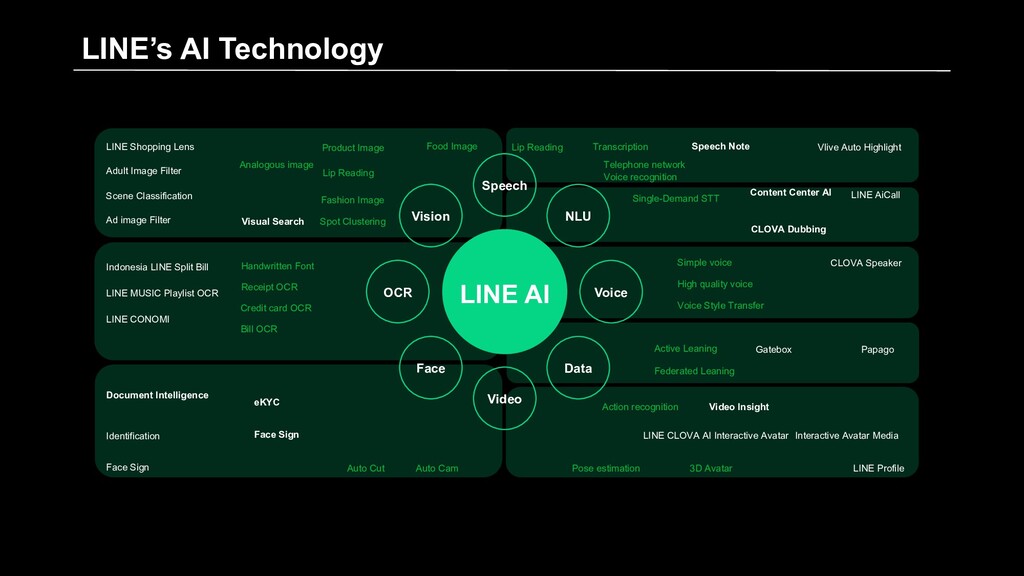
LINE AI Speech Video Voice NLU Data OCR Vision Face
LINE Shopping Lens Adult Image Filter Scene Classification Ad image Filter Visual Search Analogous image Product Image Lip Reading Fashion Image Spot Clustering Food Image Indonesia LINE Split Bill LINE MUSIC Playlist OCR LINE CONOMI Handwritten Font Receipt OCR Credit card OCR Bill OCR Document Intelligence Identification Face Sign eKYC Face Sign Auto Cut Auto Cam Transcription Telephone network Voice recognition Single-Demand STT Simple voice High quality voice Voice Style Transfer Active Leaning Federated Leaning Action recognition Pose estimation Speech Note Vlive Auto Highlight Content Center AI CLOVA Dubbing LINE AiCall CLOVA Speaker Gatebox Papago Video Insight LINE CLOVA AI Interactive Avatar Interactive Avatar Media 3D Avatar LINE Profile Lip Reading LINE’s AI Technology -
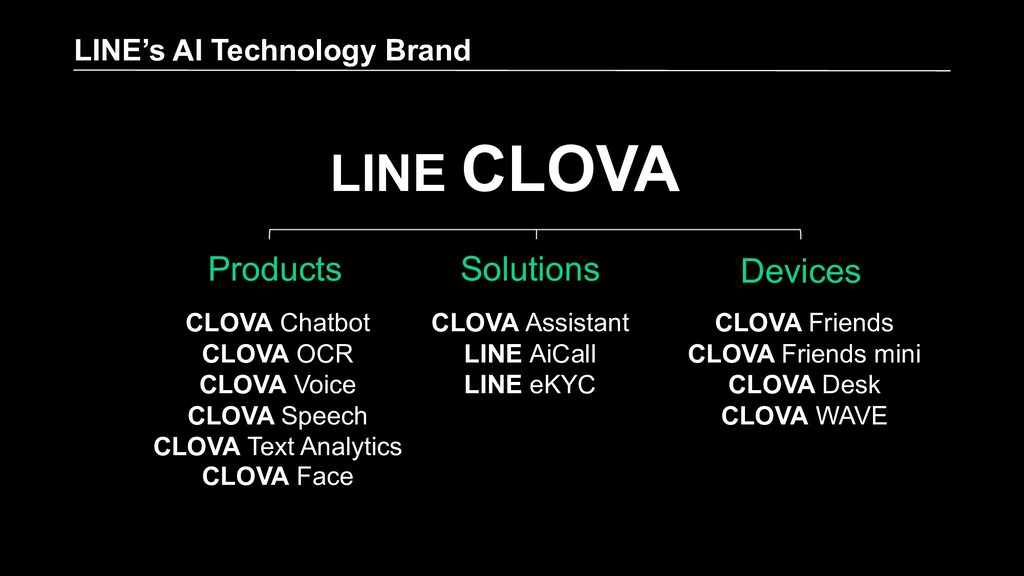
LINE CLOVA Products CLOVA Chatbot CLOVA OCR CLOVA Voice CLOVA
Speech CLOVA Text Analytics CLOVA Face CLOVA Assistant LINE AiCall LINE eKYC Solutions Devices CLOVA Friends CLOVA Friends mini CLOVA Desk CLOVA WAVE LINE’s AI Technology Brand -
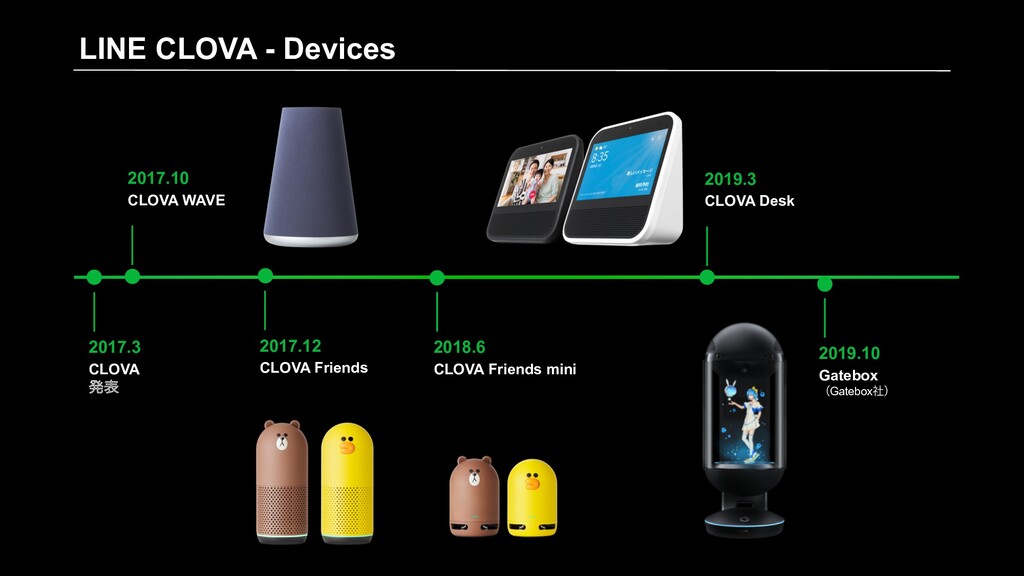
2017.3 CLOVA ൃද 2017.12 CLOVA Friends 2019.3 CLOVA Desk 2018.6
CLOVA Friends mini 2017.10 CLOVA WAVE 2019.10 Gatebox ʢGateboxࣾʣ LINE CLOVA - Devices -
LINE Publication and speech research Speech processing DCASE2020 Task4 Winner
with Nagoya University and Johns Hopkins University4 Parallel WaveGAN: Fast and High-Quality GPU Text-to-Speech DNN based speech source separation Differential Privacy Differentially Private Deep Generative Models Image processing Neural Implicit Embedding for Point Cloud Analysis 2019 (6): ICASSP (3)INTERSPEECH (2)WASPAA (1) 2020(27): ICASSP (11) EUSIPCO (3) INTERSPEECH (4) DCASE (1) APSIPA (3) CVPR (1) ICDE (1) IUI2021 (1) -
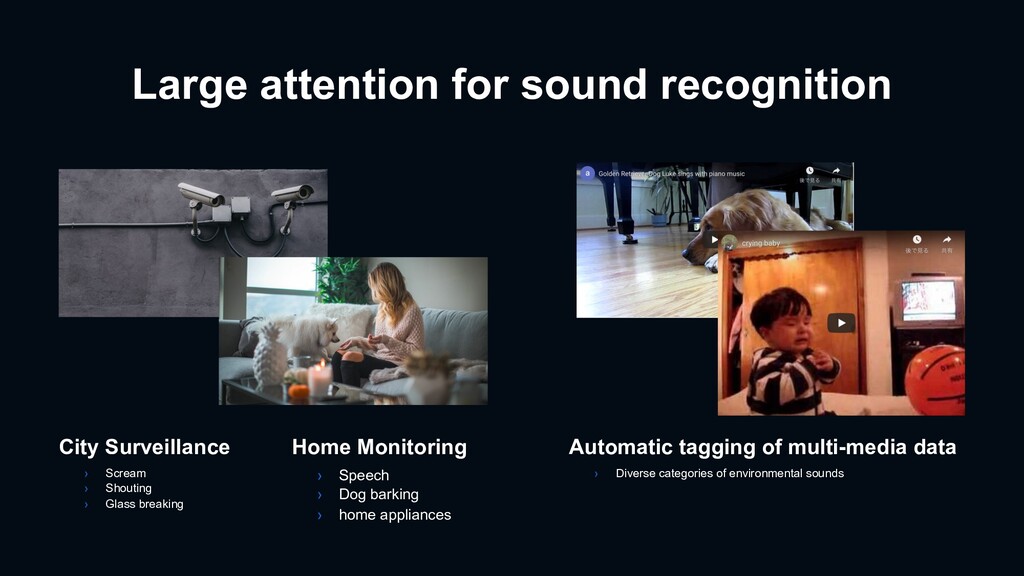
Large attention for sound recognition Automatic tagging of multi-media data
› Diverse categories of environmental sounds City Surveillance › Scream › Shouting › Glass breaking Home Monitoring › Speech › Dog barking › home appliances -
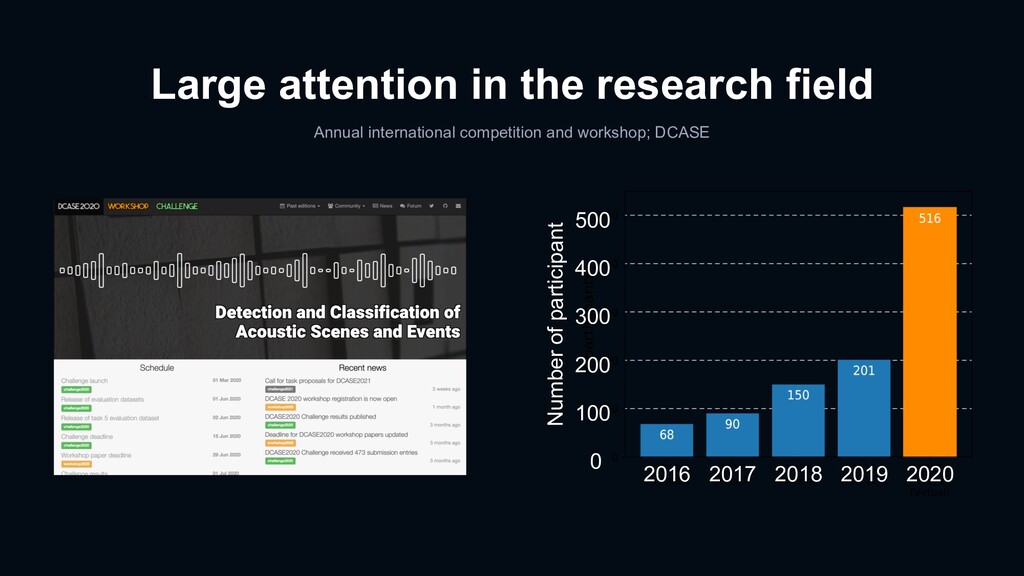
Large attention in the research field Annual international competition and
workshop; DCASE 2020 2019 2018 2017 2016 0 100 200 300 400 500 Number of participant -
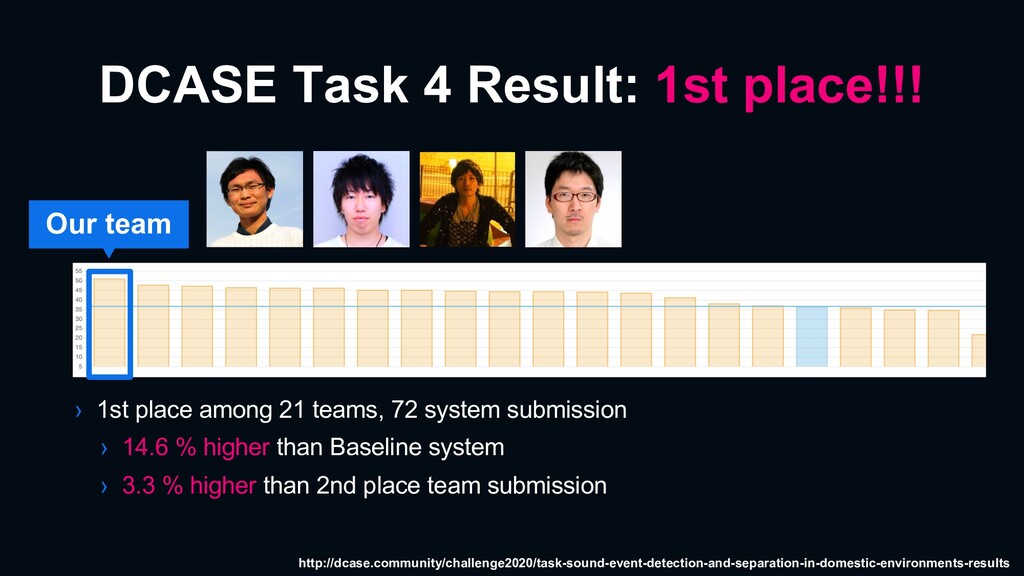
DCASE Task 4 Result: 1st place!!! › 1st place among
21 teams, 72 system submission › 14.6 % higher than Baseline system › 3.3 % higher than 2nd place team submission Our team http://dcase.community/challenge2020/task-sound-event-detection-and-separation-in-domestic-environments-results -
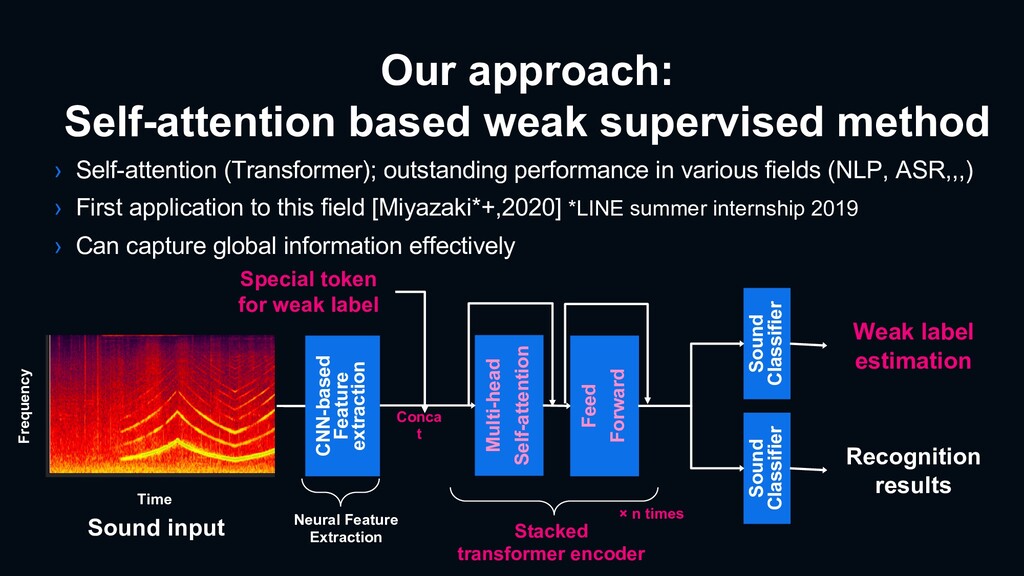
Our approach: Self-attention based weak supervised method › Self-attention (Transformer);
outstanding performance in various fields (NLP, ASR,,,) › First application to this field [Miyazaki*+,2020] *LINE summer internship 2019 › Can capture global information effectively Multi-head Self-attention Sound input Time Frequency Sound Classifier Weak label estimation Neural Feature Extraction Stacked transformer encoder Feed Forward Sound Classifier Recognition results Special token for weak label × n times Conca t CNN-based Feature extraction -
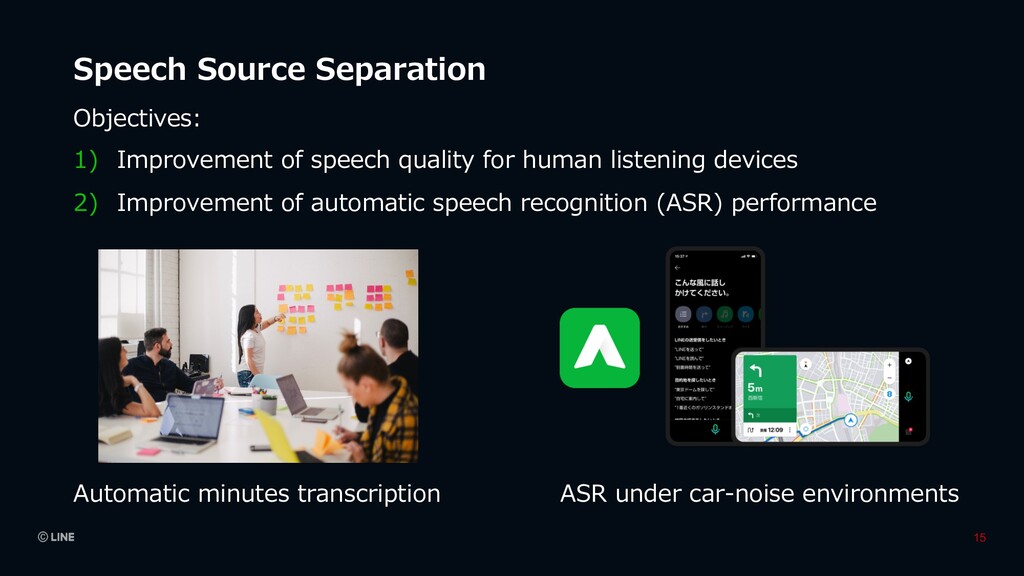
Speech Source Separation Objectives: 1) Improvement of speech quality for
human listening devices 2) Improvement of automatic speech recognition (ASR) performance Automatic minutes transcription ASR under car-noise environments -
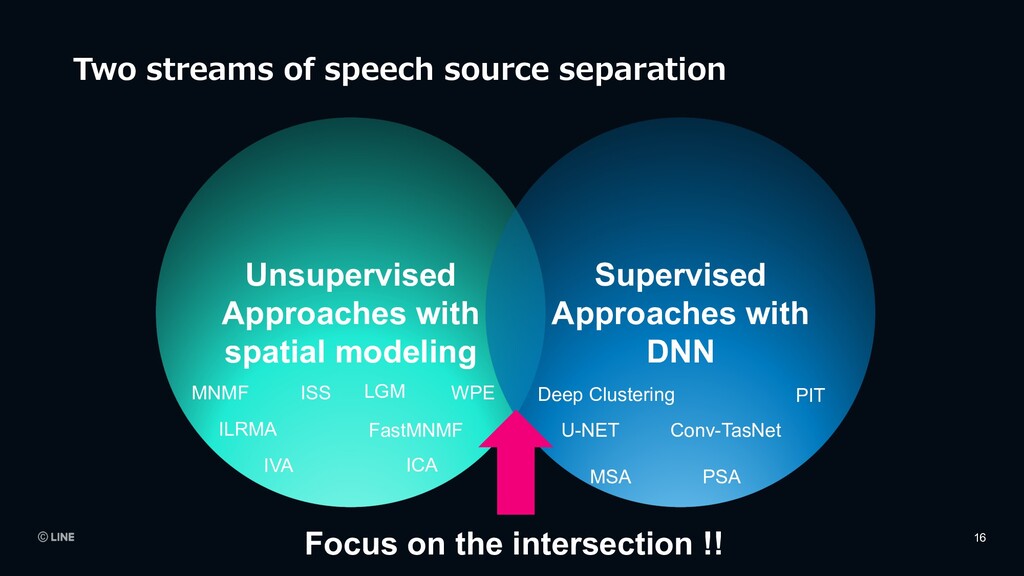
16 Two streams of speech source separation Unsupervised Approaches with
spatial modeling ICA IVA ILRMA WPE MNMF FastMNMF ISS LGM Supervised Approaches with DNN Deep Clustering PIT U-NET Conv-TasNet PSA MSA Focus on the intersection !! -
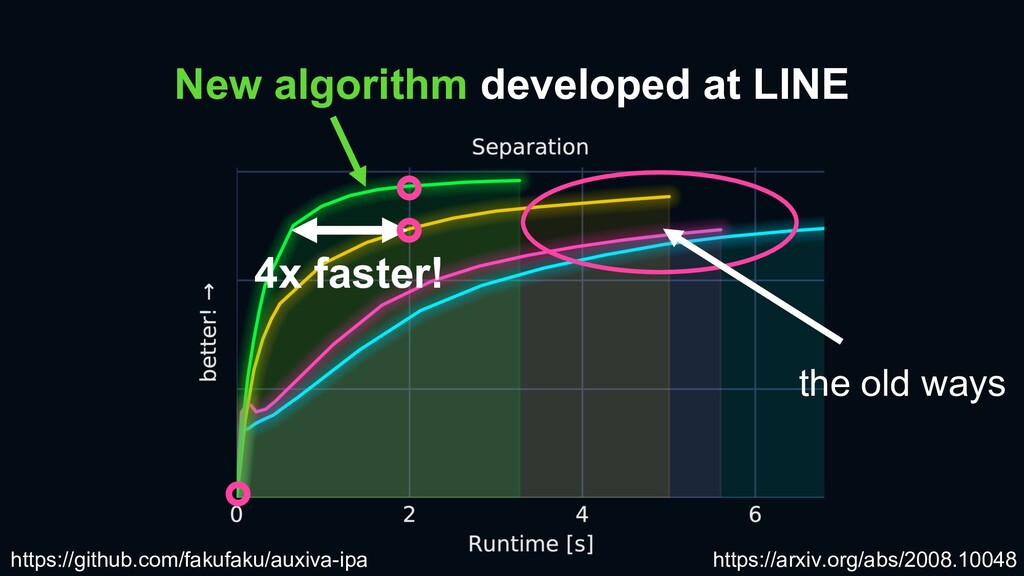
New algorithm developed at LINE the old ways https://arxiv.org/abs/2008.10048 4x
faster! https://github.com/fakufaku/auxiva-ipa -
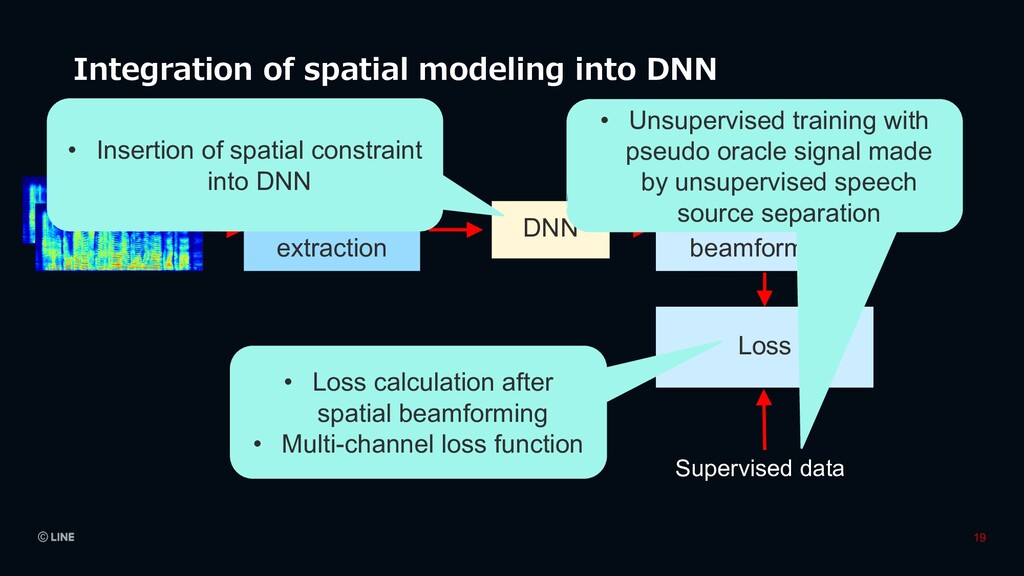
Integration of spatial modeling into DNN Feature extraction DNN Spatial
beamforming Loss Supervised data • Loss calculation after spatial beamforming • Multi-channel loss function • Insertion of spatial constraint into DNN • Unsupervised training with pseudo oracle signal made by unsupervised speech source separation -
Unsupervised DNN training [Togami ICASSP2020] Speech source model Spatial model
estimation Separated signal and estimated variance Back Propagation Non-DNN speech source separation Separated signal and estimated variance Loss Non-DNN speech source separation is utilized as a pseudo clean signal generator ! Deep Neural Network -
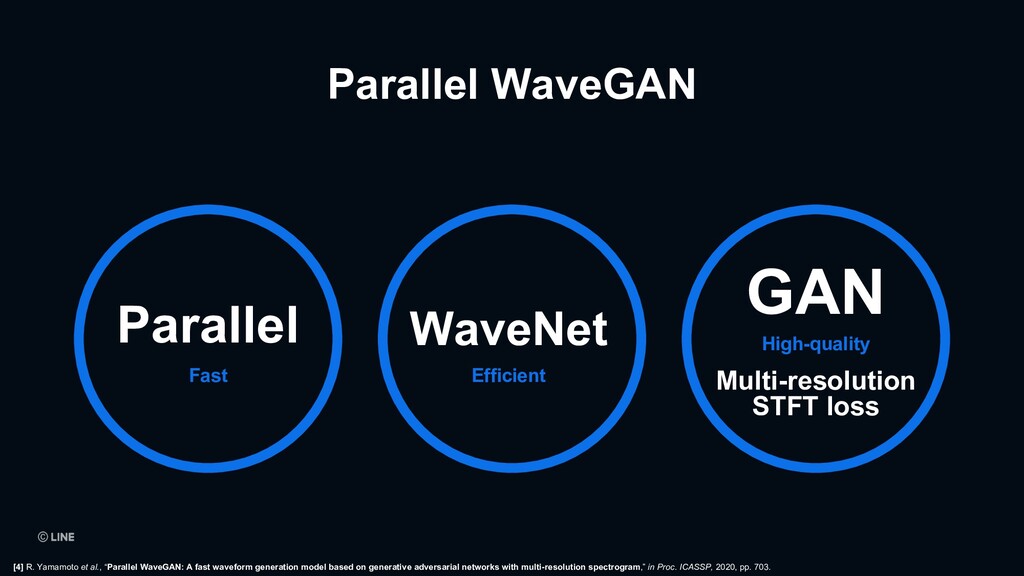
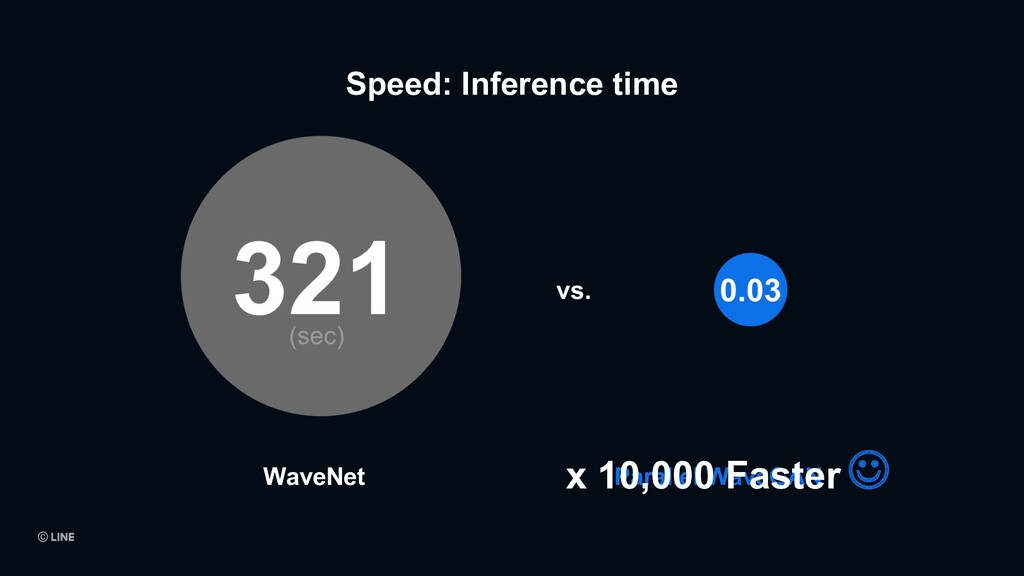
Fast Parallel High-quality GAN Efficient WaveNet Multi-resolution STFT loss Parallel
WaveGAN [4] R. Yamamoto et al., “Parallel WaveGAN: A fast waveform generation model based on generative adversarial networks with multi-resolution spectrogram,” in Proc. ICASSP, 2020, pp. 703. -
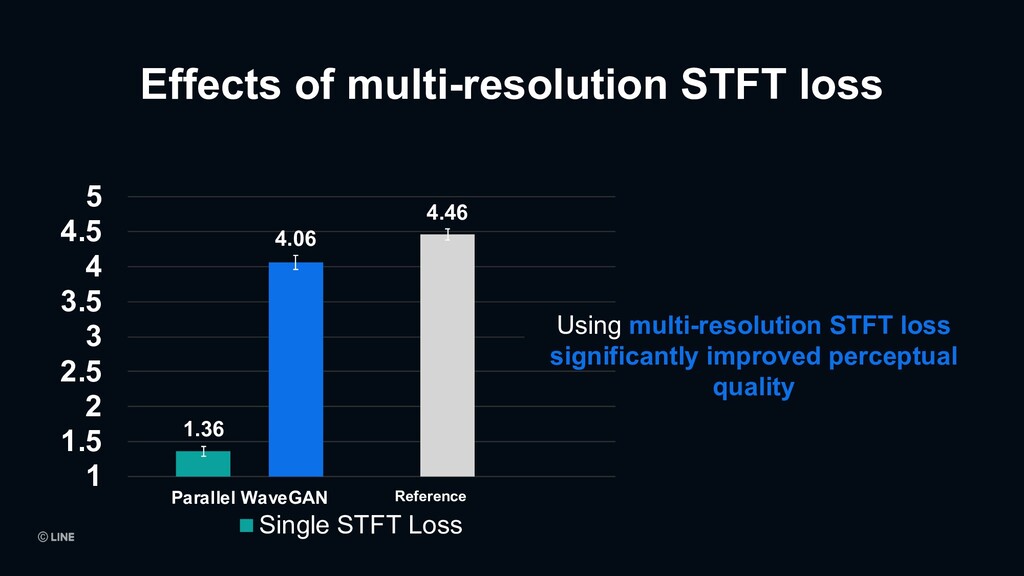
1.36 4.46 4.06 1 1.5 2 2.5 3 3.5 4
4.5 5 Parallel WaveGAN Single STFT Loss Using multi-resolution STFT loss significantly improved perceptual quality Effects of multi-resolution STFT loss Reference -
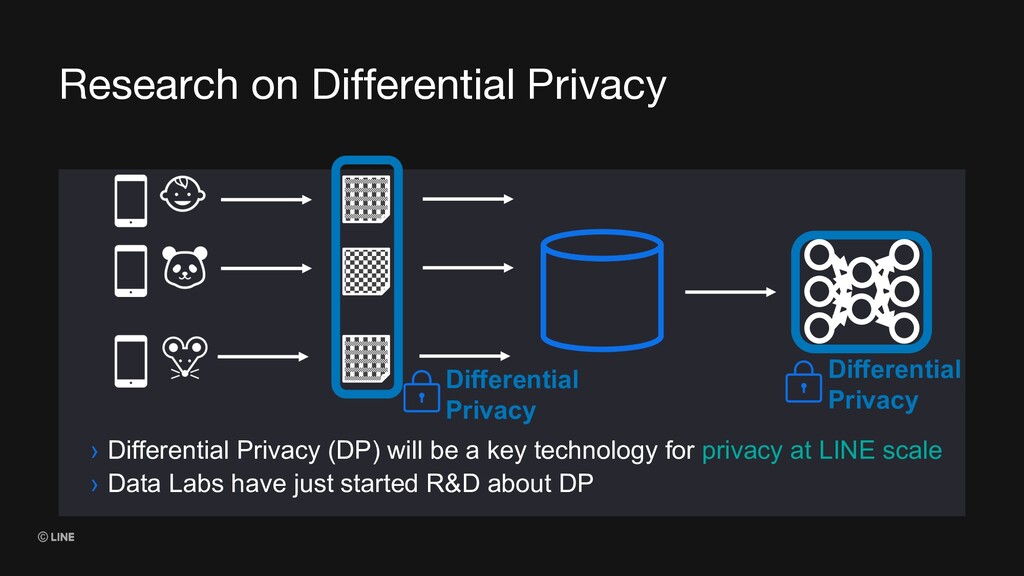
Research on Differential Privacy Differential Privacy Differential Privacy › Differential
Privacy (DP) will be a key technology for privacy at LINE scale › Data Labs have just started R&D about DP -
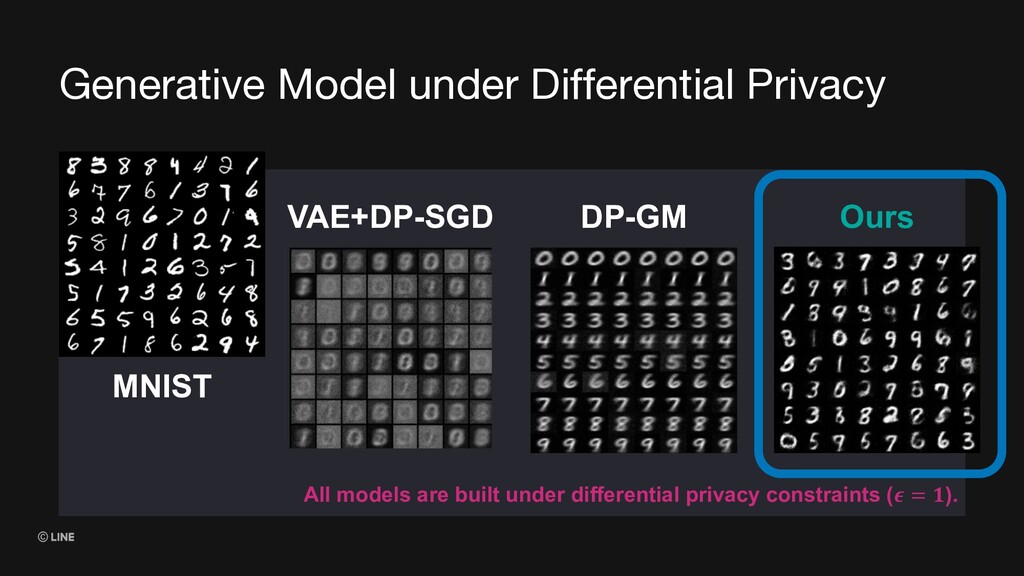
Generative Model under Differential Privacy MNIST VAE+DP-SGD DP-GM Ours All
models are built under differential privacy constraints (! = #). -
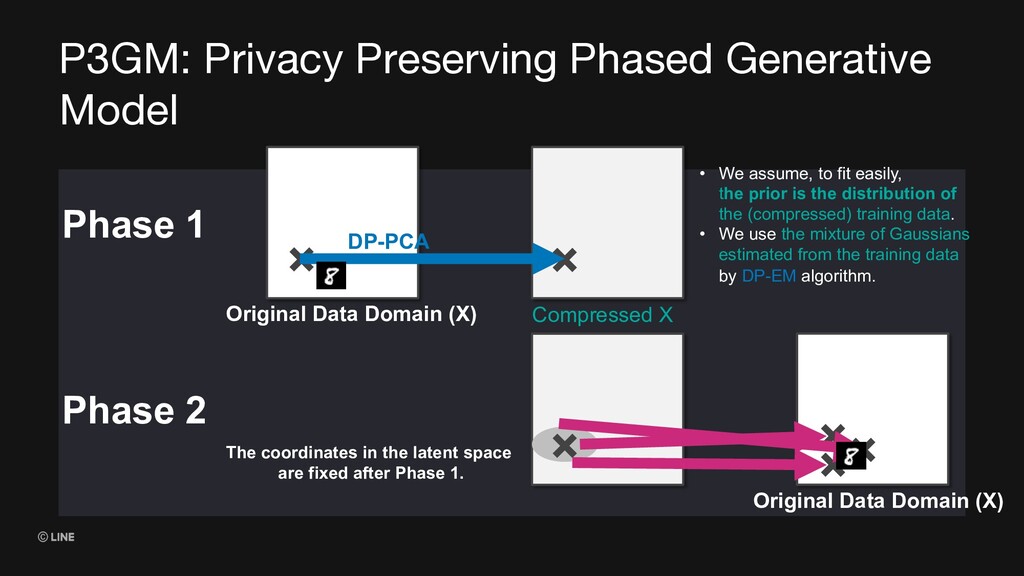
P3GM: Privacy Preserving Phased Generative Model × Original Data Domain
(X) • We assume, to fit easily, the prior is the distribution of the (compressed) training data. • We use the mixture of Gaussians estimated from the training data by DP-EM algorithm. × DP-PCA × × × × Original Data Domain (X) Compressed X Phase 1 Phase 2 The coordinates in the latent space are fixed after Phase 1.