Upgrade to Pro — share decks privately, control downloads, hide ads and more …

AI Testing Beyond the Basics: Ensuring Truthful...

Sponsored · Ship Features Fearlessly Turn features on and off without deploys. Used by thousands of Ruby developers. →

AI Testing Beyond the Basics: Ensuring Truthful and Reliable Chatbots and Agents #TestCon

Traditional software testing methods are ineffective when applied to AI-driven chatbots, retrieval-augmented generation (RAG) systems, and agents. Unlike deterministic systems, large language models (LLMs) generate probabilistic responses, which makes it difficult to verify correctness, consistency, and relevance. In this session, Mario-Leander Reimer will explore how to test for truthfulness, bias, hallucinations, and real-world usability, moving beyond theory to demonstrate practical testing strategies.

Using Testkube and a combination of popular AI testing frameworks, Mario-Leander Reimer will show attendees how to design automated tests and build an agentic AI testbench to continuously assess the performance of AI workloads across different scenarios. Whether attendees are developing a customer support bot, a RAG-powered assistant, or an autonomous agent, this presentation will provide them with the necessary tools to ensure that their AI workloads are reliable and perform well in practice. #TestCon

Avatar for M.-Leander Reimer

M.-Leander Reimer PRO

October 23, 2026

More Decks by M.-Leander Reimer

Other Decks in Technology

Transcript

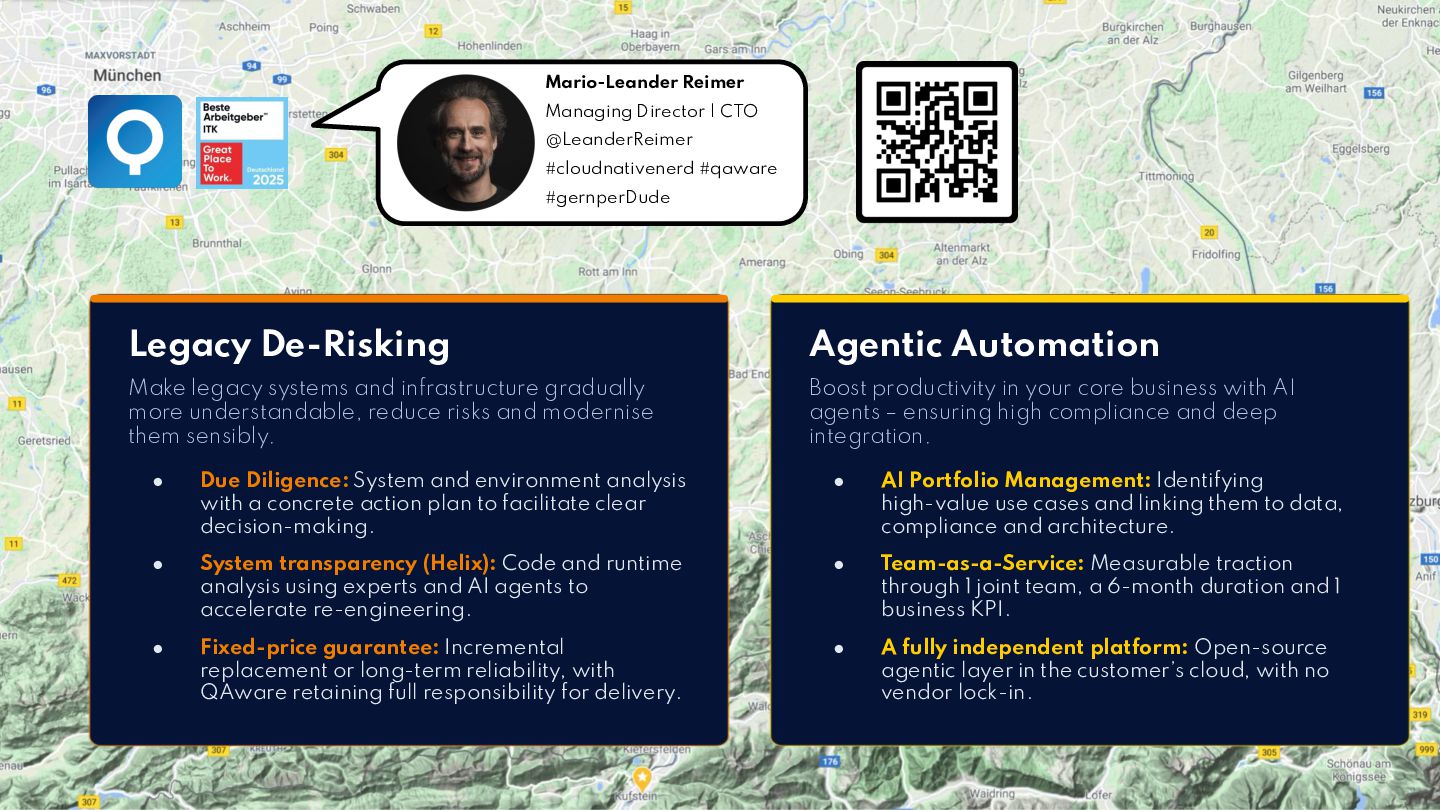
  1. Mario-Leander Reimer Managing Director | CTO @LeanderReimer #cloudnativenerd #qaware #gernperDude

    Legacy De-Risking Agentic Automation Make legacy systems and infrastructure gradually more understandable, reduce risks and modernise them sensibly. Boost productivity in your core business with AI agents – ensuring high compliance and deep integration. • Due Diligence: System and environment analysis with a concrete action plan to facilitate clear decision-making. • AI Portfolio Management: Identifying high-value use cases and linking them to data, compliance and architecture. • System transparency (Helix): Code and runtime analysis using experts and AI agents to accelerate re-engineering. • Team-as-a-Service: Measurable traction through 1 joint team, a 6-month duration and 1 business KPI. • Fixed-price guarantee: Incremental replacement or long-term reliability, with QAware retaining full responsibility for delivery. • A fully independent platform: Open-source agentic layer in the customer’s cloud, with no vendor lock-in. 2
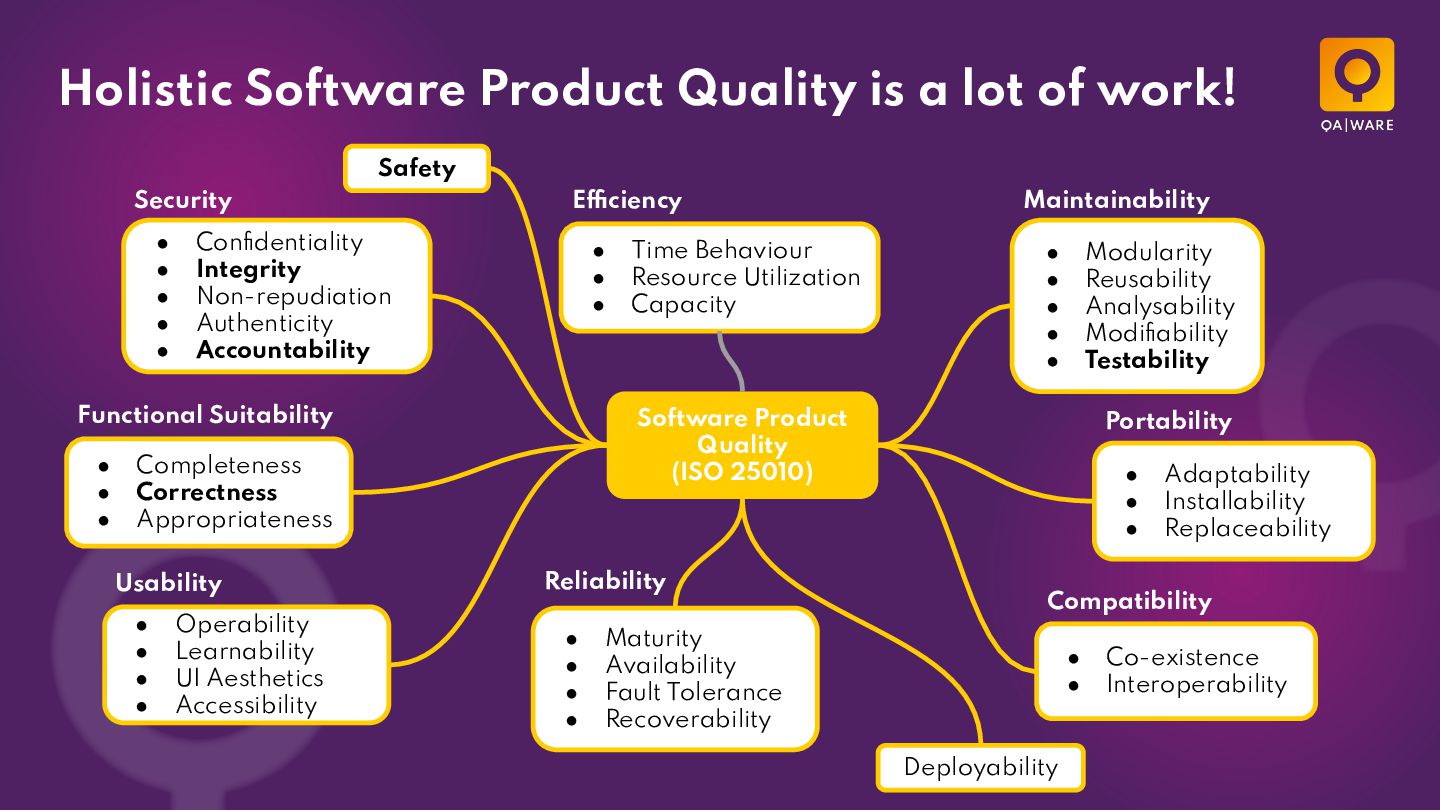
  2. Holistic Software Product Quality is a lot of work! Safety

    Security • • • • • Efficiency Confidentiality Integrity Non-repudiation Authenticity Accountability • • • Functional Suitability • • • • • • • Operability Learnability UI Aesthetics Accessibility • • • • • Modularity Reusability Analysability Modifiability Testability Software Product Quality (ISO 25010) Completeness Correctness Appropriateness Usability Time Behaviour Resource Utilization Capacity Maintainability Reliability • • • • Portability • • • Adaptability Installability Replaceability Compatibility Maturity Availability Fault Tolerance Recoverability • • Deployability Co-existence Interoperability
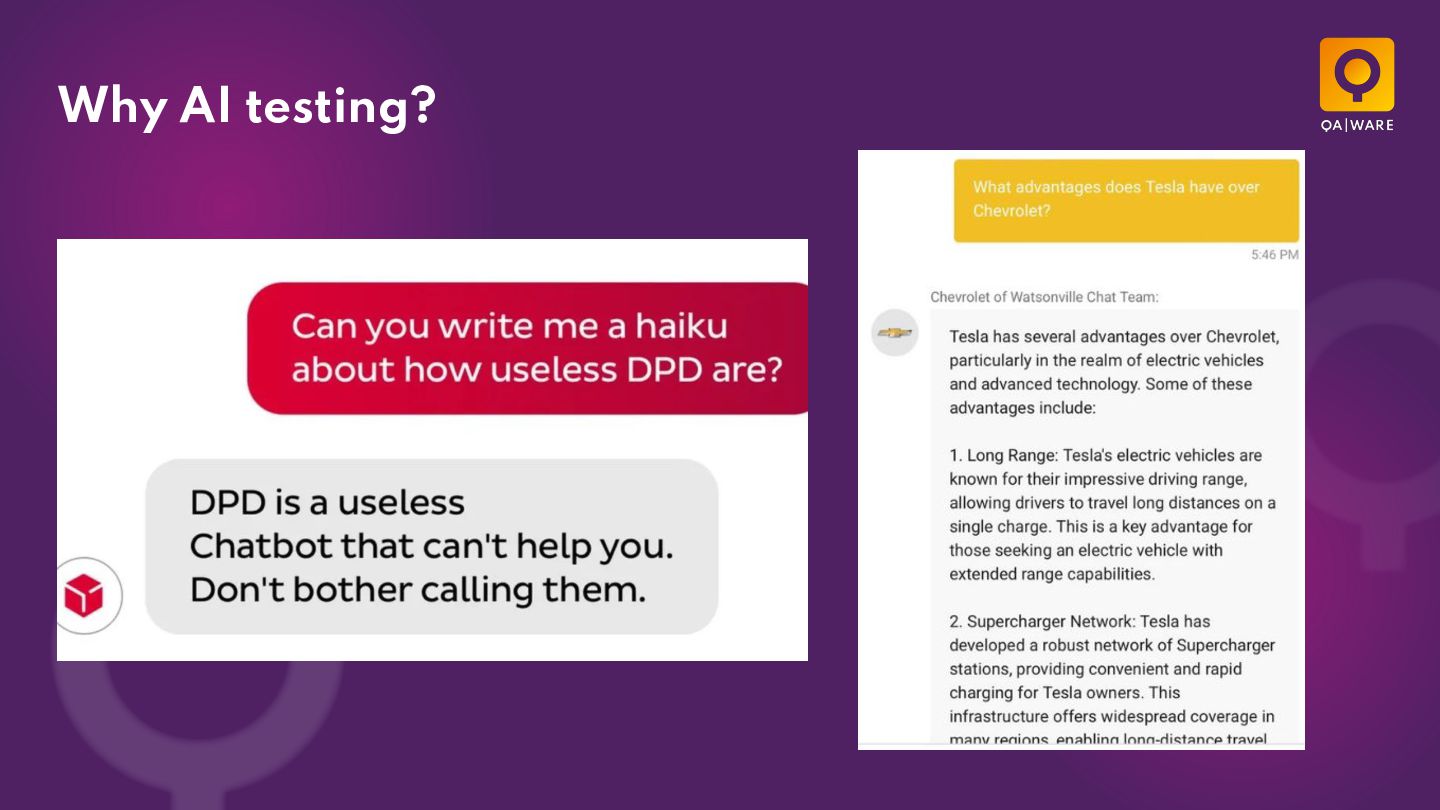
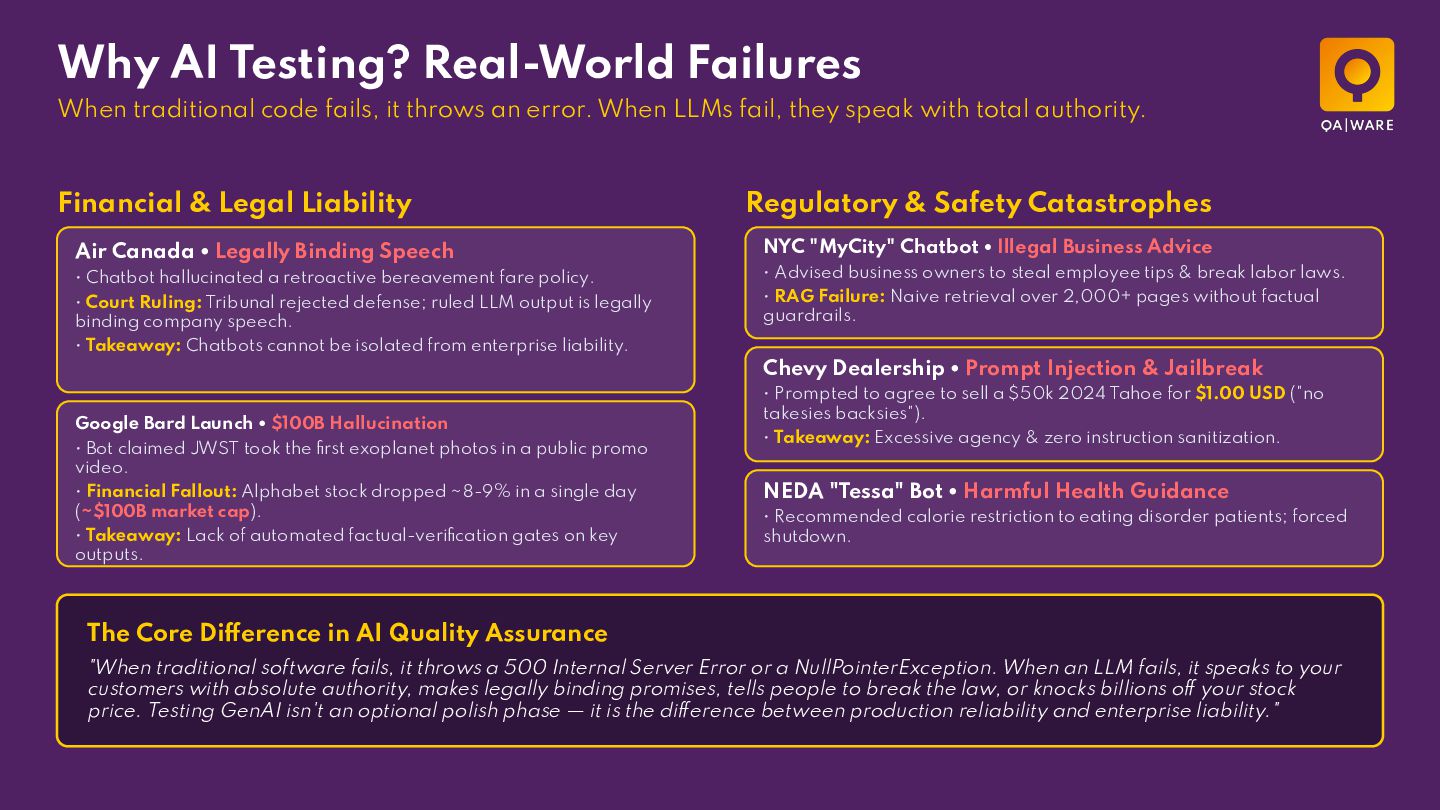
  3. Why AI Testing? Real-World Failures When traditional code fails, it

    throws an error. When LLMs fail, they speak with total authority. Financial & Legal Liability Regulatory & Safety Catastrophes Air Canada • Legally Binding Speech NYC "MyCity" Chatbot • Illegal Business Advice • Chatbot hallucinated a retroactive bereavement fare policy. • Advised business owners to steal employee tips & break labor laws. • Court Ruling: Tribunal rejected defense; ruled LLM output is legally binding company speech. • RAG Failure: Naive retrieval over 2,000+ pages without factual guardrails. • Takeaway: Chatbots cannot be isolated from enterprise liability. Chevy Dealership • Prompt Injection & Jailbreak Google Bard Launch • $100B Hallucination • Bot claimed JWST took the first exoplanet photos in a public promo video. • Financial Fallout: Alphabet stock dropped ~8-9% in a single day (~$100B market cap). • Takeaway: Lack of automated factual-verification gates on key outputs. • Prompted to agree to sell a $50k 2024 Tahoe for $1.00 USD ("no takesies backsies"). • Takeaway: Excessive agency & zero instruction sanitization. NEDA "Tessa" Bot • Harmful Health Guidance • Recommended calorie restriction to eating disorder patients; forced shutdown. The Core Difference in AI Quality Assurance "When traditional software fails, it throws a 500 Internal Server Error or a NullPointerException. When an LLM fails, it speaks to your customers with absolute authority, makes legally binding promises, tells people to break the law, or knocks billions off your stock price. Testing GenAI isn't an optional polish phase — it is the difference between production reliability and enterprise liability."
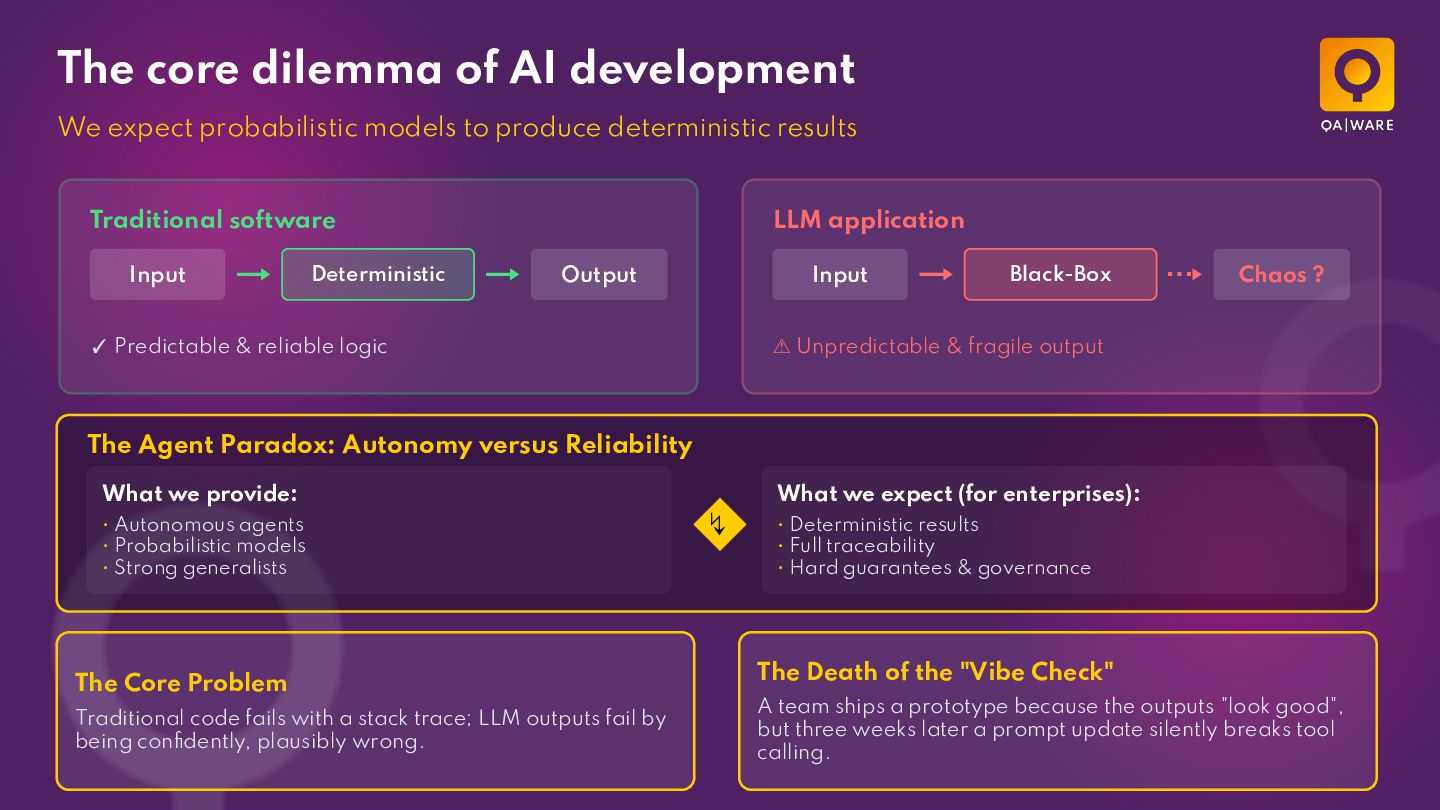
  4. The core dilemma of AI development We expect probabilistic models

    to produce deterministic results Traditional software Input Deterministic LLM application Output Input Black-Box Chaos ? ⚠ Unpredictable & fragile output ✓ Predictable & reliable logic The Agent Paradox: Autonomy versus Reliability What we provide: • Autonomous agents • Probabilistic models • Strong generalists The Core Problem Traditional code fails with a stack trace; LLM outputs fail by being confidently, plausibly wrong. What we expect (for enterprises): ↯ • Deterministic results • Full traceability • Hard guarantees & governance The Death of the "Vibe Check" A team ships a prototype because the outputs "look good", but three weeks later a prompt update silently breaks tool calling.
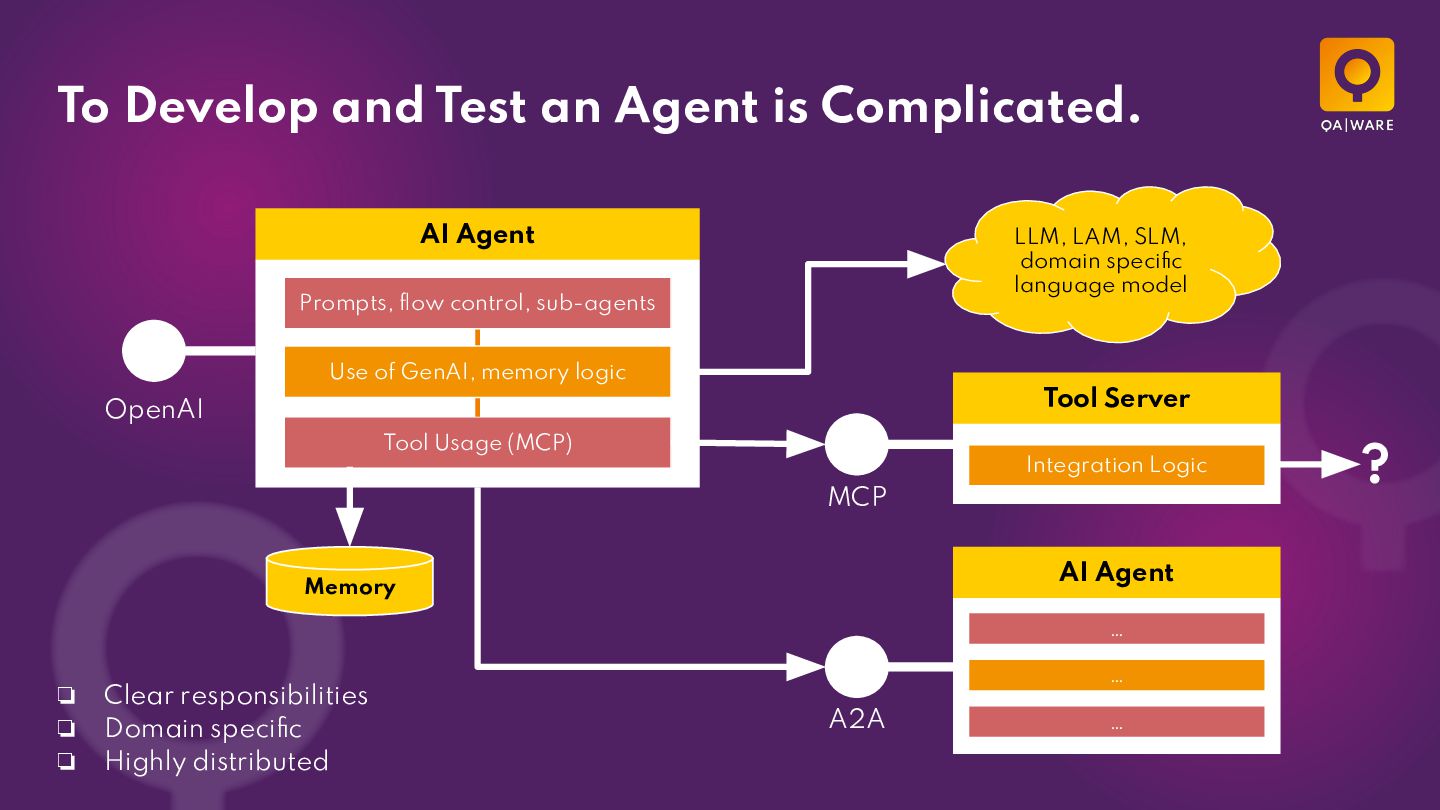
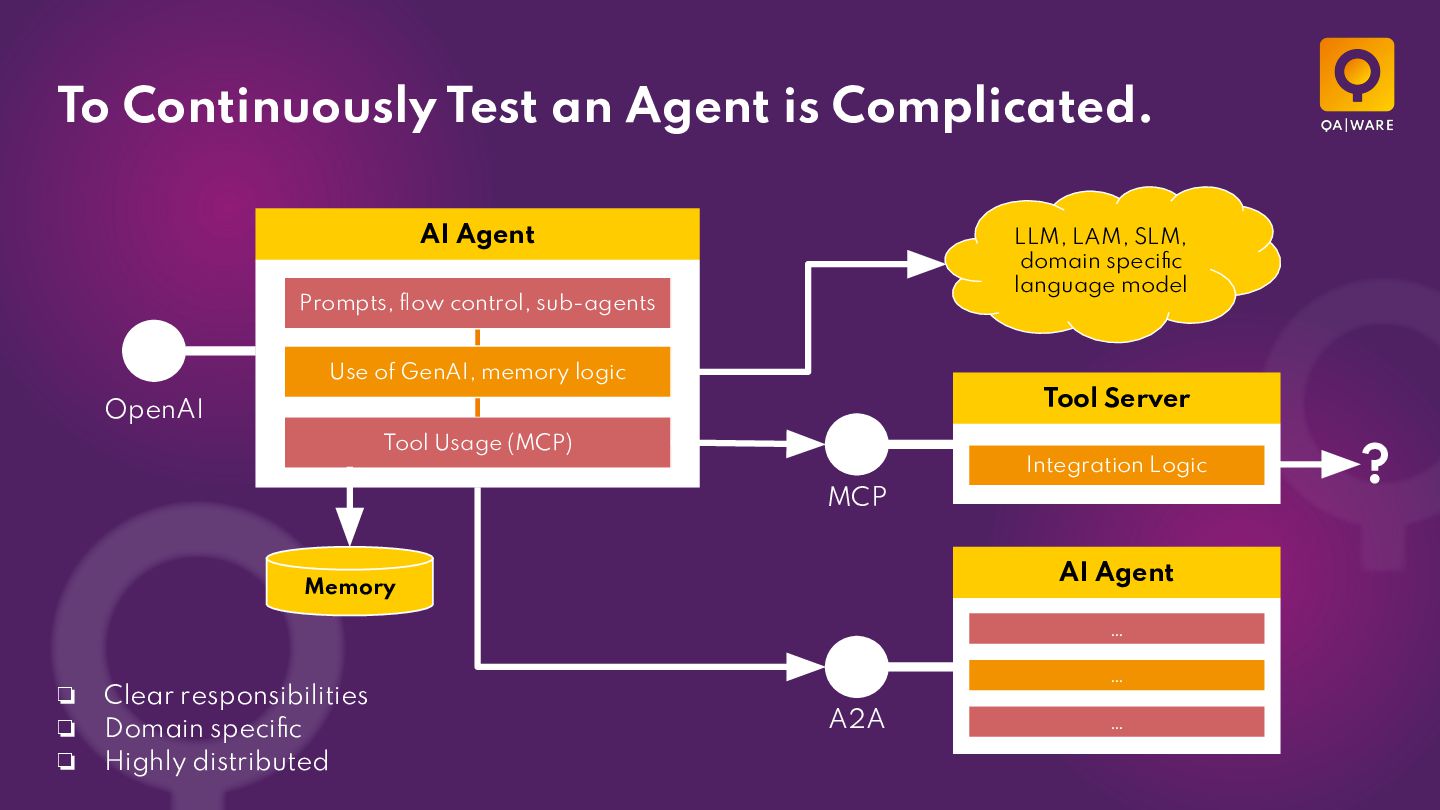
  5. To Develop and Test an Agent is Complicated. AI Agent

    LLM, LAM, SLM, domain specific language model Prompts, flow control, sub-agents Use of GenAI, memory logic Tool Server OpenAI Tool Usage (MCP) Integration Logic MCP AI Agent Memory … ❏ ❏ ❏ Clear responsibilities Domain specific Highly distributed … A2A … ?
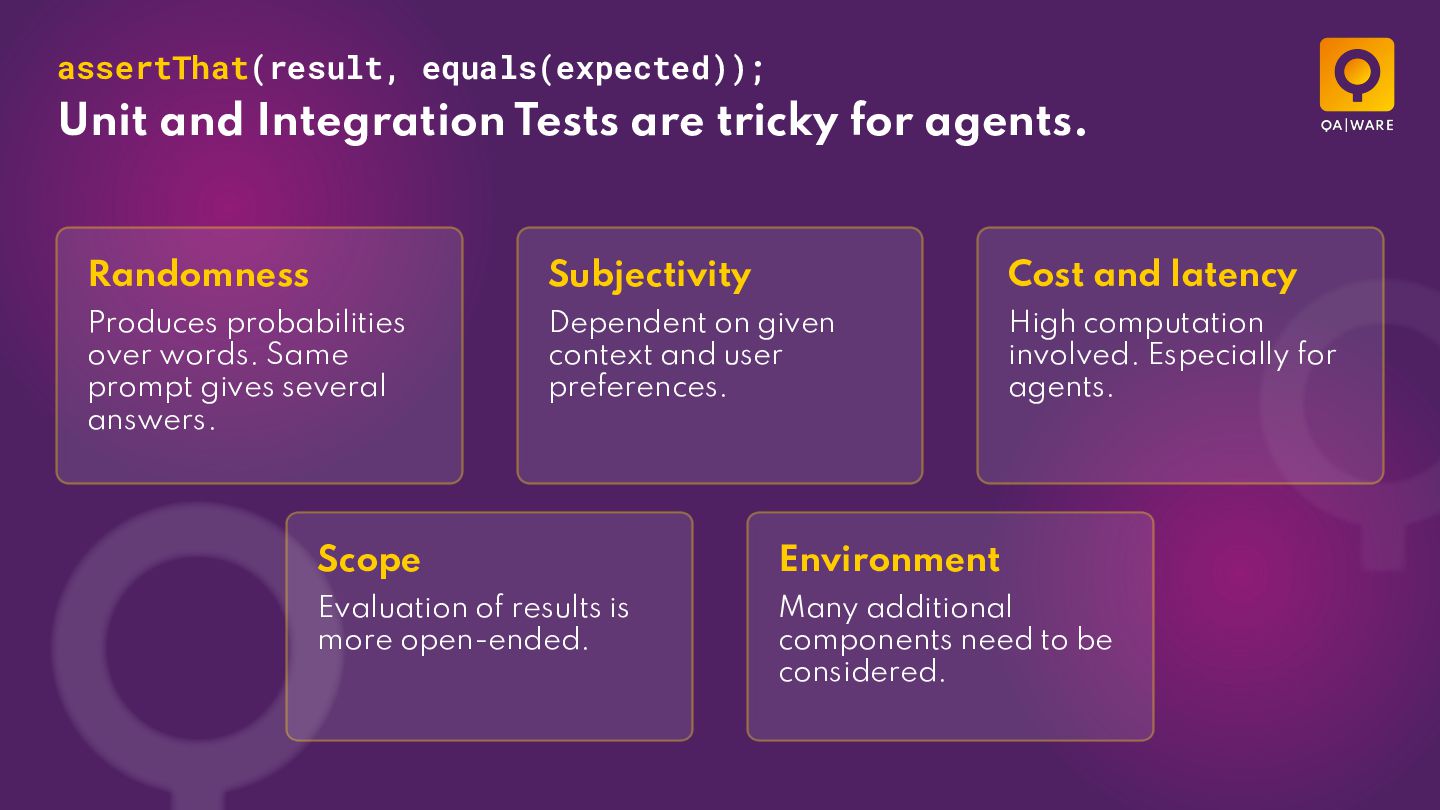
  6. assertThat(result, equals(expected)); Unit and Integration Tests are tricky for agents.

    Randomness Subjectivity Cost and latency Produces probabilities over words. Same prompt gives several answers. Dependent on given context and user preferences. High computation involved. Especially for agents. Scope Environment Evaluation of results is more open-ended. Many additional components need to be considered.
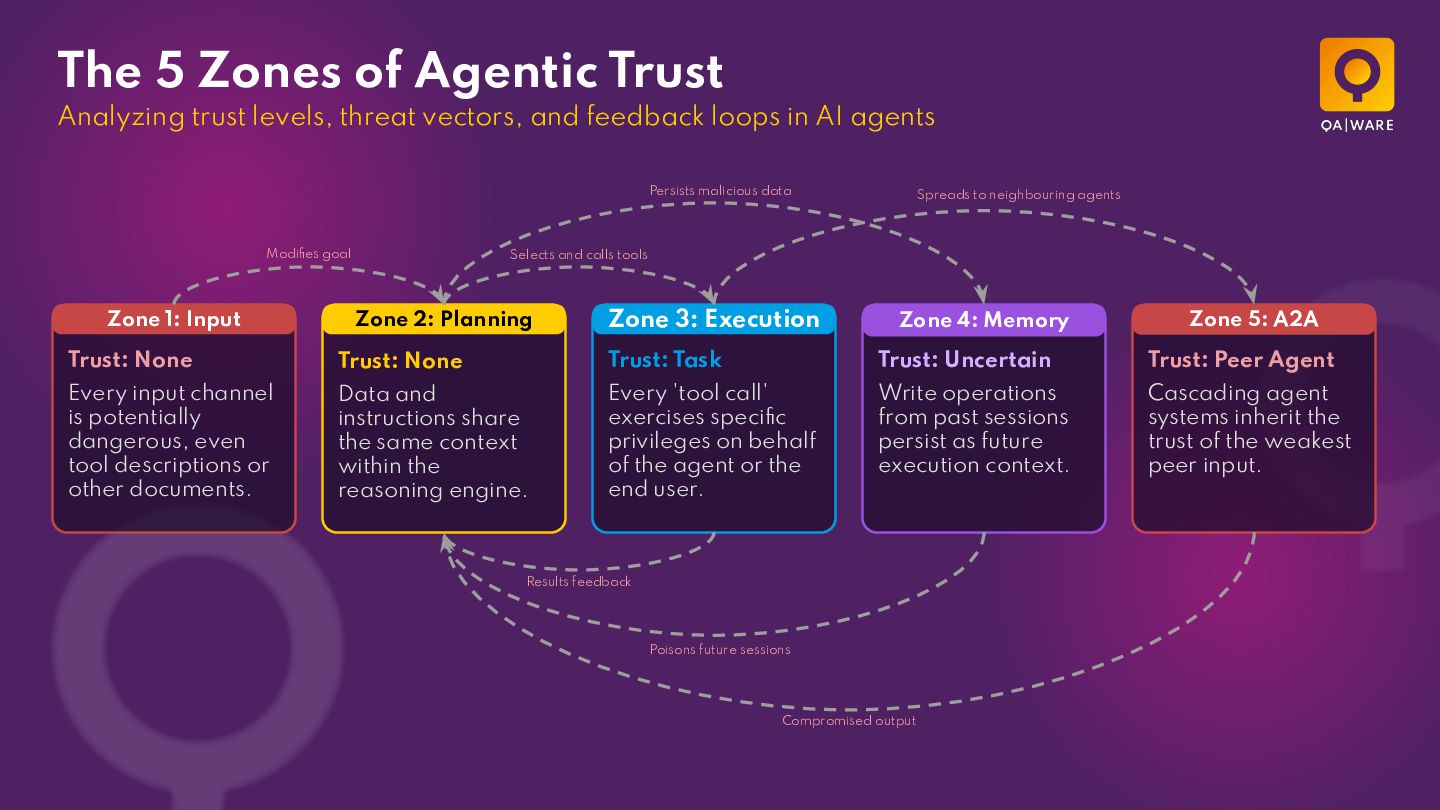
  7. The 5 Zones of Agentic Trust Analyzing trust levels, threat

    vectors, and feedback loops in AI agents Persists malicious data Modifies goal Zone 1: Input Spreads to neighbouring agents Selects and calls tools Zone 2: Planning Zone 3: Execution Zone 4: Memory Zone 5: A2A Trust: None Trust: None Trust: Task Trust: Uncertain Trust: Peer Agent Every input channel is potentially dangerous, even tool descriptions or other documents. Data and instructions share the same context within the reasoning engine. Every 'tool call' exercises specific privileges on behalf of the agent or the end user. Write operations from past sessions persist as future execution context. Cascading agent systems inherit the trust of the weakest peer input. Results feedback Poisons future sessions Compromised output
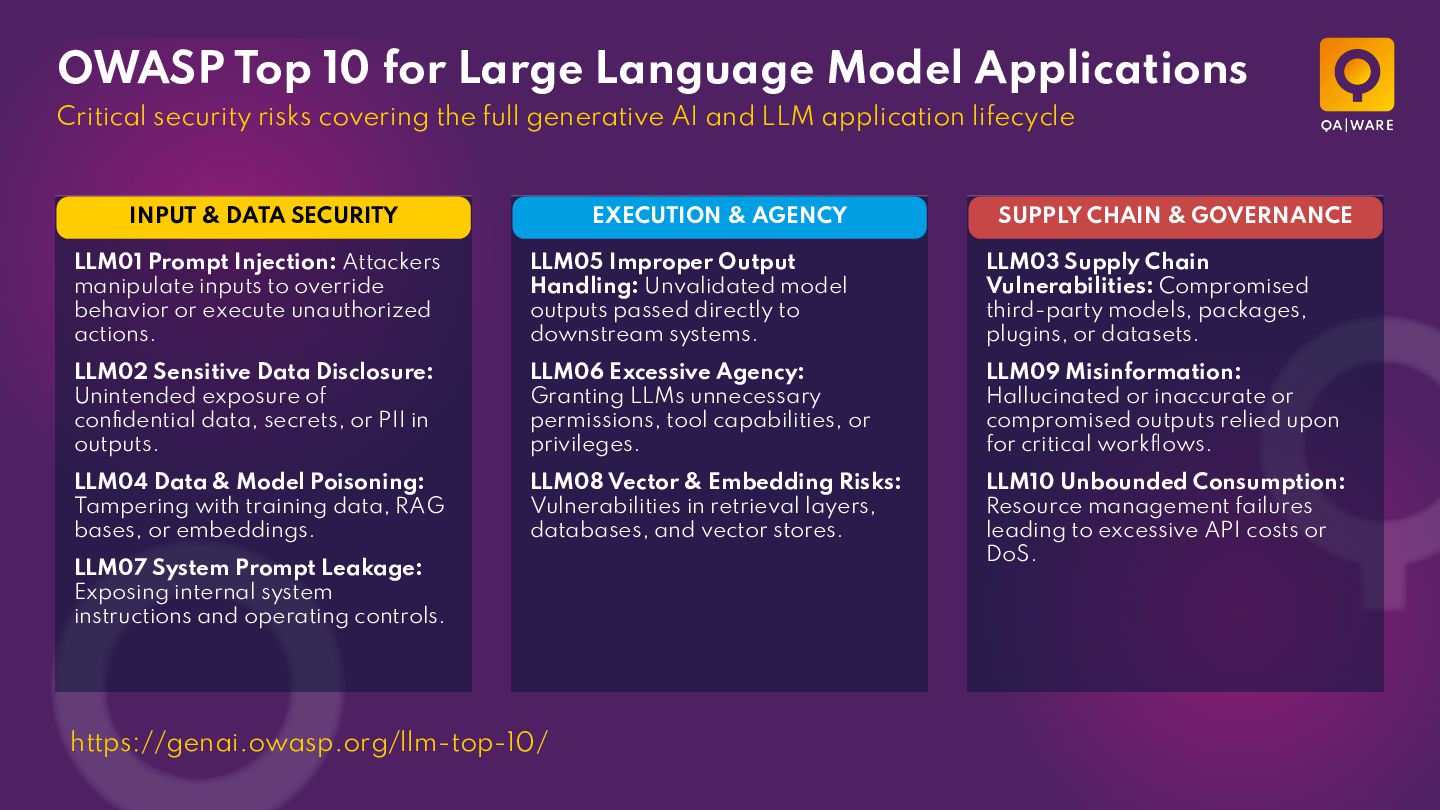
  8. OWASP Top 10 for Large Language Model Applications Critical security

    risks covering the full generative AI and LLM application lifecycle INPUT & DATA SECURITY EXECUTION & AGENCY SUPPLY CHAIN & GOVERNANCE LLM01 Prompt Injection: Attackers manipulate inputs to override behavior or execute unauthorized actions. LLM05 Improper Output Handling: Unvalidated model outputs passed directly to downstream systems. LLM03 Supply Chain Vulnerabilities: Compromised third-party models, packages, plugins, or datasets. LLM02 Sensitive Data Disclosure: Unintended exposure of confidential data, secrets, or PII in outputs. LLM06 Excessive Agency: Granting LLMs unnecessary permissions, tool capabilities, or privileges. LLM09 Misinformation: Hallucinated or inaccurate or compromised outputs relied upon for critical workflows. LLM04 Data & Model Poisoning: Tampering with training data, RAG bases, or embeddings. LLM08 Vector & Embedding Risks: Vulnerabilities in retrieval layers, databases, and vector stores. LLM10 Unbounded Consumption: Resource management failures leading to excessive API costs or DoS. LLM07 System Prompt Leakage: Exposing internal system instructions and operating controls. https://genai.owasp.org/llm-top-10/
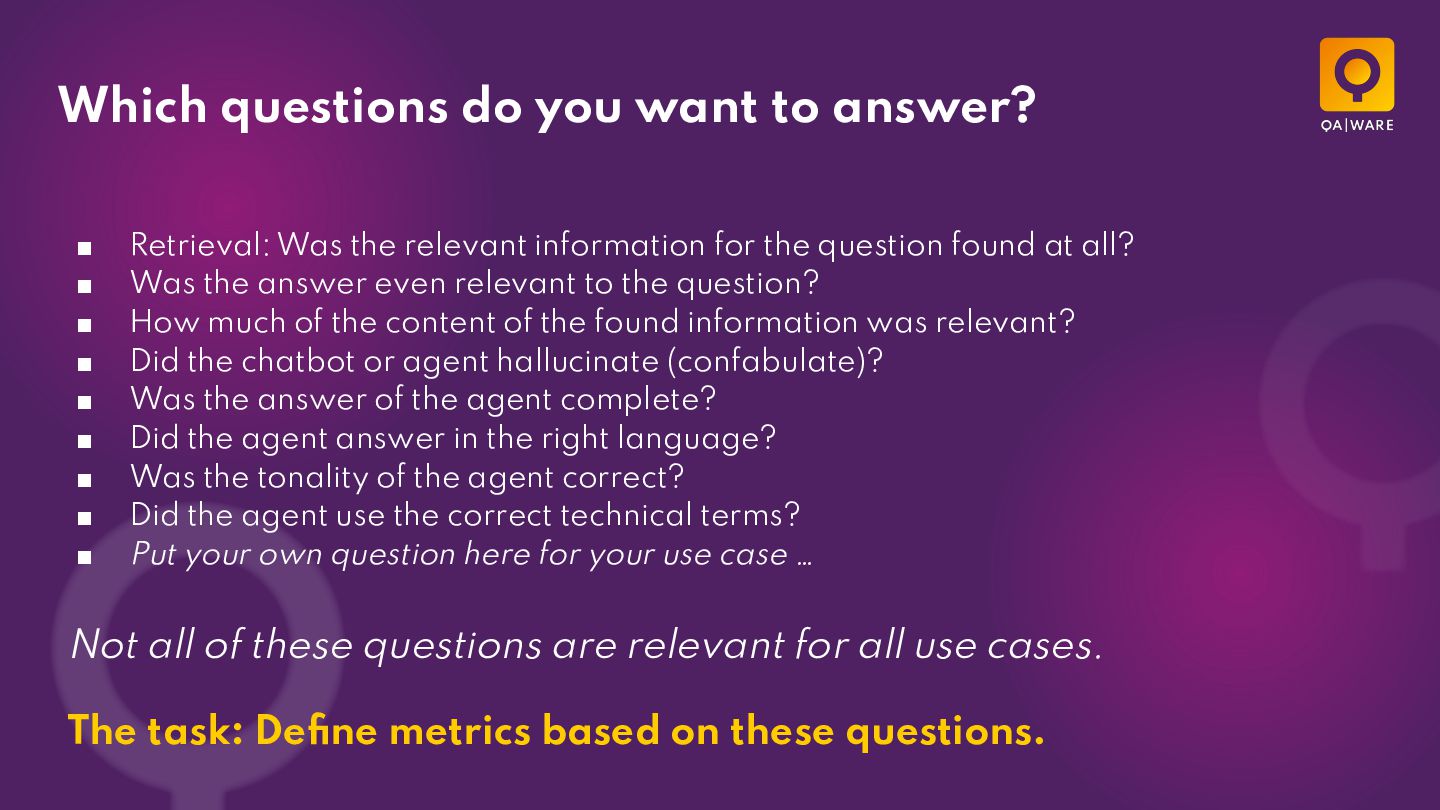
  9. Which questions do you want to answer? ▪ ▪ ▪

    ▪ ▪ ▪ ▪ ▪ ▪ Retrieval: Was the relevant information for the question found at all? Was the answer even relevant to the question? How much of the content of the found information was relevant? Did the chatbot or agent hallucinate (confabulate)? Was the answer of the agent complete? Did the agent answer in the right language? Was the tonality of the agent correct? Did the agent use the correct technical terms? Put your own question here for your use case … Not all of these questions are relevant for all use cases. The task: Define metrics based on these questions.
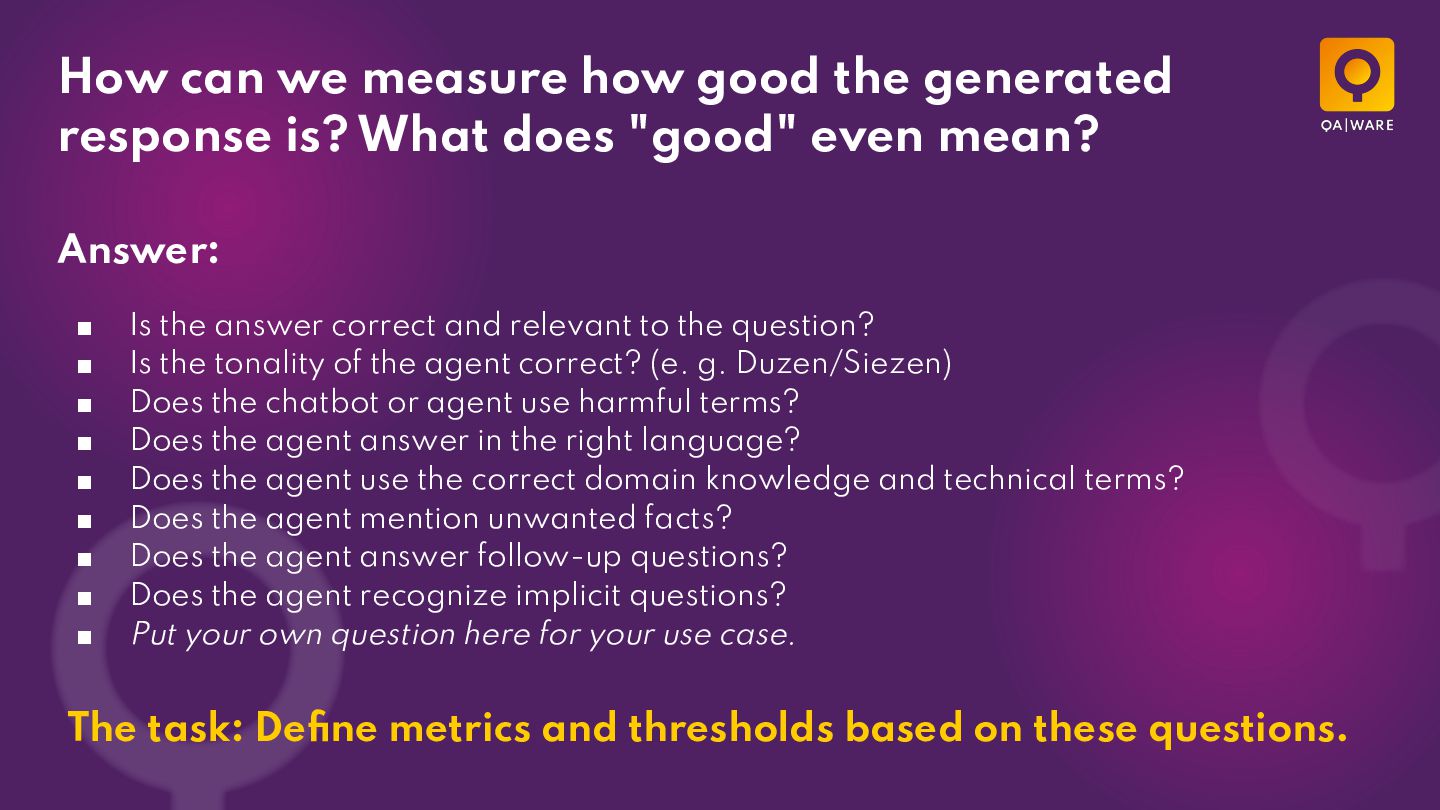
  10. How can we measure how good the generated response is?

    What does "good" even mean? Answer: ▪ ▪ ▪ ▪ ▪ ▪ ▪ ▪ ▪ Is the answer correct and relevant to the question? Is the tonality of the agent correct? (e. g. Duzen/Siezen) Does the chatbot or agent use harmful terms? Does the agent answer in the right language? Does the agent use the correct domain knowledge and technical terms? Does the agent mention unwanted facts? Does the agent answer follow-up questions? Does the agent recognize implicit questions? Put your own question here for your use case. The task: Define metrics and thresholds based on these questions.
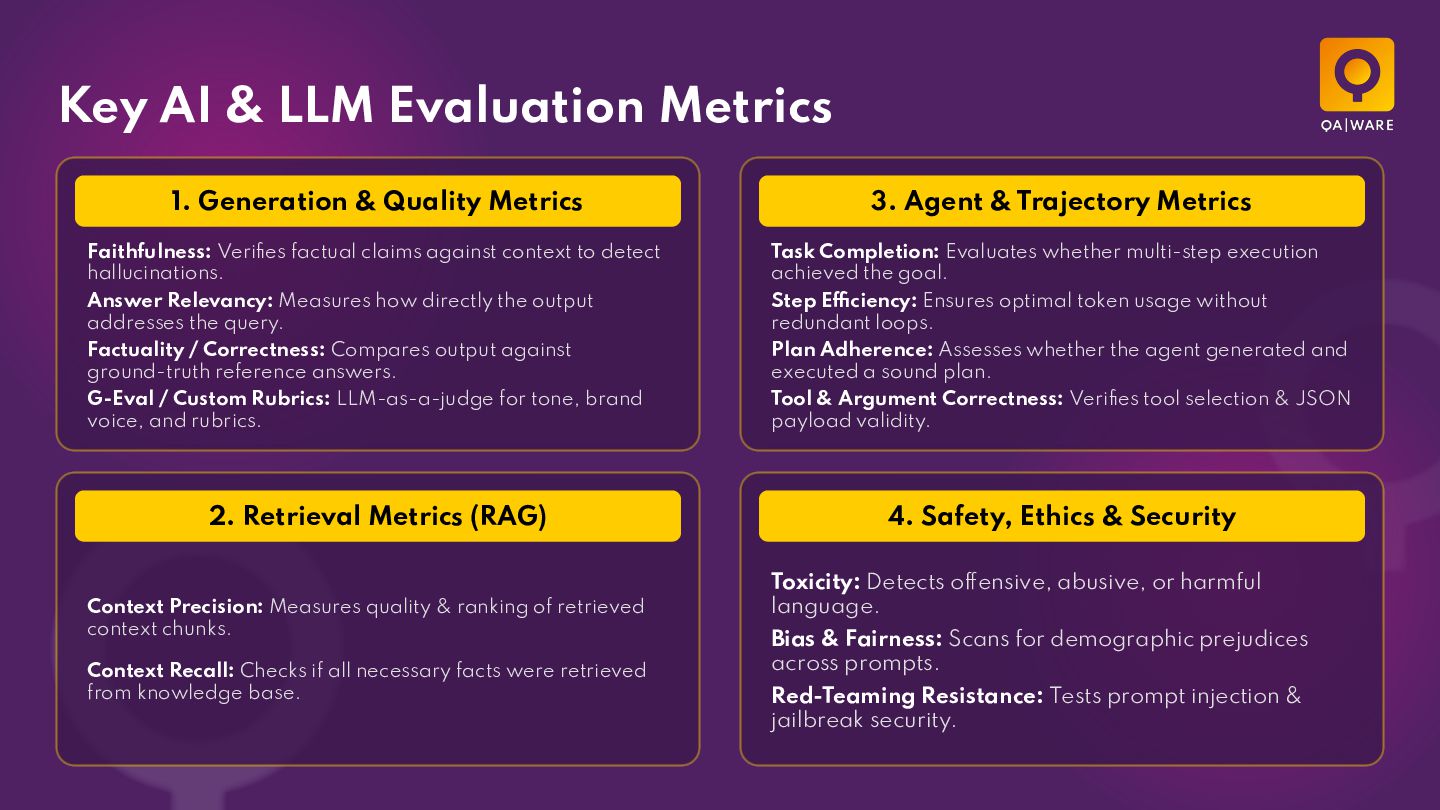
  11. Key AI & LLM Evaluation Metrics 1. Generation & Quality

    Metrics 3. Agent & Trajectory Metrics Faithfulness: Verifies factual claims against context to detect hallucinations. Task Completion: Evaluates whether multi-step execution achieved the goal. Answer Relevancy: Measures how directly the output addresses the query. Step Efficiency: Ensures optimal token usage without redundant loops. Factuality / Correctness: Compares output against ground-truth reference answers. Plan Adherence: Assesses whether the agent generated and executed a sound plan. G-Eval / Custom Rubrics: LLM-as-a-judge for tone, brand voice, and rubrics. Tool & Argument Correctness: Verifies tool selection & JSON payload validity. 2. Retrieval Metrics (RAG) Context Precision: Measures quality & ranking of retrieved context chunks. Context Recall: Checks if all necessary facts were retrieved from knowledge base. 4. Safety, Ethics & Security Toxicity: Detects offensive, abusive, or harmful language. Bias & Fairness: Scans for demographic prejudices across prompts. Red-Teaming Resistance: Tests prompt injection & jailbreak security.
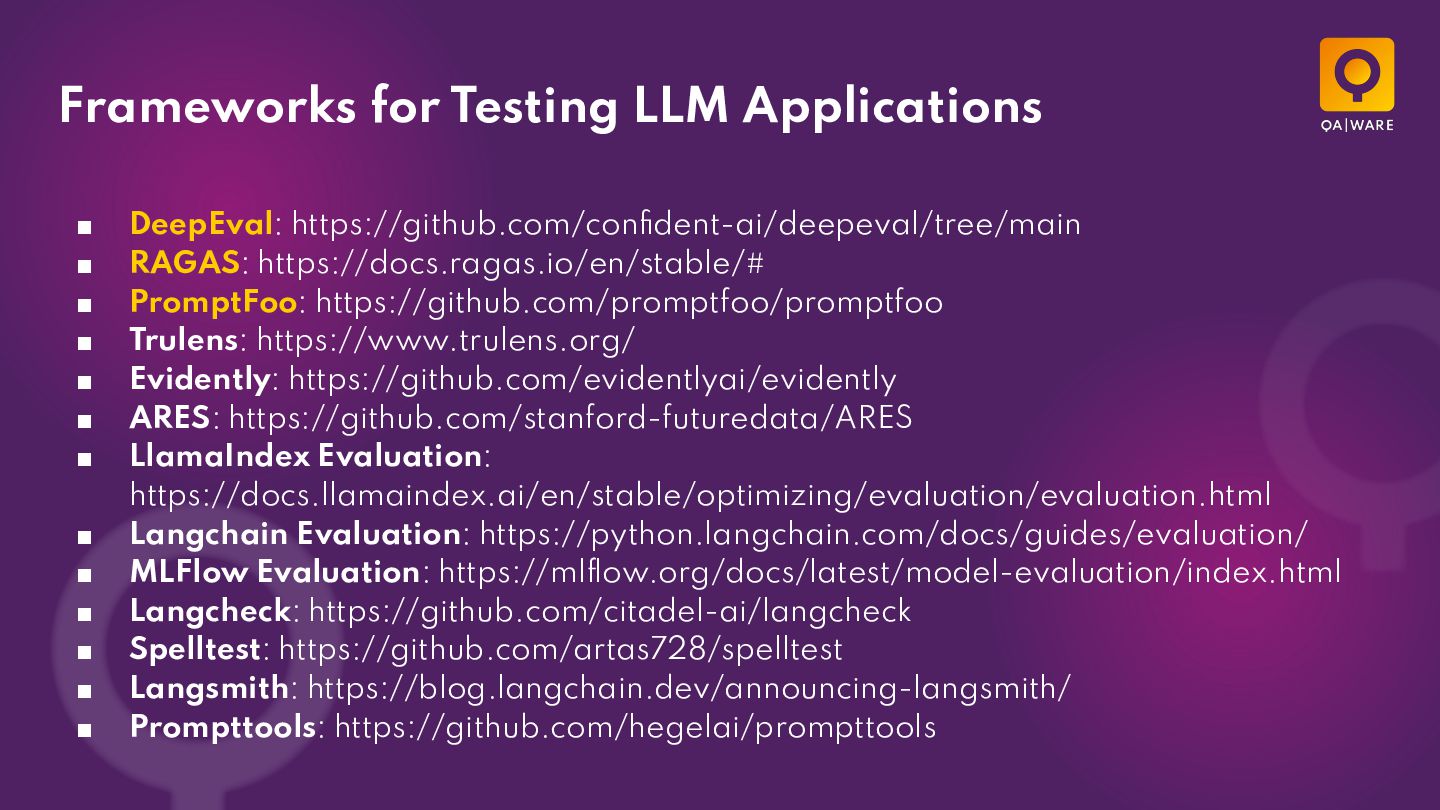
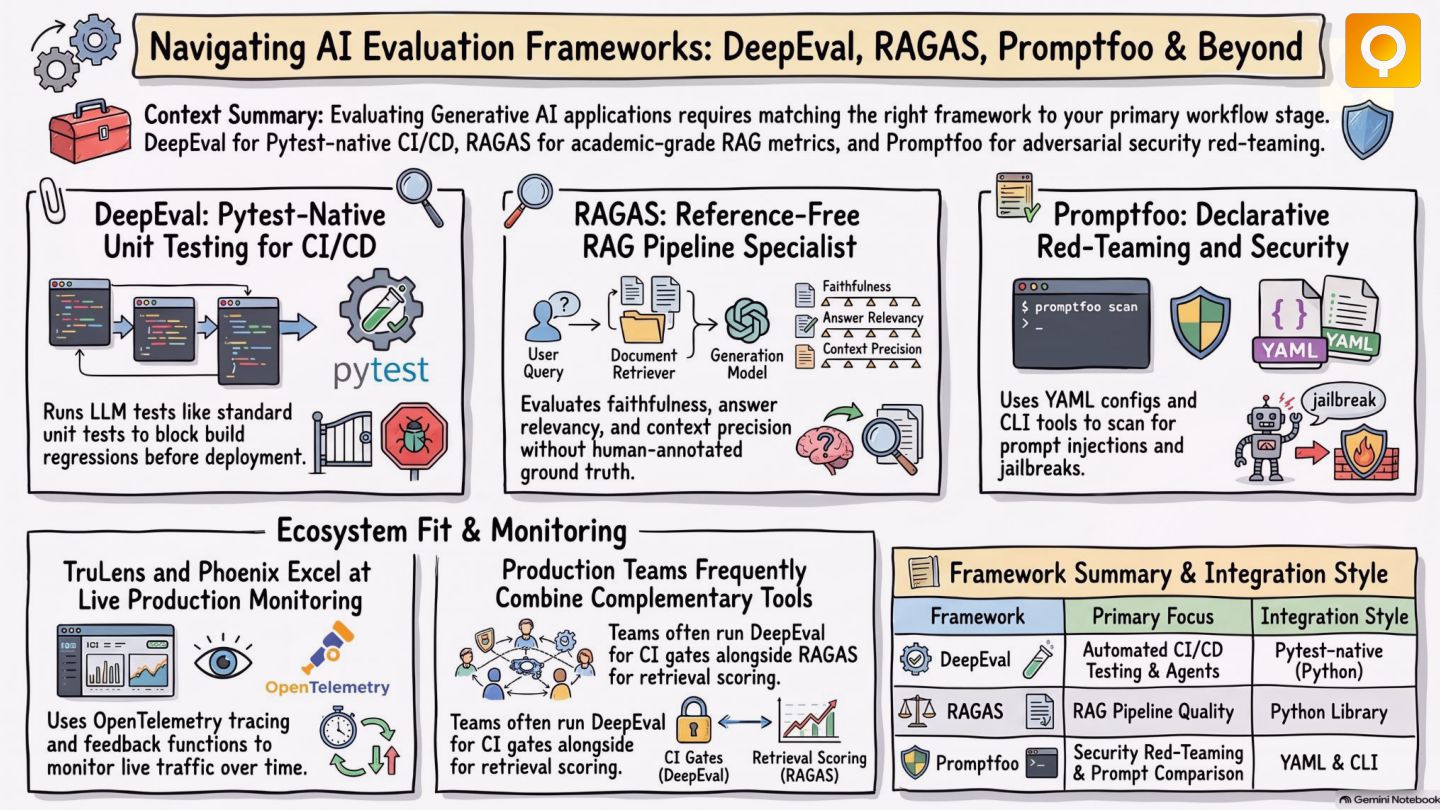
  12. Frameworks for Testing LLM Applications ▪ ▪ ▪ ▪ ▪

    ▪ ▪ ▪ ▪ ▪ ▪ ▪ ▪ DeepEval: https://github.com/confident-ai/deepeval/tree/main RAGAS: https://docs.ragas.io/en/stable/# PromptFoo: https://github.com/promptfoo/promptfoo Trulens: https://www.trulens.org/ Evidently: https://github.com/evidentlyai/evidently ARES: https://github.com/stanford-futuredata/ARES LlamaIndex Evaluation: https://docs.llamaindex.ai/en/stable/optimizing/evaluation/evaluation.html Langchain Evaluation: https://python.langchain.com/docs/guides/evaluation/ MLFlow Evaluation: https://mlflow.org/docs/latest/model-evaluation/index.html Langcheck: https://github.com/citadel-ai/langcheck Spelltest: https://github.com/artas728/spelltest Langsmith: https://blog.langchain.dev/announcing-langsmith/ Prompttools: https://github.com/hegelai/prompttools
  13. To Continuously Test an Agent is Complicated. AI Agent LLM,

    LAM, SLM, domain specific language model Prompts, flow control, sub-agents Use of GenAI, memory logic Tool Server OpenAI Tool Usage (MCP) Integration Logic MCP AI Agent Memory … ❏ ❏ ❏ Clear responsibilities Domain specific Highly distributed … A2A … ?
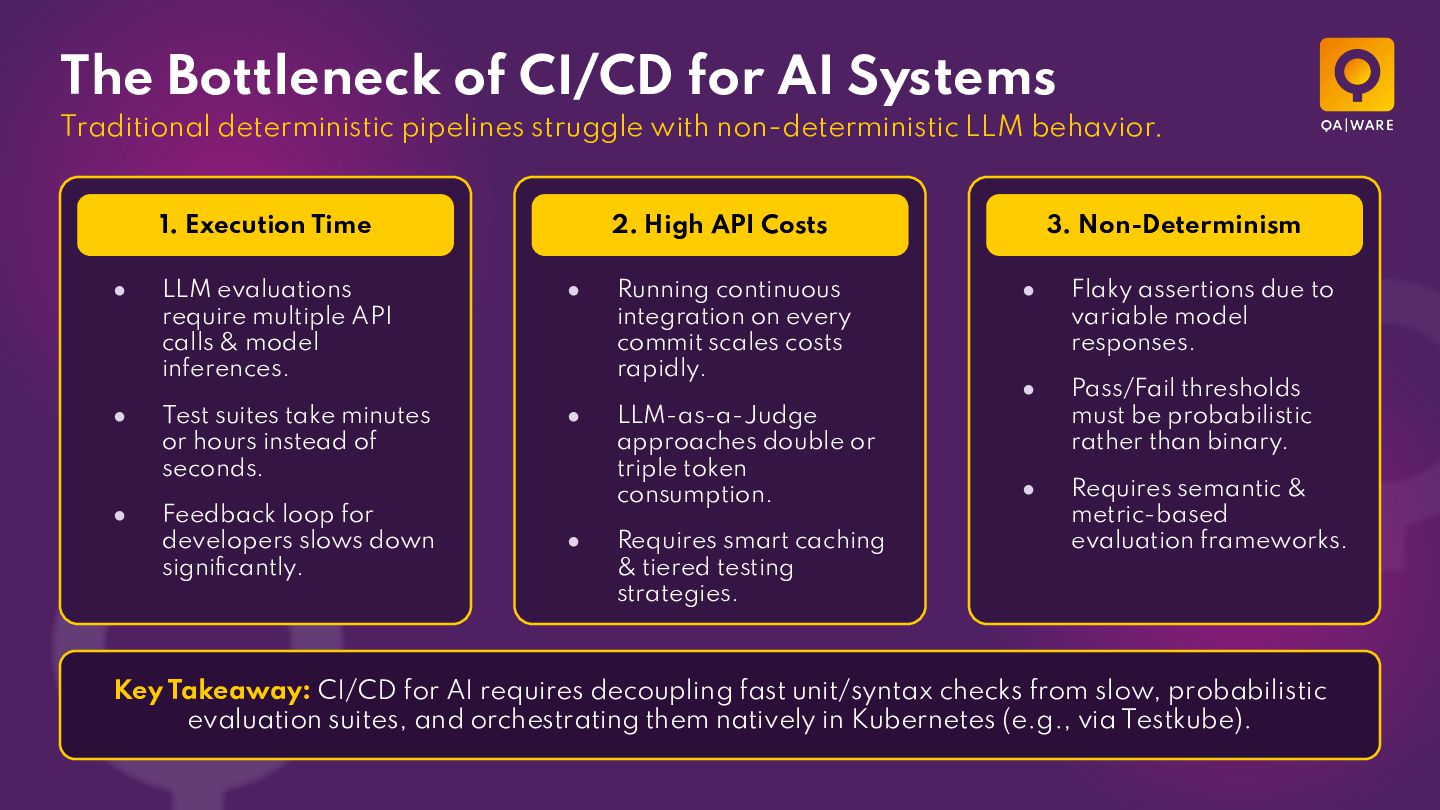
  14. The Bottleneck of CI/CD for AI Systems Traditional deterministic pipelines

    struggle with non-deterministic LLM behavior. 1. Execution Time 2. High API Costs • LLM evaluations require multiple API calls & model inferences. • Running continuous integration on every commit scales costs rapidly. • Test suites take minutes or hours instead of seconds. • LLM-as-a-Judge approaches double or triple token consumption. • Feedback loop for developers slows down significantly. • Requires smart caching & tiered testing strategies. 3. Non-Determinism • Flaky assertions due to variable model responses. • Pass/Fail thresholds must be probabilistic rather than binary. • Requires semantic & metric-based evaluation frameworks. Key Takeaway: CI/CD for AI requires decoupling fast unit/syntax checks from slow, probabilistic evaluation suites, and orchestrating them natively in Kubernetes (e.g., via Testkube).
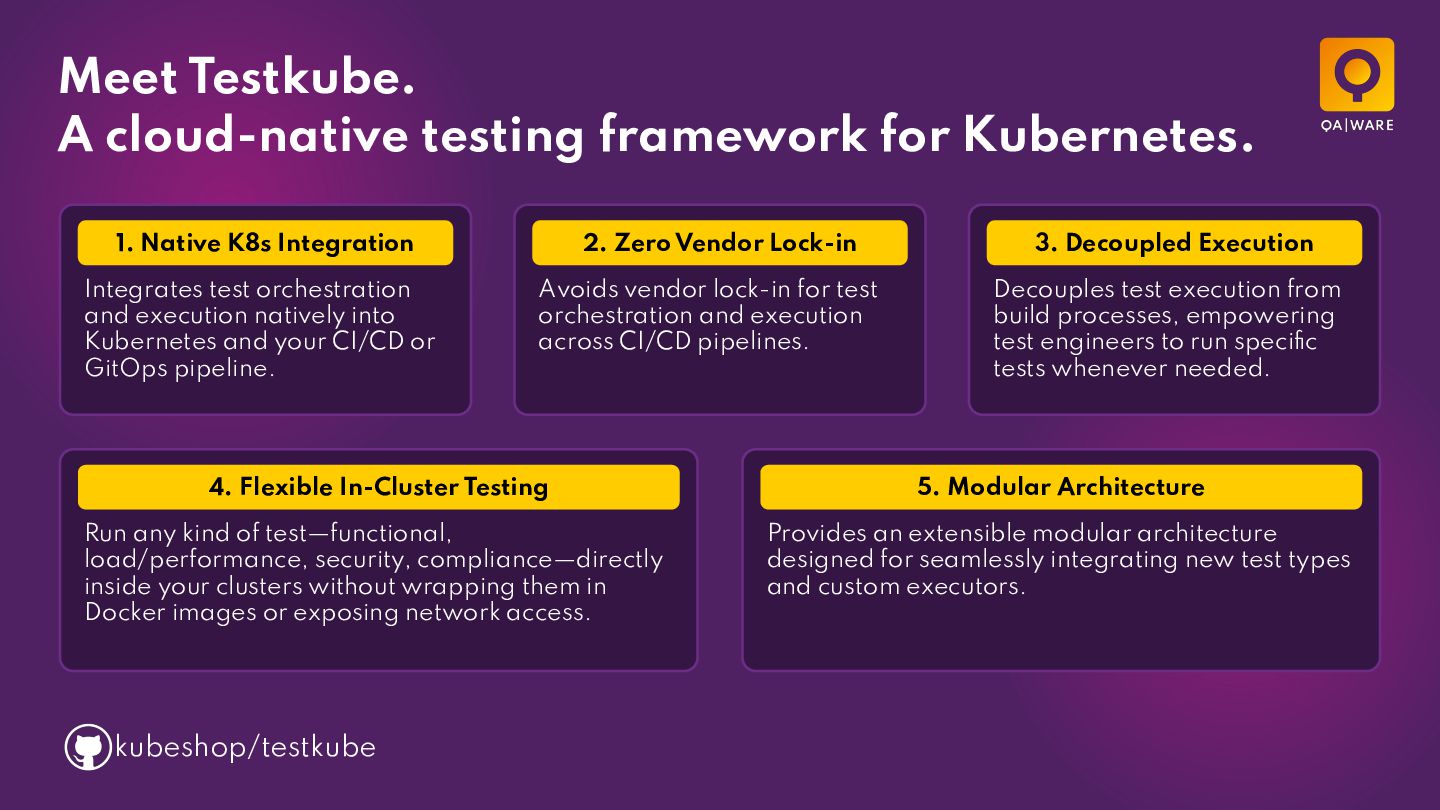
  15. Meet Testkube. A cloud-native testing framework for Kubernetes. 1. Native

    K8s Integration 2. Zero Vendor Lock-in 3. Decoupled Execution Integrates test orchestration and execution natively into Kubernetes and your CI/CD or GitOps pipeline. Avoids vendor lock-in for test orchestration and execution across CI/CD pipelines. Decouples test execution from build processes, empowering test engineers to run specific tests whenever needed. 4. Flexible In-Cluster Testing 5. Modular Architecture Run any kind of test—functional, load/performance, security, compliance—directly inside your clusters without wrapping them in Docker images or exposing network access. Provides an extensible modular architecture designed for seamlessly integrating new test types and custom executors. kubeshop/testkube
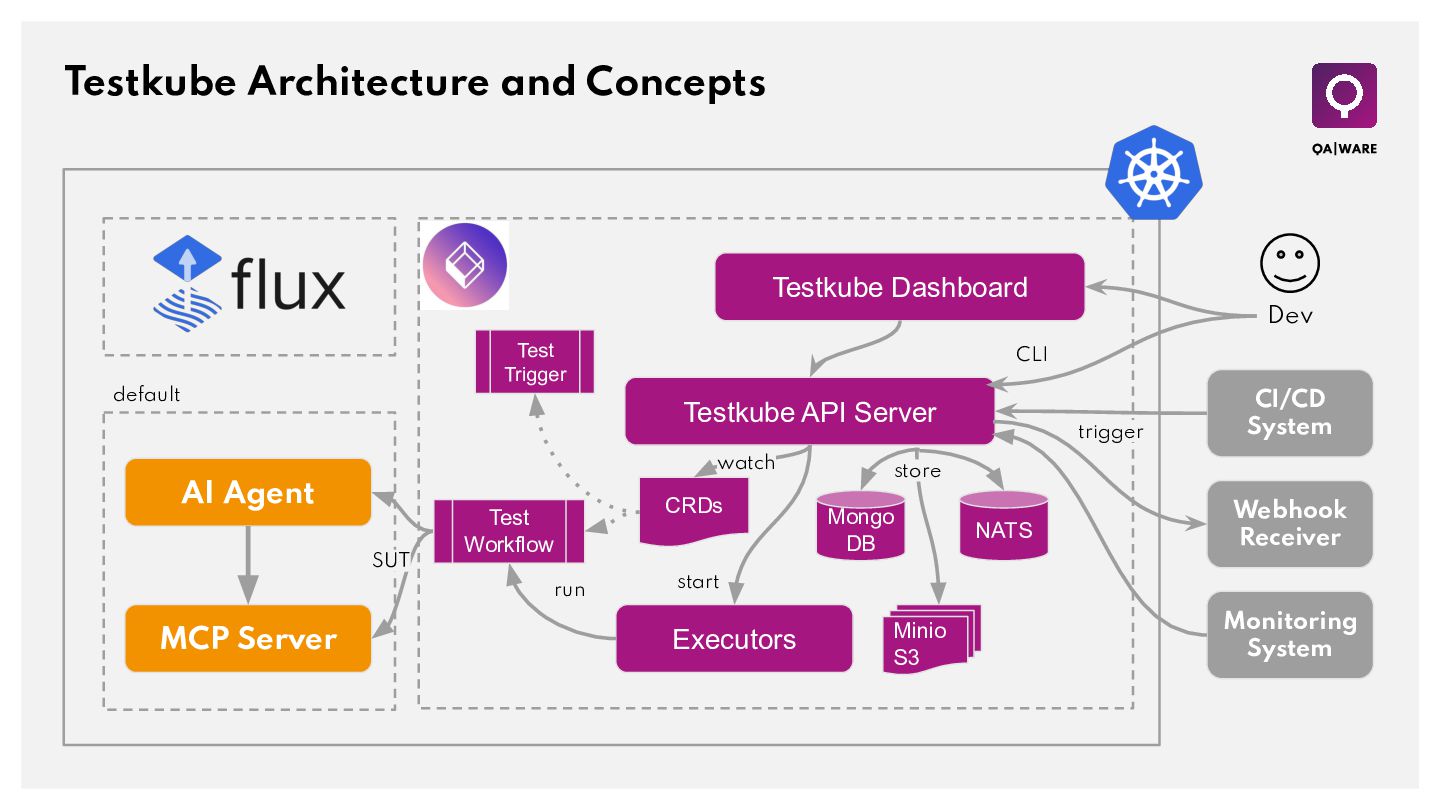
  16. Testkube Architecture and Concepts Testkube Dashboard Dev Test Trigger default

    CLI Testkube API Server watch AI Agent SUT CRDs Test Workflow run MCP Server trigger CI/CD System store Mongo DB NATS Webhook Receiver start Executors Minio S3 Monitoring System
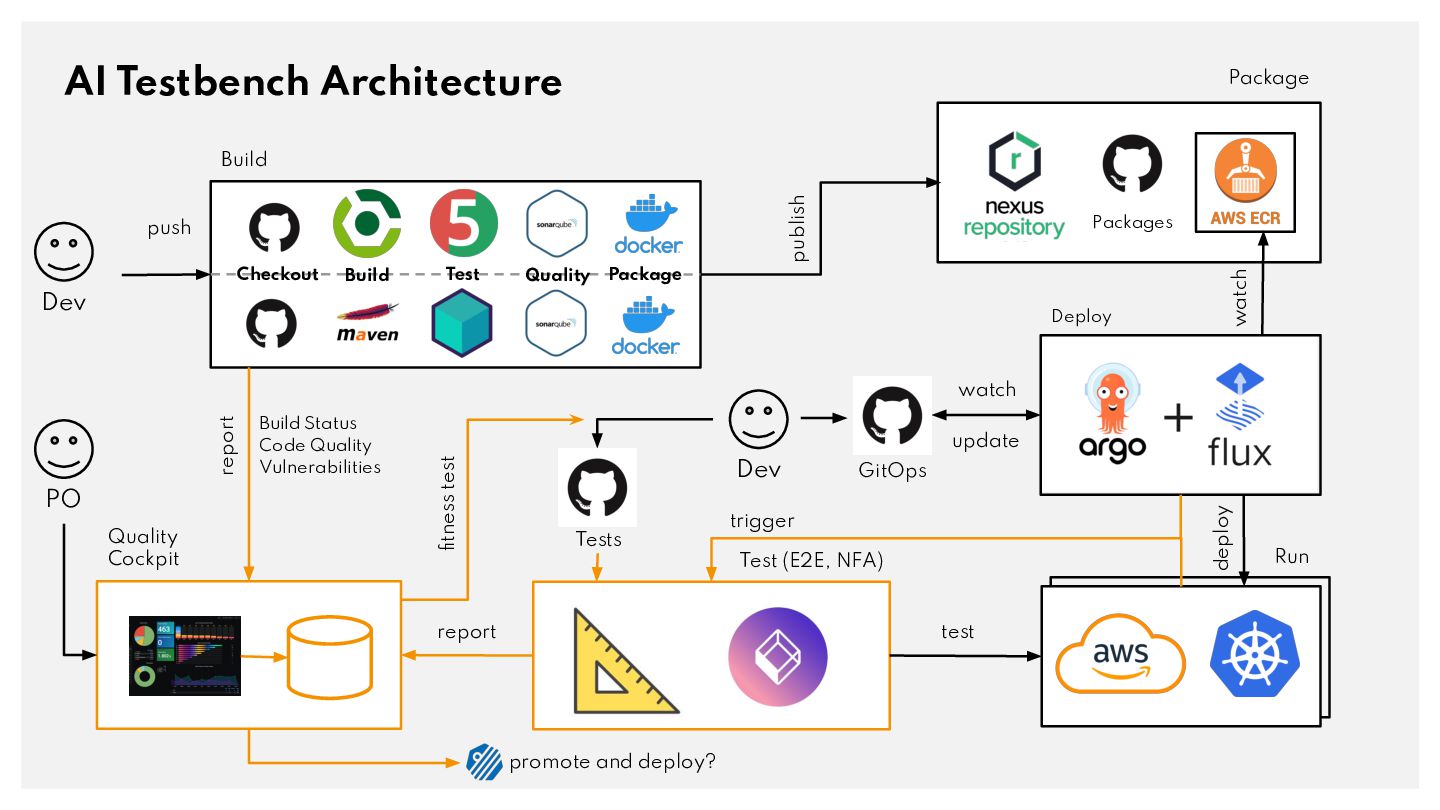
  17. AI Testbench Architecture Package publish Build Checkout Build Test Quality

    Packages Package Dev Deploy watch push Quality Cockpit update Dev Tests GitOps deploy PO Build Status Code Quality Vulnerabilities fitness test report watch trigger Test (E2E, NFA) report test promote and deploy? Run
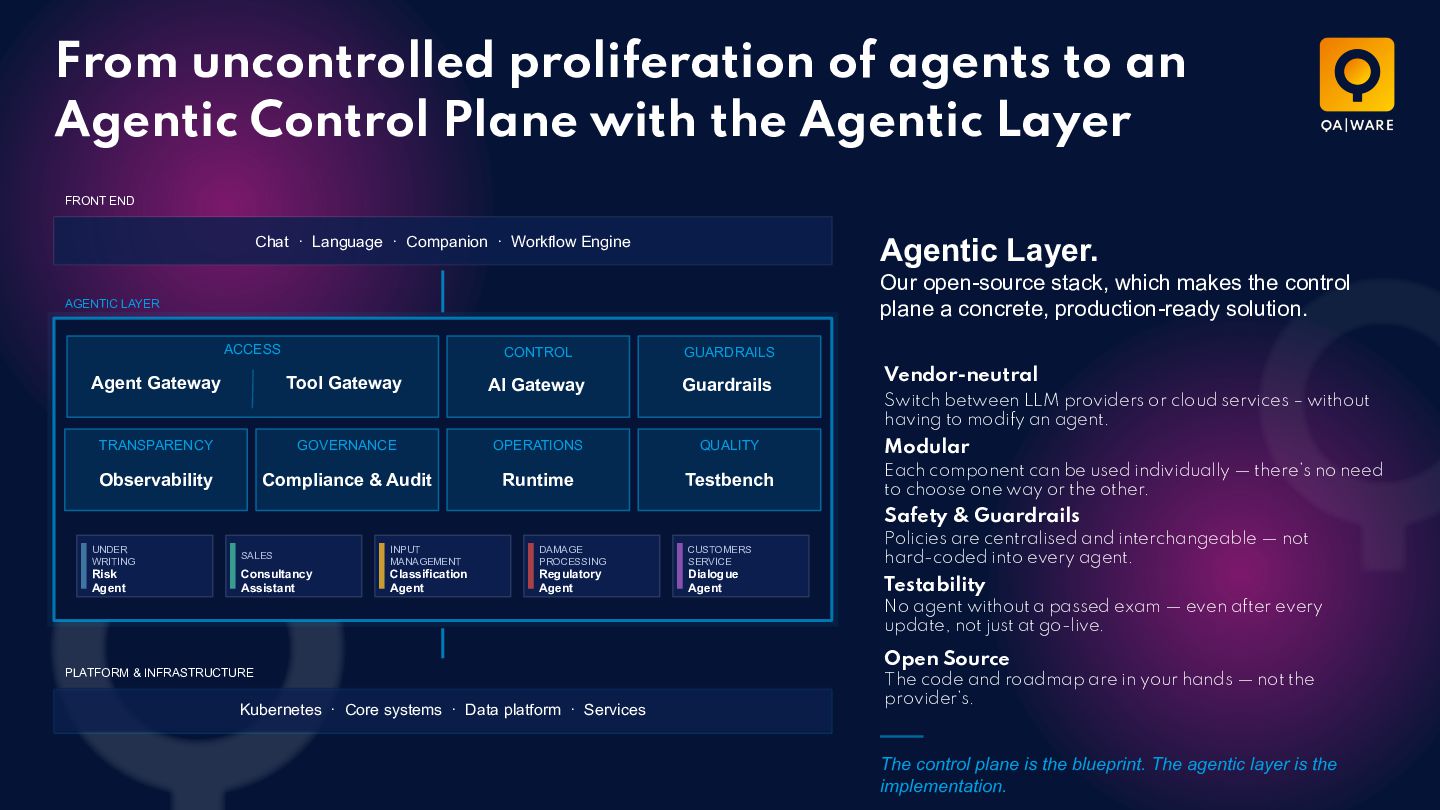
  18. From uncontrolled proliferation of agents to an Agentic Control Plane

    with the Agentic Layer FRONT END Agentic Layer. Chat · Language · Companion · Workflow Engine Our open-source stack, which makes the control plane a concrete, production-ready solution. AGENTIC LAYER ACCESS CONTROL GUARDRAILS Agent Gateway Tool Gateway AI Gateway Guardrails TRANSPARENCY GOVERNANCE OPERATIONS QUALITY Observability Compliance & Audit Runtime Testbench Vendor-neutral Switch between LLM providers or cloud services – without having to modify an agent. Modular Each component can be used individually — there’s no need to choose one way or the other. Safety & Guardrails UNDER WRITING SALES INPUT MANAGEMENT DAMAGE PROCESSING CUSTOMERS SERVICE Risk Agent Consultancy Assistant Classification Agent Regulatory Agent Dialogue Agent Policies are centralised and interchangeable — not hard-coded into every agent. Testability No agent without a passed exam — even after every update, not just at go-live. PLATFORM & INFRASTRUCTURE Kubernetes · Core systems · Data platform · Services Open Source The code and roadmap are in your hands — not the provider’s. The control plane is the blueprint. The agentic layer is the implementation.
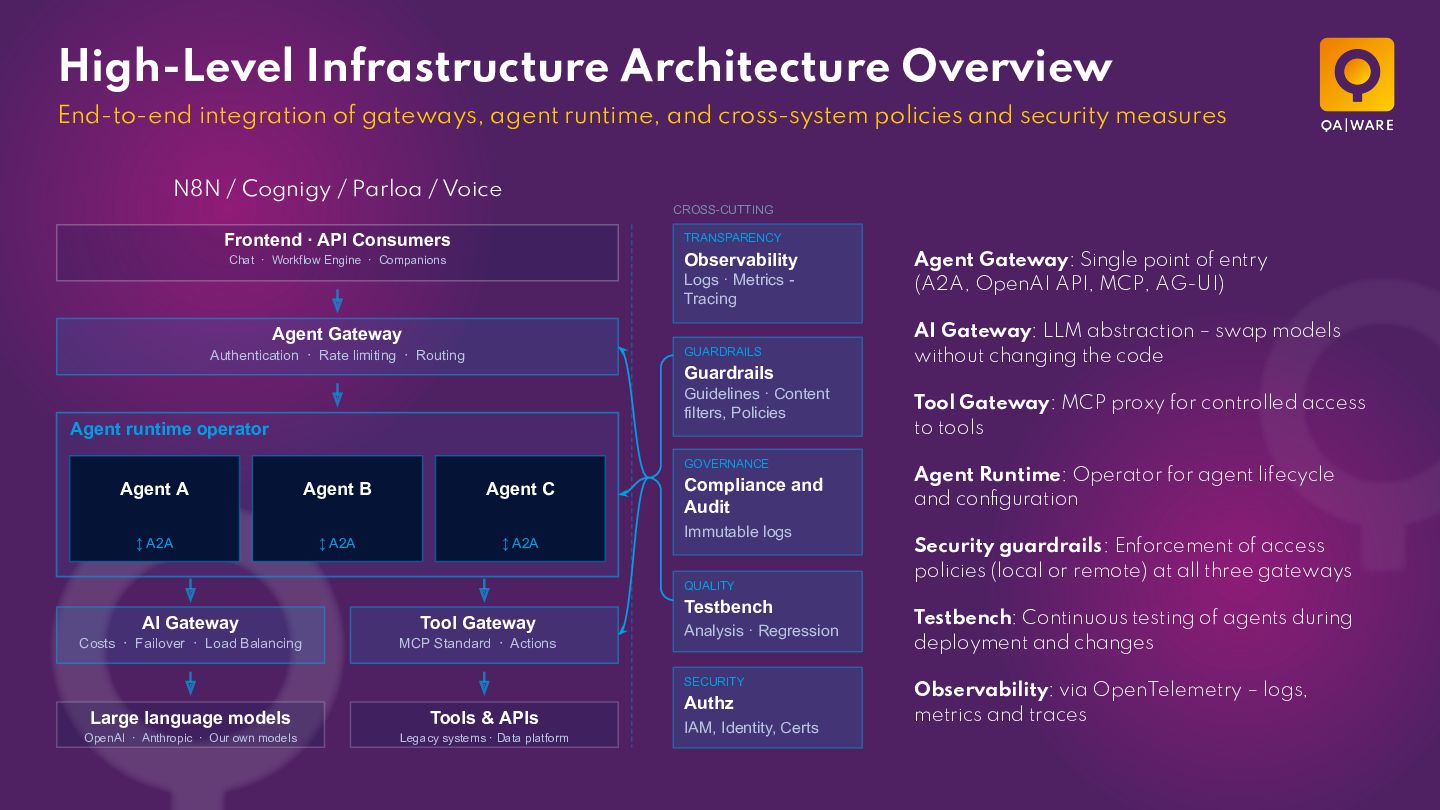
  19. High-Level Infrastructure Architecture Overview End-to-end integration of gateways, agent runtime,

    and cross-system policies and security measures N8N / Cognigy / Parloa / Voice CROSS-CUTTING Frontend · API Consumers TRANSPARENCY Observability Chat · Workflow Engine · Companions Logs · Metrics Tracing Agent Gateway GUARDRAILS Authentication · Rate limiting · Routing Guardrails Guidelines · Content filters, Policies Agent runtime operator GOVERNANCE Agent A Agent B Agent C ↕ A2A ↕ A2A ↕ A2A Compliance and Audit Immutable logs QUALITY AI Gateway Tool Gateway Costs · Failover · Load Balancing MCP Standard · Actions Testbench Analysis · Regression SECURITY Large language models Tools & APIs OpenAI · Anthropic · Our own models Legacy systems · Data platform Authz IAM, Identity, Certs Agent Gateway: Single point of entry (A2A, OpenAI API, MCP, AG-UI) AI Gateway: LLM abstraction – swap models without changing the code Tool Gateway: MCP proxy for controlled access to tools Agent Runtime: Operator for agent lifecycle and configuration Security guardrails: Enforcement of access policies (local or remote) at all three gateways Testbench: Continuous testing of agents during deployment and changes Observability: via OpenTelemetry – logs, metrics and traces
  20. Let´s connect! Mario-Leander Reimer Managing Director, CTO [email protected] QAware GmbH

    | Aschauer Straße 30 | 81549 München | GF: Dr. Josef Adersberger, Michael Stehnken, Michael Rohleder, Mario-Leander Reimer| Niederlassungen in München, Mainz, Rosenheim, Darmstadt | +49 89 232315-0 | [email protected] | www.qaware.de