Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Distributed Deep Learning With Spark on AWS

Distributed Deep Learning With Spark on AWS

Training deep networks is a time-consuming process, with networks for object recognition often requiring multiple days to train. For this reason, leveraging the resources of a cluster to speed up training is an important area of work. In this talk we'll show how to use an AWS Spark cluster to train a model quickly from a laptop at a very little cost.

Avatar for Vincent Van Steenbergen

Vincent Van Steenbergen

March 15, 2016

Other Decks in Science

Transcript

  1. WHOAMI VINCENT VAN STEENBERGEN Playing with Scala, Akka & Spark

    +/- 3 years Deeply interested in Artificial Intelligence and Data Analysis
  2. TRAINING A MODEL REQUIRES: 1. a lot of time (usually

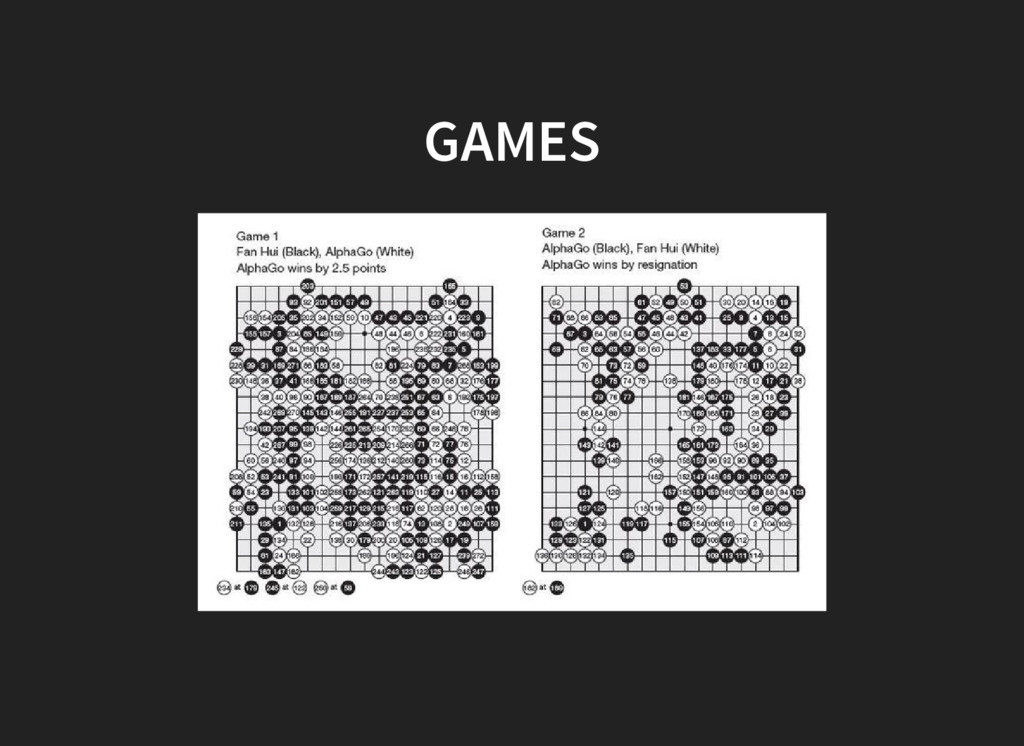
    weeks/months) 2. a lot of computing power Ex: AlphaGo - 1202 CPU and 176 GPU - 6 weeks training
  3. SO HOW CAN I DO THAT... from my laptop? for

    a decent cost? within a short timespan?
  4. YES YOU CAN! Technicaly possible on a (high end) laptop

    but very slow Solution: distribute training over a cluster
  5. AMAZON WEB SERVICES (EC2) GPU instances (g2.2xlarge, g2.8xlarge) Spot instances

    (on demand, generally 2-3 times cheaper than regular instances)
  6. G2.8XLARGE CONFIGURATION Four NVIDIA GRID GPUs, each with 1,536 CUDA

    cores and 4 GB of video memory 32 vCPUs 60 GiB of memory 240 GB (2 x 120) of SSD storage Average price: $1.00 per hour
  7. ADVANTAGES Can run on an existing cluster along other Spark

    jobs Leverage existing Caffe models Use SQL, DataFrames, existing LMDB files Peer-to peer communication with Message passing