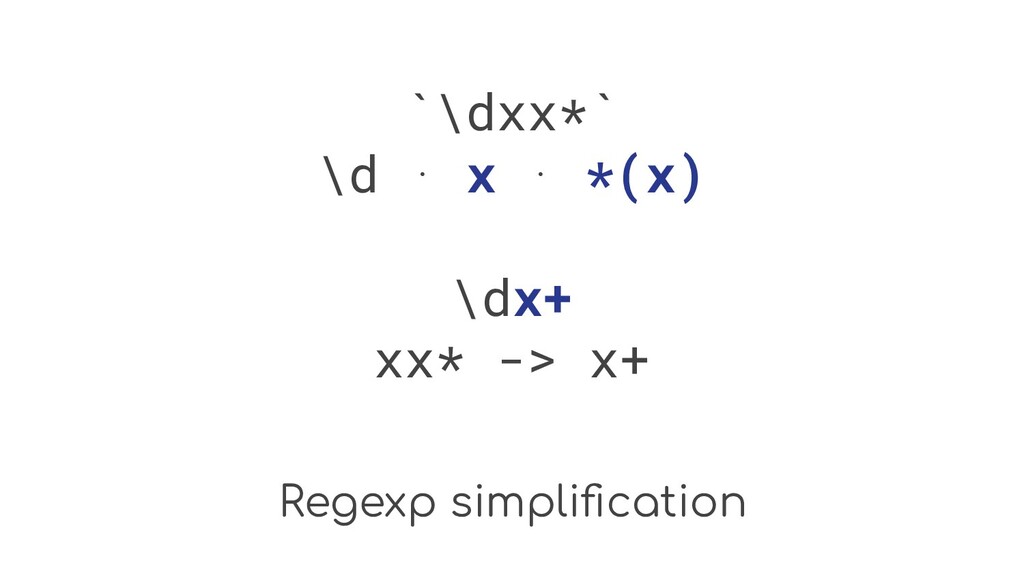Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
How to do regexp analysis
Search
Iskander (Alex) Sharipov
April 25, 2020
Programming
330
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
How to do regexp analysis
Iskander (Alex) Sharipov
April 25, 2020
More Decks by Iskander (Alex) Sharipov
See All by Iskander (Alex) Sharipov
quasigo
quasilyte
0
130
Go gamedev: XM music
quasilyte
0
170
Zero alloc pathfinding
quasilyte
0
830
Mycelium
quasilyte
0
130
Roboden game pitch
quasilyte
0
330
Ebitengine Ecosystem Overview
quasilyte
1
1.1k
Go gamedev patterns
quasilyte
0
580
profile-guided code analysis
quasilyte
0
410
Go inlining
quasilyte
0
180
Other Decks in Programming
See All in Programming
SODA - FACT BOOK(JP)
sodainc
1
40k
LLM 101
dalinaum
0
460
선언형 햅틱 라이브러리 진동을 소개합니다
l2hyunwoo
1
280
SODA - FACT BOOK(EN)
sodainc
1
200
Getting Started with Vibe Coding
miccheng
0
180
Railsのためのパスキー実践入門 〜マルチテナントSaaSでの意思決定〜
utakaha
4
2.8k
Long Living Tokens, Die, Die, Die! (or: The One Ring is Banned in Modern)
sylph01
0
400
SFCで実現する病院・医療システムの動的組み立て式UI
koukimiura
1
160
React Native経験者が Flutterを30⽇間触って驚いたこと
3saito
0
140
Web Framework Benchmark Battle 2026, Any%
a_matsuda
3
3.1k
Next.js: The final boss of Web Performance
guaca
0
380
複雑なUIコンポーネントとの ⻑い付き合い⽅:波及するバグからテスト戦略を経て、安全な再設計へ
mixplace
0
510
Featured
See All Featured
Crafting Experiences
bethany
1
420
Chasing Engaging Ingredients in Design
codingconduct
0
380
Building the Perfect Custom Keyboard
takai
2
940
Being A Developer After 40
akosma
PRO
92
590k
Evolving SEO for Evolving Search Engines
ryanjones
0
350
Hiding What from Whom? A Critical Review of the History of Programming languages for Music
tomoyanonymous
3
1.4k
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
380
Navigating Team Friction
lara
192
16k
Put a Button on it: Removing Barriers to Going Fast.
kastner
60
4.6k
Mobile First: as difficult as doing things right
swwweet
225
10k
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
730
Max Prin - Stacking Signals: How International SEO Comes Together (And Falls Apart)
techseoconnect
PRO
0
520
Transcript
How to do regexp analysis @quasilyte / GolangKazan 2020
Not why, but how Implementation advice and potential issues overview.
go-critic NoVerify Open-Source analyzers
Discussion plan • Handling regexp syntax • Analyzing regexp flow
• Finding bugs in regular expressions • Regexp rewriting
Handling regexp syntax
Why making own parser? Most regexp libraries use parsers that
give up on the first error. For analysis, we need rich AST (parse tree even) and error-tolerant parser.
Writing a parser Useful resources: • Regexp syntax docs (BNF,
re2-syntax) • Pratt parsers tutorial (RU, EN) • Regexp corpus for tests (gist) • Dialect-specific documentation
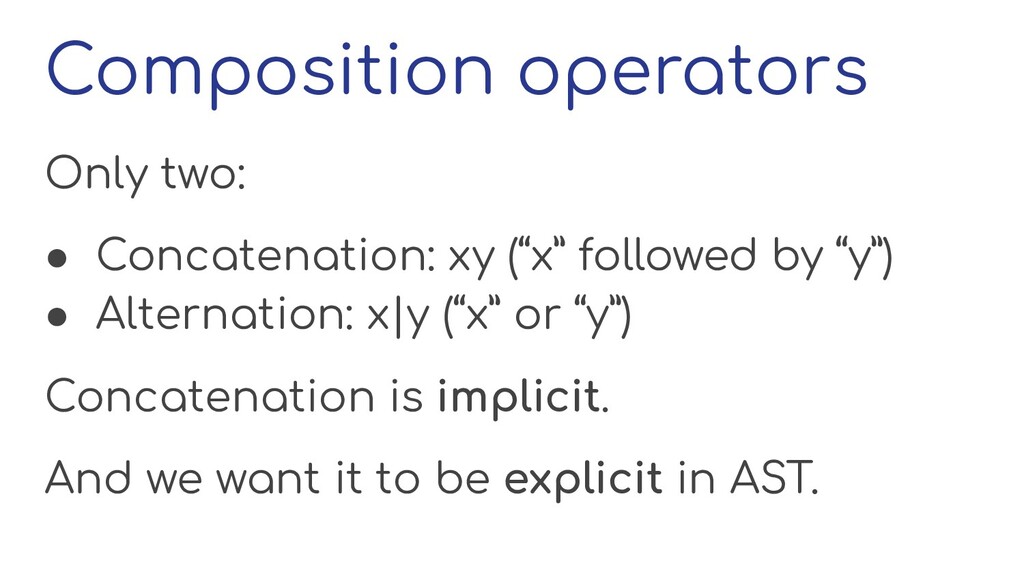
Composition operators Only two: • Concatenation: xy (“x” followed by
“y”) • Alternation: x|y (“x” or “y”) Concatenation is implicit. And we want it to be explicit in AST.
Concat operation `0|xy[a-z]` ⬇ 0 | x ⋅ y ⋅
[a-z]
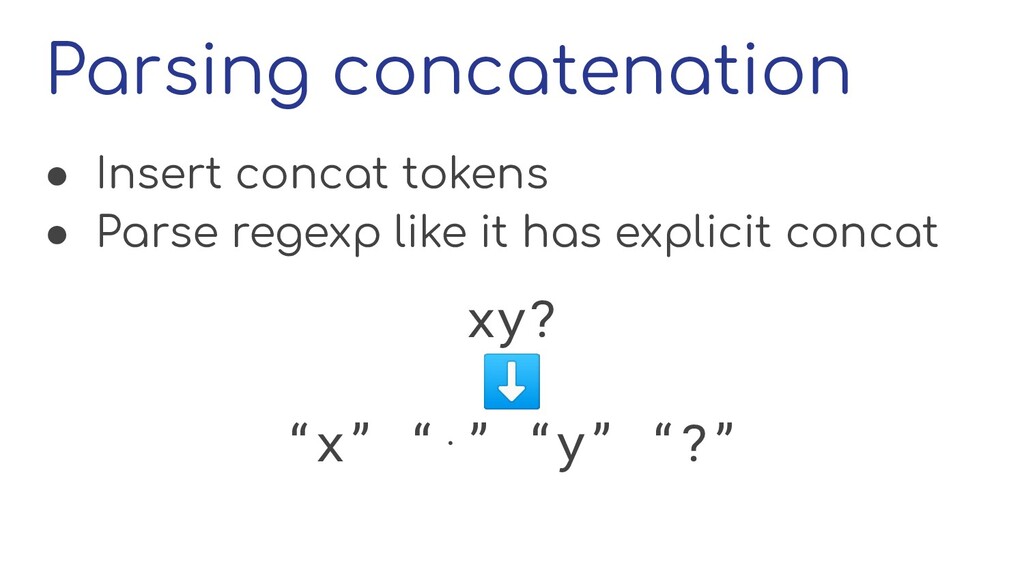
Parsing concatenation • Insert concat tokens • Parse regexp like
it has explicit concat xy? ⬇ “x” “⋅” “y” “?”
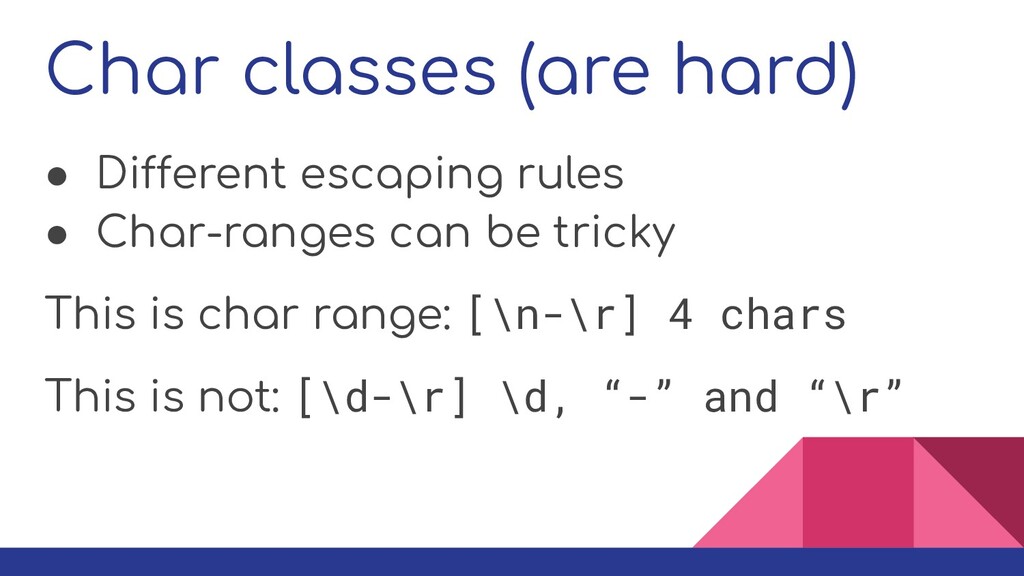
Char classes (are hard) • Different escaping rules • Char-ranges
can be tricky This is char range: [\n-\r] 4 chars This is not: [\d-\r] \d, “-” and “\r”
Char classes syntax `[][]` What is it?
Char classes syntax `[][]` A char class of “]” and
“[“! `[\]\[]`
Char classes syntax `[^]*|\[[^\]]` What is it?
Char classes syntax `[^]*|\[[^\]]` A single char class! `[^\]*|\[\[^\]]`
Char classes syntax `[+=-_]` What will be matched?
Char classes syntax `[+=-_]` “F” matched
Char classes syntax `[+=\-_]` “F” not matched
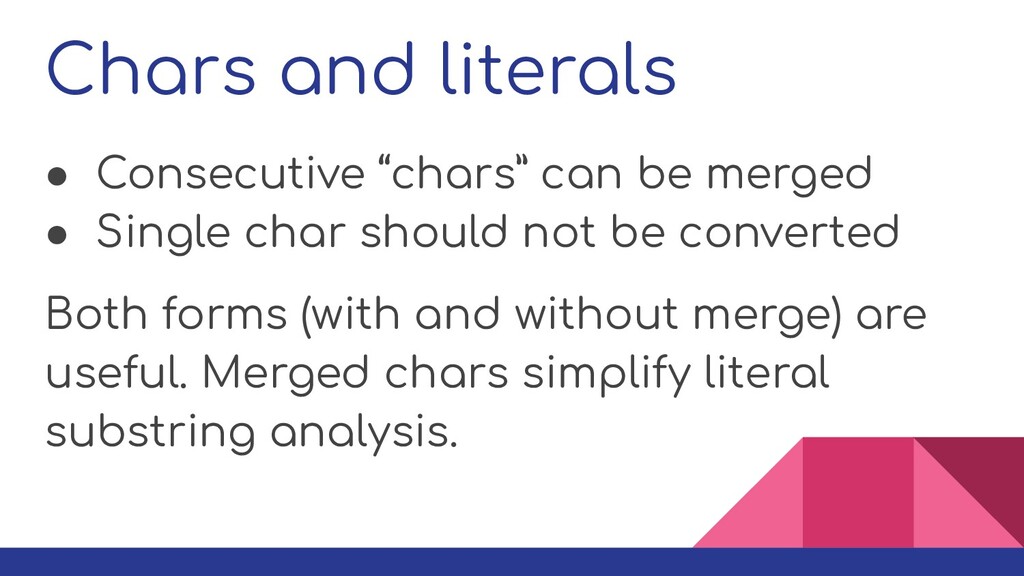
Chars and literals • Consecutive “chars” can be merged •
Single char should not be converted Both forms (with and without merge) are useful. Merged chars simplify literal substring analysis.
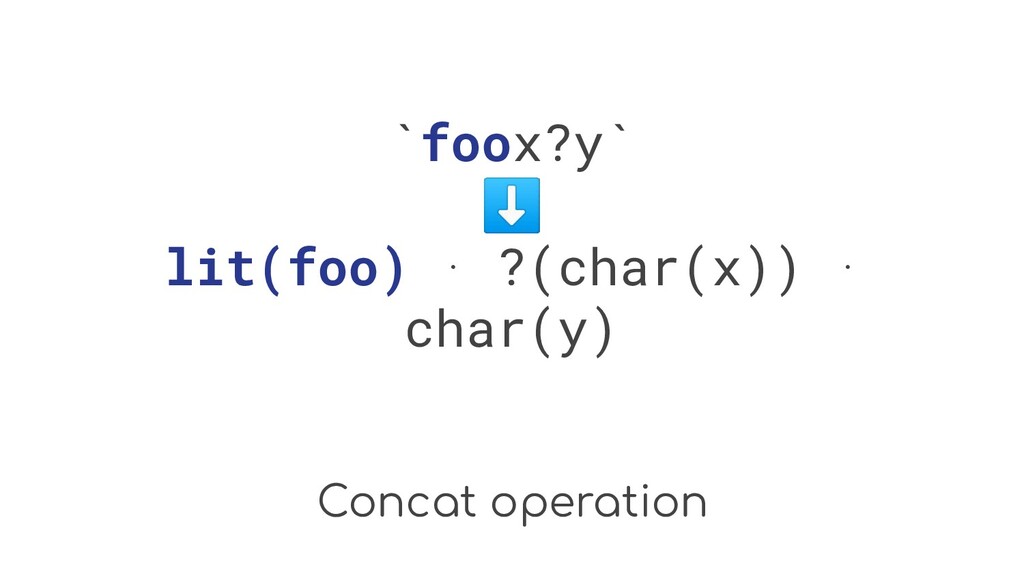
Concat operation `foox?y` ⬇ lit(foo) ⋅ ?(char(x)) ⋅ char(y)
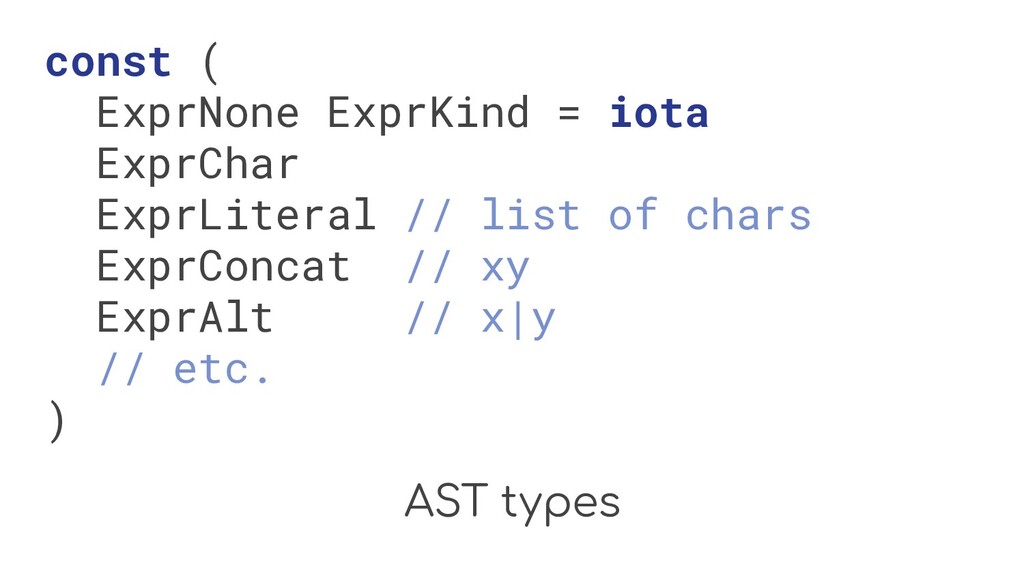
AST types There are at least two approaches: • One
type + enum tags • Many types + shared interface/base Both have pros and cons.
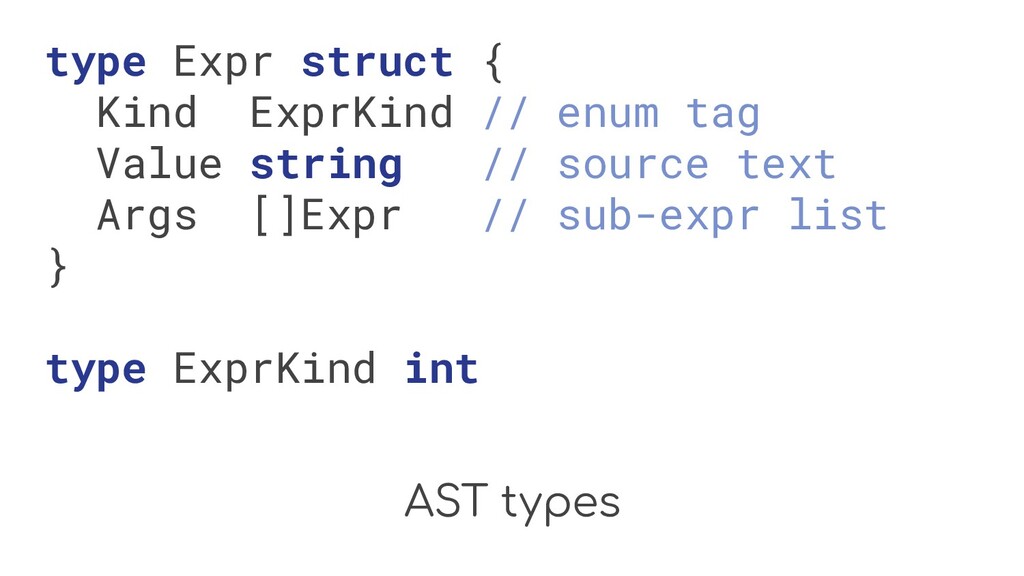
AST types type Expr struct { Kind ExprKind // enum
tag Value string // source text Args []Expr // sub-expr list } type ExprKind int
AST types const ( ExprNone ExprKind = iota ExprChar ExprLiteral
// list of chars ExprConcat // xy ExprAlt // x|y // etc. )
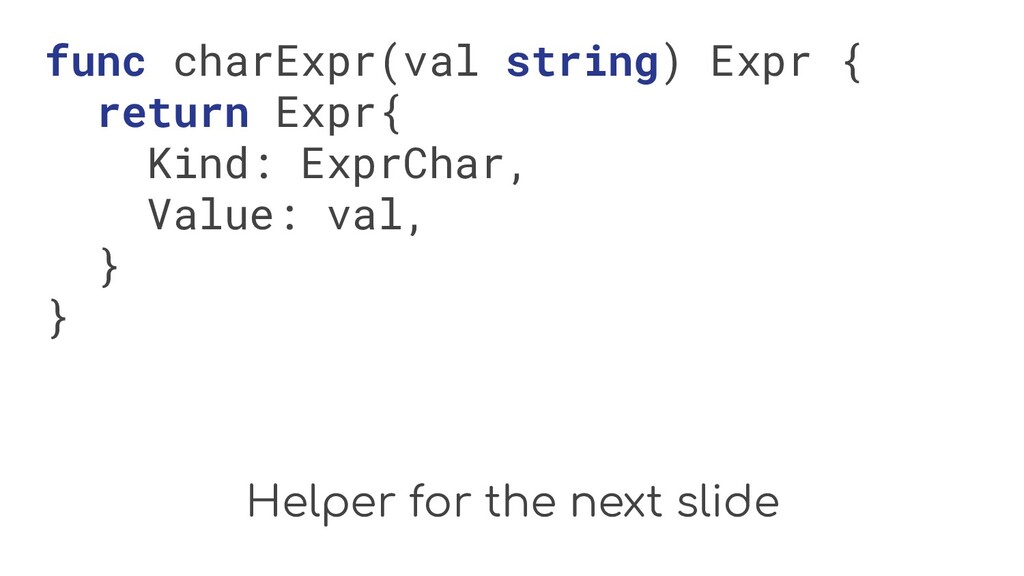
Helper for the next slide func charExpr(val string) Expr {
return Expr{ Kind: ExprChar, Value: val, } }
AST of `x|yz` Expr{ Kind: ExprAlt, Value: "x|yz", Args: []Expr{
charExpr("x"), { Kind: ExprConcat, Value: "yz", Args: []Expr{ charExpr("y"), charExpr("z"), }, }, }, }
Go regexp parsing library https://github.com/quasilyte/regex contains a `regex/syntax` package that
is used in both NoVerify and go-critic. It can parse both re2 and pcre patterns.
Analyzing regexp flow
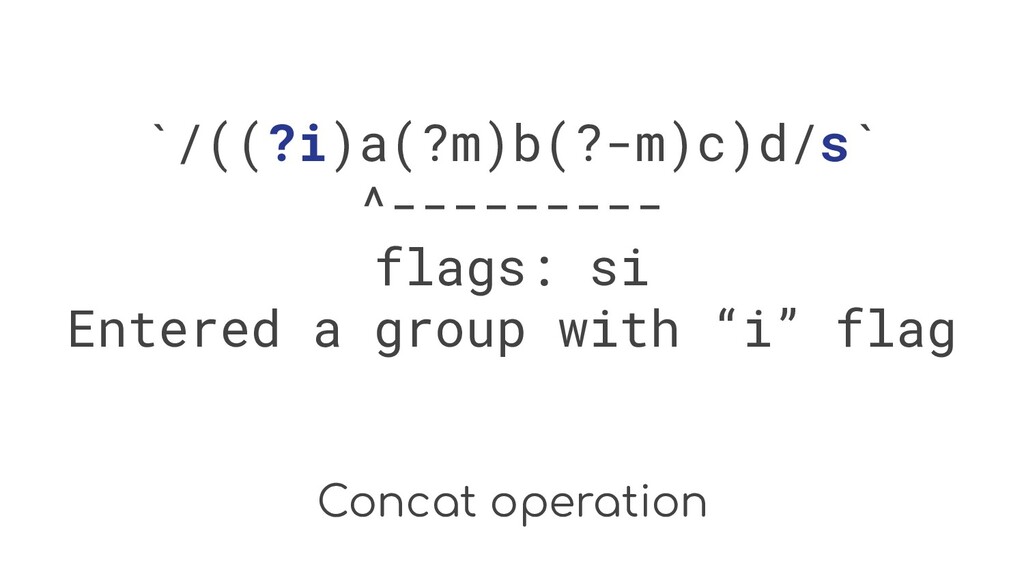
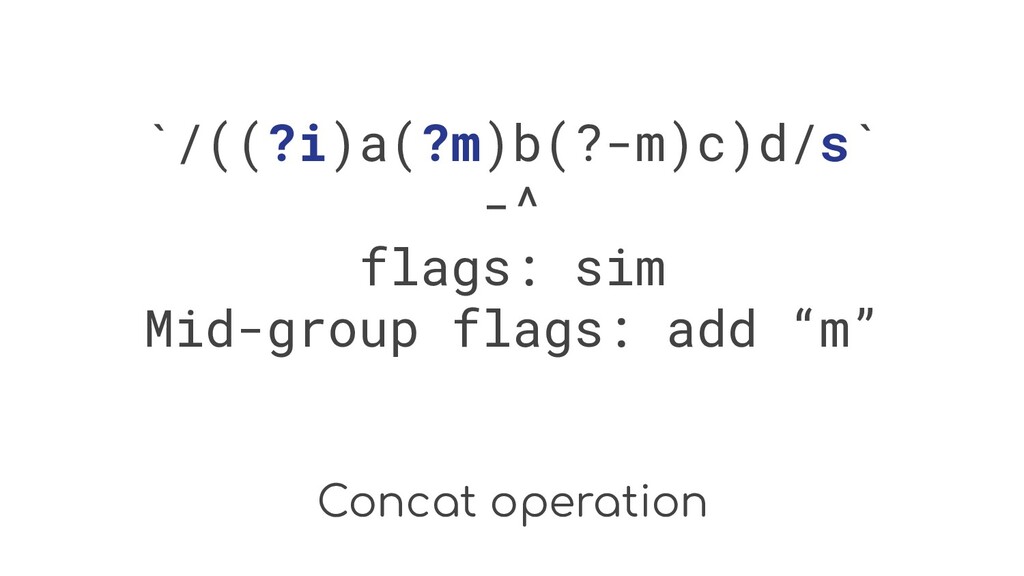
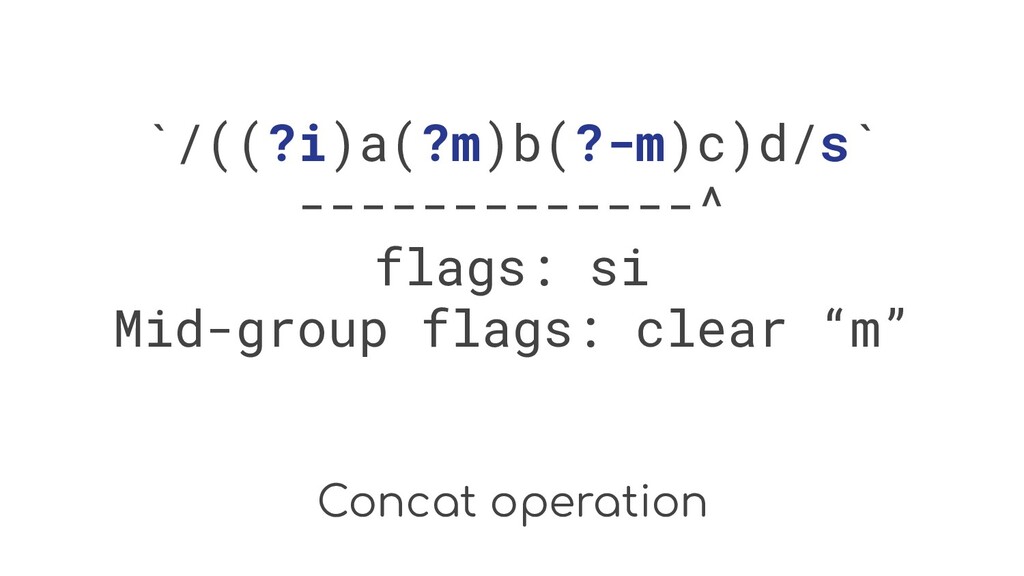
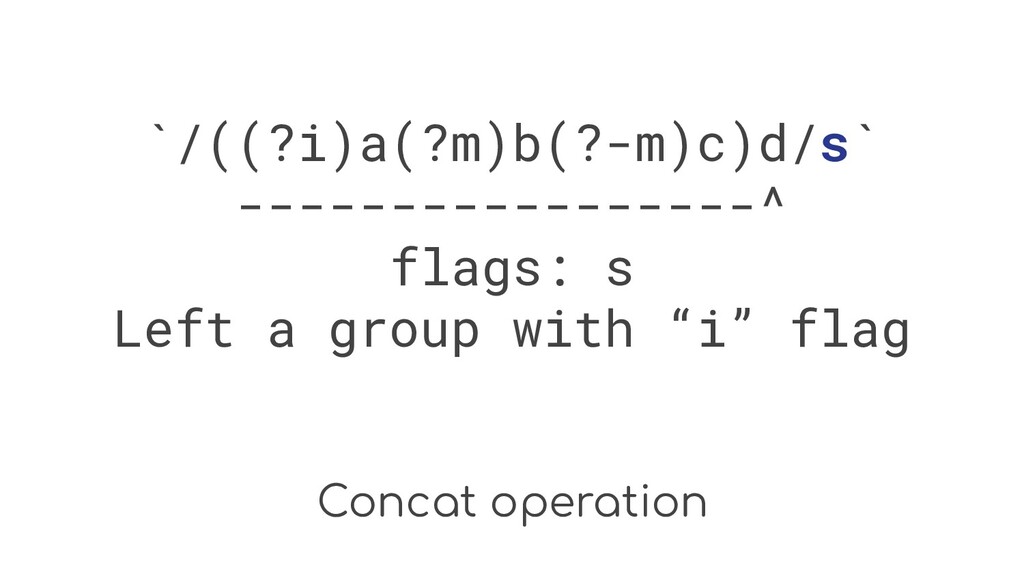
Regexp flags A regular expression can have an initial set
of flags, then it can add or remove any of them inside the expression. The effect is localized to the current (potentially capturing) group.
Concat operation `/((?i)a(?m)b(?-m)c)d/s` ^--------- flags: si Entered a group with
“i” flag
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -^ flags: sim Mid-group flags: add “m”
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -------------^ flags: si Mid-group flags: clear “m”
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -----------------^ flags: s Left a group with
“i” flag
Flags flow • Flags are lexically scoped • Groups are
a scoping unit • Leaving a group drops a scope • Entering a group adds a scope
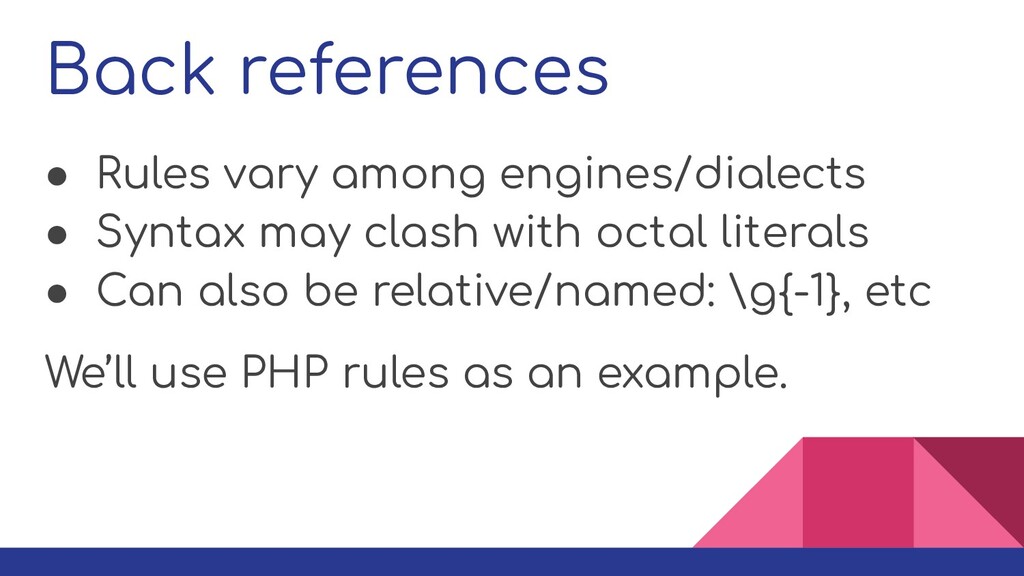
Back references • Rules vary among engines/dialects • Syntax may
clash with octal literals • Can also be relative/named: \g{-1}, etc We’ll use PHP rules as an example.
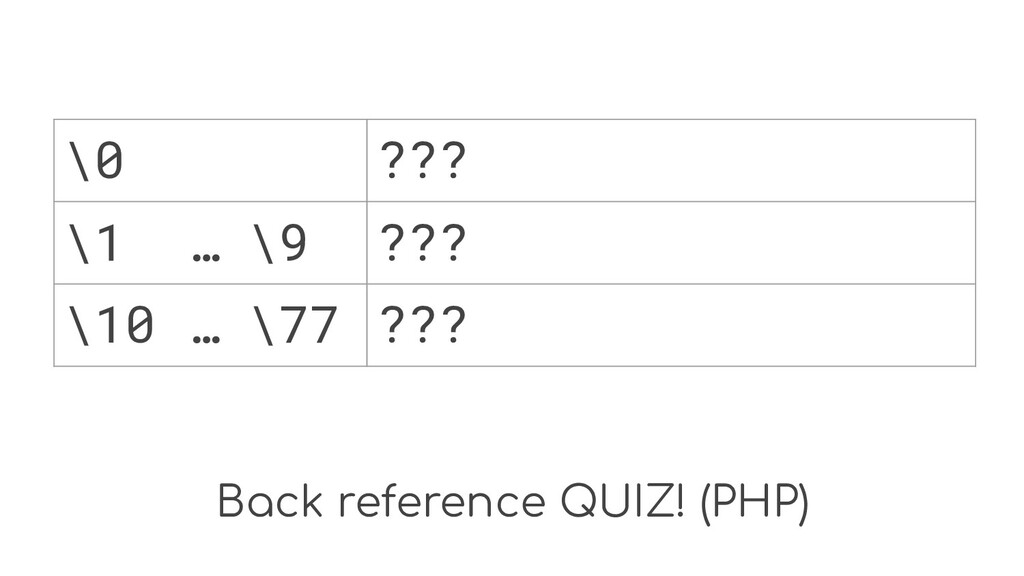
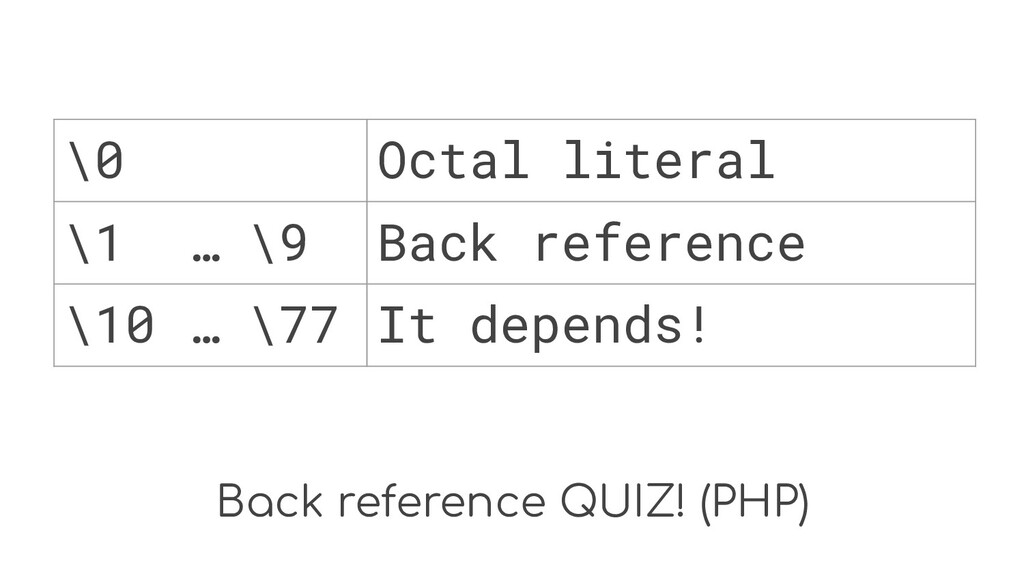
Back reference QUIZ! (PHP) \0 ??? \1 … \9 ???
\10 … \77 ???
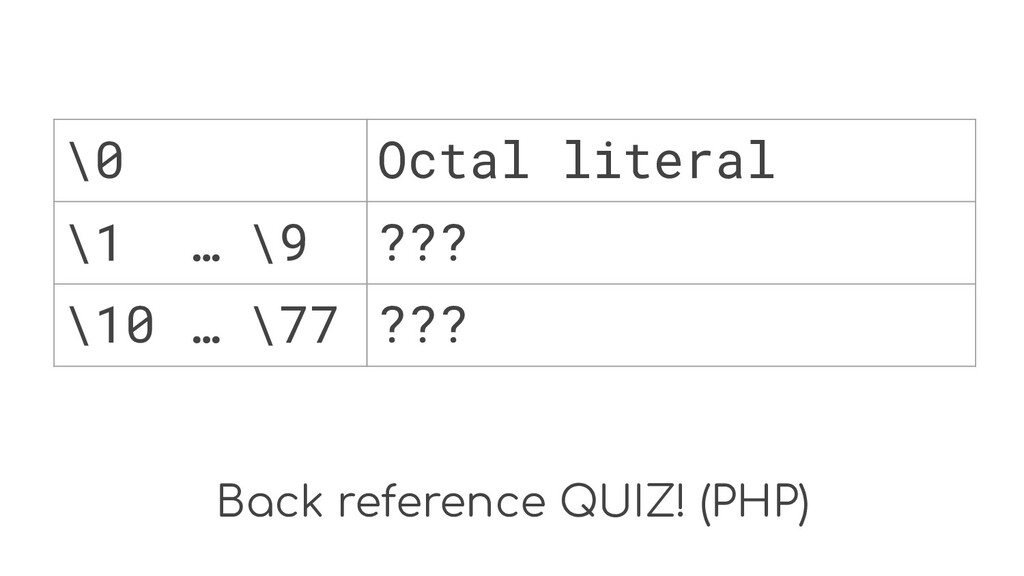
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
??? \10 … \77 ???
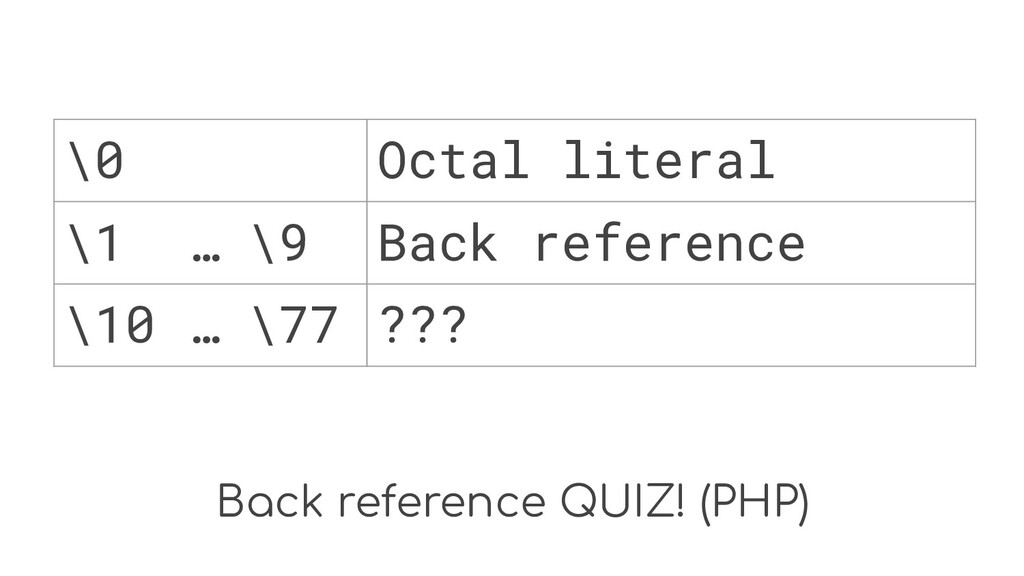
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
Back reference \10 … \77 ???
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
Back reference \10 … \77 It depends!
Groups flow • Capturing groups are numbered from left to
right. • Non-capturing groups are ignored. • Groups can have a name.
Finding bugs in regular expressions
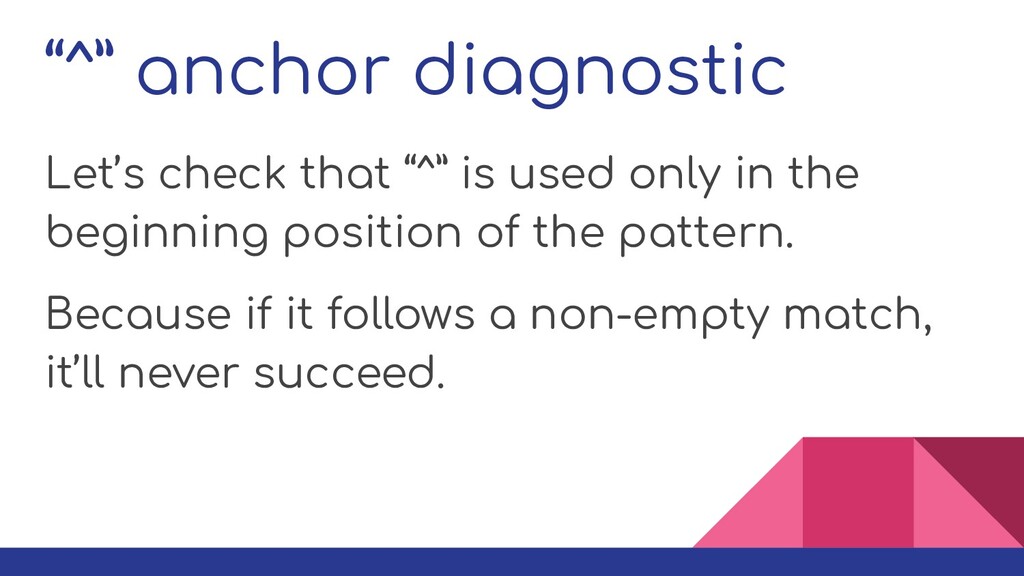
“^” anchor diagnostic Let’s check that “^” is used only
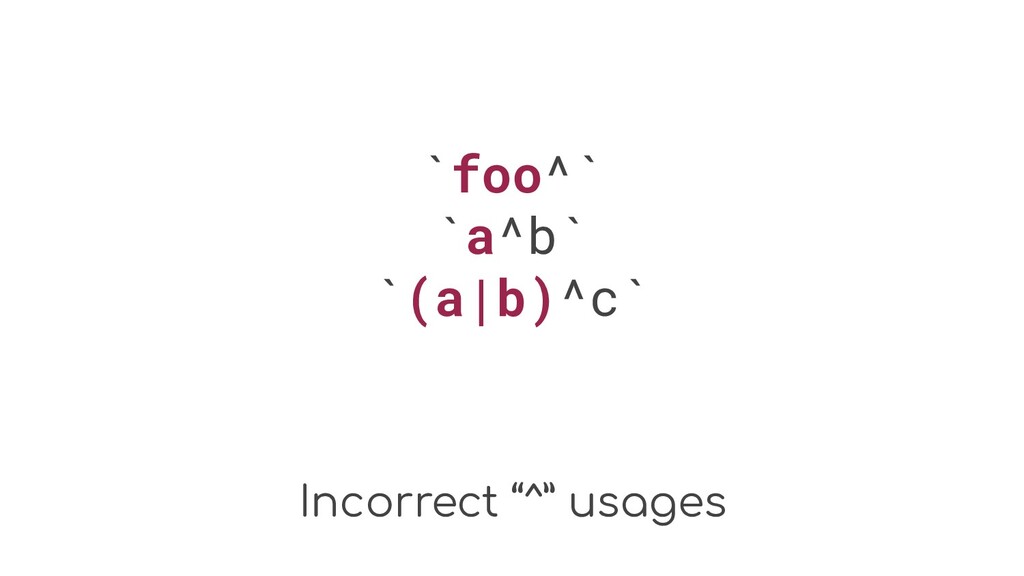
in the beginning position of the pattern. Because if it follows a non-empty match, it’ll never succeed.
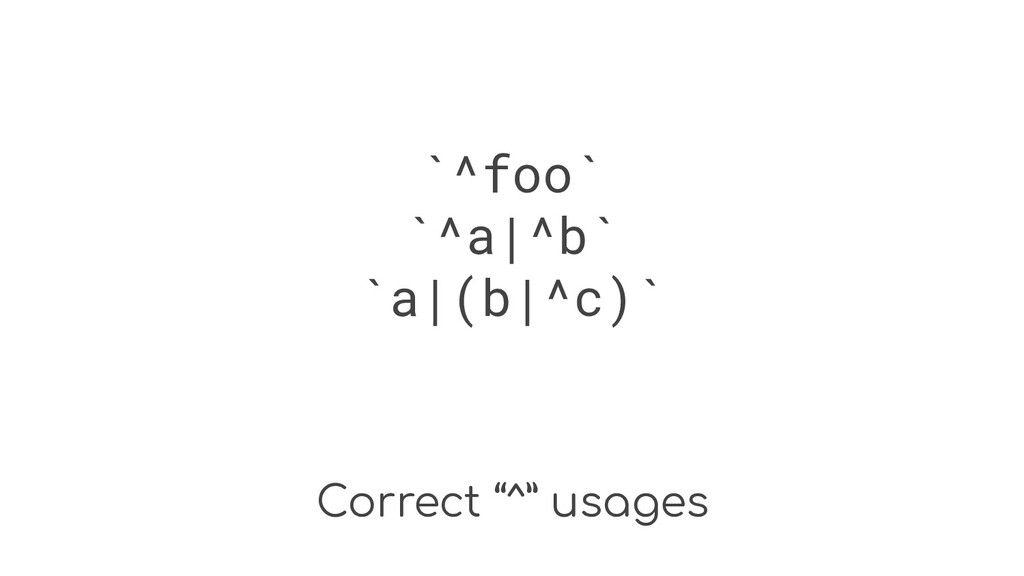
Correct “^” usages `^foo` `^a|^b` `a|(b|^c)`
Incorrect “^” usages `foo^` `a^b` `(a|b)^c`
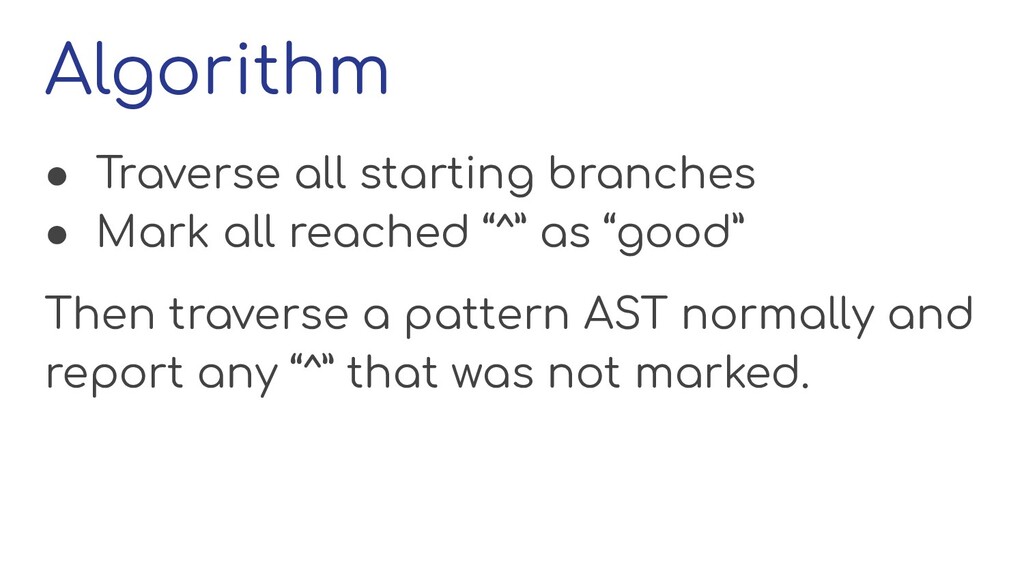
Algorithm • Traverse all starting branches • Mark all reached
“^” as “good” Then traverse a pattern AST normally and report any “^” that was not marked.
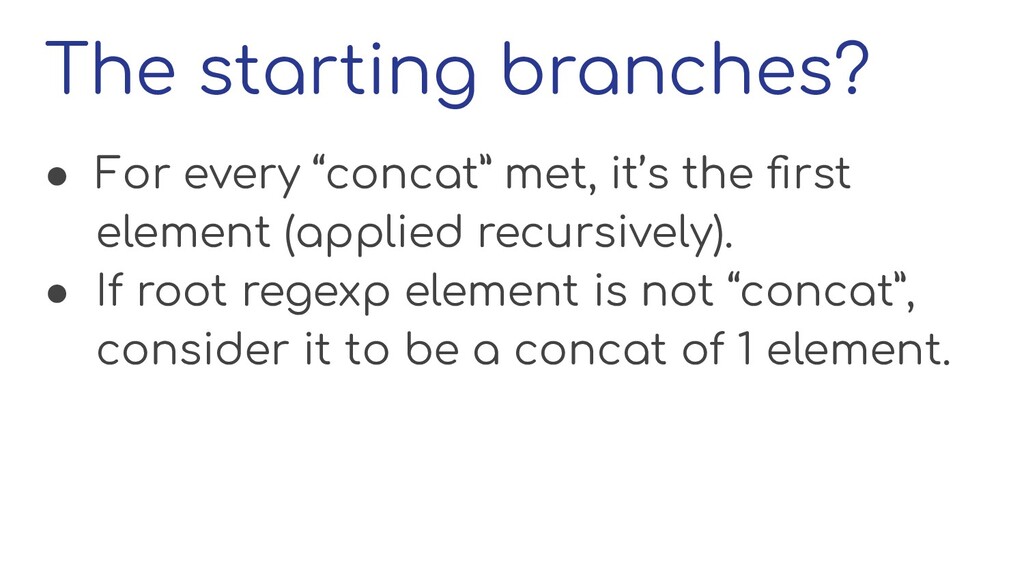
The starting branches? • For every “concat” met, it’s the
first element (applied recursively). • If root regexp element is not “concat”, consider it to be a concat of 1 element.
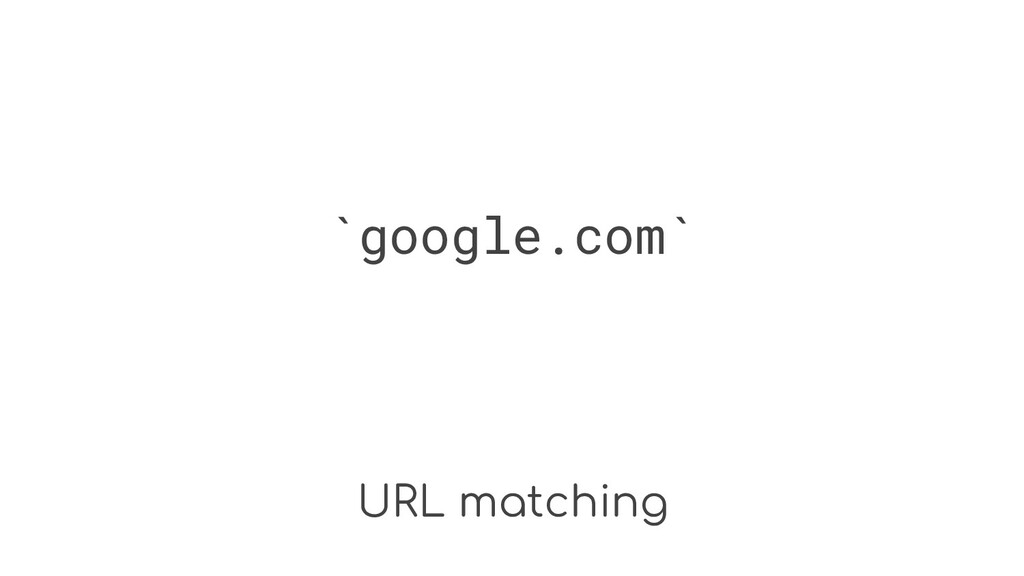
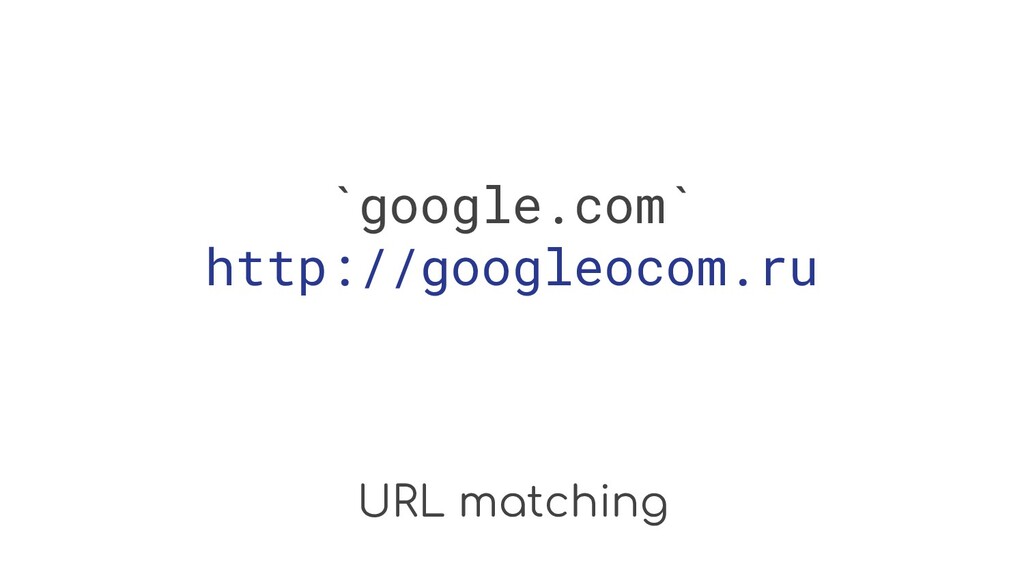
URL matching `google.com`
URL matching `google.com` http://googleocom.ru
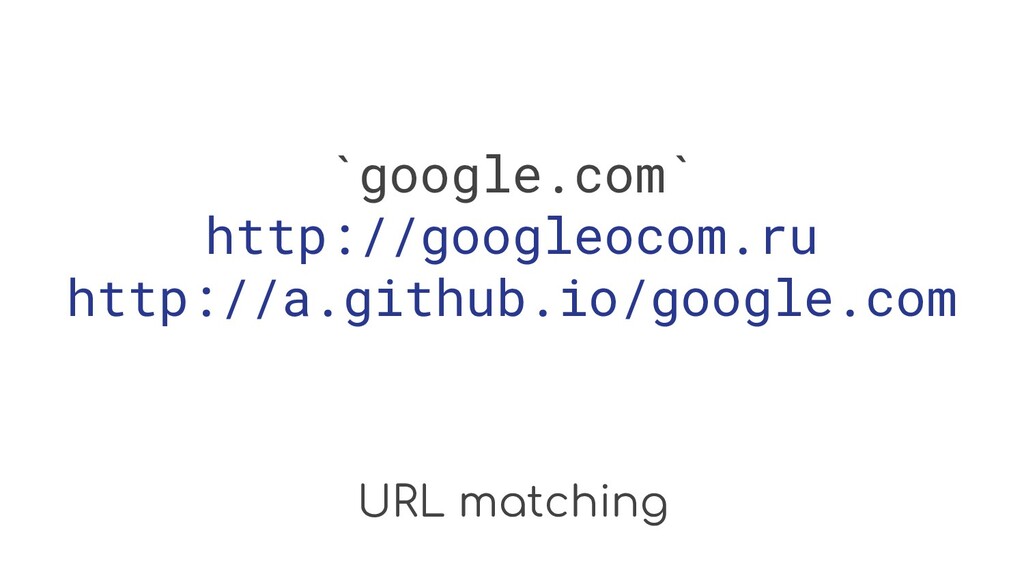
URL matching `google.com` http://googleocom.ru http://a.github.io/google.com
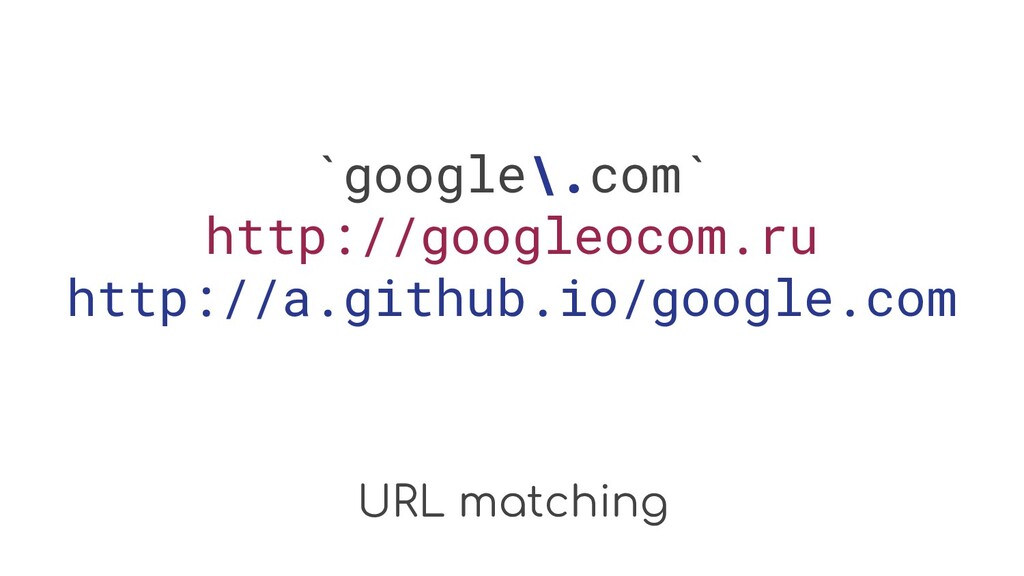
URL matching `google\.com` http://googleocom.ru http://a.github.io/google.com
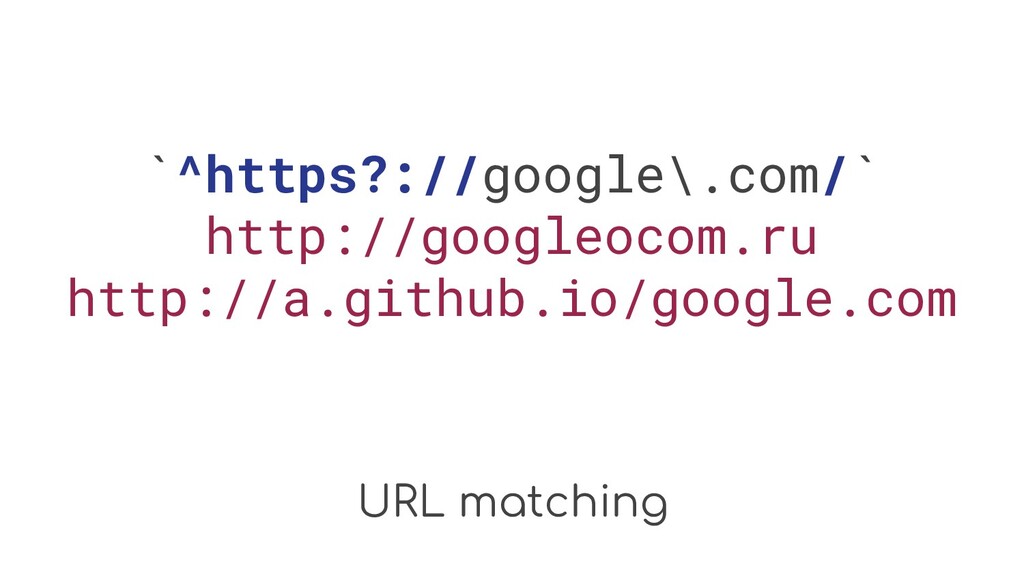
URL matching `^https?://google\.com/` http://googleocom.ru http://a.github.io/google.com
URL matching When “.” is used before common domain name
like “com”, it’s probably a mistake. If we have char sequences represented as a single AST node, this analysis is trivial.
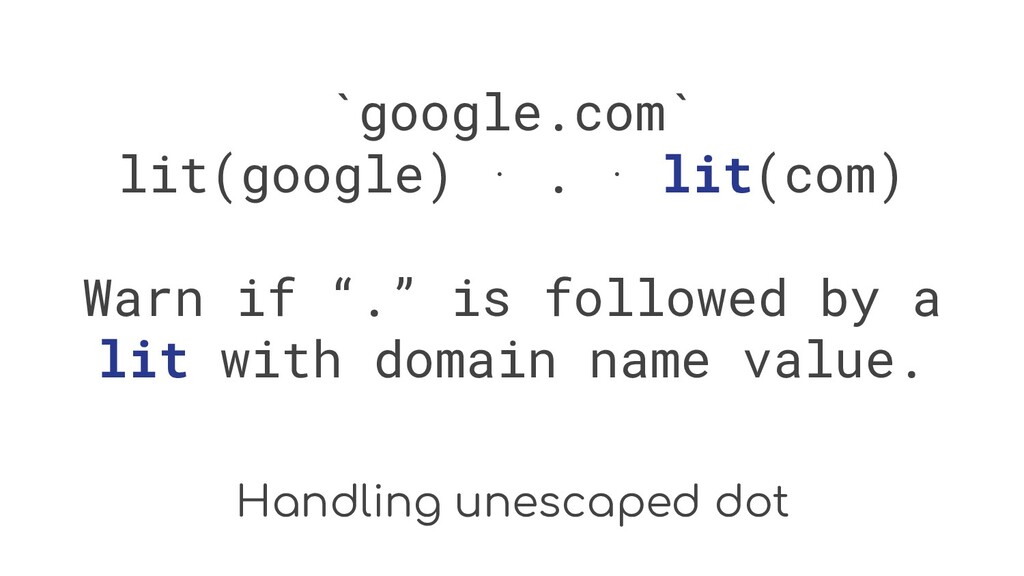
Handling unescaped dot `google.com` lit(google) ⋅ . ⋅ lit(com) Warn
if “.” is followed by a lit with domain name value.
Regexp rewriting
Regexp input generation It’s quite simple to generate a string
that will be matched by a regular expression if you have that regexp AST.
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa N matches of \w
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa7 1 match of [0-9]
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa7 May do nothing for $
Regexp input generation Generating a non-matching strings can be useful
for catastrophic backtracking evaluation.
Regexp simplification Instead of writing a matching characters we can
write the pattern syntax itself. By replacing recognized AST node sequences with something simpler, we can perform a regexp simplification.
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x)
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x) \d Can’t
simplify \d, write as is
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x) \dx+ xx*
-> x+
Oh, the possibilities! x{1,} -> x+ [a-z\d][a-z\d] -> [a-z\d]{2} [^\d]
-> \D a|b|c -> [abc]
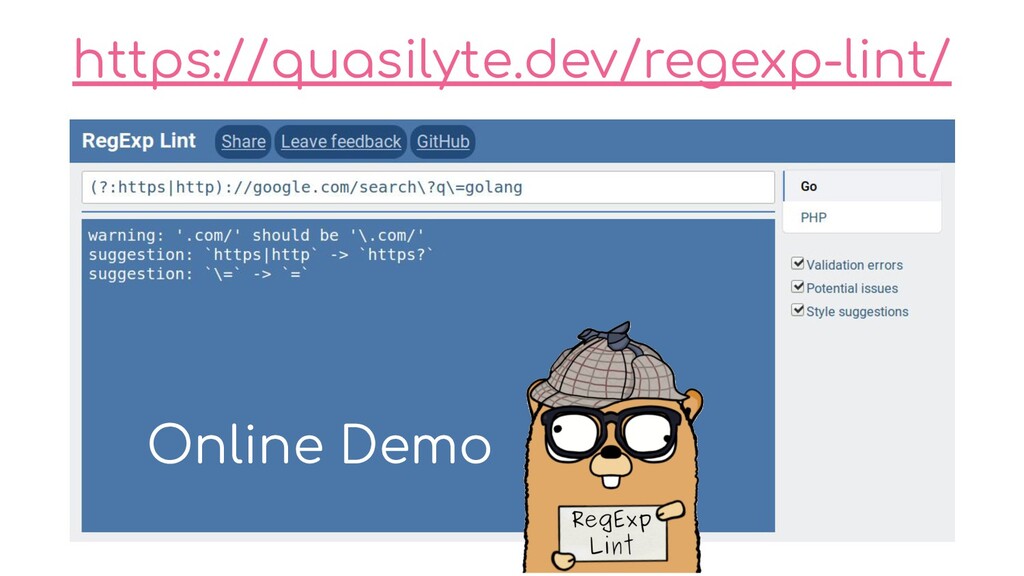
https://quasilyte.dev/regexp-lint/ Online Demo
Submit your ideas! :) If you have a particular regexp
simplification or bug pattern that is not detected by regexp-lint, let me know.
Thank you.


 quasilyte
 sodainc
 dalinaum
 l2hyunwoo
 miccheng
 utakaha
 sylph01
 koukimiura
 3saito
 a_matsuda
 guaca
 mixplace
 bethany
 codingconduct
 takai
 akosma
 ryanjones
 tomoyanonymous
 nikkihalliwell
 lara
 kastner
 swwweet
 techseoconnect


![Char classes syntax `[][]` A char class of “]” and](https://files.speakerdeck.com/presentations/80b2d4f016f84985a2e4aff96dbbccbd/slide_12.jpg)