Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Data at the Speed of your Users
Search
Rustam Aliyev
September 26, 2014
Technology
85
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Data at the Speed of your Users
Apache Cassandra and Spark for simple, distributed, near real-time stream processing.
Rustam Aliyev
September 26, 2014
More Decks by Rustam Aliyev
See All by Rustam Aliyev
From monolith web app to micro-frontends
rstml
0
970
Lightning Fast Analytics with Spark and Cassandra
rstml
2
330
Deep dive into CQL
rstml
1
76
Other Decks in Technology
See All in Technology
会社説明資料
persolserverworks
0
9.8k
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
130
サブエージェントと Claude Mods で作る独自 Advisor ツールの話
kenichiodo
2
160
分析AIエージェントを育てる、動く環境を育てる
codatum
1
1.1k
AI時代のPRレビューにどう向き合うか?
kairim0
1
240
Kiro Crewをはじめよう
kizawa2020
1
160
re:Invent初参加で変わったこと、2回目にやってみたいこと(JAWS-UG彩の国埼玉 #12)
mhrtech
2
220
Persisting Massive Data with Rails ~Designing for 60 billion rows, and fighting the bottlenecks~ Railsで挑む大量データ永続化 〜600億件を永続化するための設計とボトルネックとの戦い〜
occhi
0
730
Railsで挑む大量データ永続化 〜600億件を永続化するための設計とボトルネックとの戦い〜
occhi
1
580
go-sqletch
moznion
0
140
Active Record Connection Adaptersにおける長年の課題に再び取り組む
yahonda
0
150
今さら理解するウェブフォントver.2026
takanorip
3
770
Featured
See All Featured
Faster Mobile Websites
deanohume
310
32k
[RailsConf 2023] Rails as a piece of cake
palkan
59
7.1k
Effective software design: The role of men in debugging patriarchy in IT @ Voxxed Days AMS
baasie
1
570
The SEO identity crisis: Don't let AI make you average
varn
0
590
SEO for Brand Visibility & Recognition
aleyda
0
4.8k
Claude Code どこまでも/ Claude Code Everywhere
nwiizo
68
59k
Building a Modern Day E-commerce SEO Strategy
aleyda
45
9.3k
Sam Torres - BigQuery for SEOs
techseoconnect
PRO
0
580
Why You Should Never Use an ORM
jnunemaker
PRO
61
10k
Impact Scores and Hybrid Strategies: The future of link building
tamaranovitovic
0
460
技術選定の審美眼(2025年版) / Understanding the Spiral of Technologies 2025 edition
twada
PRO
120
120k
The Curse of the Amulet
leimatthew05
3
16k
Transcript
Data at the Speed of your Users Apache Cassandra and
Spark for simple, distributed, near real-time stream processing. GOTO Copenhagen 2014
Rustam Aliyev Solution Architect at . ! ! @rstml
Big Data? Photo: Flickr / Watches En Masse
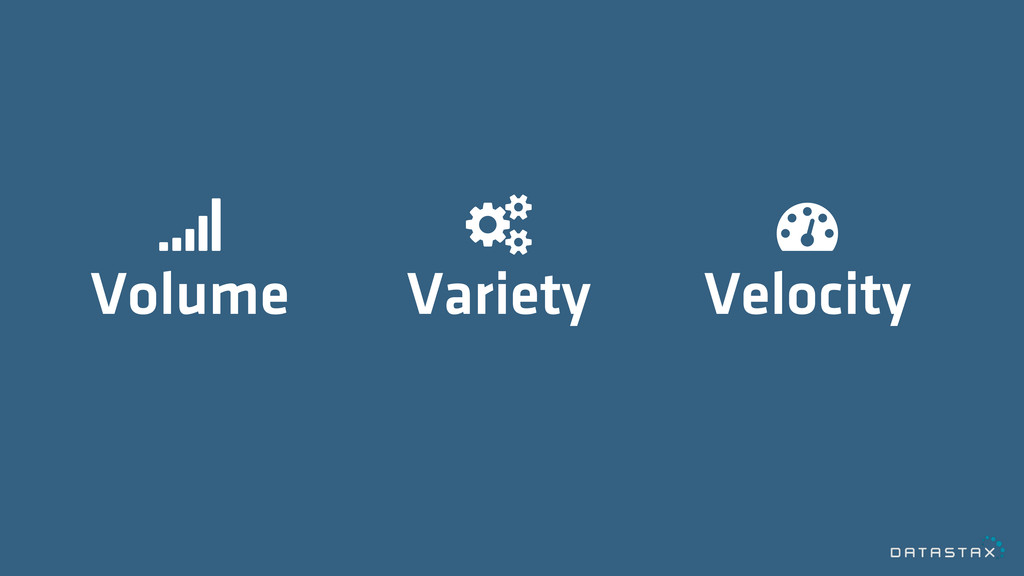
" Volume # Variety $ Velocity
Velocity = Near Real Time
Near Real Time?
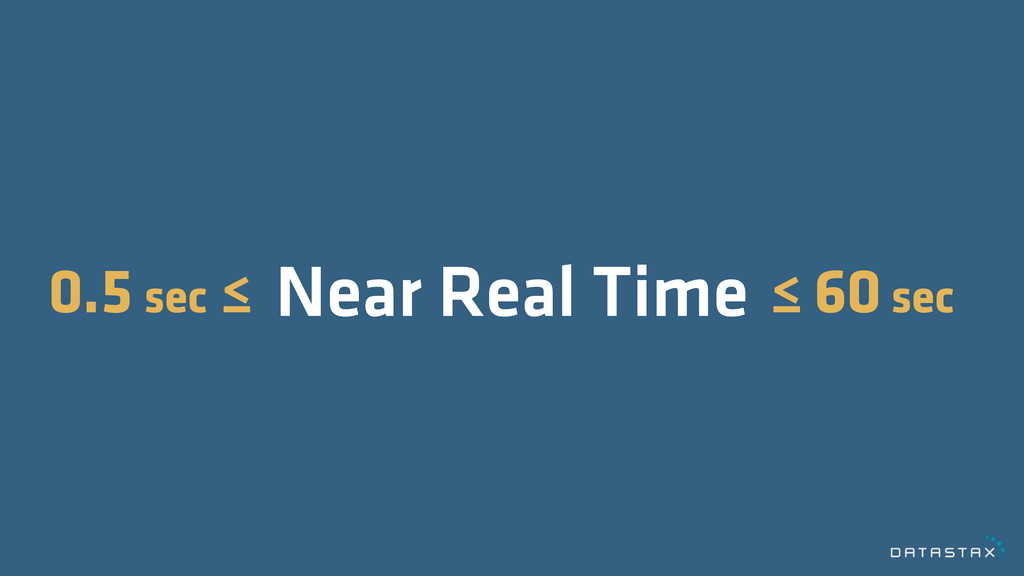
0.5 sec ≤ ≤ 60 sec Near Real Time
Use Cases Photo: Flickr / Swiss Army / Jim Pennucci
Web Analytics Dynamic Pricing Recommendation Fraud Detection
Architecture Photo: Ilkin Kangarli / Baku Haydar Aliyev Center
Architecture Goals Low Latency High Availability Horizontal Scalability Simplicity
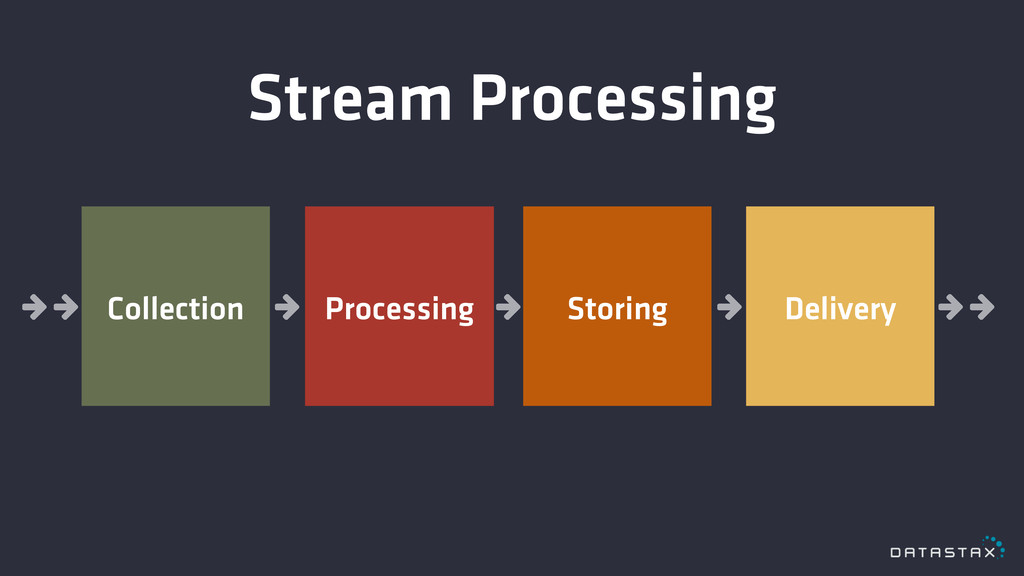
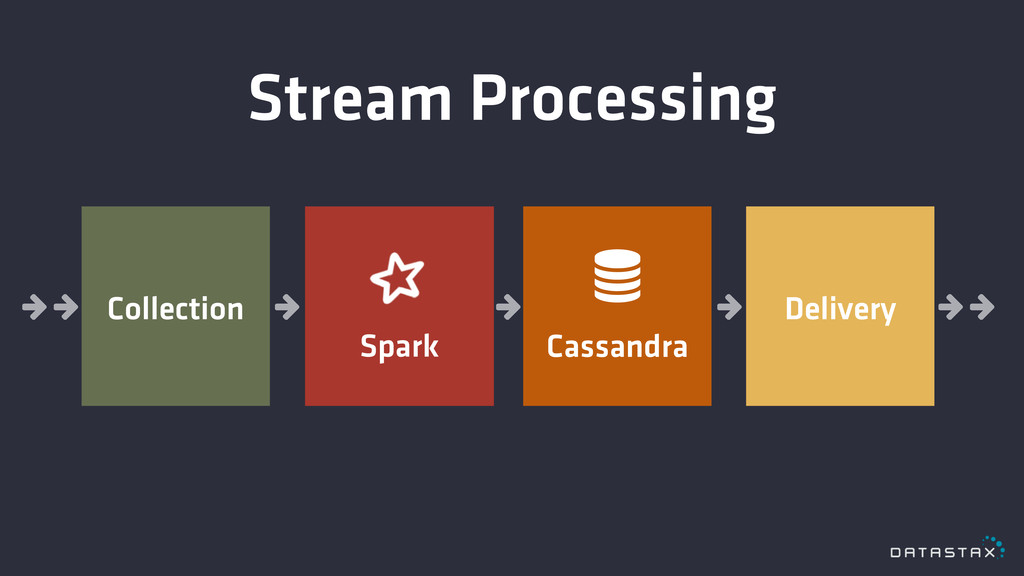
Stream Processing % % % % % % % %
% % % % % % % % % % % % % % % % % % % % % % % Collection Processing Storing Delivery
Stream Processing % % % % % % % %
% % % % % % % % % % % % % % % % % % % % % % % Collection ! ! Spark ! Cassandra Delivery
Cassandra Distributed Database Photo: Flickr / Hypostyle Hall / Jorge
Láscar
Data Model
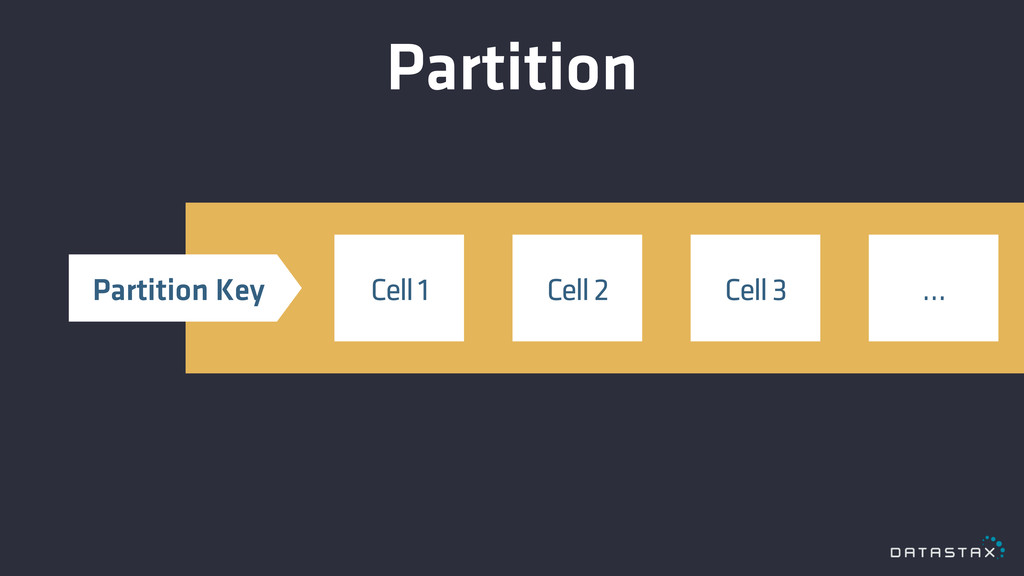
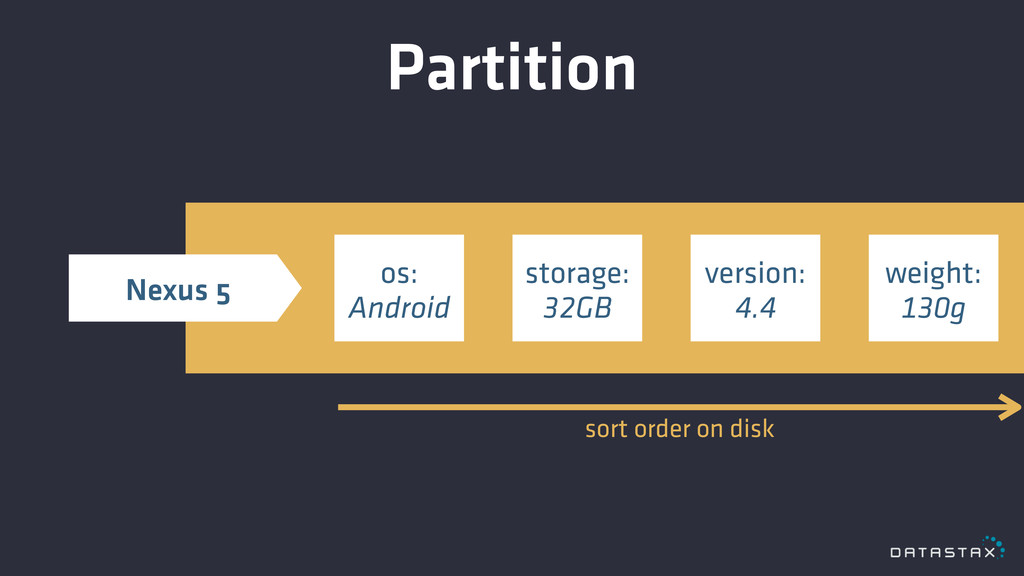
Partition Cell 1 Cell 2 … Cell 3 Partition Key
Partition os: Android storage: 32GB version: 4.4 weight: 130g sort
order on disk Nexus 5
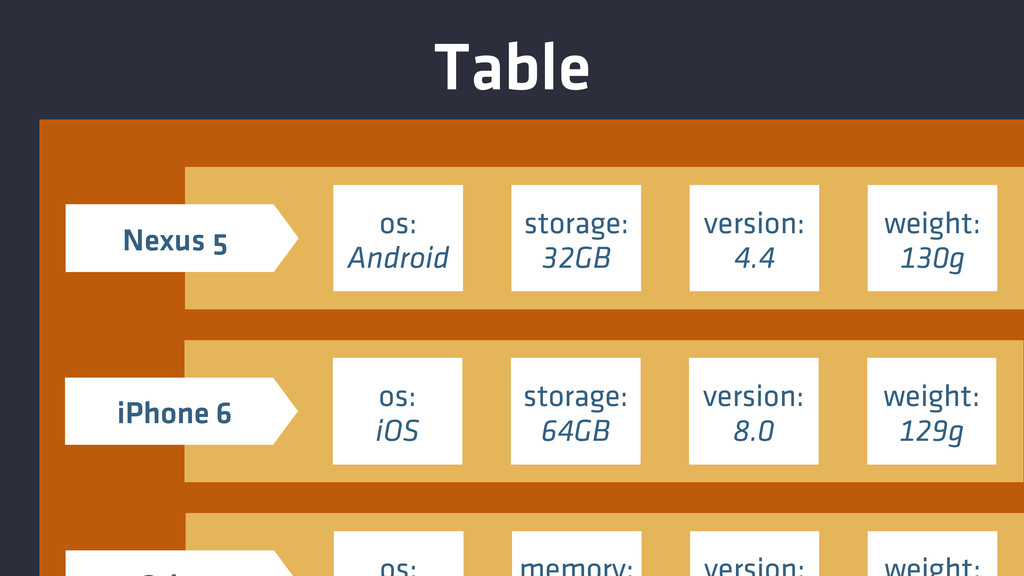
Table os: Android storage: 32GB version: 4.4 weight: 130g Nexus
5 os: iOS storage: 64GB version: 8.0 weight: 129g iPhone 6
Distribution
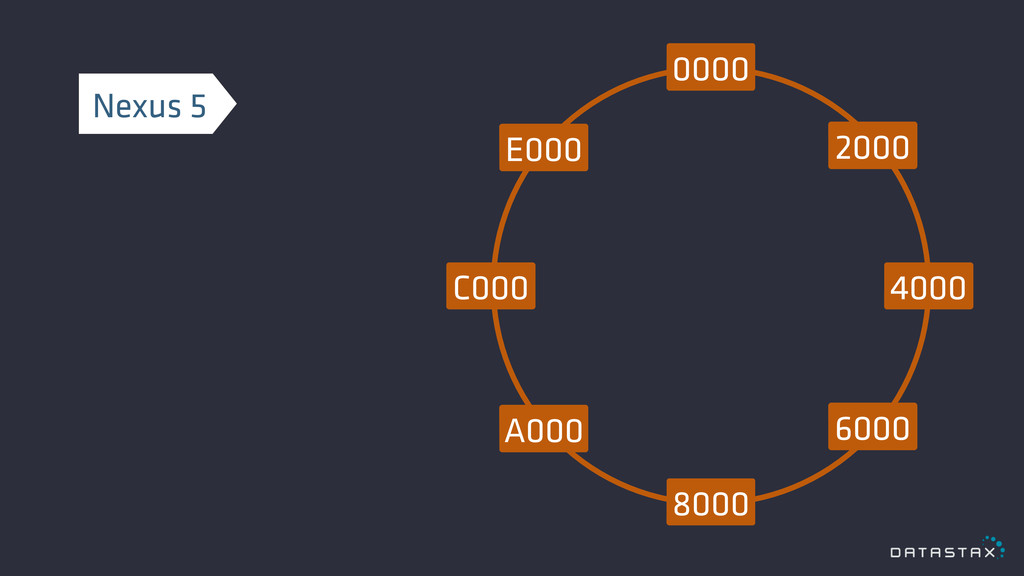
0000 8000 4000 C000 2000 6000 E000 A000 3D97 Nexus
5
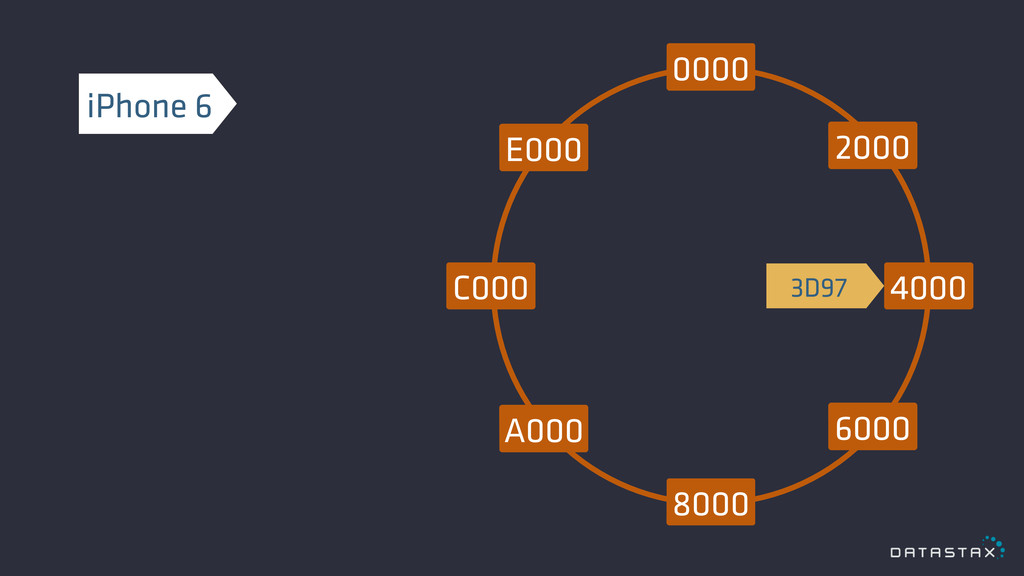
0000 8000 4000 C000 2000 6000 E000 A000 9C4F iPhone
6 3D97
Replication
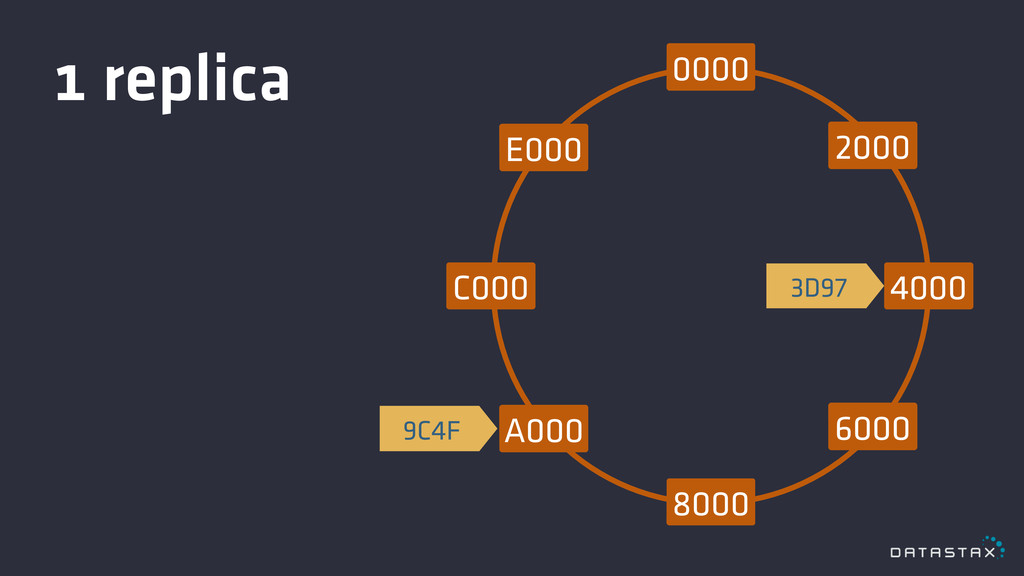
0000 8000 4000 C000 2000 6000 E000 A000 3D97 9C4F
1 replica
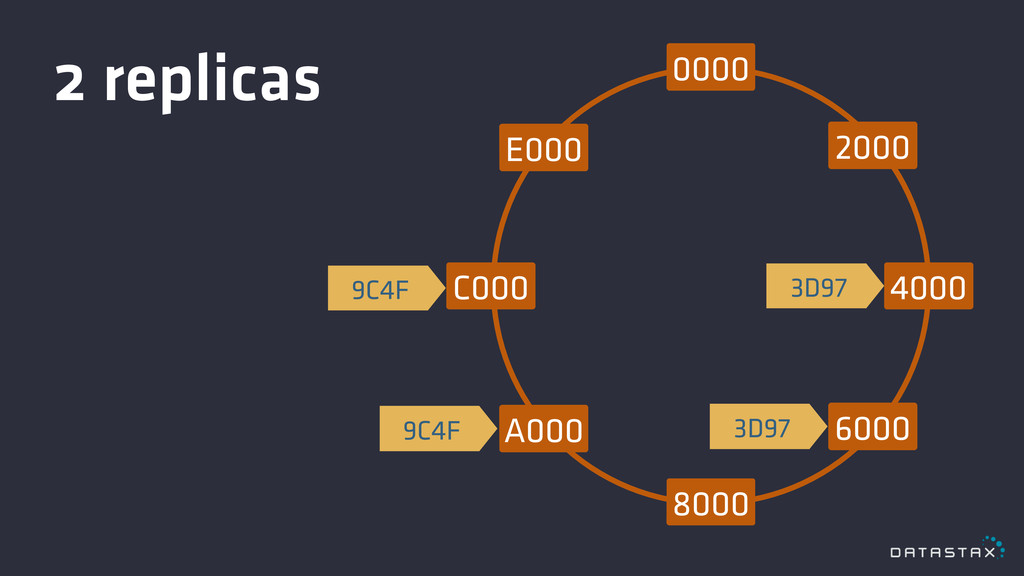
0000 8000 4000 C000 2000 6000 E000 A000 3D97 9C4F
9C4F 3D97 2 replicas
Spark Distributed Data Processing Engine Photo: Flickr / Sparklers /
Alexandra Compo / CreativeCommons
Fast In-memory
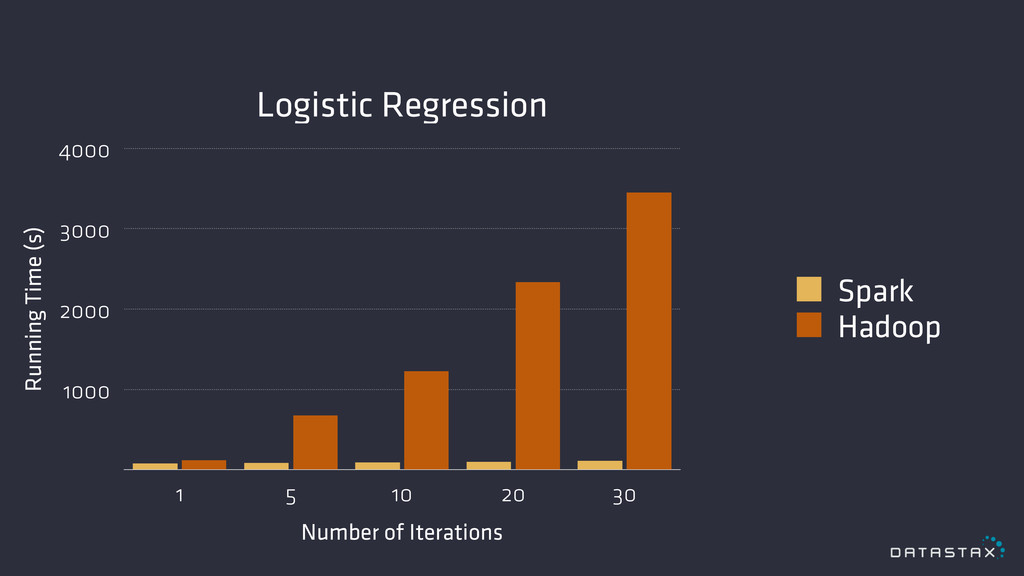
Logistic Regression Running Time (s) 1000 2000 3000 4000 Number
of Iterations 1 5 10 20 30 Spark Hadoop
Easy
map ! reduce
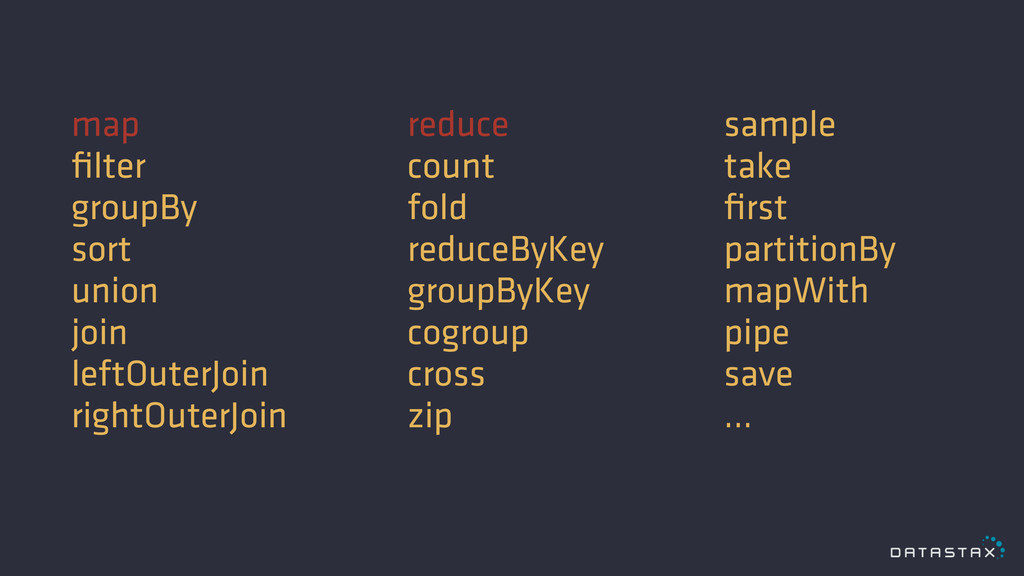
map filter groupBy sort union join leftOuterJoin rightOuterJoin reduce count
fold reduceByKey groupByKey cogroup cross zip sample take first partitionBy mapWith pipe save ...
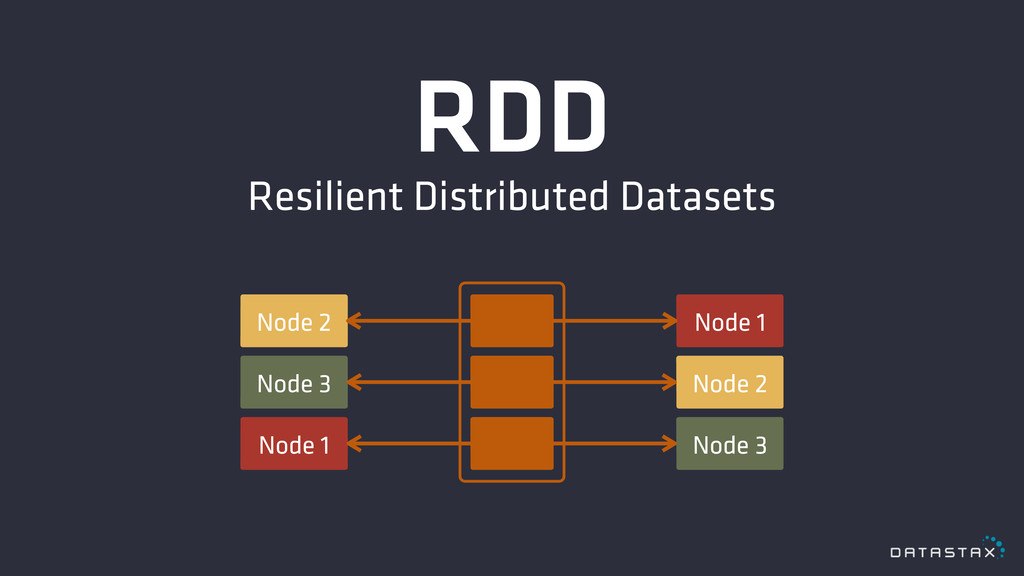
RDD Resilient Distributed Datasets Node 1 Node 2 Node 3
Node 1 Node 2 Node 3
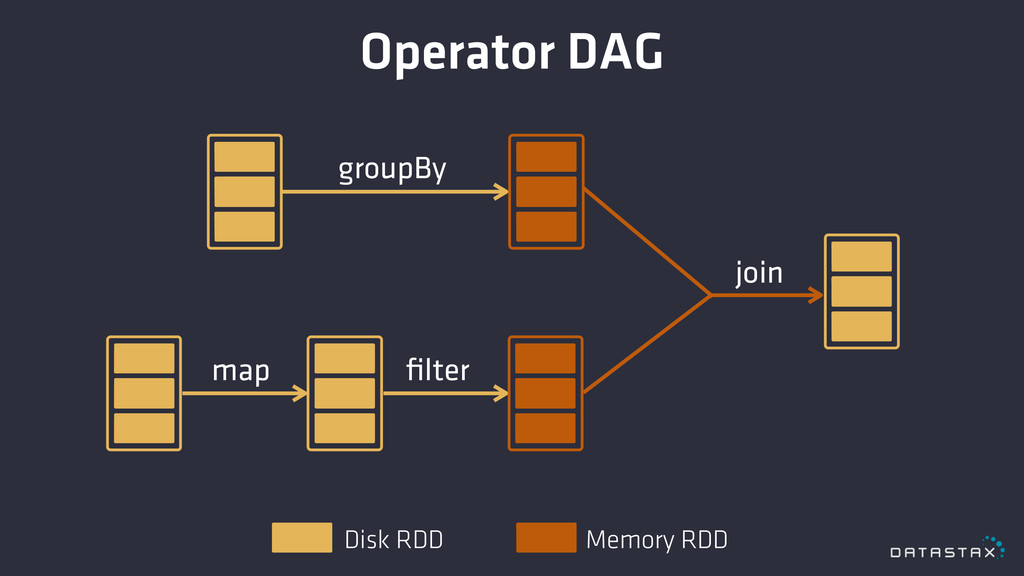
Operator DAG groupBy join filter map Disk RDD Memory RDD
Spark Streaming Micro-batching
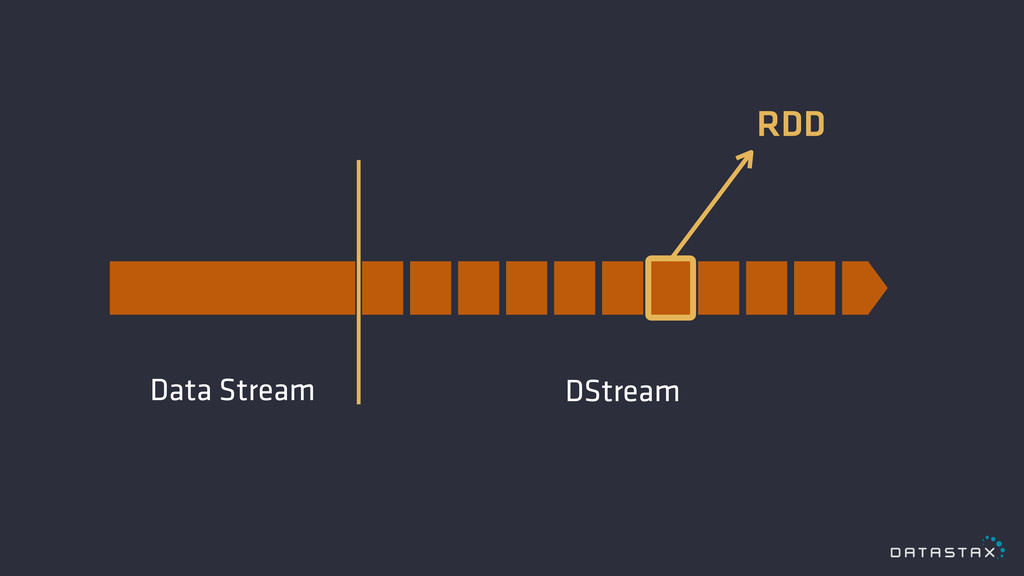
RDD DStream Data Stream
Spark + Cassandra DataStax Spark Cassandra Connector
https://github.com/datastax/spark-cassandra-connector
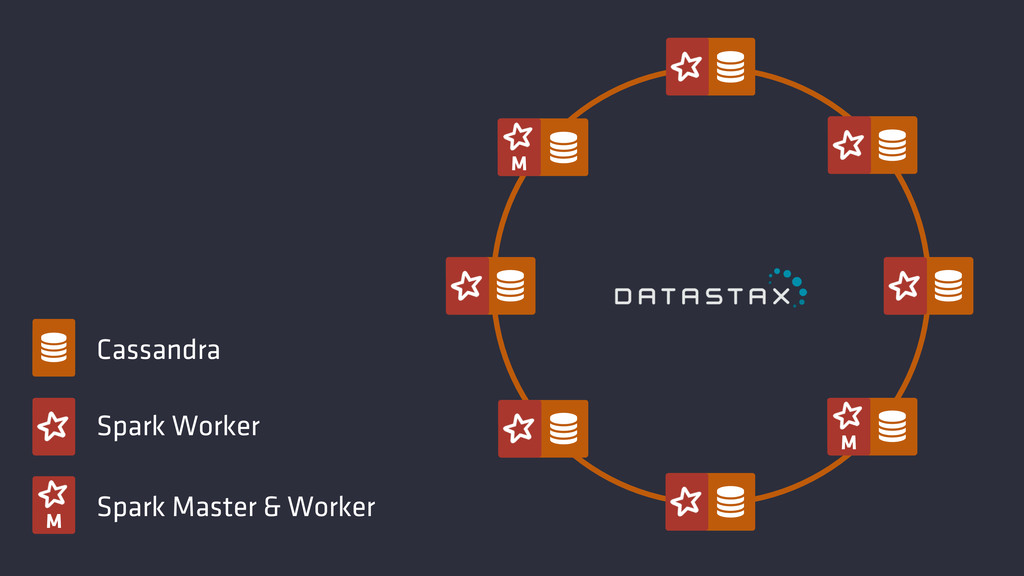
M M
M Cassandra Spark Worker Spark Master & Worker
Demo ! ! Twitter Analytics
Cassandra Data Model
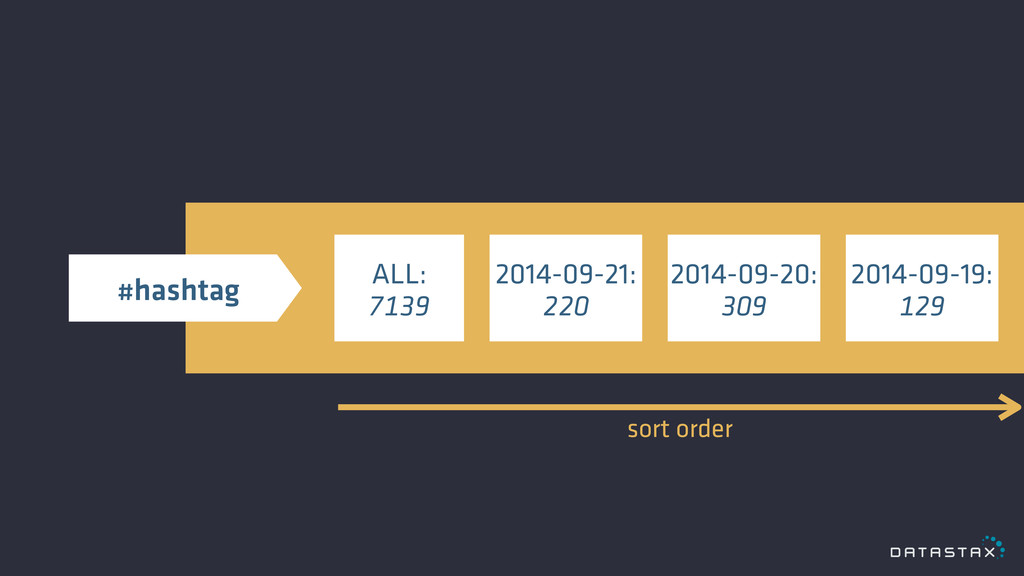
ALL: 7139 2014-09-21: 220 2014-09-20: 309 2014-09-19: 129 sort order
#hashtag
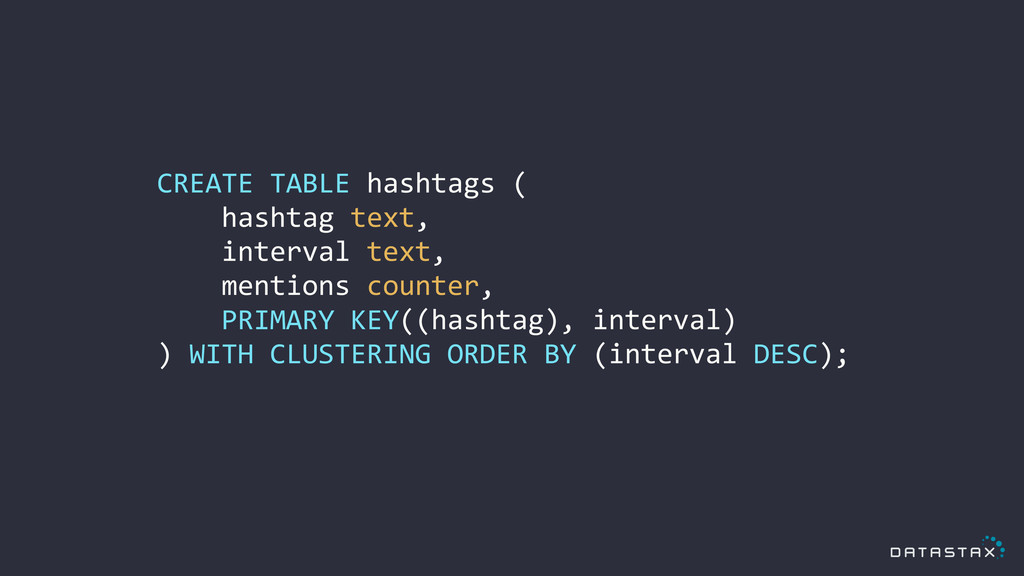
CREATE TABLE hashtags ( hashtag text,
interval text, mentions counter, PRIMARY KEY((hashtag), interval) ) WITH CLUSTERING ORDER BY (interval DESC);
Processing Data Stream
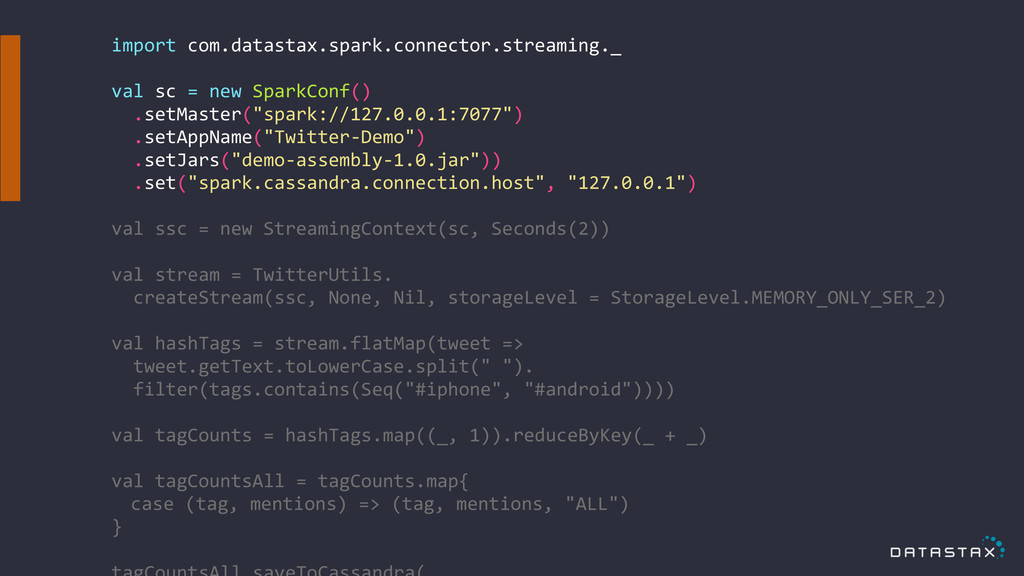
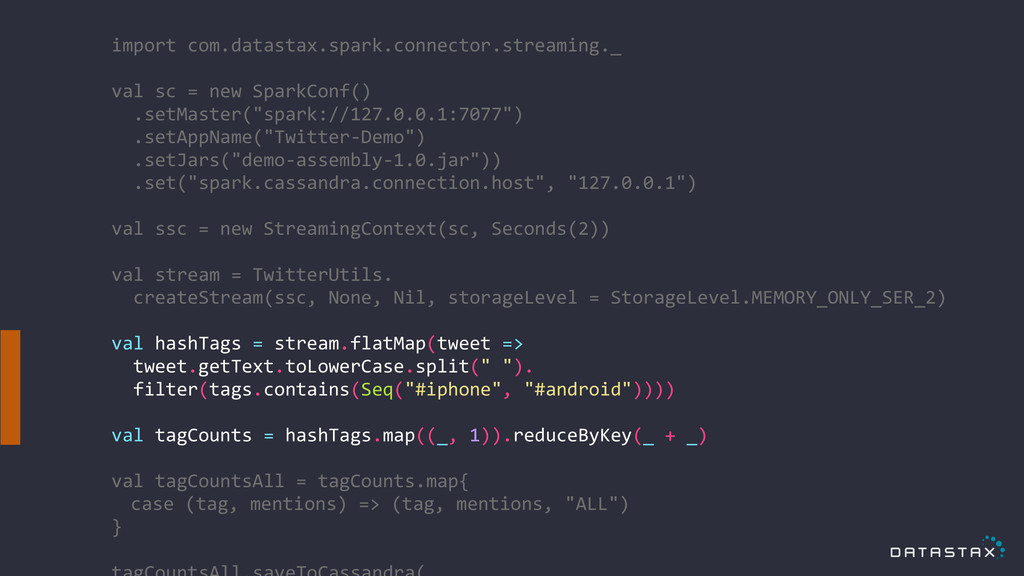
import com.datastax.spark.connector.streaming._ ! val sc = new SparkConf()
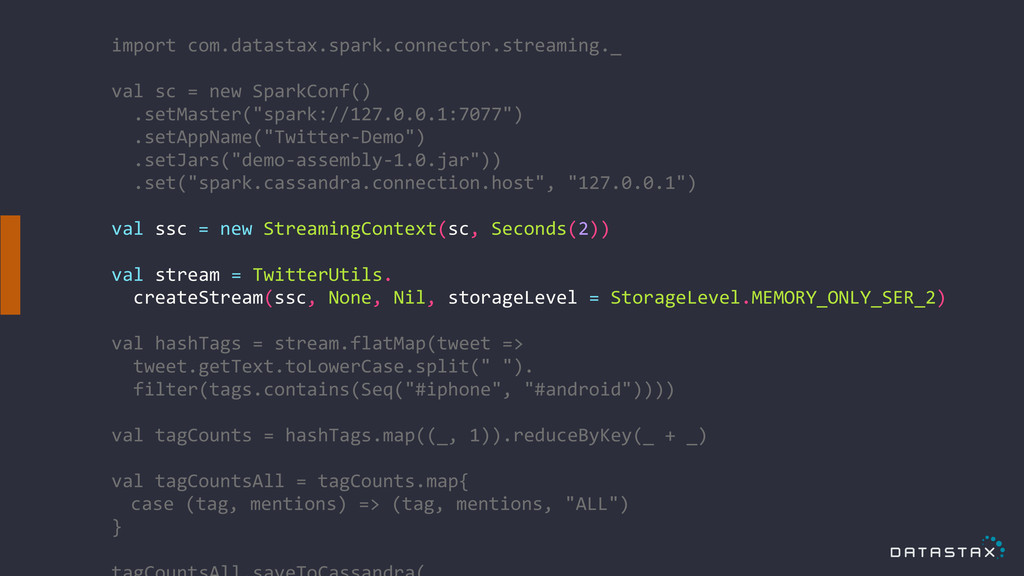
.setMaster("spark://127.0.0.1:7077") .setAppName("Twitter-‐Demo") .setJars("demo-‐assembly-‐1.0.jar")) .set("spark.cassandra.connection.host", "127.0.0.1") ! val ssc = new StreamingContext(sc, Seconds(2)) ! val stream = TwitterUtils. createStream(ssc, None, Nil, storageLevel = StorageLevel.MEMORY_ONLY_SER_2) ! val hashTags = stream.flatMap(tweet => tweet.getText.toLowerCase.split(" "). filter(tags.contains(Seq("#iphone", "#android")))) ! val tagCounts = hashTags.map((_, 1)).reduceByKey(_ + _) ! val tagCountsAll = tagCounts.map{ case (tag, mentions) => (tag, mentions, "ALL") } !
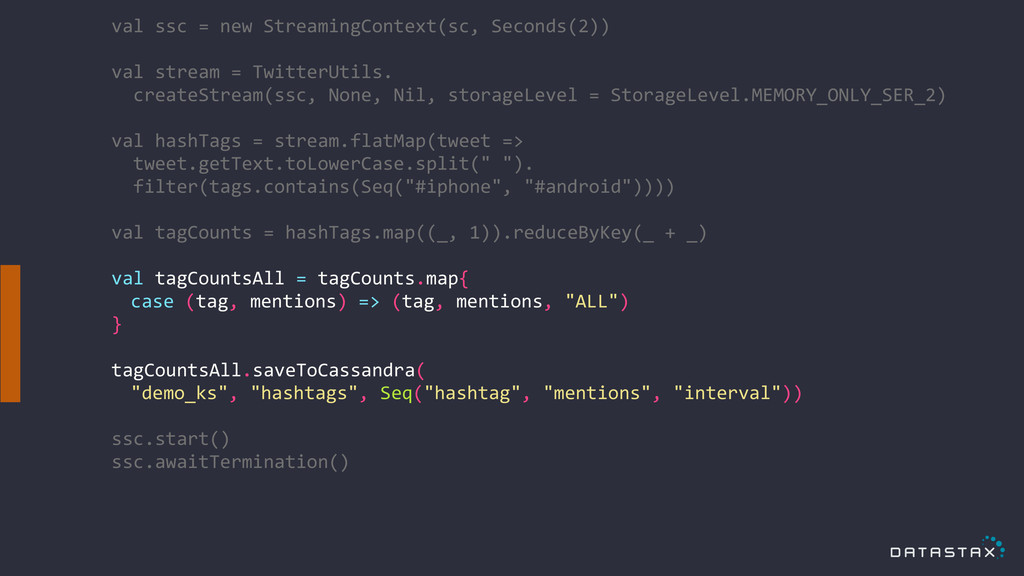
! val ssc = new StreamingContext(sc, Seconds(2)) ! val
stream = TwitterUtils. createStream(ssc, None, Nil, storageLevel = StorageLevel.MEMORY_ONLY_SER_2) ! val hashTags = stream.flatMap(tweet => tweet.getText.toLowerCase.split(" "). filter(tags.contains(Seq("#iphone", "#android")))) ! val tagCounts = hashTags.map((_, 1)).reduceByKey(_ + _) ! val tagCountsAll = tagCounts.map{ case (tag, mentions) => (tag, mentions, "ALL") } ! tagCountsAll.saveToCassandra( "demo_ks", "hashtags", Seq("hashtag", "mentions", "interval")) ! ssc.start() ssc.awaitTermination()
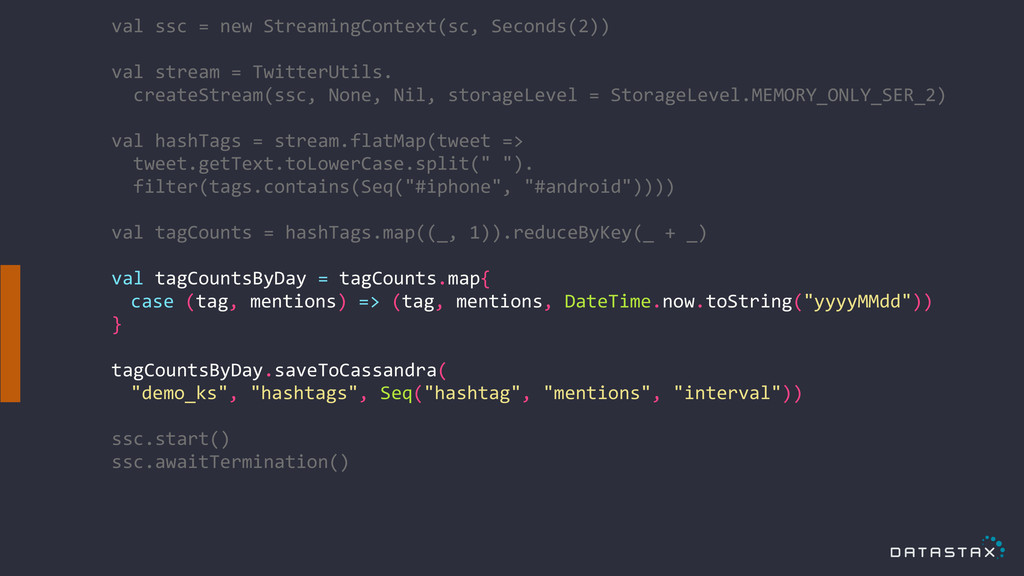
! val ssc = new StreamingContext(sc, Seconds(2)) ! val
stream = TwitterUtils. createStream(ssc, None, Nil, storageLevel = StorageLevel.MEMORY_ONLY_SER_2) ! val hashTags = stream.flatMap(tweet => tweet.getText.toLowerCase.split(" "). filter(tags.contains(Seq("#iphone", "#android")))) ! val tagCounts = hashTags.map((_, 1)).reduceByKey(_ + _) ! val tagCountsByDay = tagCounts.map{ case (tag, mentions) => (tag, mentions, DateTime.now.toString("yyyyMMdd")) } ! tagCountsByDay.saveToCassandra( "demo_ks", "hashtags", Seq("hashtag", "mentions", "interval")) ! ssc.start() ssc.awaitTermination()
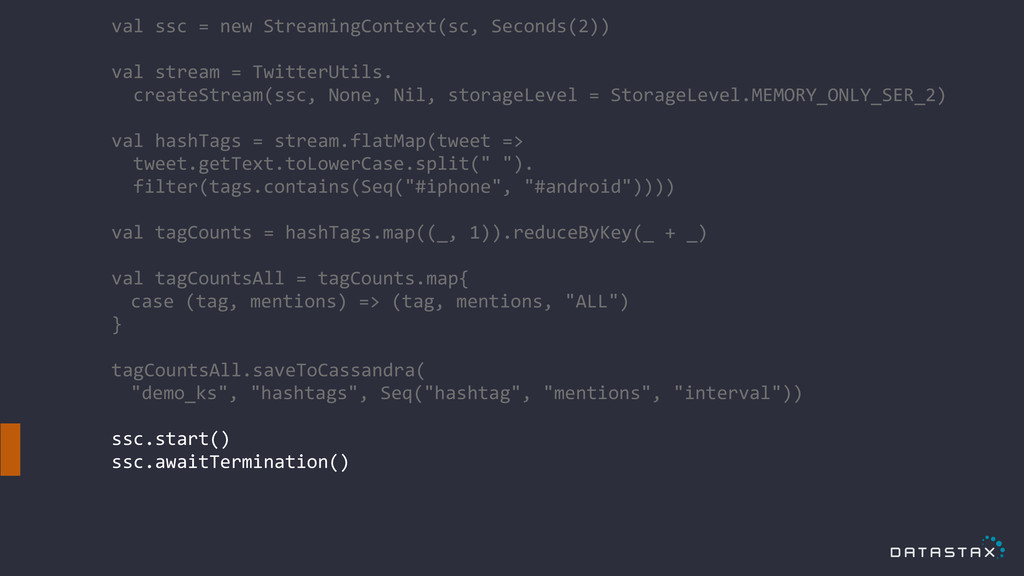
! val ssc = new StreamingContext(sc, Seconds(2)) ! val
stream = TwitterUtils. createStream(ssc, None, Nil, storageLevel = StorageLevel.MEMORY_ONLY_SER_2) ! val hashTags = stream.flatMap(tweet => tweet.getText.toLowerCase.split(" "). filter(tags.contains(Seq("#iphone", "#android")))) ! val tagCounts = hashTags.map((_, 1)).reduceByKey(_ + _) ! val tagCountsAll = tagCounts.map{ case (tag, mentions) => (tag, mentions, "ALL") } ! tagCountsAll.saveToCassandra( "demo_ks", "hashtags", Seq("hashtag", "mentions", "interval")) ! ssc.start() ssc.awaitTermination()
Questions ?


 rstml
 persolserverworks
 pfn
 kenichiodo
 codatum
 kairim0
 kizawa2020
 mhrtech
 occhi
 moznion
 yahonda
 takanorip
 deanohume
 palkan
 baasie
 varn
 aleyda
 nwiizo
 techseoconnect
 jnunemaker
 tamaranovitovic
 twada
 leimatthew05