Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Hybrid Autoregressive Transducer [輪講発表資料]
Search
shibutani
June 22, 2022
Research
510
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Hybrid Autoregressive Transducer [輪講発表資料]
Hybrid Autoregressive Transducer に関する輪講発表資料です。
shibutani
June 22, 2022
More Decks by shibutani
See All by shibutani
AIで進めるQA自動化の現在地 - E2Eリグレッションテストの整備と維持 -
shibukazu
9
4.1k
越境するAIのために、境界を取り払う - AI 時代の開発体験向上に向けたリポジトリ統合の取り組み -
shibukazu
1
770
メッセージキュー型の非同期処理から Temporal 移行へ
shibukazu
4
5.9k
はじめてのOSS開発からみえたGo言語の強み
shibukazu
4
1.6k
全自動コードレビューの夢 〜実際に活用されるAIコードレビューの実現に向けて〜
shibukazu
11
5.8k
Perceiver: General Perception with Iterative [輪講発表資料]
shibukazu
0
150
Other Decks in Research
See All in Research
[UAI2026, Tutorial Talk] Tensor Networks for Density Estimation: The merits of low-rank structures, tractable inference, and uncertainty quantification
gkazunii
0
110
Volatilité des marchés et sécheresse historique, l’élevage bovin viande sous contraintes en 2026
institutdelelevage
PRO
0
180
就労支援の現場での生成AI活用
enochan
0
180
フィジカルAIの社会実装に向けて -AIエージェントからAgentic Roboticsへ-
hf149
1
2.6k
Sleuthcon Keynote - How Cybercriminals (ab)use AI
fr0gger
0
430
Pretrain Where? Investigating How Pretraining Data Diversity Impacts Geospatial Foundation Model Performance
satai
3
190
Byzantine Eventual Consistency for Reliable Local-First Software
ept
0
320
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
230
【令和7年度版】内航船 VS 外航船 早見表
anikisencyo
0
160
湯村研究室の紹介2026 / yumulab2026
yumulab
0
190
JPA2026_NetworkTutorial_JunKashihara
junkashihara
0
250
Prithvi-EO-2.0
satai
3
110
Featured
See All Featured
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
720
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k
Darren the Foodie - Storyboard
khoart
PRO
4
4k
A Tale of Four Properties
chriscoyier
163
24k
The AI Search Optimization Roadmap by Aleyda Solis
aleyda
2
6.4k
Paper Plane
katiecoart
PRO
5
54k
Future Trends and Review - Lecture 12 - Web Technologies (1019888BNR)
signer
PRO
0
3.8k
The Straight Up "How To Draw Better" Workshop
denniskardys
239
140k
The Illustrated Guide to Node.js - THAT Conference 2024
reverentgeek
1
590
Reflections from 52 weeks, 52 projects
jeffersonlam
356
22k
Getting science done with accelerated Python computing platforms
jacobtomlinson
2
560
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
Transcript
Hybrid Autoregressive Transducer (HAT) [Variani, Rybach+ 2020] 京都大学 音声メディア研究室 M1
渋谷和樹 1
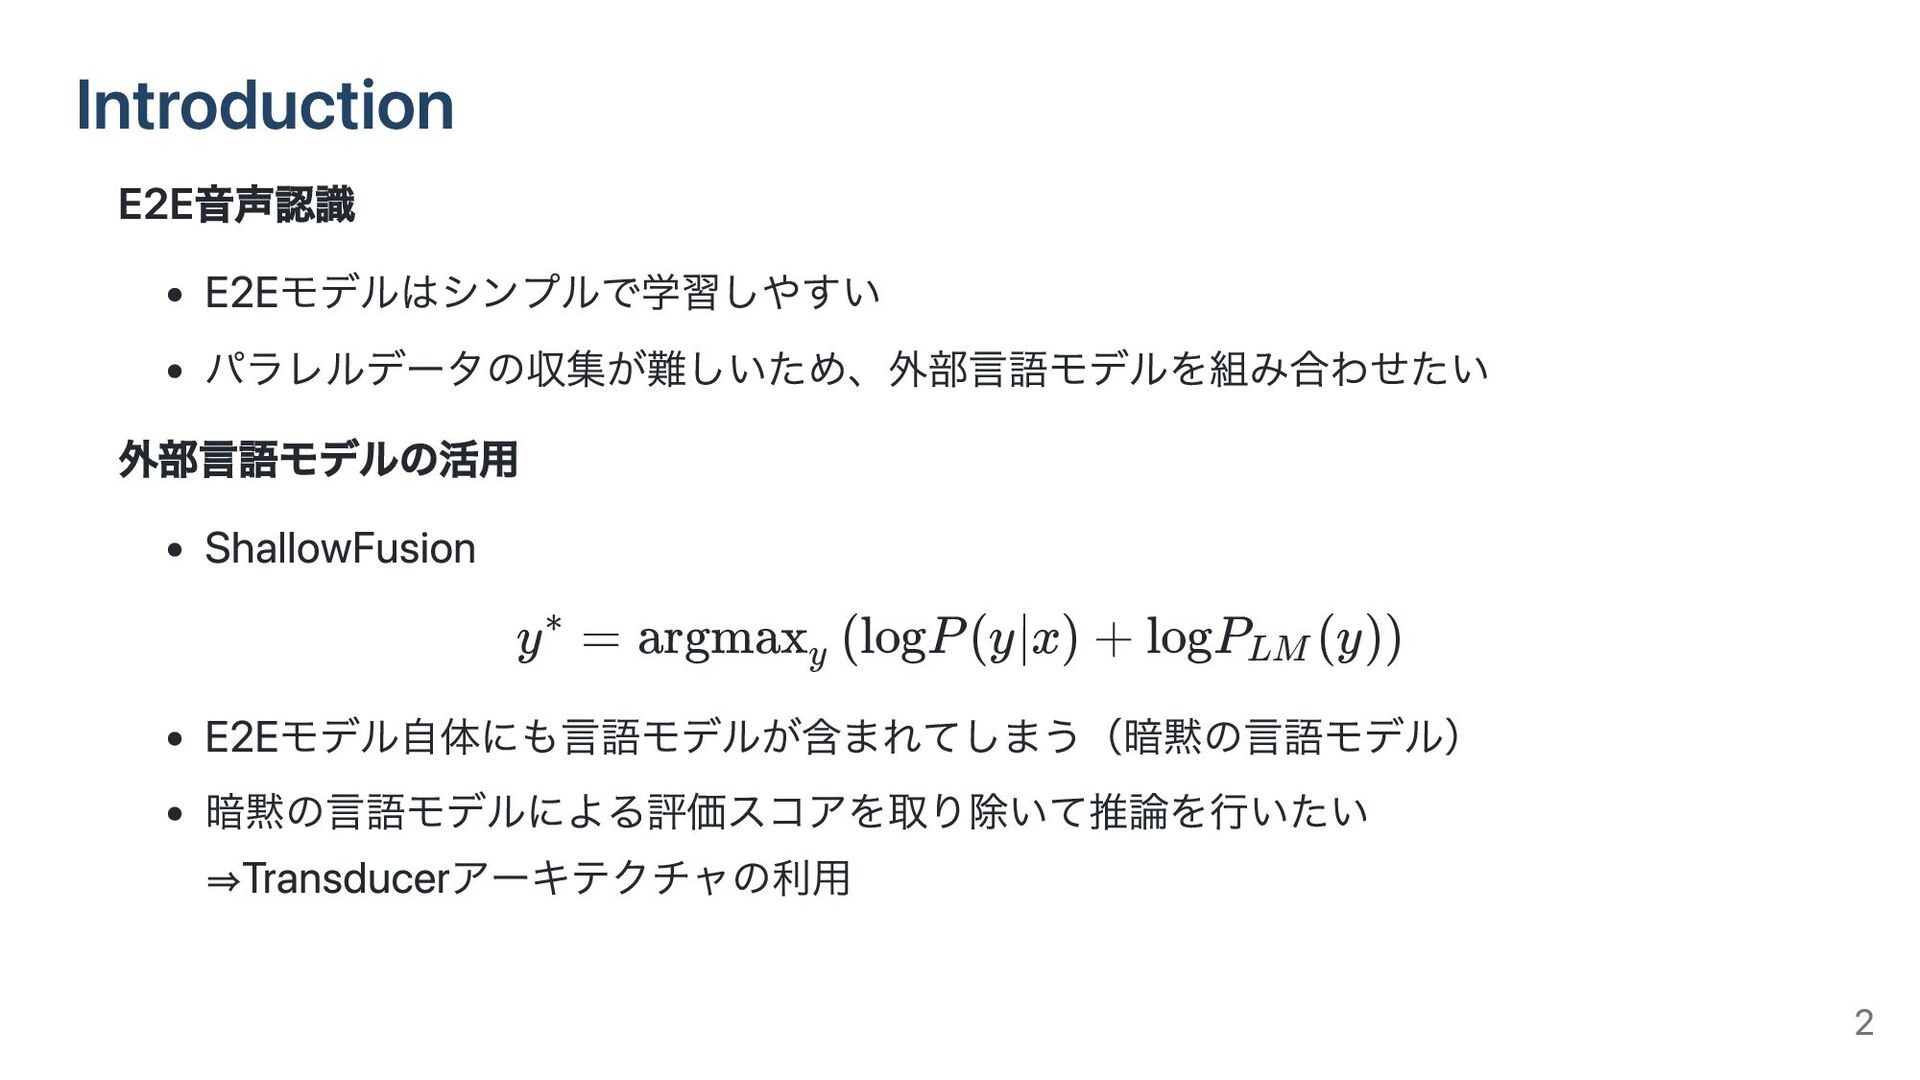
E2E音声認識 E2Eモデルはシンプルで学習しやすい パラレルデータの収集が難しいため、外部言語モデルを組み合わせたい 外部言語モデルの活用 ShallowFusion y = ∗ argmax
logP(y∣x) + logP (y) y ( LM ) E2Eモデル自体にも言語モデルが含まれてしまう(暗黙の言語モデル) 暗黙の言語モデルによる評価スコアを取り除いて推論を行いたい ⇒Transducerアーキテクチャの利用 Introduction 2
Transducer 3
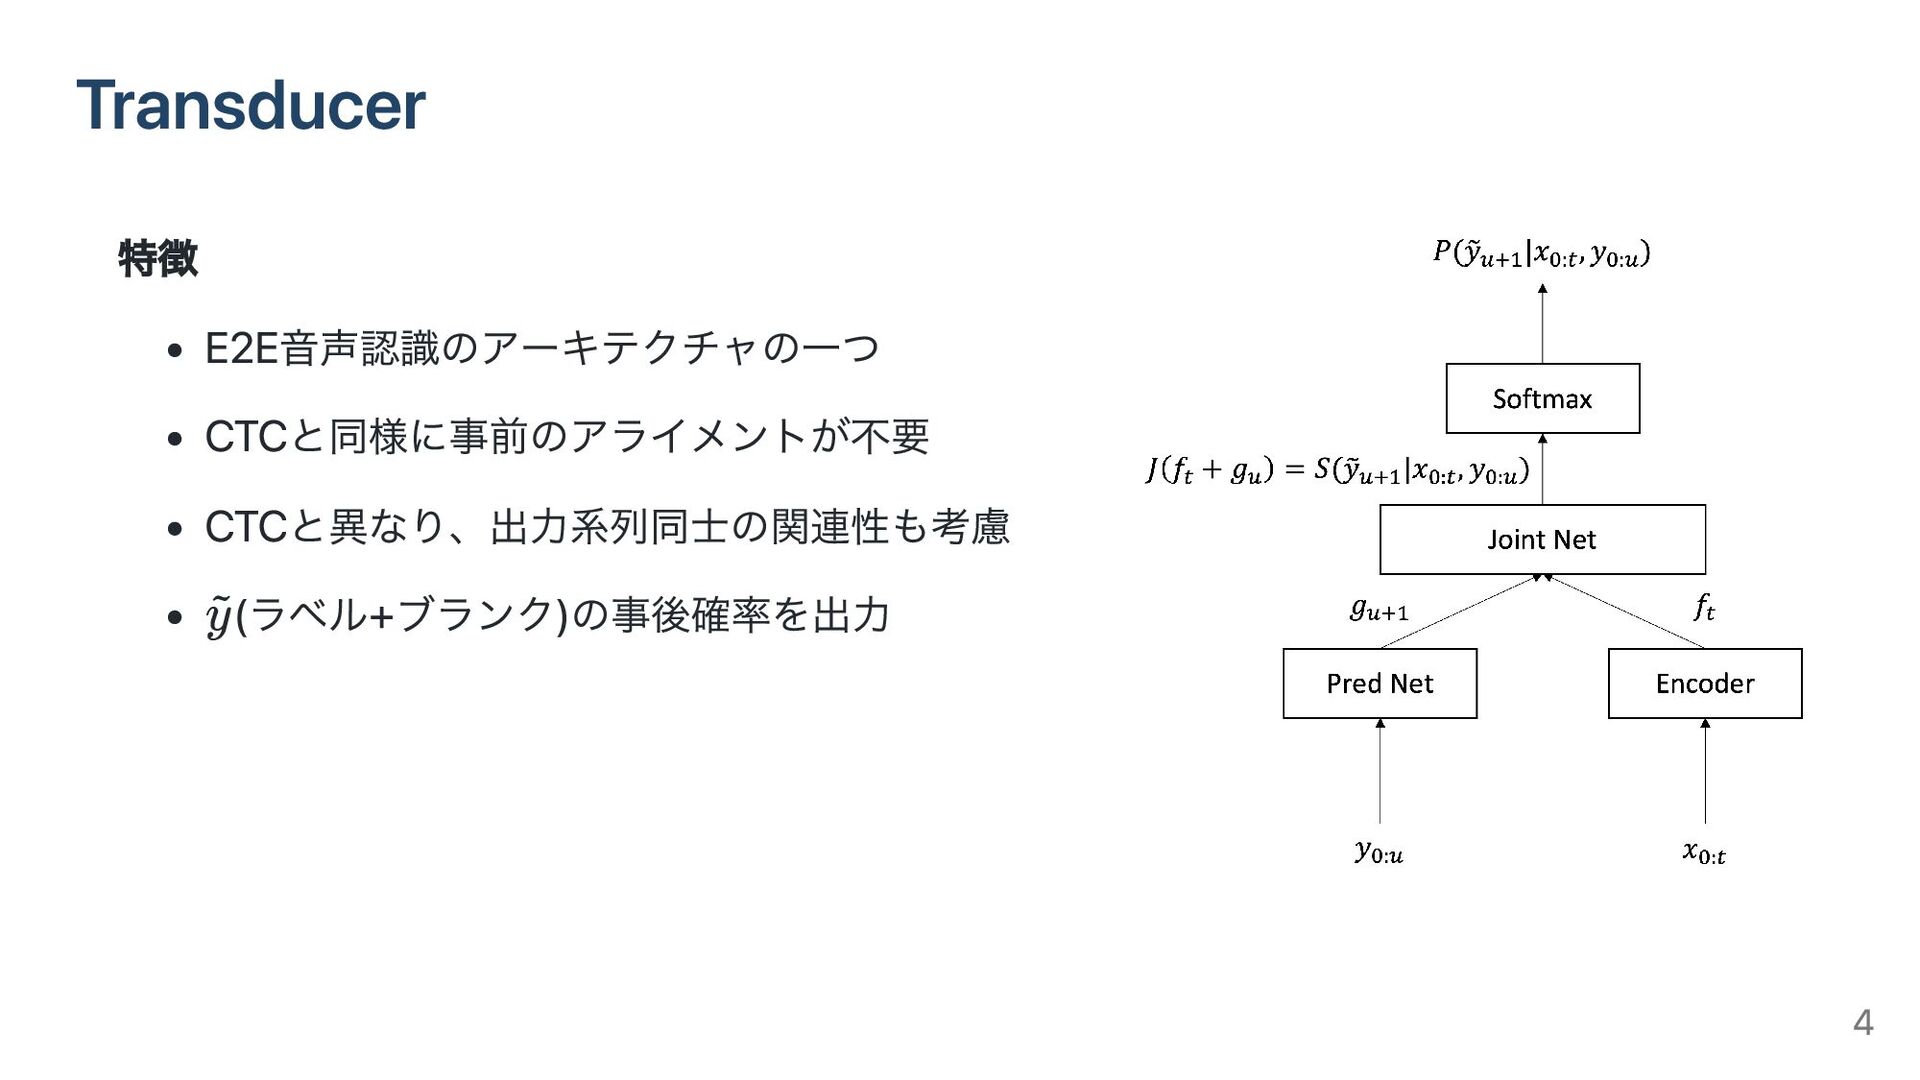
Transducer 特徴 E2E音声認識のアーキテクチャの一つ CTCと同様に事前のアライメントが不要 CTCと異なり、出力系列同士の関連性も考慮 (ラベル+ブランク)の事後確率を出力 y ~ 4
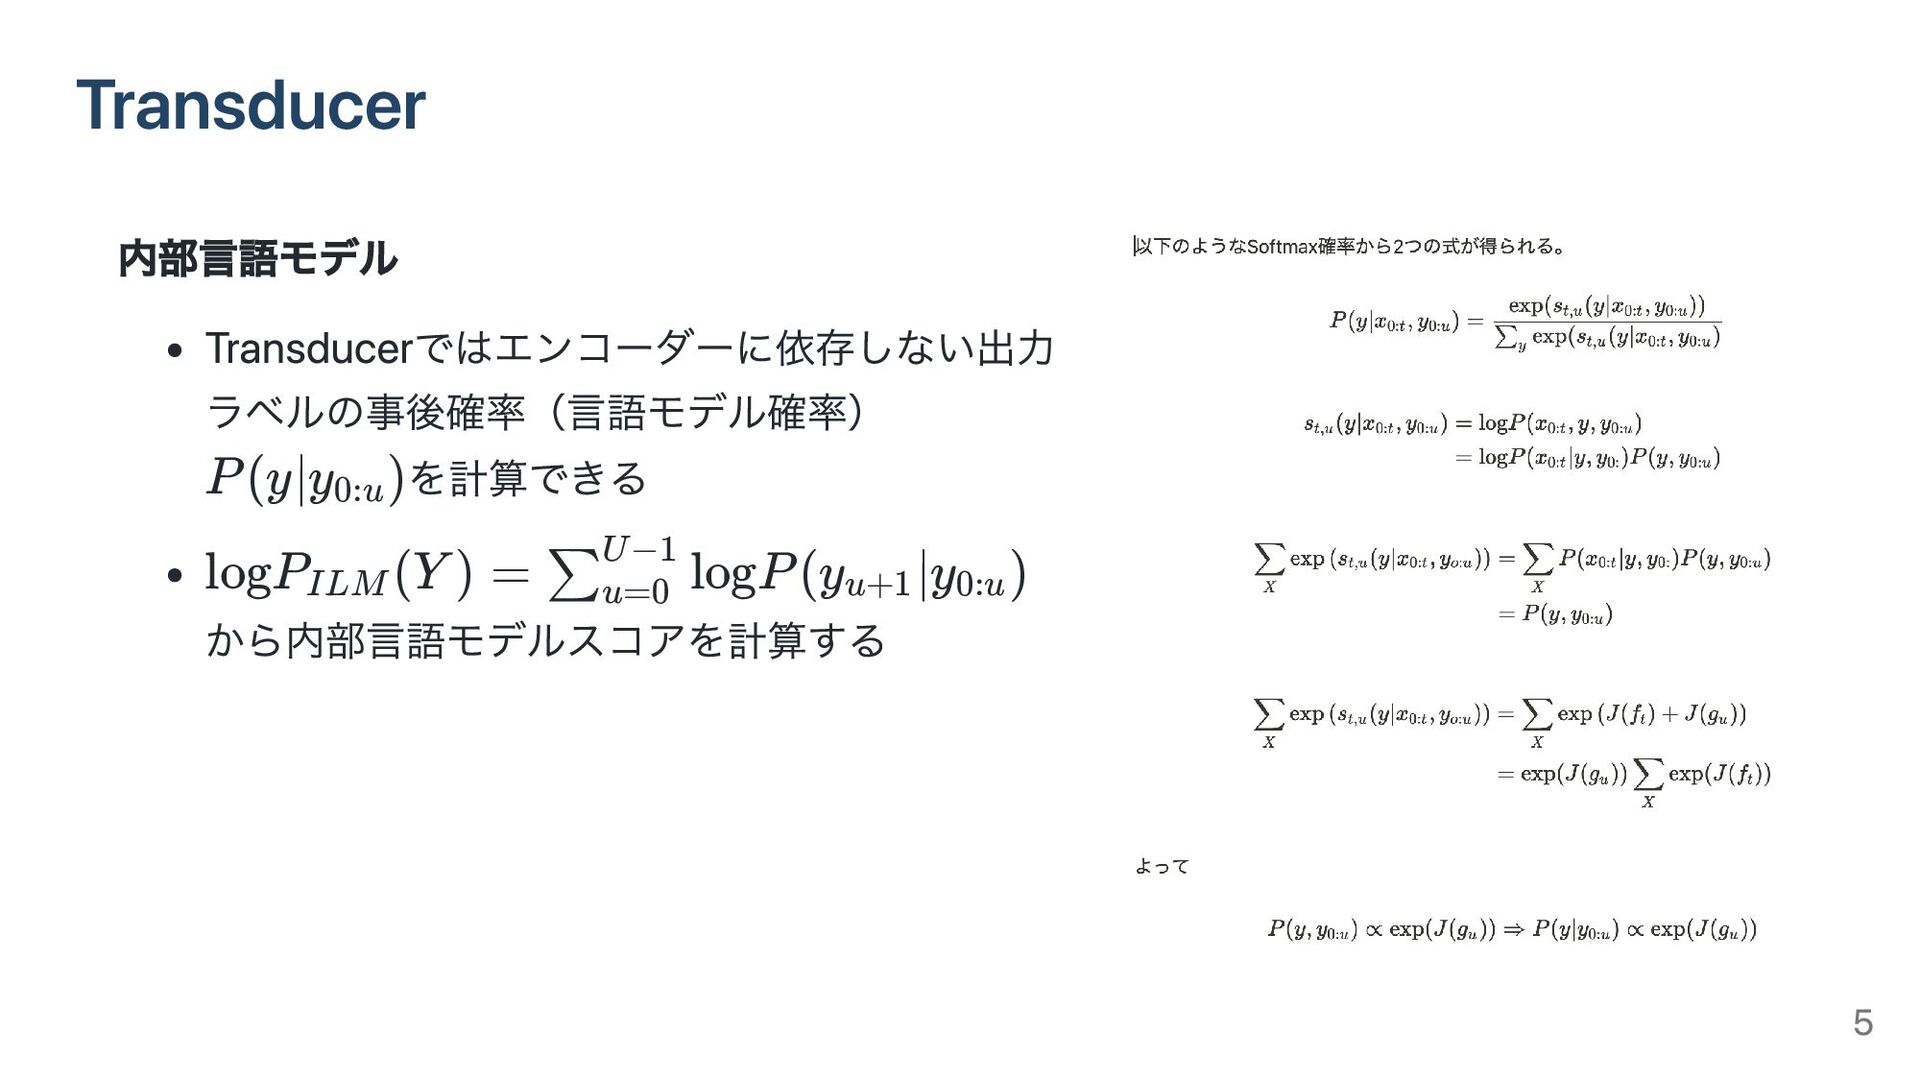
Transducer 内部言語モデル Transducerではエンコーダーに依存しない出力 ラベルの事後確率(言語モデル確率) を計算できる から内部言語モデルスコアを計算する P(y∣y ) 0:u
logP (Y ) = ILM logP(y ∣y ) ∑ u=0 U−1 u+1 0:u 5
HAT 6
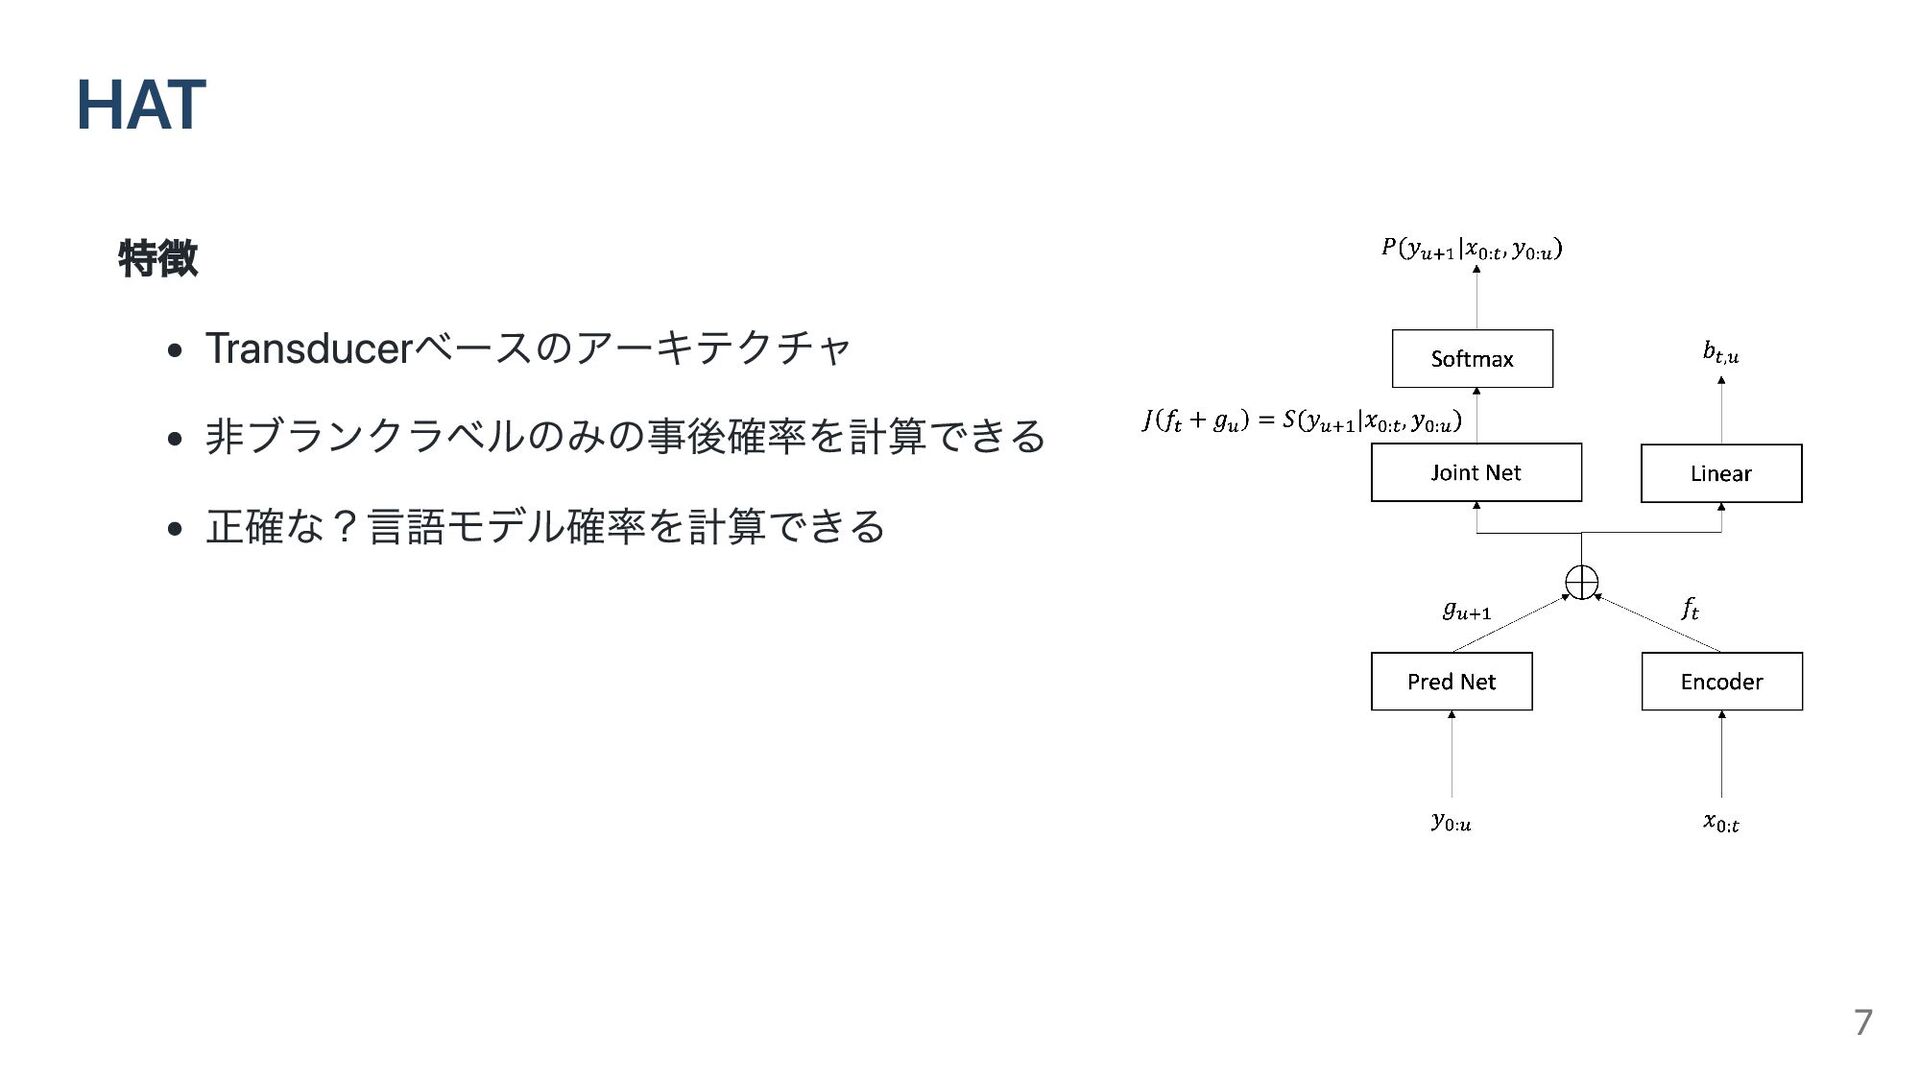
HAT 特徴 Transducerベースのアーキテクチャ 非ブランクラベルのみの事後確率を計算できる 正確な?言語モデル確率を計算できる 7
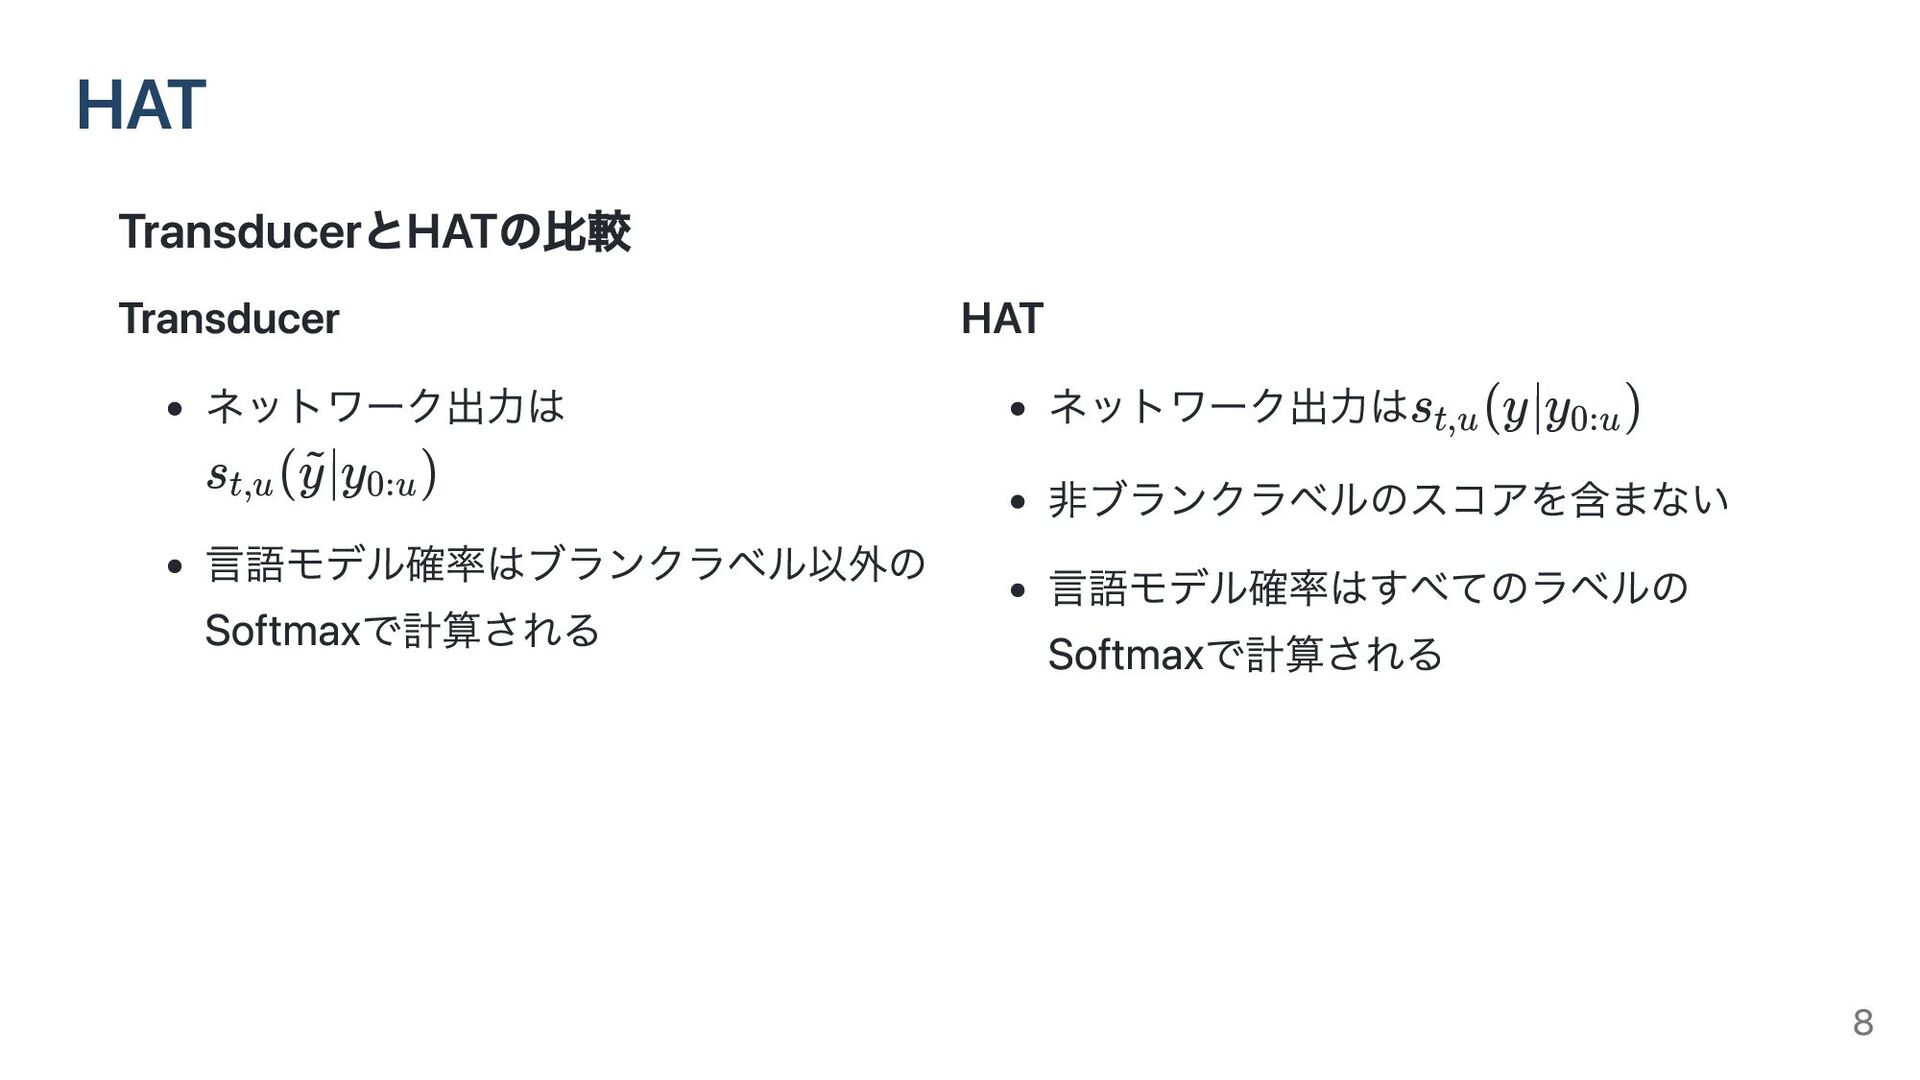
TransducerとHATの比較 HAT Transducer ネットワーク出力は 言語モデル確率はブランクラベル以外の Softmaxで計算される s (
∣y ) t,u y ~ 0:u HAT ネットワーク出力は 非ブランクラベルのスコアを含まない 言語モデル確率はすべてのラベルの Softmaxで計算される s (y∣y ) t,u 0:u 8
結果 9
実験設定 データセット: Google VoiceSearch Traffic 評価指標: WER アーキテクチャ: Encoder: 5layer,
2048cells/layerのLSTM Pred Net: 2layer, 256cells/layerのLSTM Joint Net: 1layerの線形層 入力: 対数メルスペクトログラム 結果 10
学習 強制アライメントを行い、教師ラベル(文章)の音素列を得る 各モデルは42種類の音素の事後確率を予測 各モデル単体で学習を行う(学習時は外部言語モデルを利用しない) 推論 各モデルを音響モデルとして使用 WFSTとして発音辞書・外部言語モデルを組み合わせてデコーディング 結果 11
各手法のデコード方法 Cross-Entropy CTC, RNN-T HAT 結果 = y ~∗
argmax λ log P(x ∣ ) + y ~ 1 (∏ t=1 T t y ~ t ) logP (B( )) LM y ~ = y ~∗ argmax λ logP ( ∣x) + y ~ 1 ′ y ~ logP (B( )) + LM y ~ λ v( ) 2 y ~ = y ~∗ argmax λ logP( ∣x) + y ~ 1 y ~ logP (B( )) − LM y ~ λ logP (B( )) 2 ILM y ~ 12
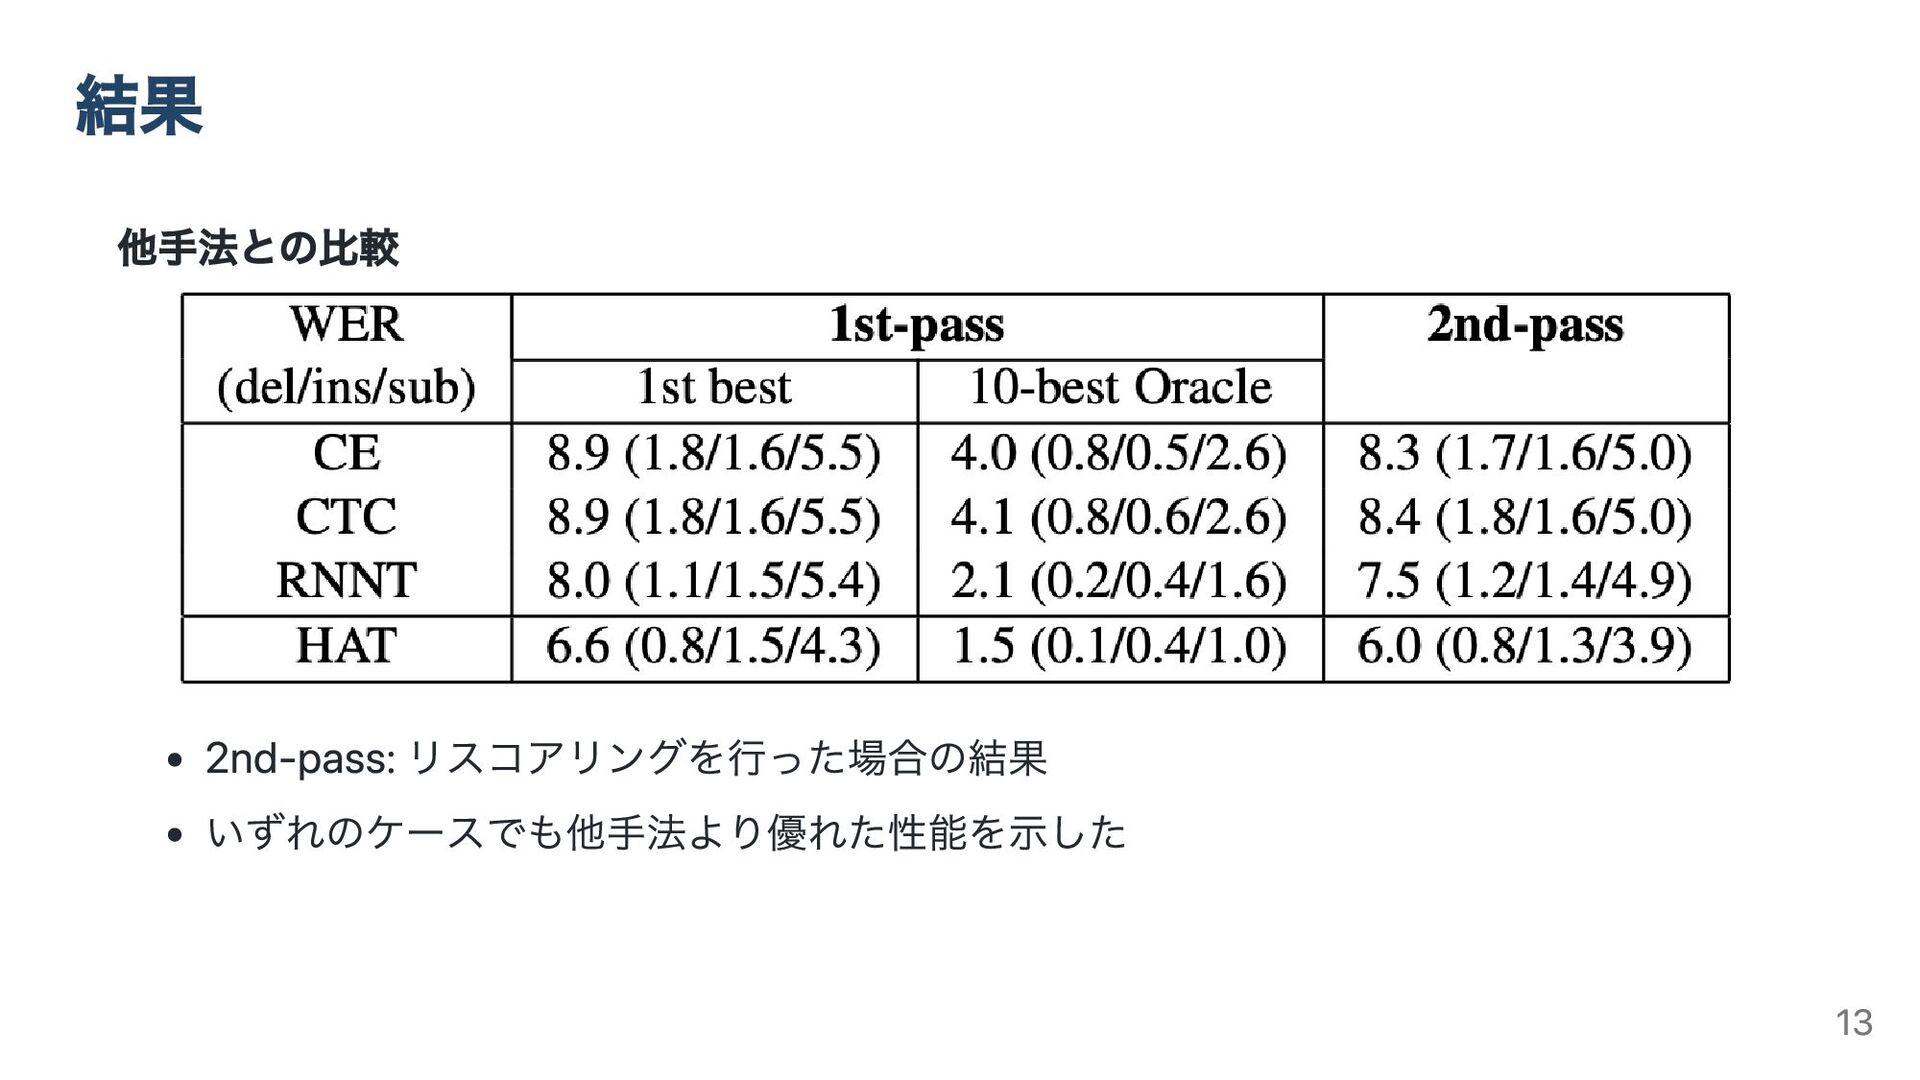
他手法との比較 2nd-pass: リスコアリングを行った場合の結果 いずれのケースでも他手法より優れた性能を示した 結果 13
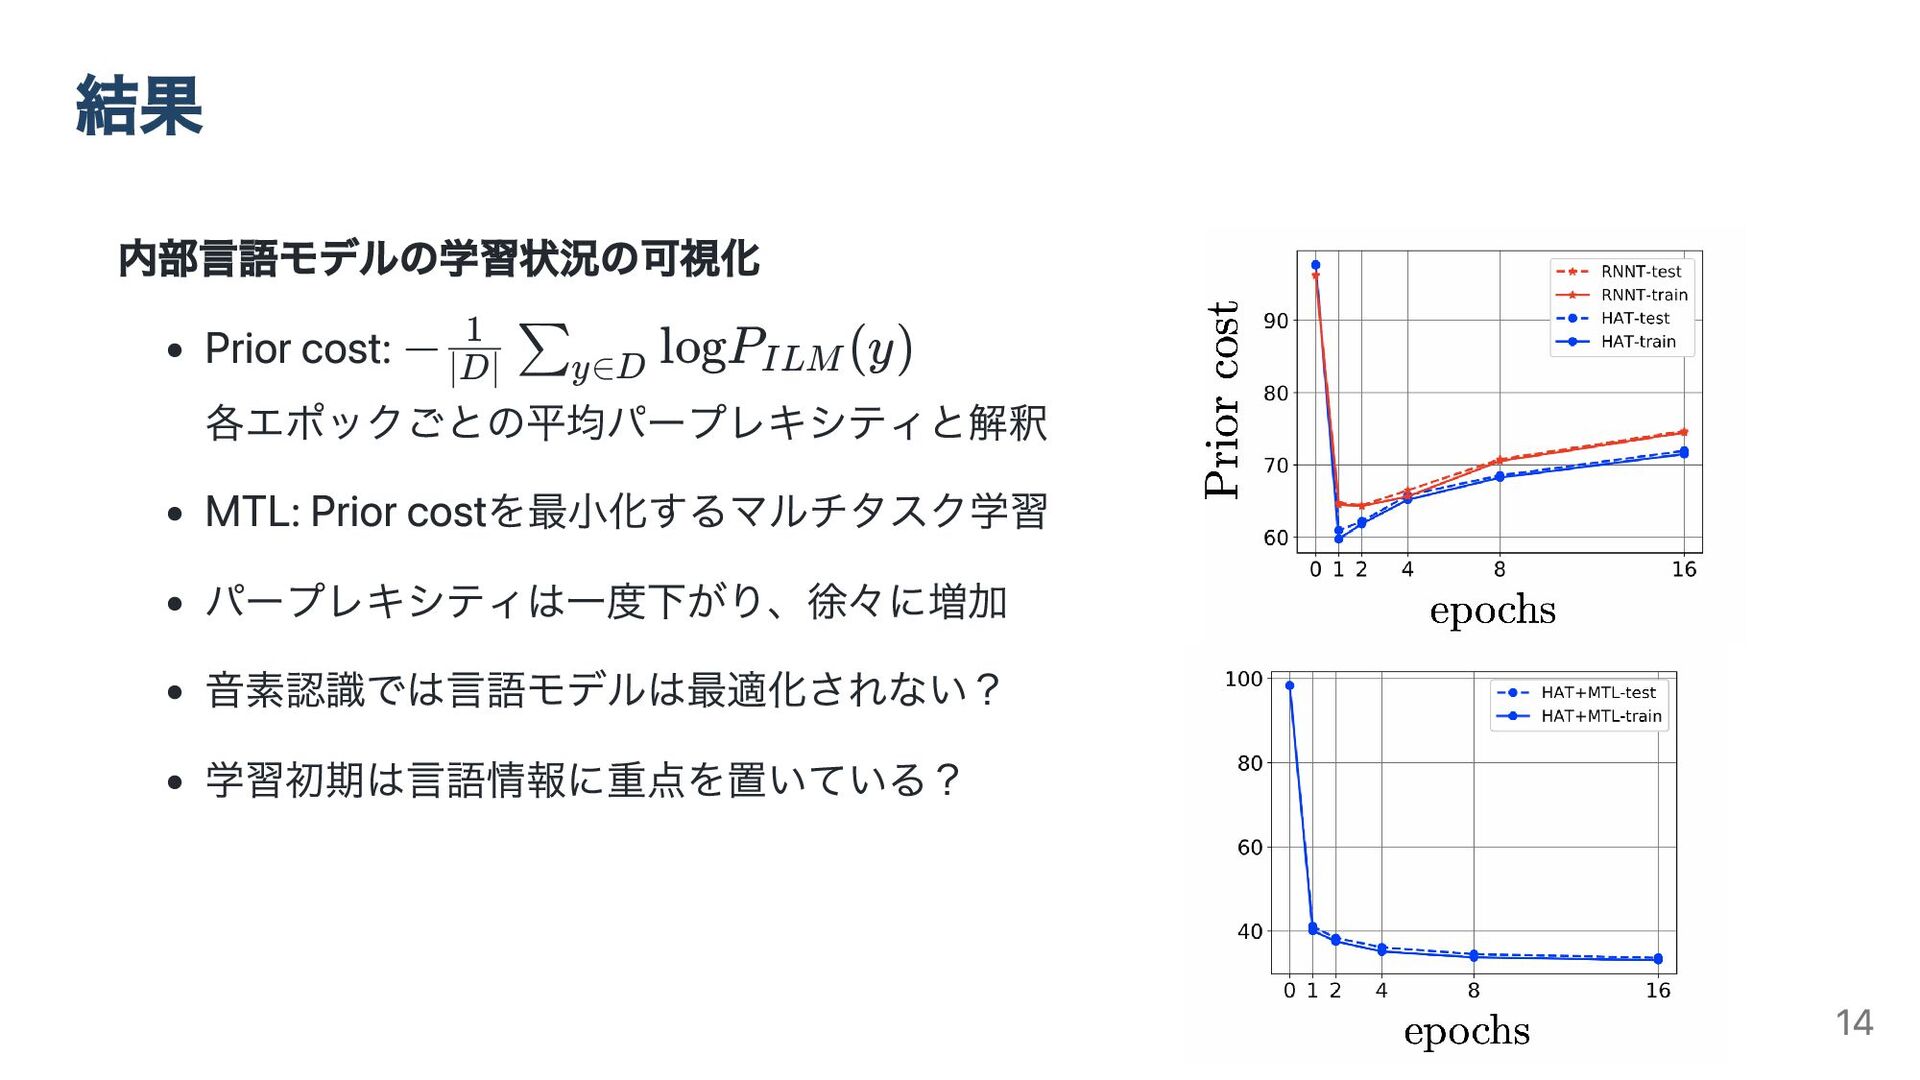
結果 内部言語モデルの学習状況の可視化 Prior cost: 各エポックごとの平均パープレキシティと解釈 MTL: Prior costを最小化するマルチタスク学習 パープレキシティは一度下がり、徐々に増加 音素認識では言語モデルは最適化されない?
学習初期は言語情報に重点を置いている? − logP (y) ∣D∣ 1 ∑ y∈D ILM 14
結果 内部言語モデルの寄与率とWER HAT 付近で最も良い性能 ただのShallowFusionではなく、内部言語 モデルの影響を取り除くことが重要 HAT+MTL Prior costを最小化しているが性能はあまり 向上していない
よい内部言語モデルを構築することは重要 ではないということ? λ = 2 1 15
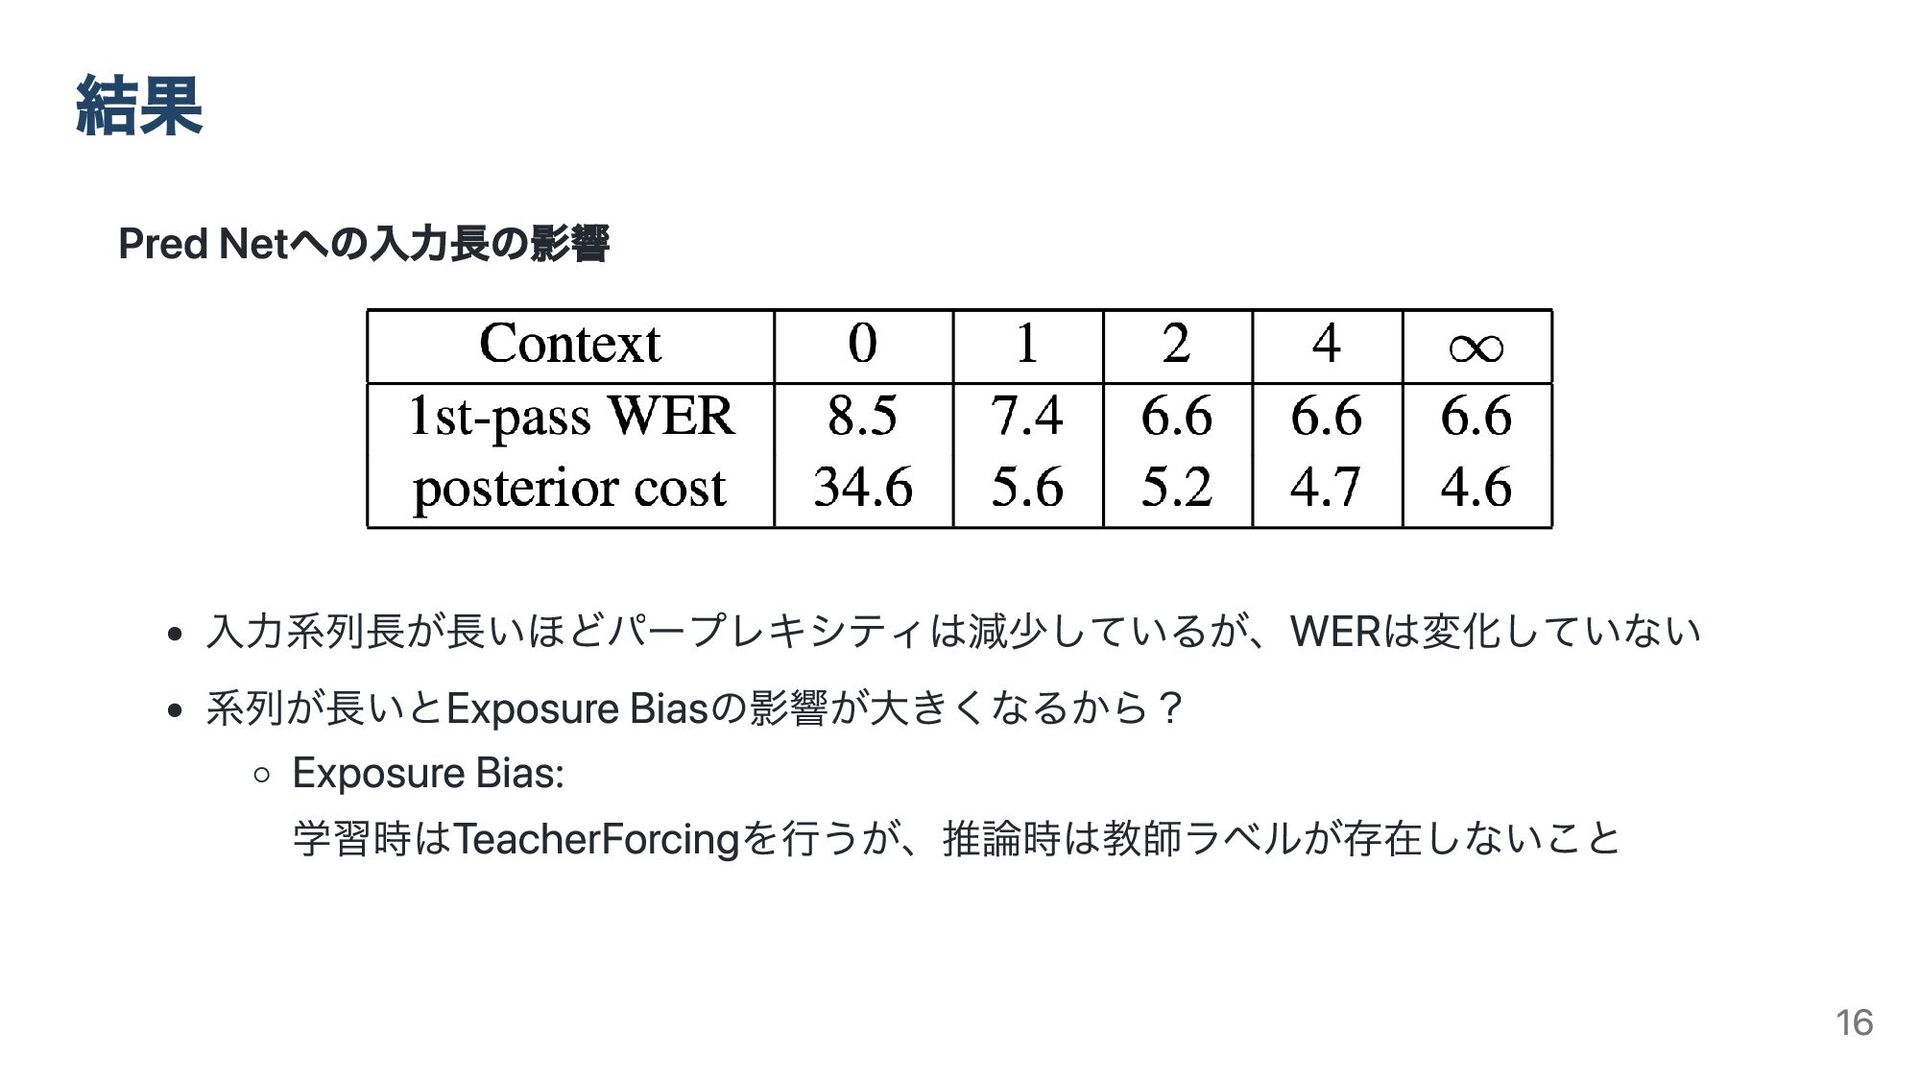
Pred Netへの入力長の影響 入力系列長が長いほどパープレキシティは減少しているが、WERは変化していない 系列が長いとExposure Biasの影響が大きくなるから? Exposure Bias: 学習時はTeacherForcingを行うが、推論時は教師ラベルが存在しないこと 結果 16
まとめ 17
E2Eモデルを音響モデルとして利用するためのアプローチであるHATを提案 内部言語モデルのパープレキシティを評価できるようになった →外部言語モデルの必要性の判断基準となる まとめ 18


 shibukazu
 gkazunii
 institutdelelevage
 enochan
 hf149
 fr0gger
 satai
 ept
 rikkabotan7
 anikisencyo
 yumulab
 junkashihara
 techseoconnect
 tammyeverts
 khoart
 chriscoyier
 aleyda
 katiecoart
 signer
 denniskardys
 reverentgeek
 jeffersonlam
 jacobtomlinson
 samlambert