ability to absorb or avoid damage without suffering complete failure.” - wikipedia >> Failure might be observed. But the rest of the system continues to run normally. ---------- O ---------- “Fault tolerance is the property that enables a system to continue operating properly in the event of the failure of some of its components.” - wikipedia >> Does not feel any impact except for some delay during the failover. What Is Resiliency & Fault Tolerance? What is Resiliency & Fault Tolerance ?
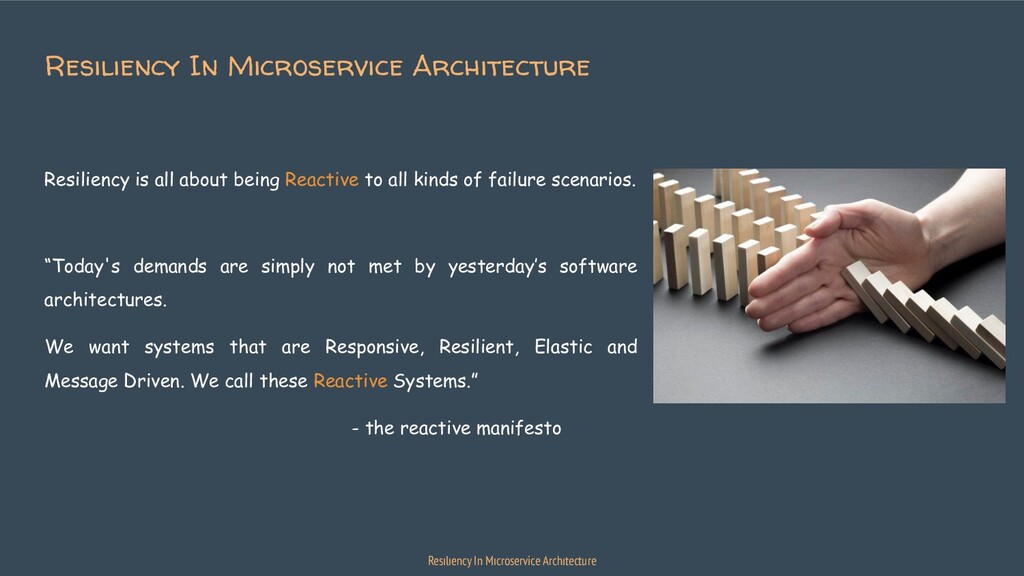
failure scenarios. “Today's demands are simply not met by yesterday’s software architectures. We want systems that are Responsive, Resilient, Elastic and Message Driven. We call these Reactive Systems.” - the reactive manifesto Resılıency In Mıcroservice Archıtecture Resılıency In Mıcroservice Archıtecture
various microservices is also the first step for resiliency. What’s next? • Infrastructure ( High Av., Redundancy, Autoscaling, IaC, etc. ) • Independent Microservices • Applying Some Patterns • Chaos Engineering Resılıency In Mıcroservice Archıtecture
the harder to achieve resiliency. • If a service goes down, this should not affect other services. ( SPoF ) • SPoF is not only about service-to-service. ( DB, Message Bus, Load Balancer, API Gateway, etc. ) So, how to build independent microservices? Independent Microservices Independent Microservices
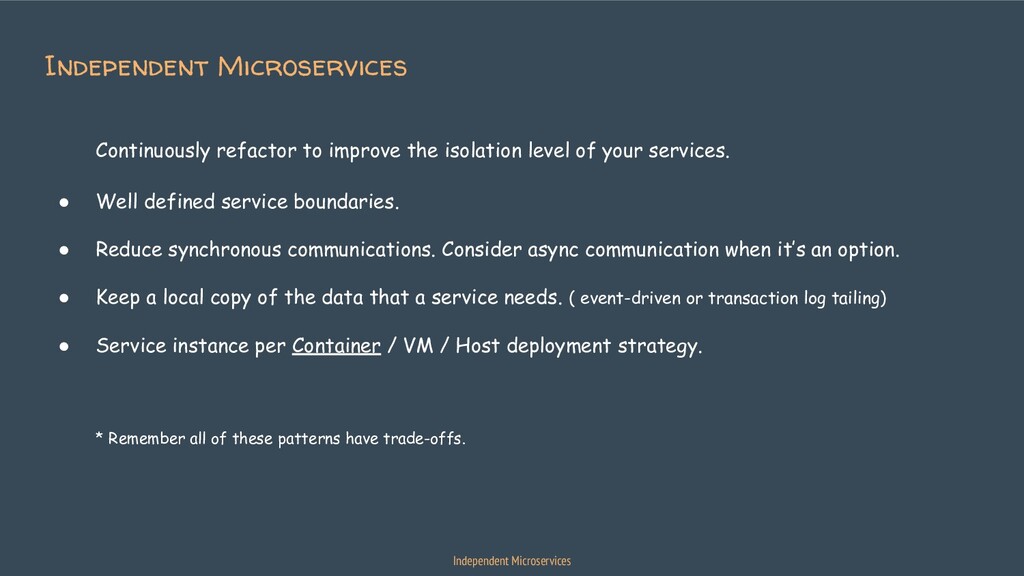
• Well defined service boundaries. • Reduce synchronous communications. Consider async communication when it’s an option. • Keep a local copy of the data that a service needs. ( event-driven or transaction log tailing) • Service instance per Container / VM / Host deployment strategy. * Remember all of these patterns have trade-offs. Independent Mıcroservices Independent Microservices
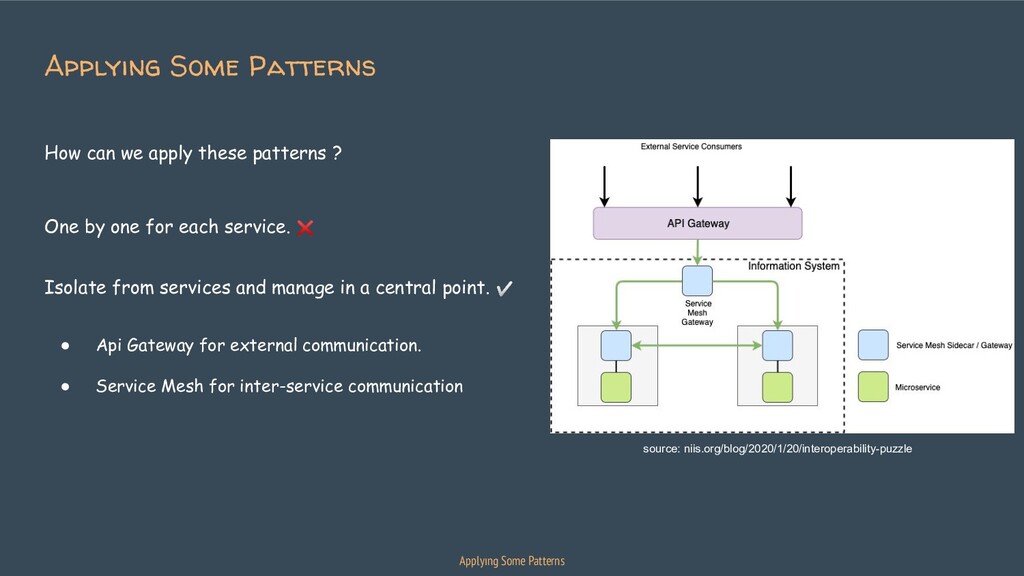
for each service. ❌ Isolate from services and manage in a central point. ✅ • Api Gateway for external communication. • Service Mesh for inter-service communication Applyıng Some Patterns Applyıng Some Patterns source: niis.org/blog/2020/1/20/interoperability-puzzle
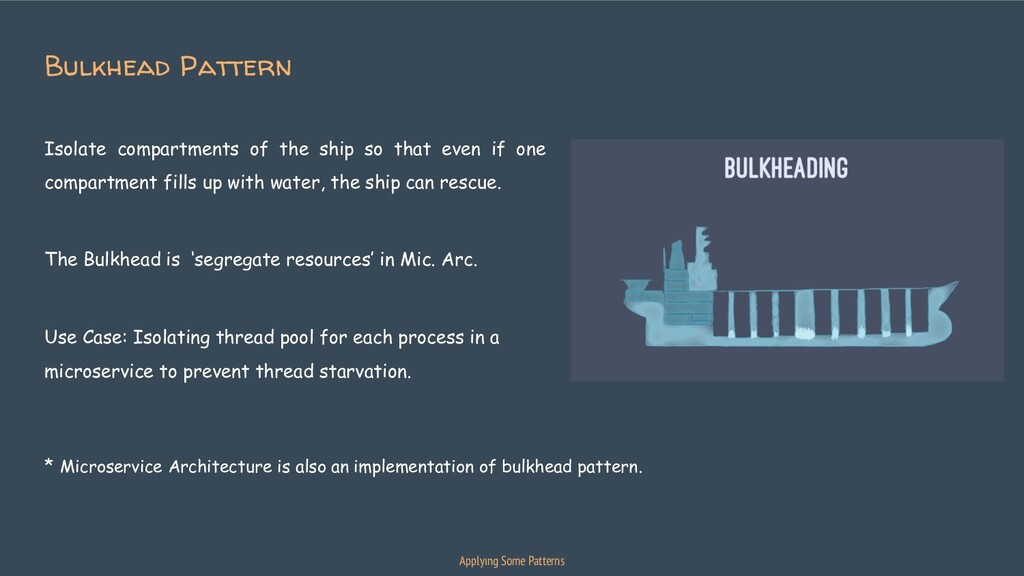
if one compartment fills up with water, the ship can rescue. The Bulkhead is ‘segregate resources’ in Mic. Arc. Use Case: Isolating thread pool for each process in a microservice to prevent thread starvation. * Microservice Architecture is also an implementation of bulkhead pattern. Applyıng Some Patterns
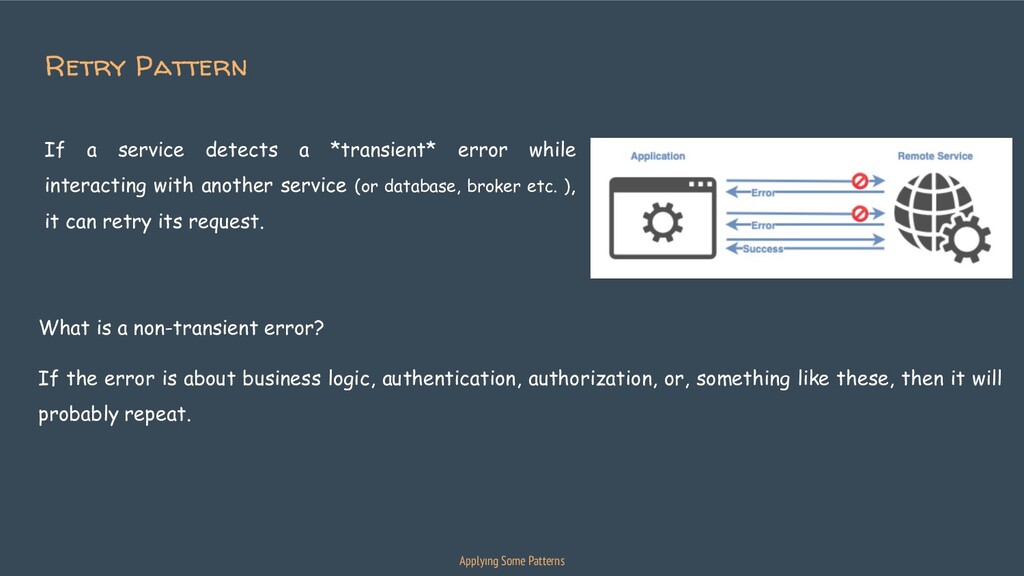
interacting with another service (or database, broker etc. ), it can retry its request. What is a non-transient error? If the error is about business logic, authentication, authorization, or, something like these, then it will probably repeat. Applyıng Some Patterns
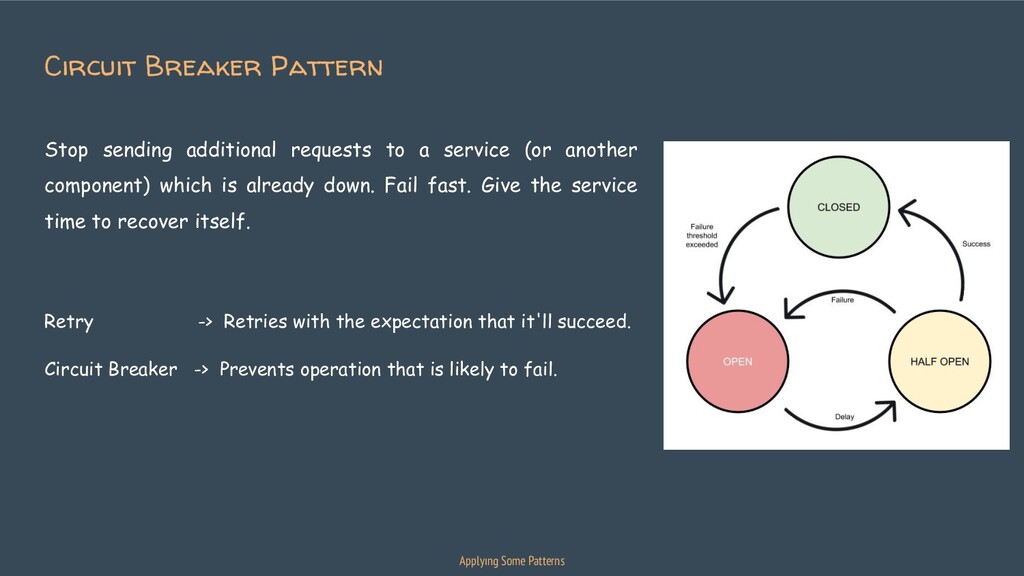
which is already down. Fail fast. Give the service time to recover itself. Retry -> Retries with the expectation that it'll succeed. Circuit Breaker -> Prevents operation that is likely to fail. Circuit Breaker Pattern Applyıng Some Patterns
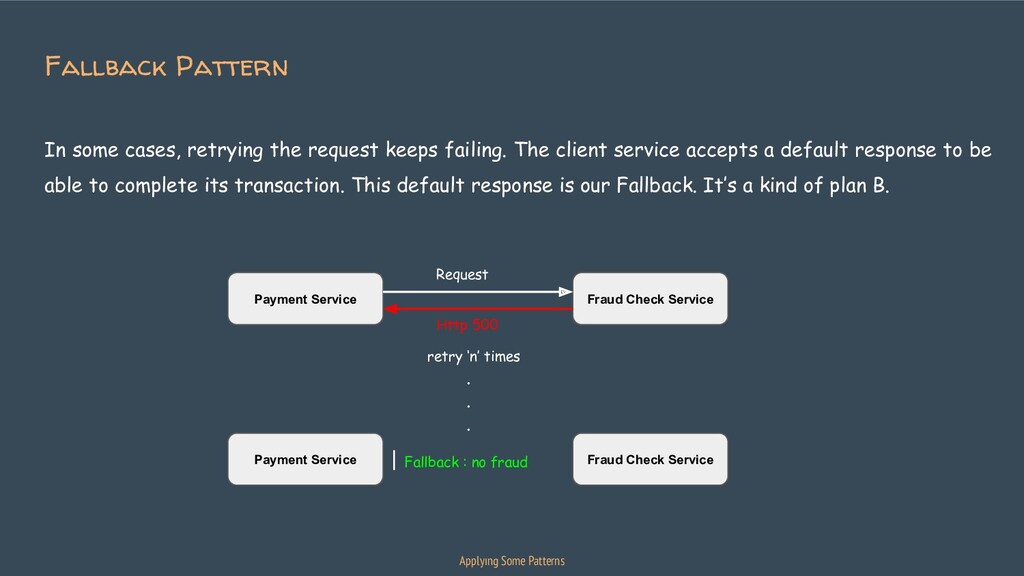
The client service accepts a default response to be able to complete its transaction. This default response is our Fallback. It’s a kind of plan B. Applyıng Some Patterns Payment Service Fraud Check Service . . . Payment Service Fraud Check Service | Fallback : no fraud Request Http 500 retry ‘n’ times
service. Throughput: The rate of messages transferred in a certain amount of time. Why do we need to control it? • Security concerns Auth service is called tens of times in a minute for the same user? • Preventing resource starvation Throttle lower-priority traffic to give enough resources to critical transactions. Rate Lımıtıng Applyıng Some Patterns
service for an undetermined amount of time. Your job is to find the best timeout value. Try to keep it as short as possible. Timeout Pattern Benefits ; • Make the service work even when the dependent service is not available. ( Sync I/O ) • Don’t block any thread for a long time. ( Async I/O ) Applyıng Some Patterns
a system before they cause an outage. While Netflix was migrating from physical infra to AWS in 2010, they created a chaos engineering tool called ‘Chaos Monkey’. Chaos Engineering Chaos Monkey was continuously running in Netflix’s production environment and regularly shutting down EC2 instances to ensure that services to be resilient to instance failures. Netflix Chaos Monkey
an instance would not affect the entire streaming experience. After the success of first soldier, Chaos Monkey, they created Simian Army; ➔ Latency Monkey, ➔ Janitor Monkey, ➔ Doctor Monkey, ➔ Chaos Gorilla, ➔ Chaos Kong etc. Chaos Engineering Netflix Simian Army
something like injecting a microbe to a body and see how it fights it. Test Steps ; Form a theory --> Carry out the experiment --> See if it validates the theory or not. Some Real-World Events ; Inject latency between services, Randomly terminate VMs or containers, CPU Load, Memory Load, Fill up disk, Turn off networking, etc. Chaos Engıneerıng Chaos Engineering
application life cycle. Designing, Coding, Refactoring, Testing, Deploying, and Maintaining. • How do you test your code before deploying to production ? • Deployment strategy ( backup, roll back, isolation, etc. ) • Load testing • Resources consumption • Sync/Async communication Resiliency is not only about infra or some patterns, but also about network, application, people and culture. Conclusion Conclusion


 suadev
 gam0022
 naokihaba
 kawashimo0
 seike460
 syumai
 satoshi256kbyte
 hatsu38
 bells17
 htkym
 taiseiue
 akihisaikeda
 steliosf
 raygrieselhuber
 cassininazir
 marketingsoph
 eileencodes
 nonsquared
 pedronauck
 maggiecrowley
 skipperchong
 nikkihalliwell
 tanoku
 inesmontani
 leimatthew05