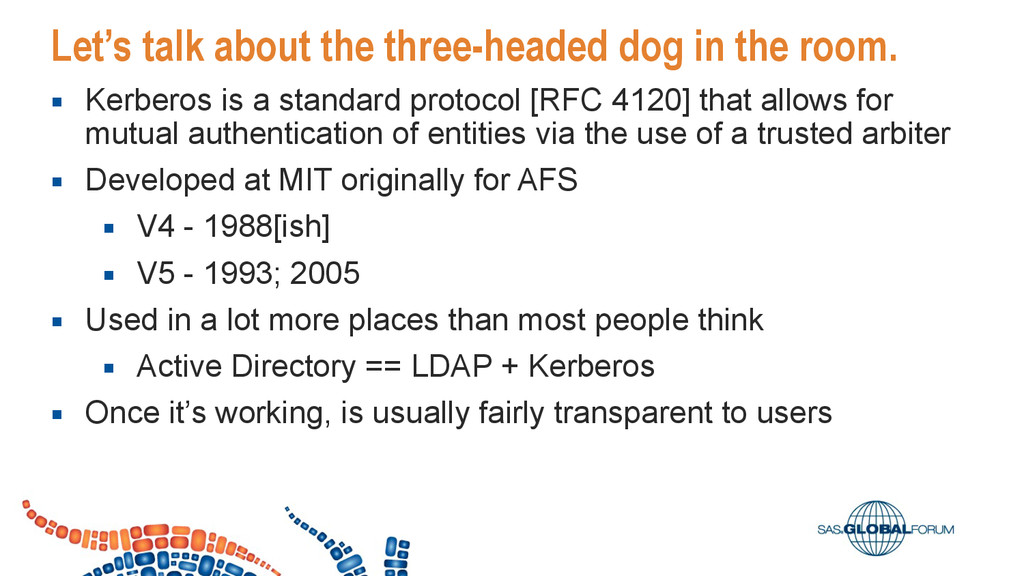
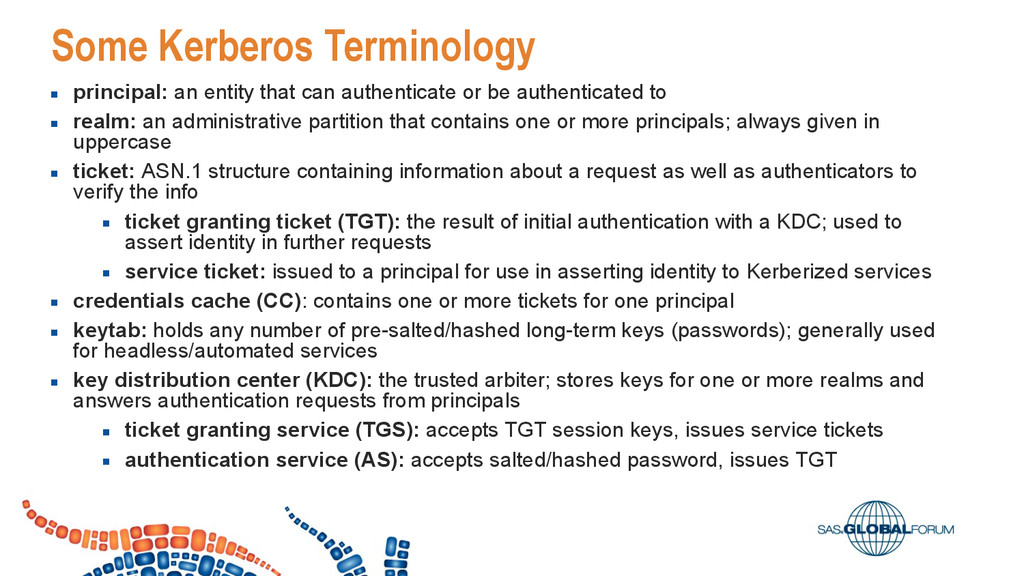
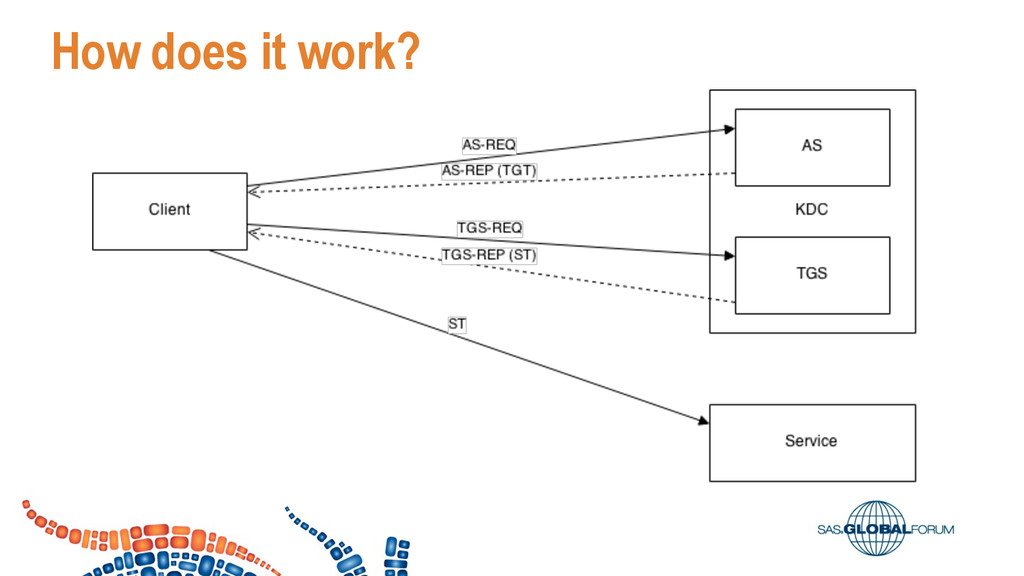
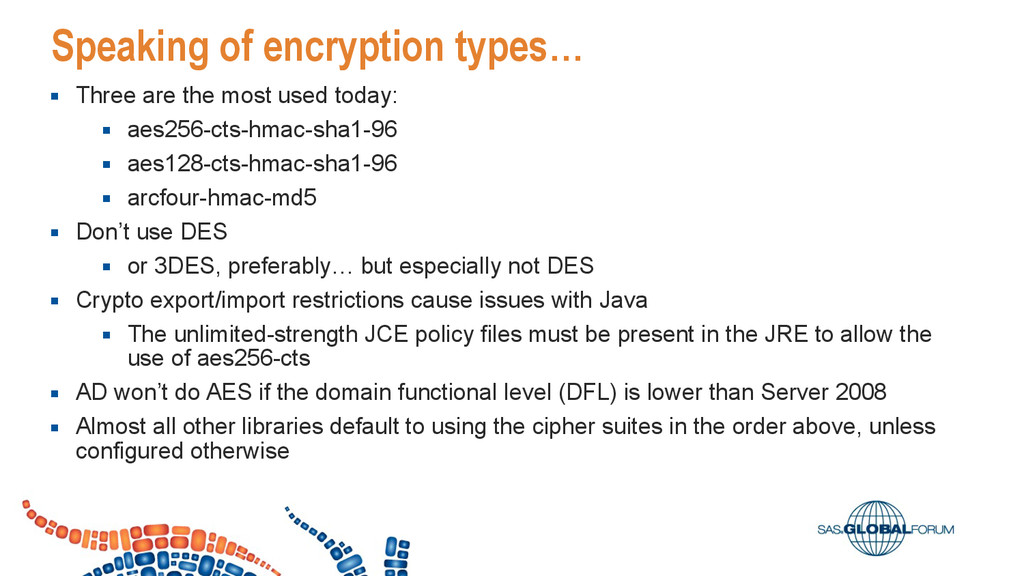
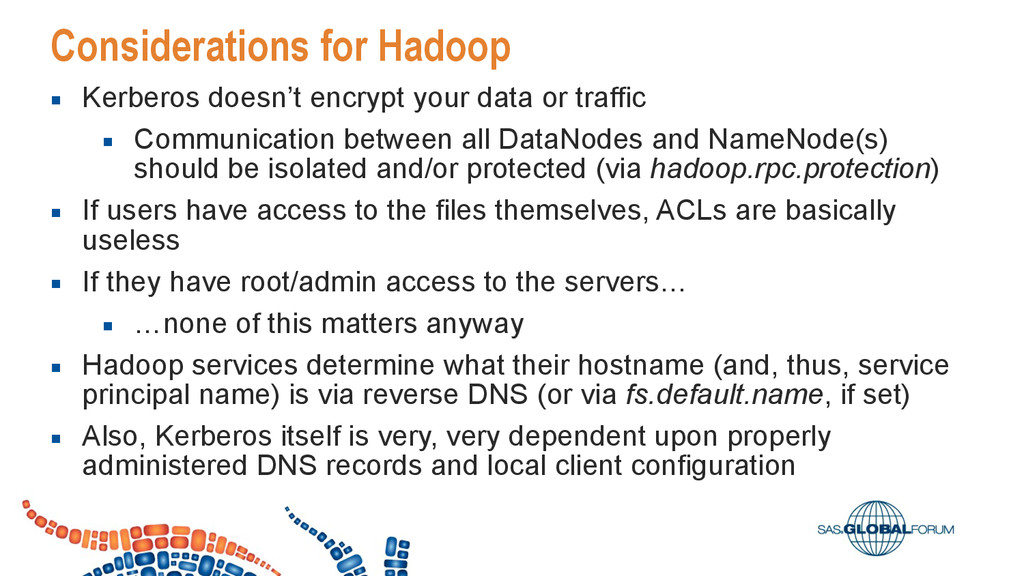
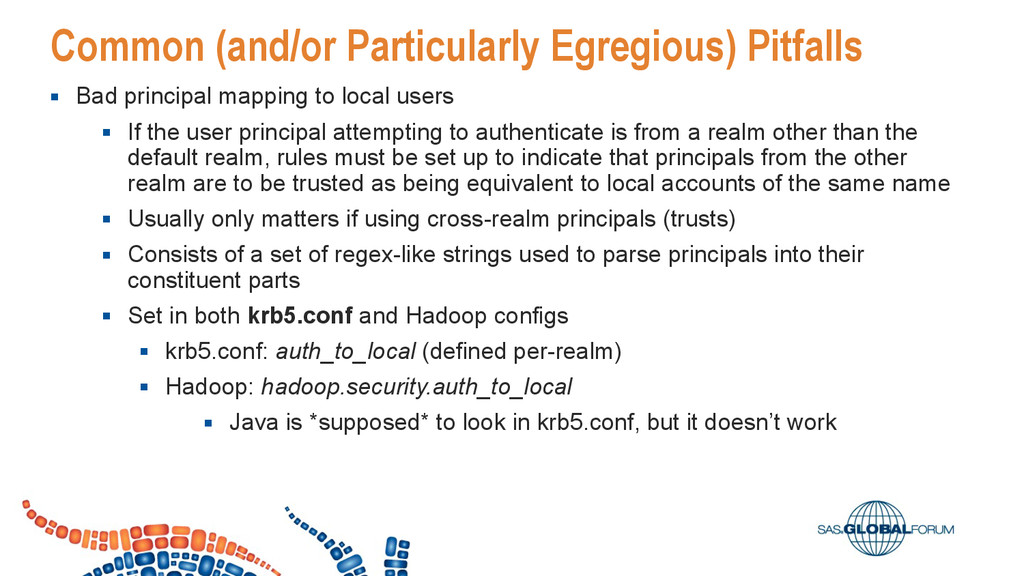
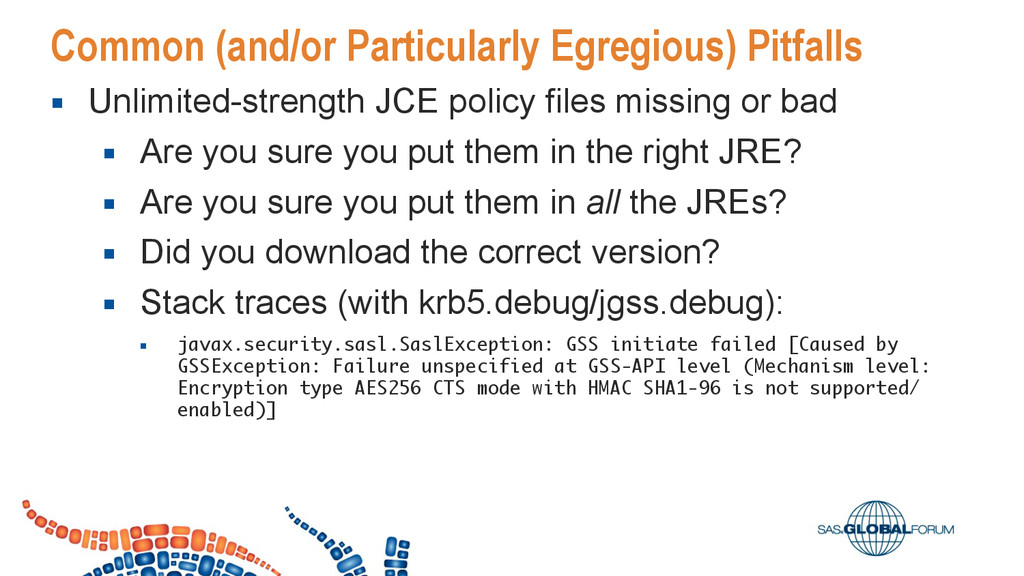
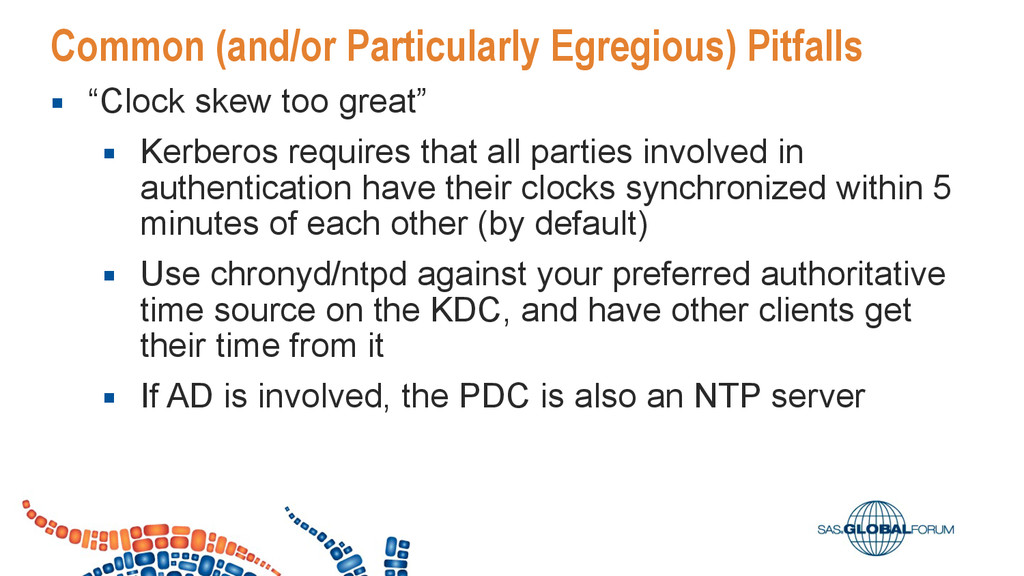
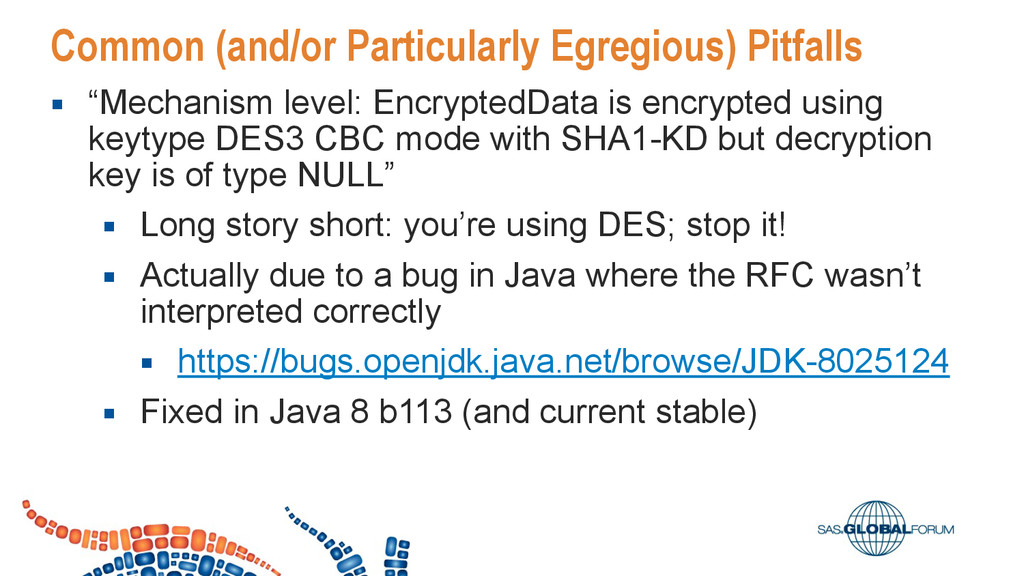
The Hadoop ecosystem is vast, and there's a lot of conflicting information available about how to best secure any given implementation. It's also difficult to fix any mistakes made early on once an instance is put into production. In this paper, we demonstrate the currently accepted best practices for securing and Kerberizing Hadoop clusters in a vendor-agnostic way, review some of the not-so-obvious pitfalls one could encounter during the process, and delve into some of the theory behind why things are the way they are.


 artoy
 steliosf
 nao_randd
 irinanazarova
 y0hgi
 kmars0605
 ryu1013
 suneo3476
 takai
 yutobara
 syumai
 utakaha
 jonoalderson
 katarinadahlin
 axbom
 codingconduct
 rkendrick25
 oripsolob
 skipperchong
 chikuwait
 mayunak
 baasie
 kimpetersen
 badams