(under MIT licence) • https://code.google.com/p/cavity/ • Very much a “personal” open source project • I didn’t want to be writing the same plumbing repeatedly • I figured other people might get mileage from the code and packages • It’s probably rather idiosyncratic • Everything is TDD with as near to total coverage as I can get • Releases are pushed to NuGet • https://www.nuget.org/packages?q=Cavity • At some point I will probably port to GitHub
2.0 / 3.5 / 4.0 (all three frameworks are separately targeted) • Comma-separation and tab-separation are currently implemented • Designed as forward-only, read-only StreamReader implementations • Expectation that data files are immutable (write-once, read-many) • Reader implementations are wrapped by DataSheet encapsulations • Data is primarily exposed as IEnumerable<KeyStringDictionary> • Enables the power of System.Linq
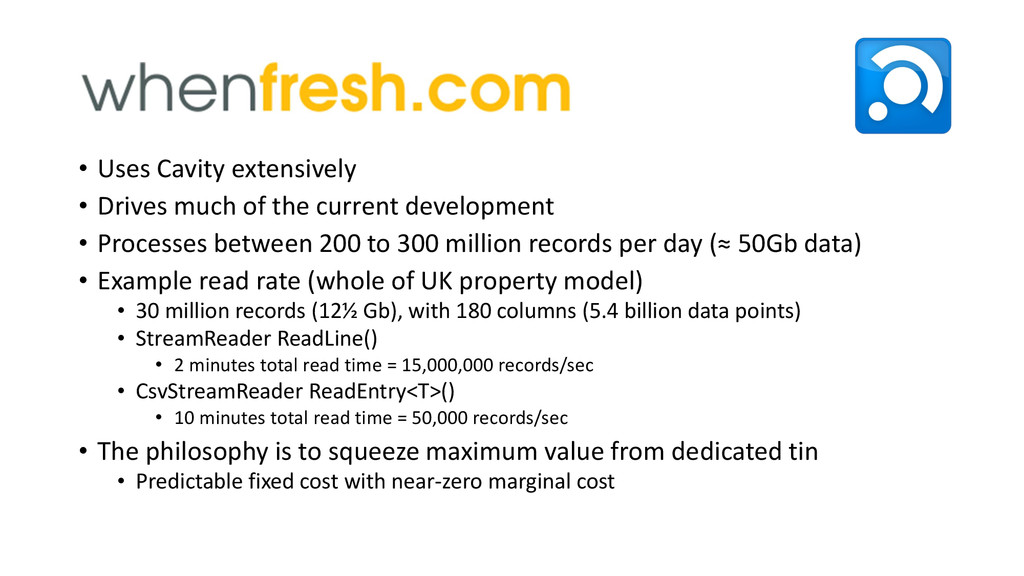
development • Processes between 200 to 300 million records per day (≈ 50Gb data) • Example read rate (whole of UK property model) • 30 million records (12½ Gb), with 180 columns (5.4 billion data points) • StreamReader ReadLine() • 2 minutes total read time = 15,000,000 records/sec • CsvStreamReader ReadEntry<T>() • 10 minutes total read time = 50,000 records/sec • The philosophy is to squeeze maximum value from dedicated tin • Predictable fixed cost with near-zero marginal cost
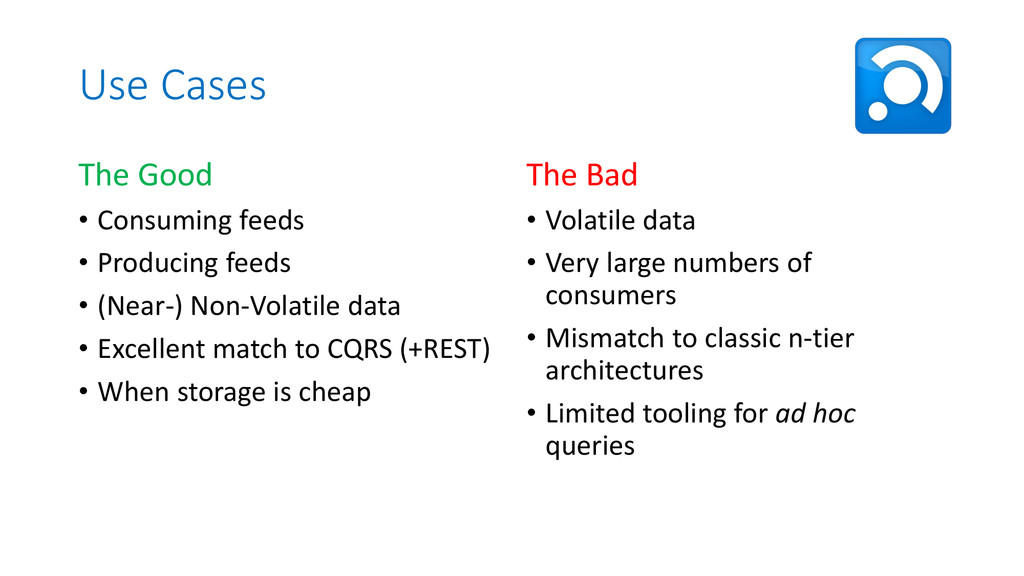
• (Near-) Non-Volatile data • Excellent match to CQRS (+REST) • When storage is cheap The Bad • Volatile data • Very large numbers of consumers • Mismatch to classic n-tier architectures • Limited tooling for ad hoc queries


 ueponx
 namiki64
 akitoshiga
 maimyyym
 codmoninc
 ivry_presentationmaterials
 oikon48
 riyaamemiya
 shugo
 terapyon
 kash1064
 akhino
 letsgokoyo
 popppiees
 kastner
 tammyeverts
 cassininazir
 tanoku
 bkeepers
 reverentgeek
 palkan
 davetheseo
 stuffmc
 marcelosomers