Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Features
Speaker Deck
PRO
Sign in
Sign up for free
Search
Search
How Postgres Could Index Itself
Search
Andrew Kane
September 08, 2017
Programming
3.3k
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
How Postgres Could Index Itself
Andrew Kane
September 08, 2017
Other Decks in Programming
See All in Programming
20260828_品質と開発生産性を両立させる、AI時代のE2Eテストの考え方
magicpod
0
130
KotlinConf Extended South Korea 2026 Keynote
l2hyunwoo
0
130
AWS Step Functions 大規模並列の壁を越える / jaws-sonic-2026-niigata-step-functions
kasacchiful
PRO
0
300
Gmail/Google DriveをトリガーにAIエージェントを動かそう! / Run AI agents with Gmail/Google Drive as triggers!
har1101
3
460
Discordを用いたラボオートメーション関連情報収集の自動化
noguhiro2002
0
490
「つくるAI」だけではバグは見つからない ~テストに必要な「見つけるAI」を分離させる戦略~
mfunaki
0
230
AIと壁打ちしながら進めるコスト管理
fufuhu
2
1.9k
LoopHub - ローカルで動く GitHub で、AI と共同開発
jugyo
0
380
Go を使い始めて 2 ヶ月の学び / My first two months with Go
contour_gara
0
420
Webエンジニアなのにブラウザの仕組みがわからないので、Pythonで自作してみた
tatsuki12
4
1.7k
Hello, Hiroshima Geospatial Data! — Exploring DoboX with Python
ra0kley
0
160
型解析で実現する Go の言語内 DSL / Conference に Go! タイムテーブルの歩き方 for Gophers
mazrean
0
120
Featured
See All Featured
Speed Design
sergeychernyshev
33
2.1k
Rebuilding a faster, lazier Slack
samanthasiow
85
9.6k
The Spectacular Lies of Maps
axbom
PRO
1
970
Save Time (by Creating Custom Rails Generators)
garrettdimon
PRO
32
4.6k
How to make the Groovebox
asonas
2
2.4k
How to Get Subject Matter Experts Bought In and Actively Contributing to SEO & PR Initiatives.
livdayseo
0
180
Believing is Seeing
oripsolob
1
210
Deep Space Network (abreviated)
tonyrice
0
290
Color Theory Basics | Prateek | Gurzu
gurzu
0
450
AI Search: Where Are We & What Can We Do About It?
aleyda
0
7.9k
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.5k
The Success of Rails: Ensuring Growth for the Next 100 Years
eileencodes
47
8.3k
Transcript
How Postgres Could Index Itself
None
github.com/ankane
None
Read speed vs Write speed Space
None
v1
Collect queries Analyze queries
pg_stat_statements Query Total Time (ms) Calls Average Time (ms) SELECT
… 40,000 80,000 0.5 SELECT … 30,000 300 100
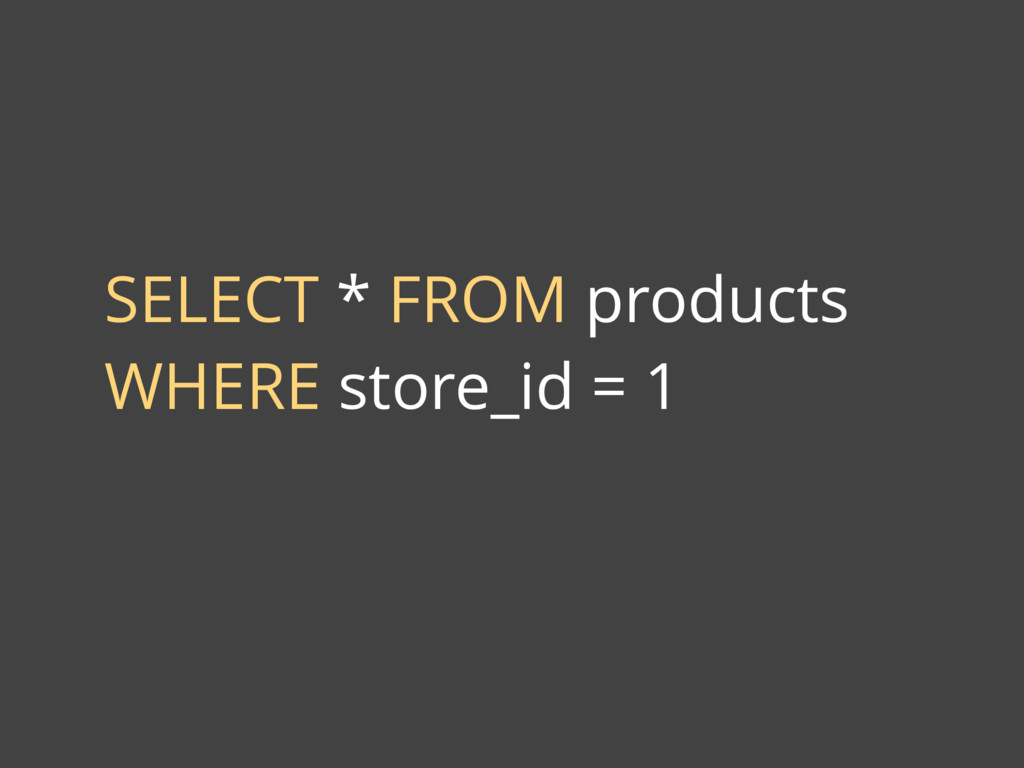
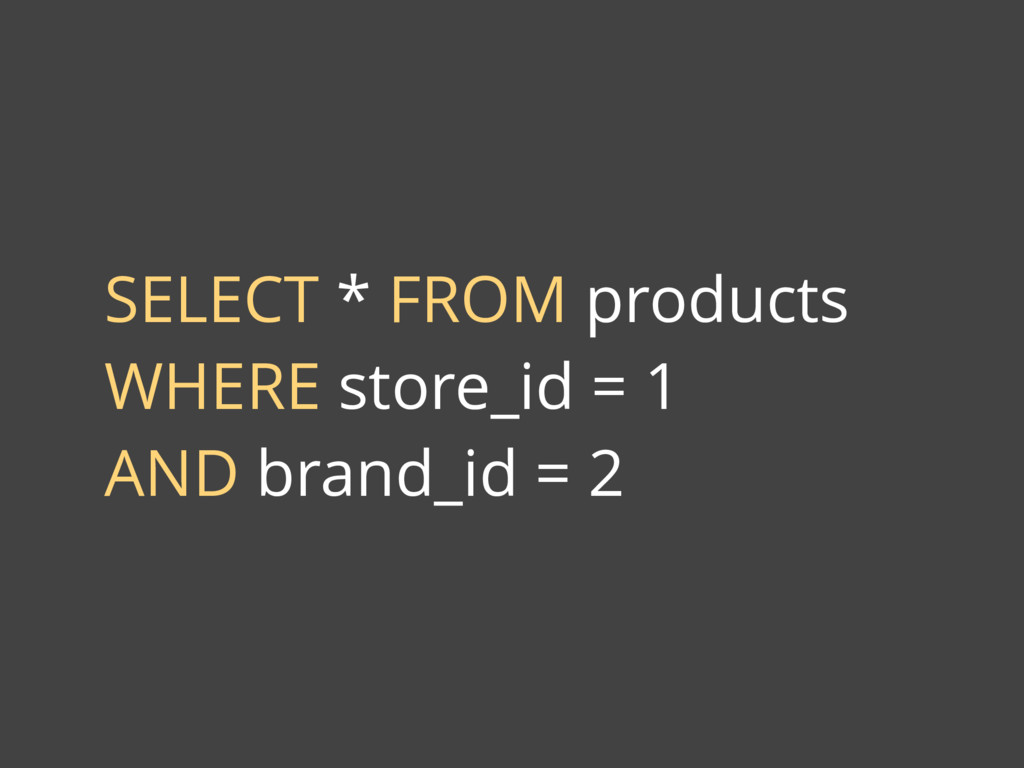
SELECT * FROM products WHERE store_id = 1
pg query github.com/lfittl/pg_query _
SELECT * FROM products WHERE store_id = 1
SELECT * FROM products WHERE store_id = 1 AND brand_id
= 2
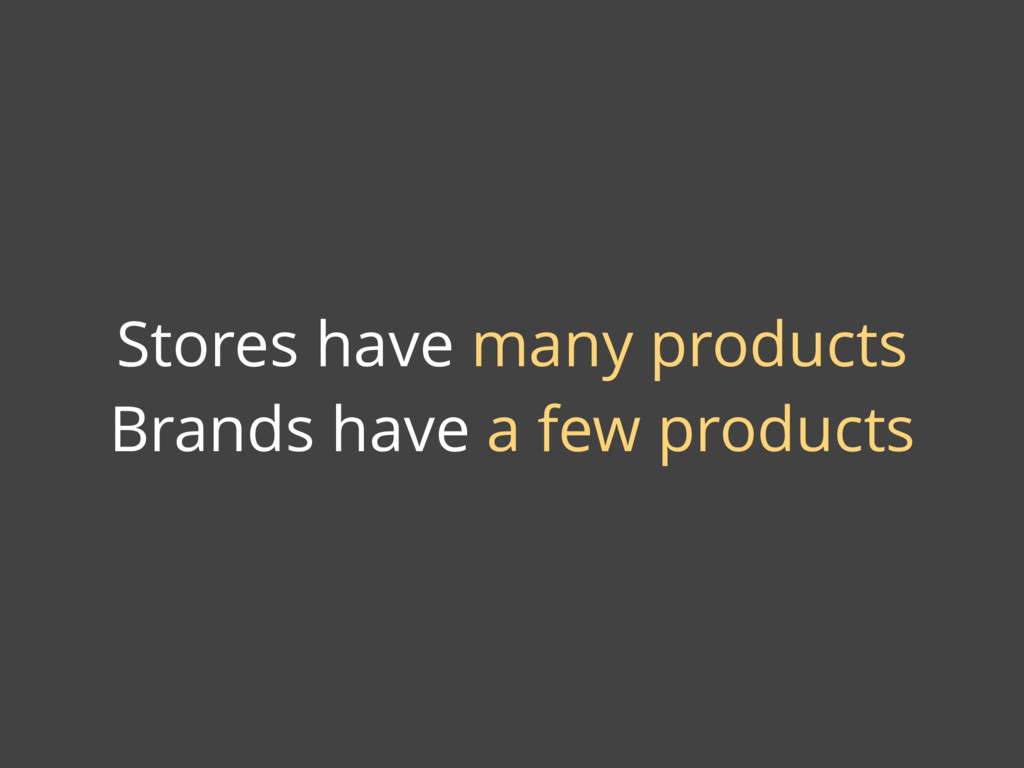
Stores have many products Brands have a few products
id store_id brand_id 1 1 2 2 4 8 3
1 9 4 1 3 fetch store_id = 1 id store_id brand_id 1 1 2 2 4 8 3 1 9 4 1 3 filter brand_id = 2 id store_id brand_id 1 1 2 2 4 8 3 1 9 4 1 3 id store_id brand_id 1 1 2 2 4 8 3 1 9 4 1 3 filter store_id = 1 fetch brand_id = 2
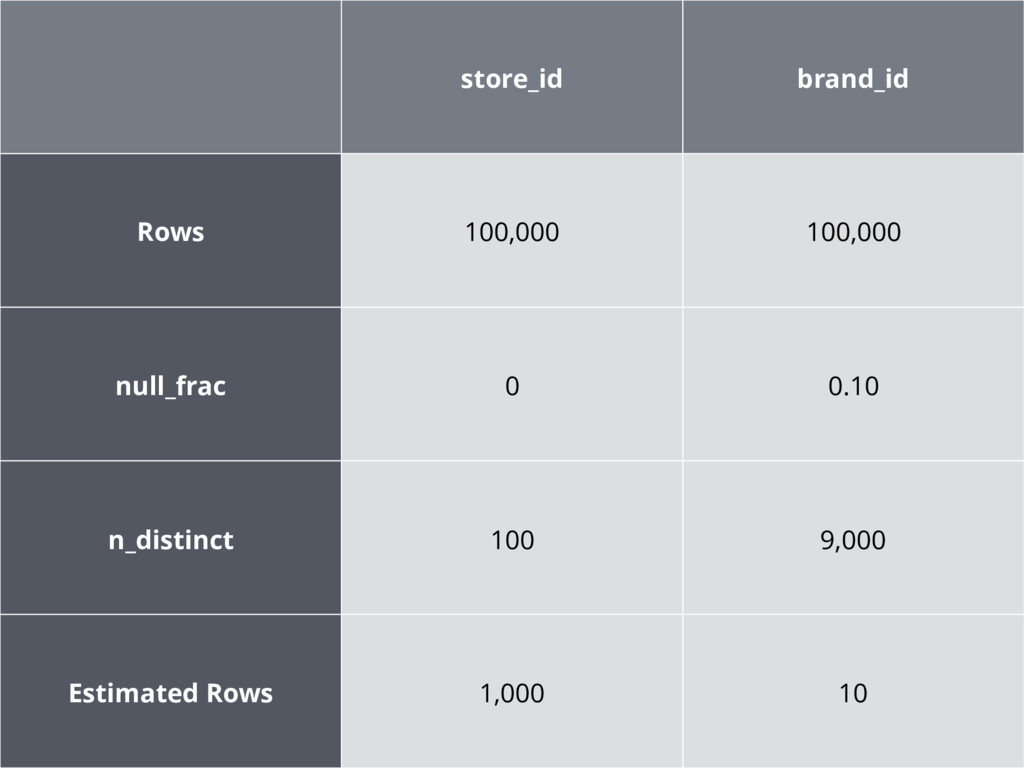
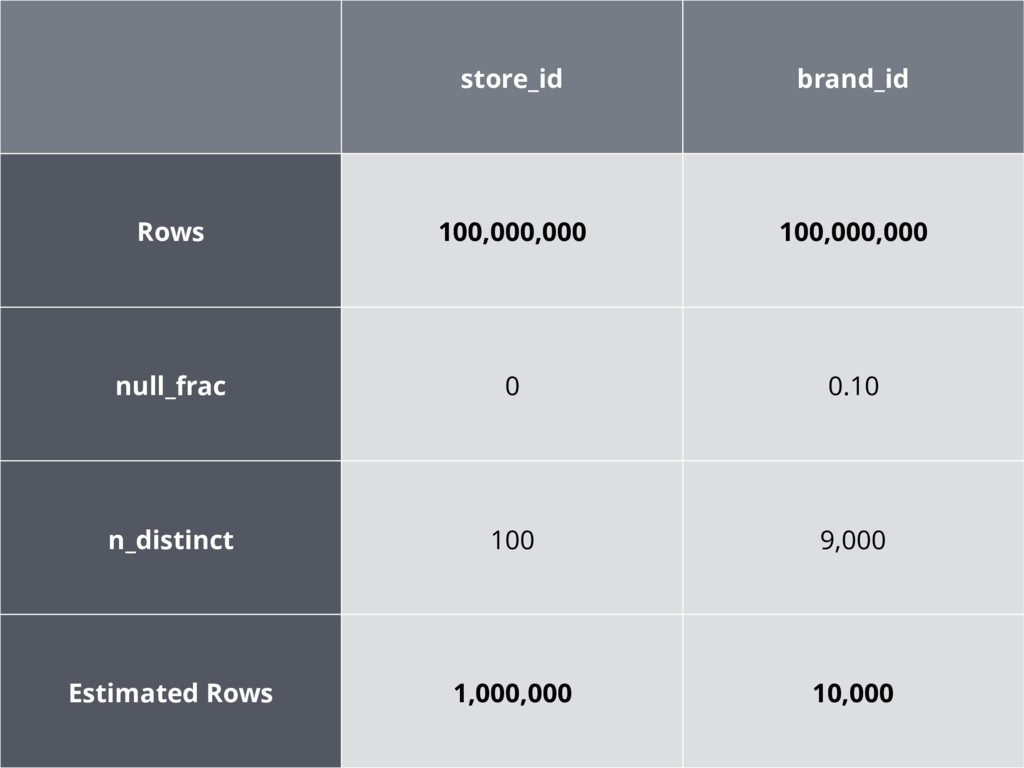
pg_stats n_distinct null_frac
store_id brand_id Rows 100,000 100,000 null_frac 0 0.10 n_distinct 100
9,000 Estimated Rows 1,000 10
store_id brand_id Rows 100,000,000 100,000,000 null_frac 0 0.10 n_distinct 100
9,000 Estimated Rows 1,000,000 10,000
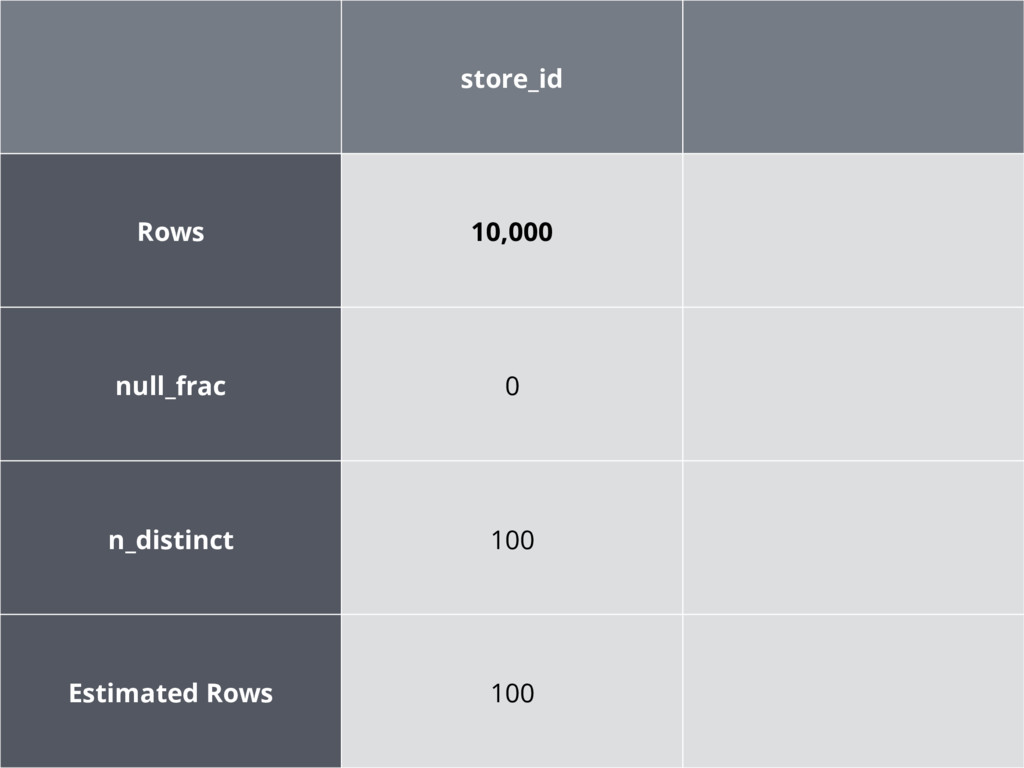
store_id Rows 10,000 null_frac 0 n_distinct 100 Estimated Rows 100
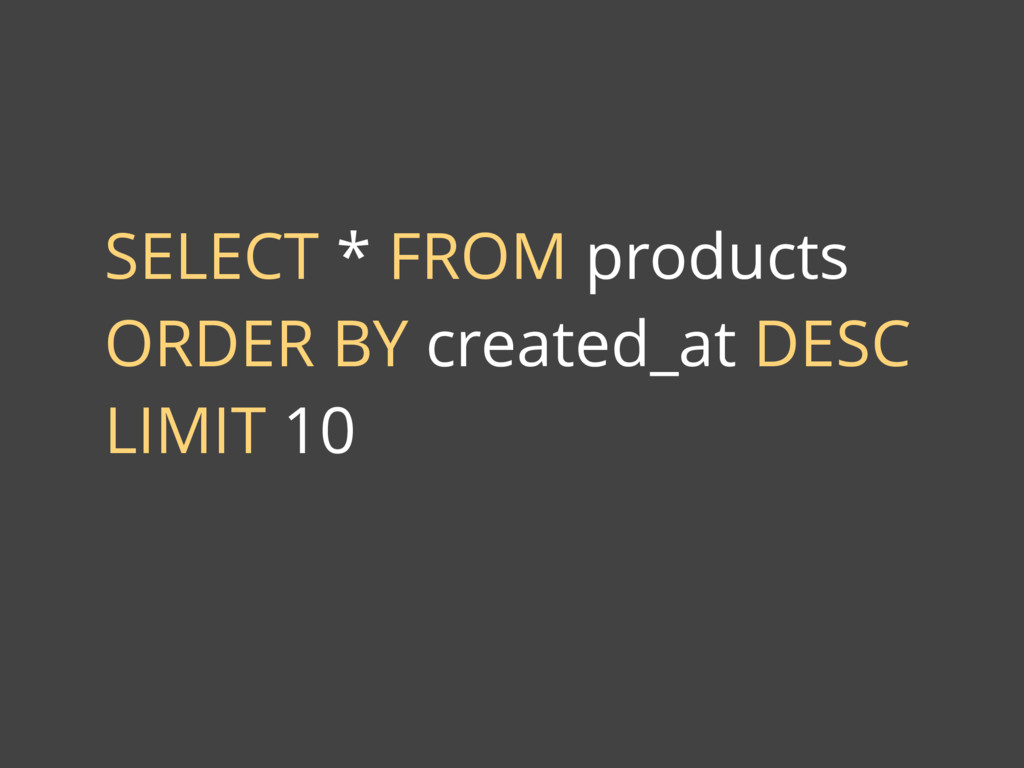
SELECT * FROM products ORDER BY created_at DESC LIMIT 10
SELECT * FROM products WHERE store_id = 1 ORDER BY
created_at DESC LIMIT 10
None
Shortcomings
Single table plus Simple WHERE clause and/or Simple ORDER BY
clause
Duplicating planner logic
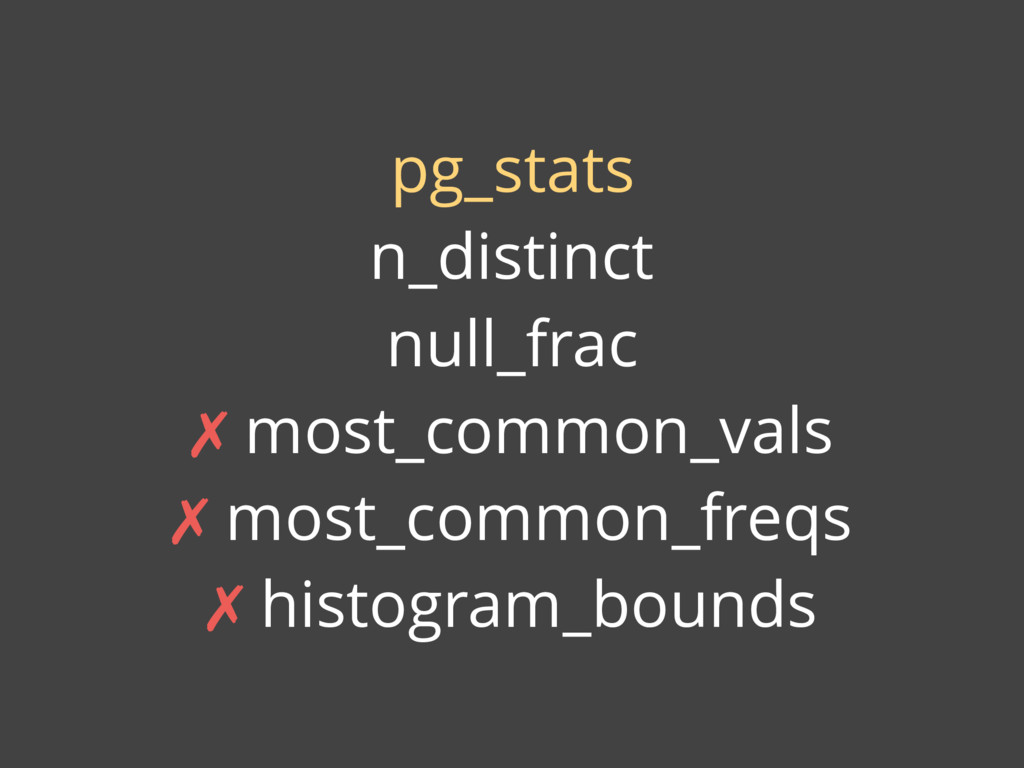
pg_stats n_distinct null_frac ✗ most_common_vals ✗ most_common_freqs ✗ histogram_bounds
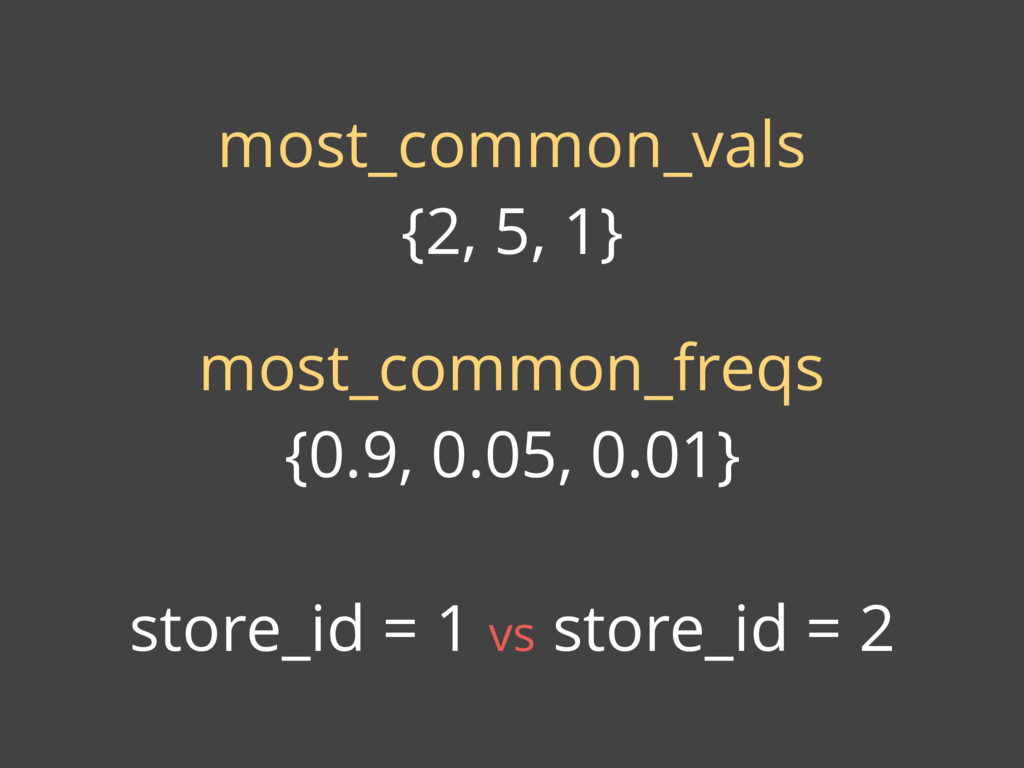
most_common_vals {2, 5, 1} most_common_freqs {0.9, 0.05, 0.01} store_id =
1 vs store_id = 2
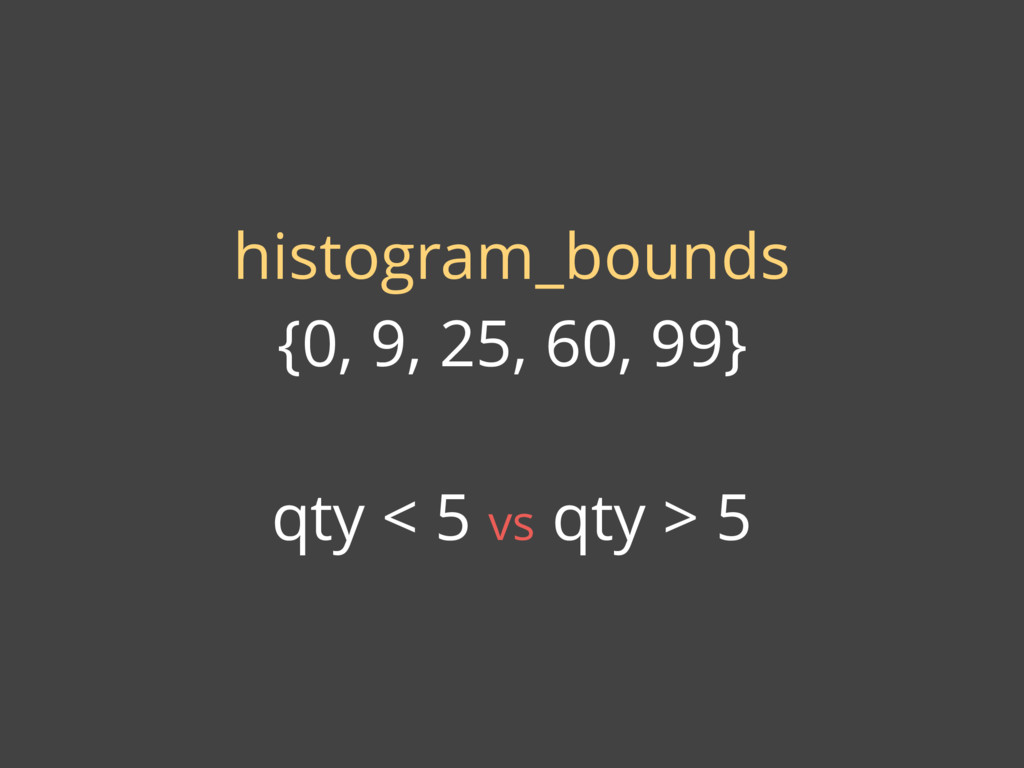
histogram_bounds {0, 9, 25, 60, 99} qty < 5 vs
qty > 5
SELECT * FROM products WHERE store_id = ?
v2
log_min_statement_duration duration: 100 ms statement: SELECT * FROM products WHERE
store_id = 1
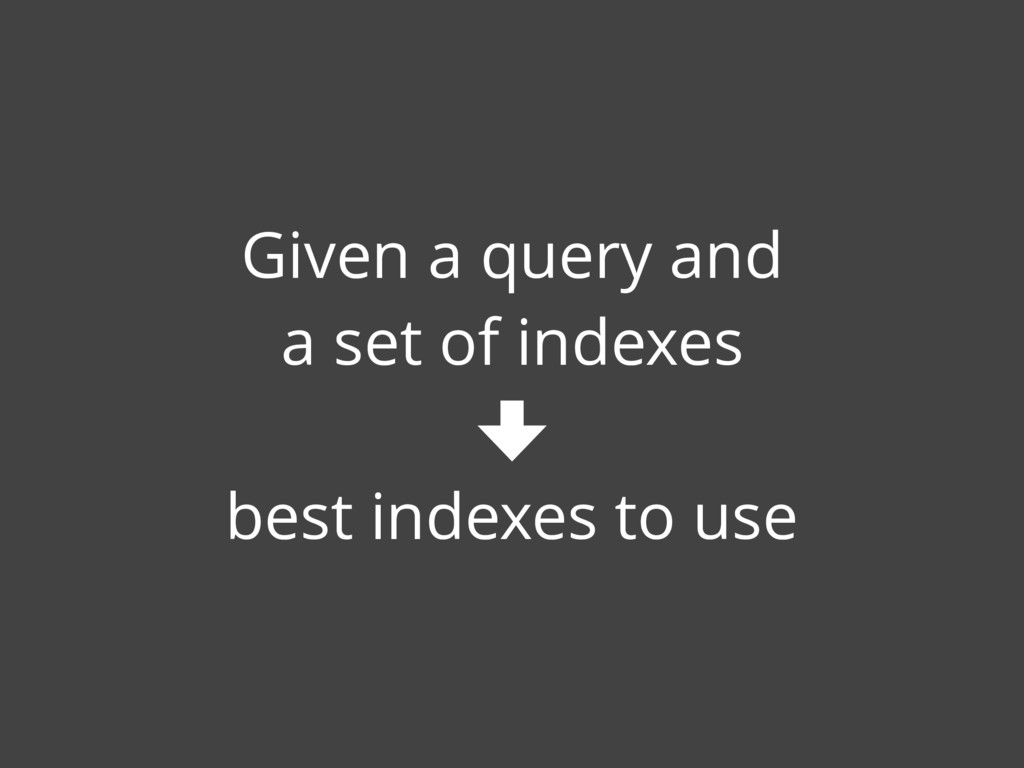
Given a query and a set of indexes best indexes
to use
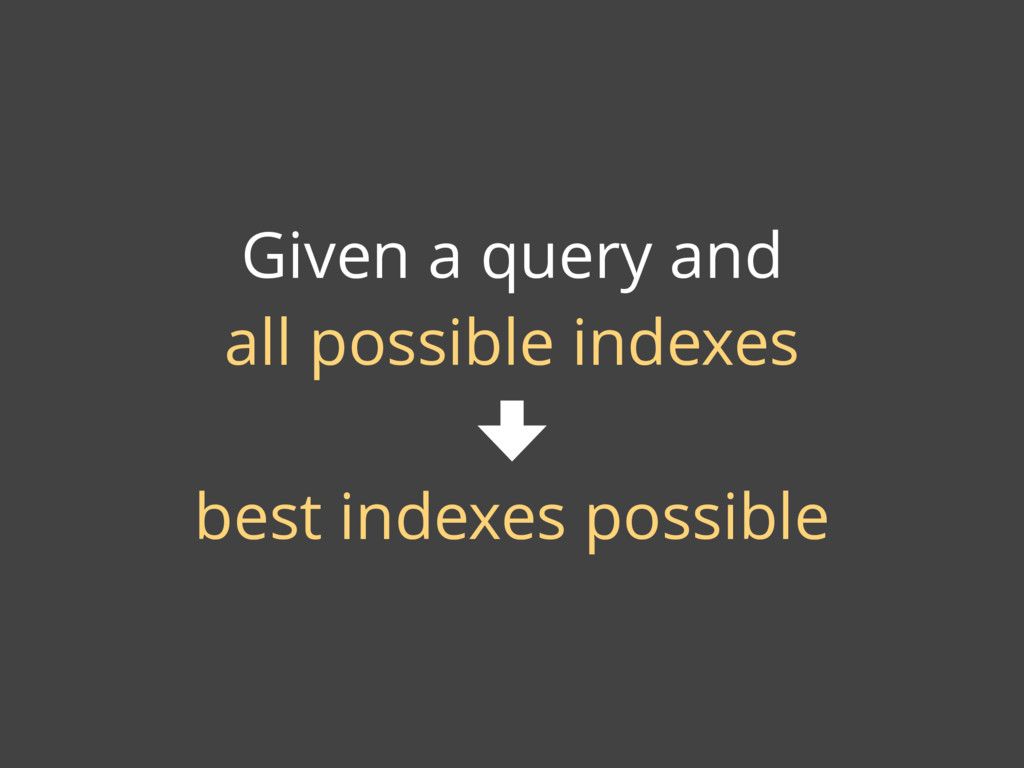
Given a query and all possible indexes best indexes possible
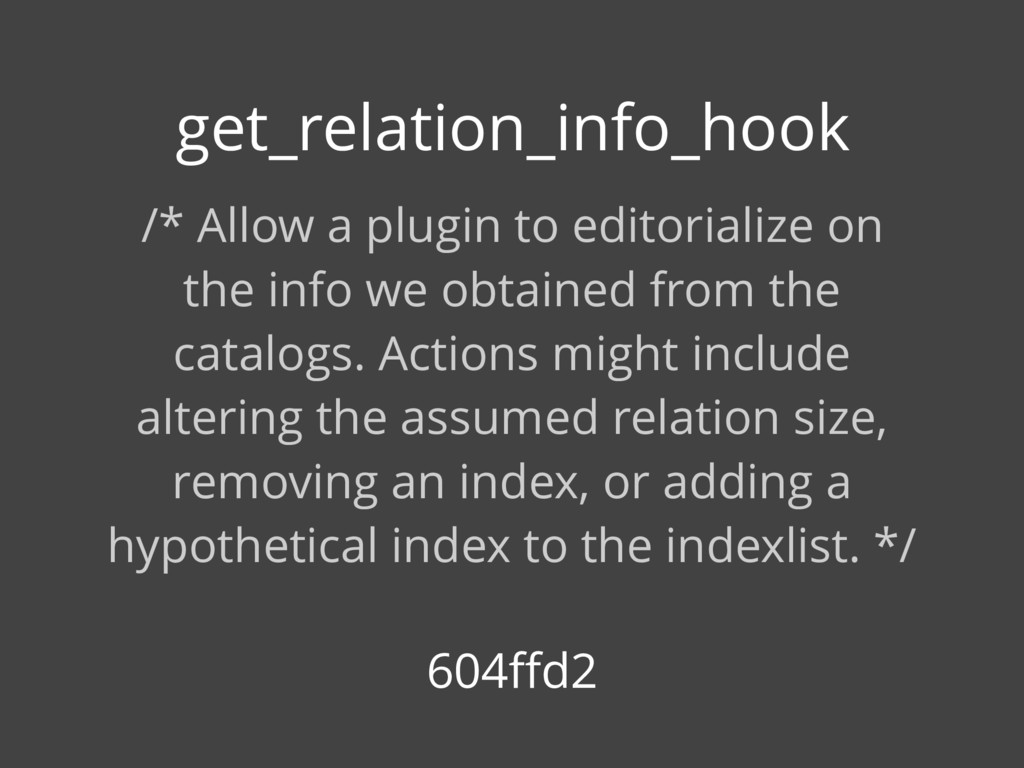
/* Allow a plugin to editorialize on the info we
obtained from the catalogs. Actions might include altering the assumed relation size, removing an index, or adding a hypothetical index to the indexlist. */ get_relation_info_hook 604ffd2
hypopg github.com/dalibo/hypopg
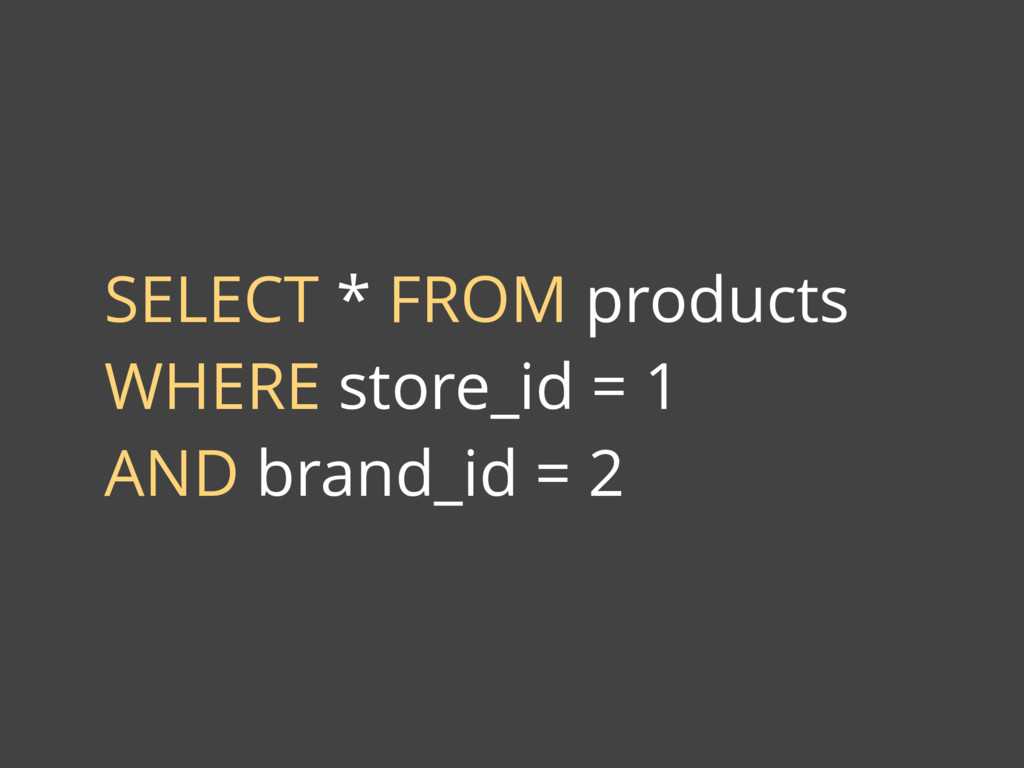
SELECT * FROM products WHERE store_id = 1 AND brand_id
= 2
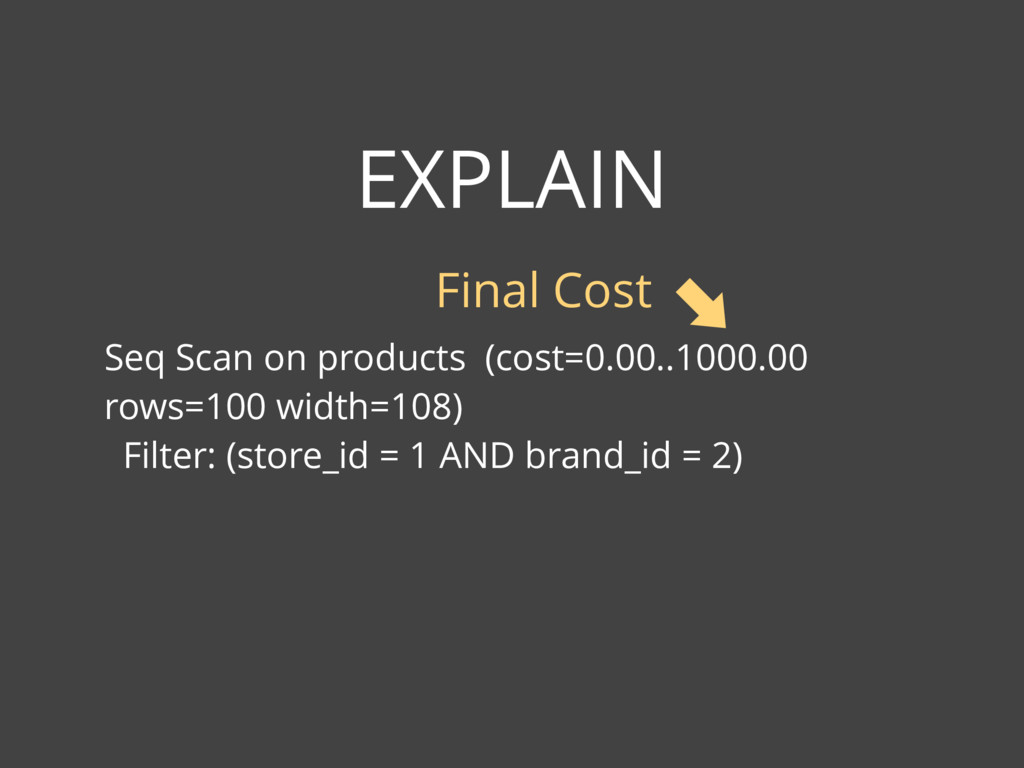
EXPLAIN Seq Scan on products (cost=0.00..1000.00 rows=100 width=108) Filter: (store_id
= 1 AND brand_id = 2) Final Cost
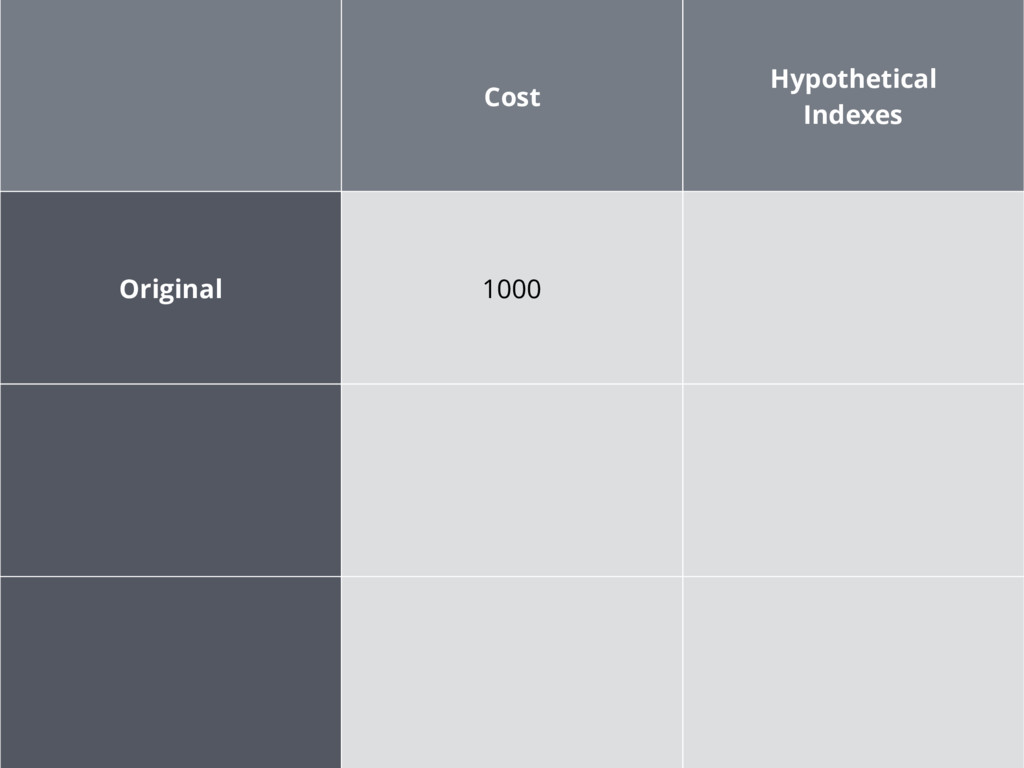
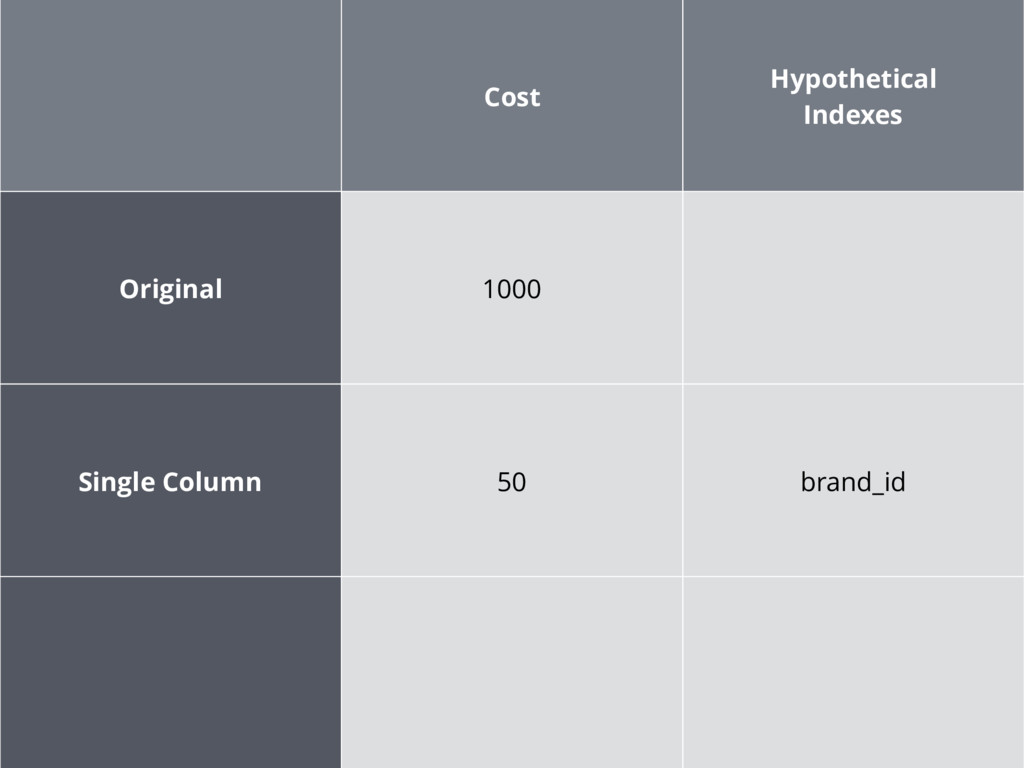
Cost Hypothetical Indexes Original 1000
Add hypothetical indexes store_id brand_id
EXPLAIN Index Scan using <41072>hypo_btree on products (cost=0.28..50.29 rows=1 width=108)
Index Cond: (brand_id = 2) Filter: (store_id = 1) Final Cost Index
Cost Hypothetical Indexes Original 1000 Single Column 50 brand_id
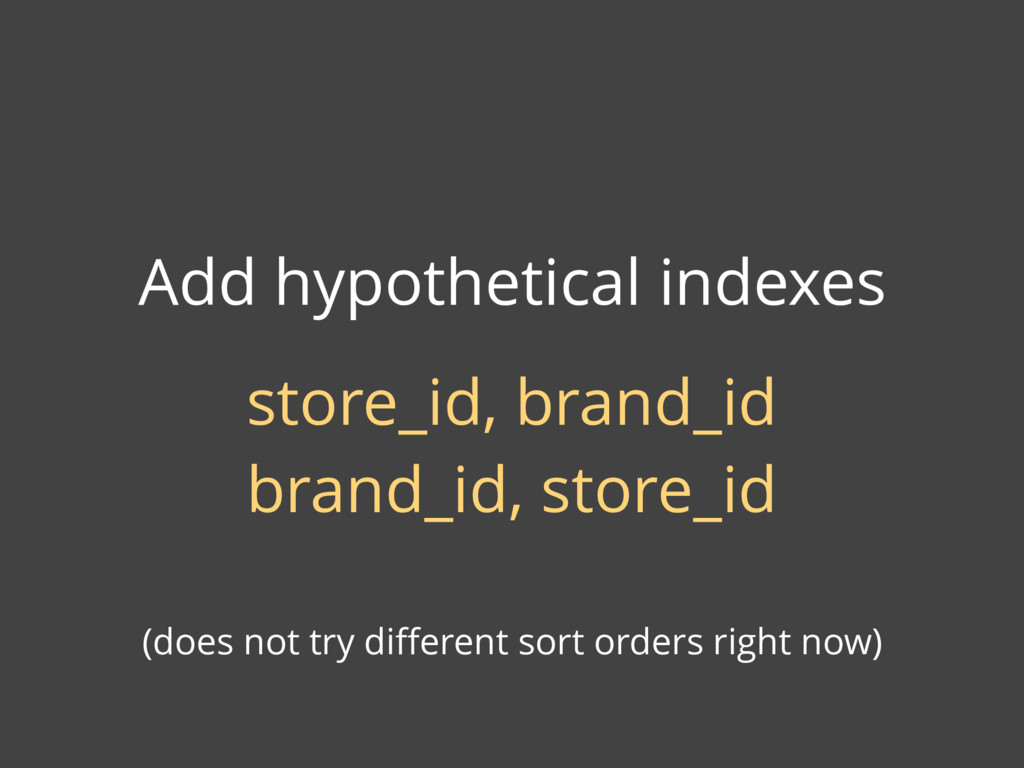
Add hypothetical indexes store_id, brand_id brand_id, store_id (does not try
different sort orders right now)
Cost Hypothetical Indexes Original 1000 Single Column 50 brand_id Multi
Column 45 brand_id, store_id
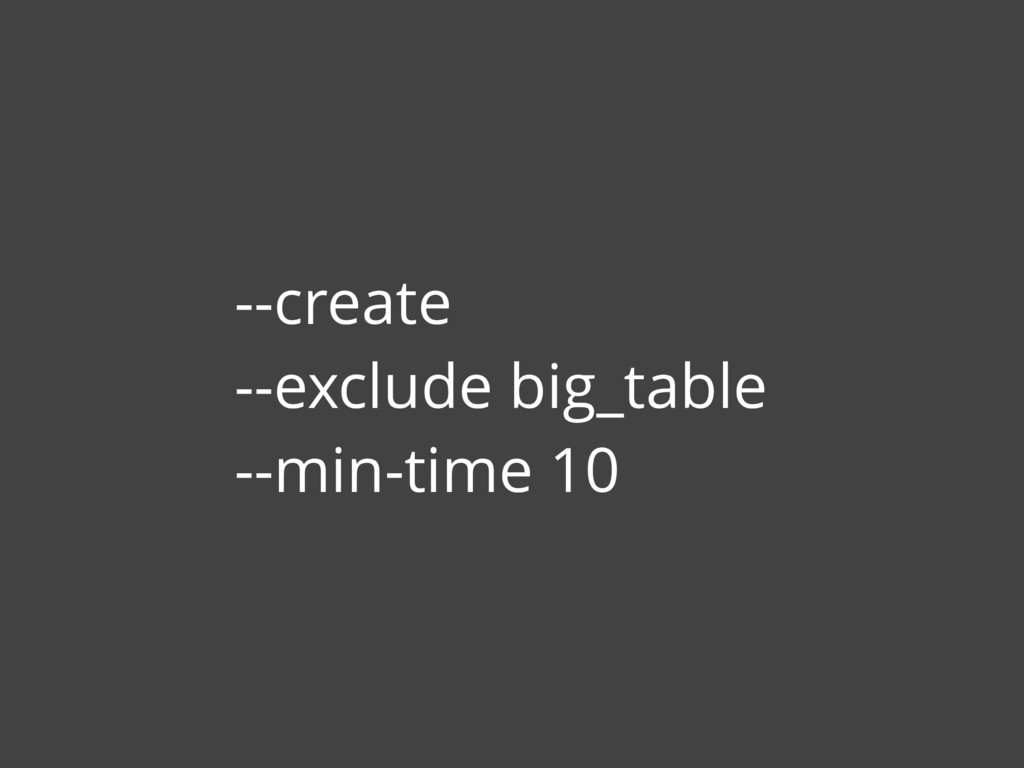
Dexter github.com/ankane/dexter
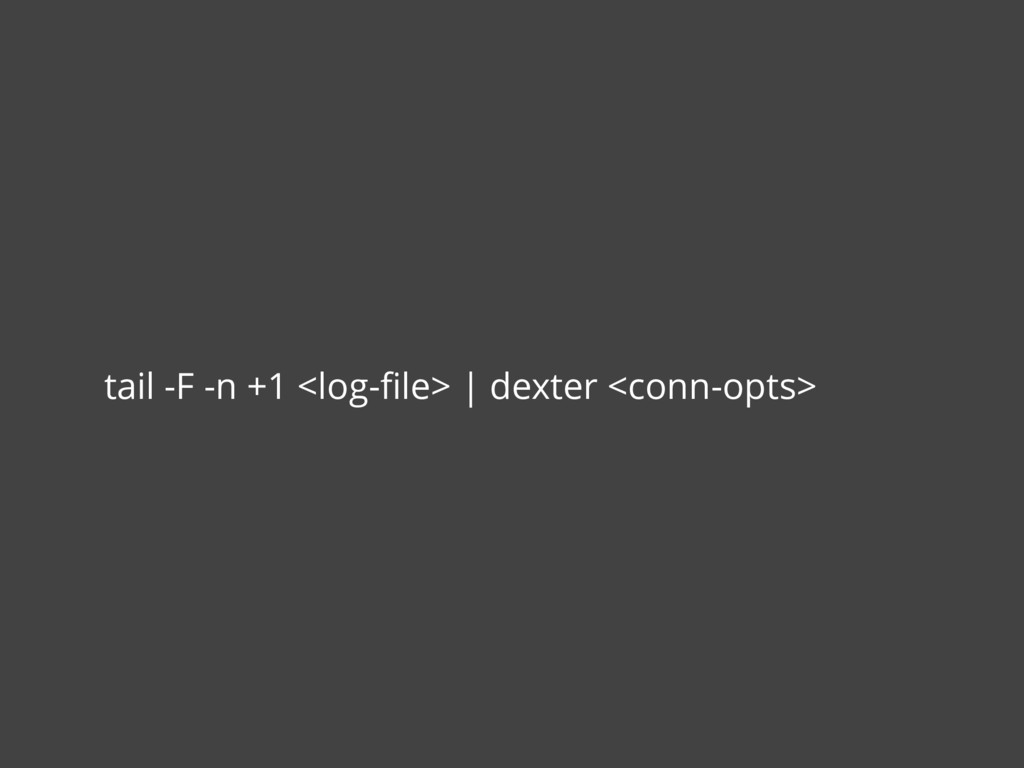
tail -F -n +1 <log-file> | dexter <conn-opts>
--create --exclude big_table --min-time 10
Shortcomings
SELECT * FROM products WHERE a = 1 AND b
= 2 SELECT * FROM products WHERE b = 2
B-TREE Only No Expressions No Partial
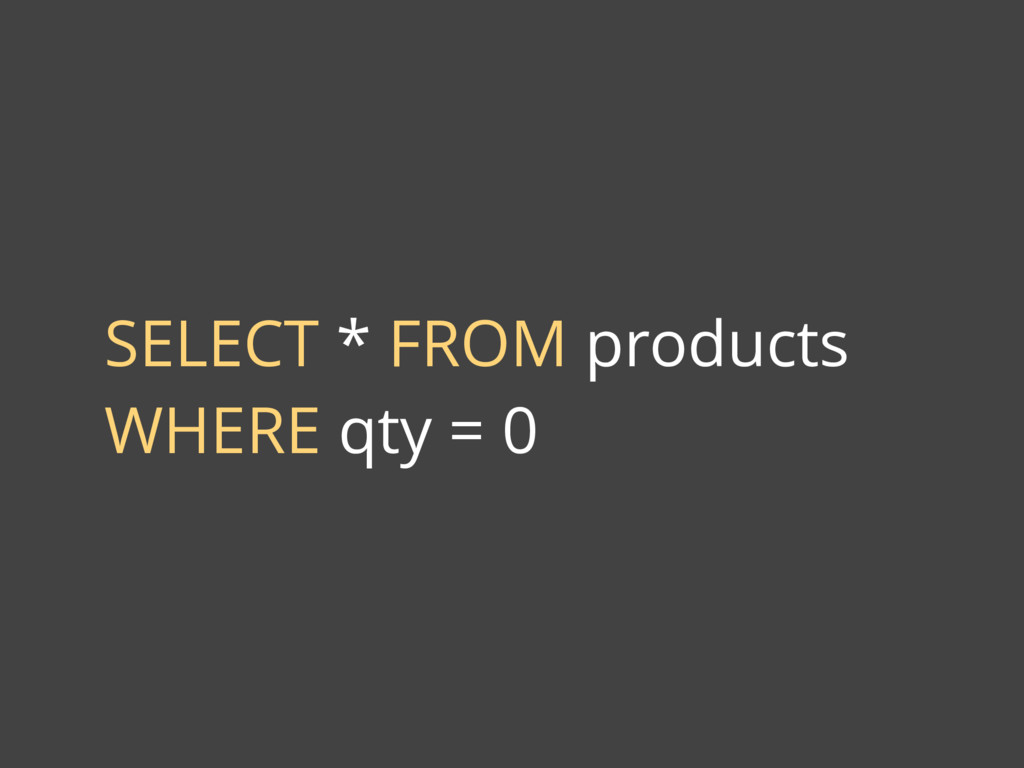
SELECT * FROM products WHERE qty = 0
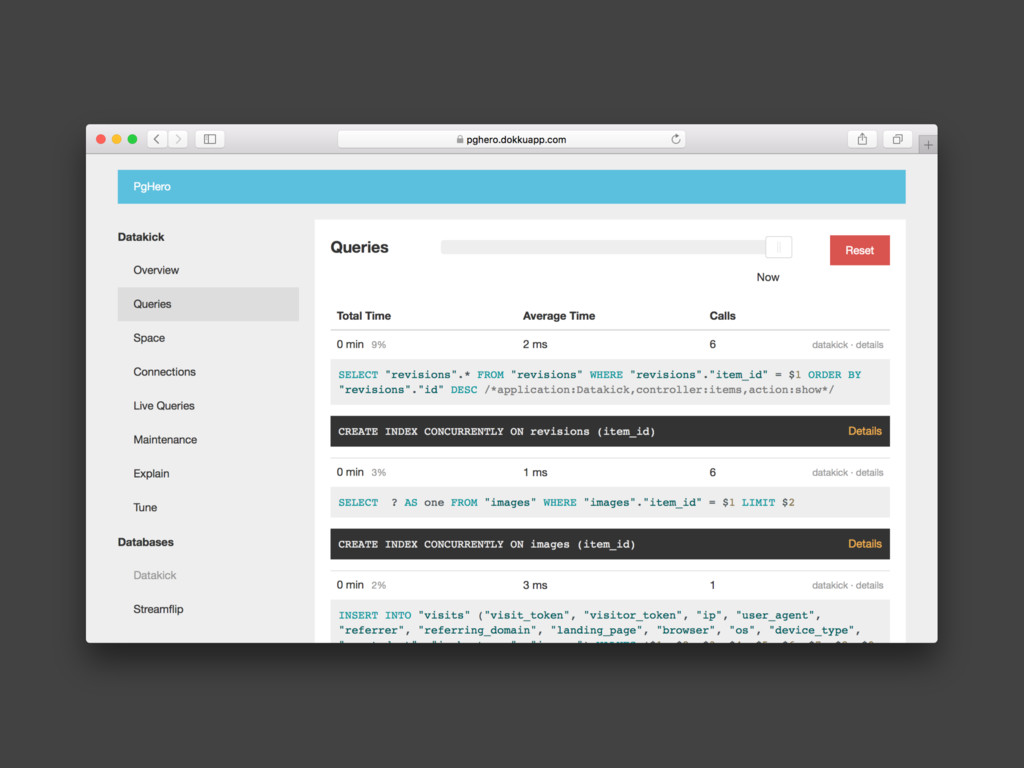
DROP INDEX Unused indexes
HypoPG Extension Support
None
pg_query HypoPG
Get Involved github.com/ankane/dexter


 magicpod
 l2hyunwoo
 kasacchiful
 har1101
 noguhiro2002
 mfunaki
 fufuhu
 jugyo
 contour_gara
 tatsuki12
 ra0kley
 mazrean
 sergeychernyshev
 samanthasiow
 axbom
 garrettdimon
 asonas
 livdayseo
 oripsolob
 tonyrice
 gurzu
 aleyda
 irinanazarova
 eileencodes