Upgrade to Pro — share decks privately, control downloads, hide ads and more …

June 2024 - Cracking the Code: Deciphering Eval...

June 2024 - Cracking the Code: Deciphering Evaluation Essentials for RAG

Join us for an enlightening exploration into the world of Retrieval Augmented Generation (RAG) systems, where we uncover the intricacies of evaluation criteria and demystify the role of existing tools and frameworks.
In this presentation, we'll dissect the essential components necessary for robust RAG evaluation, contrasting them with the offerings of current frameworks.
From semantic understanding to content coherence, we'll highlight what truly matters in the evaluation process, empowering you to make informed decisions in the ever-evolving landscape of RAG systems.

Video here : https://www.youtube.com/watch?v=swI4SLDTFH0

Avatar for Atita Arora

Atita Arora

June 26, 2026

More Decks by Atita Arora

Other Decks in Technology

Transcript

  1. About me Started 2008 - Computer Applications - Strategic Business

    Management - Vector / Semantic Search - Language analysis - Information retrieval Opensource Loves to travel, eat, cook Mom of 2 boys
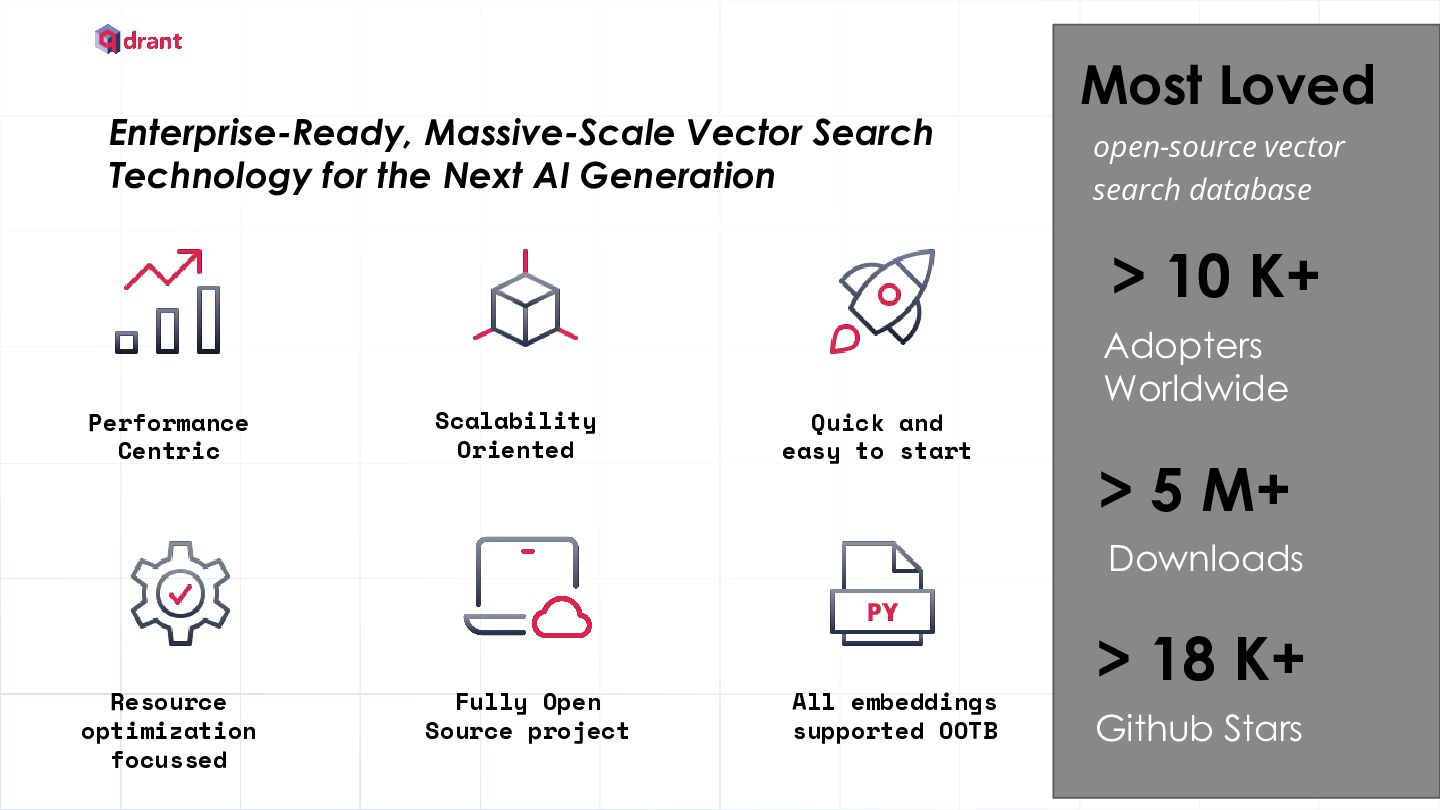
  2. Enterprise-Ready, Massive-Scale Vector Search Technology for the Next AI Generation

    Performance Centric Quick and easy to start Resource optimization focussed All embeddings supported OOTB Fully Open Source project Scalability Oriented Most Loved open-source vector search database > 10 K+ Adopters Worldwide > 5 M+ Downloads > 18 K+ Github Stars
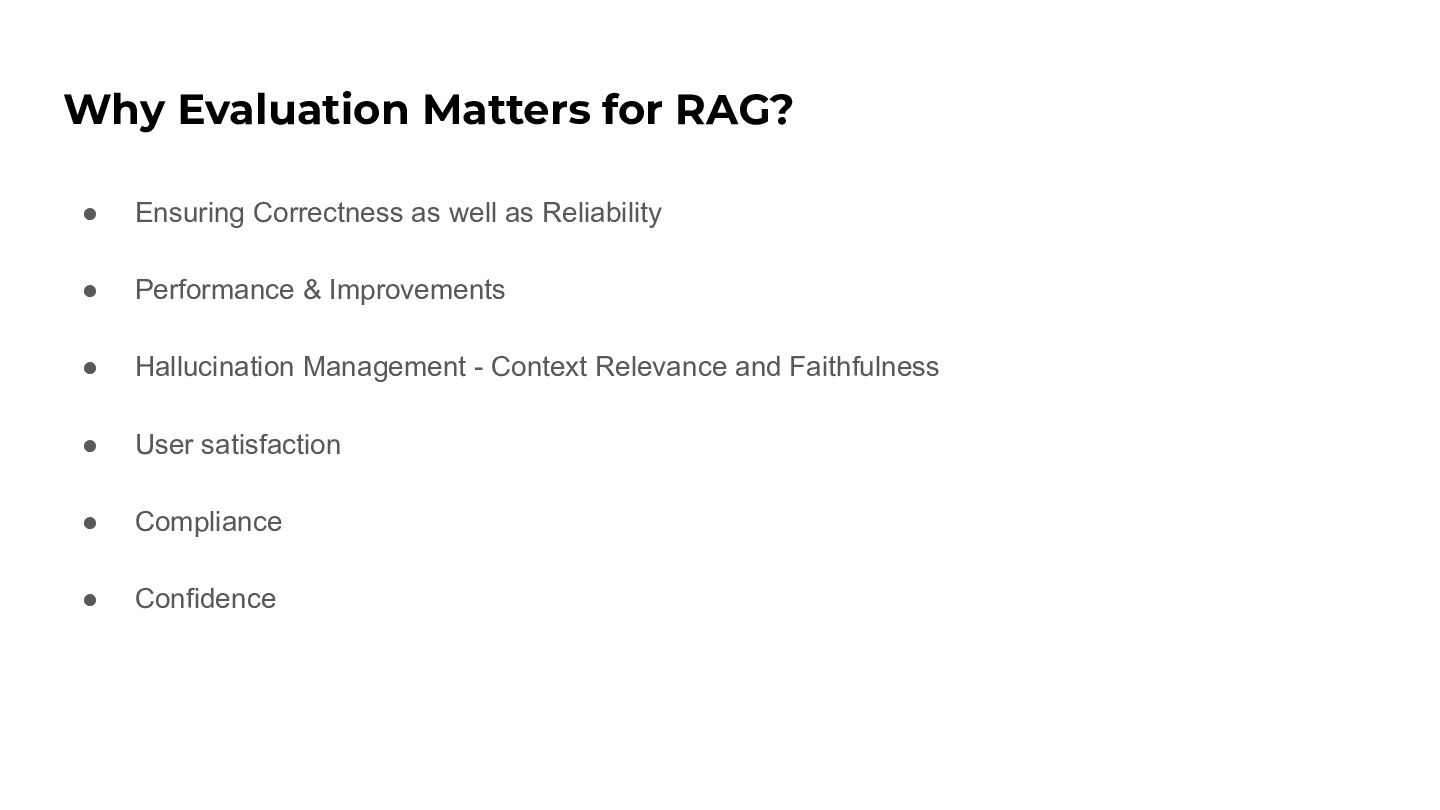
  3. Why Evaluation Matters for RAG? • Ensuring Correctness as well

    as Reliability • Performance & Improvements • Hallucination Management - Context Relevance and Faithfulness • User satisfaction • Compliance • Confidence
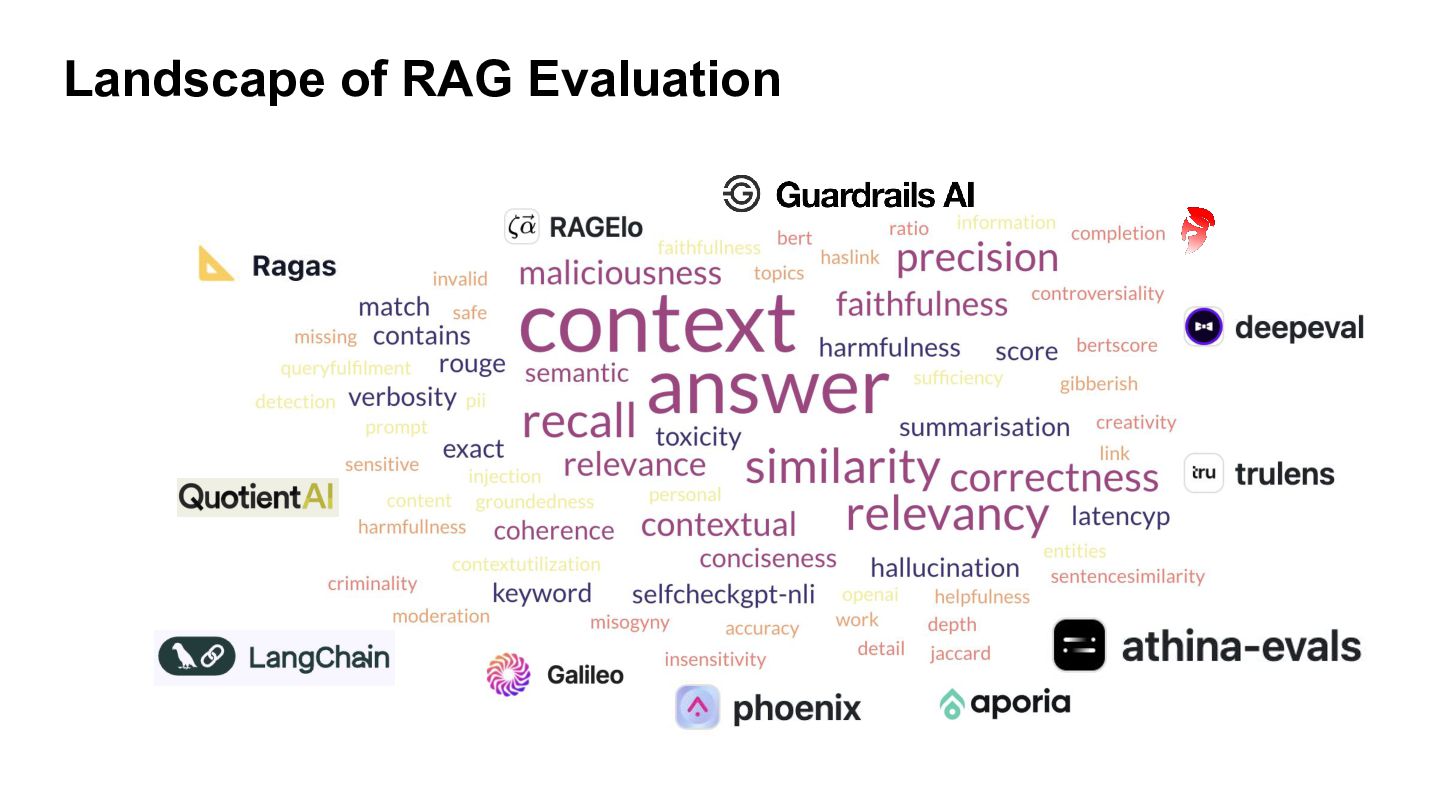
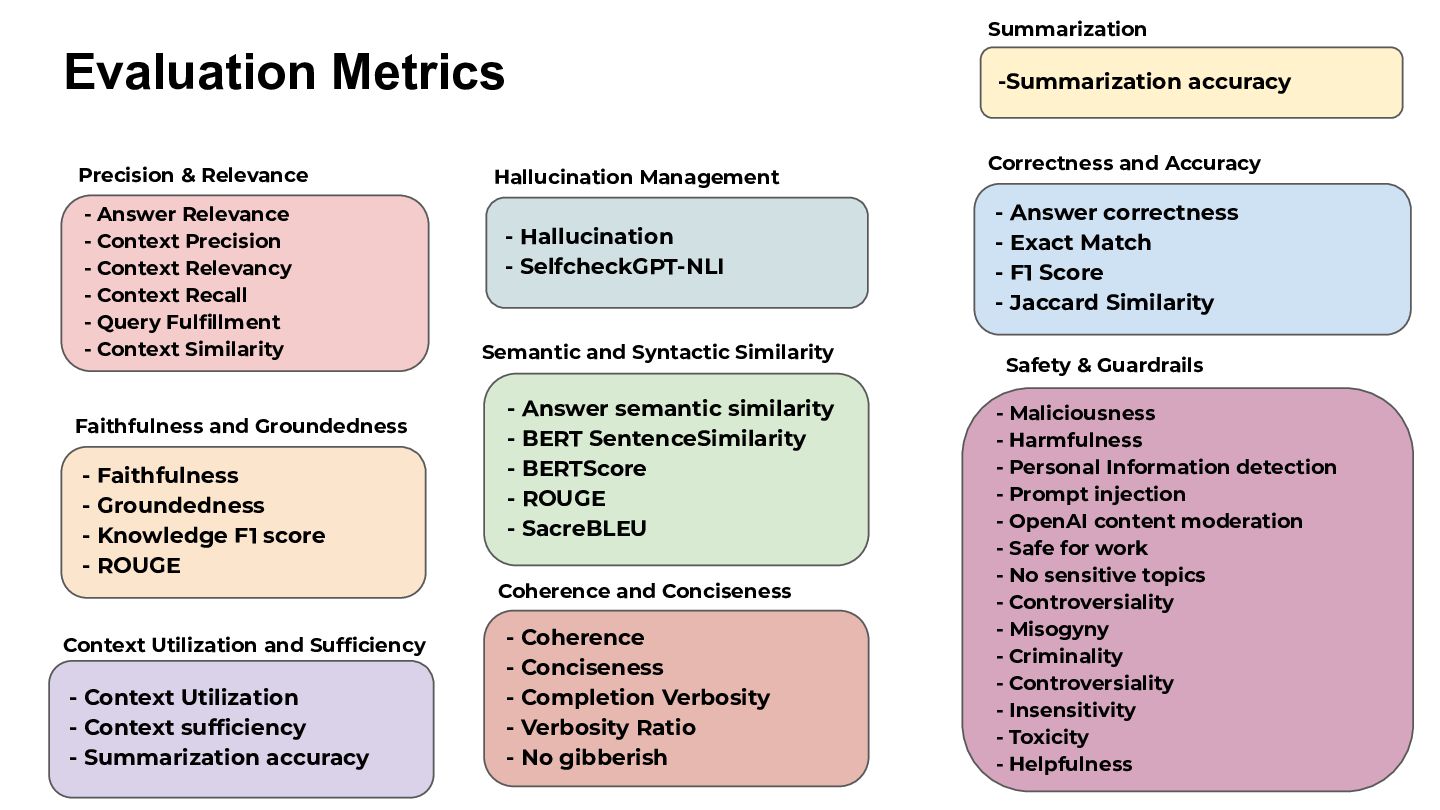
  4. Precision & Relevance Evaluation Metrics Semantic and Syntactic Similarity Context

    Utilization and Sufficiency - Answer Relevance - Context Precision - Context Relevancy - Context Recall - Query Fulfillment - Context Similarity - Faithfulness - Groundedness - Knowledge F1 score - ROUGE - Hallucination - SelfcheckGPT-NLI -Summarization accuracy - Answer correctness - Exact Match - F1 Score - Jaccard Similarity - Answer semantic similarity - BERT SentenceSimilarity - BERTScore - ROUGE - SacreBLEU - Coherence - Conciseness - Completion Verbosity - Verbosity Ratio - No gibberish Coherence and Conciseness Hallucination Management - Context Utilization - Context sufficiency - Summarization accuracy - Maliciousness - Harmfulness - Personal Information detection - Prompt injection - OpenAI content moderation - Safe for work - No sensitive topics - Controversiality - Misogyny - Criminality - Controversiality - Insensitivity - Toxicity - Helpfulness Faithfulness and Groundedness Correctness and Accuracy Safety & Guardrails Summarization
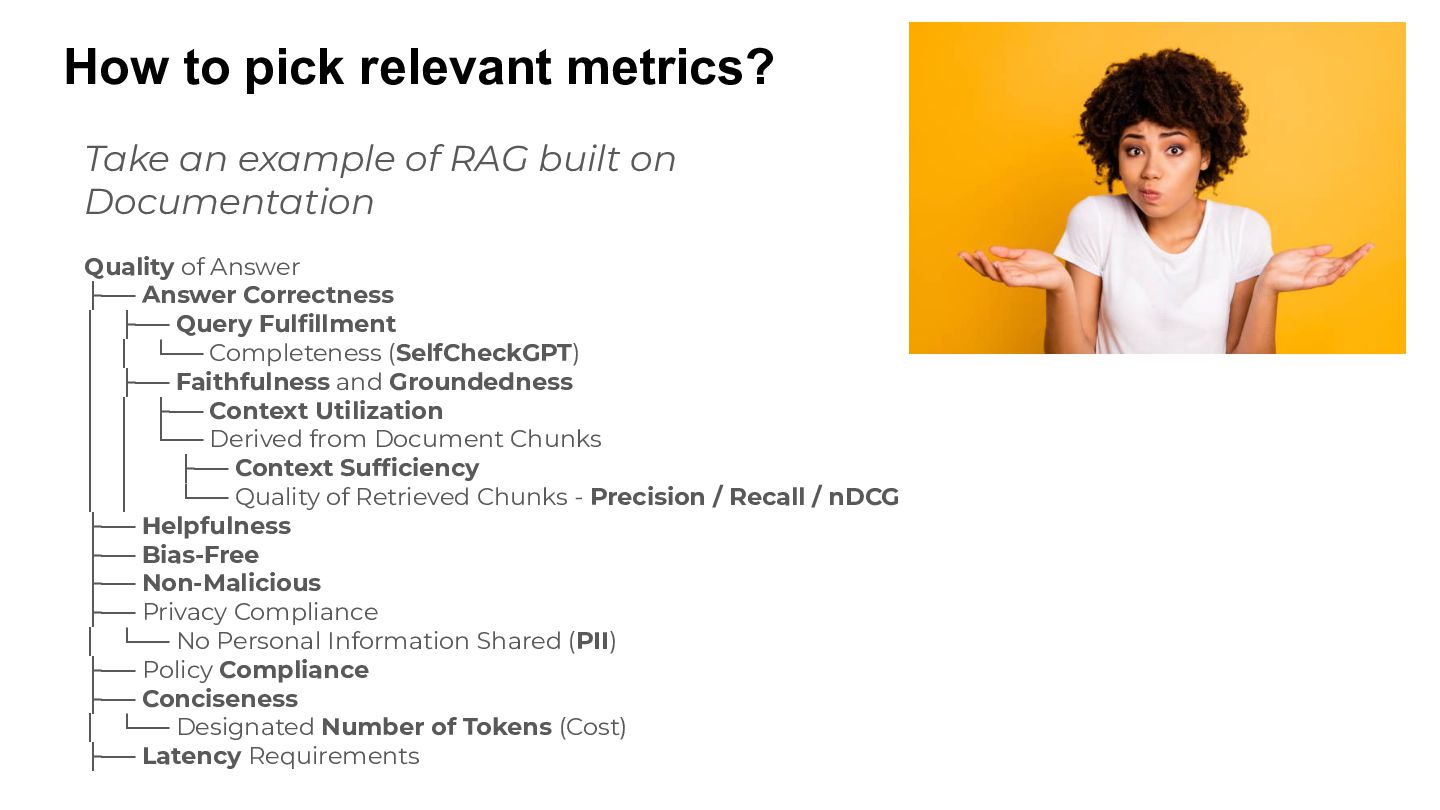
  5. How to pick relevant metrics? Take an example of RAG

    built on Documentation Quality of Answer ├── Answer Correctness │ ├── Query Fulfillment │ │ └── Completeness (SelfCheckGPT) │ ├── Faithfulness and Groundedness │ │ ├── Context Utilization │ │ └── Derived from Document Chunks │ │ ├── Context Sufficiency │ │ └── Quality of Retrieved Chunks - Precision / Recall / nDCG ├── Helpfulness ├── Bias-Free ├── Non-Malicious ├── Privacy Compliance │ └── No Personal Information Shared (PII) ├── Policy Compliance ├── Conciseness │ └── Designated Number of Tokens (Cost) ├── Latency Requirements
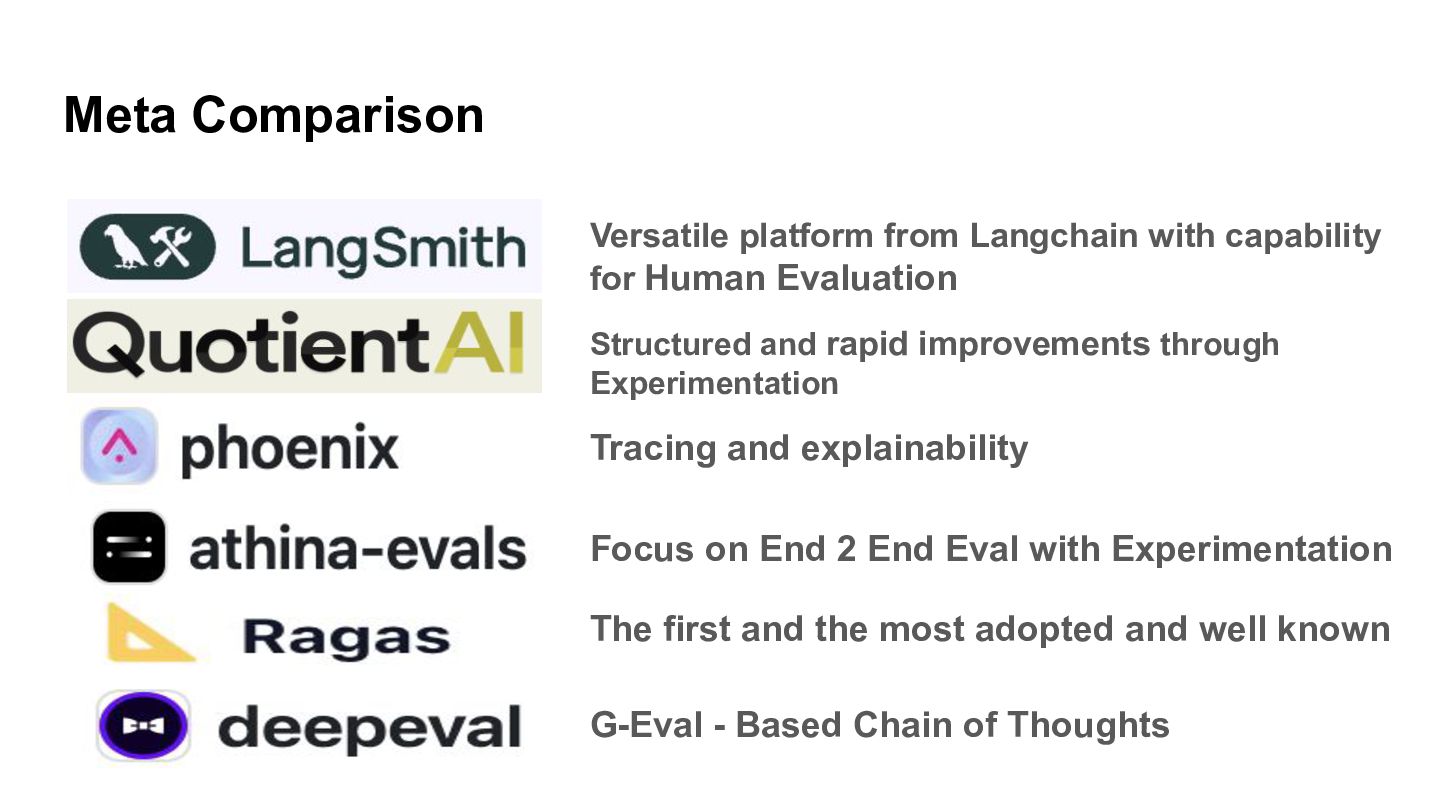
  6. Meta Comparison Versatile platform from Langchain with capability for Human

    Evaluation Structured and rapid improvements through Experimentation Tracing and explainability Focus on End 2 End Eval with Experimentation The first and the most adopted and well known G-Eval - Based Chain of Thoughts
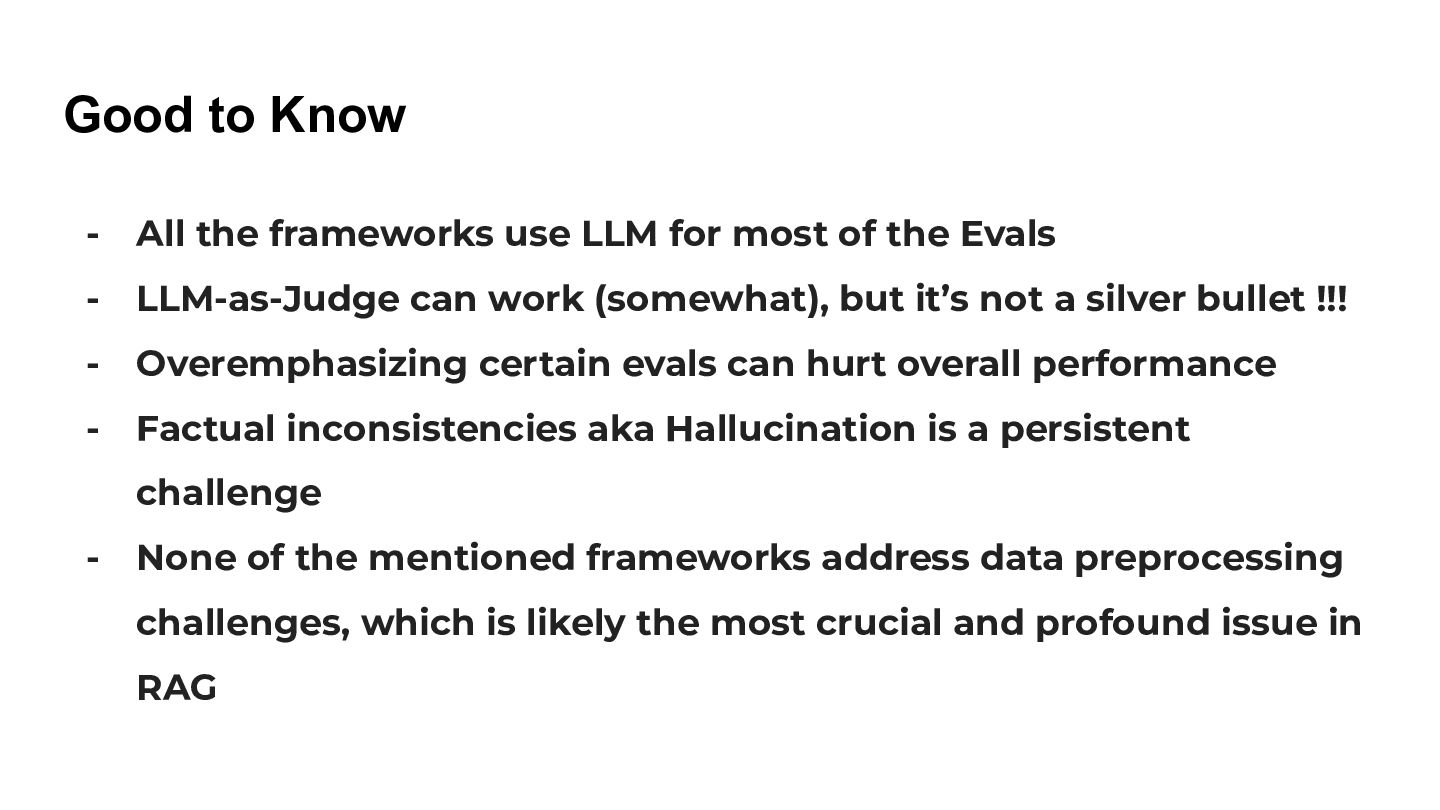
  7. Good to Know - All the frameworks use LLM for

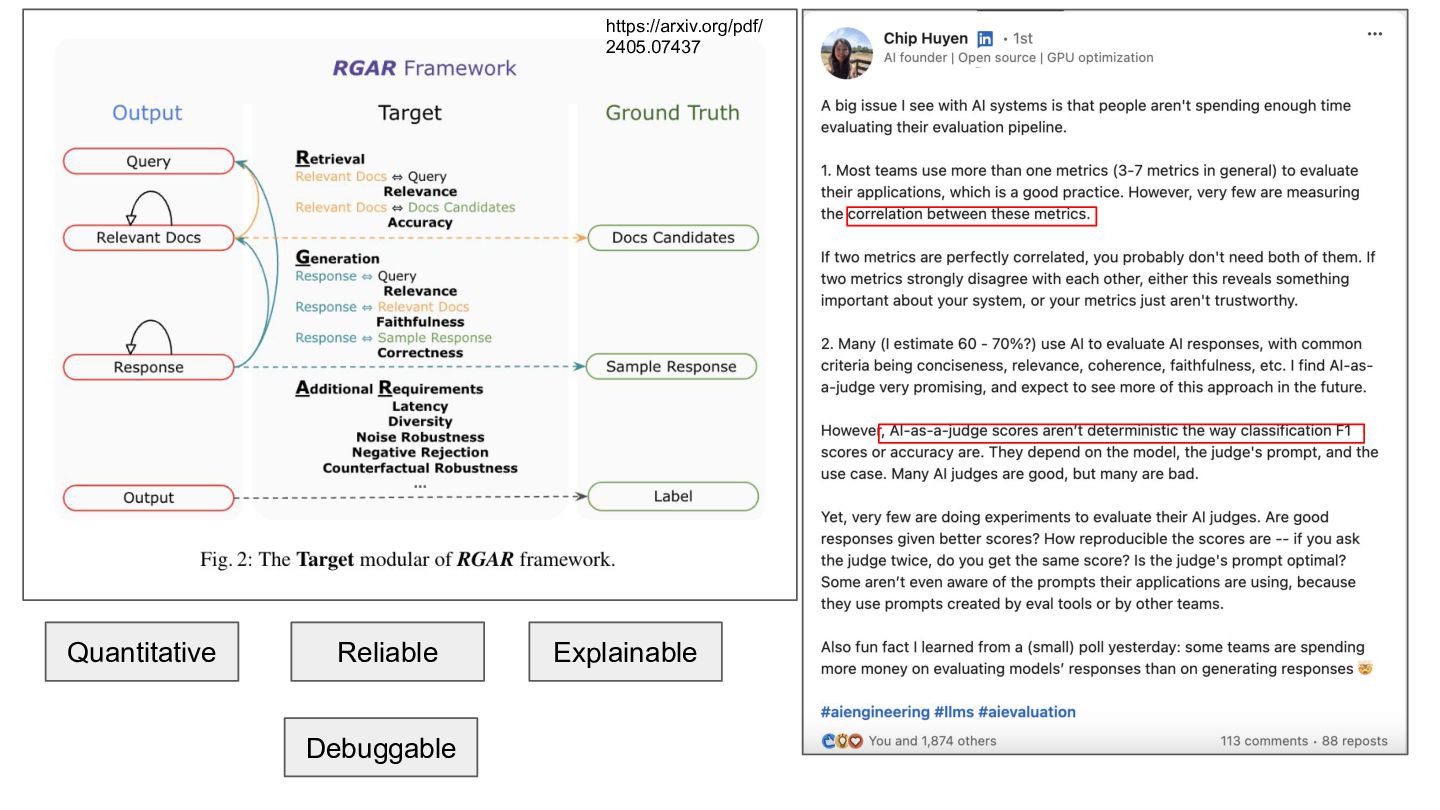
    most of the Evals - LLM-as-Judge can work (somewhat), but it’s not a silver bullet !!! - Overemphasizing certain evals can hurt overall performance - Factual inconsistencies aka Hallucination is a persistent challenge - None of the mentioned frameworks address data preprocessing challenges, which is likely the most crucial and profound issue in RAG
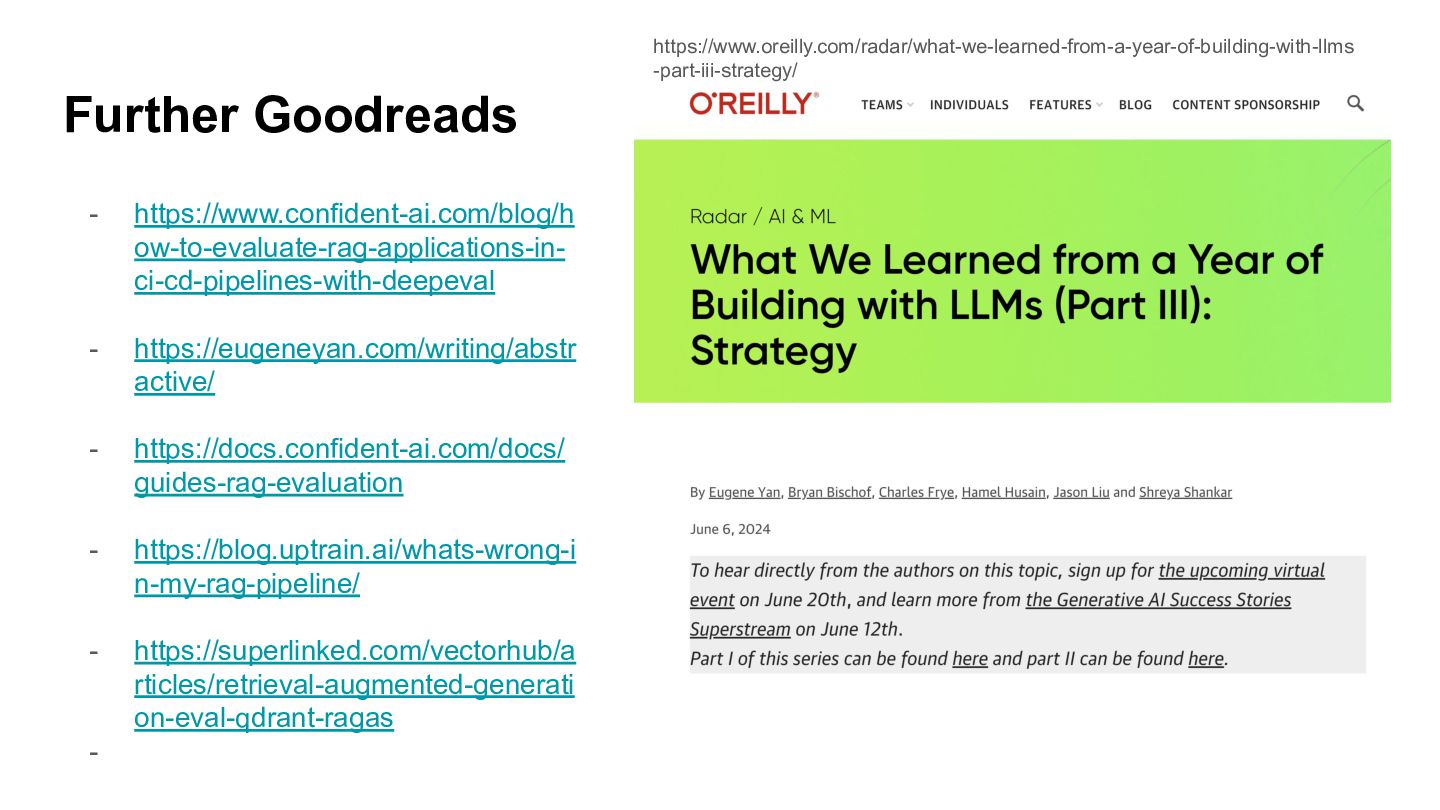
  8. Further Goodreads https://www.oreilly.com/radar/what-we-learned-from-a-year-of-building-with-llms -part-iii-strategy/ - https://www.confident-ai.com/blog/h ow-to-evaluate-rag-applications-in- ci-cd-pipelines-with-deepeval - https://eugeneyan.com/writing/abstr

    active/ - https://docs.confident-ai.com/docs/ guides-rag-evaluation - https://blog.uptrain.ai/whats-wrong-i n-my-rag-pipeline/ - https://superlinked.com/vectorhub/a rticles/retrieval-augmented-generati on-eval-qdrant-ragas -
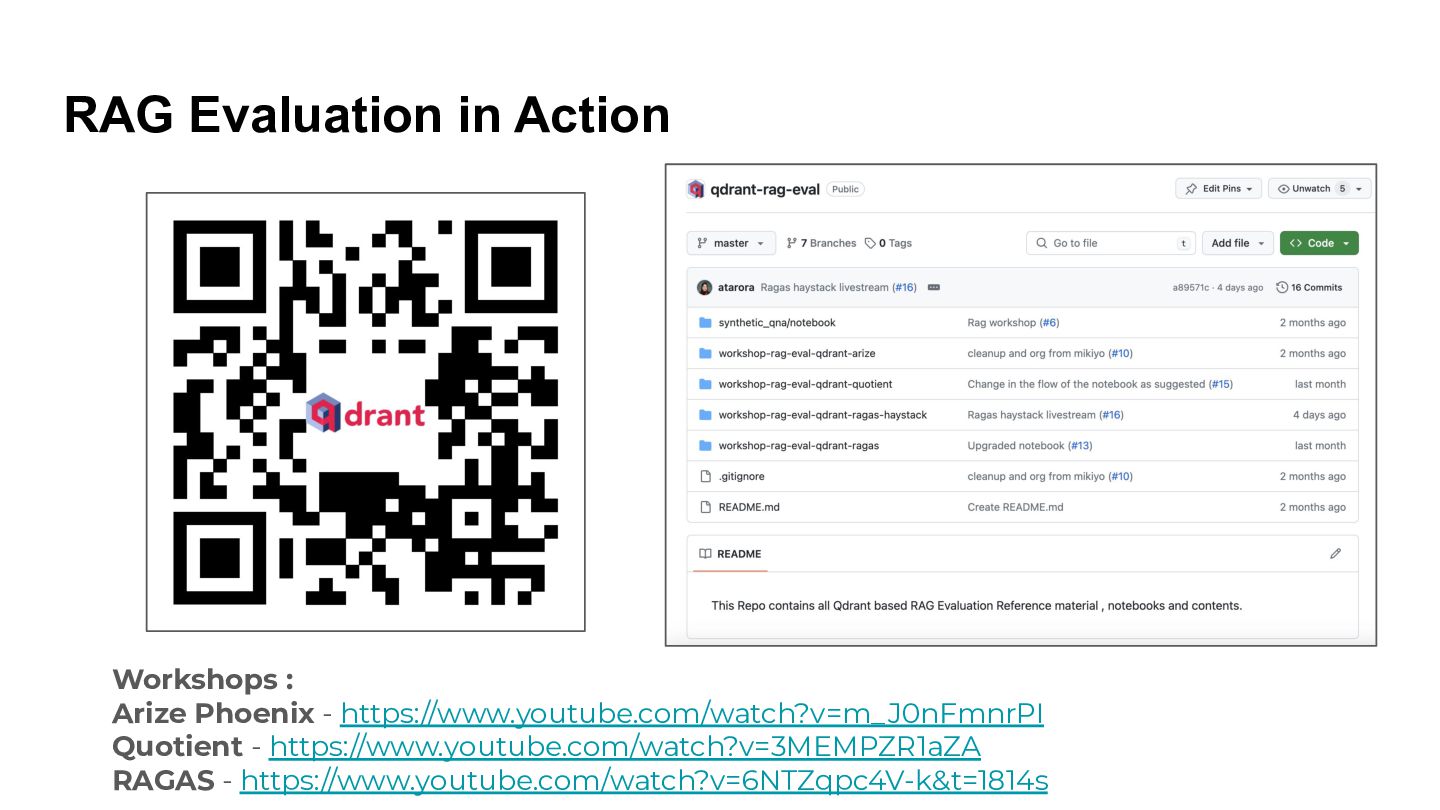
  9. RAG Evaluation in Action Workshops : Arize Phoenix - https://www.youtube.com/watch?v=m_J0nFmnrPI

    Quotient - https://www.youtube.com/watch?v=3MEMPZR1aZA RAGAS - https://www.youtube.com/watch?v=6NTZqpc4V-k&t=1814s