Share
Embed
Dealing with computer vision competition on Kaggle
In this talk we will discuss how to start dealing with computer vision challenges: GPU-resources, which competition to choose, what tutorial to take before start and how to improve your score
https://www.meetup.com/Kaggle-Munich/events/248986846/
Alex Tselikov
May 02, 2018
Transcript
27 slides
-
DEALING WITH COMPUTER VISION COMPETITION ON KAGGLE ALEX TSELIKOV DATA
SCIENTIST @ KI-LABS -
WHO AM I • Ph.D. in computer science (data analysis)
• Data Science & Data Analysis, 5+ years (industry and academia) • Currently: Senior Data Scientist, KI-Labs • Previous: Senior Data Scientist, VEON (Telecom) -
NN EXPERIENCE • NLP projects: creating chat-bot for call-center with
deep learning back-end, improving chat-bot accuracy by processing clients messages using word2vec technology. • 5-6 CNN layers (embeding, Convolution, MaxPooling, Flatten, Dense, Dropout, Dense) • 3-4 LSTM layers (embeding, LSTM, Dense) -
BEST WAY TO LEANR SOMETHING - is to tell it
to somebody else -
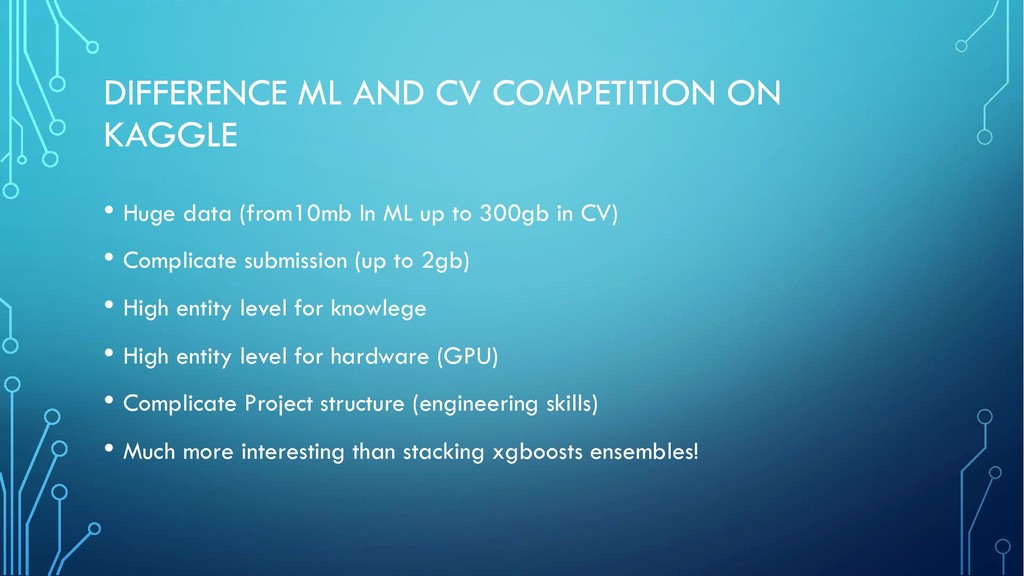
DIFFERENCE ML AND CV COMPETITION ON KAGGLE • Huge data
(from10mb In ML up to 300gb in CV) • Complicate submission (up to 2gb) • High entity level for knowlege • High entity level for hardware (GPU) • Complicate Project structure (engineering skills) • Much more interesting than stacking xgboosts ensembles! -
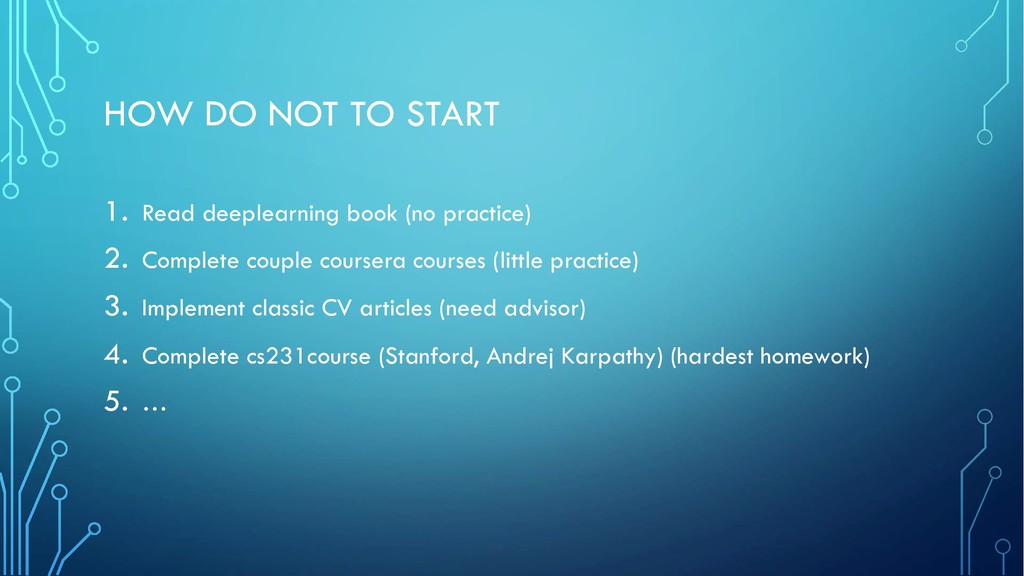
HOW DO NOT TO START 1. Read deeplearning book (no
practice) 2. Complete couple coursera courses (little practice) 3. Implement classic CV articles (need advisor) 4. Complete cs231course (Stanford, Andrej Karpathy) (hardest homework) 5. … -
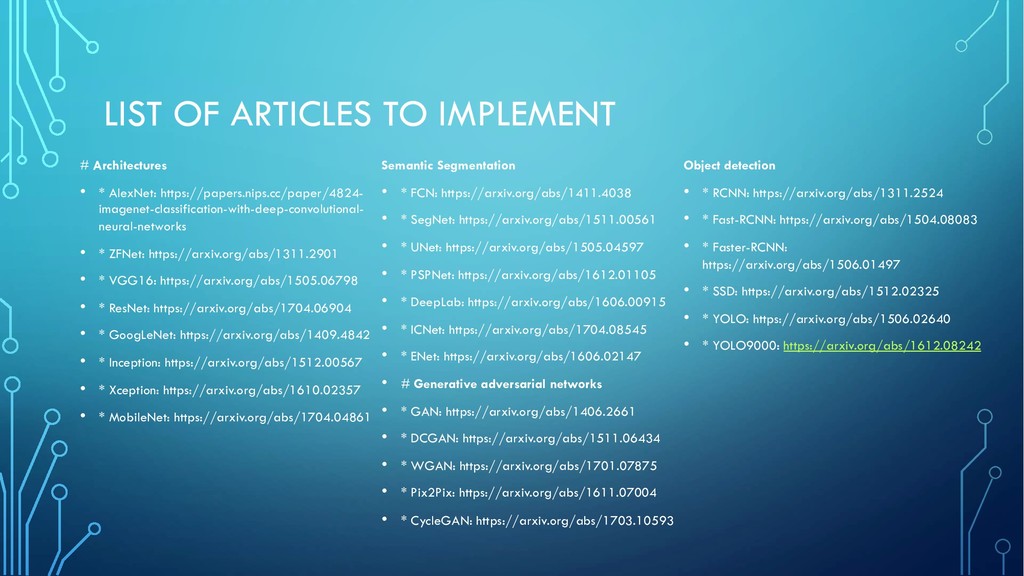
LIST OF ARTICLES TO IMPLEMENT # Architectures • * AlexNet:
https://papers.nips.cc/paper/4824- imagenet-classification-with-deep-convolutional- neural-networks • * ZFNet: https://arxiv.org/abs/1311.2901 • * VGG16: https://arxiv.org/abs/1505.06798 • * ResNet: https://arxiv.org/abs/1704.06904 • * GoogLeNet: https://arxiv.org/abs/1409.4842 • * Inception: https://arxiv.org/abs/1512.00567 • * Xception: https://arxiv.org/abs/1610.02357 • * MobileNet: https://arxiv.org/abs/1704.04861 Semantic Segmentation • * FCN: https://arxiv.org/abs/1411.4038 • * SegNet: https://arxiv.org/abs/1511.00561 • * UNet: https://arxiv.org/abs/1505.04597 • * PSPNet: https://arxiv.org/abs/1612.01105 • * DeepLab: https://arxiv.org/abs/1606.00915 • * ICNet: https://arxiv.org/abs/1704.08545 • * ENet: https://arxiv.org/abs/1606.02147 • # Generative adversarial networks • * GAN: https://arxiv.org/abs/1406.2661 • * DCGAN: https://arxiv.org/abs/1511.06434 • * WGAN: https://arxiv.org/abs/1701.07875 • * Pix2Pix: https://arxiv.org/abs/1611.07004 • * CycleGAN: https://arxiv.org/abs/1703.10593 Object detection • * RCNN: https://arxiv.org/abs/1311.2524 • * Fast-RCNN: https://arxiv.org/abs/1504.08083 • * Faster-RCNN: https://arxiv.org/abs/1506.01497 • * SSD: https://arxiv.org/abs/1512.02325 • * YOLO: https://arxiv.org/abs/1506.02640 • * YOLO9000: https://arxiv.org/abs/1612.08242 -
HOW TO START 1. Become on LB: • Get minimal
CV knowledge (1-4 lecture of fast.ai course / cs231 lectures) • Check public kernels/github and understand task and solution pipeline • Complete simple bencmark & Submit prediction (not easy) 2. Improve knowledge and score: • Check solution from previous similar competition • Try to understand it as deep as you can (this is rigth time to finish with fast.ai, read some chapters from DL book, classic articles, etc ) • Improove your current solution • Don‘t forget about kaggle tricks & liks :) -
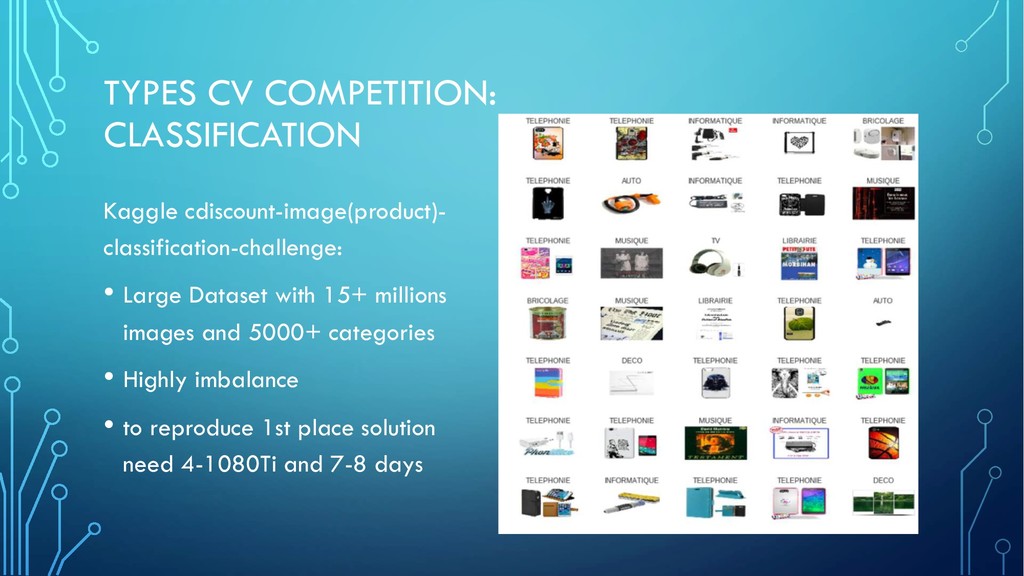
TYPES CV COMPETITION: CLASSIFICATION Kaggle cdiscount-image(product)- classification-challenge: • Large Dataset
with 15+ millions images and 5000+ categories • Highly imbalance • to reproduce 1st place solution need 4-1080Ti and 7-8 days -
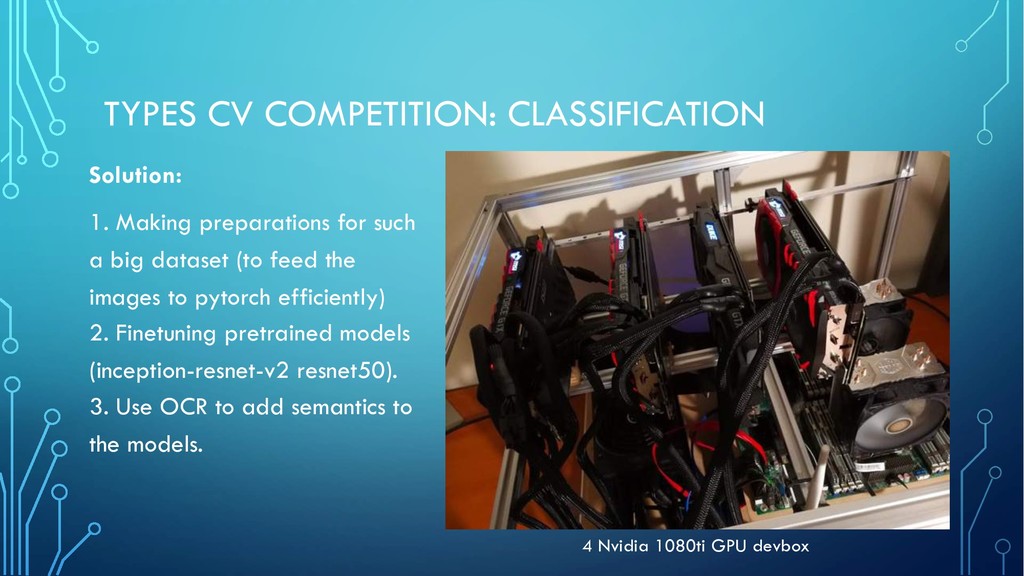
TYPES CV COMPETITION: CLASSIFICATION Solution: 1. Making preparations for such
a big dataset (to feed the images to pytorch efficiently) 2. Finetuning pretrained models (inception-resnet-v2 resnet50). 3. Use OCR to add semantics to the models. 4 Nvidia 1080ti GPU devbox -
CLASSIFICATION TRICKS • Try different achitectures: Resnet-101, Resnet-50, SE-Resnet-50, Resnet-101,
Resnet- 152 • Out of fold prediction (averaging, 2nd layer) • Decrise learning rate for epochs 1..5: lr = 0.001, 6: lr = 0.0001, 7: lr = 0.00001 • Increase batch size for epochs • Test Time Augmentation (5-10 random trasforming + averaging) • Hard negative sampling (rebalance to minimize false detection) • Decrease image size, use random crops + random flips for augmentation • Ensembles: Averaging (arifm, geom), 2nd layer -
ANOTHER APPROACH FOR CLASSIFICATION • initalize a model using pretrained
weights from Imagenet (increase channels from 512 to 5k), there were not frozen layers, the augmentation was disabled. • as soon as the validation score stopped growing, we added augmentation and doubled batch size – score began to grow sharply. But, after a while the growth stopped • repeated this procedure again and again -
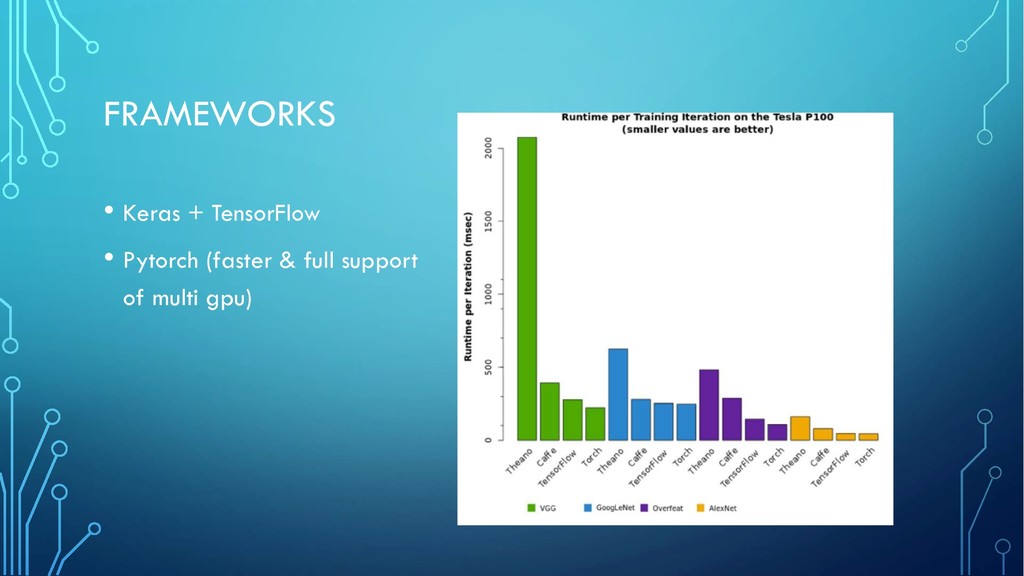
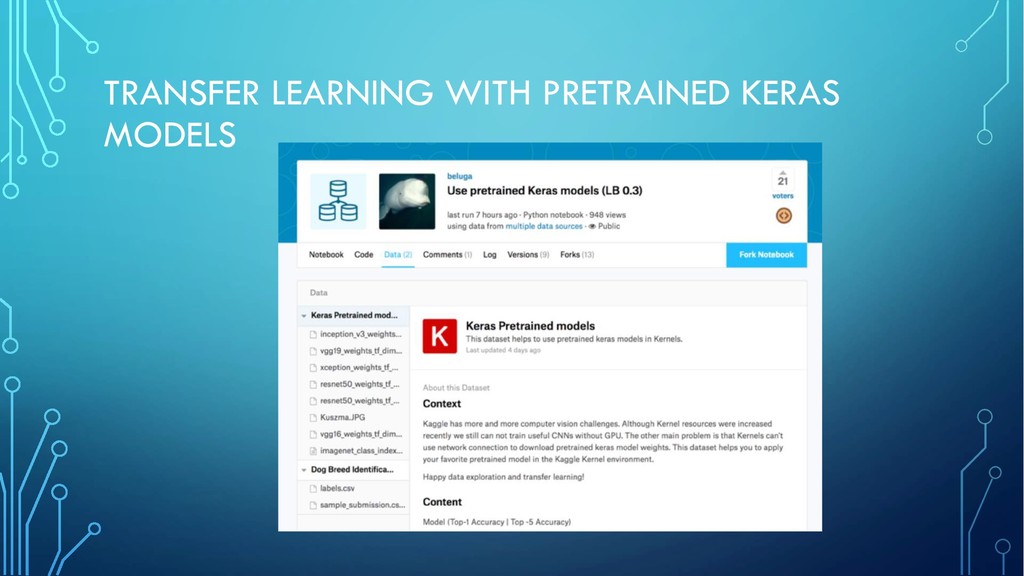
FRAMEWORKS • Keras + TensorFlow • Pytorch (faster & full
support of multi gpu) -
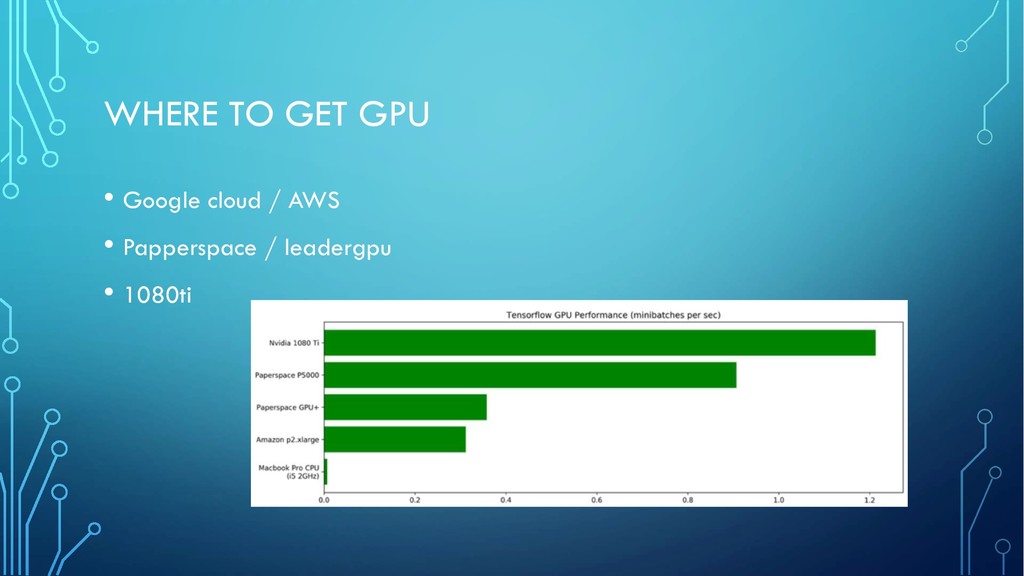
WHERE TO GET GPU • Google cloud / AWS •
Papperspace / leadergpu • 1080ti -
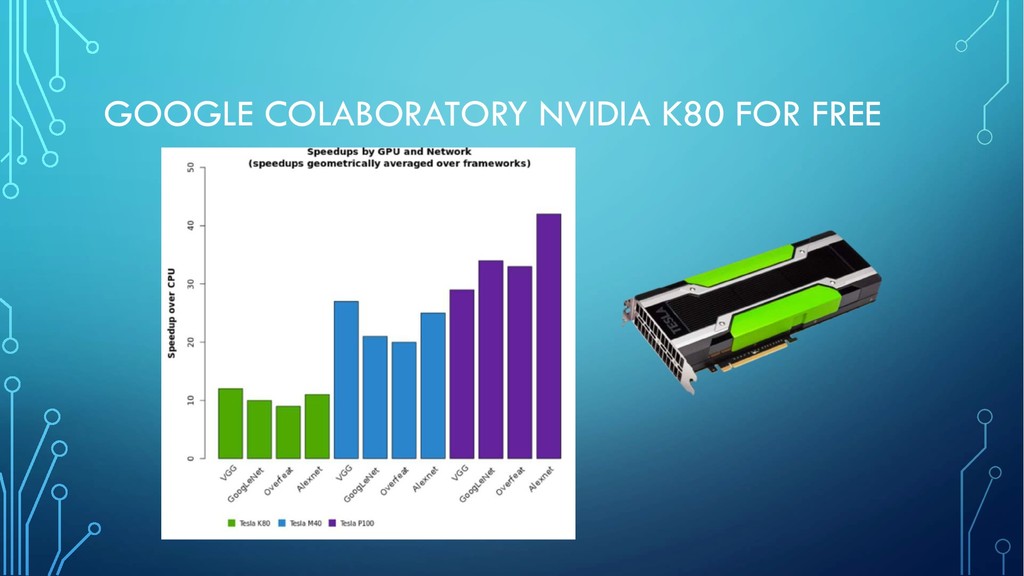
GOOGLE COLABORATORY FEATURES: • Preinstalled TF and Keras • You
need only google account • Easy map google drive • Looks like usual Jupyter notebook (ssh-access also possible) • Submit prediction straight from colaboratory (kaggle-api) • VM creates for 12 hours (use checkpoints to save&load and continue) • Don‘t forget to set GPU in hardware accelerator! -
HOW TO CHOOSE COMPETITION • Data size (what to do
with 300gb data?) • Dates (at least 3 weeks) • Training/money/playground competition -
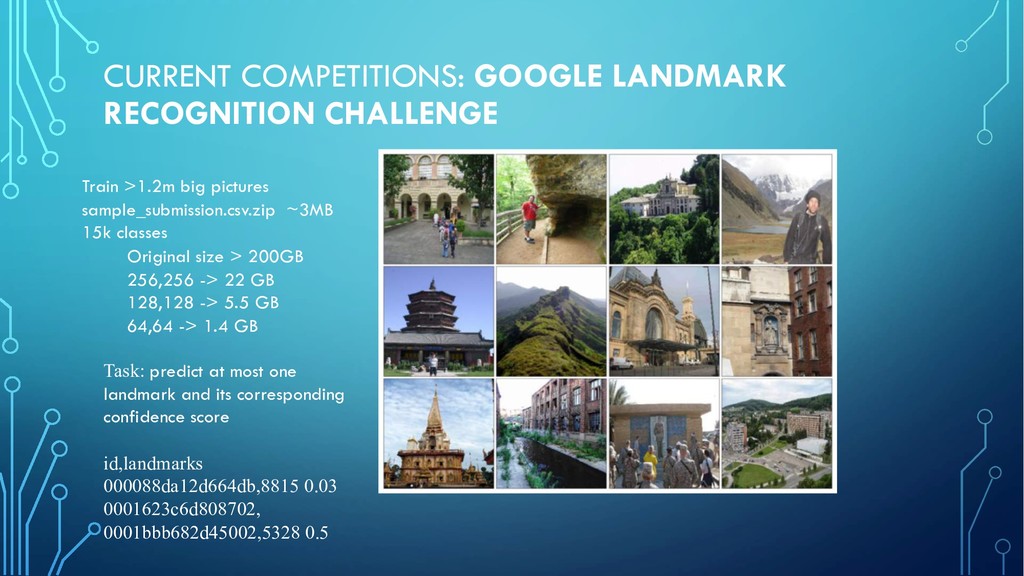
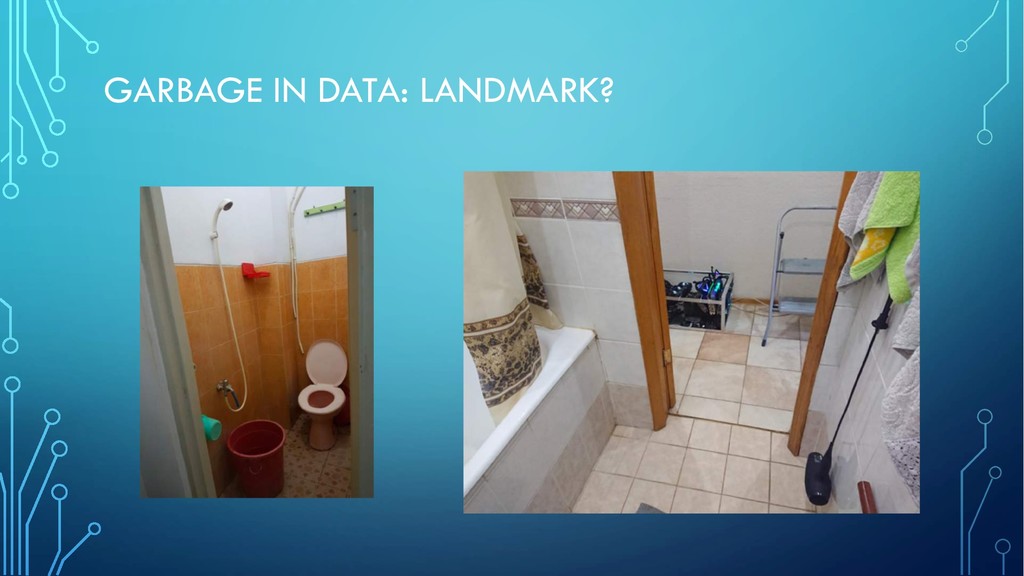
CURRENT COMPETITIONS: GOOGLE LANDMARK RECOGNITION CHALLENGE Original size > 200GB
256,256 -> 22 GB 128,128 -> 5.5 GB 64,64 -> 1.4 GB Train >1.2m big pictures sample_submission.csv.zip ~3MB 15k classes Task: predict at most one landmark and its corresponding confidence score id,landmarks 000088da12d664db,8815 0.03 0001623c6d808702, 0001bbb682d45002,5328 0.5 -
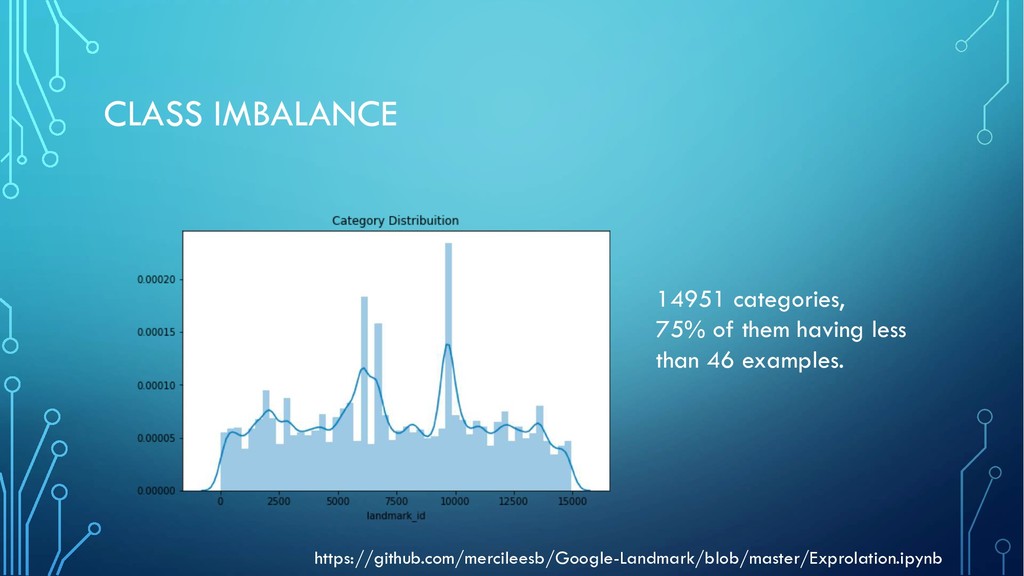
CLASS IMBALANCE 14951 categories, 75% of them having less than
46 examples. https://github.com/mercileesb/Google-Landmark/blob/master/Exprolation.ipynb -
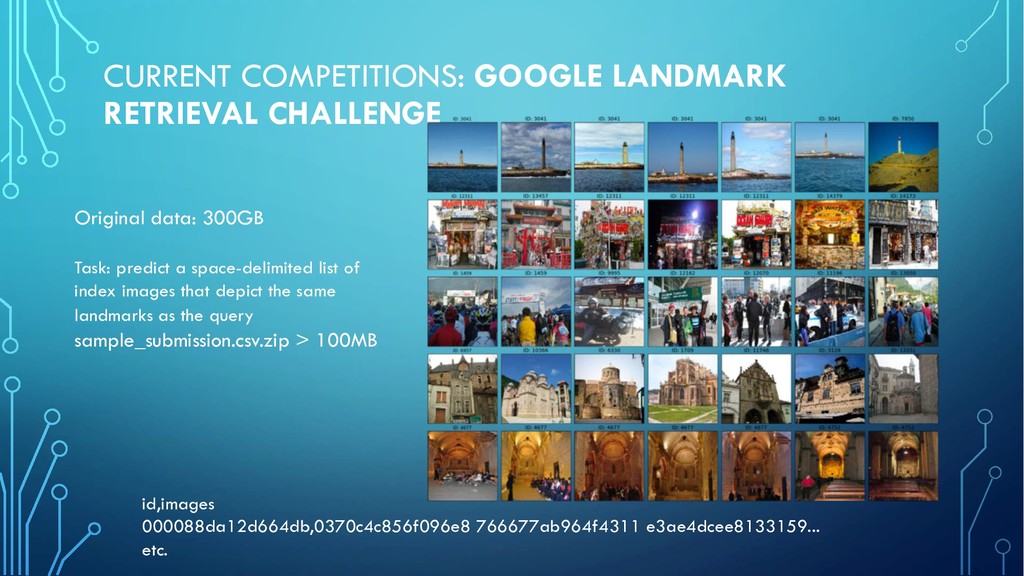
CURRENT COMPETITIONS: GOOGLE LANDMARK RETRIEVAL CHALLENGE id,images 000088da12d664db,0370c4c856f096e8 766677ab964f4311 e3ae4dcee8133159...
etc. Original data: 300GB Task: predict a space-delimited list of index images that depict the same landmarks as the query sample_submission.csv.zip > 100MB -
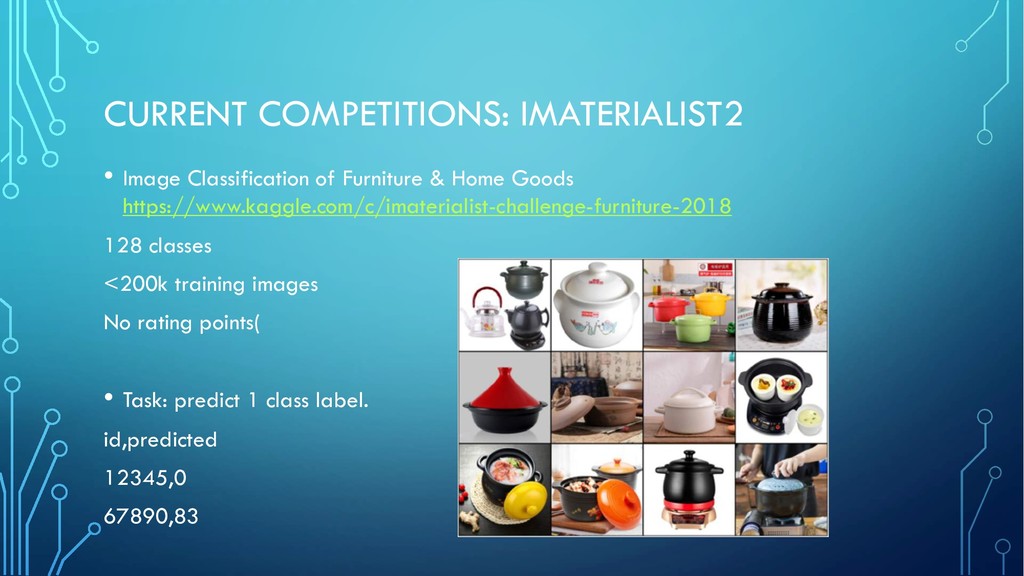
CURRENT COMPETITIONS: IMATERIALIST2 • Image Classification of Furniture & Home
Goods https://www.kaggle.com/c/imaterialist-challenge-furniture-2018 128 classes <200k training images No rating points( • Task: predict 1 class label. id,predicted 12345,0 67890,83 -
PIPELINE: • Download data (downsize) • Understand data structure •
Do exploritary analysis • Create simple model • Submit prediction -
WHAT TO TRY NOW • https://www.kaggle.com/c/whale-categorization-playground#description • Understand the task
• Try kernels • Try google colab • Try TTA • Try finetune pretrained model -
USEFULL LINKS • http://www.fast.ai/ • http://www.deeplearningbook.org/ • Cs231n Convolutional Neural
Networks for Visual Recognition - Stanford by Fei-Fei Li, Andrej Karpathy http://vision.stanford.edu/teaching/cs231n/syllabus.html • Colab tutorial&mout Google Drive: https://medium.com/deep-learning-turkey/google-colab-free-gpu-tutorial-e113627b9f5d • Use Tensor Board in Colab: https://stackoverflow.com/a/48468512/1334157 • List of competitions to join (not only kaggle) https://github.com/iphysresearch/DataSciComp#active-competitons-to-join • Using Transfer Learning with Pre-Trained Keras Models to Distinguish Dog Breeds https://www.kaggle.com/gaborfodor/dog-breed-pretrained-keras-models-lb-0-3