Share
Embed
Keep calm and carry on: scaling your org with microservices
from ddd exchange in london, april 2018
Charity Majors
April 27, 2018
Transcript
88 slides
-
Keep Calm and Carry On: Scaling Your Org With Microservices
Charity Majors, @mipsytipsy -
Keep Calm and Carry On: Scaling Your Org With Microservices
Charity Majors, @mipsytipsy -
What are microservices? • Monorepo — sometimes • Independently deployable,
small modular services • Decentralized governance • Small teams, up to maybe a dozen people • Operating independently, interacting with other teams via APIs -
Naming a thing has power convention design patterns community best
practices vetted in multiple environments “hey, haven’t we been doing this forever?” -
Many catastrophic states exist at any given time. Your system
is never entirely ‘up’ -
You need: a new mindset new habits new tools a
sense of humor forgiveness :) remember … you are still an early adopter! -
You need: a new mindset new habits new tools a
sense of humor forgiveness :) remember … you are still an early adopter! -
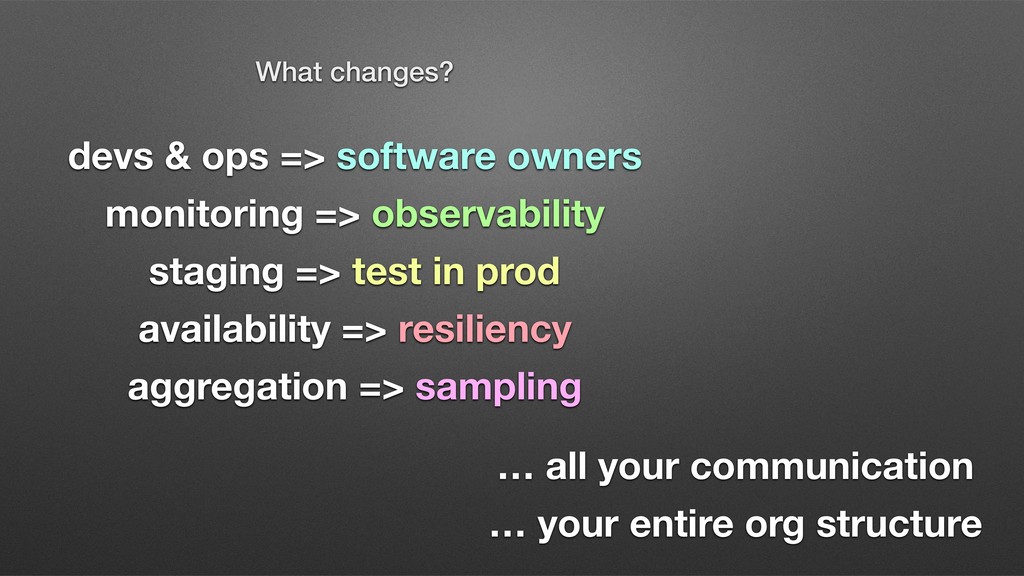
devs & ops => software owners monitoring => observability staging
=> test in prod availability => resiliency aggregation => sampling … all your communication … your entire org structure What changes? -
Software needs owners. Not operators, not developers Owners have impact
on the full lifecycle of their software: build, fix, listen, patch, commit, deploy, revert, rollback, instrument, understand, anticipate, verify, validate. devs & ops => software owners -
The most powerful weapon in your arsenal is always cause
and effect. Engineers should be on call for their own services. -
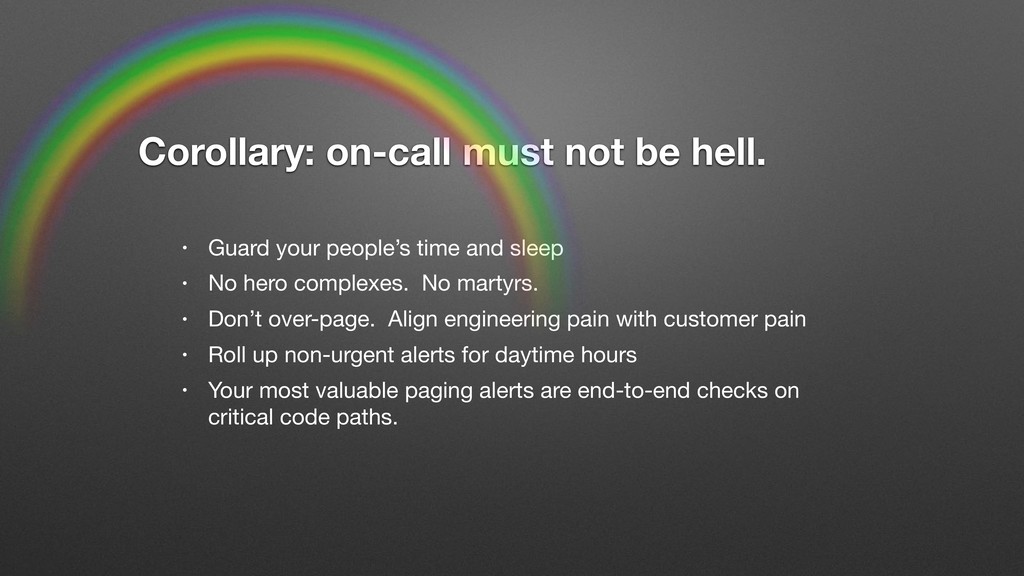
• Guard your people’s time and sleep • No hero
complexes. No martyrs. • Don’t over-page. Align engineering pain with customer pain • Roll up non-urgent alerts for daytime hours • Your most valuable paging alerts are end-to-end checks on critical code paths. Corollary: on-call must not be hell. -
Probe every software engineering candidate for their ops experience &
attitude. … yep, even FE/mobile devs! -
Senior software engineers should be reasonably good at these things.
So if they are not, don’t promote them. Operations engineering is about making systems maintainable, reliable, and comprehensible. -
Distributed systems are particularly hostile to being cloned or imitated.
(clients, concurrency, chaotic traffic patterns, edge cases …) These systems have an infinitely long list of almost-impossible failure scenarios that make staging copies particularly worthless. this is a black hole for engineering time -
unit tests integration tests functional tests basic failover test before
prod: … the basics. the simple stuff. -
behavioral tests experiments load tests (!!) edge cases canaries rolling
deploys multi-region test in prod: … where shit gets real. -
That energy is better used elsewhere: Production. You can catch
80% of the bugs with 20% of the effort. And you should. @caitie’s PWL talk: https://youtu.be/-3tw2MYYT0Q -
feature flags (launch darkly high cardinality tooling (honeycomb) gate your
releases () canaries, shadow systems (goturbine, linkerd) capture/replay for databases (apiary, percona) also build or use: jk dont build your own -
Failure is not rare Practice shipping and fixing lots of
small problems And practice on your users!! -
Does everyone … know what normal looks like? know how
to deploy? know how to roll back? know how to canary? know how to debug in production? Practice!!~ -
1. Canarying. Automated canarying. Promotion of canaries. 2. Making deploys
more automated and robust 3. Making the fastest path the correctest/safest path 4. Limiting the critical path. Limiting the blast radius. 5. Shipping features behind feature flags 6. Making rollbacks just another boring deploy 7. Instrumentation. Good defaults. Test on employees. Your allies: These are *always* a good use of your time. (Staging is *sometimes* a good use of your time) -
Why do people sink so much time into staging, when
they can’t even tell if their own production environment is healthy or not? -
You have an observable system when your team can quickly
and reliably track down any new problem in real time.. monitoring => observability -
Observability “In control theory, observability is a measure of how
well internal states of a system can be inferred from knowledge of its external outputs. The observability and controllability of a system are mathematical duals." — wikipedia … translate??!? -
Observability Can you understand what’s happening inside your code and
systems, simply by asking questions using your tools? Can you answer any new question you think of, or only the ones you prepared for? Having to ship new code every time you want to ask a new question … SUCKS. -
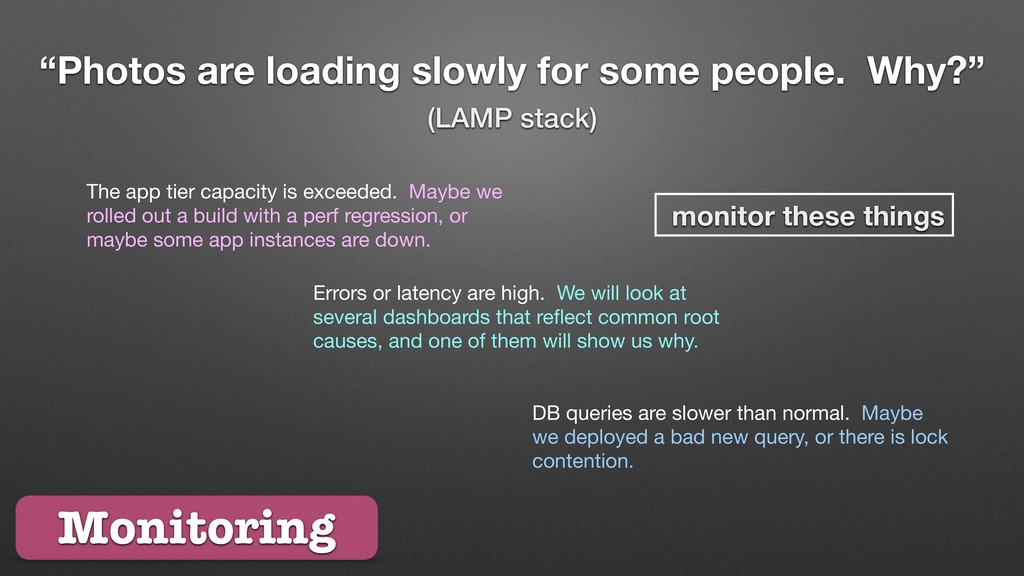
The app tier capacity is exceeded. Maybe we rolled out
a build with a perf regression, or maybe some app instances are down. DB queries are slower than normal. Maybe we deployed a bad new query, or there is lock contention. Errors or latency are high. We will look at several dashboards that reflect common root causes, and one of them will show us why. “Photos are loading slowly for some people. Why?” Monitoring (LAMP stack) monitor these things -
Characteristics Monitoring • Known-unknowns predominate • Intuition-friendly • Dashboards are
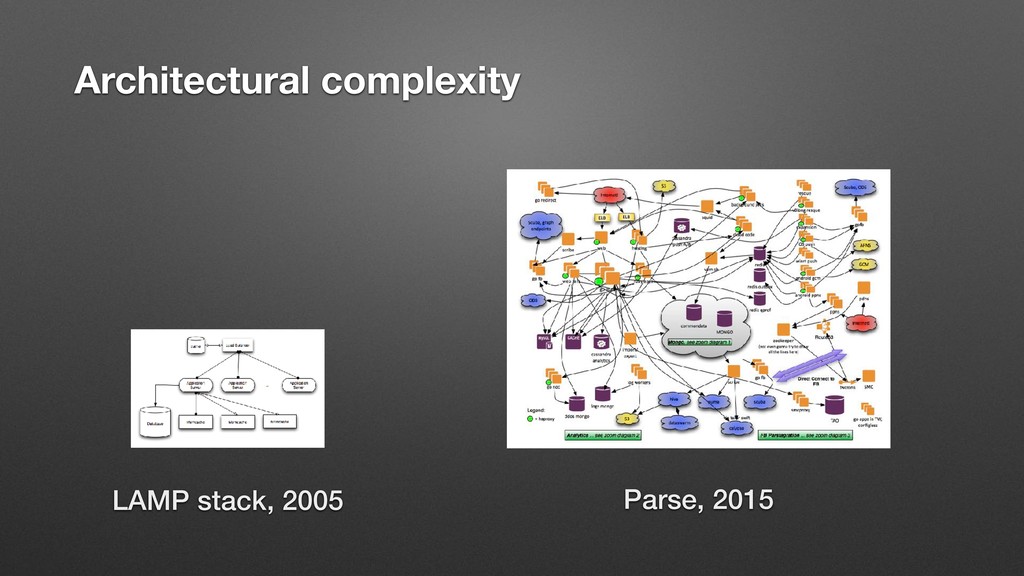
valuable. • Monolithic app, single data source. • The health of the system more or less accurately represents the experience of the individual users. (LAMP stack) -
Best Practices Monitoring • Lots of actionable active checks and
alerts • Proactively notify engineers of failures and warnings • Maintain a runbook for stable production systems • Rely on clusters and clumps of tightly coupled systems all breaking at once -
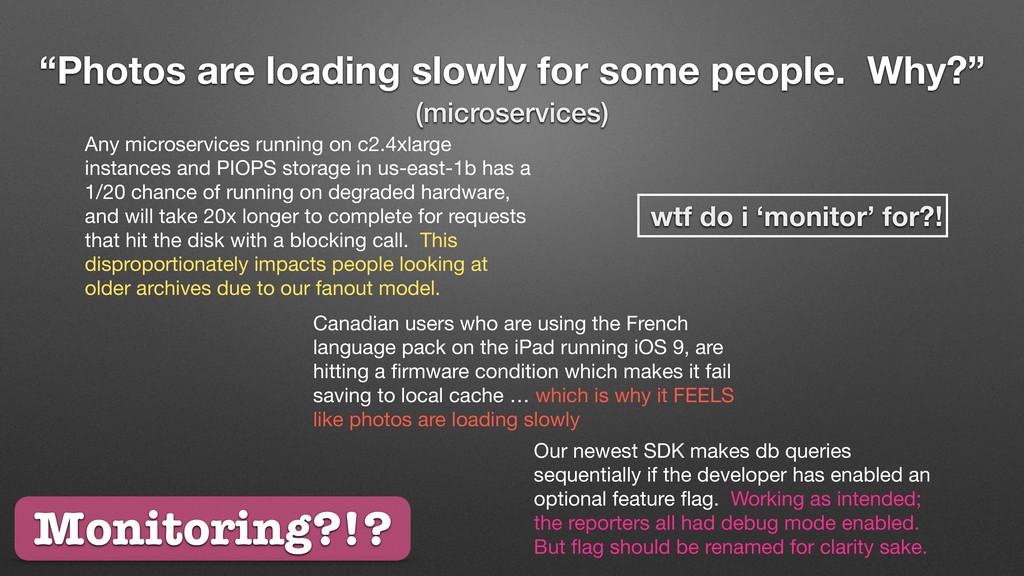
“Photos are loading slowly for some people. Why?” (microservices) Any
microservices running on c2.4xlarge instances and PIOPS storage in us-east-1b has a 1/20 chance of running on degraded hardware, and will take 20x longer to complete for requests that hit the disk with a blocking call. This disproportionately impacts people looking at older archives due to our fanout model. Canadian users who are using the French language pack on the iPad running iOS 9, are hitting a firmware condition which makes it fail saving to local cache … which is why it FEELS like photos are loading slowly Our newest SDK makes db queries sequentially if the developer has enabled an optional feature flag. Working as intended; the reporters all had debug mode enabled. But flag should be renamed for clarity sake. wtf do i ‘monitor’ for?! Monitoring?!? -
These are all unknown-unknowns that may have never happened before,
or ever happen again (They are also the overwhelming majority of what you have to care about for the rest of your life.) -
Characteristics • Unknown-unknowns are most of the problems • “Many”
components and storage systems • You cannot model the entire system in your head. Dashboards may be actively misleading. • The hardest problem is often identifying which component(s) to debug or trace. • The health of the system is irrelevant. The health of each individual request is of supreme consequence. (microservices/complex systems) Observability -
Best Practices • Rich instrumentation. • Events, not metrics. •
Sampling, not write-time aggregation. • Few (if any) dashboards. • Test in production.. a lot. • Very few paging alerts. Observability (microservices/complex systems) -
Why: Instrumentation? Events, not metrics? No dashboards? Sampling, not time
series aggregation? Test in production? Fewer alerts? -
8 commandments for a Glorious Future™ well-instrumented high cardinality high
dimensionality event-driven structured well-owned sampled tested in prod. -
Instrumentation? Start at the edge and work down Internal state
from software you didn’t write, too Wrap every network call, every data call Structured data only `gem install` magic will only get you so far -
Events, not metrics? (trick question.. you’ll need both but you’ll
rely on events more and more) Cardinality Context Structured data -
UUIDs db raw queries normalized queries comments firstname, lastname PID/PPID
app ID device ID HTTP header type build ID IP:port shopping cart ID userid ... etc Some of these … might be … useful … YA THINK??! High cardinality will save your ass. Metrics (cardinality) -
You must be able to break down by 1/millions and
THEN by anything/everything else High cardinality is not a nice-to-have ‘Platform problems’ are now everybody’s problems -
Events tell stories. Arbitrarily wide events mean you can amass
more and more context over time. Use sampling to control costs and bandwidth. Structure your data at the source to reap massive efficiencies over strings. Events (“Logs” are just a transport mechanism for events) -
Aggregation is a one-way trip Destroying raw events eliminates your
ability to ask new questions. Forever. Aggregates are the devil -
Aggregates destroy your precious details. You need MORE detail and
MORE context. Aggregates -
availability => resiliency Shrink the critical path Automatedly remediate Invest
in canaries Build exploratory, open-ended introspection Observability > * -
Software needs owners. Not operators, not developers Owners have impact
on the full lifecycle of their software: build, fix, listen, patch, commit, deploy, revert, rollback, instrument, understand, anticipate, verify, validate. aggregation => sampling -
… all your communication @mranney, Uber “With microservices, you cleverly
swap out your technical problems for political problems.” -
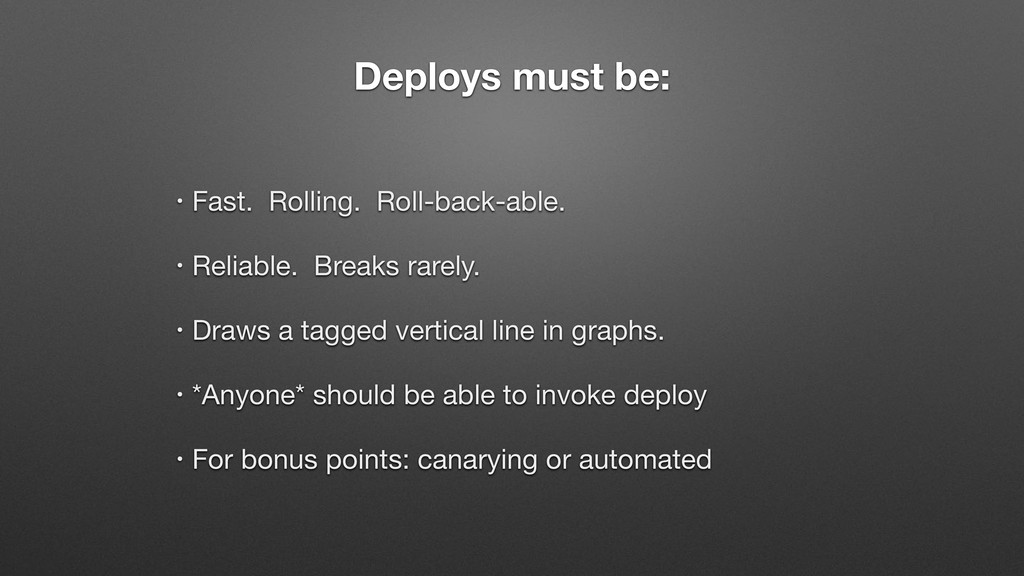
Deploys must be: • Fast. Rolling. Roll-back-able. • Reliable. Breaks
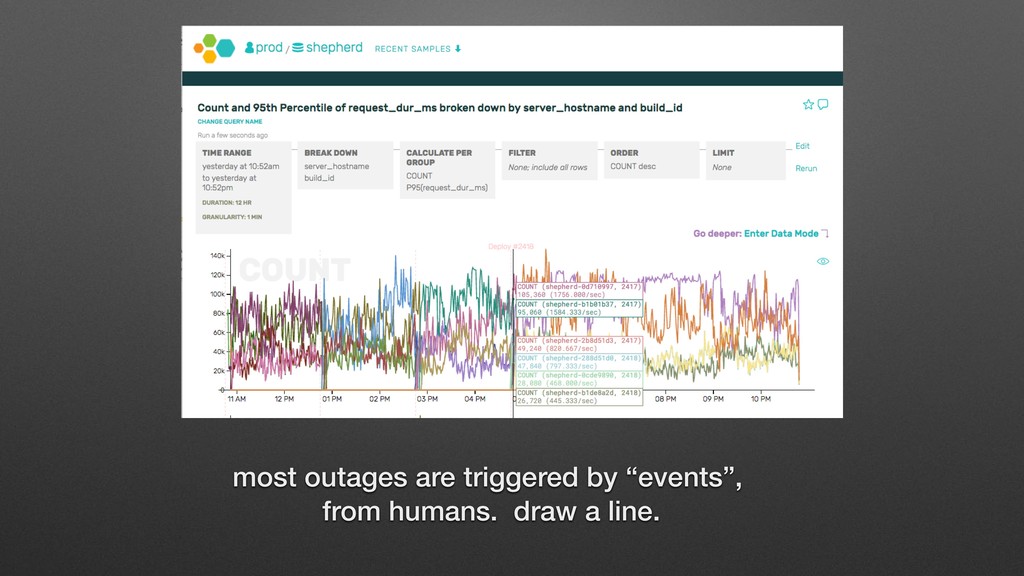
rarely. • Draws a tagged vertical line in graphs. • *Anyone* should be able to invoke deploy • For bonus points: canarying or automated -
… your entire org structure @mranney, Uber “With microservices, you
cleverly swap out your technical problems for political problems.” -
Choose the problems you are not going to solve, or
they will choose you. -
Yes but …. Yes, microservices helps you drift a little
bit and innovate independently … BUT, not as much as you might think. You all still share a fabric, after all. Stateful still gonna ruin your party. (and IPC, sec discovery, caching, cd pipelines, databases etc.) -
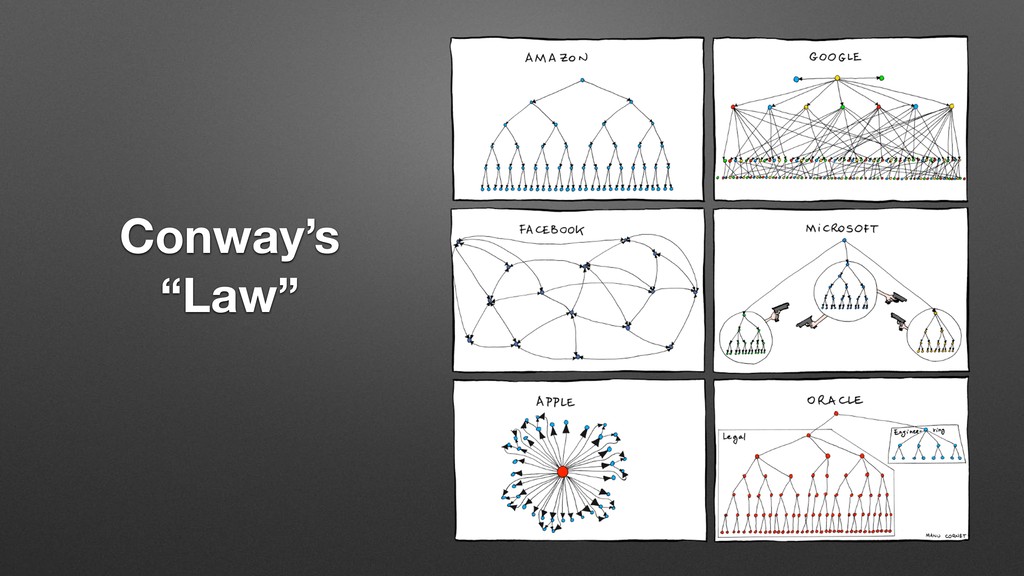
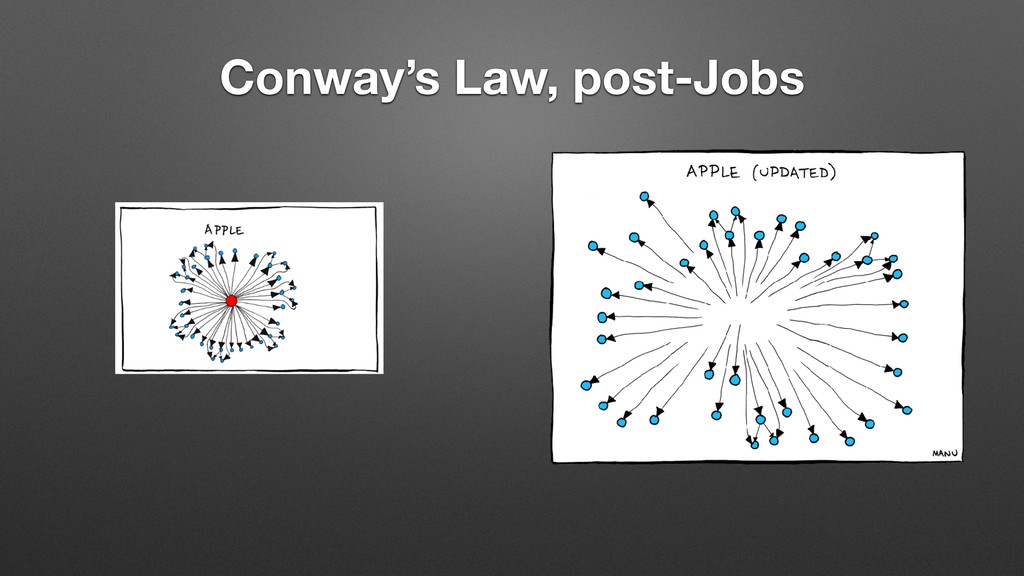
References: Conway’s Law Swap tech problems for political Multiple repos
http://blog.christianposta.com/microservices/youre-not-going-to-do-microservices/ Terrific talks by @aspyker, @adrianco, @samnewman, @martinfowler, @mattranney, etc: https://medium.facilelogin.com/ten-talks-on-microservices-you-cannot-miss-at-any- cost-7bbe5ab7f43f#.qqzeqpw2l https://www.infoq.com/presentations/7-sins-microservices