Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Apache Cassandra for Big Data Applications

Apache Cassandra for Big Data Applications

This is an introduction to Cassandra that I gave at Jazoon 2012 in Zurich, Switzerland in June 2012.

Christof Roduner
June 28, 2012

Transcript

45 slides
  1. Apache Cassandra for Big Data Applications @scandit www.scandit.com Jazoon 2012
    June 27, 2012 Christof Roduner Scandit co-founder and COO [email protected] | @lomumol
  2. 4 AGENDA  Cassandra origins and use  How we

    use Cassandra  Data model  Cluster organization  Replication  Consistency  Query Language CQL  Practical experience
  3. 7 SCANDIT Scandit provides developers with tools to build, analyze

    and monetize product-centric apps. http://www.scandit.com/video
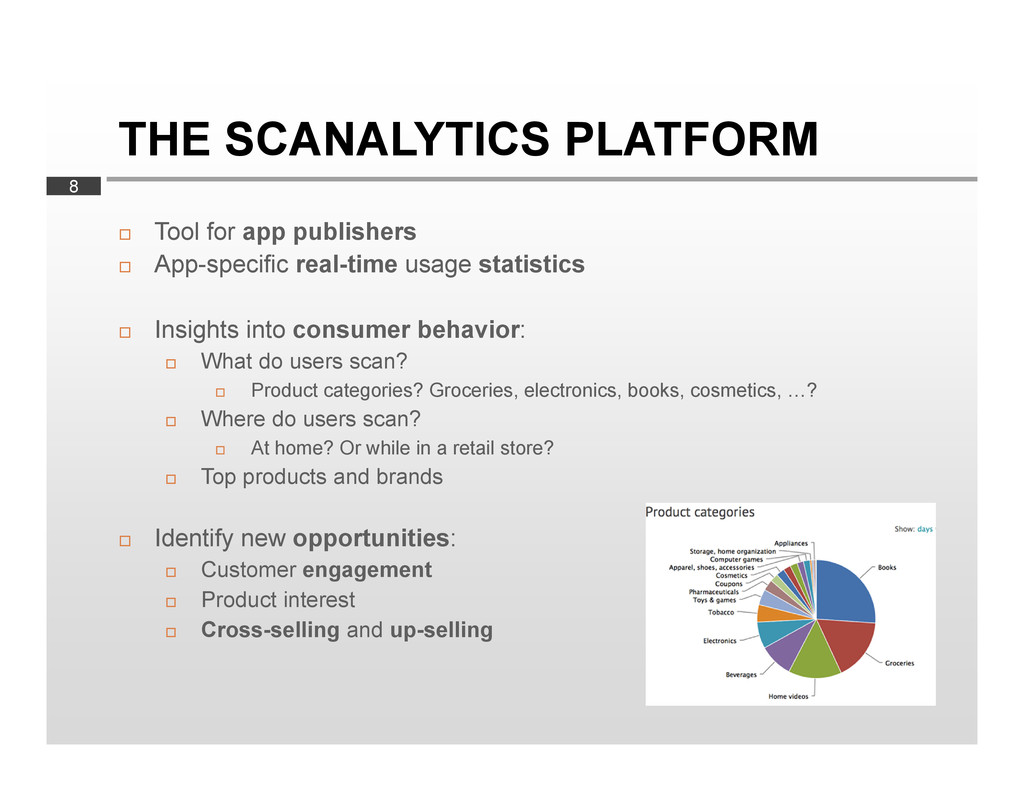
  4. 8 THE SCANALYTICS PLATFORM  Tool for app publishers 

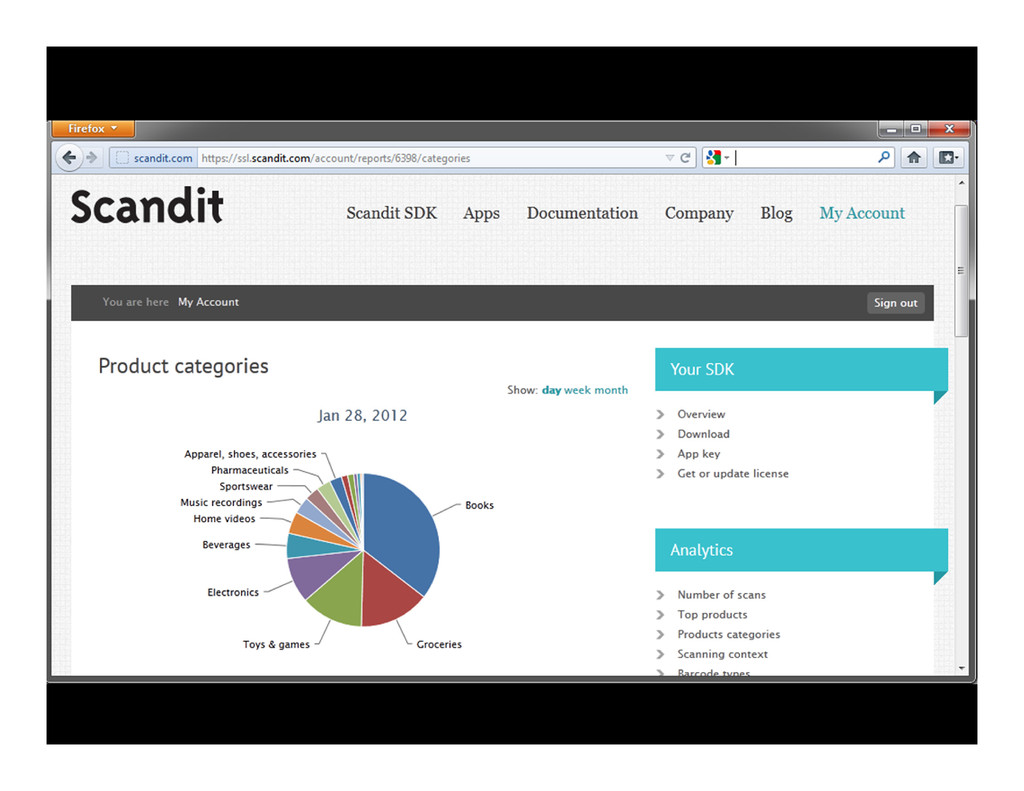
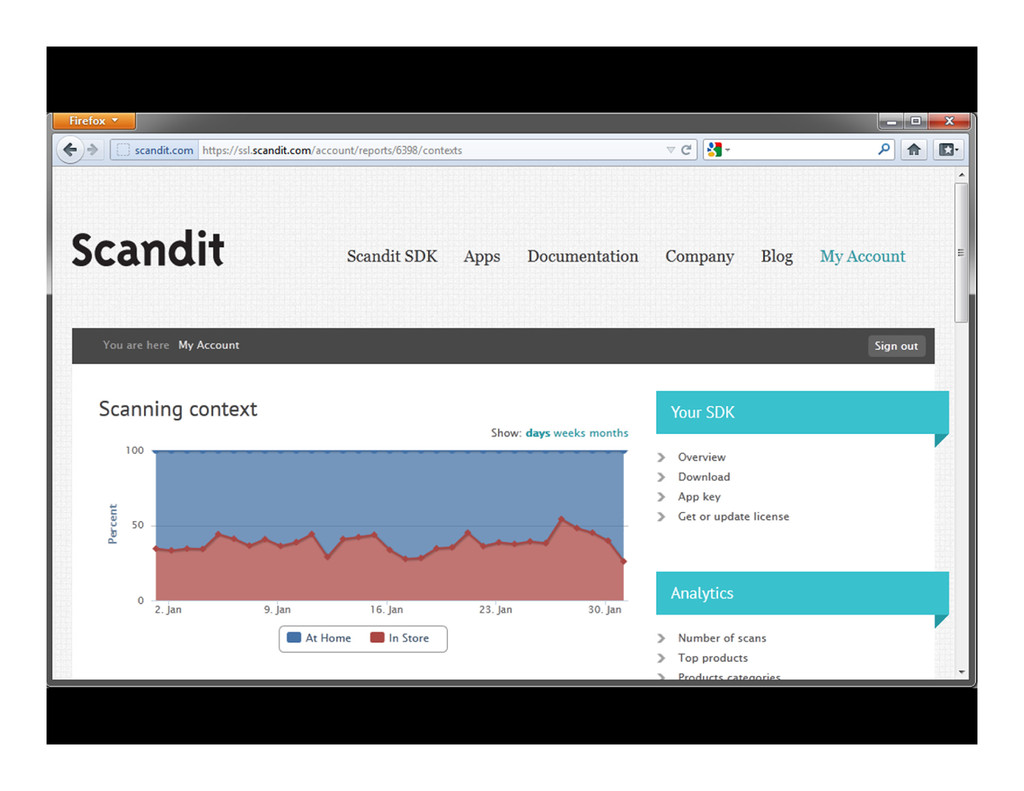
    App-specific real-time usage statistics  Insights into consumer behavior:  What do users scan?  Product categories? Groceries, electronics, books, cosmetics, …?  Where do users scan?  At home? Or while in a retail store?  Top products and brands  Identify new opportunities:  Customer engagement  Product interest  Cross-selling and up-selling
  5. 11 BACKEND REQUIREMENTS  Product database  Many millions of

    products  Many different data sources  Curation of product data (filtering, etc.)  Analysis of scans  Accept and store high volumes of scans  Generate statistics over extended time periods  Correlate with product data  Provide reports to developers
  6. 12 BACKEND DESIGN GOALS  Scalability  High-volume storage 

    High-volume throughput  Support large number of concurrent client requests (app)  Availability  Low maintenance  Even as our user base grows  Multiple data centers
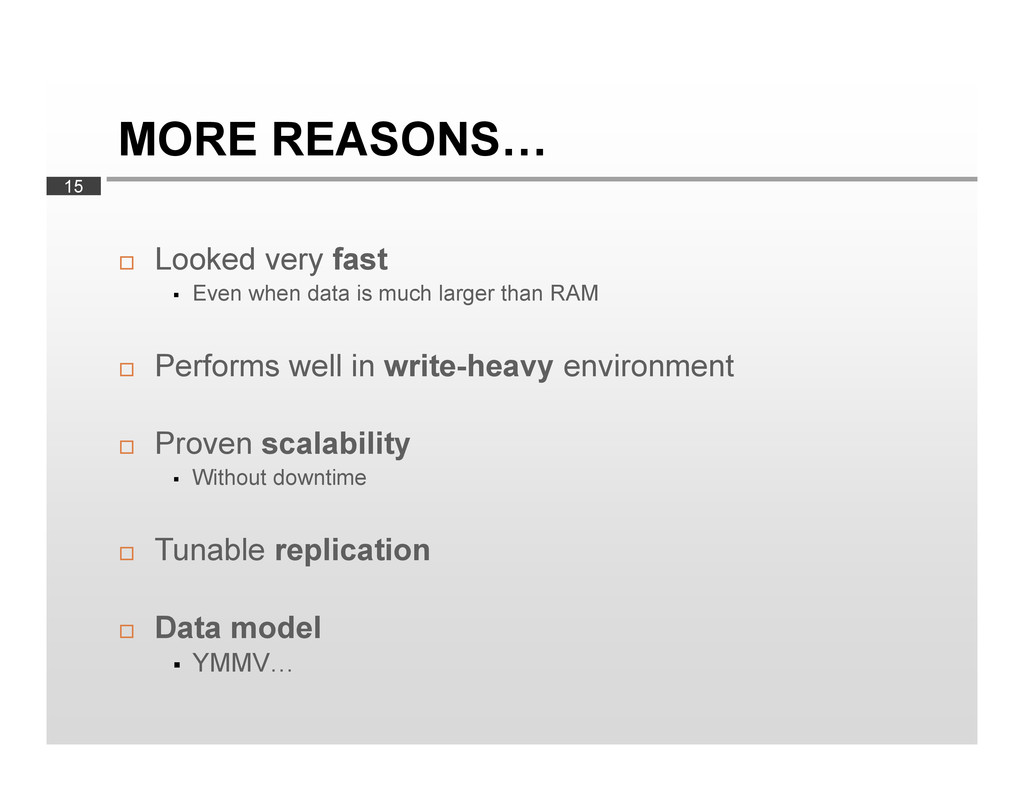
  7. 15 MORE REASONS…  Looked very fast  Even when

    data is much larger than RAM  Performs well in write-heavy environment  Proven scalability  Without downtime  Tunable replication  Data model  YMMV…
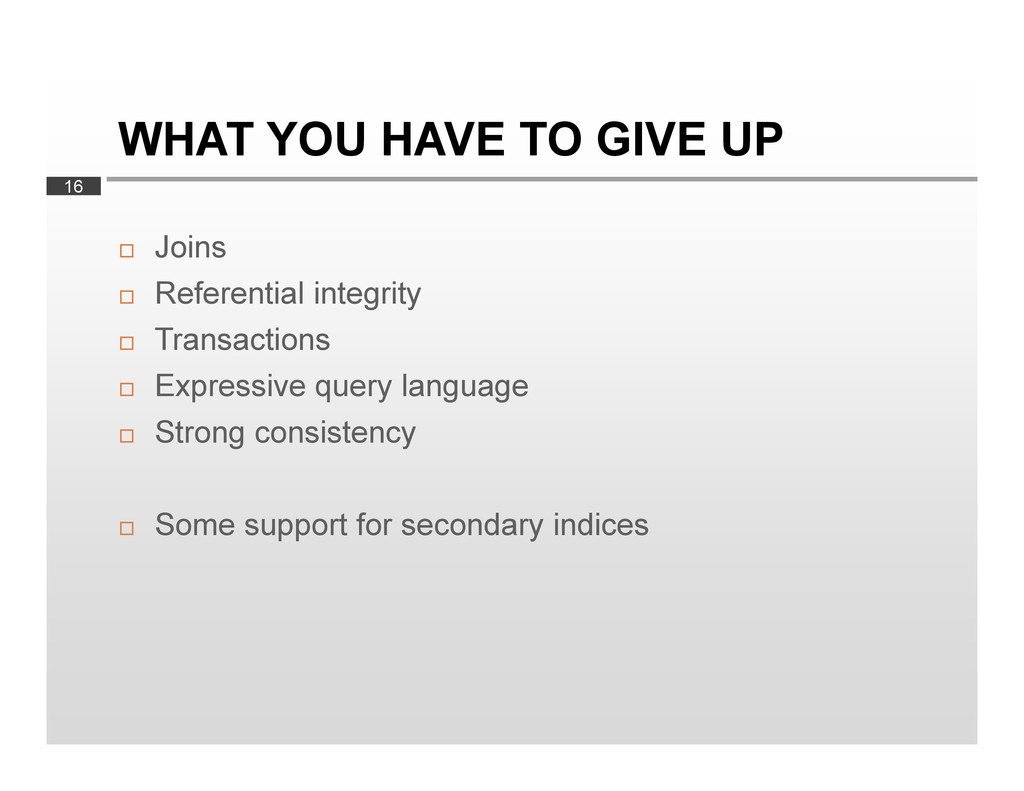
  8. 16 WHAT YOU HAVE TO GIVE UP  Joins 

    Referential integrity  Transactions  Expressive query language  Strong consistency  Some support for secondary indices
  9. 17 CASSANDRA DATA MODEL  Column families  Rows 

    Columns  (Supercolumns)  Deprecated, so we’ll skip them…
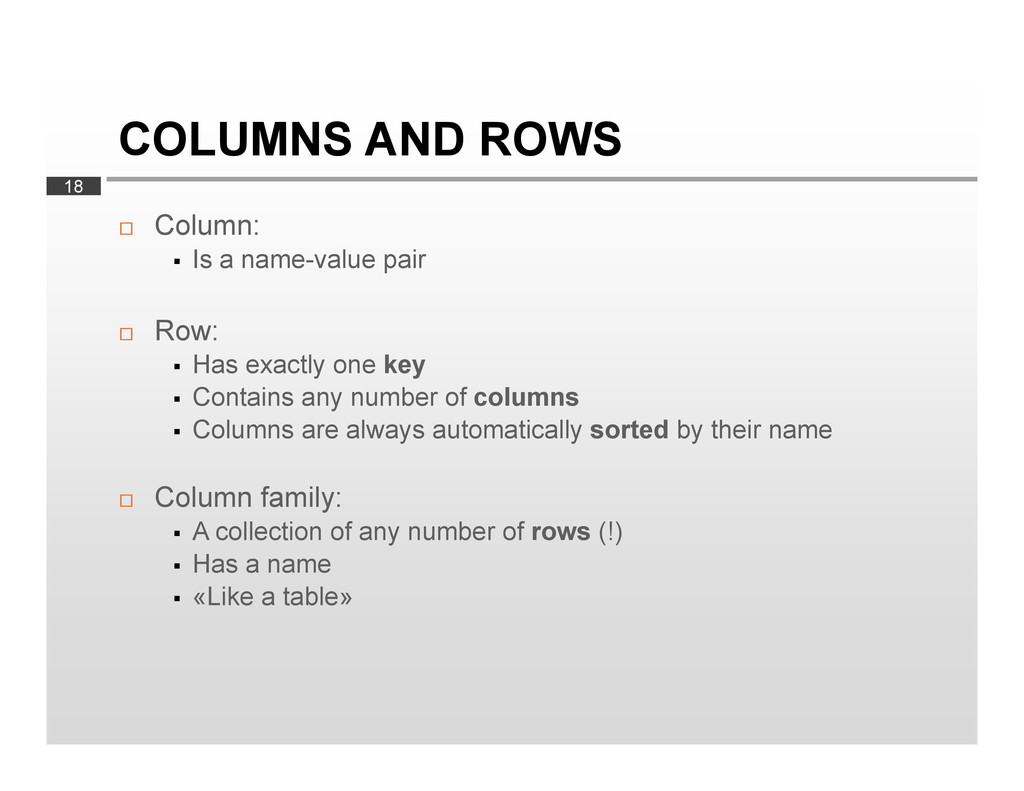
  10. 18 COLUMNS AND ROWS  Column:  Is a name-value

    pair  Row:  Has exactly one key  Contains any number of columns  Columns are always automatically sorted by their name  Column family:  A collection of any number of rows (!)  Has a name  «Like a table»
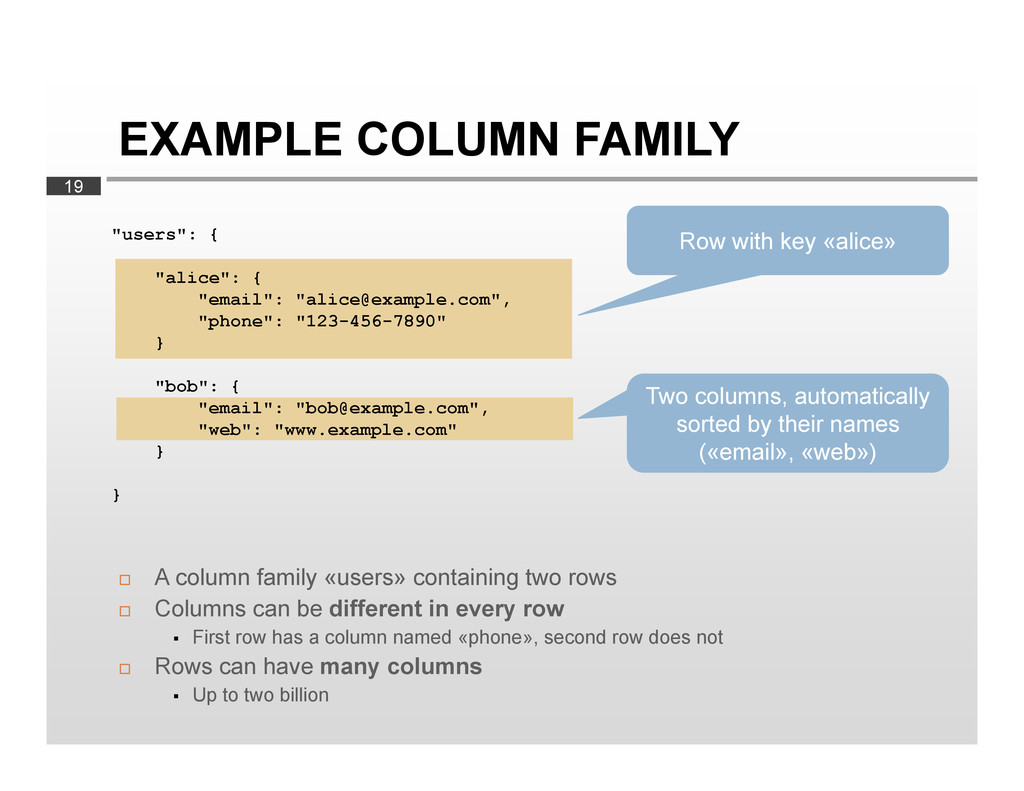
  11. 19 EXAMPLE COLUMN FAMILY  A column family «users» containing

    two rows  Columns can be different in every row  First row has a column named «phone», second row does not  Rows can have many columns  Up to two billion "users": { "alice": { "email": "[email protected]", "phone": "123-456-7890" } "bob": { "email": "[email protected]", "web": "www.example.com" } } Row with key «alice» Two columns, automatically sorted by their names («email», «web»)
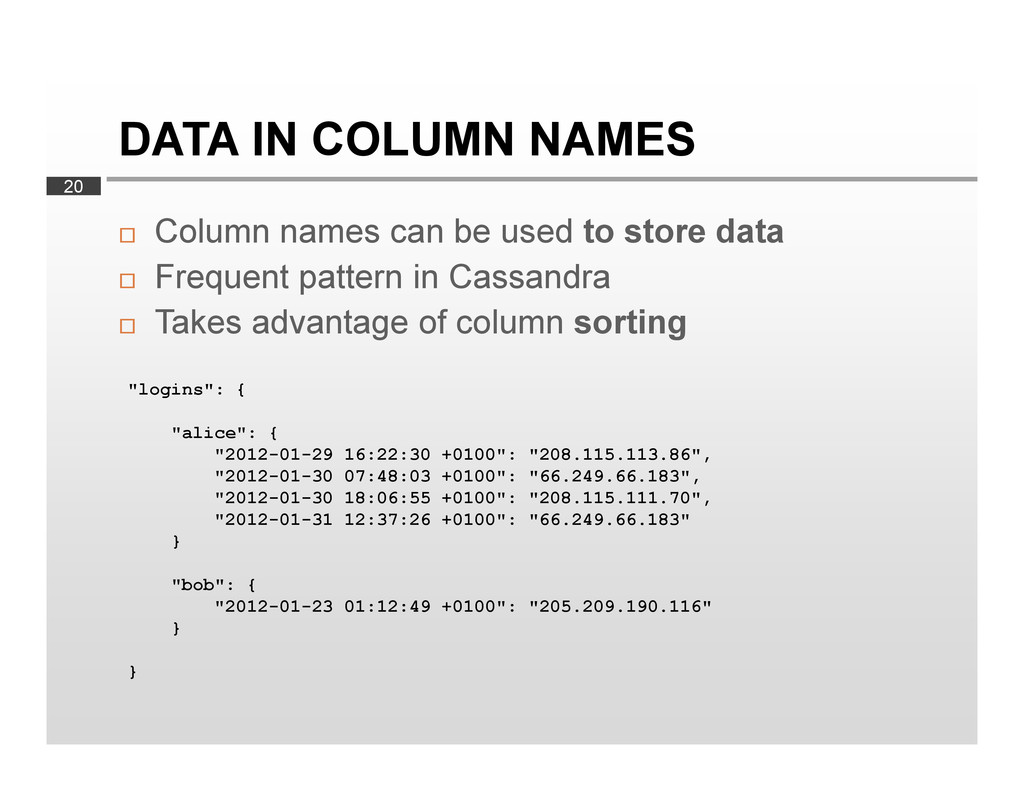
  12. 20 DATA IN COLUMN NAMES  Column names can be

    used to store data  Frequent pattern in Cassandra  Takes advantage of column sorting "logins": { "alice": { "2012-01-29 16:22:30 +0100": "208.115.113.86", "2012-01-30 07:48:03 +0100": "66.249.66.183", "2012-01-30 18:06:55 +0100": "208.115.111.70", "2012-01-31 12:37:26 +0100": "66.249.66.183" } "bob": { "2012-01-23 01:12:49 +0100": "205.209.190.116" } }
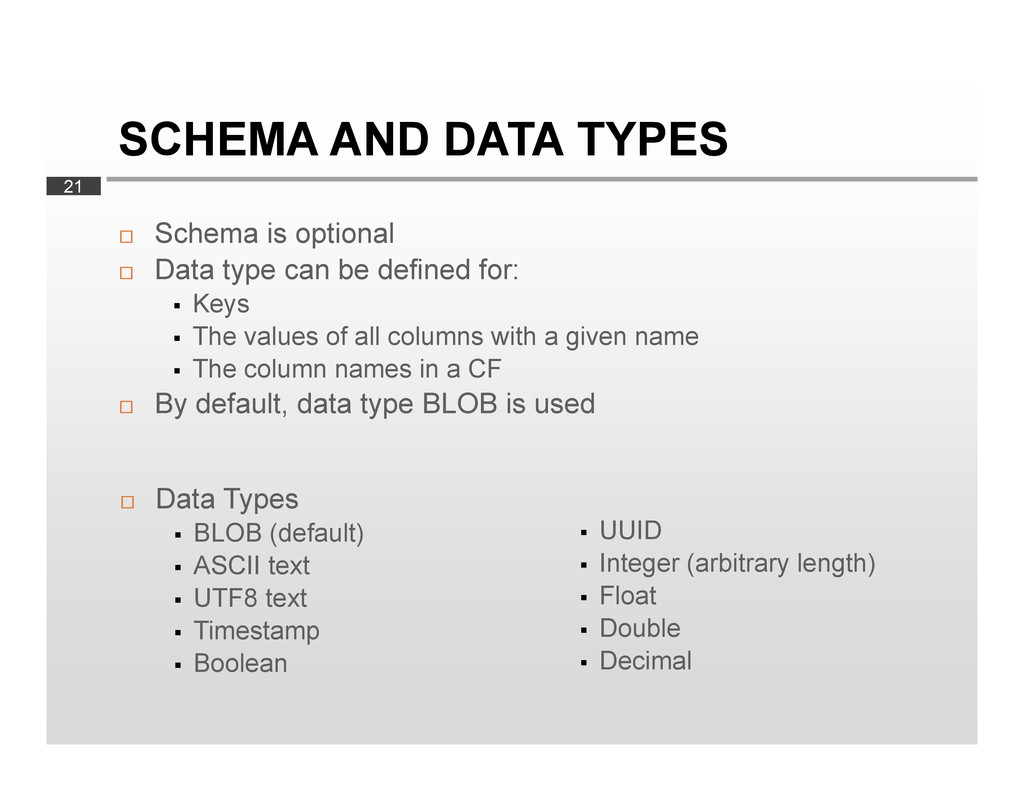
  13. 21 SCHEMA AND DATA TYPES  Schema is optional 

    Data type can be defined for:  Keys  The values of all columns with a given name  The column names in a CF  By default, data type BLOB is used  Data Types  BLOB (default)  ASCII text  UTF8 text  Timestamp  Boolean  UUID  Integer (arbitrary length)  Float  Double  Decimal
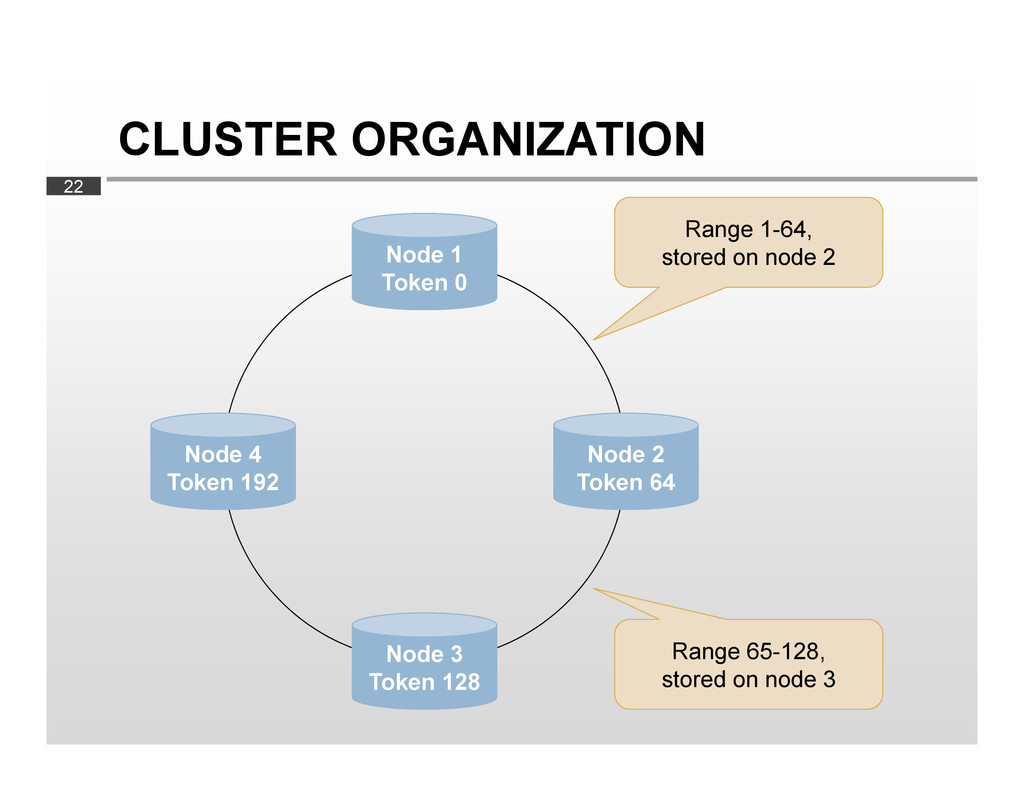
  14. 22 CLUSTER ORGANIZATION Node 3 Token 128 Node 2 Token

    64 Node 4 Token 192 Node 1 Token 0 Range 1-64, stored on node 2 Range 65-128, stored on node 3
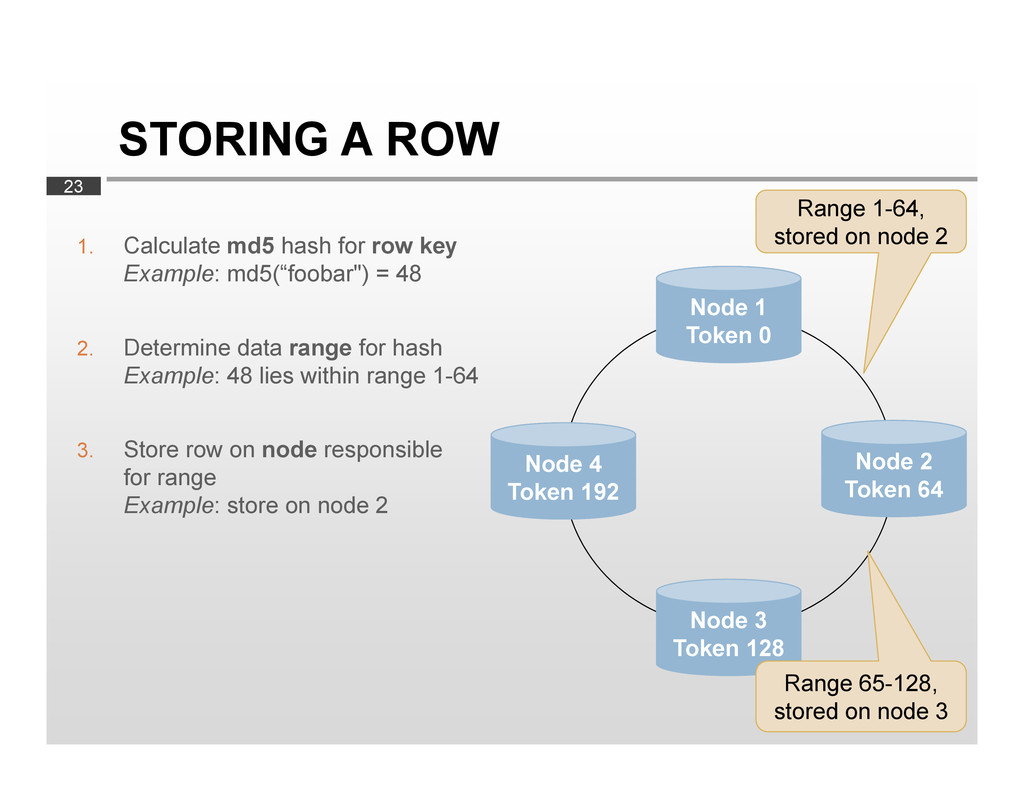
  15. 23 STORING A ROW 1. Calculate md5 hash for row

    key Example: md5(“foobar") = 48 2. Determine data range for hash Example: 48 lies within range 1-64 3. Store row on node responsible for range Example: store on node 2 Node 3 Token 128 Node 2 Token 64 Node 4 Token 192 Node 1 Token 0 Range 1-64, stored on node 2 Range 65-128, stored on node 3
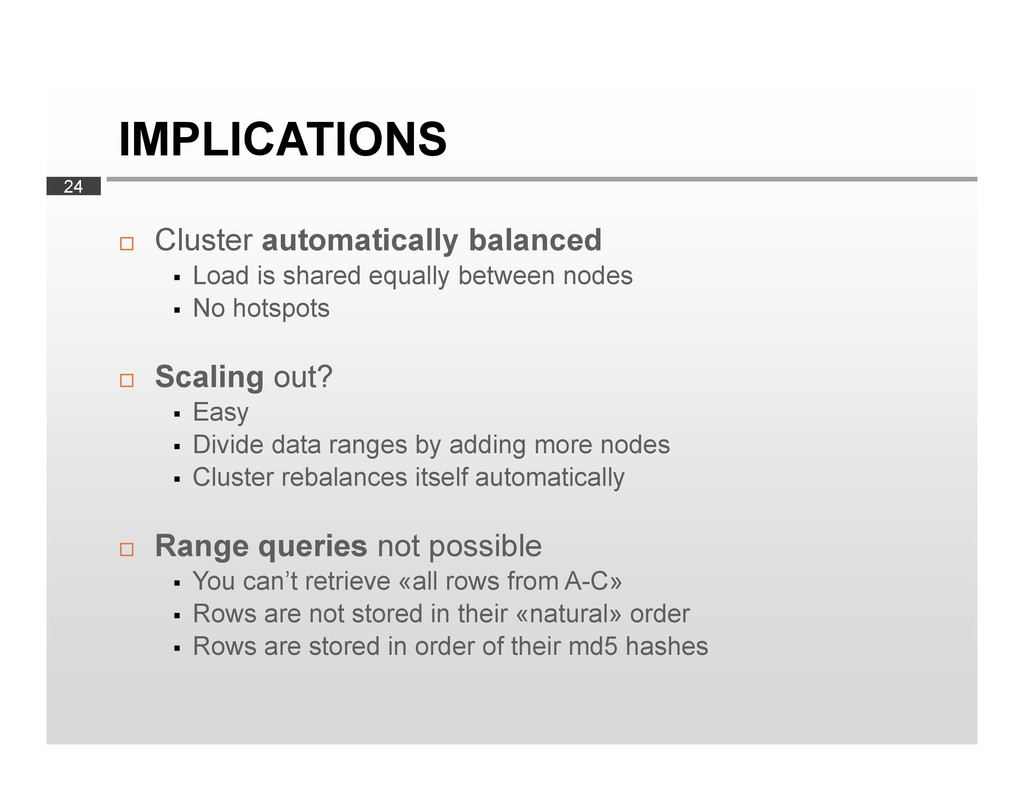
  16. 24 IMPLICATIONS  Cluster automatically balanced  Load is shared

    equally between nodes  No hotspots  Scaling out?  Easy  Divide data ranges by adding more nodes  Cluster rebalances itself automatically  Range queries not possible  You can’t retrieve «all rows from A-C»  Rows are not stored in their «natural» order  Rows are stored in order of their md5 hashes
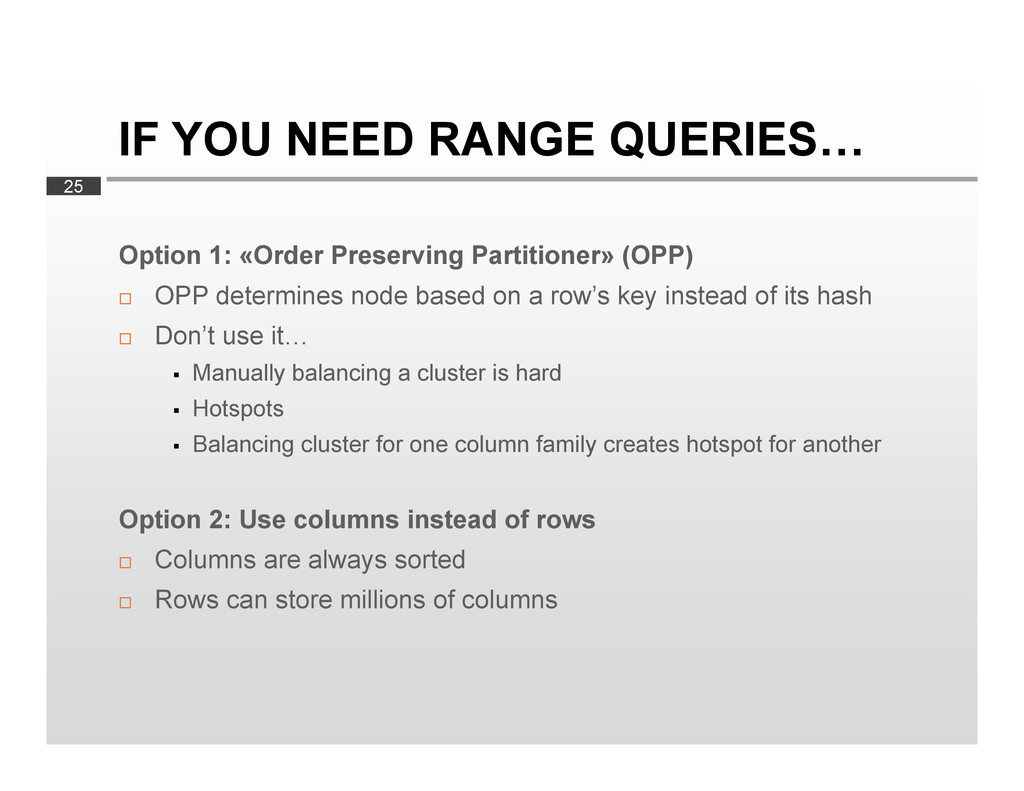
  17. 25 IF YOU NEED RANGE QUERIES… Option 1: «Order Preserving

    Partitioner» (OPP)  OPP determines node based on a row’s key instead of its hash  Don’t use it…  Manually balancing a cluster is hard  Hotspots  Balancing cluster for one column family creates hotspot for another Option 2: Use columns instead of rows  Columns are always sorted  Rows can store millions of columns
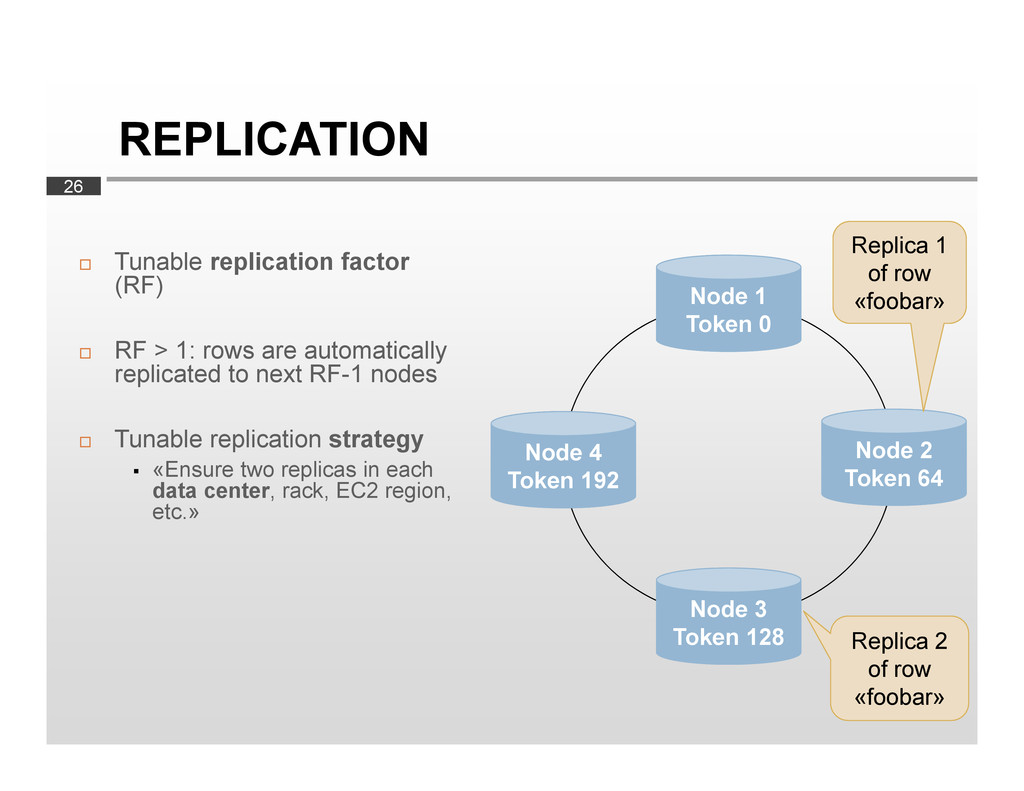
  18. 26 REPLICATION  Tunable replication factor (RF)  RF >

    1: rows are automatically replicated to next RF-1 nodes  Tunable replication strategy  «Ensure two replicas in each data center, rack, EC2 region, etc.» Node 3 Token 128 Node 2 Token 64 Node 4 Token 192 Node 1 Token 0 Replica 1 of row «foobar» Replica 2 of row «foobar»
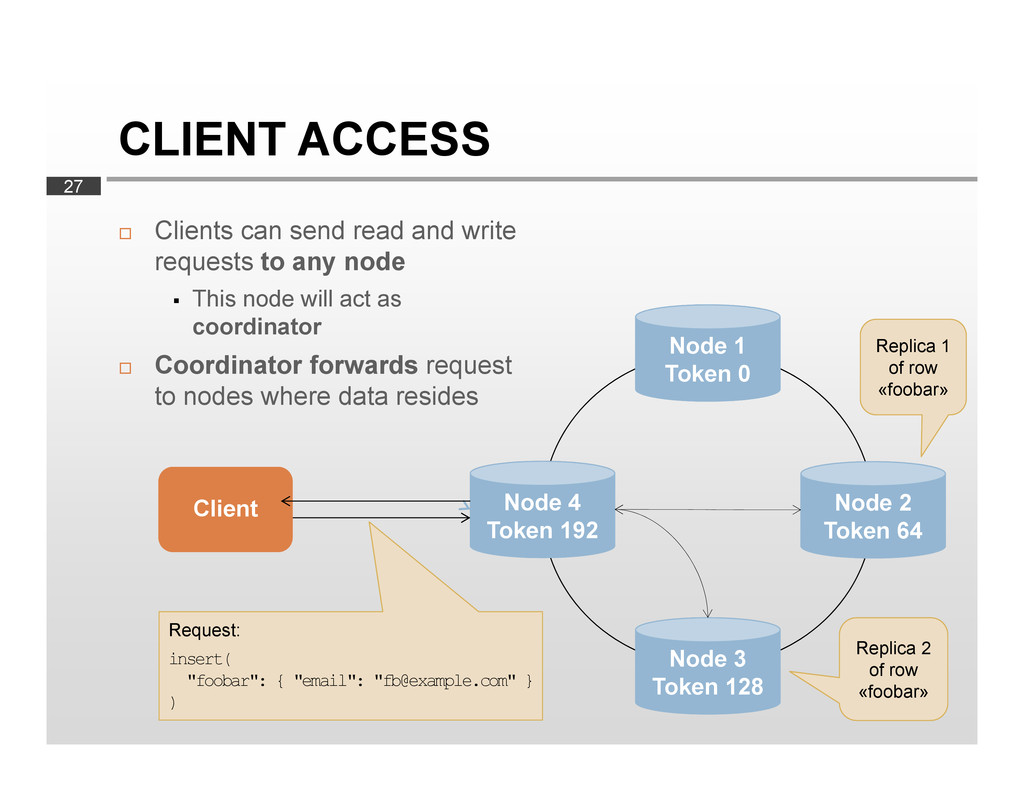
  19. 27 CLIENT ACCESS  Clients can send read and write

    requests to any node  This node will act as coordinator  Coordinator forwards request to nodes where data resides Node 3 Token 128 Node 2 Token 64 Node 4 Token 192 Node 1 Token 0 Client Request: insert( "foobar": { "email": "[email protected]" } ) Replica 2 of row «foobar» Replica 1 of row «foobar»
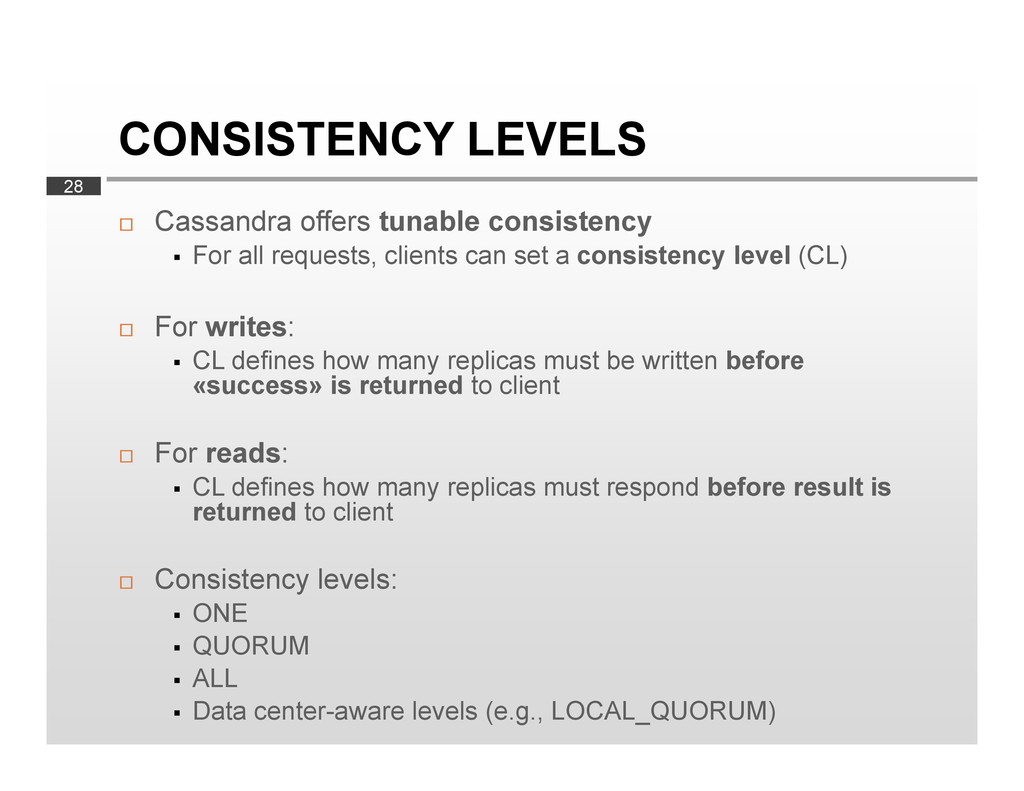
  20. 28 CONSISTENCY LEVELS  Cassandra offers tunable consistency  For

    all requests, clients can set a consistency level (CL)  For writes:  CL defines how many replicas must be written before «success» is returned to client  For reads:  CL defines how many replicas must respond before result is returned to client  Consistency levels:  ONE  QUORUM  ALL  Data center-aware levels (e.g., LOCAL_QUORUM)
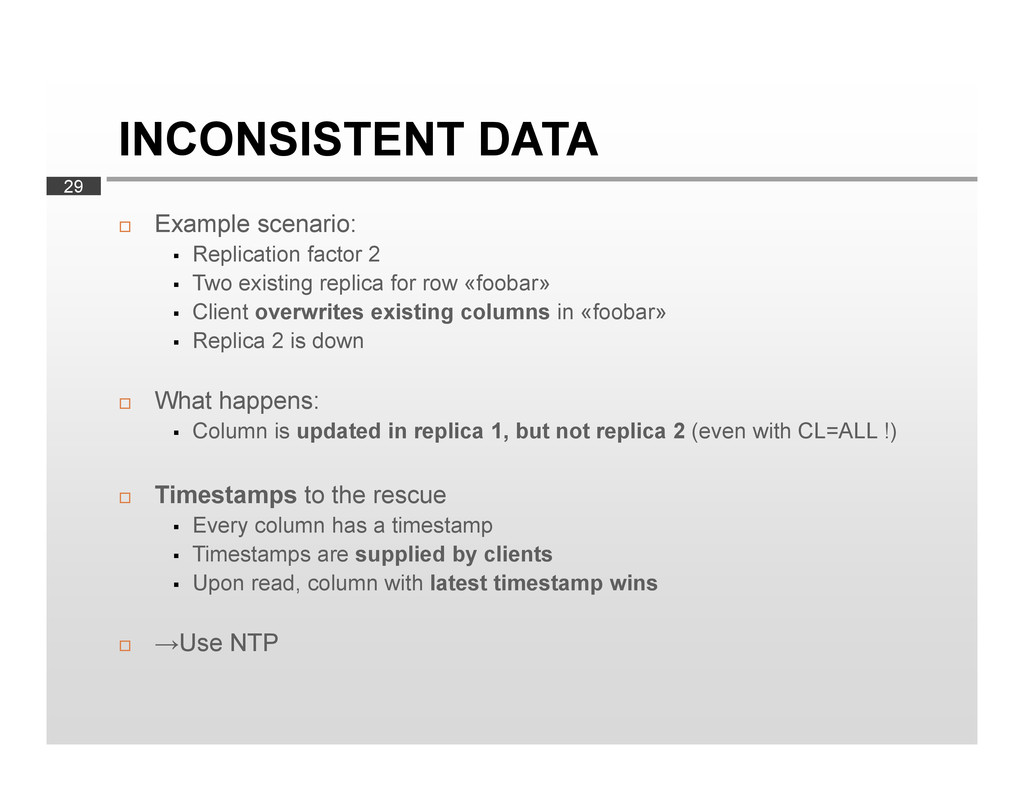
  21. 29 INCONSISTENT DATA  Example scenario:  Replication factor 2

     Two existing replica for row «foobar»  Client overwrites existing columns in «foobar»  Replica 2 is down  What happens:  Column is updated in replica 1, but not replica 2 (even with CL=ALL !)  Timestamps to the rescue  Every column has a timestamp  Timestamps are supplied by clients  Upon read, column with latest timestamp wins  →Use NTP
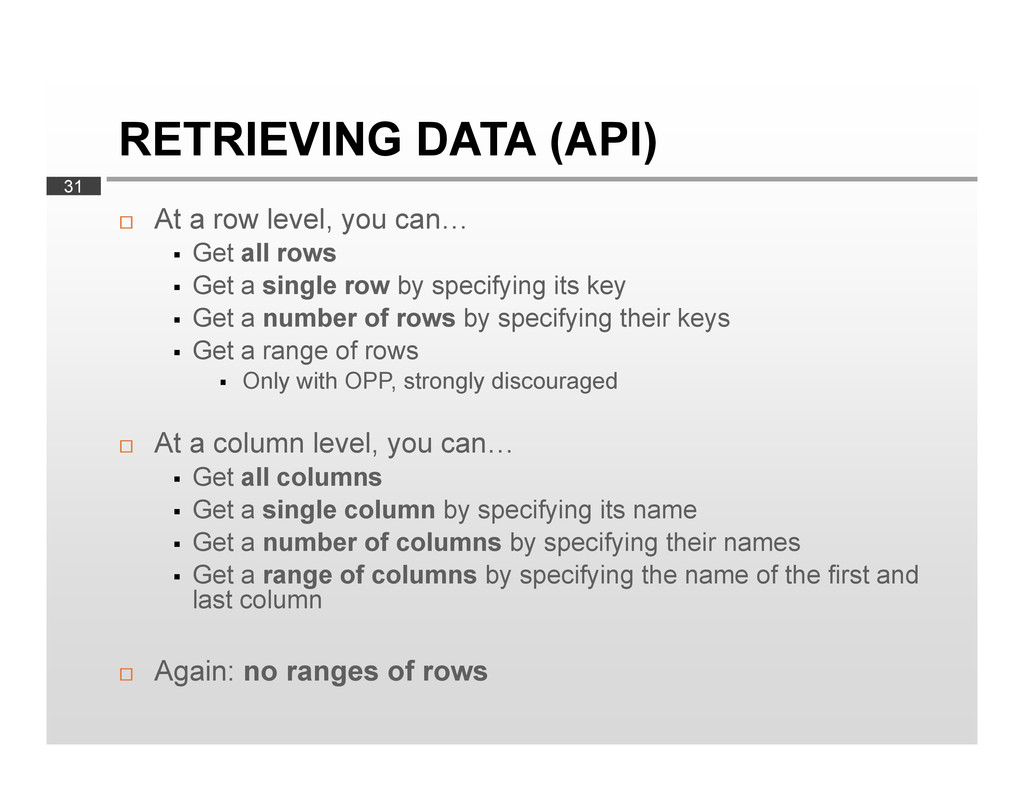
  22. 31 RETRIEVING DATA (API)  At a row level, you

    can…  Get all rows  Get a single row by specifying its key  Get a number of rows by specifying their keys  Get a range of rows  Only with OPP, strongly discouraged  At a column level, you can…  Get all columns  Get a single column by specifying its name  Get a number of columns by specifying their names  Get a range of columns by specifying the name of the first and last column  Again: no ranges of rows
  23. 32 "users": { "alice": { "email": "[email protected]", "phone": "123-456-7890" }

    "bob": { "email": "[email protected]", "web": "www.example.com" } } CASSANDRA QUERY LANGUAGE (CQL) UPDATE users SET "email" = "[email protected]", "phone" = "123-456-7890" WHERE KEY = "alice";
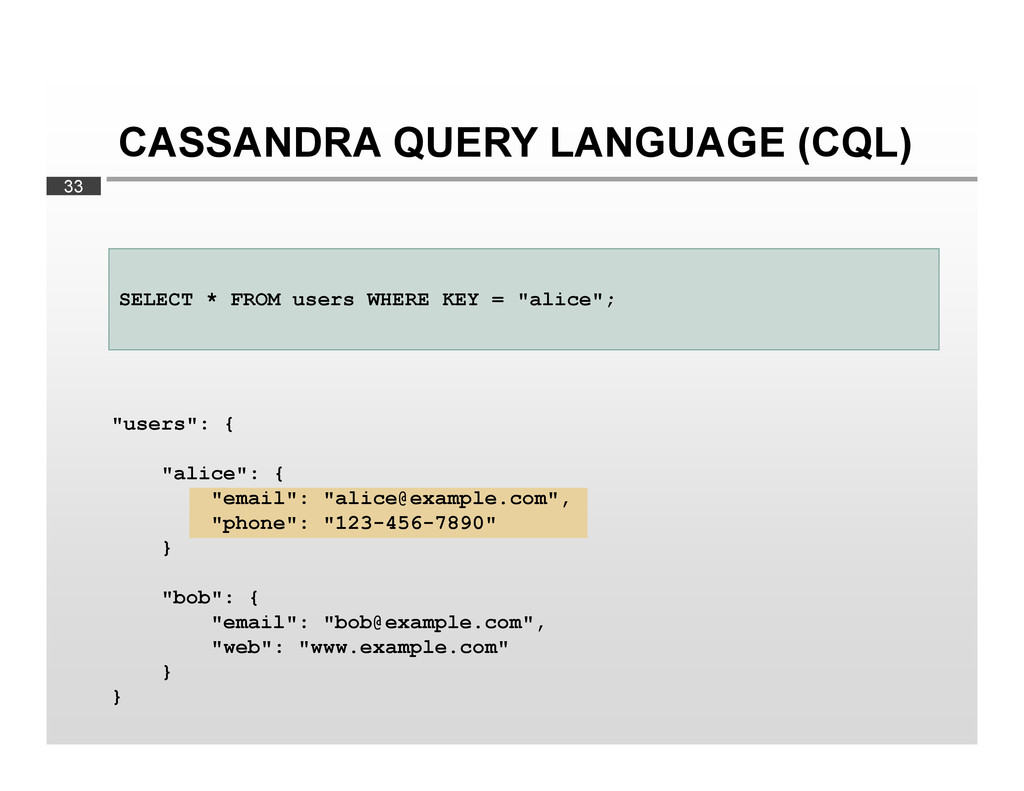
  24. 33 CASSANDRA QUERY LANGUAGE (CQL) SELECT * FROM users WHERE

    KEY = "alice"; "users": { "alice": { "email": "[email protected]", "phone": "123-456-7890" } "bob": { "email": "[email protected]", "web": "www.example.com" } }
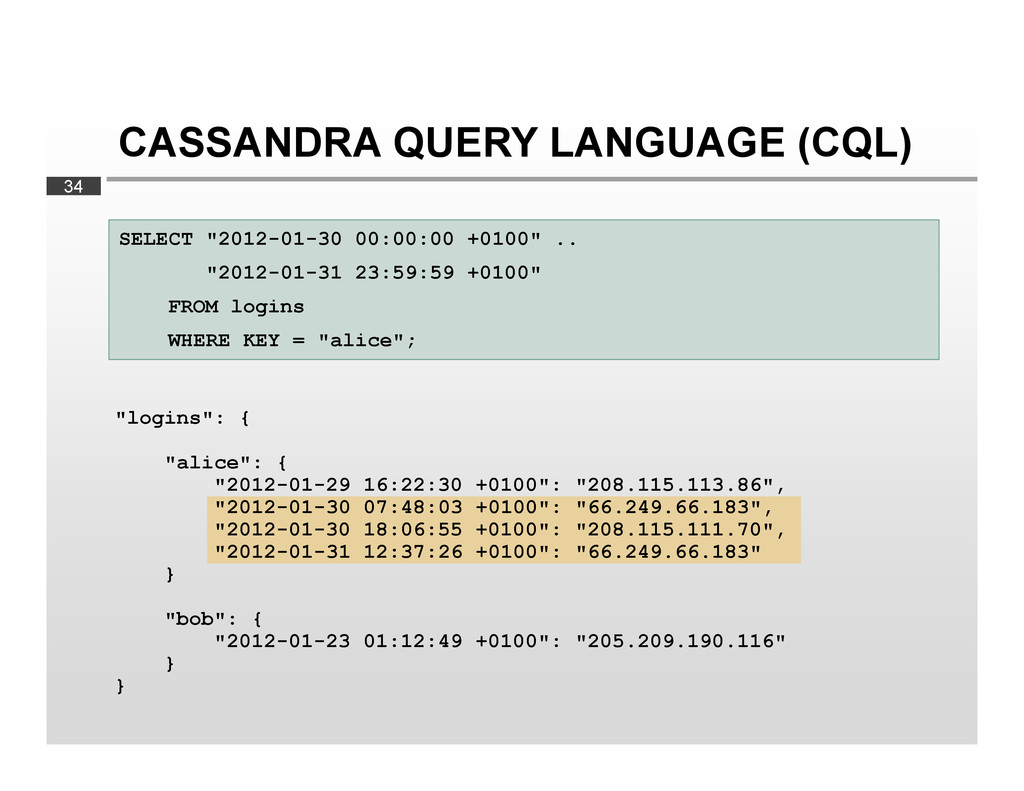
  25. 34 "logins": { "alice": { "2012-01-29 16:22:30 +0100": "208.115.113.86", "2012-01-30

    07:48:03 +0100": "66.249.66.183", "2012-01-30 18:06:55 +0100": "208.115.111.70", "2012-01-31 12:37:26 +0100": "66.249.66.183" } "bob": { "2012-01-23 01:12:49 +0100": "205.209.190.116" } } CASSANDRA QUERY LANGUAGE (CQL) SELECT "2012-01-30 00:00:00 +0100" .. "2012-01-31 23:59:59 +0100" FROM logins WHERE KEY = "alice";
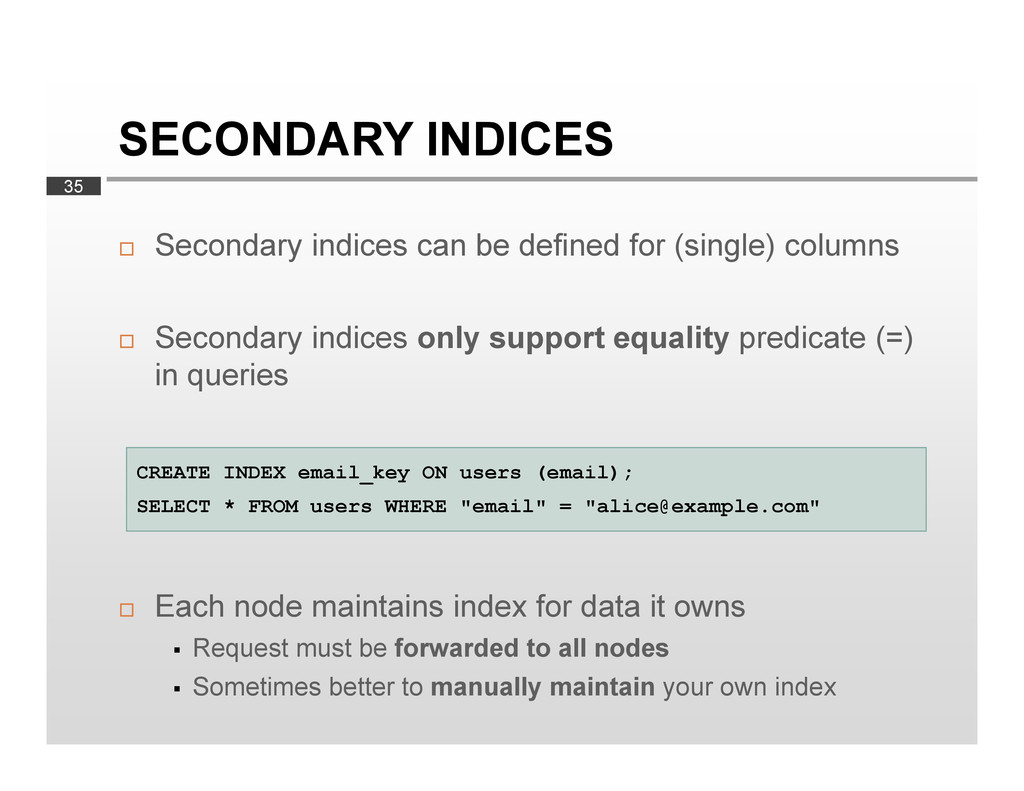
  26. 35 SECONDARY INDICES  Secondary indices can be defined for

    (single) columns  Secondary indices only support equality predicate (=) in queries  Each node maintains index for data it owns  Request must be forwarded to all nodes  Sometimes better to manually maintain your own index CREATE INDEX email_key ON users (email); SELECT * FROM users WHERE "email" = "[email protected]"
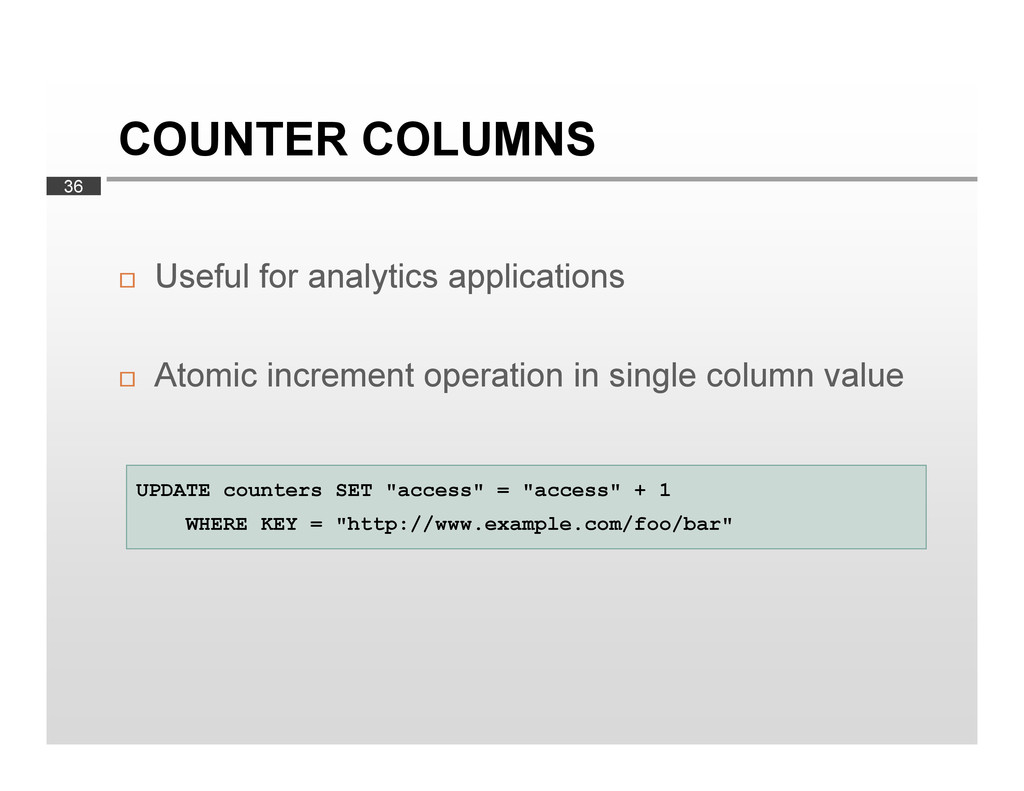
  27. 36 COUNTER COLUMNS  Useful for analytics applications  Atomic

    increment operation in single column value UPDATE counters SET "access" = "access" + 1 WHERE KEY = "http://www.example.com/foo/bar"
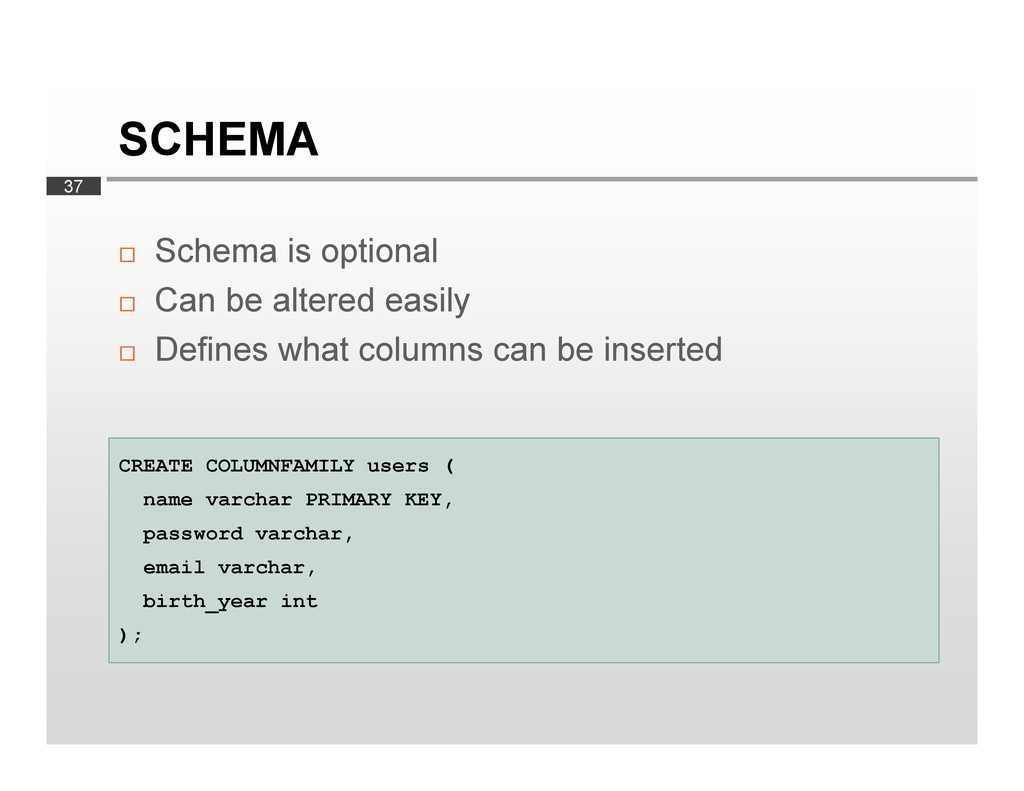
  28. 37 SCHEMA  Schema is optional  Can be altered

    easily  Defines what columns can be inserted CREATE COLUMNFAMILY users ( name varchar PRIMARY KEY, password varchar, email varchar, birth_year int );
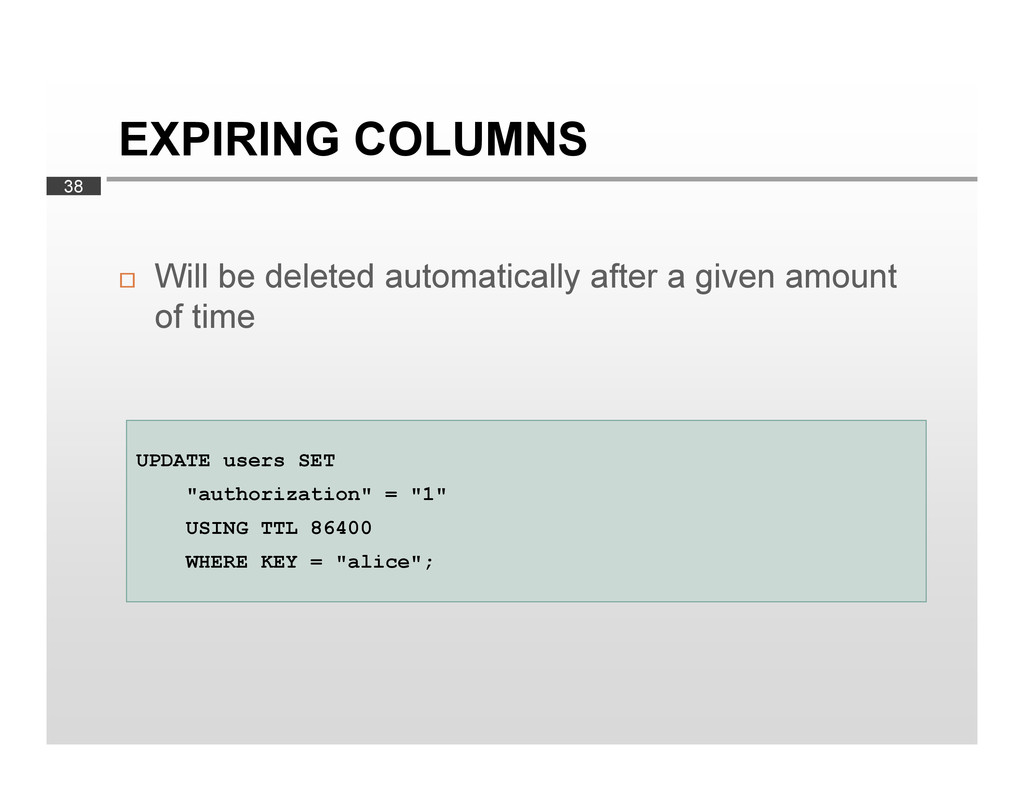
  29. 38 EXPIRING COLUMNS  Will be deleted automatically after a

    given amount of time UPDATE users SET "authorization" = "1" USING TTL 86400 WHERE KEY = "alice";
  30. 39 PRODUCTION EXPERIENCE: CLUSTER AT SCANDIT  Nodes in three

    data centers  Linux machines  Identical setup on every node  Allows for easy failover
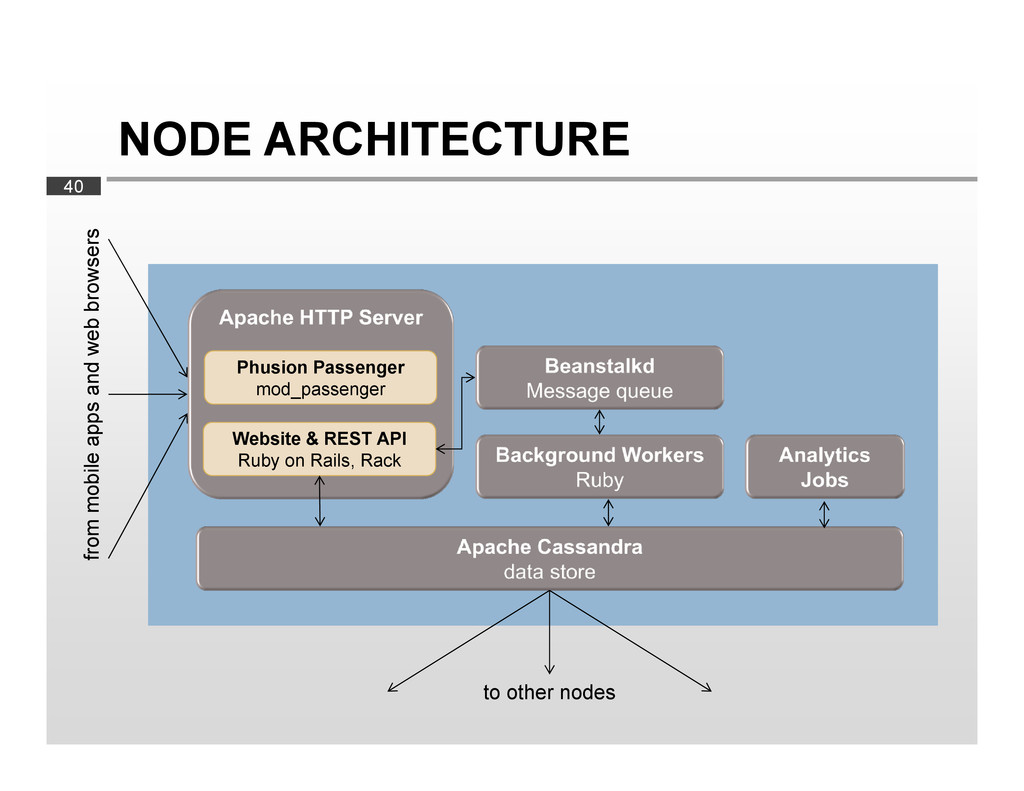
  31. 40 NODE ARCHITECTURE Website & REST API Ruby on Rails,

    Rack to other nodes from mobile apps and web browsers Phusion Passenger mod_passenger
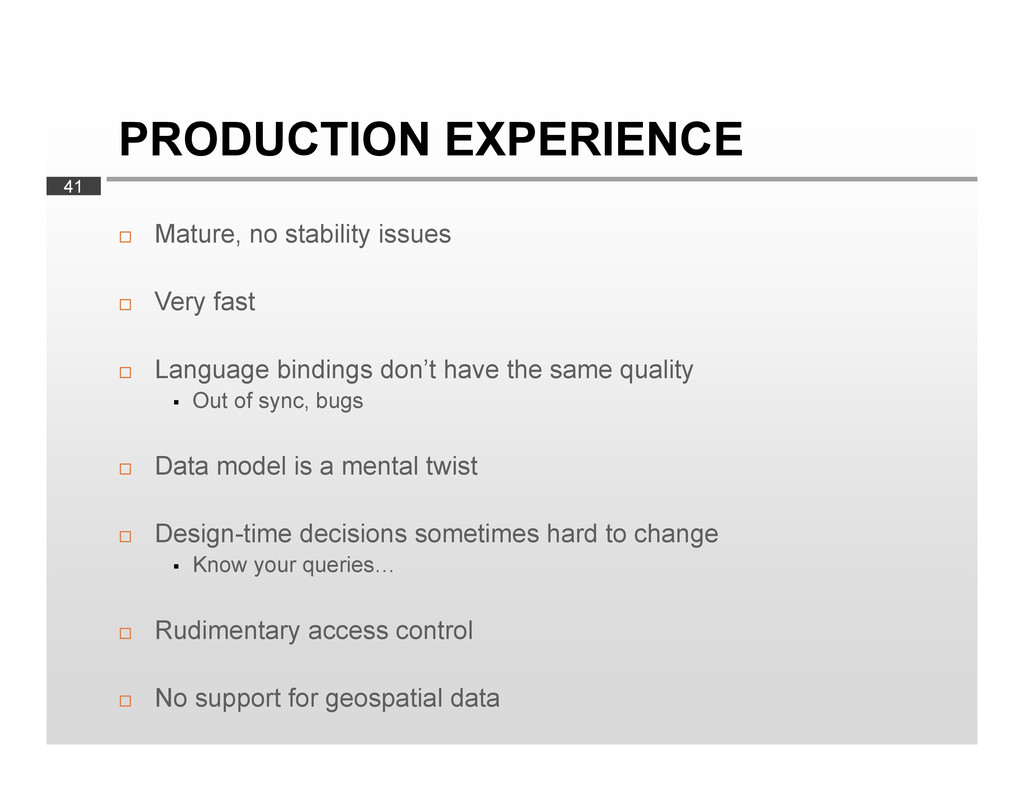
  32. 41 PRODUCTION EXPERIENCE  Mature, no stability issues  Very

    fast  Language bindings don’t have the same quality  Out of sync, bugs  Data model is a mental twist  Design-time decisions sometimes hard to change  Know your queries…  Rudimentary access control  No support for geospatial data
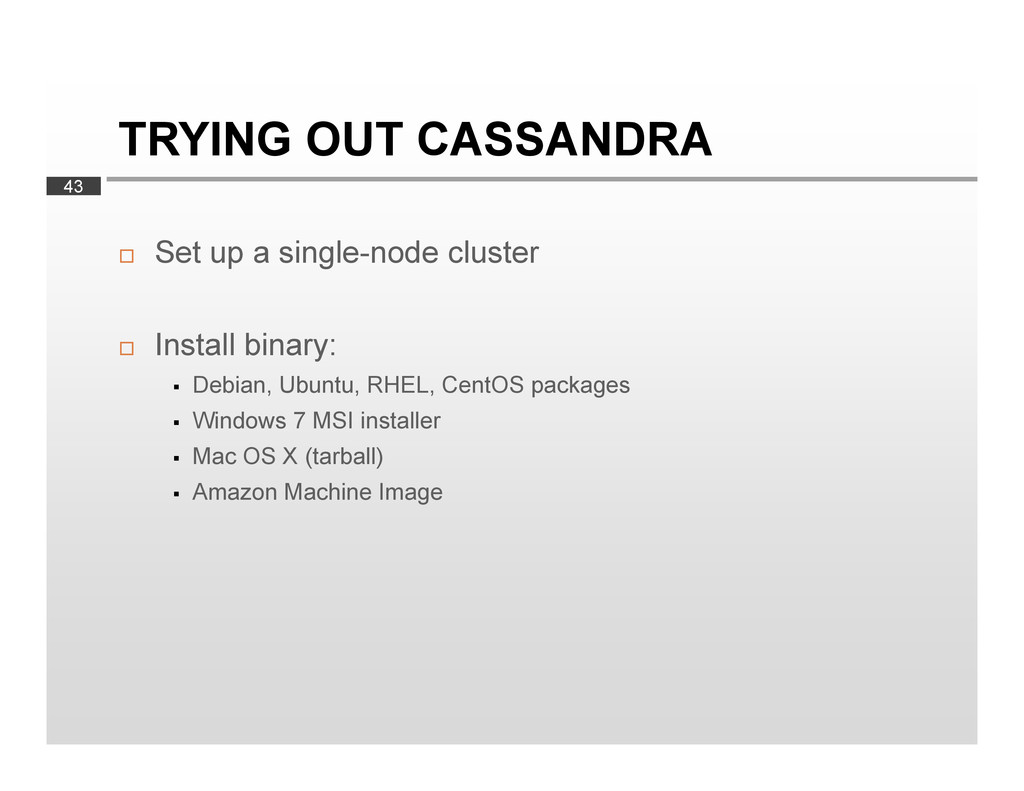
  33. 43 TRYING OUT CASSANDRA  Set up a single-node cluster

     Install binary:  Debian, Ubuntu, RHEL, CentOS packages  Windows 7 MSI installer  Mac OS X (tarball)  Amazon Machine Image
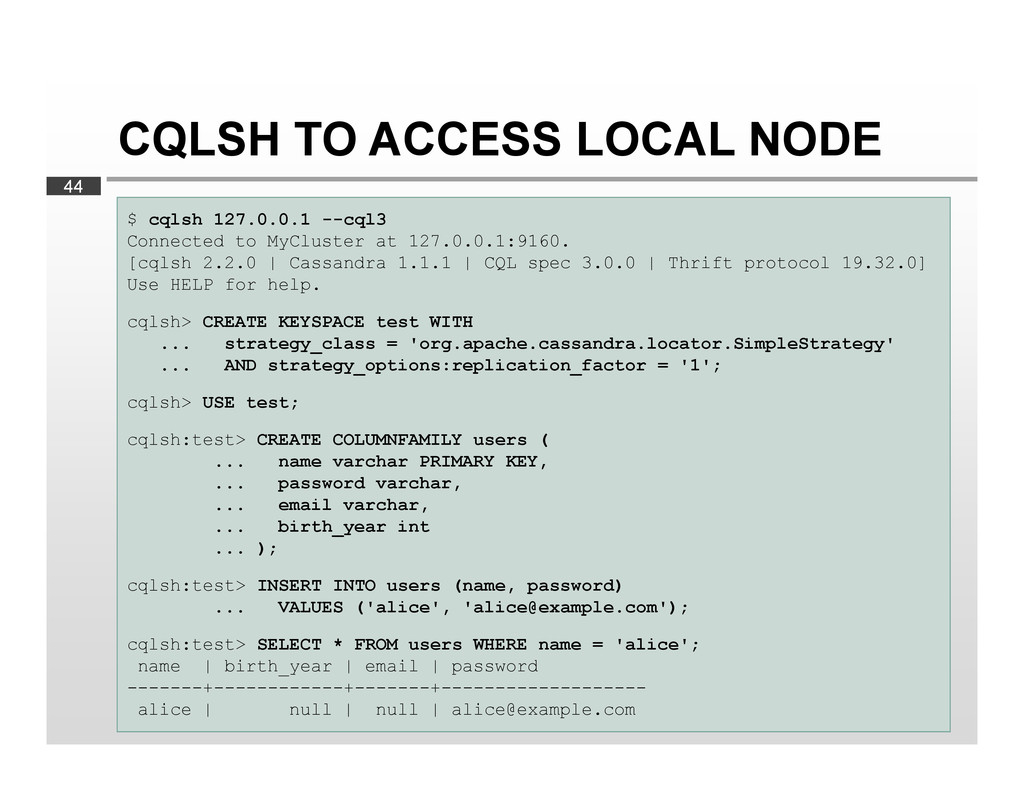
  34. 44 CQLSH TO ACCESS LOCAL NODE $ cqlsh 127.0.0.1 --cql3

    Connected to MyCluster at 127.0.0.1:9160. [cqlsh 2.2.0 | Cassandra 1.1.1 | CQL spec 3.0.0 | Thrift protocol 19.32.0] Use HELP for help. cqlsh> CREATE KEYSPACE test WITH ... strategy_class = 'org.apache.cassandra.locator.SimpleStrategy' ... AND strategy_options:replication_factor = '1'; cqlsh> USE test; cqlsh:test> CREATE COLUMNFAMILY users ( ... name varchar PRIMARY KEY, ... password varchar, ... email varchar, ... birth_year int ... ); cqlsh:test> INSERT INTO users (name, password) ... VALUES ('alice', '[email protected]'); cqlsh:test> SELECT * FROM users WHERE name = 'alice'; name | birth_year | email | password -------+------------+-------+------------------- alice | null | null | [email protected]
  35. 45 DOCUMENTATION  DataStax website  Company founded by Cassandra

    developers  Apache website  Mailing lists

More Decks by Christof Roduner

Other Decks in Programming