Share
Embed
Transcript
35 slides
-
Analyzing Data in MongoDB Sandeep Parikh Technical Product
Manager [email protected] @crcsmnky -
Agenda • Brief background • Common use cases
• Analyzing your data • Questions -
MongoDB Basics • Scalable, high performance, open source NoSQL
database • Data stored in JSON-‐style documents • Rich objects: arrays, dictionaries • Schema-‐free -
MongoDB Features • Ad-‐hoc queries • Indexes
• Atomic document updates • Single-‐master replication • Can be used to scale reads • Auto-‐sharding • Scale your write workload -
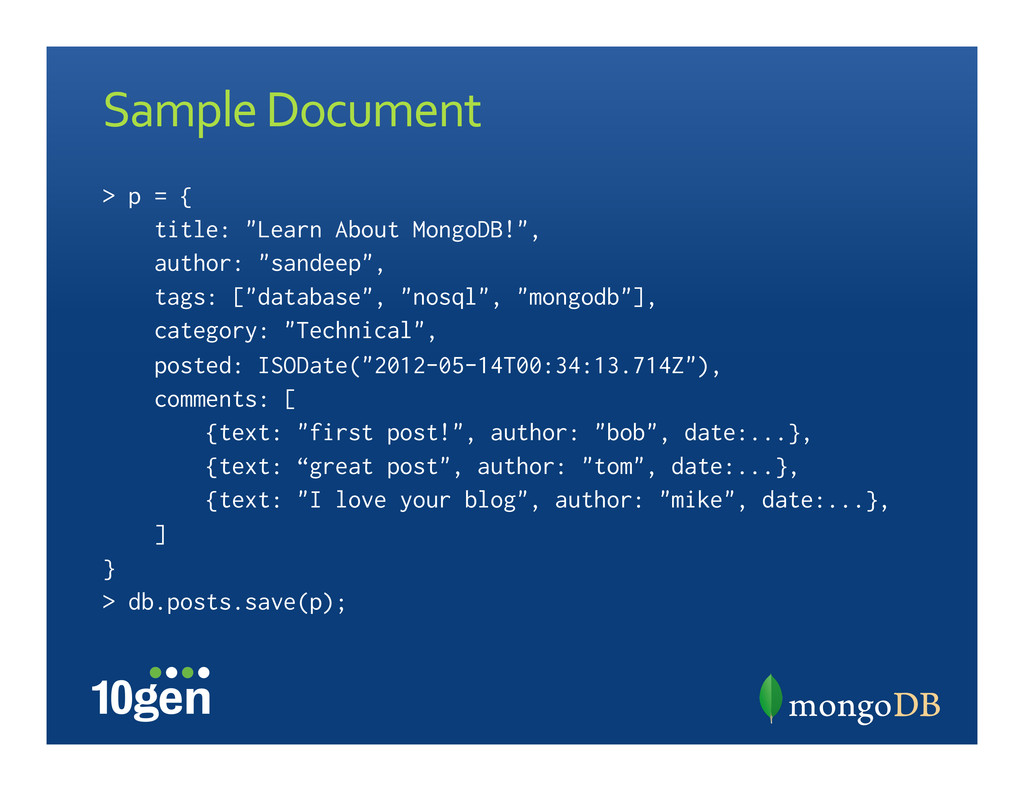
Sample Document > p = { title: "Learn About
MongoDB!", author: "sandeep", tags: ["database", "nosql", "mongodb"], category: "Technical", posted: ISODate("2012-05-14T00:34:13.714Z"), comments: [ {text: "first post!", author: "bob", date:...}, {text: “great post", author: "tom", date:...}, {text: "I love your blog", author: "mike", date:...}, ] } > db.posts.save(p); -
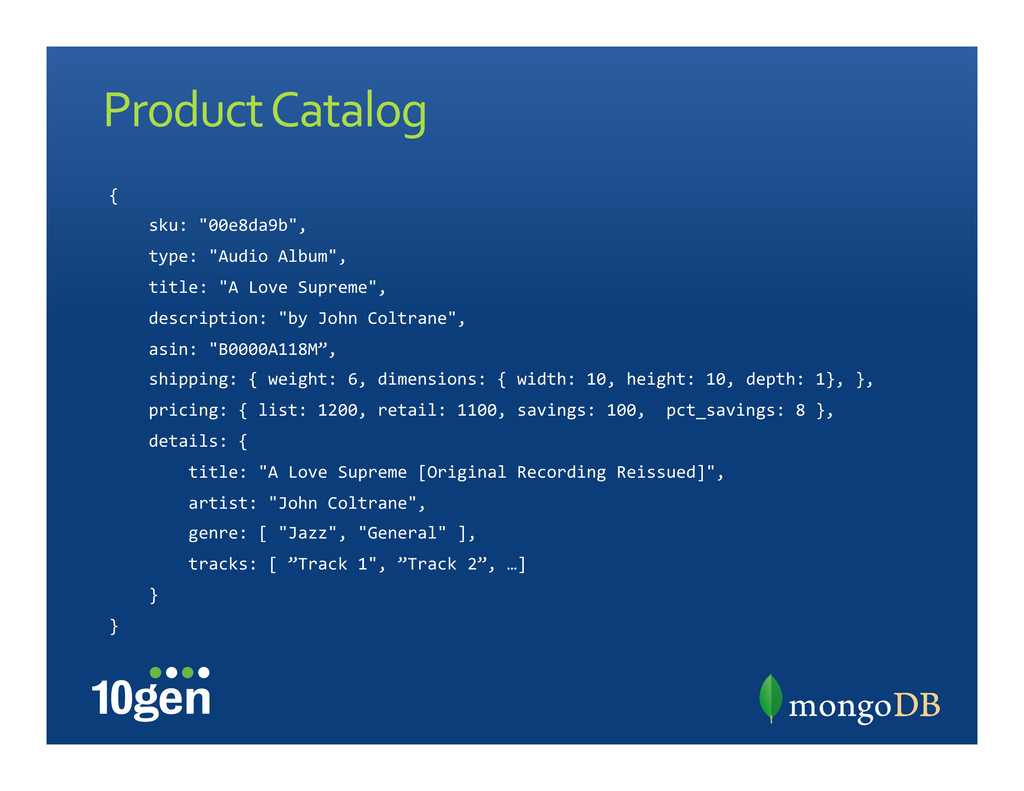
Product Catalog { sku: "00e8da9b",
type: "Audio Album", title: "A Love Supreme", description: "by John Coltrane", asin: "B0000A118M”, shipping: { weight: 6, dimensions: { width: 10, height: 10, depth: 1}, }, pricing: { list: 1200, retail: 1100, savings: 100, pct_savings: 8 }, details: { title: "A Love Supreme [Original Recording Reissued]", artist: "John Coltrane", genre: [ "Jazz", "General" ], tracks: [ ”Track 1", ”Track 2”, …] } } -
Product Catalog • Shopping/e-‐commerce • Build compound indexes
across multiple attributes • Ex. Type and Genre • Good fit for storing multiple product types with different attributes • Include things like “type” in your shard key -
Storing Comments • One document per comment •
Threading comments and replies • Indexes can be built for fast paging through comments • Direct links • Shard comments by post/discussion -
More Use Cases • Operational intelligence • Storing
log data • Pre-‐aggregated reports • Hierarchical aggregation (e.g. monthly rollups) • Product management • Inventory management • Product category hierarchies • Content management • Metadata/asset management -
Use Case Docs • http://docs.mongodb.org/manual/use-‐cases/ • For each
case: • Overviews • Schemas • Query and indexing operations • Scaling reads/writes -
Map-‐Reduce • Execute across documents in a collection
• map • reduce • finalize • Populate map jobs with queries • Incremental MR • Sharded datasets run MR in parallel -
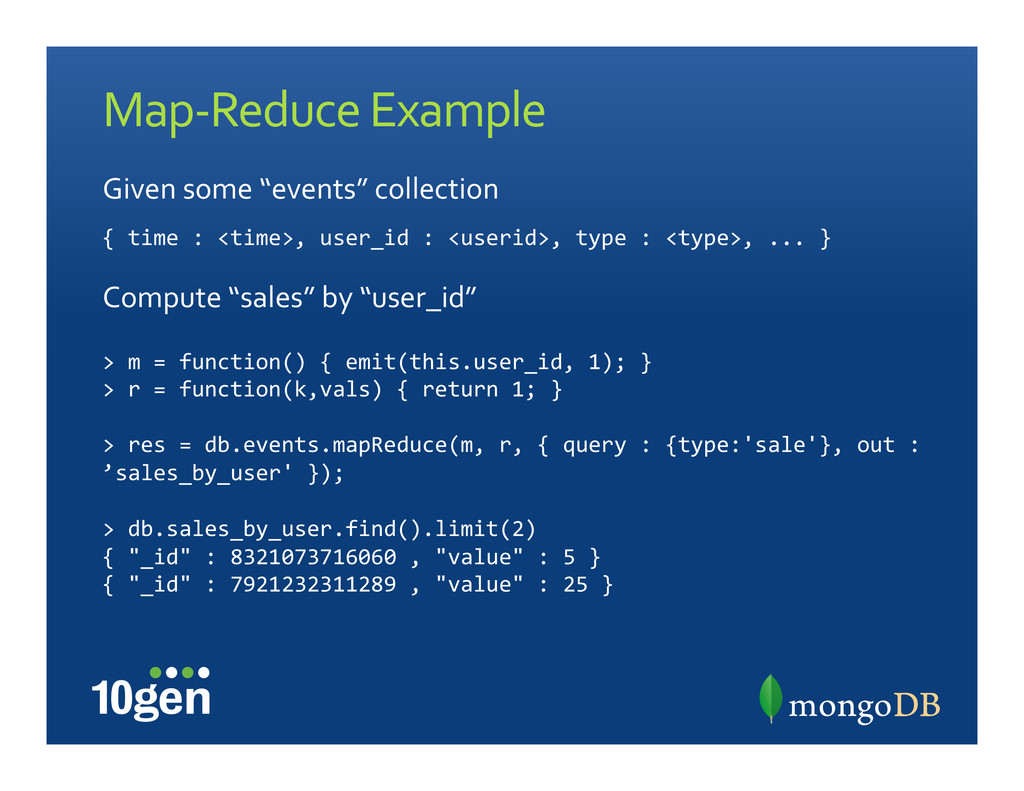
Map-‐Reduce Example > m = function() { emit(this.user_id, 1);
} > r = function(k,vals) { return 1; } > res = db.events.mapReduce(m, r, { query : {type:'sale'}, out : ’sales_by_user' }); > db.sales_by_user.find().limit(2) { "_id" : 8321073716060 , "value" : 5 } { "_id" : 7921232311289 , "value" : 25 } { time : <time>, user_id : <userid>, type : <type>, ... } Given some “events” collection Compute “sales” by “user_id” -
What’s Not To Love? • Map-‐Reduce functions are written
in Javascript • Complex MRs might not be fun to write • Runs in the single-‐threaded Javascript engine • Could be resource intensive for simple operations • Not robust enough for complex operations -
Aggregation Framework • MR is a big hammer
• Simpler tasks should be easier • Skip writing Javascript • Skip executing Javascript • Plus, get some support for complex document structures • In development and testing now (2.1.x), stable release soon (2.2) -
Aggregation Features • Declarative framework; no JS required
• Describe a chain of operations • We’re going to continue adding functions • Implemented in the core server (C++) so it works faster and scales better -
Define Pipeline • A series of operations (e.g. Unix
pipe) • Documents are passed through the pipeline to produce/compute a result • Pipeline operations chained together • Aggregate information • ETL data into different forms -
Pipeline Operations • $match: like find() as a filter
• $project: extract fields, compute values • $unwind: split arrays • $group: put items into defined buckets • $sort: order documents • $limit: only process N documents • $skip: start after X documents -
Projections • Reshape your documents • Pull fields
“up”, push fields “down” • Compute across fields using built-‐in functions: • Boolean • Comparison • Arithmetic • String • Date -
Projections • Combine functions using • $ifNull
• $cond • Arithmetic functions work with • Strings ($add concatenates) • Dates ($add/$subtract) -
Grouping • Simple aggregations; similar to Reduce •
Pick a key and N values to “reduce” • $addToSet • $first/$last • $min/max • $avg • $sum • $push -
Aggregation Tips • Use $match as early as possible
• Avoids collection scanning and pulling in more than you need • Use $sort as early as possible • Query optimizer can be used to choose an index instead of sorting the result itself • Support in drivers via db.runCommand() • Break up the work, documents are limited to 16MB -
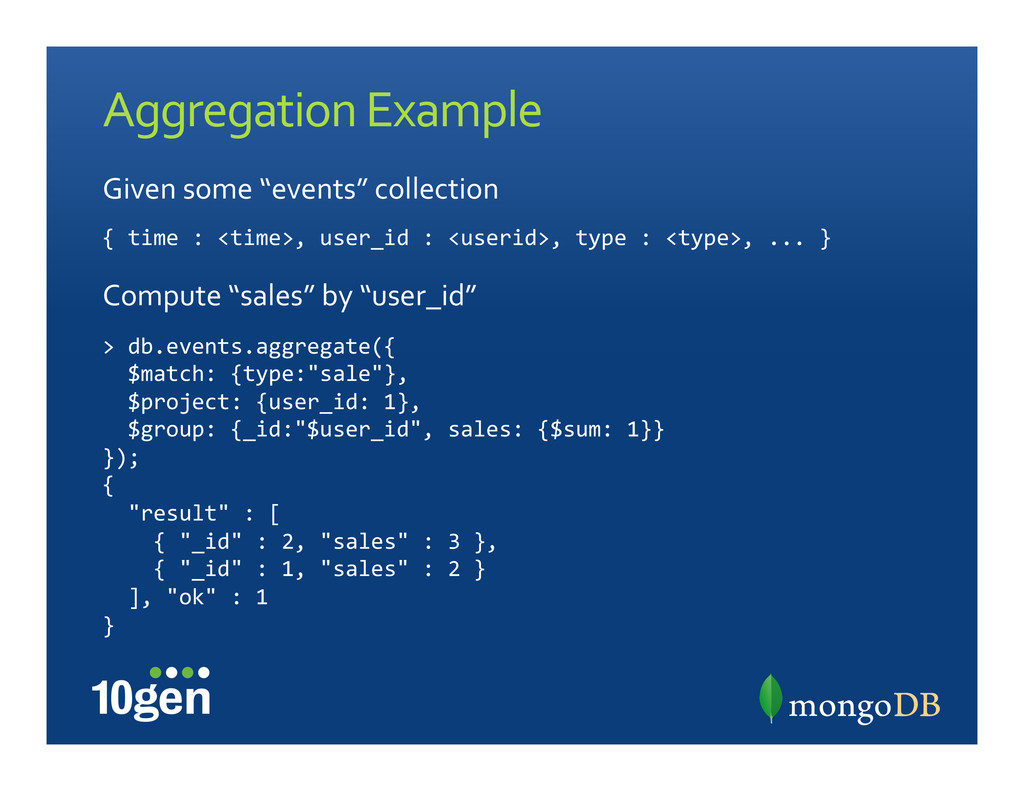
Aggregation Example > db.events.aggregate({ $match: {type:"sale"},
$project: {user_id: 1}, $group: {_id:"$user_id", sales: {$sum: 1}} }); { "result" : [ { "_id" : 2, "sales" : 3 }, { "_id" : 1, "sales" : 2 } ], "ok" : 1 } { time : <time>, user_id : <userid>, type : <type>, ... } Given some “events” collection Compute “sales” by “user_id” -
MongoDB-‐Hadoop • MongoDB-‐Hadoop adapter • 1.0 released about
2 months ago • Working on the next release • Support for MongoDB as input/output format • Works with • Native MR jobs • Streaming • Pig -
MongoDB-‐Hadoop • Hive support is in-‐progress • Support
for streaming varies across releases • CDH3/CDH4 (yes) • 0.20.x (no) • 1.0.x (no) • 0.21.x (yes) -
MongoDB-‐Hadoop Resources • Github • https://github.com/mongodb/mongo-‐hadoop •
Building and running MR examples with adapter • http://www.mongodb.org/display/DOCS/Hadoop +Quick+Start • Walkthrough of using streaming • http://blog.mongodb.org/post/24610529795/hadoop-‐ streaming-‐support-‐for-‐mongodb -
Now What? • You know how to pull data
to/from MongoDB • How do you put these two things to good use? -
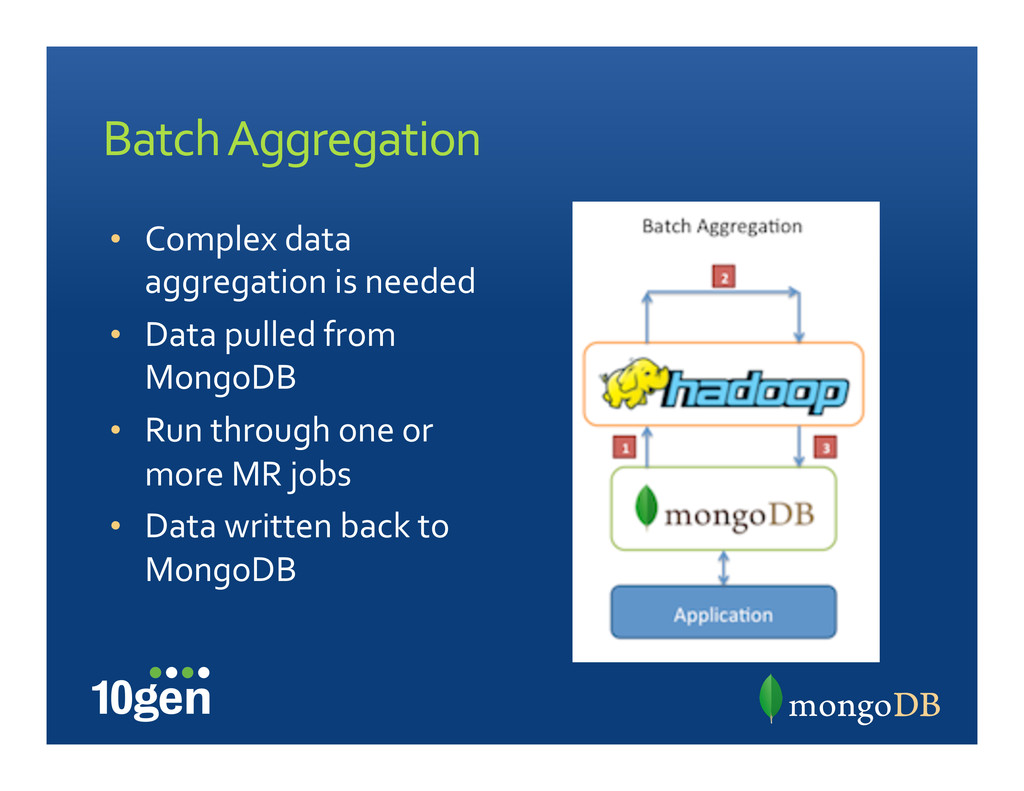
Batch Aggregation • Complex data aggregation is needed
• Data pulled from MongoDB • Run through one or more MR jobs • Data written back to MongoDB -
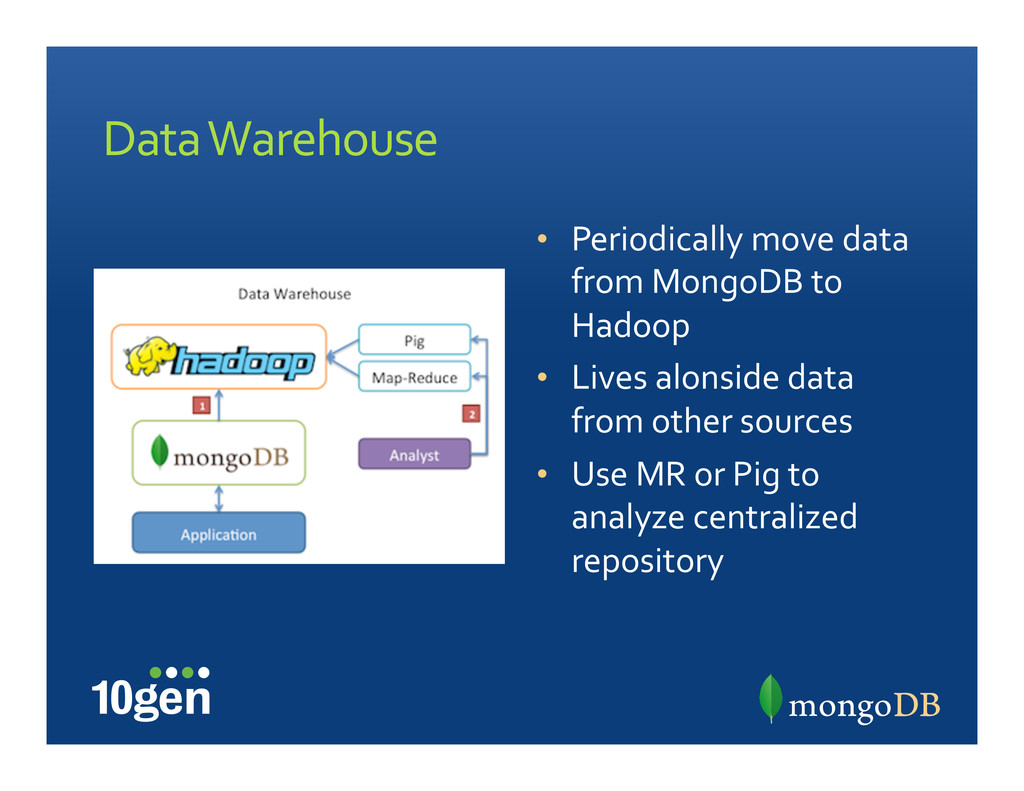
Data Warehouse • Periodically move data from MongoDB
to Hadoop • Lives alonside data from other sources • Use MR or Pig to analyze centralized repository -
Platforms • Pentaho and Jaspersoft • Both offer
• Business analytics platforms • Enterprise and Community editions • Ad-‐hoc analysis and reporting, explore data from MongoDB • Integration with other parts of the big data stack • http://www.mongodb.org/display/DOCS/ Business+Intelligence -
Questions, Comments • Sandeep Parikh • [email protected]
• @crcsmnky • MongoDB • http://www.mongodb.org • Downloads, documentation, drivers • 10gen • http://www.10gen.com • Support, training, consulting, MMS