Share
Embed
Ceph

Derek Weitzel
February 17, 2012
Transcript
70 slides
-
In the Before… v Lets go back through some of
the mentionable distributed file systems used in HPC -
In the Before… v There were distributed filesystems like: v
Lustre – RAID over storage boxes v Recovery time after a node failure was MASSIVE! (Entire server’s contents had to be copied, one to one) v When functional, reading/writing EXTREMELY fast v Used in heavily in HPC -
In the Before… v There were distributed filesystems like: v
NFS – Network File System v Does this really count as distributed? v Single large server v Full POSIX support, in kernel since…forever v Slow with even a moderate number of clients v Dead simple -
In the Current… v There are distributed filesystems like: v
Hadoop – Apache Project inspired by Google v Massive throughput v Throughput scales with attached HDs v Have seen VERY LARGE production clusters v Facebook, Yahoo… Nebraska v Doesn’t even pretend to be POSIX -
In the Current… v There are distributed filesystems like: v
GPFS(IBM) / Panasas – Propriety file systems v Requires closed source kernel driver v Not flexible with newest kernels / OS’s v Good: Good support and large communities v Can be treated as black box for administrators v HUGE Installments (Panasas at LANL is HUGE!!!!) -
Motivation v Ceph is a emerging technology in the production
clustered environment v Designed for: v Performance – Striped data over data servers. v Reliability – No single point of failure v Scalability – Adaptable metadata cluster -
Timeline v 2006 – Ceph Paper written v 2007 –
Sage Weil earned PhD from Ceph (largely) v 2007 – 2010 Development continued, primarily for DreamHost v March 2010 – Linus merged Ceph client into mainline 2.6.34 kernel v No more patches needed for clients -
Adding Ceph to Mainline Kernel v Huge development! v Significantly
lowered cost to deploy Ceph v For production environments, it was a little too late – 2.6.32 was the stable kernel used in RHEL 6 (CentOS 6, SL 6, Oracle 6). -
Ceph Overview v Decoupled data and metadata v IO directly
with object servers v Dynamic distributed metadata management v Multiple metadata servers handling different directories (subtrees) v Reliable autonomic distributed storage v OSD’s manage themselves by replicating and monitoring -
Decoupled Data and Metadata v Increases performance by limiting interaction
between clients and servers v Decoupling is common in distributed filesystems: Hadoop, Lustre, Panasas… v In contrast to other filesystems, CEPH uses a function to calculate the block locations -
Dynamic Distributed Metadata Management v Metadata is split among cluster
of servers v Distribution of metadata changes with the number of requests to even load among metadata servers v Metadata servers also can quickly recover from failures by taking over neighbors data v Improves performance by leveling metadata load -
Reliable Autonomic Distributed Storage v Data storage servers act on
events by themselves v Initiates replication and v Improves performance by offloading decision making to the many data servers v Improves reliability by removing central control of the cluster (single point of failure) -
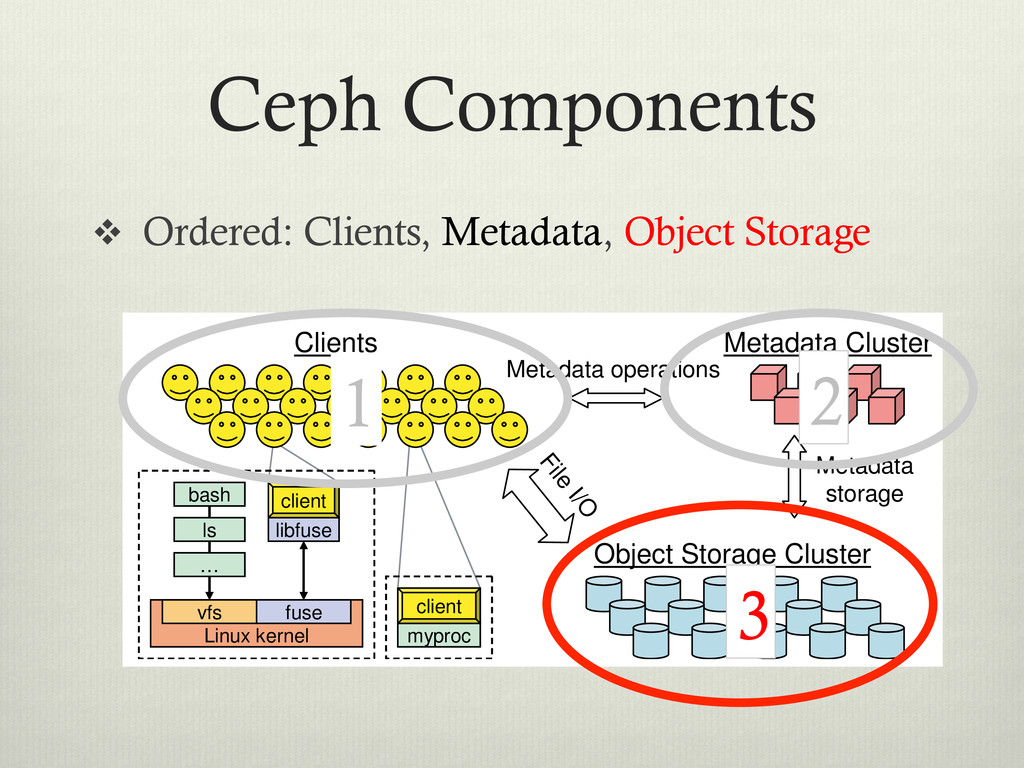
Ceph Components v Some quick definitions before getting into the
paper v MDS – Meta Data Server v ODS – Object Data Server v MON – Monitor (Now fully implemented) -
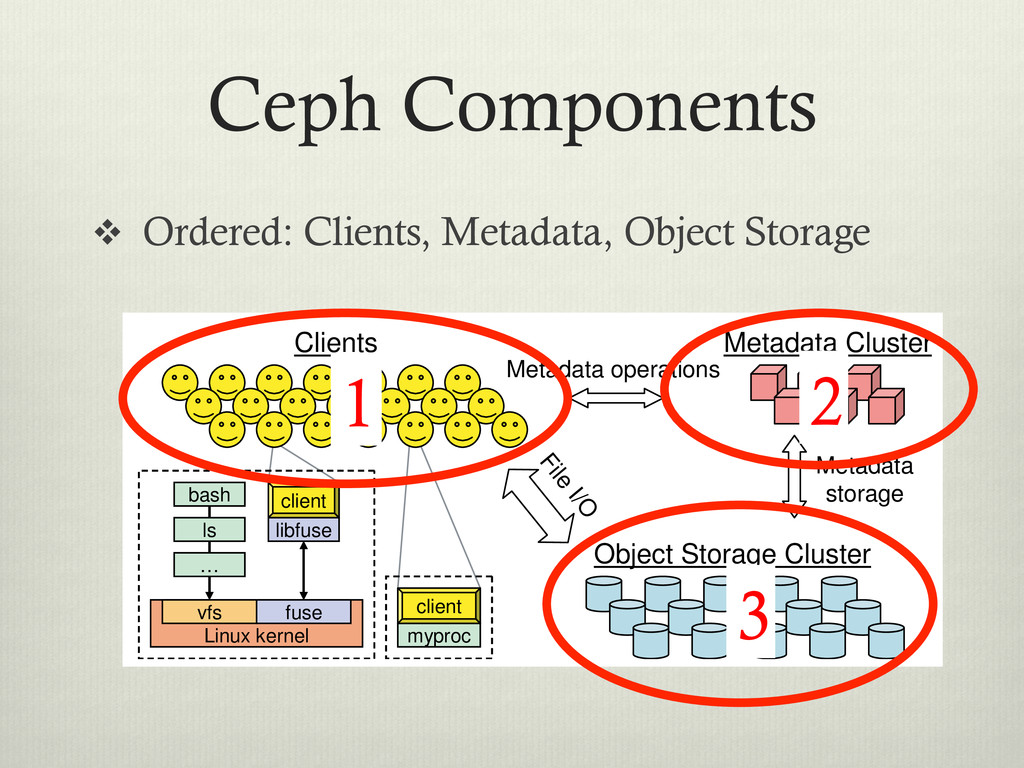
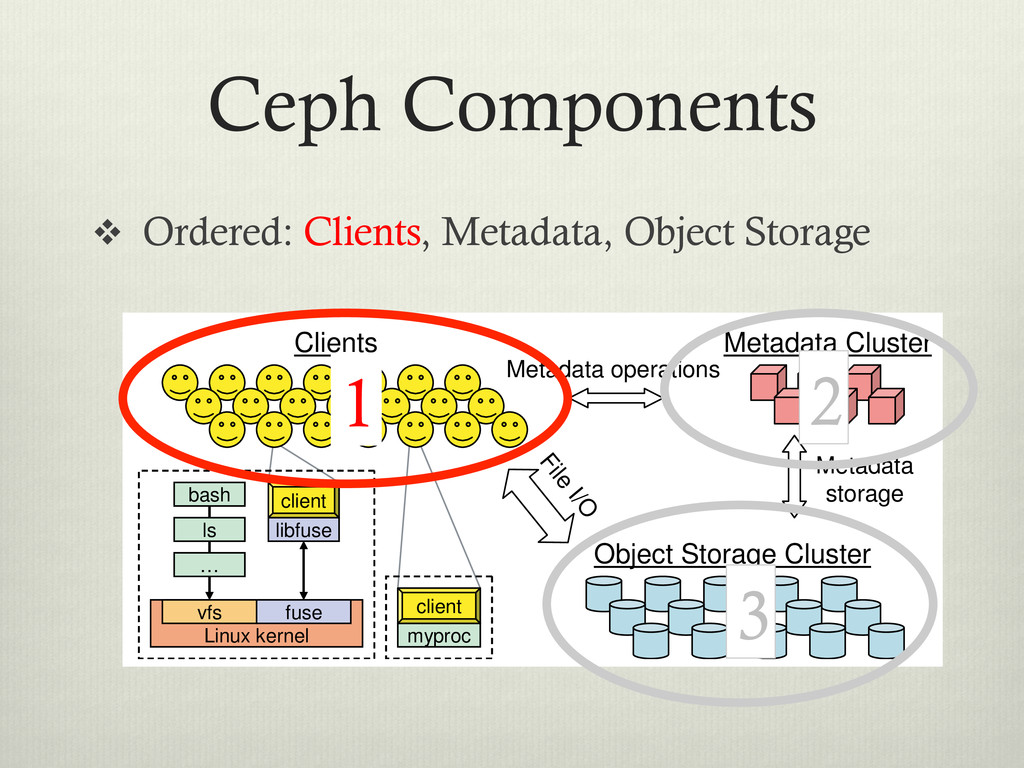
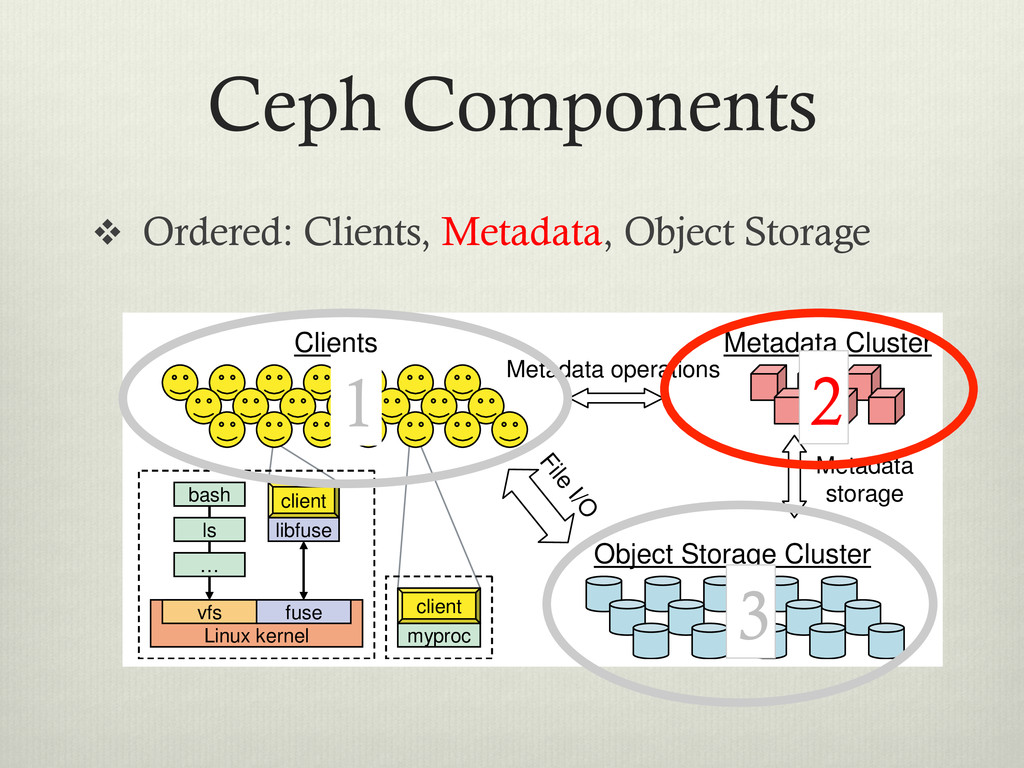
Ceph Components v Ordered: Clients, Metadata, Object Storage Metadata storage
File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in 1 2 3 -
Ceph Components v Ordered: Clients, Metadata, Object Storage Metadata storage
File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in 1 2 3 -
Client Overview v Can be a Fuse mount v File
system in user space v Introduced so file systems can use a better interface than the Linux Kernel VFS (Virtual file system) v Can link directly to the Ceph Library v Built into newest OS’s. -
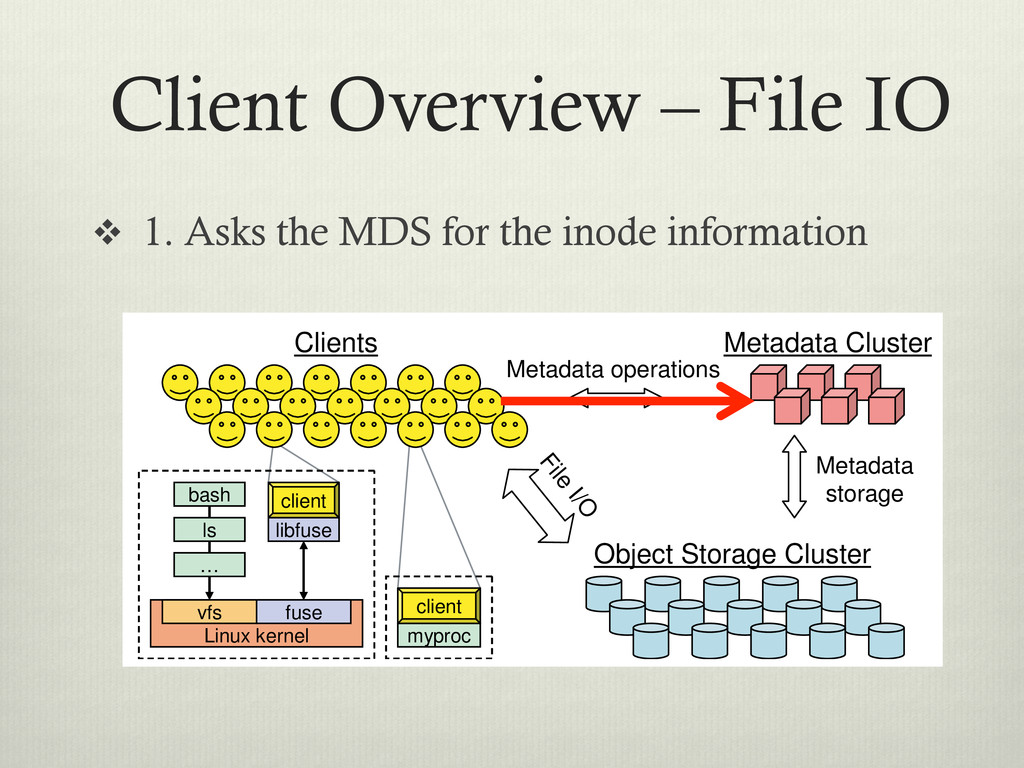
Client Overview – File IO v 1. Asks the MDS
for the inode information Metadata storage File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in -
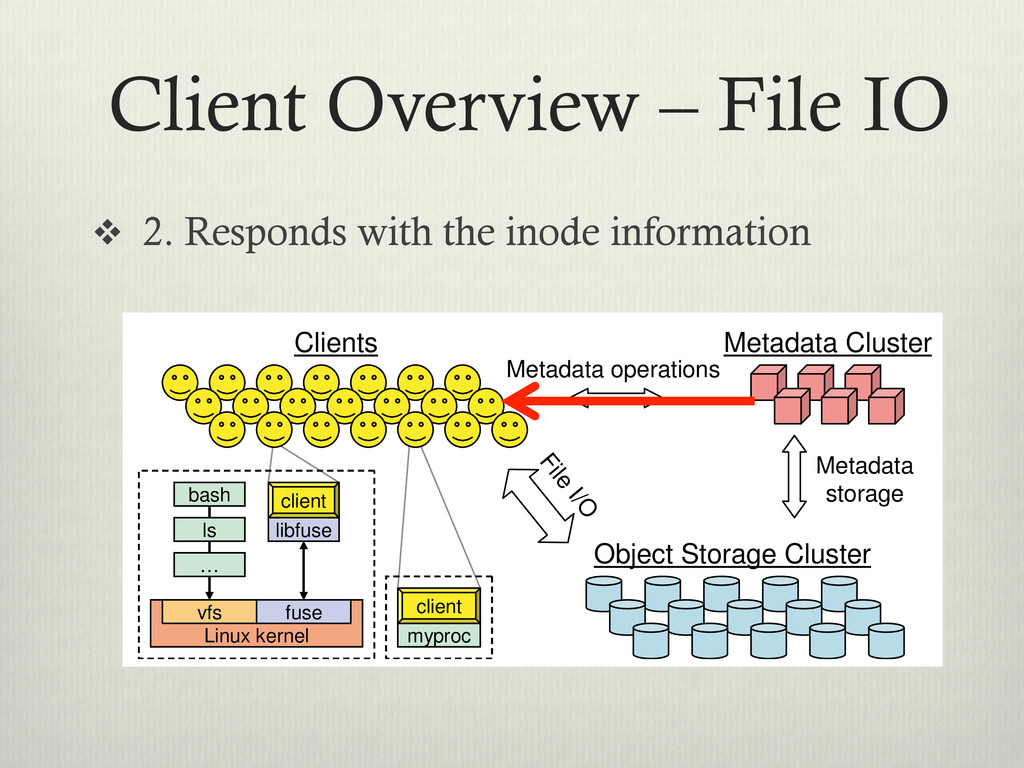
Client Overview – File IO v 2. Responds with the
inode information Metadata storage File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in -
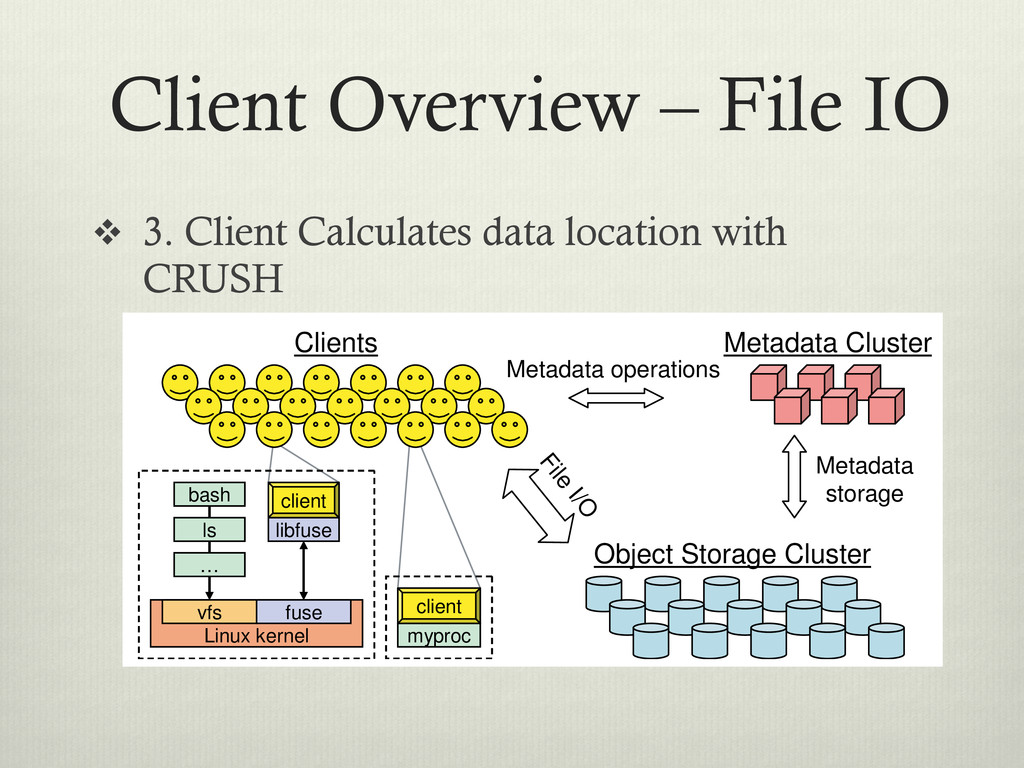
Client Overview – File IO v 3. Client Calculates data
location with CRUSH Metadata storage File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in -
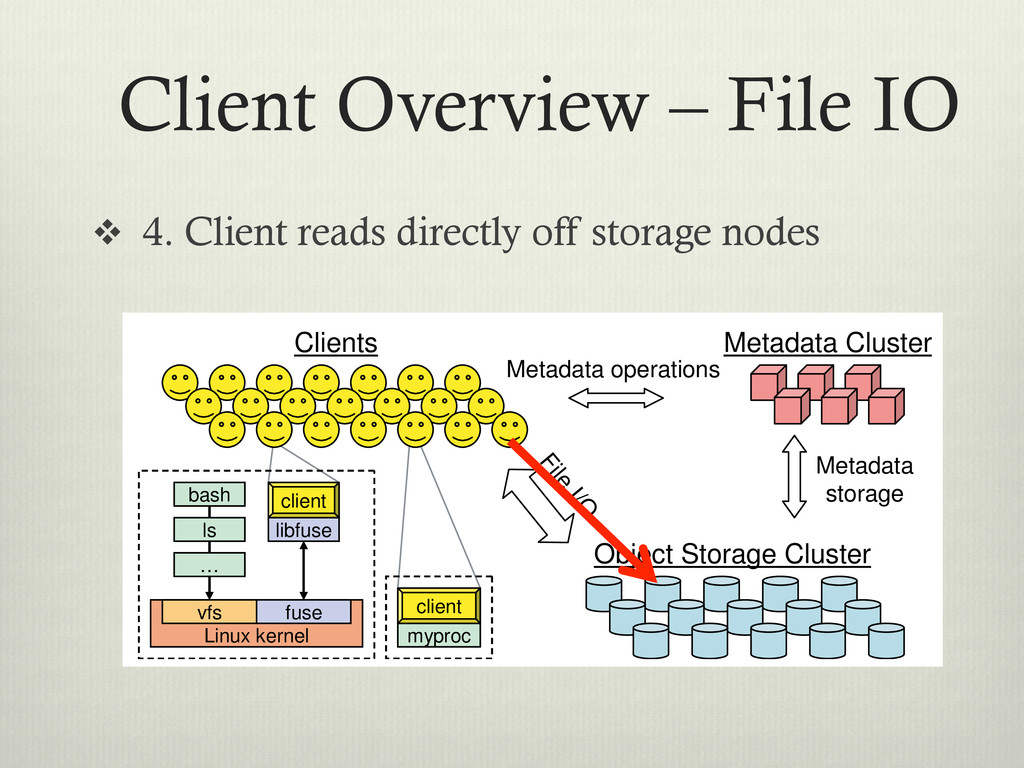
Client Overview – File IO v 4. Client reads directly
off storage nodes Metadata storage File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in -
Client Overview – File IO v Client asks MDS for
a small amount of information v Performance: Small bandwidth between client and MDS v Performance Small cache (memory) due to small data v Client calculates file location using function v Reliability: Saves the MDS from keeping block locations v Function described in data storage section -
Ceph Components v Ordered: Clients, Metadata, Object Storage Metadata storage
File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in 1 2 3 -
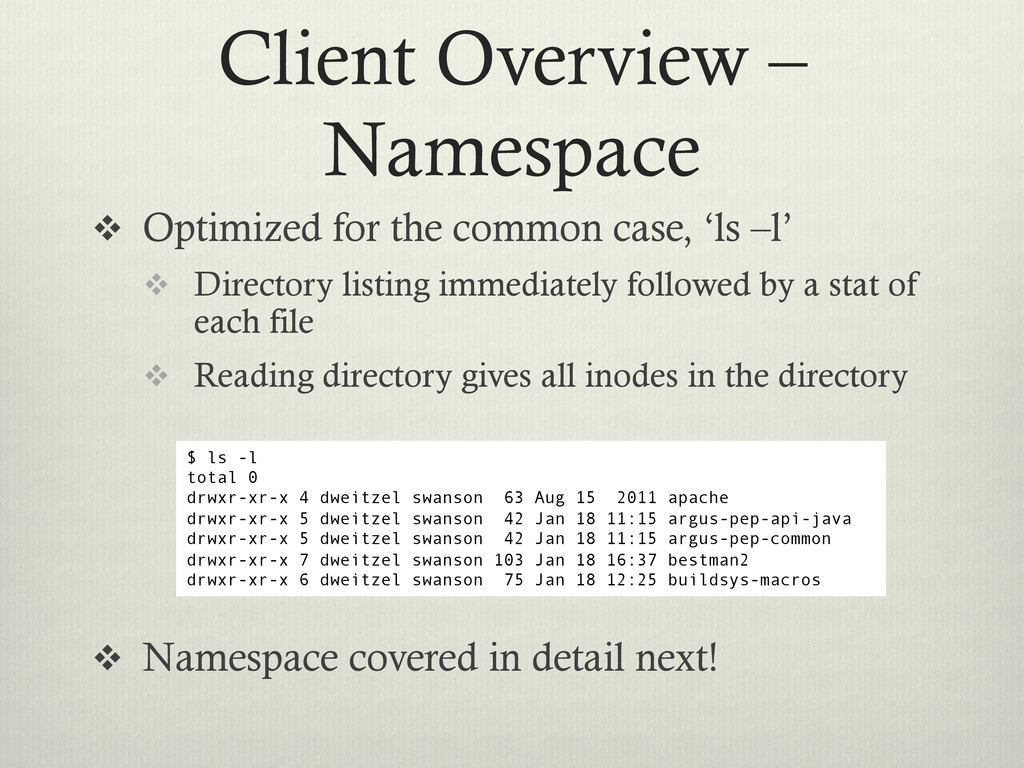
Client Overview – Namespace v Optimized for the common case,
‘ls –l’ v Directory listing immediately followed by a stat of each file v Reading directory gives all inodes in the directory v Namespace covered in detail next! $ ls -l total 0 drwxr-xr-x 4 dweitzel swanson 63 Aug 15 2011 apache drwxr-xr-x 5 dweitzel swanson 42 Jan 18 11:15 argus-pep-api-java drwxr-xr-x 5 dweitzel swanson 42 Jan 18 11:15 argus-pep-common drwxr-xr-x 7 dweitzel swanson 103 Jan 18 16:37 bestman2 drwxr-xr-x 6 dweitzel swanson 75 Jan 18 12:25 buildsys-macros -
Metadata Overview v Metadata servers (MDS) server out the file
system attributes and directory structure v Metadata is stored in the distributed filesystem beside the data v Compare this to Hadoop, where metadata is stored only on the head nodes v Updates are staged in a journal, flushed occasionally to the distributed file system -
MDS Subtree Partitioning v In HPC applications, it is common
to have ‘hot’ metadata that is needed by many clients v In order to be scalable, Ceph needs to distributed metadata requests among many servers v MDS will monitor frequency of queries using special counters v MDS will compare the counters with each other and split the directory tree to evenly split the load -
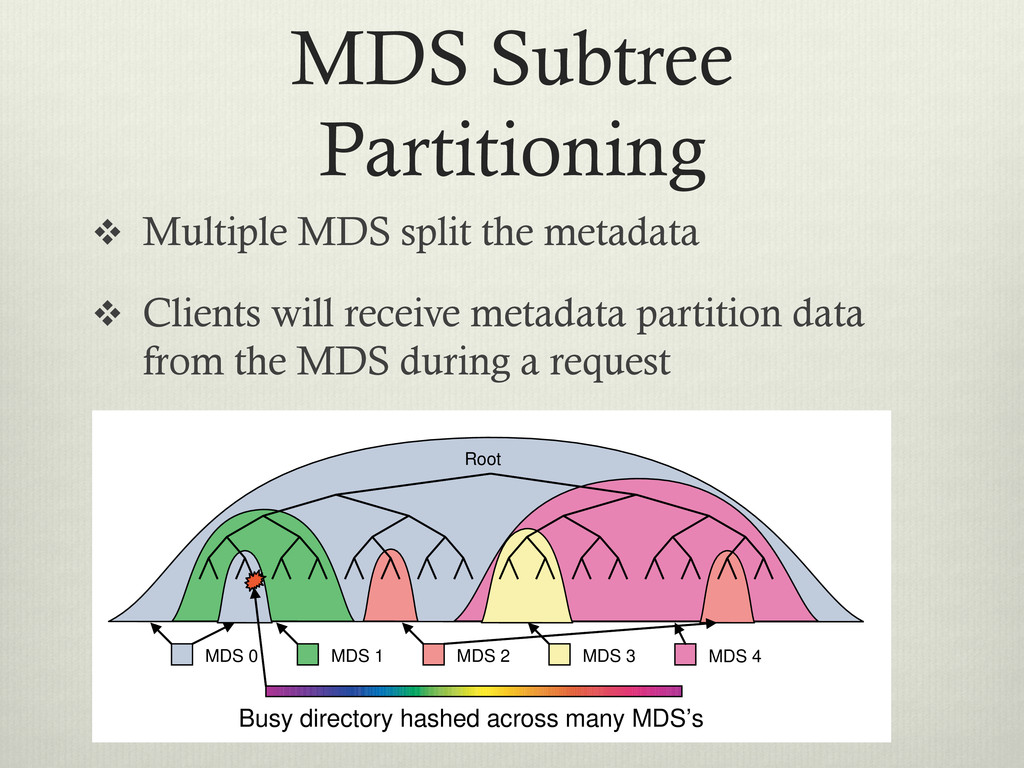
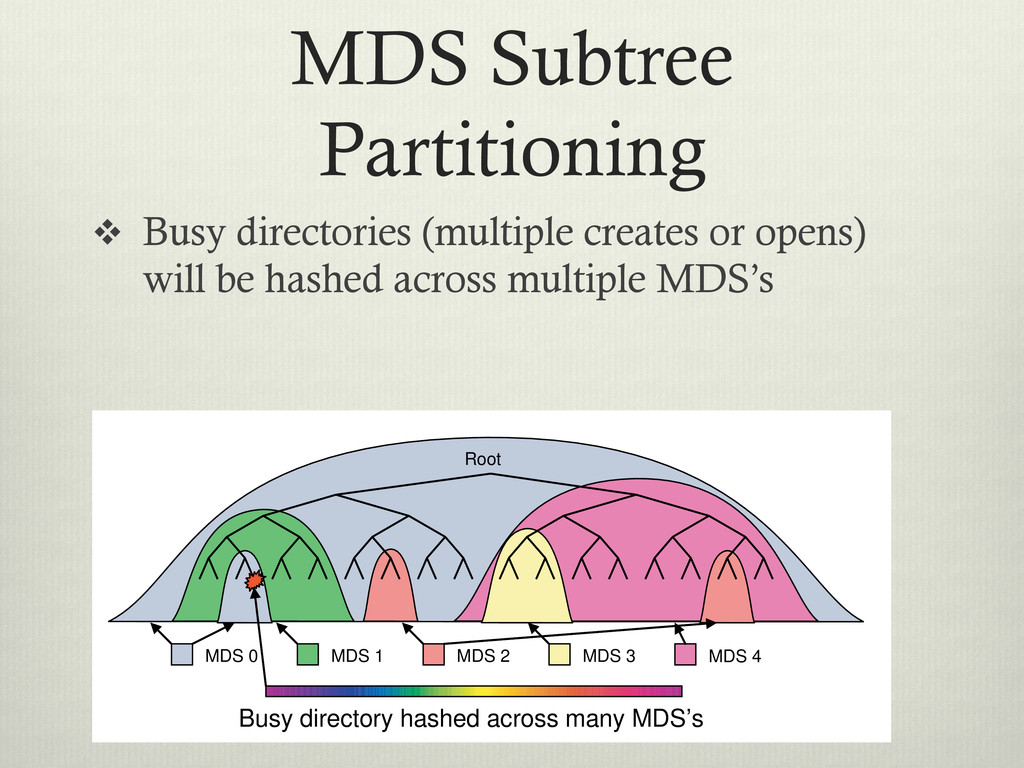
MDS Subtree Partitioning v Multiple MDS split the metadata v
Clients will receive metadata partition data from the MDS during a request Root MDS 0 MDS 4 MDS 1 MDS 2 MDS 3 Busy directory hashed across many MDS’s (owner, number change, pendent of state ferent a content for the -
MDS Subtree Partitioning v Busy directories (multiple creates or opens)
will be hashed across multiple MDS’s Root MDS 0 MDS 4 MDS 1 MDS 2 MDS 3 Busy directory hashed across many MDS’s (owner, number change, pendent of state ferent a content for the -
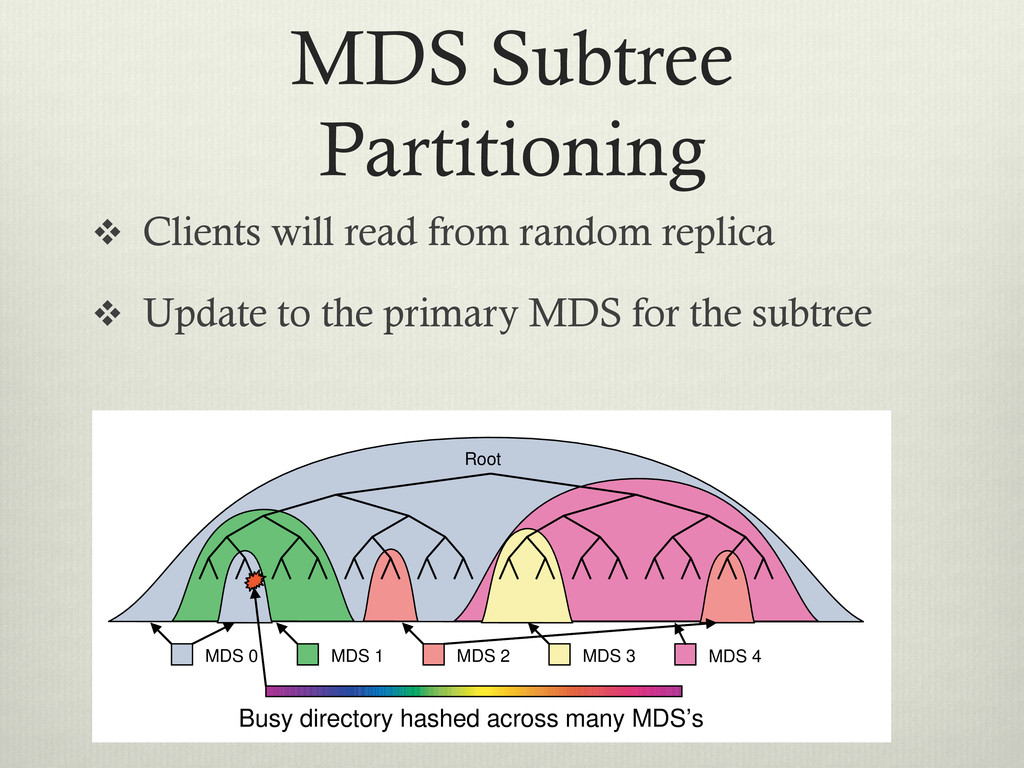
MDS Subtree Partitioning v Clients will read from random replica
v Update to the primary MDS for the subtree Root MDS 0 MDS 4 MDS 1 MDS 2 MDS 3 Busy directory hashed across many MDS’s (owner, number change, pendent of state ferent a content for the -
Ceph Components v Ordered: Clients, Metadata, Object Storage Metadata storage
File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in 1 2 3 -
Data Placement v Need a way to evenly distribute data
among storage devices (OSD) v Increased performance from even data distribution v Increased resiliency: Losing any node is minimally effects the status of the cluster if even distribution v Problem: Don’t want to keep data locations in the metadata servers v Requires lots of memory if lots of data blocks -
CRUSH v CRUSH is a pseudo-random function to find the
location of data in a distributed filesystem v Summary: Take a little information, plug into globally known function (hashing?) to find where the data is stored v Input data is: v inode number – From MDS v OSD Cluster Map (CRUSH map) – From OSD/ Monitors -
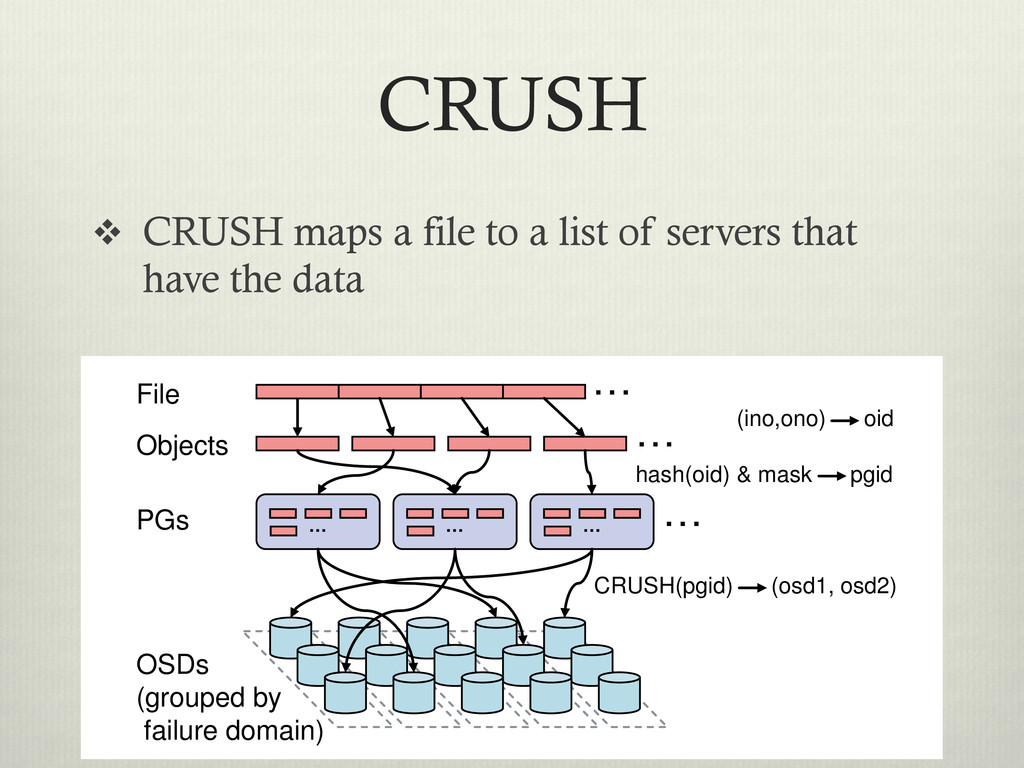
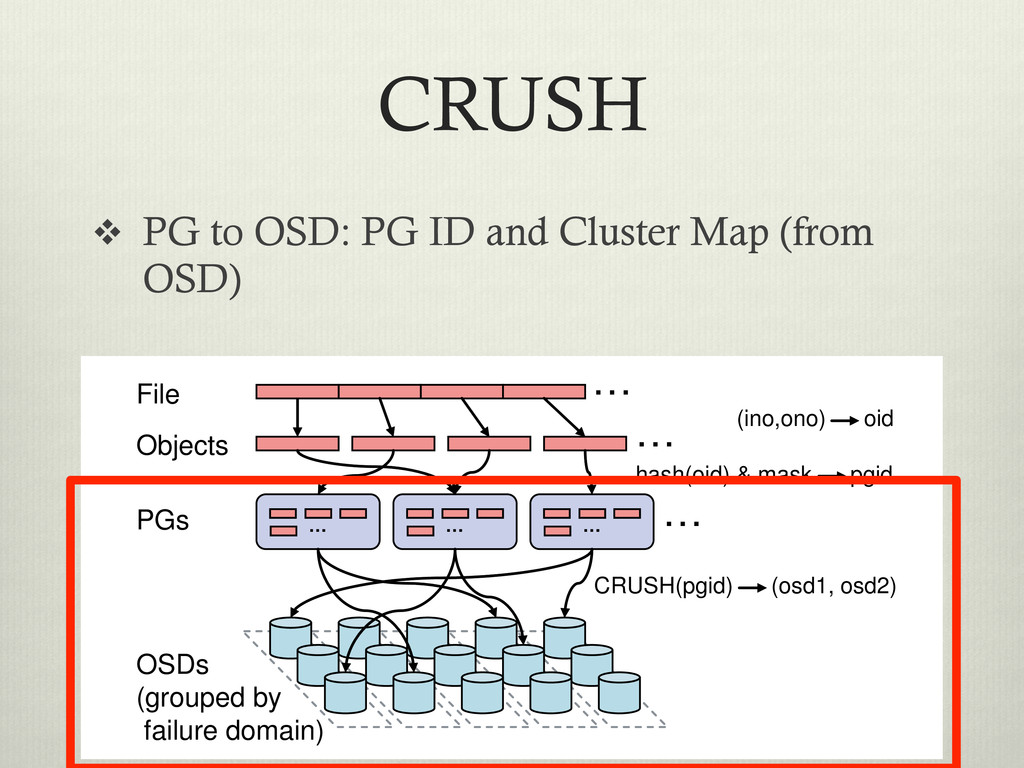
CRUSH v CRUSH maps a file to a list of
servers that have the data … … … … … … CRUSH(pgid) (osd1, osd2) OSDs (grouped by failure domain) File Objects hash(oid) & mask pgid PGs (ino,ono) oid to m u th so le fu c -
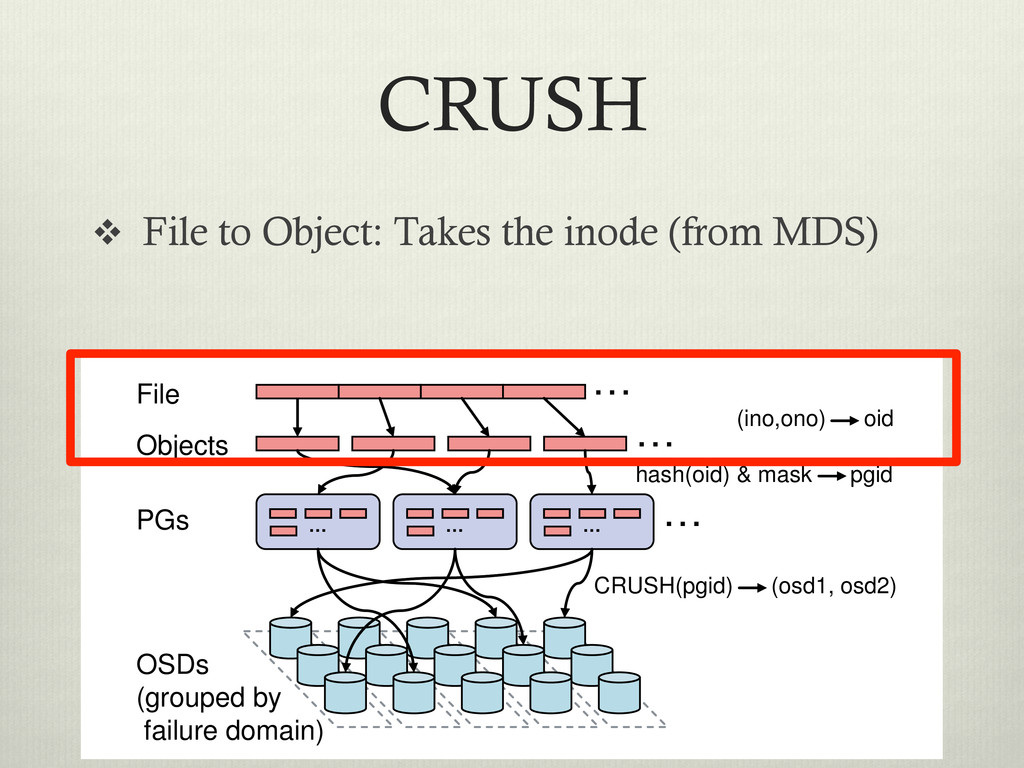
CRUSH v File to Object: Takes the inode (from MDS)
… … … … … … CRUSH(pgid) (osd1, osd2) OSDs (grouped by failure domain) File Objects hash(oid) & mask pgid PGs (ino,ono) oid to m u th so le fu c -
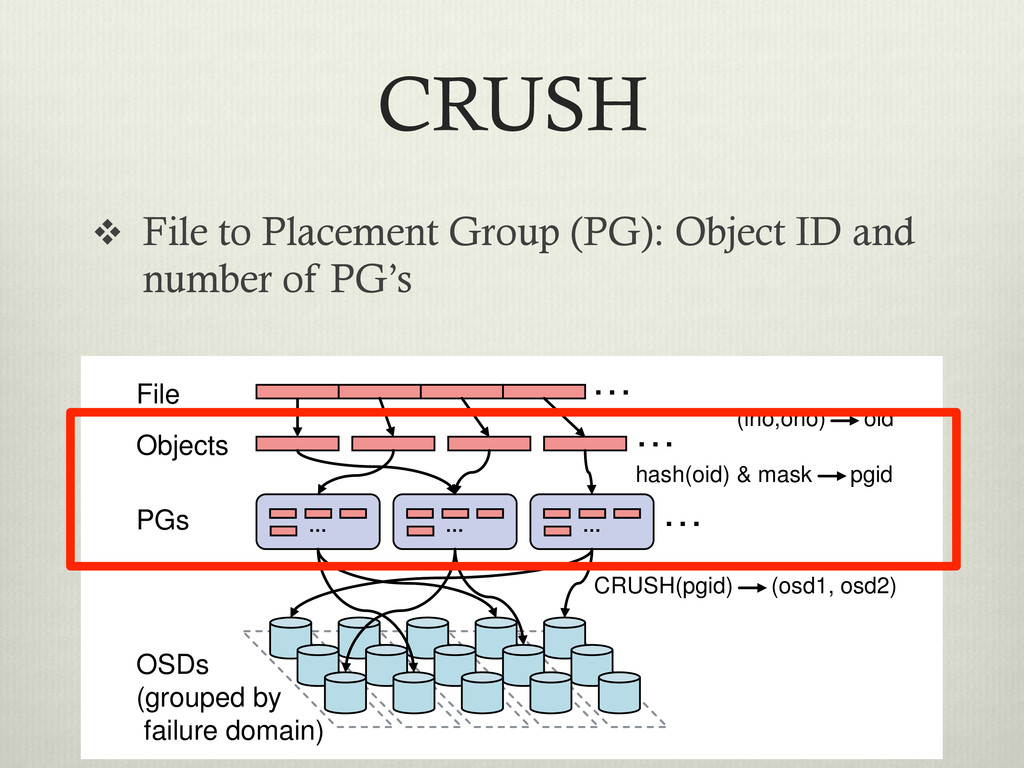
CRUSH v File to Placement Group (PG): Object ID and
number of PG’s … … … … … … CRUSH(pgid) (osd1, osd2) OSDs (grouped by failure domain) File Objects hash(oid) & mask pgid PGs (ino,ono) oid to m u th so le fu c -
Placement Group v Sets of OSDs that manage a subset
of the objects v OSD’s will have many Placement Groups v Placement Groups will have R OSD’s, where R is number of replicas v An OSD will either be a Primary or Replica v Primary is in charge of accepting modification requests for the Placement Group v Clients will write to Primary, read from random member of Placement Group -
CRUSH v PG to OSD: PG ID and Cluster Map
(from OSD) … … … … … … CRUSH(pgid) (osd1, osd2) OSDs (grouped by failure domain) File Objects hash(oid) & mask pgid PGs (ino,ono) oid to m u th so le fu c -
CRUSH v Now we know where to write the data
/ read the data v Now how do we safely handle replication and node failures? -
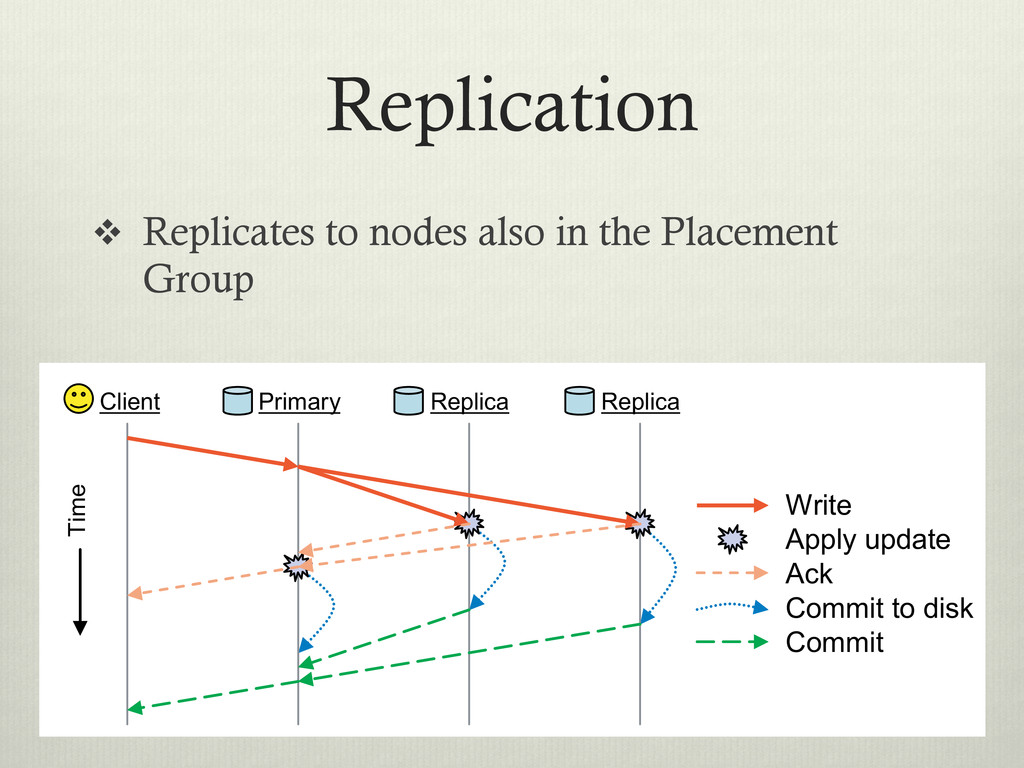
Replication v Replicates to nodes also in the Placement Group
Write Apply update Ack Commit to disk Commit Time Client Primary Replica Replica -
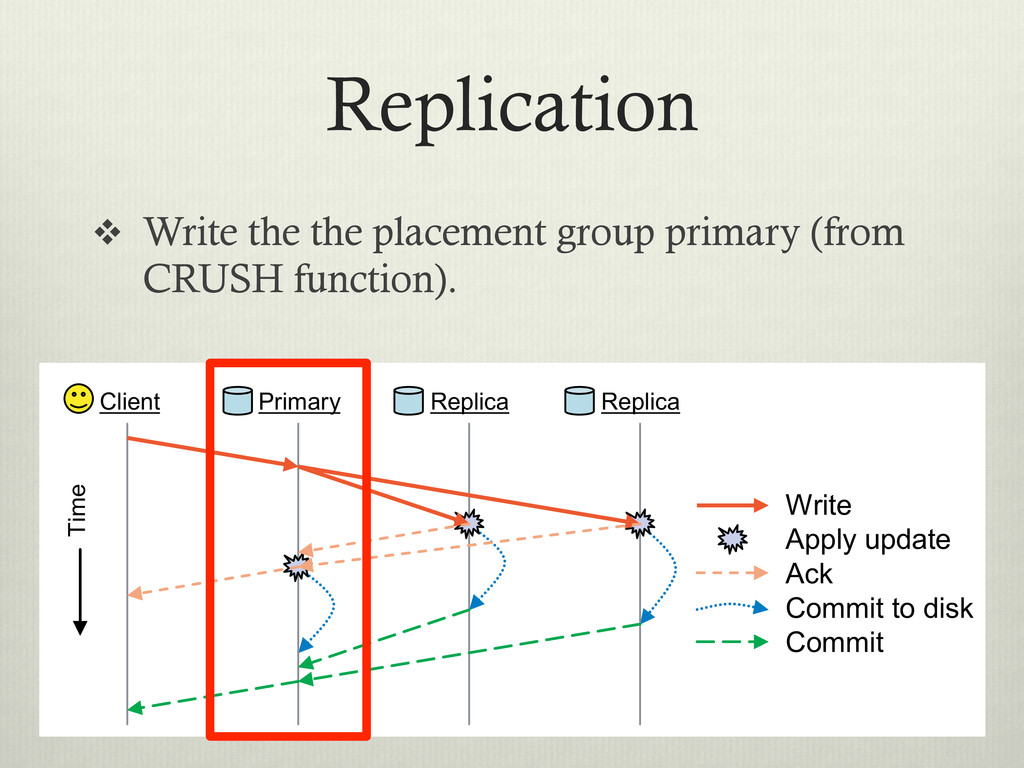
Replication v Write the the placement group primary (from CRUSH
function). Write Apply update Ack Commit to disk Commit Time Client Primary Replica Replica -
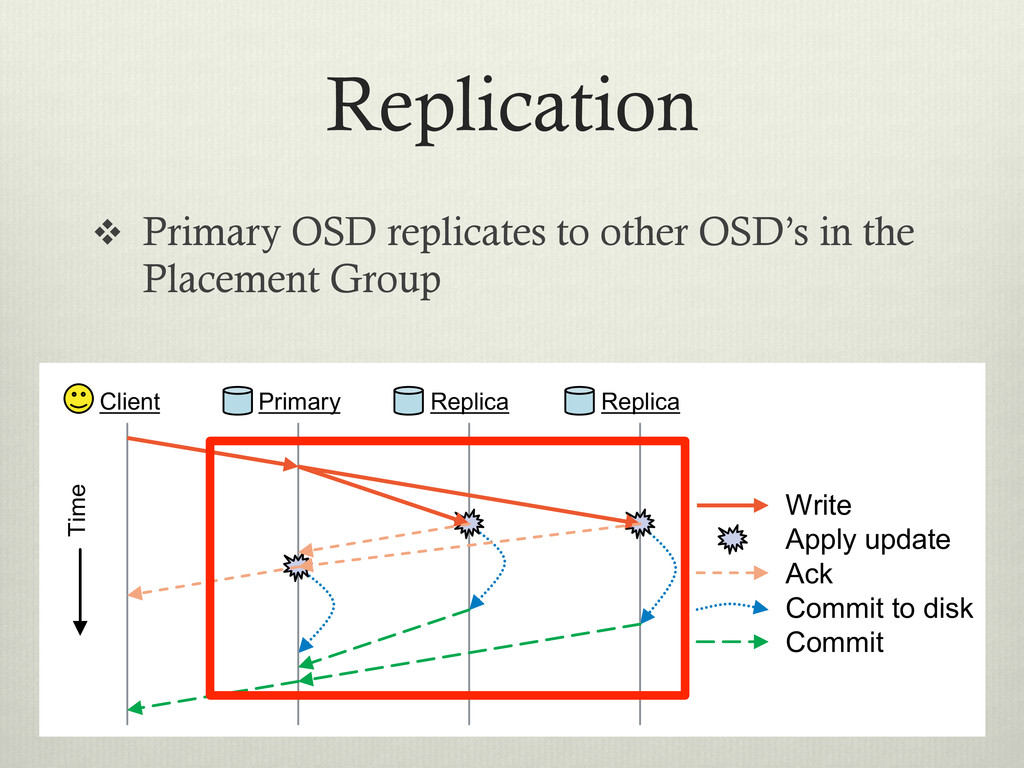
Replication v Primary OSD replicates to other OSD’s in the
Placement Group Write Apply update Ack Commit to disk Commit Time Client Primary Replica Replica -
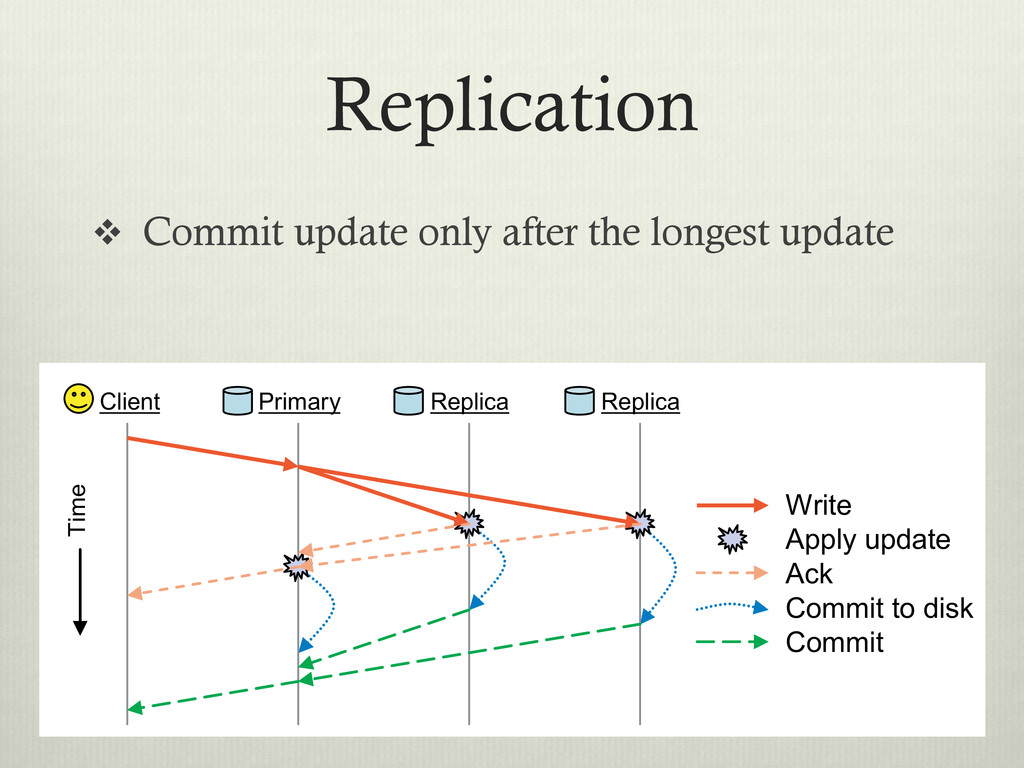
Replication v Commit update only after the longest update Write
Apply update Ack Commit to disk Commit Time Client Primary Replica Replica -
Failure Detection v Each Autonomic OSD looks after nodes in
it’s Placement Group (possible many!). v Monitors keep a cluster map (used in CRUSH) v Multiple monitors keep eye on cluster configuration, dole out cluster maps. -
Recovery & Updates v Recovery is entirely between OSDs v
OSD have two off modes, Down and Out. v Down is when the node could come back, Primary for a PG is handed off v Out is when a node will not come back, data is re- replicated. -
Recovery & Updates v Each object has a version number
v Upon bringing up, check version number of Placement Groups to see if current v Check version number of objects to see if need update -
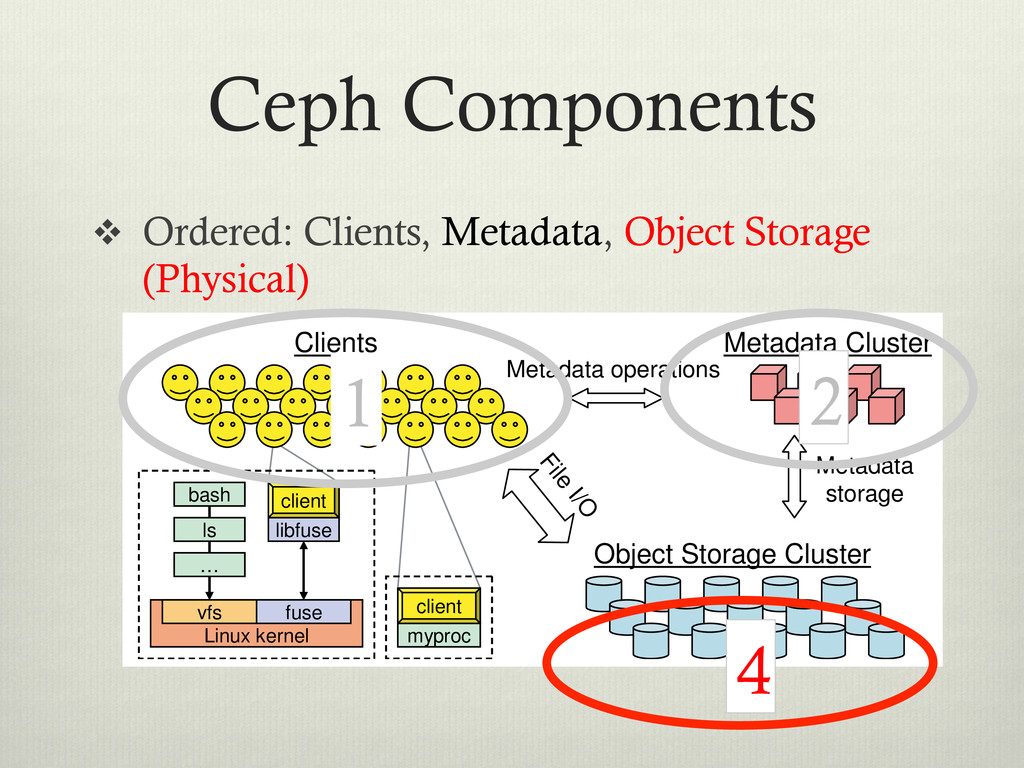
Ceph Components v Ordered: Clients, Metadata, Object Storage (Physical) Metadata
storage File I/O Metadata Cluster Object Storage Cluster client bash Linux kernel fuse vfs libfuse ls … client bash Linux kernel fuse vfs libfuse ls … myproc client myproc client Clients Metadata operations Figure 1: System architecture. Clients perform file I/O by communicating directly with OSDs. Each process can de vi ba bl ca di tri sto th in 1 2 4 -
Object Storage v The underlying filesystem can make or break
a distributed one v Filesystems have different characteristics v Example: RieserFS good at small files v XFS good at REALLY big files v Ceph keeps a lot of attributes on the inodes, needs a filesystem that can hanle attrs. -
Object Storage v Ceph can run on normal file systems,
but slow v XFS, ext3/4, … v Created own Filesystem in order to handle special object requirements of Ceph v EBOFS – Extent and B-Tree based Object File System. -
Object Storage v Important to note that development of EBOFS
has ceased v Though Ceph can run on any normal filesystem (I have it running on ext4) v Hugely recommend to run on BTRFS -
Object Storage - BTRFS v Fast Writes: Copy on write
file system for Linux v Great Performance: Supports small files with fast lookup using B-Tree algorithm v Ceph Requirement: Supports unlimited chaining of attributes v Integrated into mainline kernel 2.6.29 v Considered next generation file system v Peer of ZFS from Sun v Child of ext3/4 -
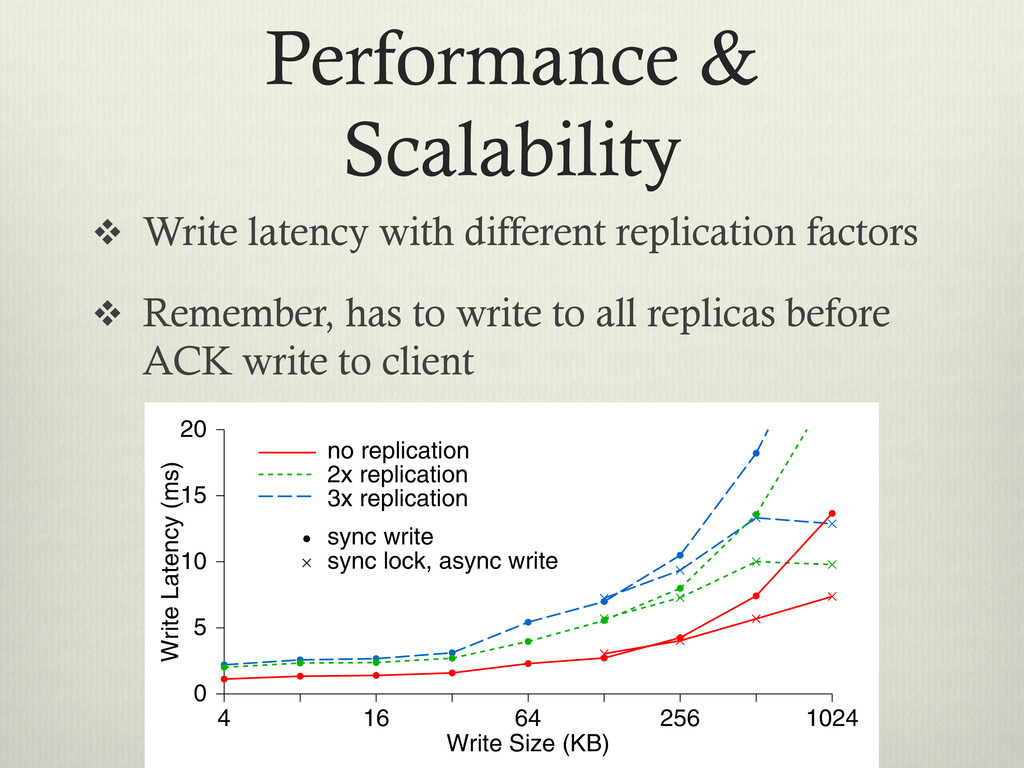
Performance & Scalability v Write latency with different replication factors
v Remember, has to write to all replicas before ACK write to client 4096 lication ication ication Write Size (KB) 4 16 64 256 1024 Write Latency (ms) 0 5 10 15 20 no replication 2x replication 3x replication sync write sync lock, async write -
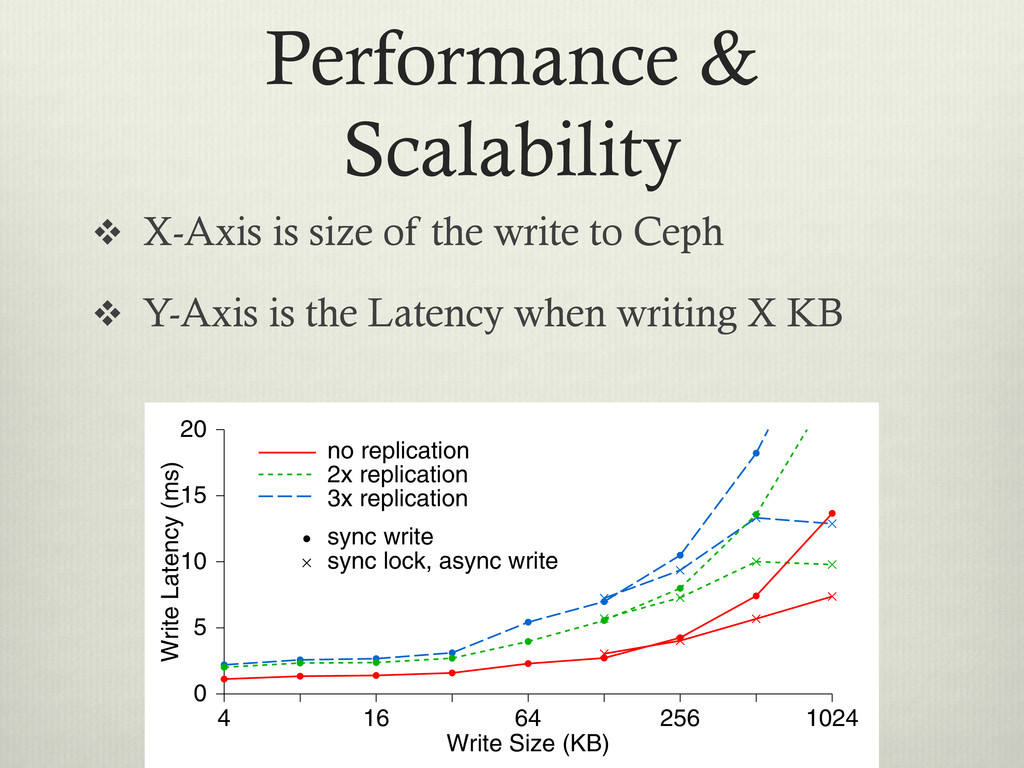
Performance & Scalability v X-Axis is size of the write
to Ceph v Y-Axis is the Latency when writing X KB 4096 lication ication ication Write Size (KB) 4 16 64 256 1024 Write Latency (ms) 0 5 10 15 20 no replication 2x replication 3x replication sync write sync lock, async write -
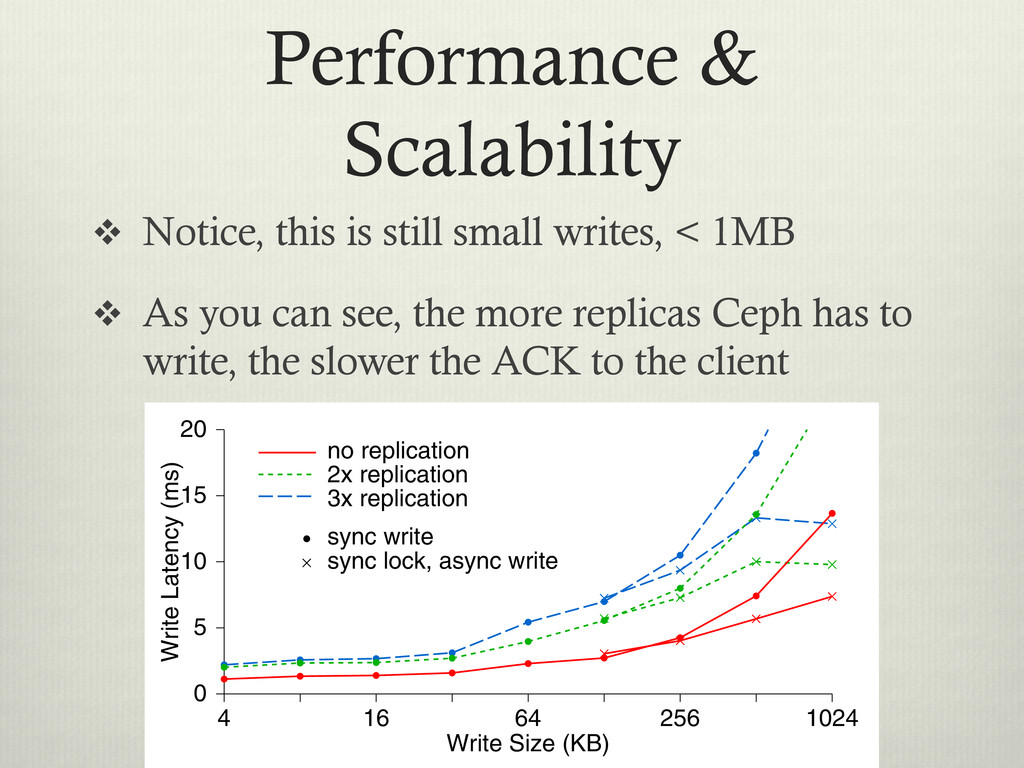
Performance & Scalability v Notice, this is still small writes,
< 1MB v As you can see, the more replicas Ceph has to write, the slower the ACK to the client 4096 lication ication ication Write Size (KB) 4 16 64 256 1024 Write Latency (ms) 0 5 10 15 20 no replication 2x replication 3x replication sync write sync lock, async write -
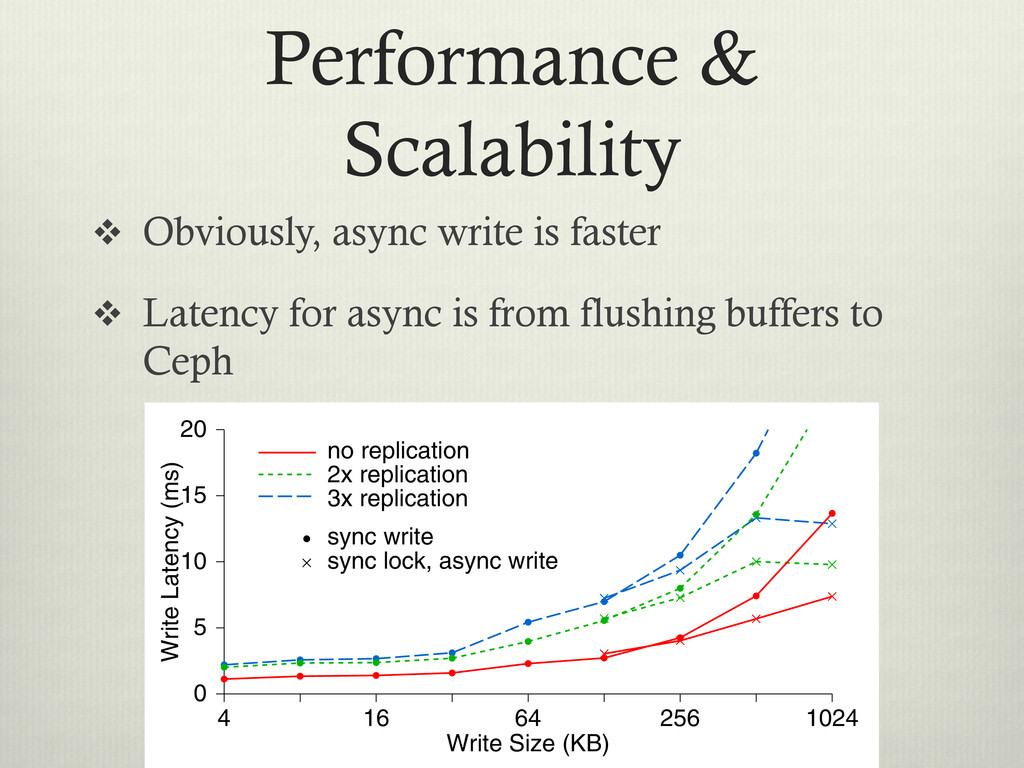
Performance & Scalability v Obviously, async write is faster v
Latency for async is from flushing buffers to Ceph 4096 lication ication ication Write Size (KB) 4 16 64 256 1024 Write Latency (ms) 0 5 10 15 20 no replication 2x replication 3x replication sync write sync lock, async write -
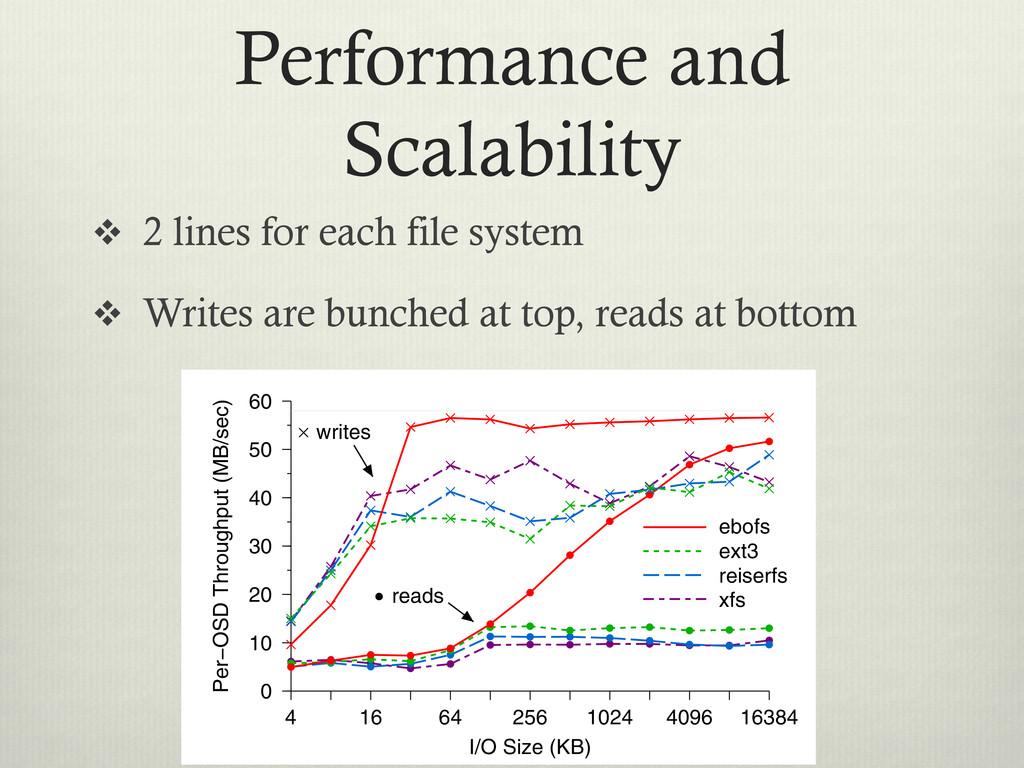
Performance and Scalability v 2 lines for each file system
v Writes are bunched at top, reads at bottom Write Size (KB) 4 16 64 256 1024 4096 Per− 0 10 2x replication 3x replication Figure 5: Per-OSD write performance. The horizontal line indicates the upper limit imposed by the physical disk. Replication has minimal impact on OSD through- put, although if the number of OSDs is fixed, n-way replication reduces total effective throughput by a factor of n because replicated data must be written to n OSDs. I/O Size (KB) 4 16 64 256 1024 4096 16384 Per−OSD Throughput (MB/sec) 0 10 20 30 40 50 60 ebofs ext3 reiserfs xfs reads writes 4 Write 0 5 Figure 7: Write cation. More th cost for small concurrently. F sion times dom for writes over asynchronously 2 Per−OSD Throughput (MB/sec) 30 40 50 60 Figure 8: OSD -
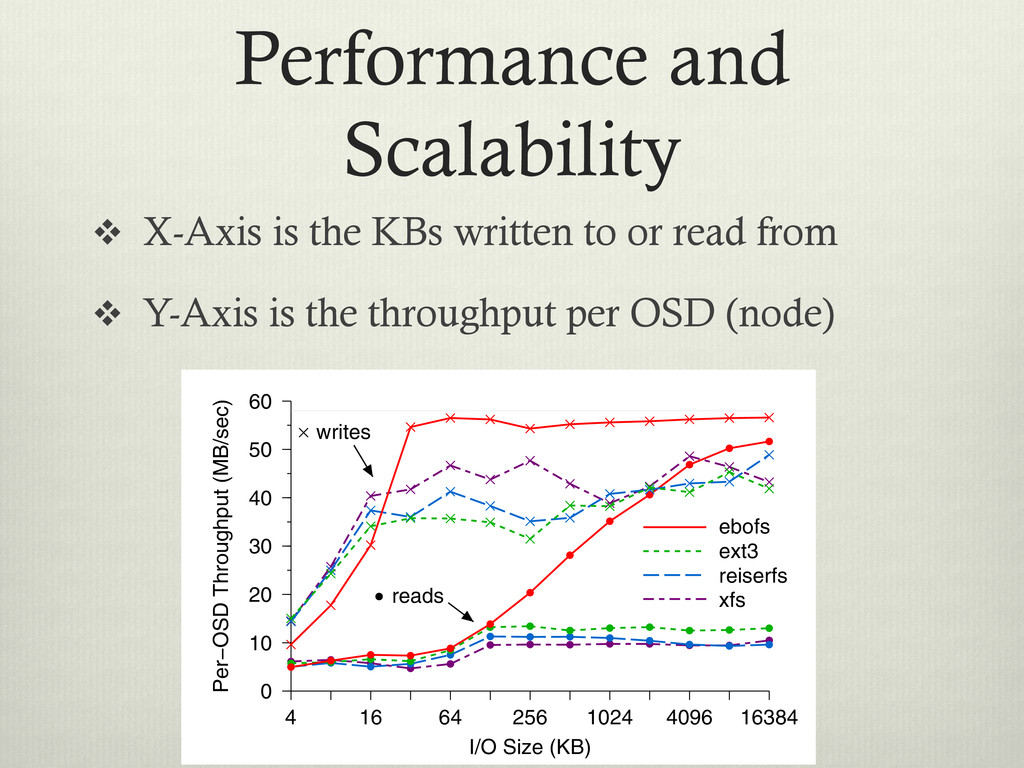
Performance and Scalability v X-Axis is the KBs written to
or read from v Y-Axis is the throughput per OSD (node) Write Size (KB) 4 16 64 256 1024 4096 Per− 0 10 2x replication 3x replication Figure 5: Per-OSD write performance. The horizontal line indicates the upper limit imposed by the physical disk. Replication has minimal impact on OSD through- put, although if the number of OSDs is fixed, n-way replication reduces total effective throughput by a factor of n because replicated data must be written to n OSDs. I/O Size (KB) 4 16 64 256 1024 4096 16384 Per−OSD Throughput (MB/sec) 0 10 20 30 40 50 60 ebofs ext3 reiserfs xfs reads writes 4 Write 0 5 Figure 7: Write cation. More th cost for small concurrently. F sion times dom for writes over asynchronously 2 Per−OSD Throughput (MB/sec) 30 40 50 60 Figure 8: OSD -
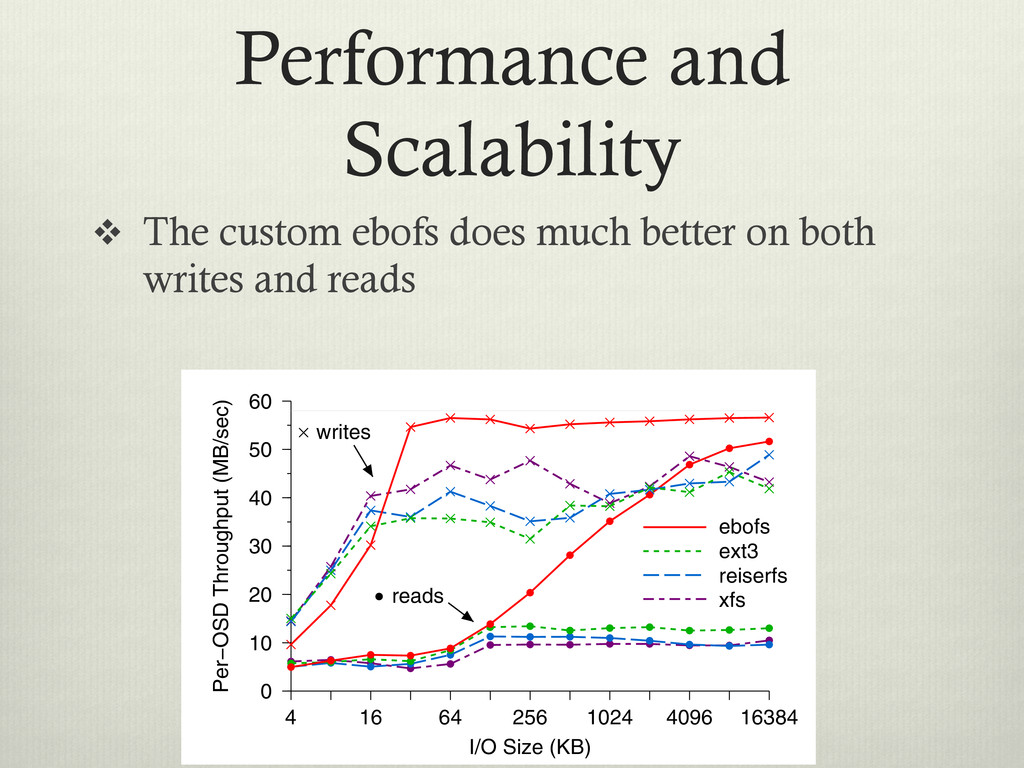
Performance and Scalability v The custom ebofs does much better
on both writes and reads Write Size (KB) 4 16 64 256 1024 4096 Per− 0 10 2x replication 3x replication Figure 5: Per-OSD write performance. The horizontal line indicates the upper limit imposed by the physical disk. Replication has minimal impact on OSD through- put, although if the number of OSDs is fixed, n-way replication reduces total effective throughput by a factor of n because replicated data must be written to n OSDs. I/O Size (KB) 4 16 64 256 1024 4096 16384 Per−OSD Throughput (MB/sec) 0 10 20 30 40 50 60 ebofs ext3 reiserfs xfs reads writes 4 Write 0 5 Figure 7: Write cation. More th cost for small concurrently. F sion times dom for writes over asynchronously 2 Per−OSD Throughput (MB/sec) 30 40 50 60 Figure 8: OSD -
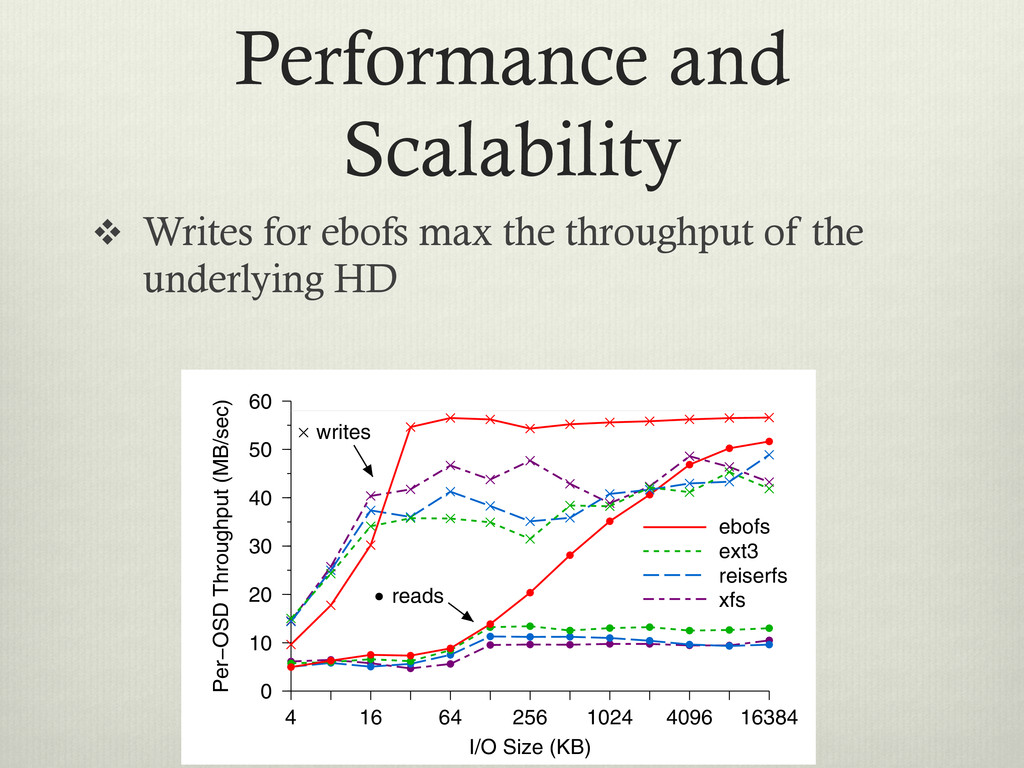
Performance and Scalability v Writes for ebofs max the throughput
of the underlying HD Write Size (KB) 4 16 64 256 1024 4096 Per− 0 10 2x replication 3x replication Figure 5: Per-OSD write performance. The horizontal line indicates the upper limit imposed by the physical disk. Replication has minimal impact on OSD through- put, although if the number of OSDs is fixed, n-way replication reduces total effective throughput by a factor of n because replicated data must be written to n OSDs. I/O Size (KB) 4 16 64 256 1024 4096 16384 Per−OSD Throughput (MB/sec) 0 10 20 30 40 50 60 ebofs ext3 reiserfs xfs reads writes 4 Write 0 5 Figure 7: Write cation. More th cost for small concurrently. F sion times dom for writes over asynchronously 2 Per−OSD Throughput (MB/sec) 30 40 50 60 Figure 8: OSD -
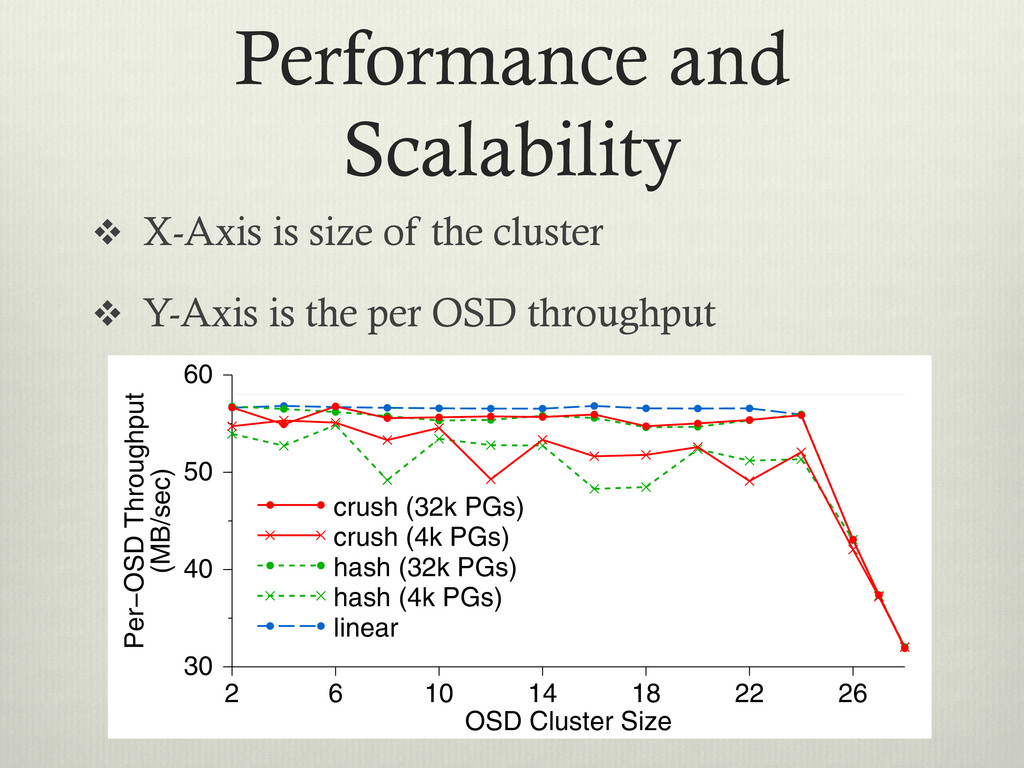
Performance and Scalability v X-Axis is size of the cluster
v Y-Axis is the per OSD throughput ical gh- way ctor Ds. 384 fs cation. More than two replicas incurs minimal additional cost for small writes because replicated updates occur concurrently. For large synchronous writes, transmis- sion times dominate. Clients partially mask that latency for writes over 128 KB by acquiring exclusive locks and asynchronously flushing the data. OSD Cluster Size 2 6 10 14 18 22 26 Per−OSD Throughput (MB/sec) 30 40 50 60 crush (32k PGs) crush (4k PGs) hash (32k PGs) hash (4k PGs) linear -
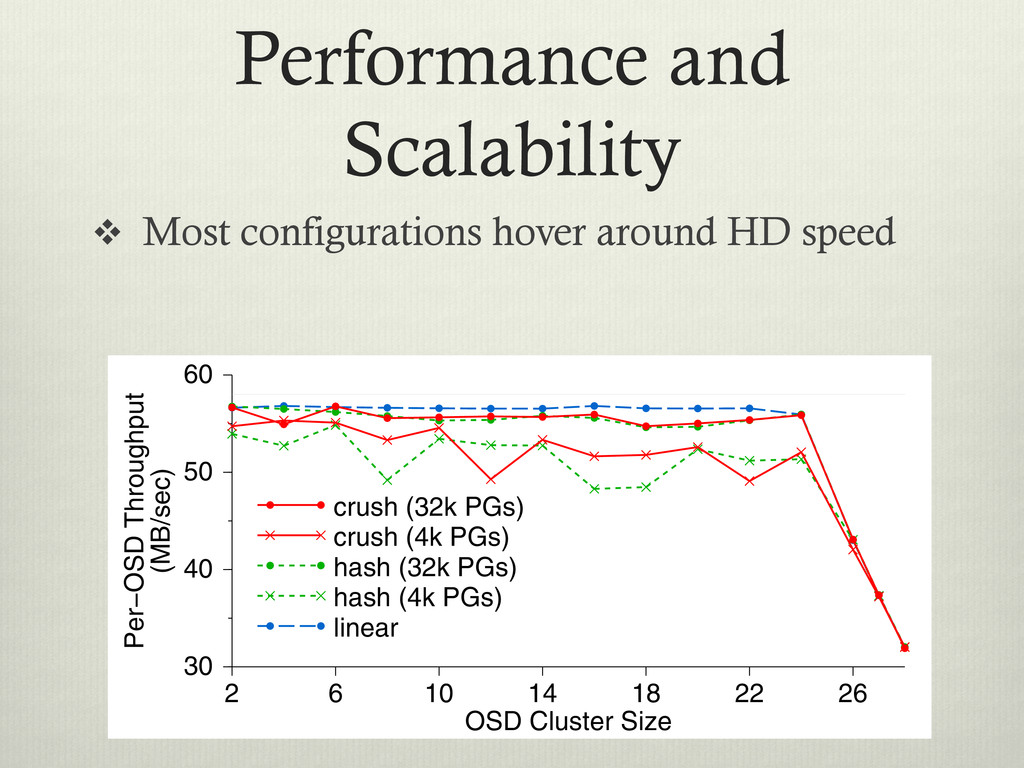
Performance and Scalability v Most configurations hover around HD speed
ical gh- way ctor Ds. 384 fs cation. More than two replicas incurs minimal additional cost for small writes because replicated updates occur concurrently. For large synchronous writes, transmis- sion times dominate. Clients partially mask that latency for writes over 128 KB by acquiring exclusive locks and asynchronously flushing the data. OSD Cluster Size 2 6 10 14 18 22 26 Per−OSD Throughput (MB/sec) 30 40 50 60 crush (32k PGs) crush (4k PGs) hash (32k PGs) hash (4k PGs) linear -
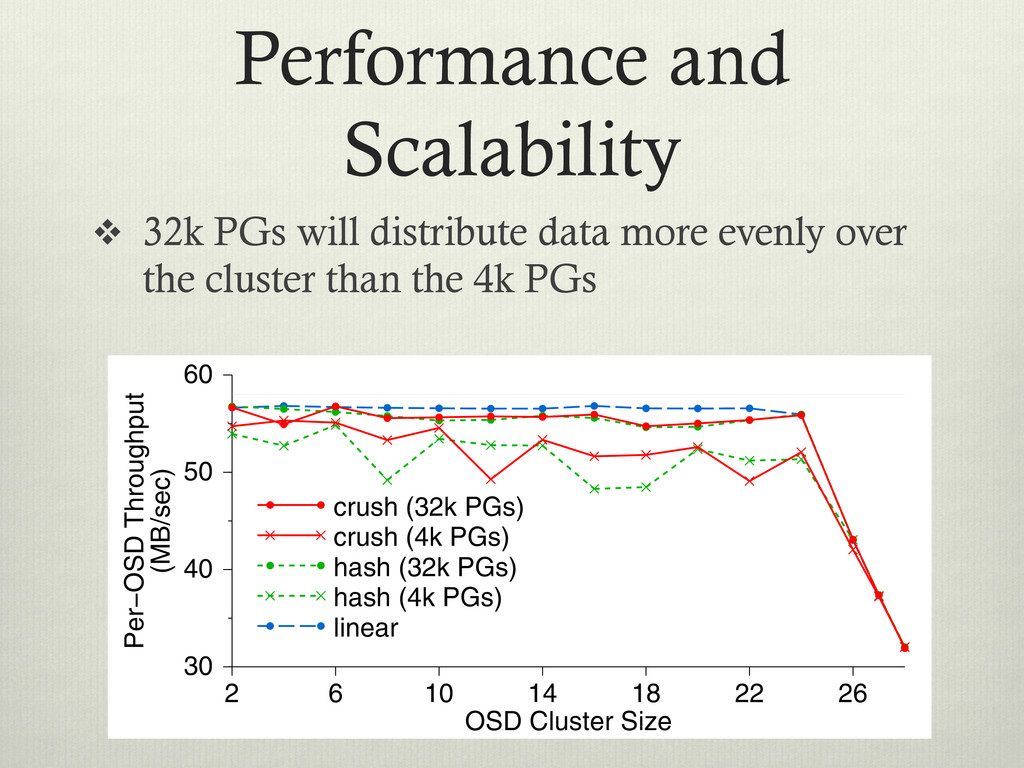
Performance and Scalability v 32k PGs will distribute data more
evenly over the cluster than the 4k PGs ical gh- way ctor Ds. 384 fs cation. More than two replicas incurs minimal additional cost for small writes because replicated updates occur concurrently. For large synchronous writes, transmis- sion times dominate. Clients partially mask that latency for writes over 128 KB by acquiring exclusive locks and asynchronously flushing the data. OSD Cluster Size 2 6 10 14 18 22 26 Per−OSD Throughput (MB/sec) 30 40 50 60 crush (32k PGs) crush (4k PGs) hash (32k PGs) hash (4k PGs) linear -
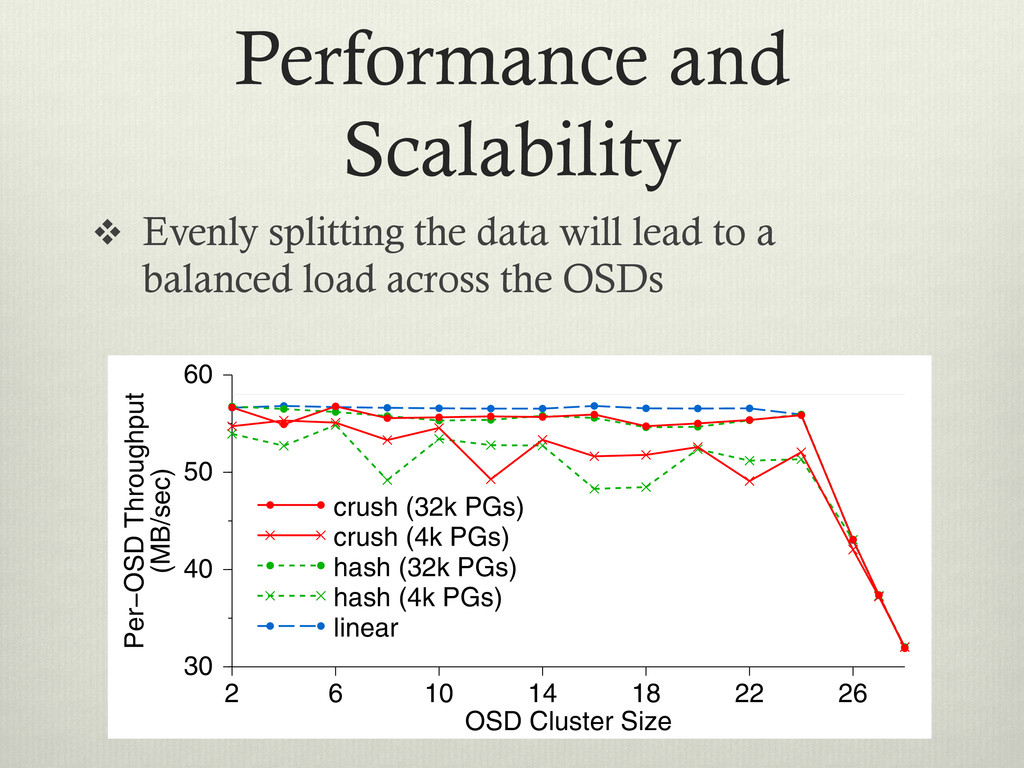
Performance and Scalability v Evenly splitting the data will lead
to a balanced load across the OSDs ical gh- way ctor Ds. 384 fs cation. More than two replicas incurs minimal additional cost for small writes because replicated updates occur concurrently. For large synchronous writes, transmis- sion times dominate. Clients partially mask that latency for writes over 128 KB by acquiring exclusive locks and asynchronously flushing the data. OSD Cluster Size 2 6 10 14 18 22 26 Per−OSD Throughput (MB/sec) 30 40 50 60 crush (32k PGs) crush (4k PGs) hash (32k PGs) hash (4k PGs) linear -
Conclusions v Very fast POSIX compliant file system v General
enough for many applications v No single point of failure – Important for large data centers v Can handle HPC like applications (lots of metadata, small files) -
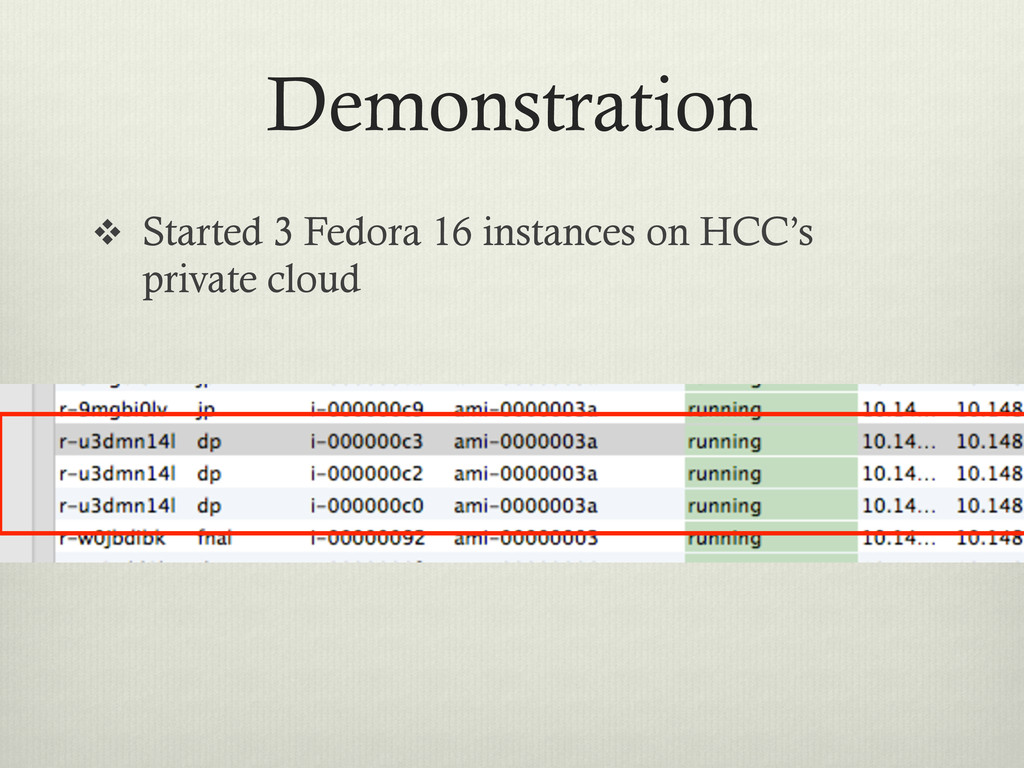
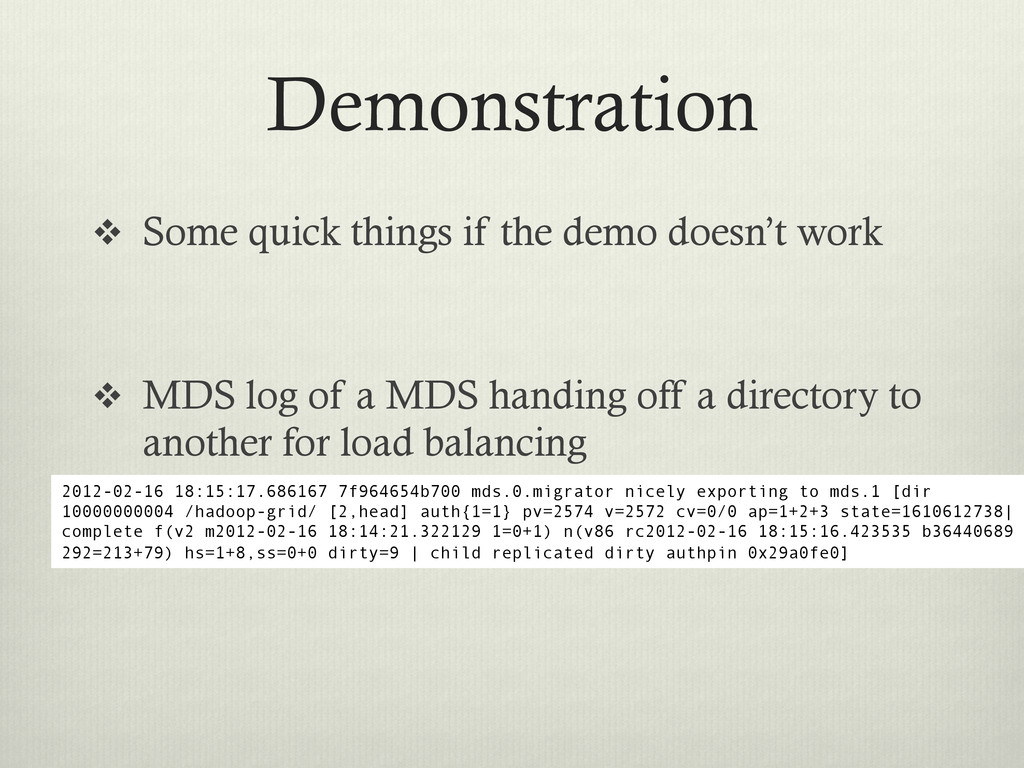
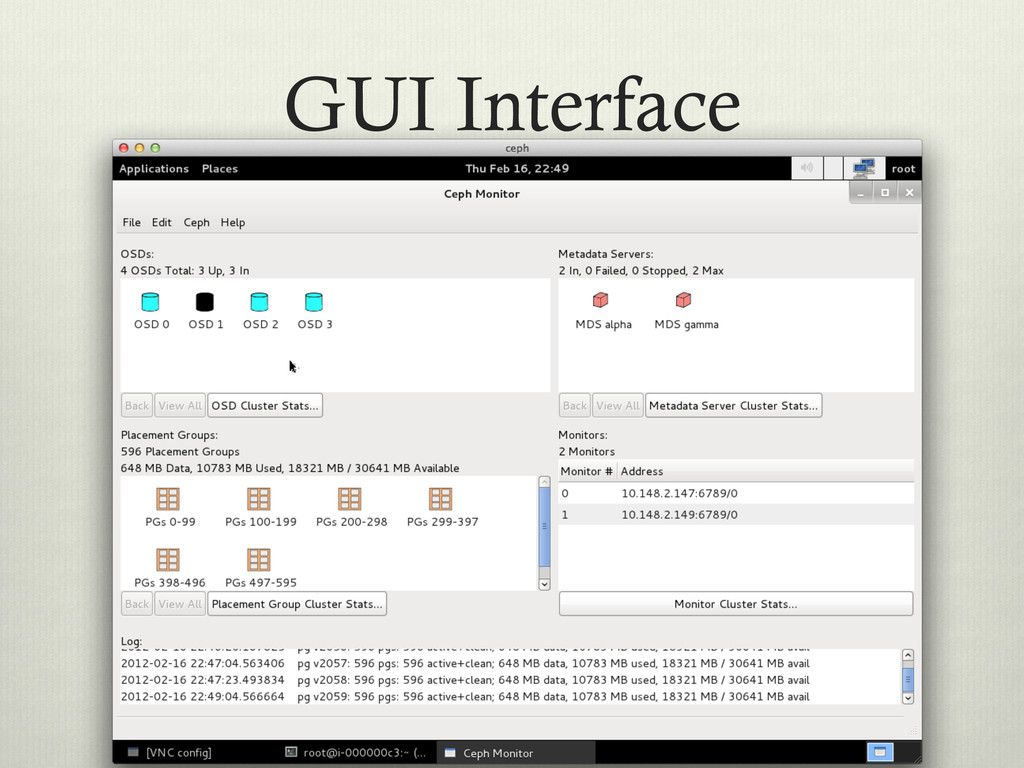
Demonstration v Some quick things if the demo doesn’t work
v MDS log of a MDS handing off a directory to another for load balancing 2012-02-16 18:15:17.686167 7f964654b700 mds.0.migrator nicely exporting to mds.1 [dir 10000000004 /hadoop-grid/ [2,head] auth{1=1} pv=2574 v=2572 cv=0/0 ap=1+2+3 state=1610612738| complete f(v2 m2012-02-16 18:14:21.322129 1=0+1) n(v86 rc2012-02-16 18:15:16.423535 b36440689 292=213+79) hs=1+8,ss=0+0 dirty=9 | child replicated dirty authpin 0x29a0fe0] -
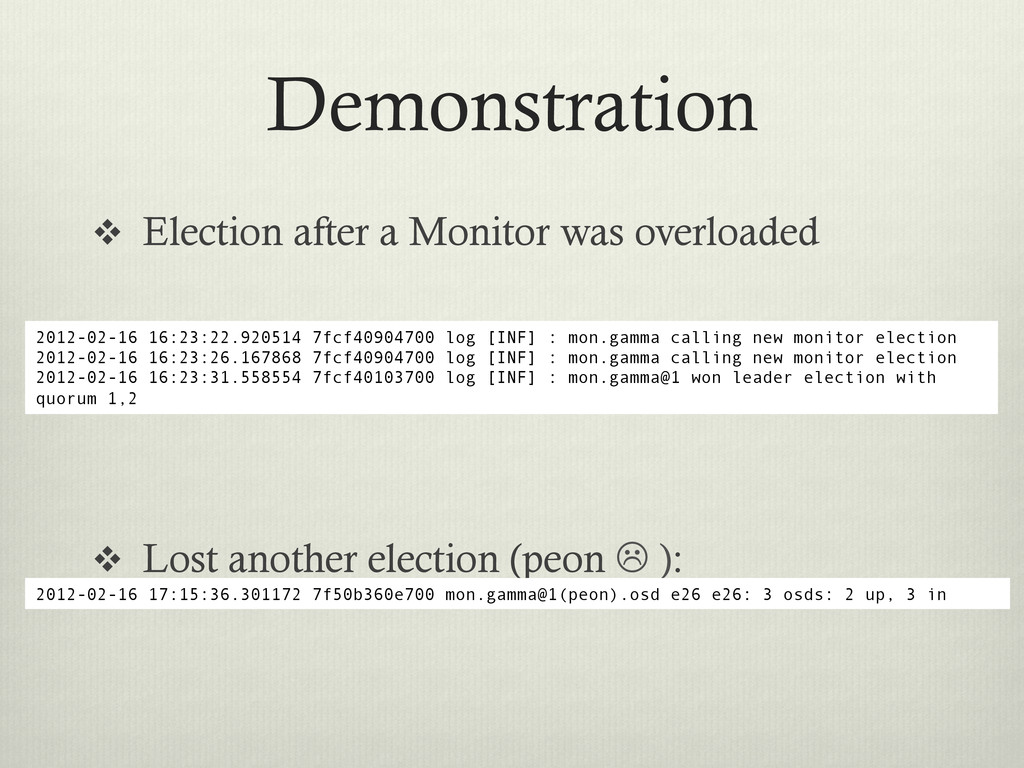
Demonstration v Election after a Monitor was overloaded v Lost
another election (peon L ): 2012-02-16 16:23:22.920514 7fcf40904700 log [INF] : mon.gamma calling new monitor election 2012-02-16 16:23:26.167868 7fcf40904700 log [INF] : mon.gamma calling new monitor election 2012-02-16 16:23:31.558554 7fcf40103700 log [INF] : mon.gamma@1 won leader election with quorum 1,2 2012-02-16 17:15:36.301172 7f50b360e700 mon.gamma@1(peon).osd e26 e26: 3 osds: 2 up, 3 in -
Where to Find More Info v New company sponsoring development
v http://ceph.newdream.net/ v Instruction on setting up CEPH can be found on the Ceph wiki: v http://ceph.newdream.net/wiki/ v Or my blog v http://derekweitzel.blogspot.com/
 ota1022
 torounit
 sue445
 yappli_developers
 tkito
 minorun365
 butadora
 a_suenami
 orimanabu
 sansantech
 biwashi
 ivry_presentationmaterials
 addyosmani
 skipperchong
 jmmastey
 thekraken
 rkendrick25
 jacobtomlinson
 ryanjones
 tmiket
 carmenintech
 katiecoart
 bluesmoon
 mclloyd