Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Антон Шишкин, Иван Комаров: Ускорение программ ...
Search
ekbcpp
November 14, 2013
270
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Антон Шишкин, Иван Комаров: Ускорение программ с помощью SIMD-операций
ekbcpp
November 14, 2013
More Decks by ekbcpp
See All by ekbcpp
Петр Манохин: Приемы event driven programming на C++
ekbcpp
0
720
Александр Лившиц: Управление динамической памятью в С/С++
ekbcpp
0
280
Featured
See All Featured
Measuring Dark Social's Impact On Conversion and Attribution
stephenakadiri
2
310
Heart Work Chapter 1 - Part 1
lfama
PRO
10
37k
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
520
VelocityConf: Rendering Performance Case Studies
addyosmani
331
25k
Making the Leap to Tech Lead
cromwellryan
135
10k
JavaScript: Past, Present, and Future - NDC Porto 2020
reverentgeek
52
6.1k
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3k
brightonSEO & MeasureFest 2025 - Winning Strategies for Black Friday CRO & PPC - Christian Goodrich
cargoodrich
3
870
Impact Scores and Hybrid Strategies: The future of link building
tamaranovitovic
0
460
Balancing Empowerment & Direction
lara
6
1.3k
Hiding What from Whom? A Critical Review of the History of Programming languages for Music
tomoyanonymous
3
1.4k
Claude Code のすすめ
schroneko
67
230k
Transcript
None
None
None
None
None
None
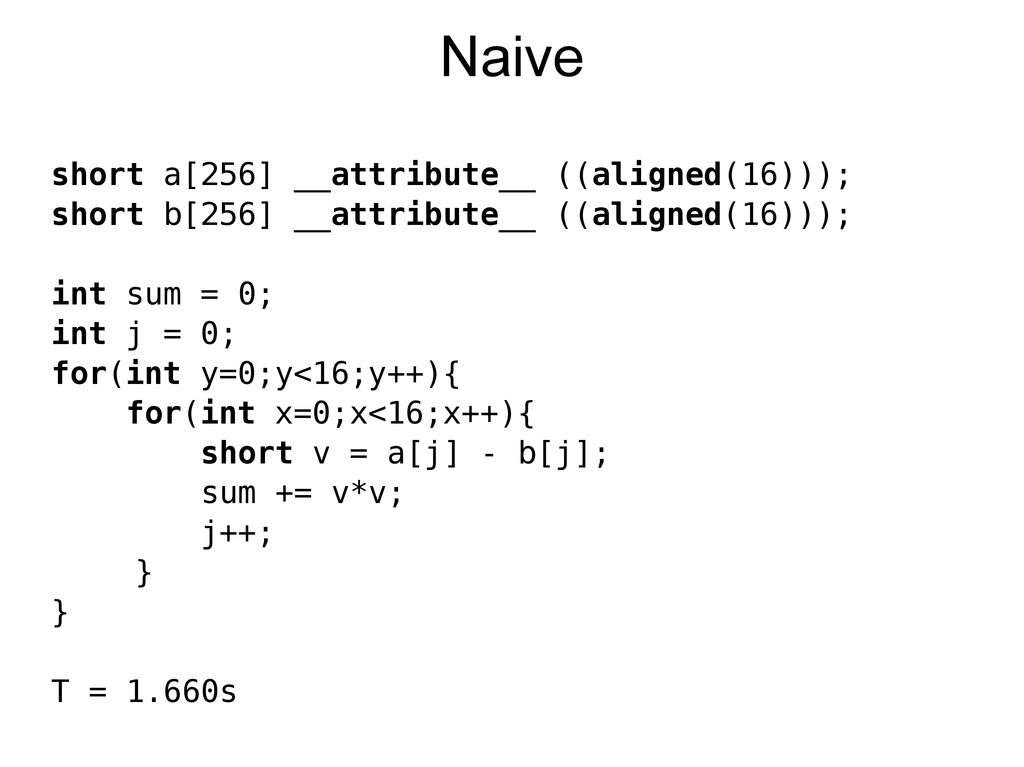
Naive short a[256] __attribute__ ((aligned(16))); short b[256] __attribute__ ((aligned(16))); int
sum = 0; int j = 0; for(int y=0;y<16;y++){ for(int x=0;x<16;x++){ short v = a[j] - b[j]; sum += v*v; j++; } } T = 1.660s
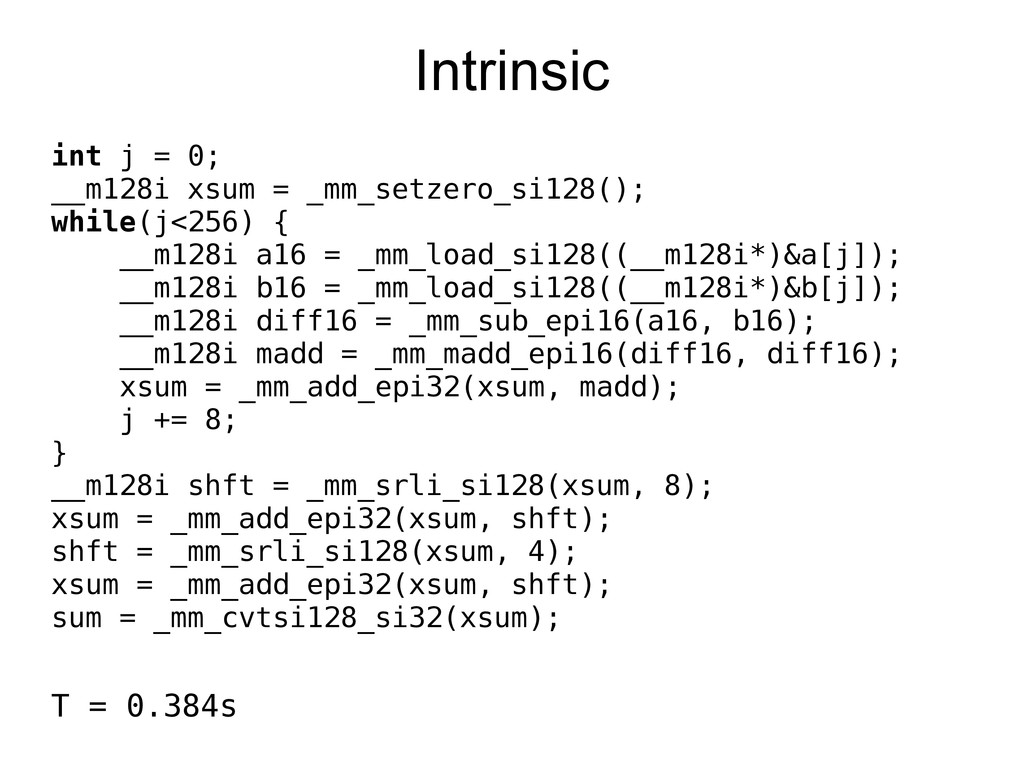
Intrinsic int j = 0; __m128i xsum = _mm_setzero_si128(); while(j<256)
{ __m128i a16 = _mm_load_si128((__m128i*)&a[j]); __m128i b16 = _mm_load_si128((__m128i*)&b[j]); __m128i diff16 = _mm_sub_epi16(a16, b16); __m128i madd = _mm_madd_epi16(diff16, diff16); xsum = _mm_add_epi32(xsum, madd); j += 8; } __m128i shft = _mm_srli_si128(xsum, 8); xsum = _mm_add_epi32(xsum, shft); shft = _mm_srli_si128(xsum, 4); xsum = _mm_add_epi32(xsum, shft); sum = _mm_cvtsi128_si32(xsum); T = 0.384s
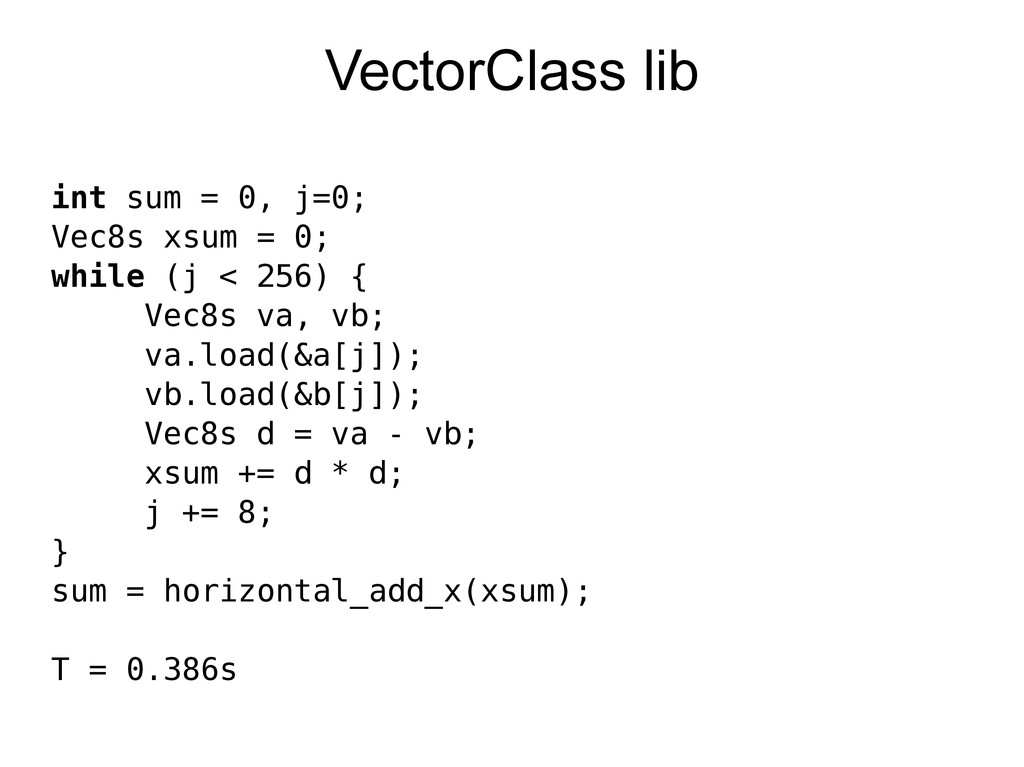
VectorClass lib int sum = 0, j=0; Vec8s xsum =
0; while (j < 256) { Vec8s va, vb; va.load(&a[j]); vb.load(&b[j]); Vec8s d = va - vb; xsum += d * d; j += 8; } sum = horizontal_add_x(xsum); T = 0.386s
None
None
None
None
None
None
None
None
None
None


 ekbcpp
 stephenakadiri
 lfama
 nikkihalliwell
 addyosmani
 cromwellryan
 reverentgeek
 bcantrill
 cargoodrich
 tamaranovitovic
 lara
 tomoyanonymous
 schroneko