Share
Embed
Deriving chemosensitivity from cell lines: forensic bioinformatics and reproducible research in high-throughput biology
Presentation of: Baggerly K.A. and Coombes K.R. (2009) Deriving chemosensitivity from cell lines: forensic bioinformatics and reproducible research in high-throughput biology. Ann Appl Stat., 3, 1309-1344.
DOI: https://dx.doi.org/10.1214/09-AOAS291
Background: M.Sc. Bioinformatics - Statistics
Presented by: Fritz Lekschas
Fritz Lekschas
May 22, 2014
Transcript
38 slides
-
DERIVING CHEMOSENSITIVITY FROM CELL LINES: FORENSIC BIOINFORMATICS AND REPRODUCIBLE RESEARCH
IN HIGH- THROUGHPUT BIOLOGY Baggerly K.A. and Coombes K.R. 22.05.2014 Fritz Lekschas 1 -
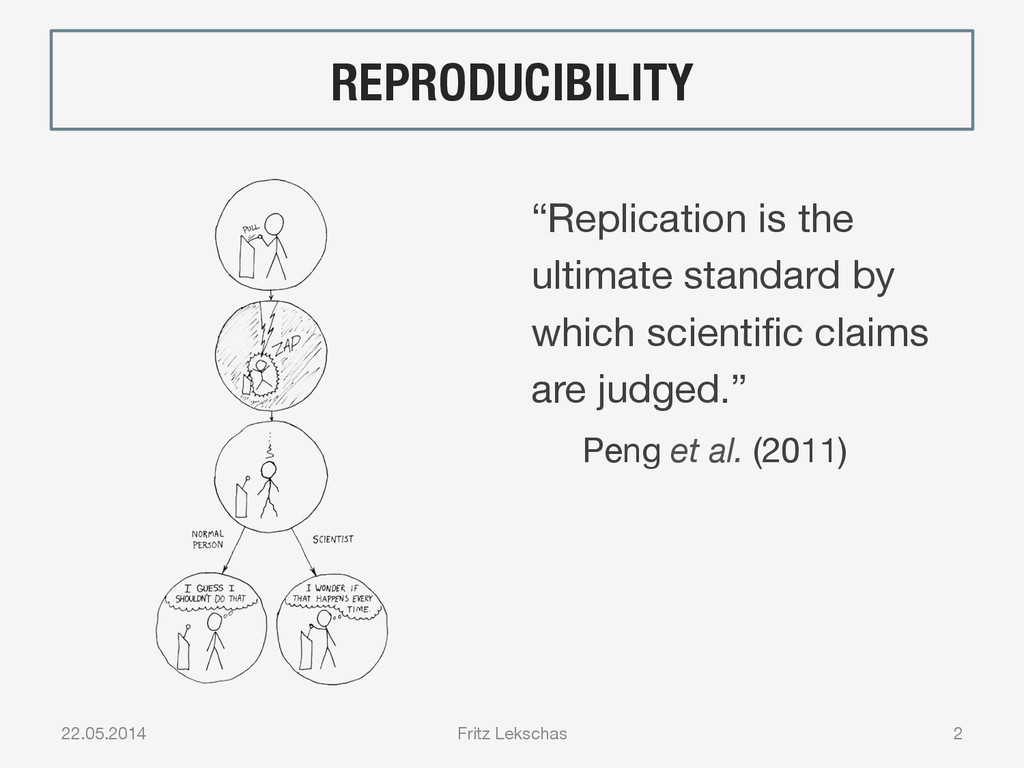
REPRODUCIBILITY “Replication is the ultimate standard by which scientific claims
are judged.” Peng et al. (2011) 22.05.2014 Fritz Lekschas 2 -
OVERVIEW • 4 case studies using microarray-based patient response prediction
à Clinical trial was on-going! • Which anticancer drug is most effective for which patient? 22.05.2014 Fritz Lekschas 3 -
CHEMOSENSITIVITY • NCI-60 – 60 human cancer cell lines (9
tissues) – Dilution assay against anticancer agents – Measure inhibition of cell growth • Sensitive vs. resistant cell lines – Differentially expressed genes à gene signature • Predict personalized drug sensitivity – Assess gene signatures 22.05.2014 Fritz Lekschas 4 -
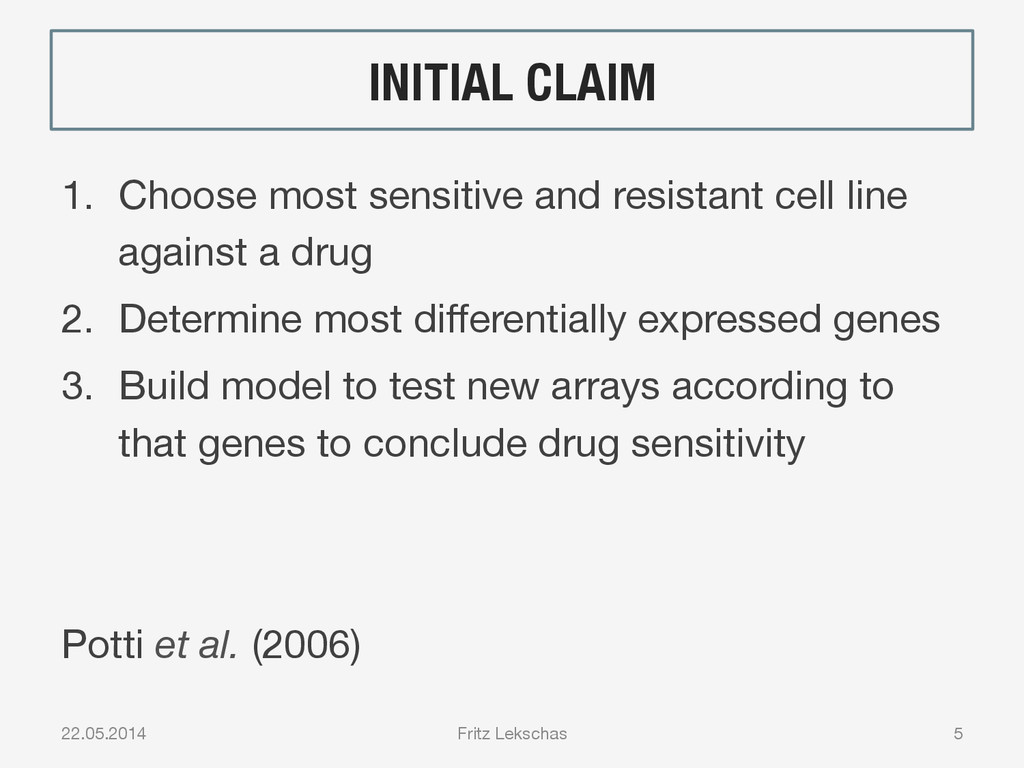
INITIAL CLAIM 1. Choose most sensitive and resistant cell line
against a drug 2. Determine most differentially expressed genes 3. Build model to test new arrays according to that genes to conclude drug sensitivity Potti et al. (2006) 22.05.2014 Fritz Lekschas 5 -
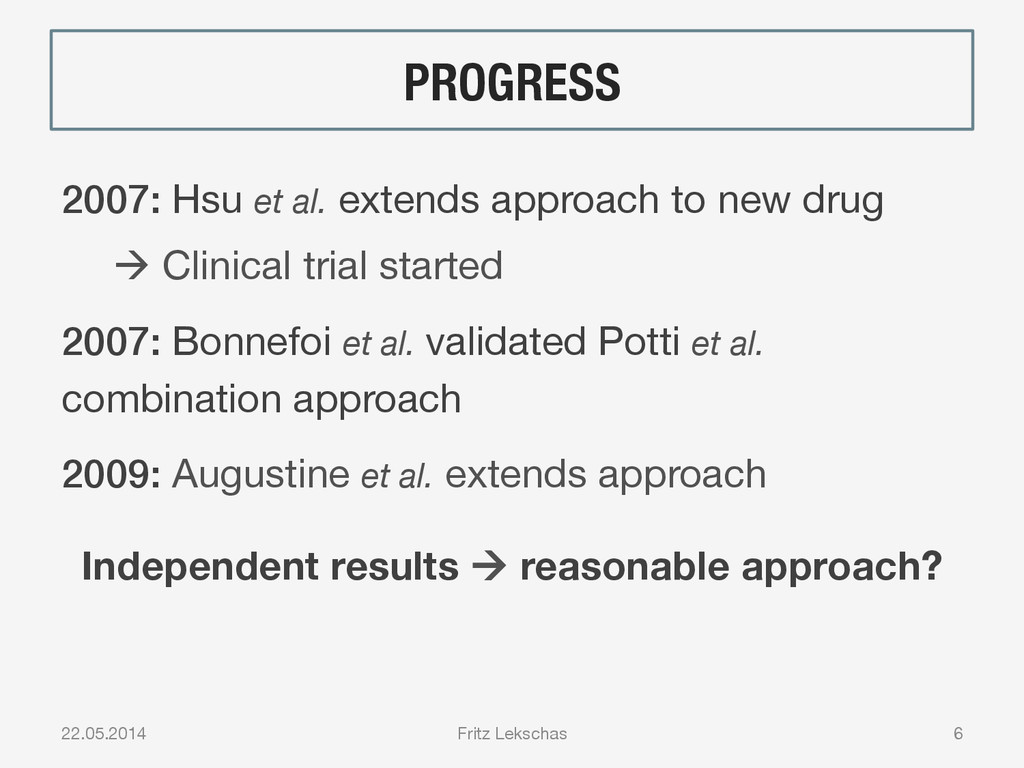
PROGRESS 2007: Hsu et al. extends approach to new drug
à Clinical trial started 2007: Bonnefoi et al. validated Potti et al. combination approach 2009: Augustine et al. extends approach Independent results reasonable approach? 22.05.2014 Fritz Lekschas 6 -
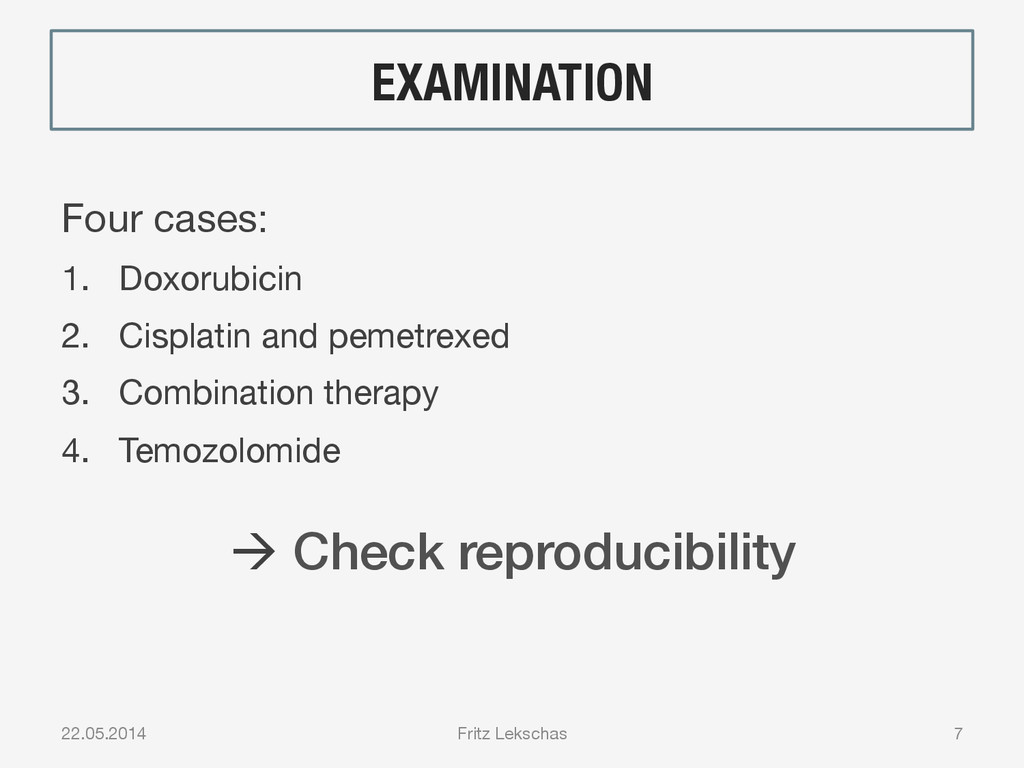
EXAMINATION Four cases: 1. Doxorubicin 2. Cisplatin and pemetrexed 3.
Combination therapy 4. Temozolomide à Check reproducibility! 22.05.2014 Fritz Lekschas 7 -
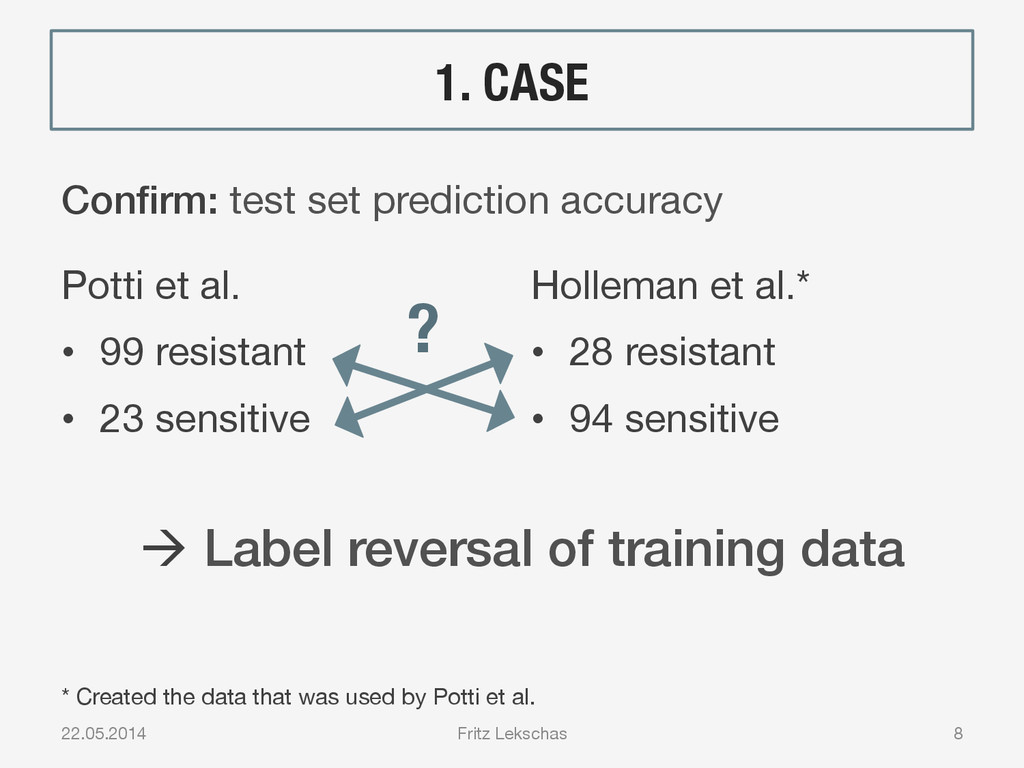
1. CASE Potti et al. • 99 resistant • 23
sensitive Holleman et al.* • 28 resistant • 94 sensitive 22.05.2014 Fritz Lekschas 8 Confirm: test set prediction accuracy * Created the data that was used by Potti et al. ? à Label reversal of training data! -
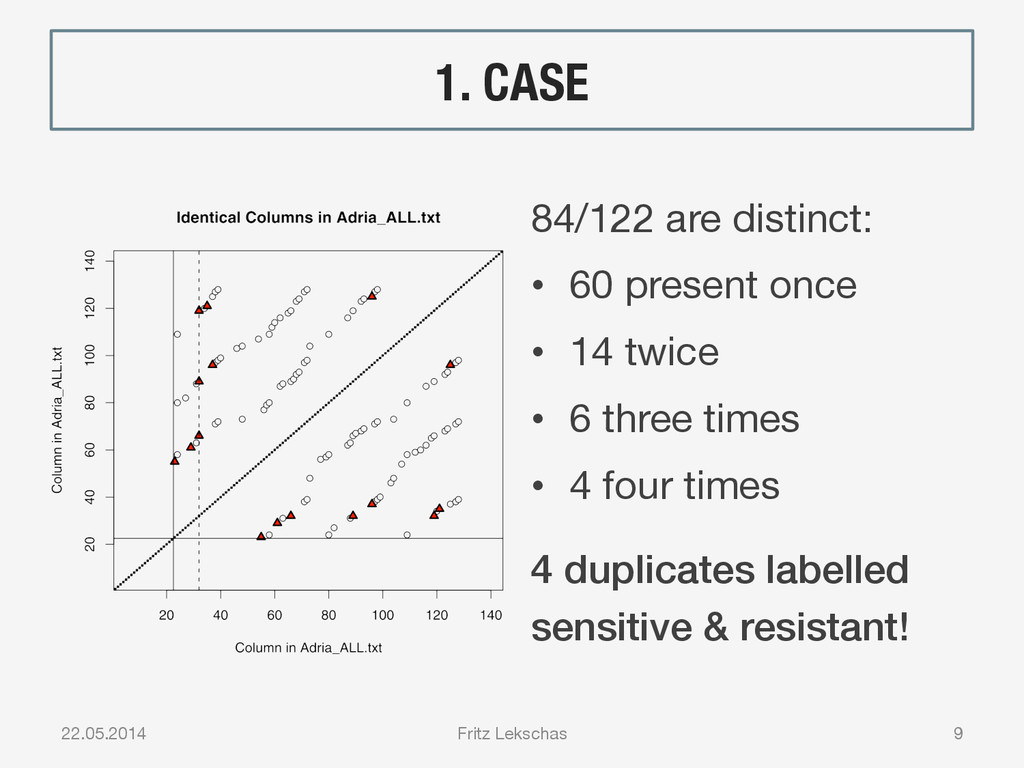
1. CASE 84/122 are distinct: • 60 present once •
14 twice • 6 three times • 4 four times 4 duplicates labelled sensitive & resistant!! 22.05.2014 Fritz Lekschas 9 -
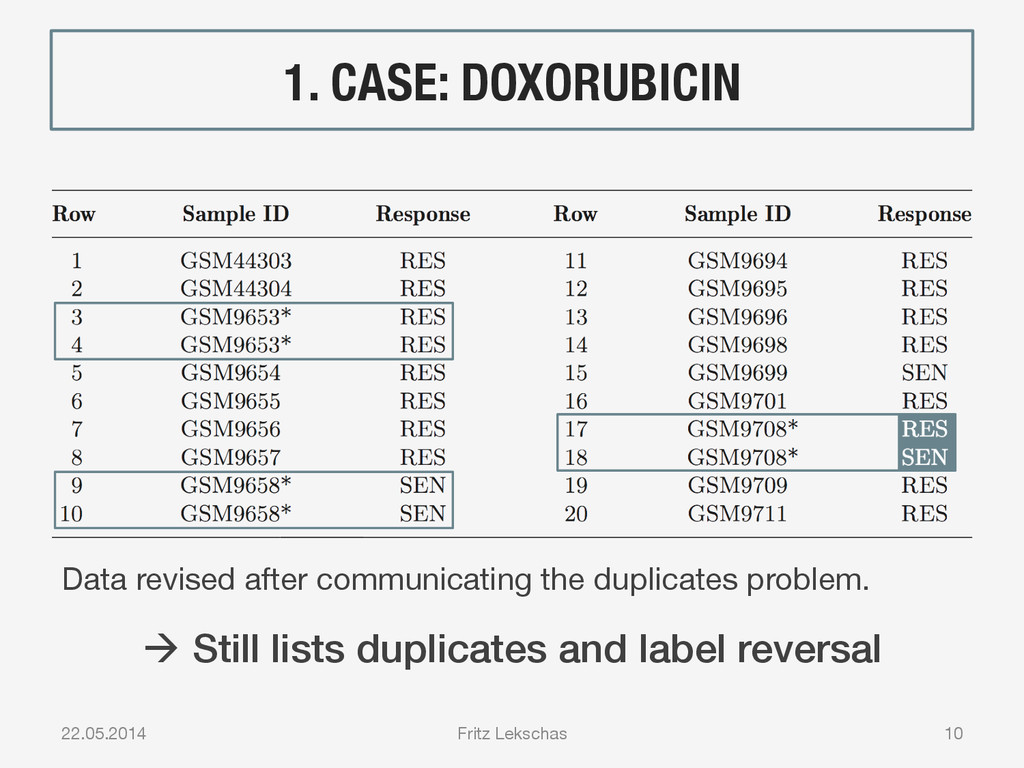
1. CASE: DOXORUBICIN 22.05.2014 Fritz Lekschas 10 Data revised after
communicating the duplicates problem. à Still lists duplicates and label reversal -
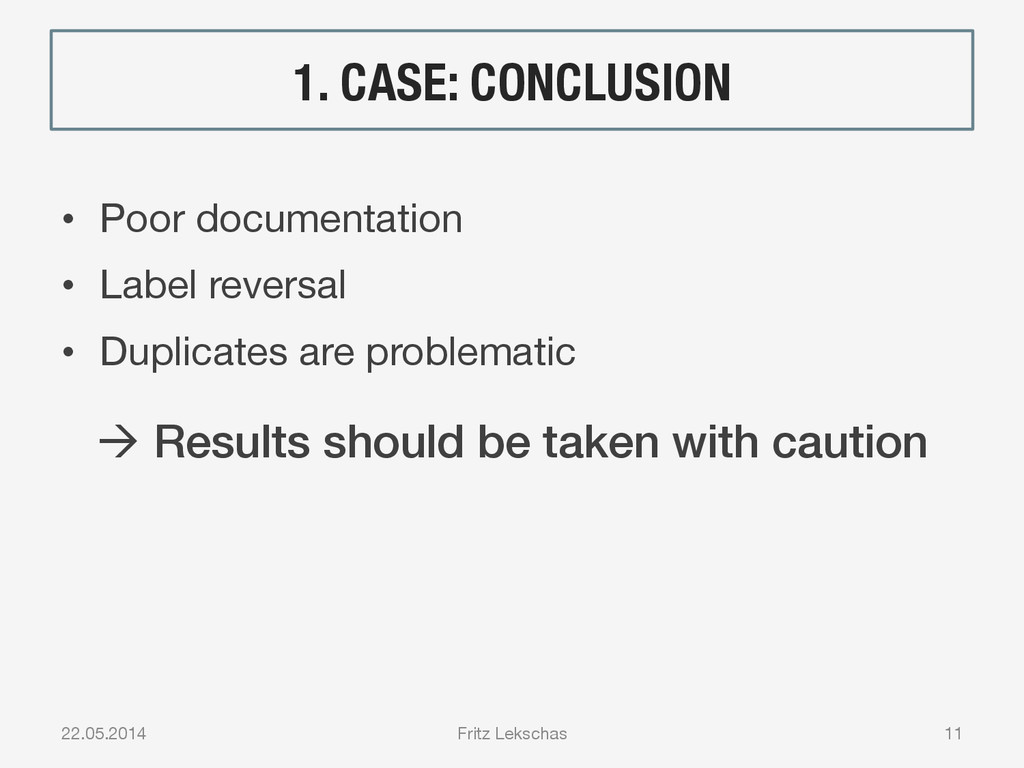
1. CASE: CONCLUSION • Poor documentation • Label reversal •
Duplicates are problematic à Results should be taken with caution! 22.05.2014 Fritz Lekschas 11 -
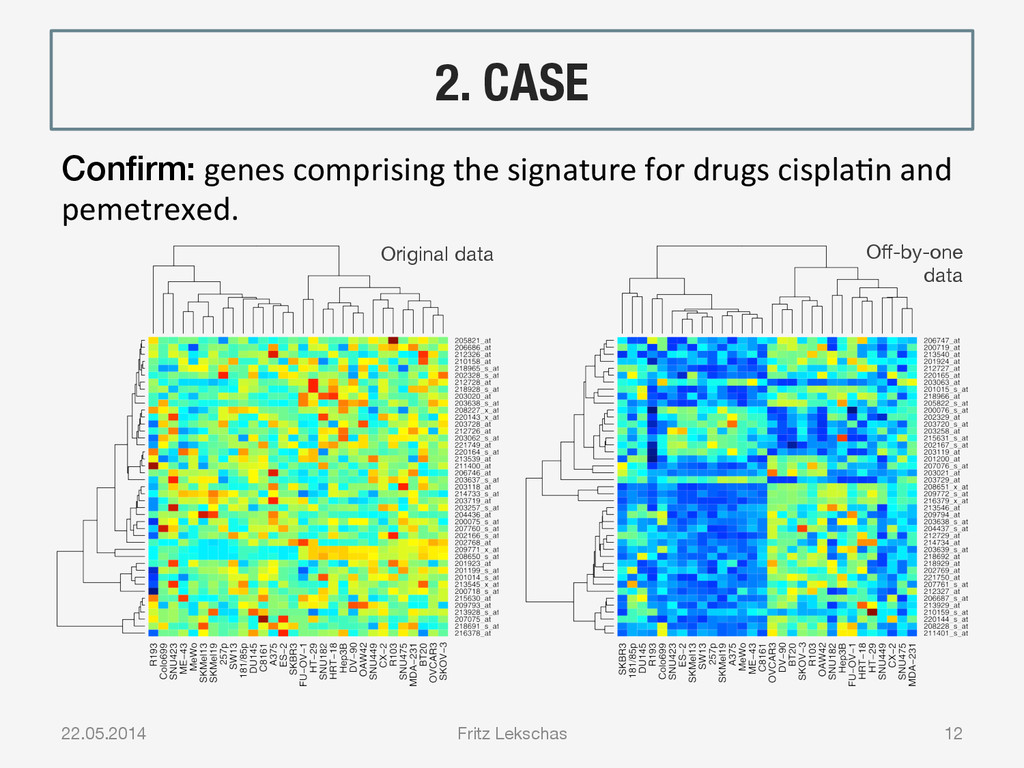
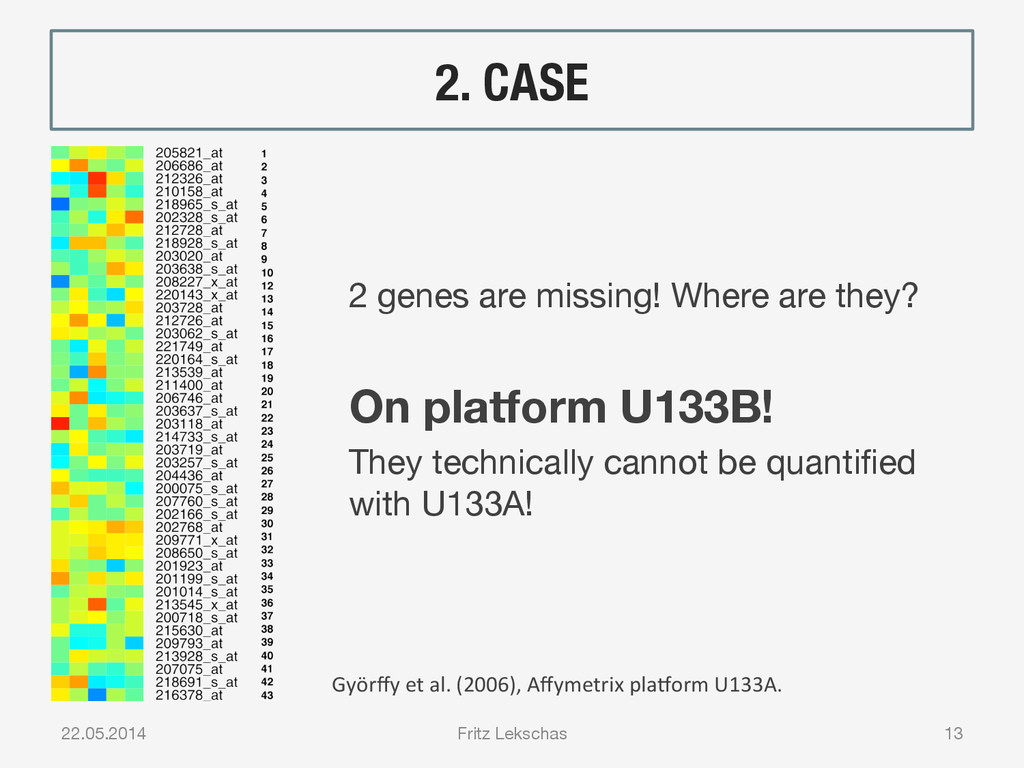
2. CASE 22.05.2014 Fritz Lekschas 12 Confirm: genes comprising the
signature for drugs cispla3n and pemetrexed. Original data Off-by-one data -
2. CASE 22.05.2014 Fritz Lekschas 13 2 genes are missing!
Where are they? Györffy et al. (2006), Affymetrix plaAorm U133A. On platform U133B! They technically cannot be quantified with U133A! -
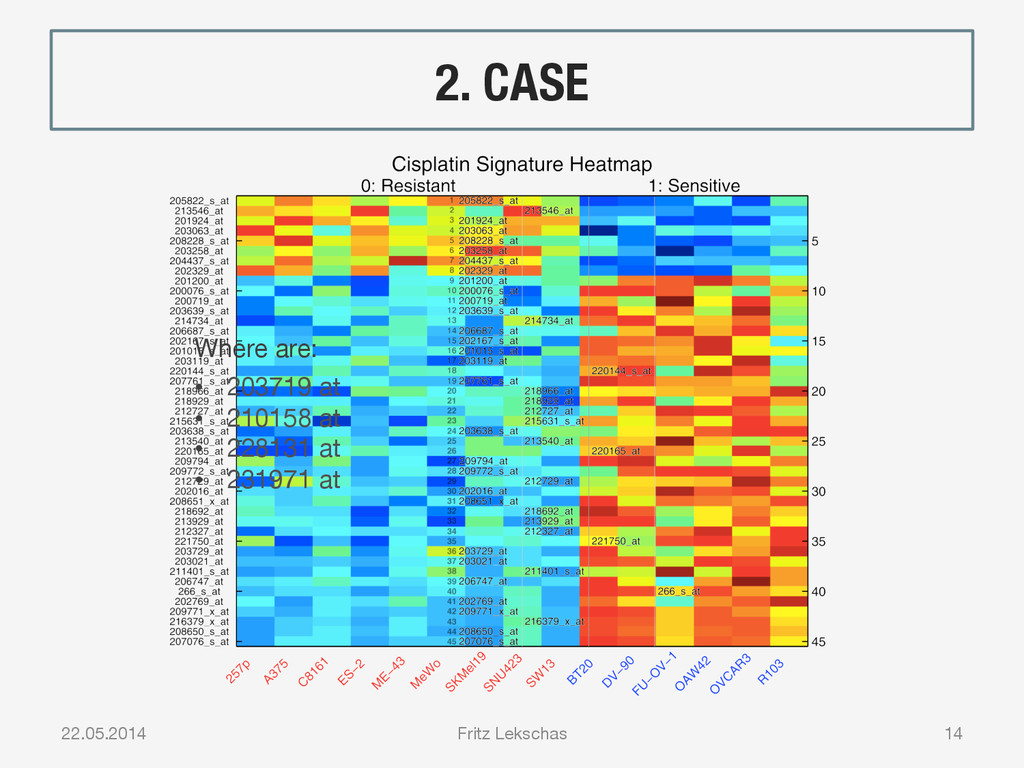
2. CASE 22.05.2014 Fritz Lekschas 14 Where are: • 203719
at • 210158 at • 228131 at • 231971 at -
2. CASE: CONCLUSION Cisplatin:! • Off-by-one index error • Only
41/45 genes found Pemetrexed:! • Off-by-one index error • Sensitive / resistant label reversal 22.05.2014 Fritz Lekschas 15 à Results should be taken with caution! -
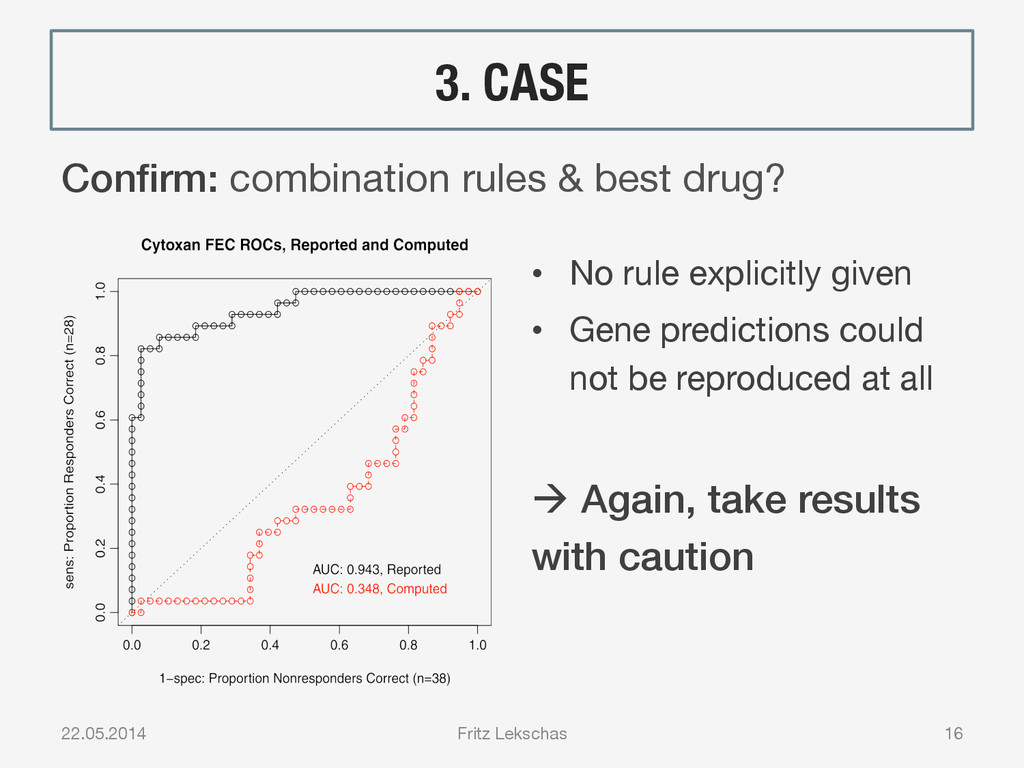
3. CASE • No rule explicitly given • Gene predictions
could not be reproduced at all à Again, take results with caution! 22.05.2014 Fritz Lekschas 16 Confirm: combination rules & best drug? -
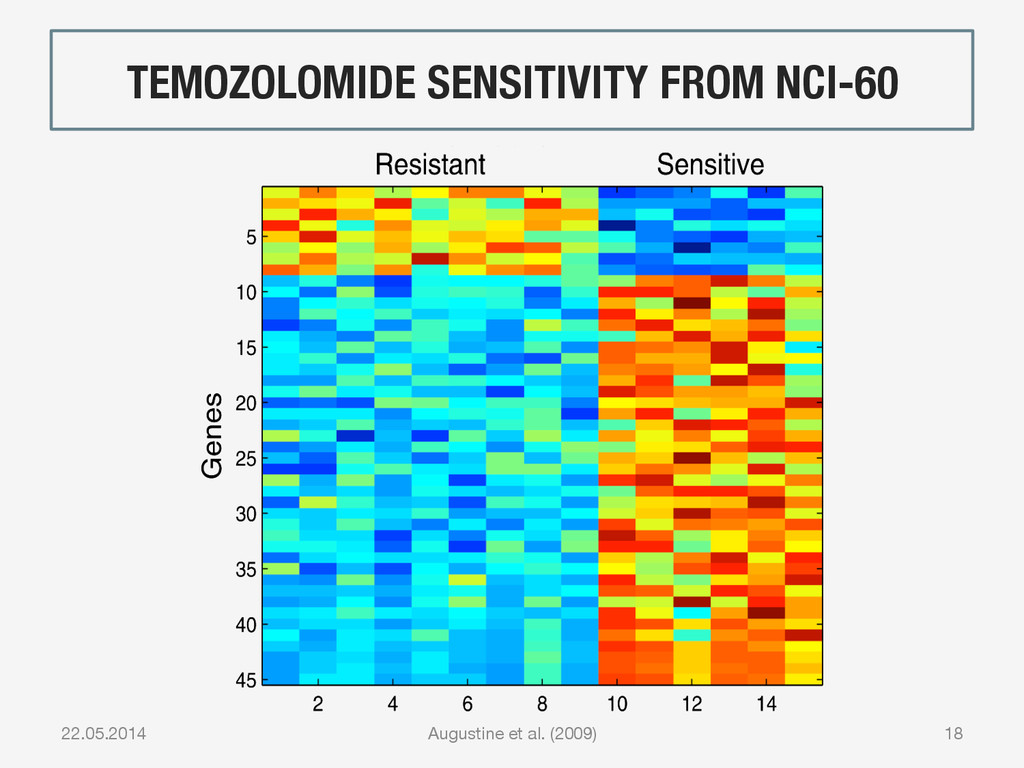
4. CASE Confirm: Match gene signature • 45 genes reported
for separating 9 resistant from 6 sensitive cell lines 22.05.2014 Fritz Lekschas 17 -
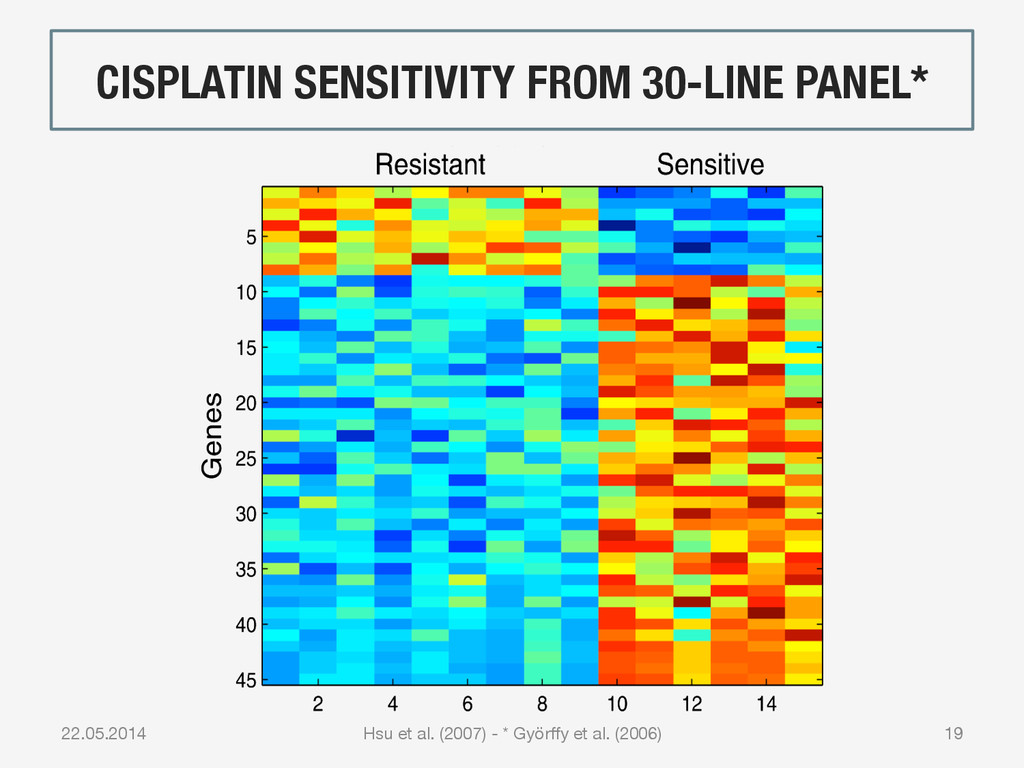
CISPLATIN SENSITIVITY FROM 30-LINE PANEL* 22.05.2014 Hsu et al. (2007)
- * Györffy et al. (2006) 19 -
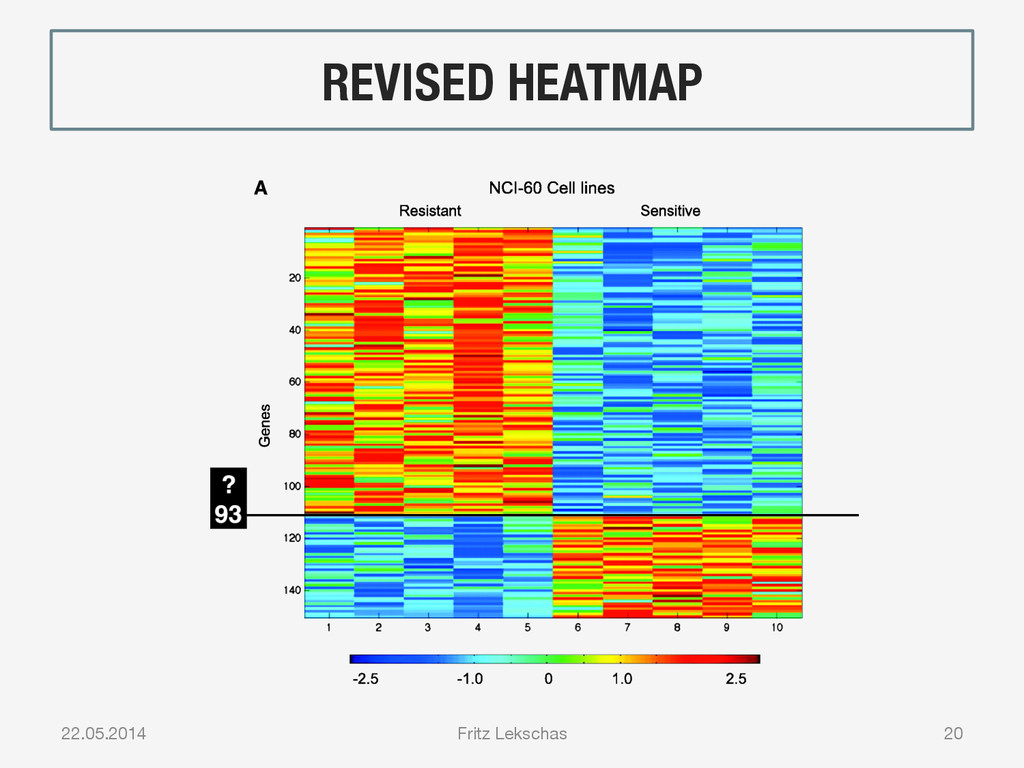
4. CASE: SUMMARY „Poor documentation led a report on drug
to include a heatmap for drug and a gene list for drug .“ à Results my be taken with caution! 22.05.2014 Fritz Lekschas 21 -
SUMMARY MISTAKES • Label reversal • Off-by-one indexing error •
Duplications • Mix-ups of different data sources 22.05.2014 Fritz Lekschas 22 -
CONCLUSION • Sparse documentation hides several errors • Errors load
to complete mix-up of data. • Corrected analysis yield predictions no better than chance Irreproducibility à No evidence! 22.05.2014 Fritz Lekschas 23 -
MOST COMMON ERRORS MAY BE SIMPLE But we can easily
avoid them! 22.05.2014 Fritz Lekschas 24 -
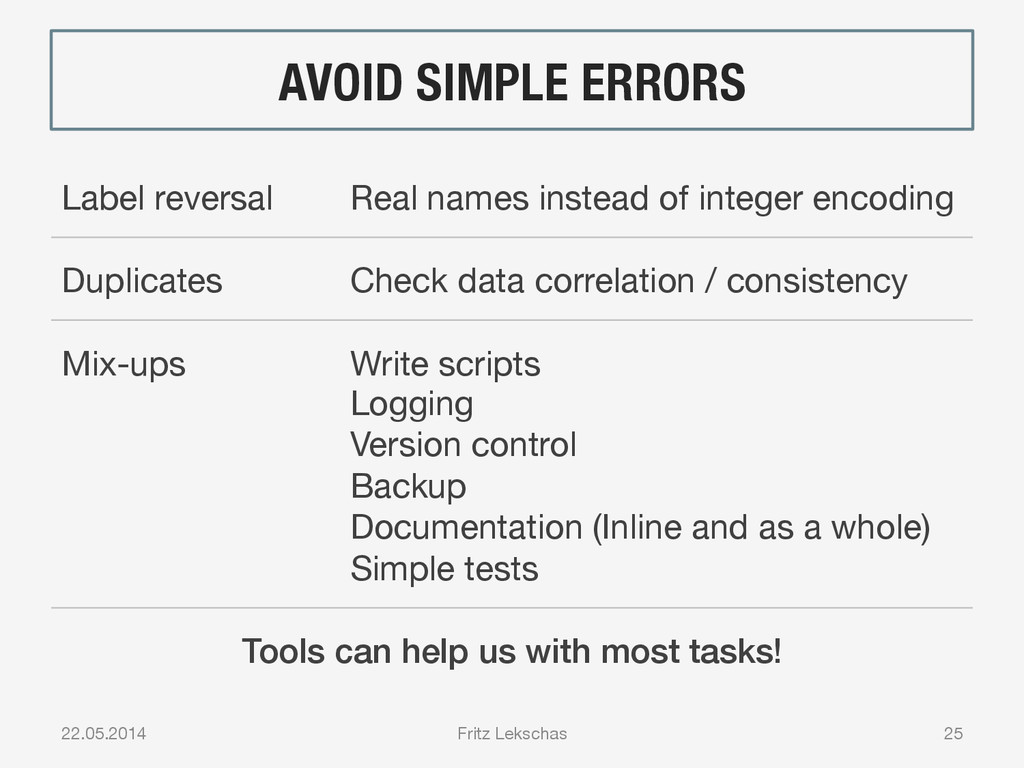
AVOID SIMPLE ERRORS Label reversal Real names instead of integer
encoding Duplicates Check data correlation / consistency Mix-ups Write scripts Logging Version control Backup Documentation (Inline and as a whole) Simple tests Tools can help us with most tasks!! 22.05.2014 Fritz Lekschas 25 -
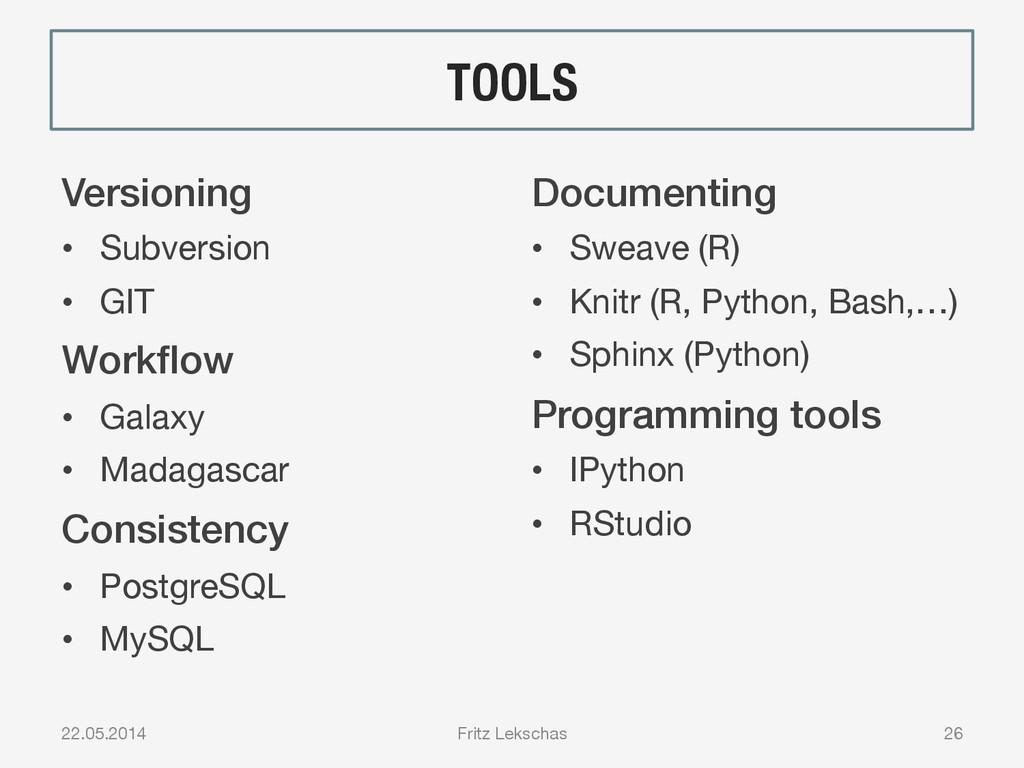
TOOLS Versioning! • Subversion • GIT Workflow! • Galaxy •
Madagascar Consistency! • PostgreSQL • MySQL Documenting! • Sweave (R) • Knitr (R, Python, Bash,…) • Sphinx (Python) Programming tools! • IPython • RStudio 22.05.2014 Fritz Lekschas 26 -
BEFORE YOU PUBLISH 22.05.2014 Fritz Lekschas 27 CHECK FOR SIMPLE
ERRORS! REMEMBER REPRODUCIBILITY -
WHEN YOU PUBLISH 22.05.2014 Fritz Lekschas 28 PUBLISH CODE! PUBLISH
DATA! PUBLISH METADATA! -
AFTER SOMEONE PUBLISHED 22.05.2014 Fritz Lekschas 29 CHECK STUDY DESIGN*
REMEMBER REPRODUCIBILITY * Ioannidis, J.P.A. (2005) Why Most Published Research Findings Are False. -
RECOMMENDED READING • Peng, R.D. (2011) Reproducible Research in Computational
Science PHYLOSOPHY • Ioannidis, J.P.A. (2005) Why Most Published Research Findings Are False STATISTICS • ICERM (2012) Reproducibility in Computational and Experimental Mathematics TIPS & TOOLS • http://bioinformatics.mdanderson.org/ Supplements/ReproRsch-All/ SUPPLEMENTARY DATA 22.05.2014 Fritz Lekschas 32 -
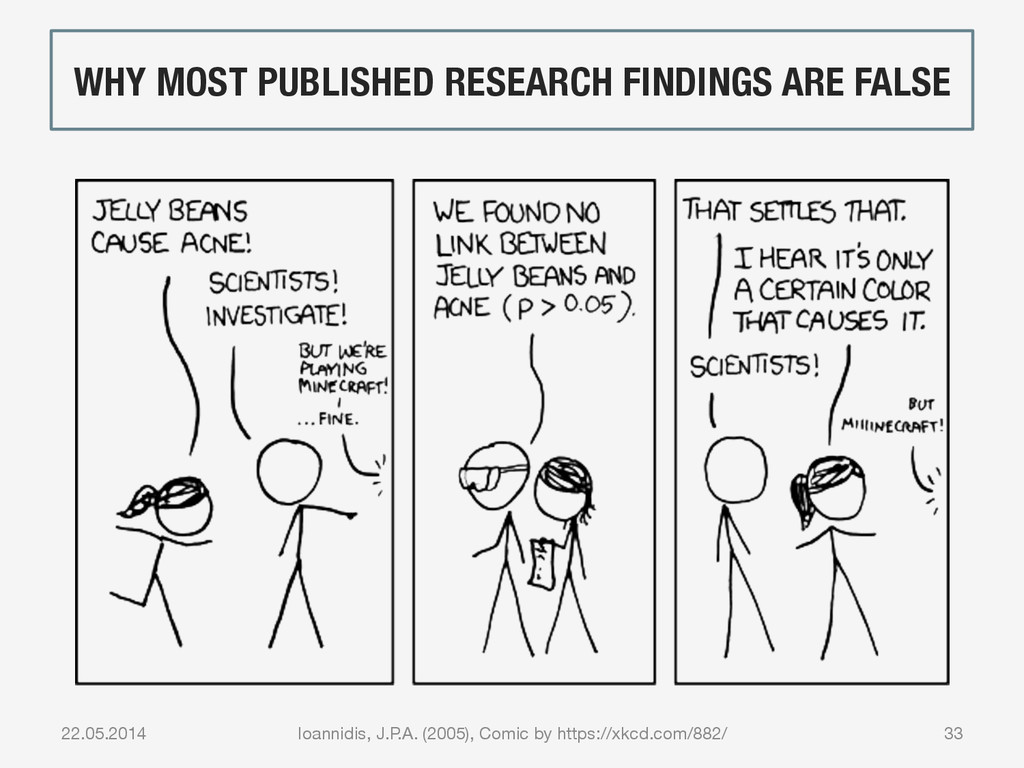
WHY MOST PUBLISHED RESEARCH FINDINGS ARE FALSE 22.05.2014 Ioannidis, J.P.A.
(2005), Comic by https://xkcd.com/882/ 33 -
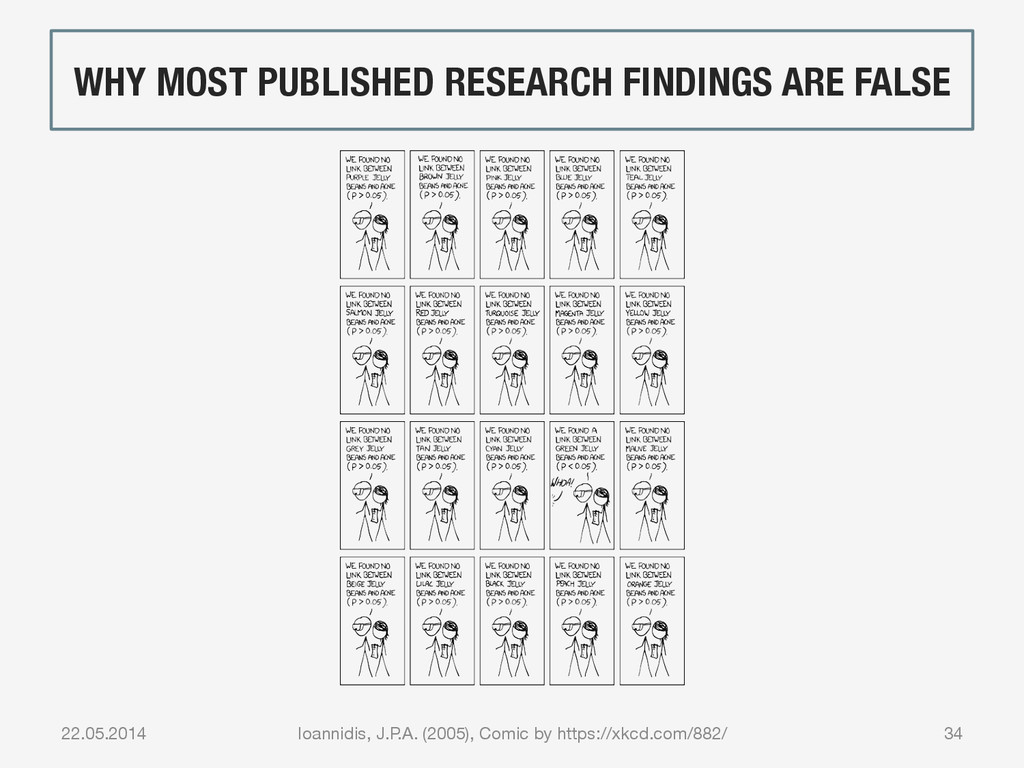
WHY MOST PUBLISHED RESEARCH FINDINGS ARE FALSE 22.05.2014 Ioannidis, J.P.A.
(2005), Comic by https://xkcd.com/882/ 34 -
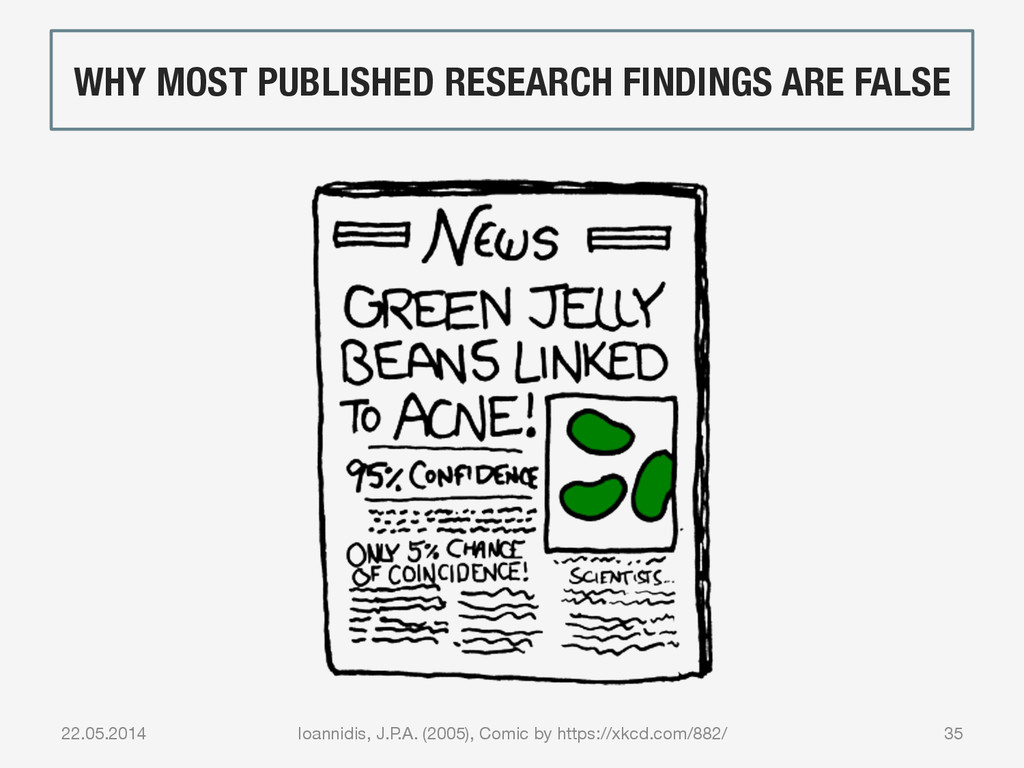
WHY MOST PUBLISHED RESEARCH FINDINGS ARE FALSE 22.05.2014 Ioannidis, J.P.A.
(2005), Comic by https://xkcd.com/882/ 35 -
WHY MOST PUBLISHED RESEARCH FINDINGS ARE FALSE “If you try
20 or more things, you should not be surprised that once an event with probability less than 0.05 = 1/20 will happen! It’s nothing to write home about… and nothing to write a scientific paper about.” John Baez (2013) 22.05.2014 Ioannidis, J.P.A. (2005) 36 -
WHY MOST PUBLISHED RESEARCH FINDINGS ARE FALSE Corollary 1: The
smaller the studies, the less likely the research findings are to be true. (If you test just a few jelly beans to see which ones ‘cause acne’, you can easily fool yourself.) Corollary 2: The smaller the effects being measured, the less likely the research findings are to be true. (If you’re studying whether jelly beans cause just a tiny bit of acne, you you can easily fool yourself.) Corollary 3: The more quantities there are to find relationships between, the less likely the research findings are to be true. (If you’re studying whether hundreds of colors of jelly beans cause hundreds of different diseases, you can easily fool yourself.) Corollary 4: The greater the flexibility in designing studies, the less likely the research findings are to be true. (If you use lots and lots of different tricks to see if different colors of jelly beans ‘cause acne’, you can easily fool yourself.) Corollary 5: The more financial and other interests and prejudices in a scientific field, the less likely the research findings are to be true. (If there’s huge money to be made selling acne-preventing jelly beans to teenagers, you can easily fool yourself.) Corollary 6: The hotter a scientific field, and the more scientific teams involved, the less likely the research findings are to be true. (If lots of scientists are eagerly doing experiments to find colors of jelly beans that prevent acne, it’s easy for someone to fool themselves… and everyone else.) 22.05.2014 Ioannidis, J.P.A. (2005), rephrased by John Baez (2013) 37 -
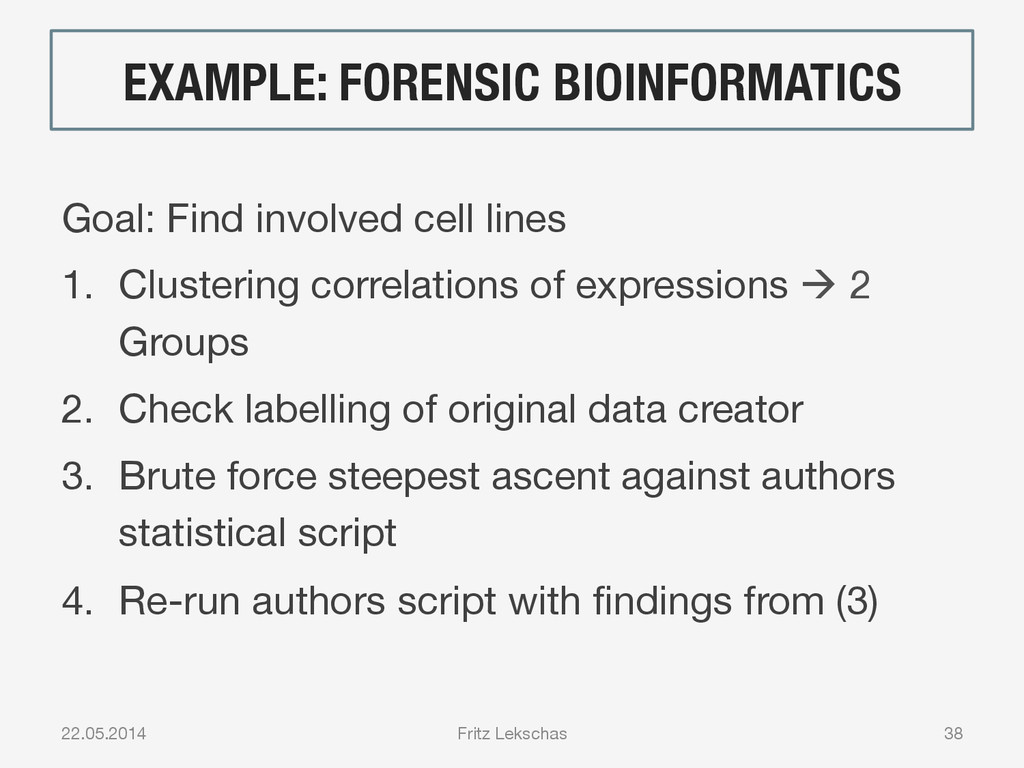
EXAMPLE: FORENSIC BIOINFORMATICS Goal: Find involved cell lines 1. Clustering
correlations of expressions à 2 Groups 2. Check labelling of original data creator 3. Brute force steepest ascent against authors statistical script 4. Re-run authors script with findings from (3) 22.05.2014 Fritz Lekschas 38