Share
Embed
Web Performance & Search Engines - A look beyond rankings
London Web Performance Meetup - 10th November 2020
There is a lot of talk about web performance as a ranking signal in Search Engines and how important or not it is, but often people are overlooking how performance affects multiple phases of a search engine such as crawling, rendering, and indexing.
In this talk, we'll try to understand how a search engine works and how some aspects of web performance affect the online presence of a website.
Giacomo Zecchini
November 10, 2020
Transcript
119 slides
-
Web Performance & Search Engines A look beyond rankings 2020/11/10
@giacomozecchini -
Hi, I’m Giacomo Zecchini Technical SEO @ Verve Search Technical
background and previous experiences in development Love: understanding how things work and Web Performance @giacomozecchini -
We are going to talk about... • How Web Performance
Affects Rankings @giacomozecchini -
We are going to talk about... • How Web Performance
Affects Rankings • How Search Engines Crawl and Render pages @giacomozecchini -
We are going to talk about... • How Web Performance
Affects Rankings • How Search Engines Crawl and Render pages • How It Affects Your Website @giacomozecchini -
Photo by Sam Balye on Unsplash Let’s talk about the
elephant in the room -
It’s been a while that search engines use and talk
about speed as a ranking factor • Using site speed in web search ranking https://webmasters.googleblog.com/2010/04/using-site-speed-in-web-search-ranking.html • Is your site ranking rank? Do a site review https://blogs.bing.com/webmaster/2010/06/24/is-your-site-ranking-rank-do-a-site-review-part-5-sem-101 • Using page speed in mobile search ranking https://webmasters.googleblog.com/2018/01/using-page-speed-in-mobile-search.html @giacomozecchini -
Bing - “How Bing ranks your content” Page load time:
Slow page load times can lead a visitor to leave your website, potentially before the content has even loaded, to seek information elsewhere. Bing may view this as a poor user experience and an unsatisfactory search result. Faster page loads are always better, but webmasters should balance absolute page load speed with a positive, useful user experience. https://www.bing.com/webmaster/help/webmaster-guidelines-30fba23a @giacomozecchini -
Yandex - “Site Quality” “How do I speed up my
site? The speed of page loading is an important indicator of a site's quality. If your site is slow, the user may not wait for a page to open and switch to a different site. This undermines their trust in your site, affects traffic and other statistical indicators. https://yandex.com/support/webmaster/yandex-indexing/page-speed.html @giacomozecchini -
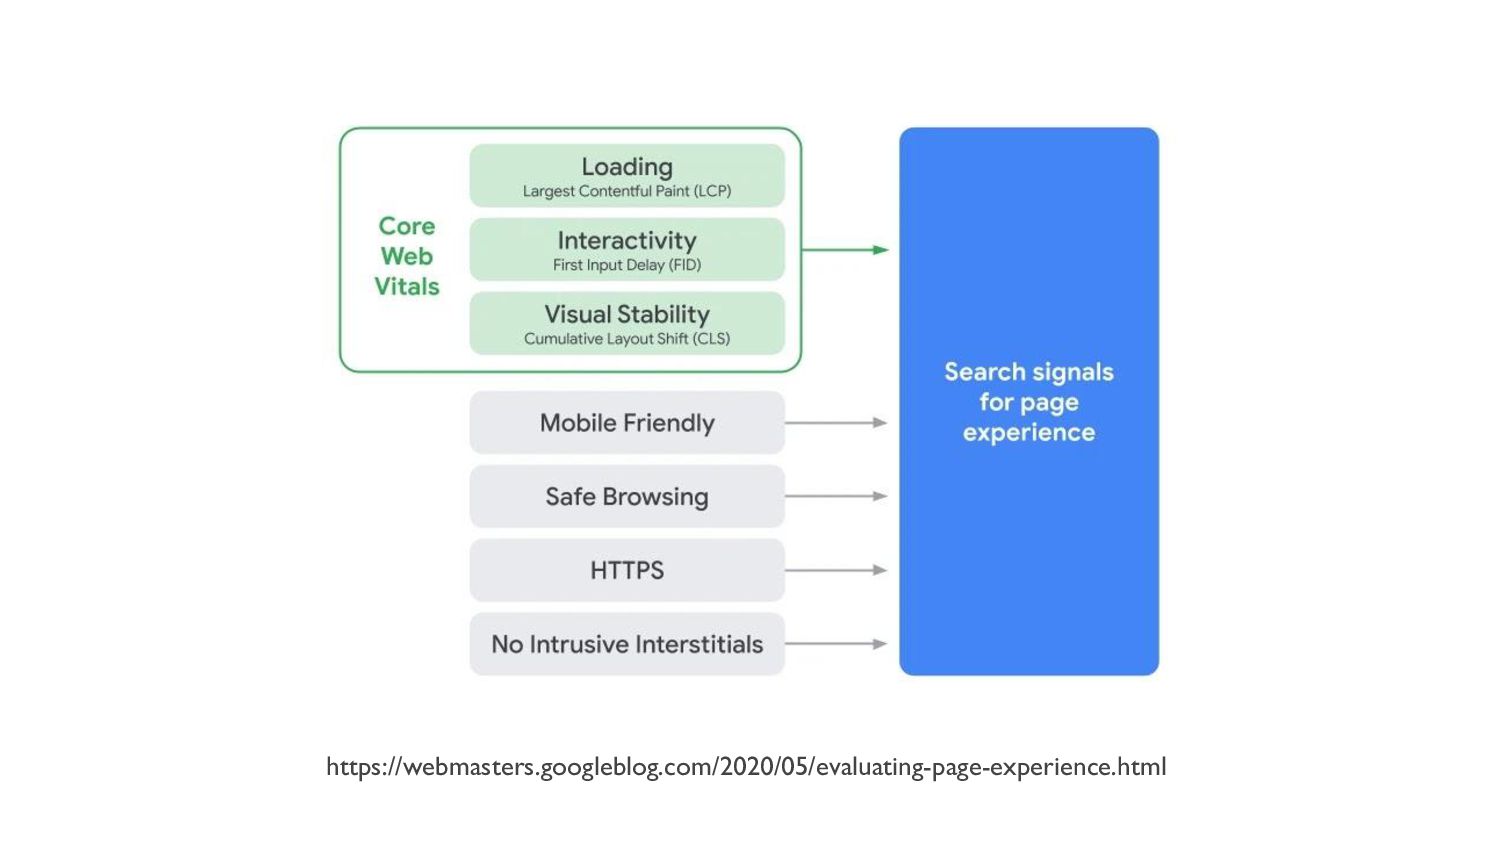
Google - “Evaluating page experience for a better web” “Earlier
this month, the Chrome team announced Core Web Vitals, a set of metrics related to speed, responsiveness and visual stability, to help site owners measure user experience on the web. Today, we’re building on this work and providing an early look at an upcoming Search ranking change that incorporates these page experience metrics.” https://webmasters.googleblog.com/2020/05/evaluating-page-experience.html @giacomozecchini -
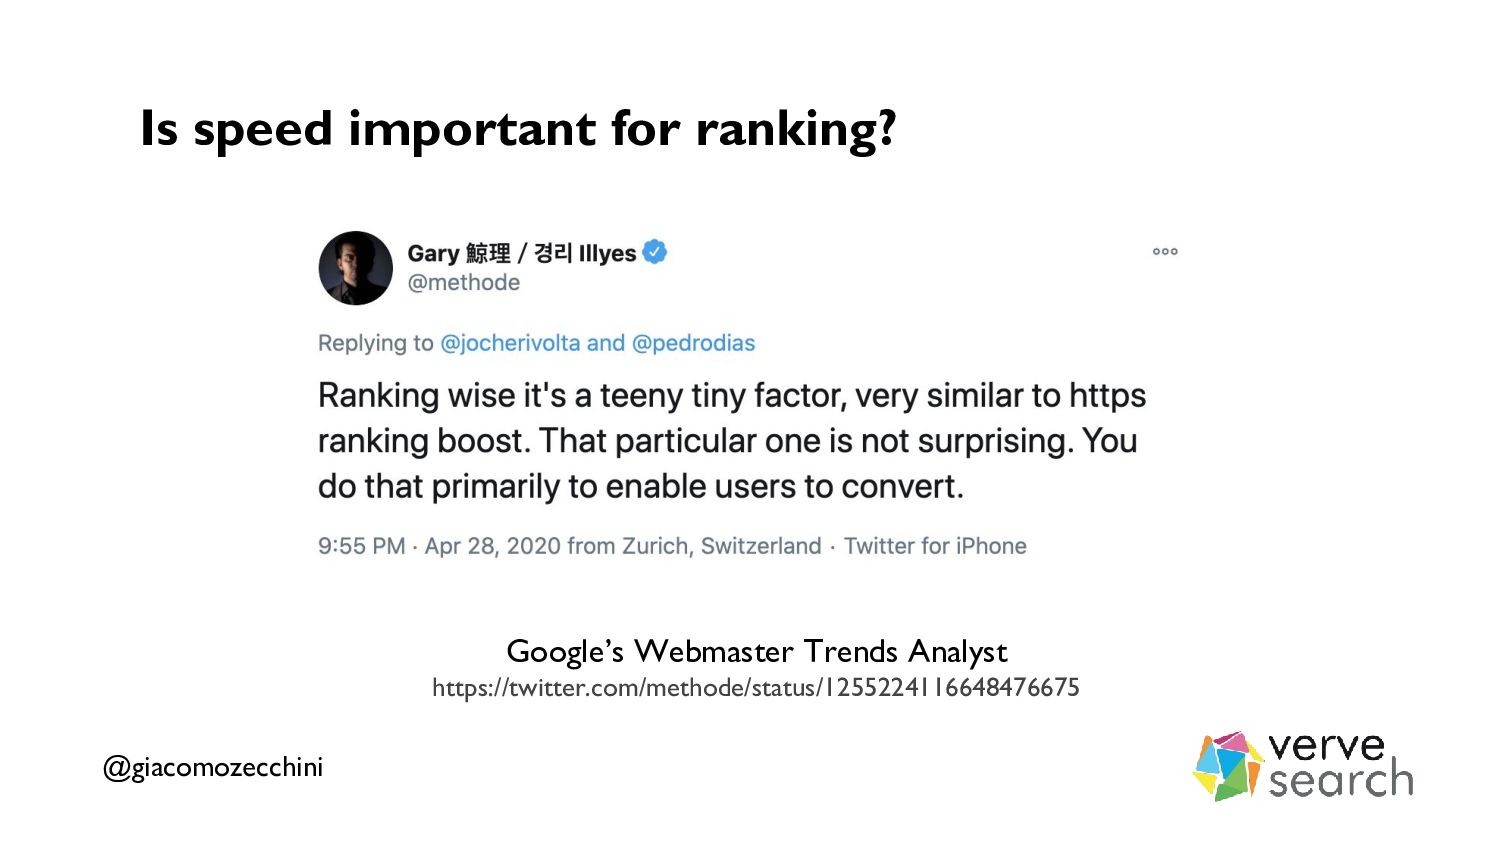
Is speed important for ranking? There are hundreds of ranking
signals, speed is one of them but not the most important one. An empty page would be damn fast but not that useful. @giacomozecchini -
Where does Google get data from for Core Web Vitals?
@giacomozecchini -
Where does Google get data from for Core Web Vitals?
• Real field data, something similar to the Chrome User Experience Report (CrUX) https://youtu.be/7HKYsJJrySY?t=45 @giacomozecchini -
Where does Google get data from for Core Web Vitals?
• Real field data, something similar to the Chrome User Experience Report (CrUX) Likely a raw version of CrUX that may contain all the “URL-Keyed Metrics” that Chrome records. https://source.chromium.org/chromium/chromium/src/+/master:tools/metrics/ukm/ukm.xml @giacomozecchini -
CrUX - Chrome User Experience Report The Chrome User Experience
Report provides user experience metrics for how real-world Chrome users experience popular destinations on the web. It’s powered by real user measurement of key user experience metrics across the public web. https://developers.google.com/web/tools/chrome-user-experience-report @giacomozecchini -
What if I’m not in CrUX? CrUX uses a threshold
related to the usage of specific websites, if there is less data than that threshold, websites or pages are not included in the Big Query / API database. @giacomozecchini -
What if I’m not in CrUX? CrUX uses a threshold
related to the usage of specific websites, if there is less data than that threshold, websites or page are not included in the Big Query / API database. We can end up with: • No data for a single page • No data for the whole origin / website @giacomozecchini -
What if CrUX has no data for my pages? If
the URL structure is easy to understand and there is a way to split your website into multiple parts looking at the URL, Google might group pages per subfolder or URL structure pattern grouping URLs that have similar content and resources. If that is not possible, Google may use the aggregate data across whole website. https://youtu.be/JV7egfF29pI?t=848 @giacomozecchini -
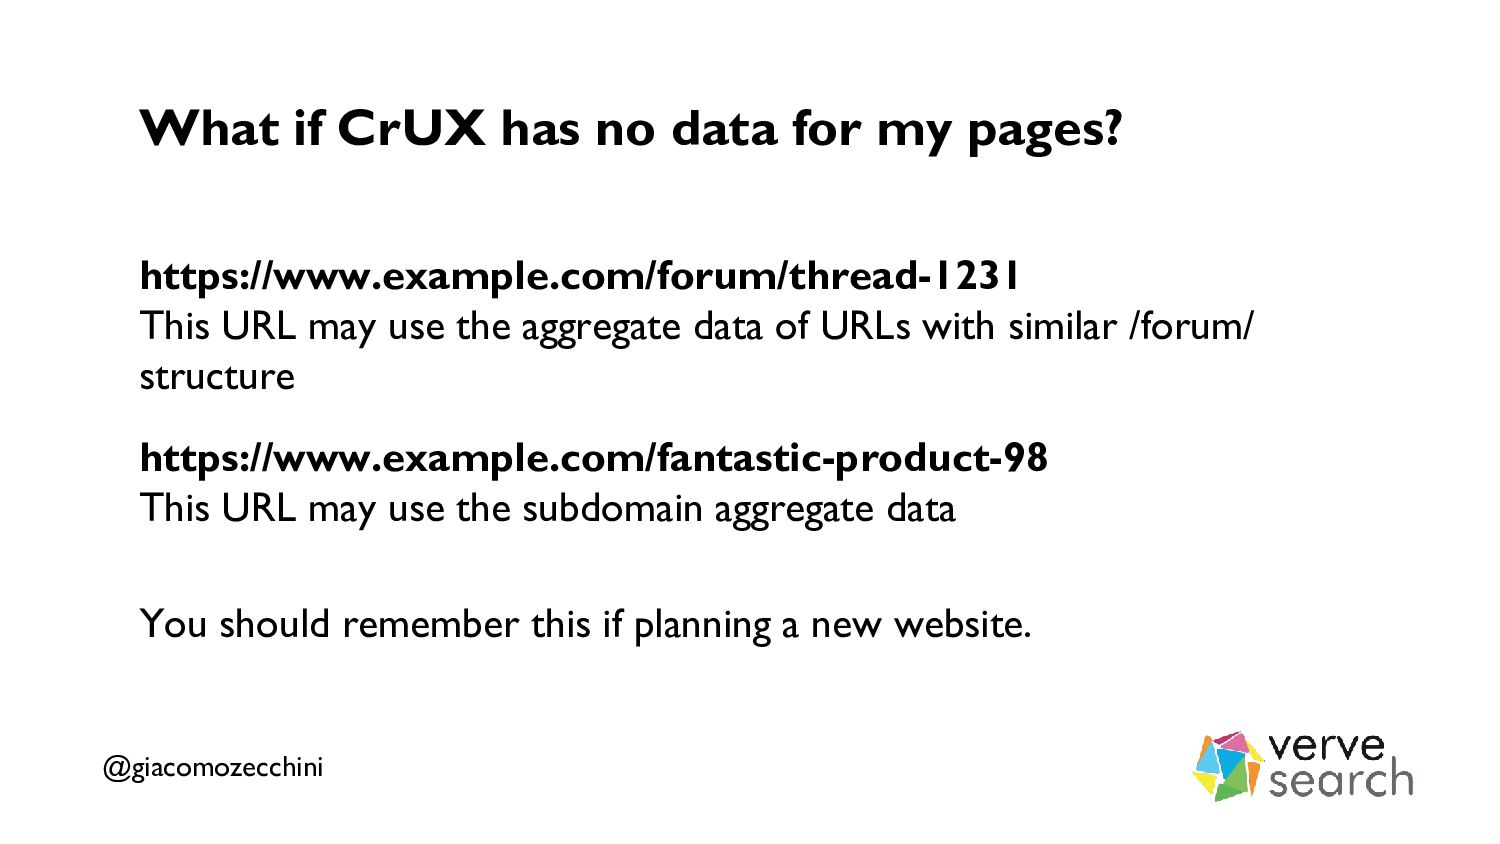
What if CrUX has no data for my pages? https://www.example.com/forum/thread-1231
This URL may use the aggregate data of URLs with similar /forum/ structure https://www.example.com/fantastic-product-98 This URL may use the subdomain aggregate data You should remember this if planning a new website. @giacomozecchini -
What if CrUX has no data for my pages? Looking
at the Core Web Vitals Report in Search Console, you can check how Google is already grouping “similar URLs” of your website. @giacomozecchini -
What if CrUX has no data for my website? This
is not really clear at the moment. @giacomozecchini -
What if CrUX has no data for my website? Possible
solutions: @giacomozecchini -
What if CrUX has no data for my website? Possible
solutions: • Not using any positive or negative value for the Core Web Vitals @giacomozecchini -
What if CrUX has no data for my website? Possible
solutions: • Not using any positive or negative value for the Core Web Vitals • Using data over a longer period of time to have enough data (BigQuery CrUX data is aggregated on monthly base, API is using the last 28 days of aggregated data) @giacomozecchini -
What if CrUX has no data for my website? Possible
solutions: • Not using any positive or negative value for the Core Web Vitals • Using data over a longer period of time to have enough data (BigQuery CrUX data is aggregated on monthly base, API is using the last 28 days of aggregated data) • Lab data, calculating theoretical speed @giacomozecchini -
What if CrUX has no data for my website? We
might have more information on this when Google will start using Core Web Vitals in Search (May, 2021). https://webmasters.googleblog.com/2020/11/timing-for-page-experience.html @giacomozecchini -
Is Google using Page Speed / Lighthouse performance score for
rankings? @giacomozecchini -
Is Google using Page Speed / Lighthouse performance score for
rankings? NO @giacomozecchini -
What about AMP? • AMP is not a ranking factor,
never has been @giacomozecchini -
What about AMP? • AMP is not a ranking factor,
never has been • Google will remove the AMP requirement from Top Stories eligibility in May, 2021 https://webmasters.googleblog.com/2020/05/evaluating-page-experience.html @giacomozecchini -
We can split what a Search Engine does in two
main parts • What happens when a user search for something • What happens in the background ahead of time @giacomozecchini -
What happens when a user searches for something When a
Search Engine gets a query from a user, it starts processing that trying to understand the meaning behind that search, retrieving and scoring the documents in the index, and eventually serving a list of results to the user. @giacomozecchini -
What happens in the background ahead of time To be
able serving to users pages that match their queries, a search engine has to: @giacomozecchini -
What happens in the background ahead of time To be
able serving to users pages that match their queries, a search engine has to: • Crawl the web @giacomozecchini -
What happens in the background ahead of time To be
able serving to users pages that match their queries, a search engine has to: • Crawl the web • Analyse crawled pages @giacomozecchini -
What happens in the background ahead of time To be
able serving to users pages that match their queries, a search engine has to: • Crawl the web • Analyse crawled pages • Build an Index @giacomozecchini -
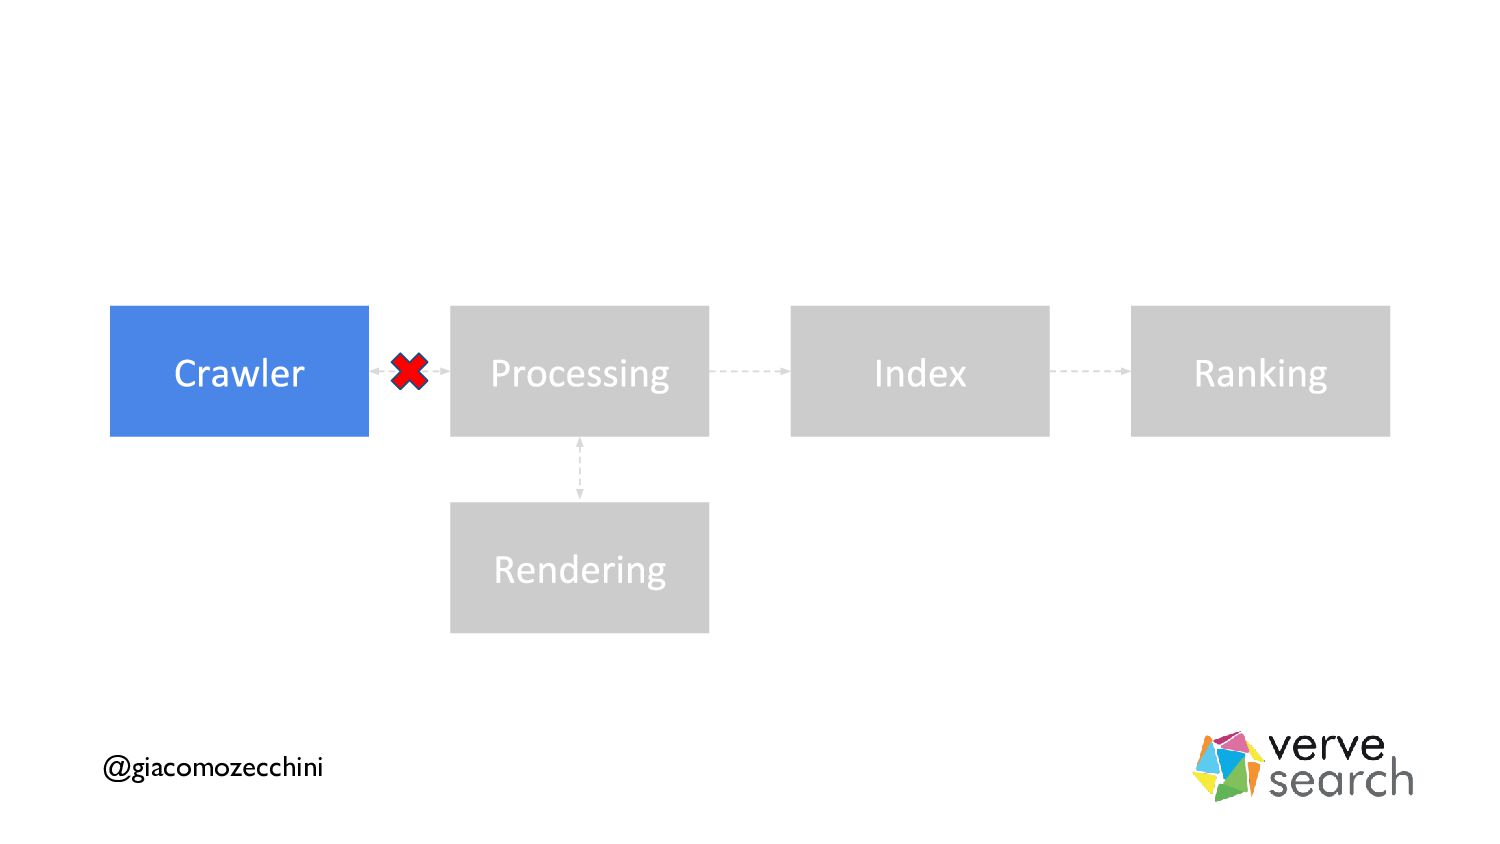
If a crawler can’t access your content, that page won’t
be indexed by search engines, nor will it be ranked. @giacomozecchini -
Even if your pages are being crawled, it doesn't mean
they will be indexed. Having your pages indexed doesn't mean they will rank. @giacomozecchini -
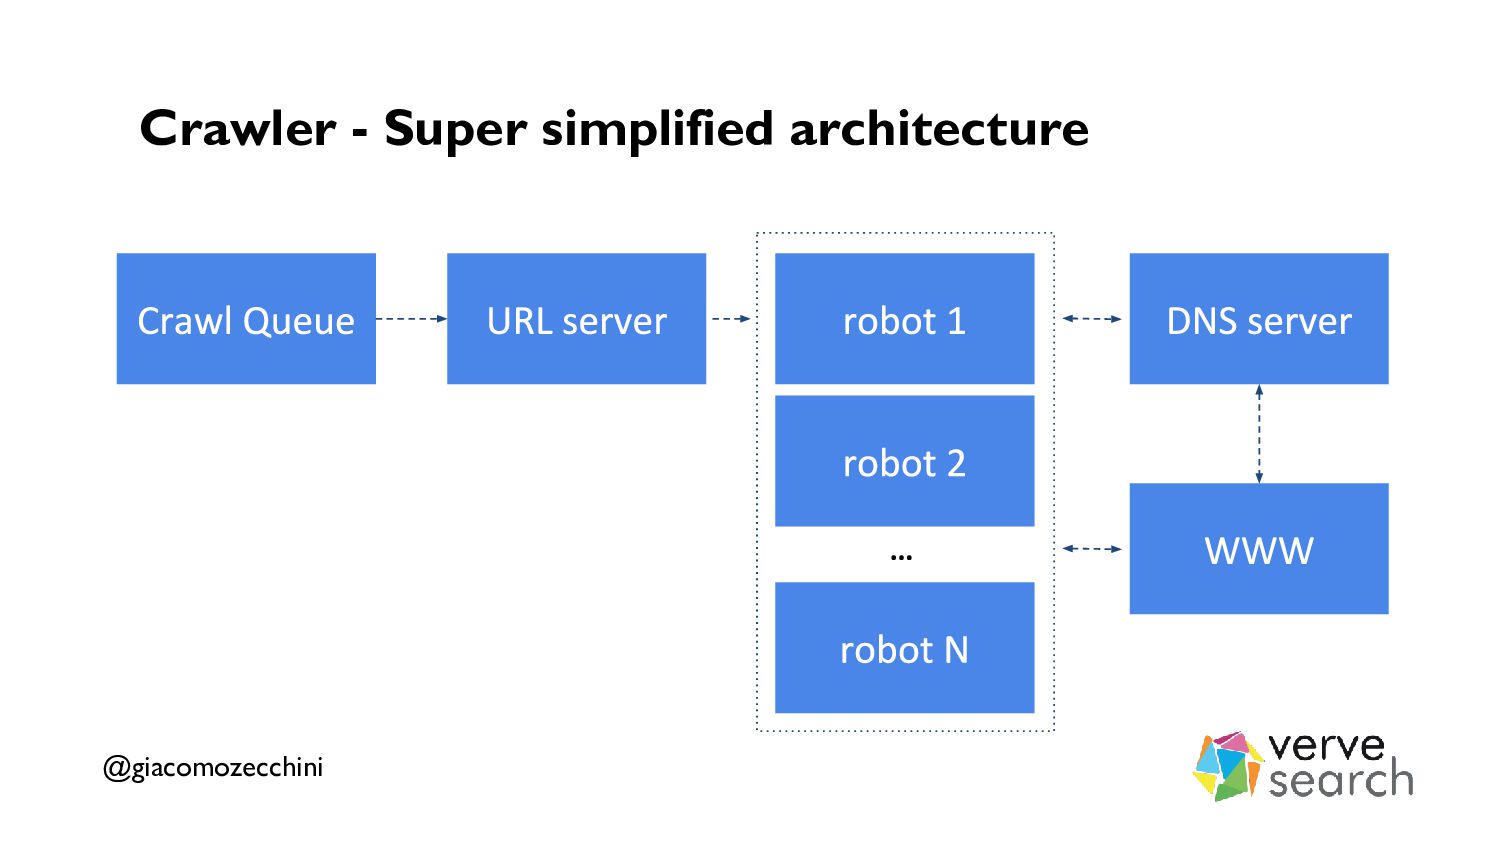
Crawler “A Web crawler, sometimes called a spider or spiderbot
and often shortened to crawler, is an Internet bot that systematically browses the World Wide Web, typically for the purpose of Web indexing (web spidering).” https://en.wikipedia.org/wiki/Web_crawler @giacomozecchini -
Crawler Features it must have: • Robustness • Politeness @giacomozecchini
Features it should have: • Distributed • Scalable • Performance and efficiency • Quality • Freshness • Extensible -
Crawler Features it must have: • Robustness • Politeness @giacomozecchini
Features it should have: • Distributed • Scalable • Performance and efficiency • Quality • Freshness • Extensible -
Crawler - Politeness Politeness can be: • Explicit - Webmasters
can define what portion of site can be crawled using the robots.txt file https://tools.ietf.org/html/draft-koster-rep-00 @giacomozecchini -
Crawler - Politeness Politeness can be: • Explicit - Webmasters
can define what portion of site can be crawled using the robots.txt file • Implicit - Search Engines should avoid requesting any site too often, they have algorithms to determine the optimal crawl speed for a site. @giacomozecchini -
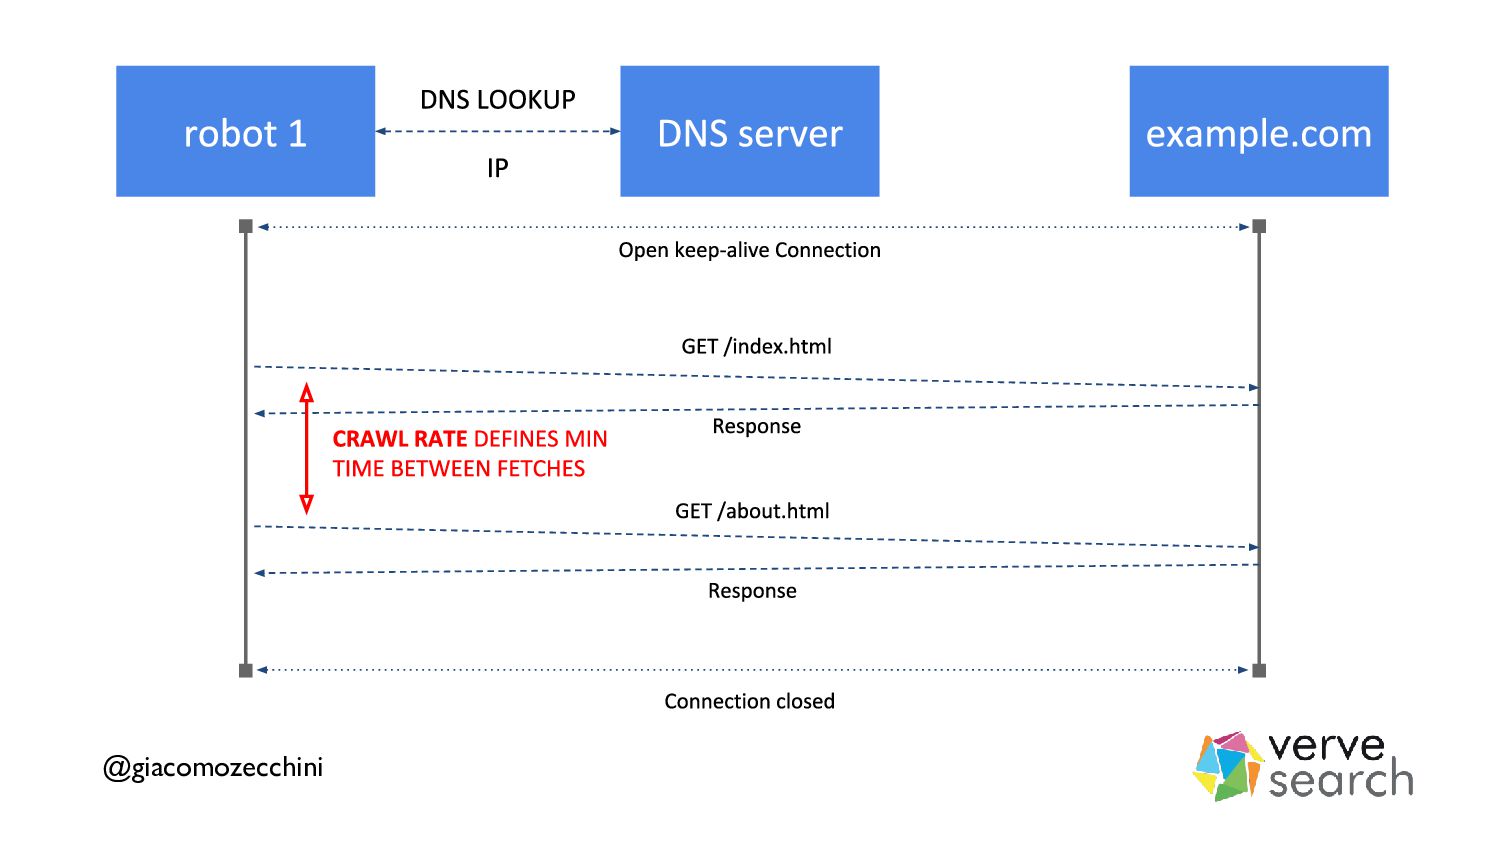
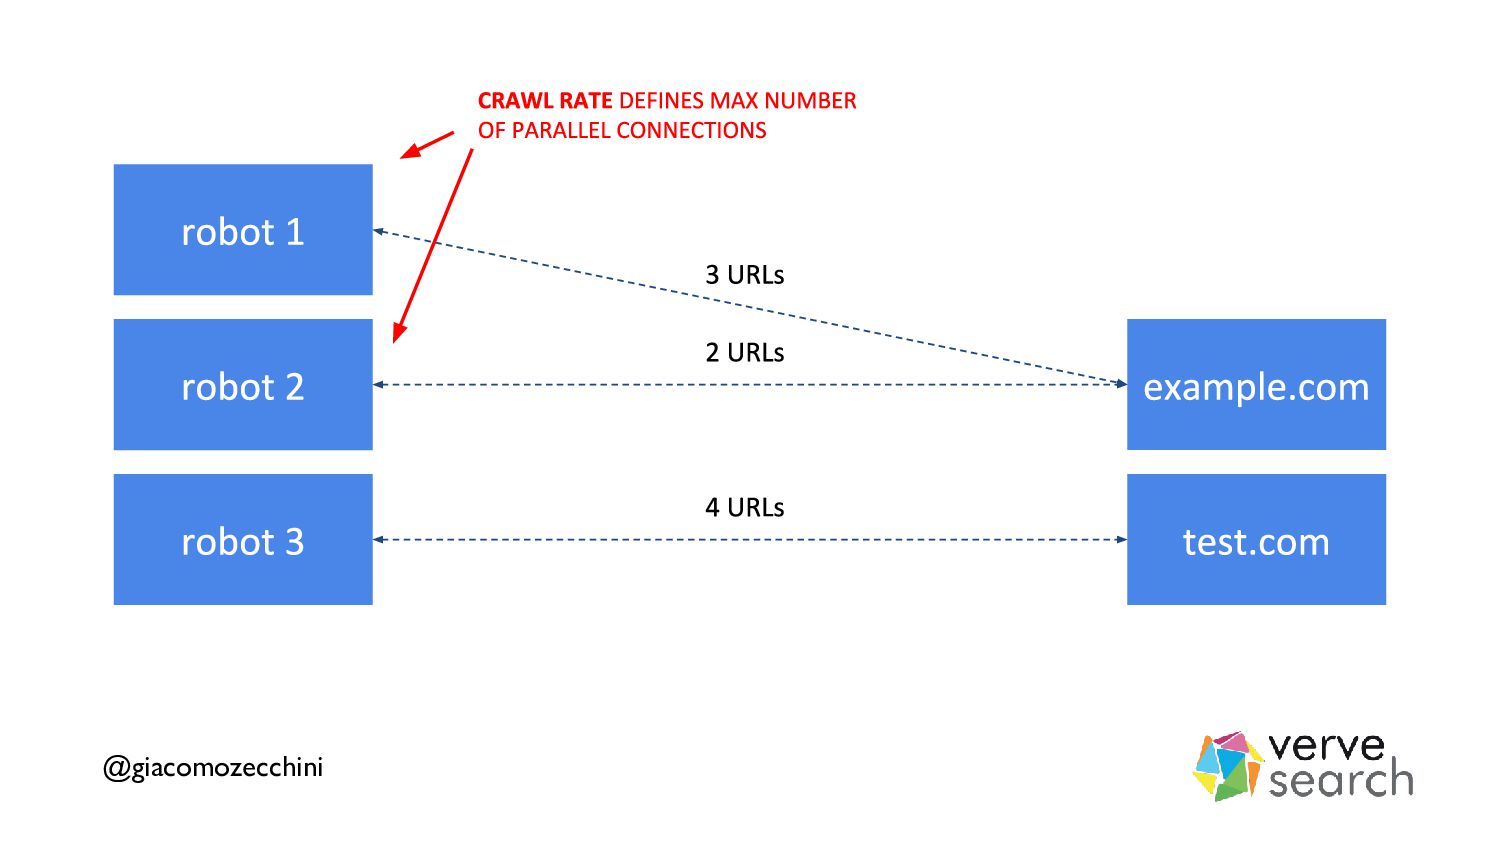
Crawler - Politeness - Crawl Rate Crawl Rate defines the
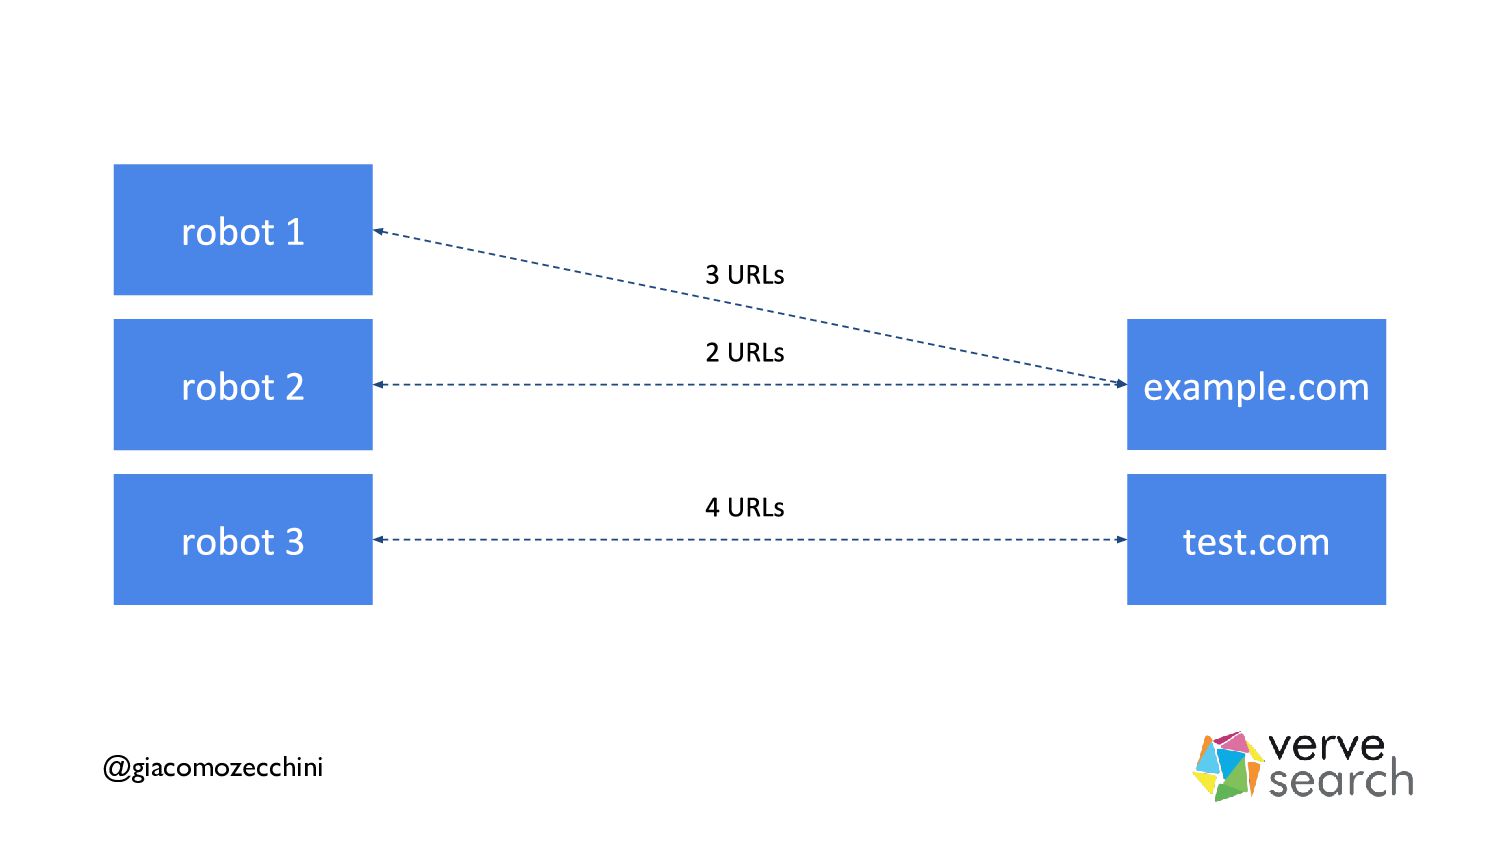
max number of parallel connections and the min time between fetches. Together with the Crawl Demand (Popularity + Staleness) is part of the Crawl Budget. https://webmasters.googleblog.com/2017/01/what-crawl-budget-means-for-googlebot.html @giacomozecchini -
Crawler - Politeness - Crawl Rate Crawl Rate is based
on the Crawl Health and the limit you can manually set in Search Console. Crawl Health is depending on the server response time. If the server is fast to answer, the crawl rate goes up. If the server slows down, starts emitting a significant number of 5xx errors or connection timeouts, crawling slows down. @giacomozecchini -
Crawler - Performance and Efficiency A crawler should make efficient
use of resources such as processor, storage, and network bandwidth. @giacomozecchini -
A crawler should make efficient use of resources, using HTTP
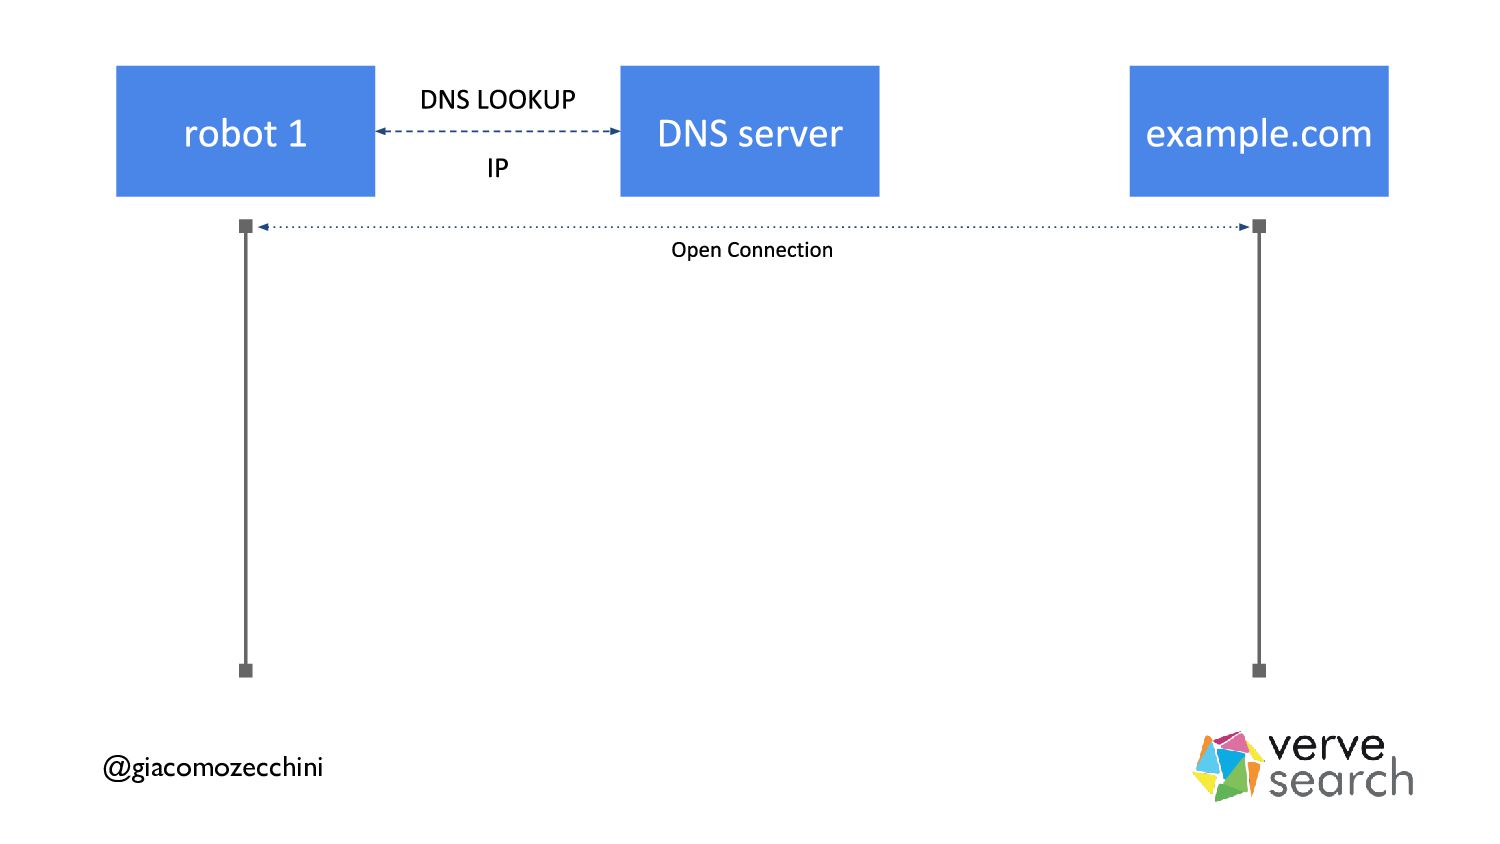
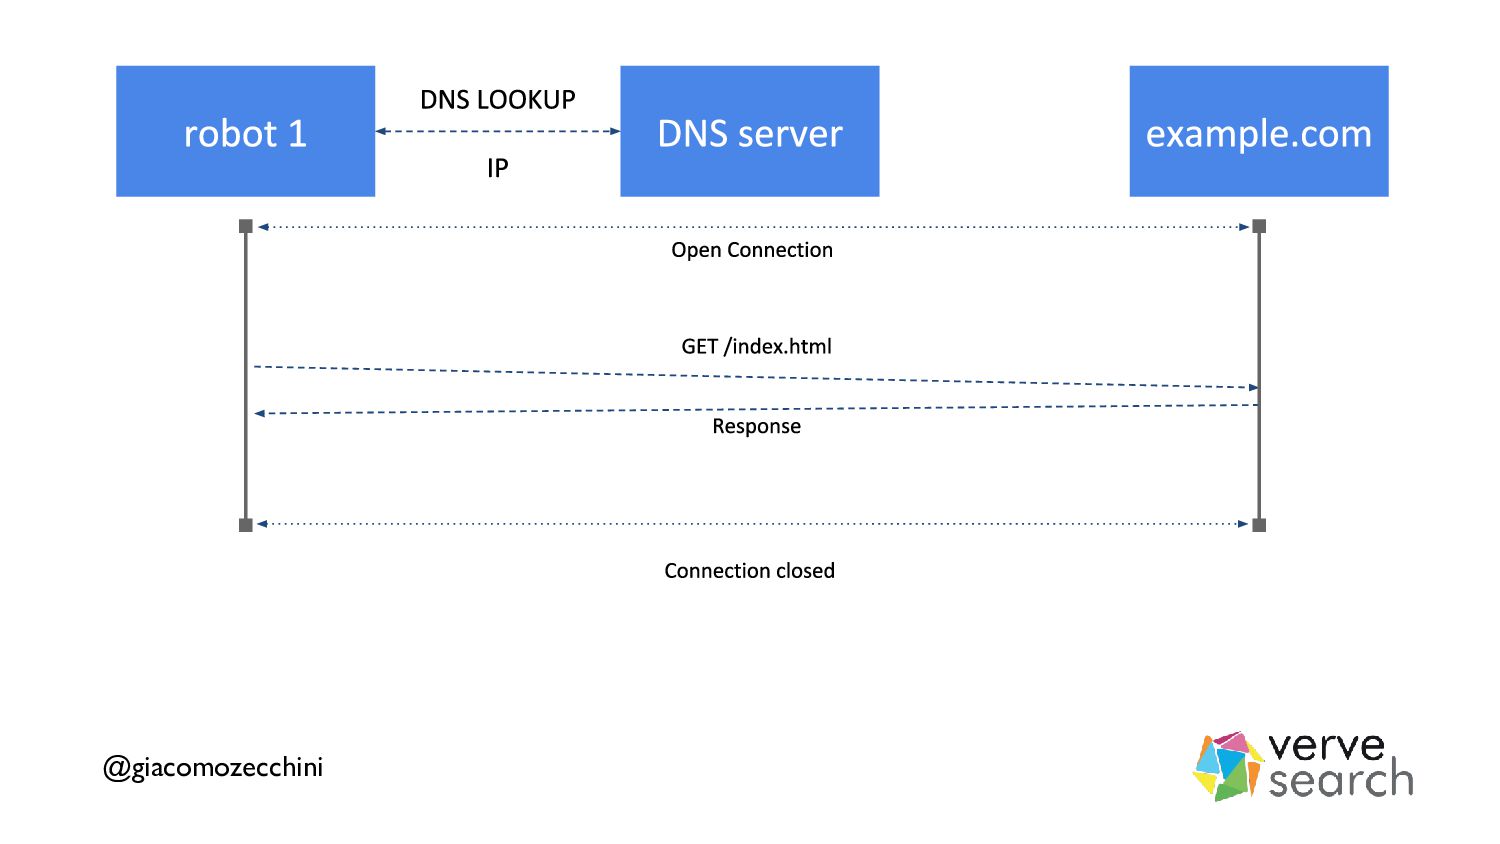
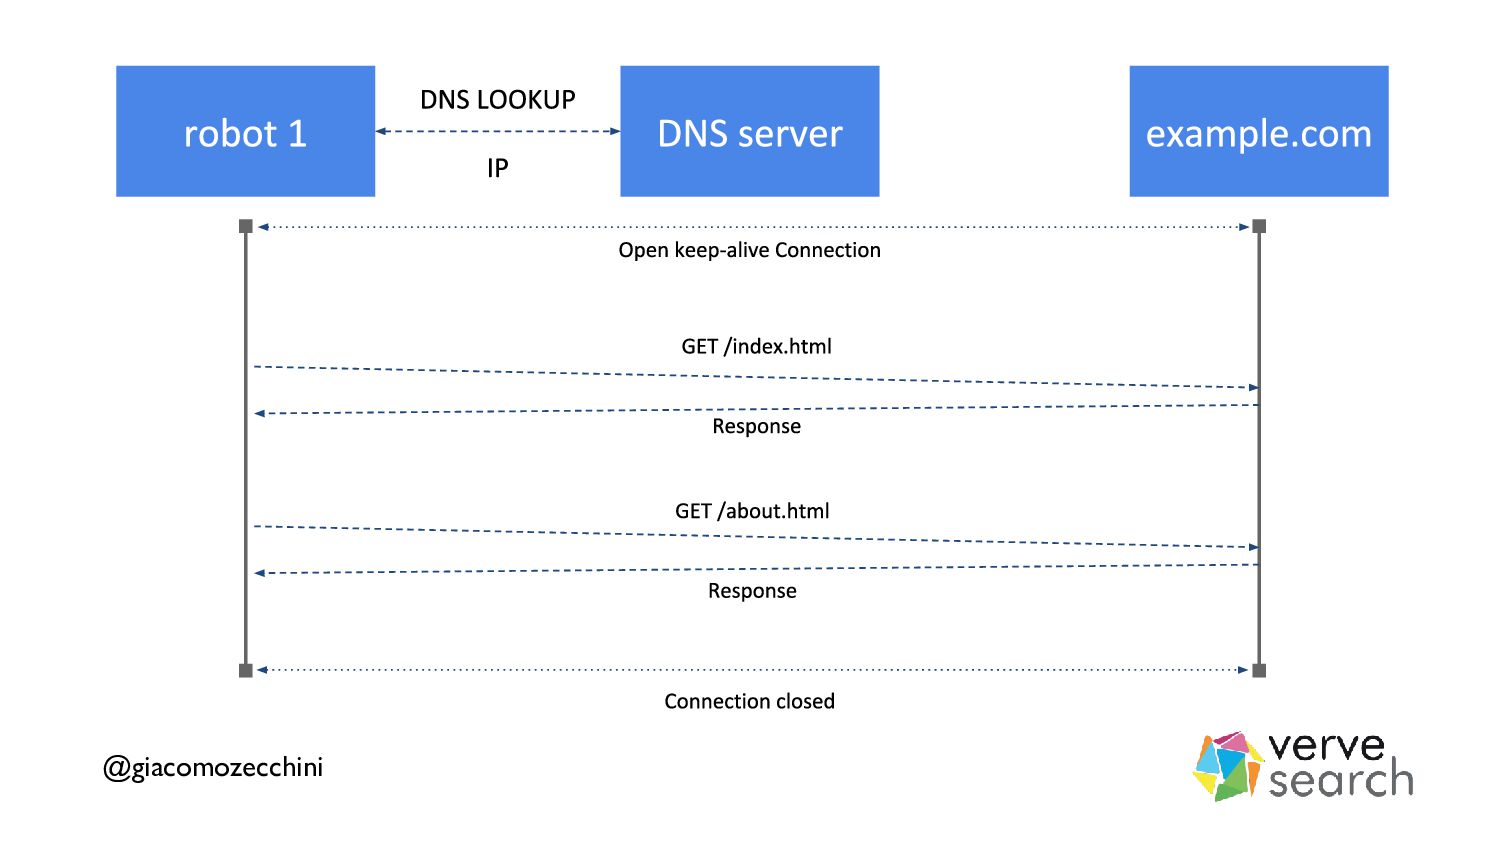
persistent connection, also called HTTP Keep-Alive connection, helps keeping robots (or threads) busy and saving time. Reusing the same TCP connection gives crawlers some advantages such as less latency in subsequent requests, less CPU usage (no multiple TLS handshakes), and reduced network congestion. @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 When I first started writing
this presentation all most popular Search Engines crawlers weren’t using HTTP/2 to make requests. @giacomozecchini -
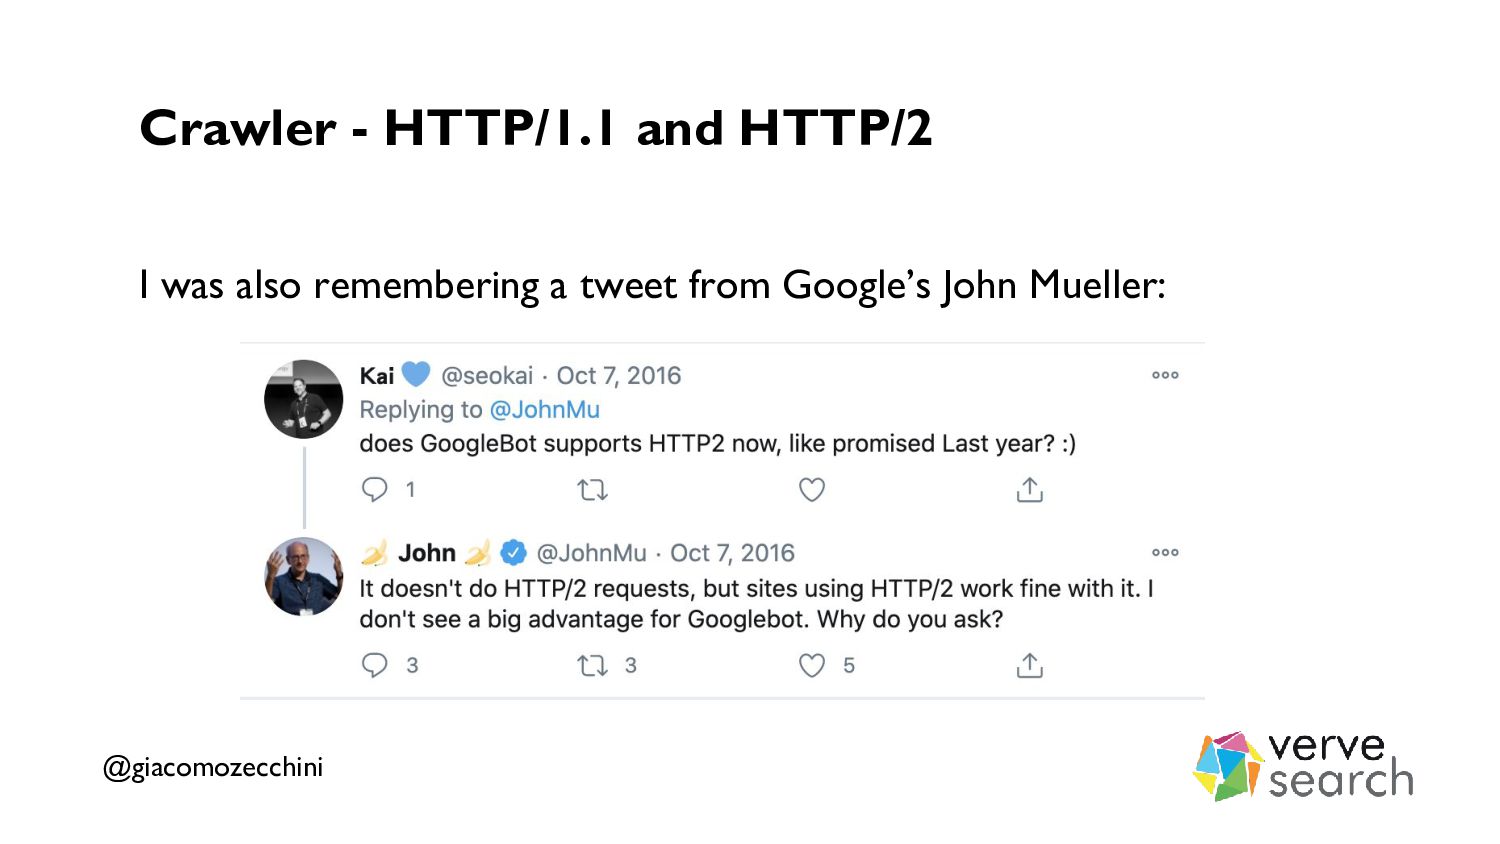
Crawler - HTTP/1.1 and HTTP/2 I was also remembering a
tweet from Google’s John Mueller: @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Instead of thinking “How can
crawlers benefit from using HTTP/2?”, I started my research from the (wrong) conclusion: crawlers have no advantages in using HTTP/2. @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Instead of thinking “How can
crawlers benefit from using HTTP/2?”, I started my research from the (wrong) conclusion: crawlers have no advantages in using HTTP/2. But then Google published this article: Googlebot will soon speak HTTP/2. https://webmasters.googleblog.com/2020/09/googlebot-will-soon-speak-http2.html @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 How can crawlers benefit from
using HTTP/2? From the Article: Some of the many, but most prominent benefits in using H2 include: • Multiplexing and concurrency • Header compression • Server push @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Multiplexing and concurrency What they
were achieving using multiple robots (or threads) each one with a single HTTP/1.1 connection will be possible using a single (or less) HTTP/2 connection with multiple parallel requests. Crawl Rate HTTP/1.1: max number of parallel connections Crawl Rate HTTP/2: max number of parallel requests @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Header Compression HTTP/2 HPACK compression
algorithms will reduce the amount of HTTP header sizes saving bandwidth. HPACK is even more effective for crawlers than browsers. Crawlers are stateless using mostly the same HTTP headers for request over and over and they might also request multiple pages (and assets) in one H2 connection. @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Server push “This feature is
not yet enabled; it's still in the evaluation phase. It may be beneficial for rendering, but we don't have anything specific to say about it at this point.” @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Server push “This feature is
not yet enabled; it's still in the evaluation phase. It may be beneficial for rendering, but we don't have anything specific to say about it at this point.” Google is making massive use of caching and this seems to be a really good reason to not use server push. I guess they will probably never enable this. @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Server push We are too
often looking at protocols in a browser-centric way, forgetting that other people might use a specific feature in a beneficial way. E.g. Rest API and server push @giacomozecchini -
Crawler - HTTP/1.1 and HTTP/2 Why it took Google so
long to approach HTTP/2? • Widely support and maturation of the protocol • Code complexity • Regression testing @giacomozecchini -
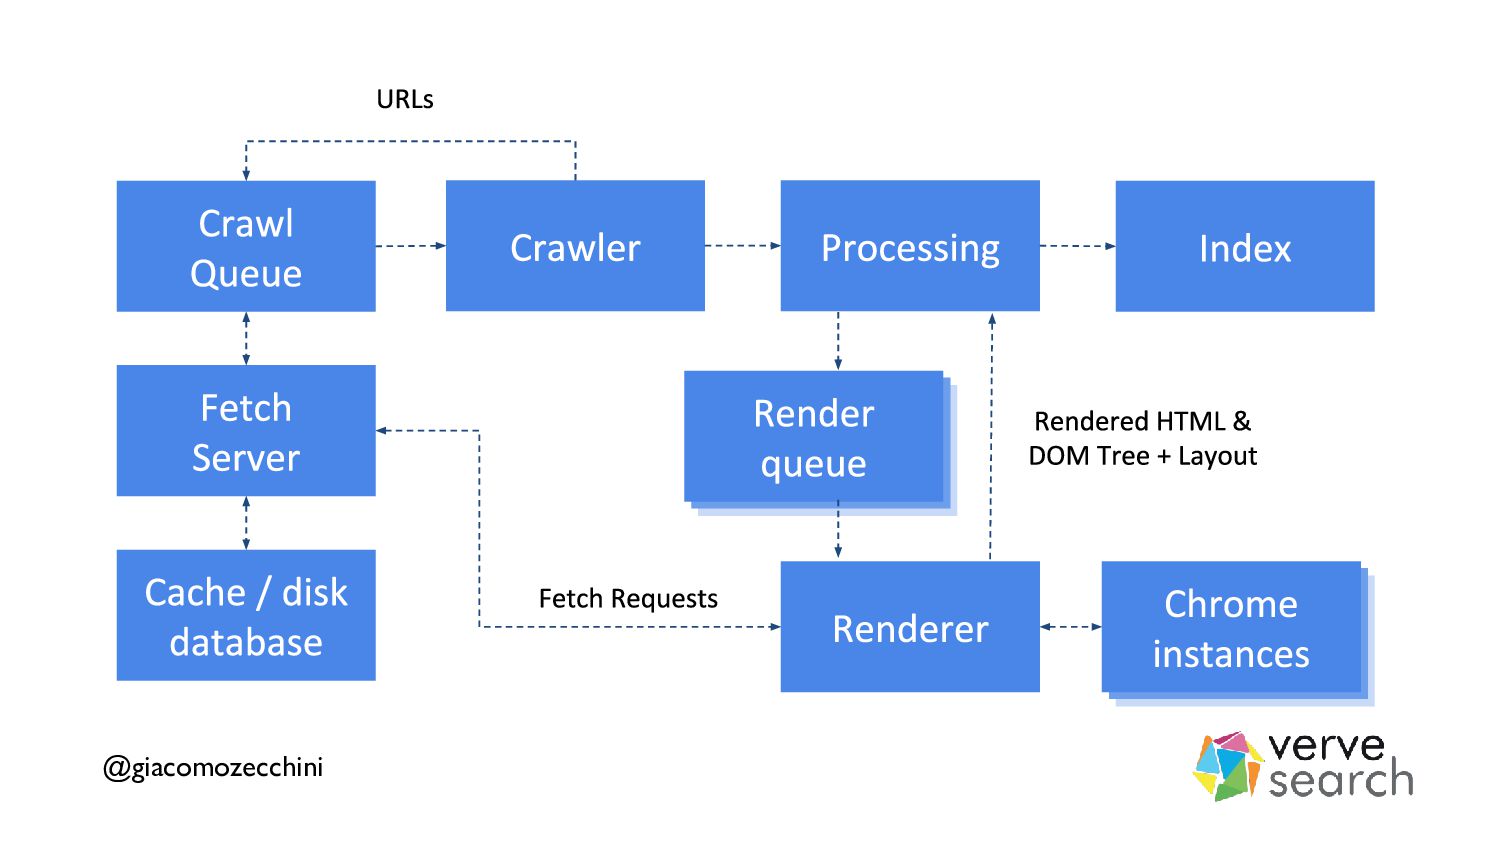
WRS (Web Rendering Service) Google is using a Web Rendering
Service in order to render pages for Search. It’s based on the Chromium rendering engine and is regularly updated to ensure support for the latest web platform features. https://webmasters.googleblog.com/2019/05/the-new-evergreen-googlebot.html @giacomozecchini -
WRS • Doesn’t obey HTTP caching rules WRS caches every
GET request for an undefined period of time (it uses an internal heuristic) @giacomozecchini -
WRS • Doesn’t obey HTTP caching rules • Limits the
number of fetches WRS might stop fetching resources after a number of requests or a period of time. It may not fetch known Analytics software. @giacomozecchini -
WRS • Doesn’t obey HTTP caching rules • Limits the
number of fetches • Built to be resilient WRS will process and render a page even if some fetches fails @giacomozecchini -
WRS • Doesn’t obey HTTP caching rules • Limits the
number of fetches • Built to be resilient • Might interrupt scripts (excessive CPU usage, error loops, etc) @giacomozecchini -
WRS If resources are not in the cache (or stale),
the crawler will request those on behalf of WRS. @giacomozecchini -
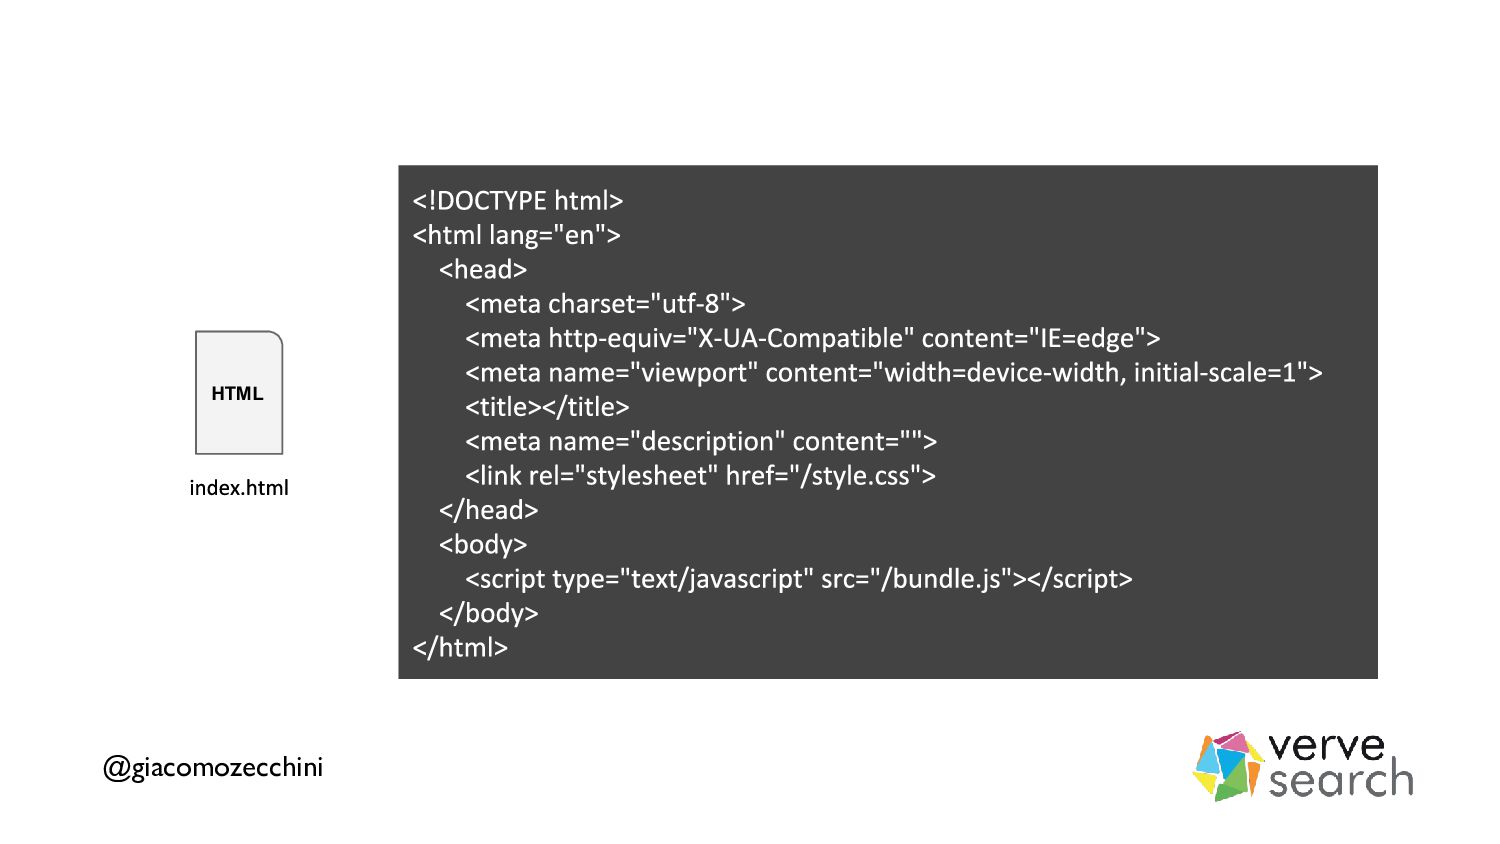
Cache and Rendering WRS is caching everything without respecting HTTP
caching rules. Using fingerprinting for file names and defining a cache busting strategy is the way to go: bundle.ap443f.js E.g. bundle.js will be cached for an undefined period of time (days, weeks, months) and will be used for rendering even if you change the code. @giacomozecchini -
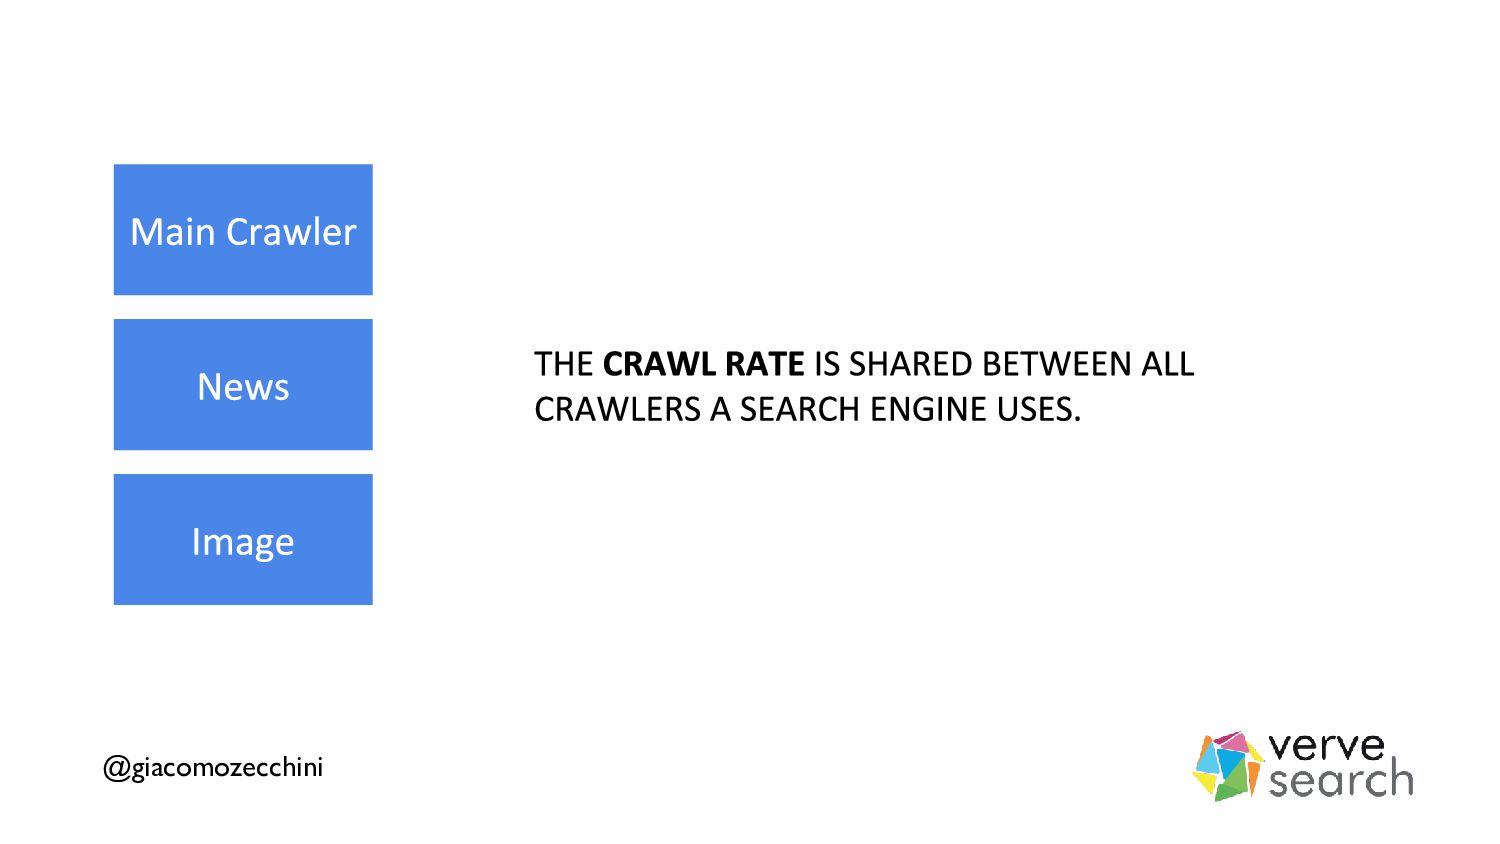
Crawl Rate and Rendering Crawl Rate is shared between crawlers
and even those requests that crawler makes on behalf of WRS don’t make an exception. If the server slows down during rendering, Crawl Rate will decrease and rendering may fail. Btw, rendering is quite resilient and it may retry later. Tip: Monitor server response time. @giacomozecchini -
Politeness and Rendering Robots.txt can block a crawler from requesting
a specific part of a website. What can go wrong? • If you are blocking a specific file, it won’t be fetched and used • If you have a JS script with a fetch/retry loop of a resource that is blocked from rule in your robots.txt, that script will be interrupted @giacomozecchini -
CPU usage and Rendering WRS limits CPU consumption and can
block excessive script run. Performance matters: you should analyse runtime performance, debug issues and remove bottlenecks. @giacomozecchini -
Third-party stuff Third-party can cause a few problems: • Resources
can be blocked through robots.txt on their domains • Request timeouts, connection errors @giacomozecchini -
Cookies Cookies, local storage and session storage are enabled but
cleared across page loads. If you are checking the presence of a specific cookie to redirect or not a user to a welcome page, WRS won’t be able to render those pages. @giacomozecchini -
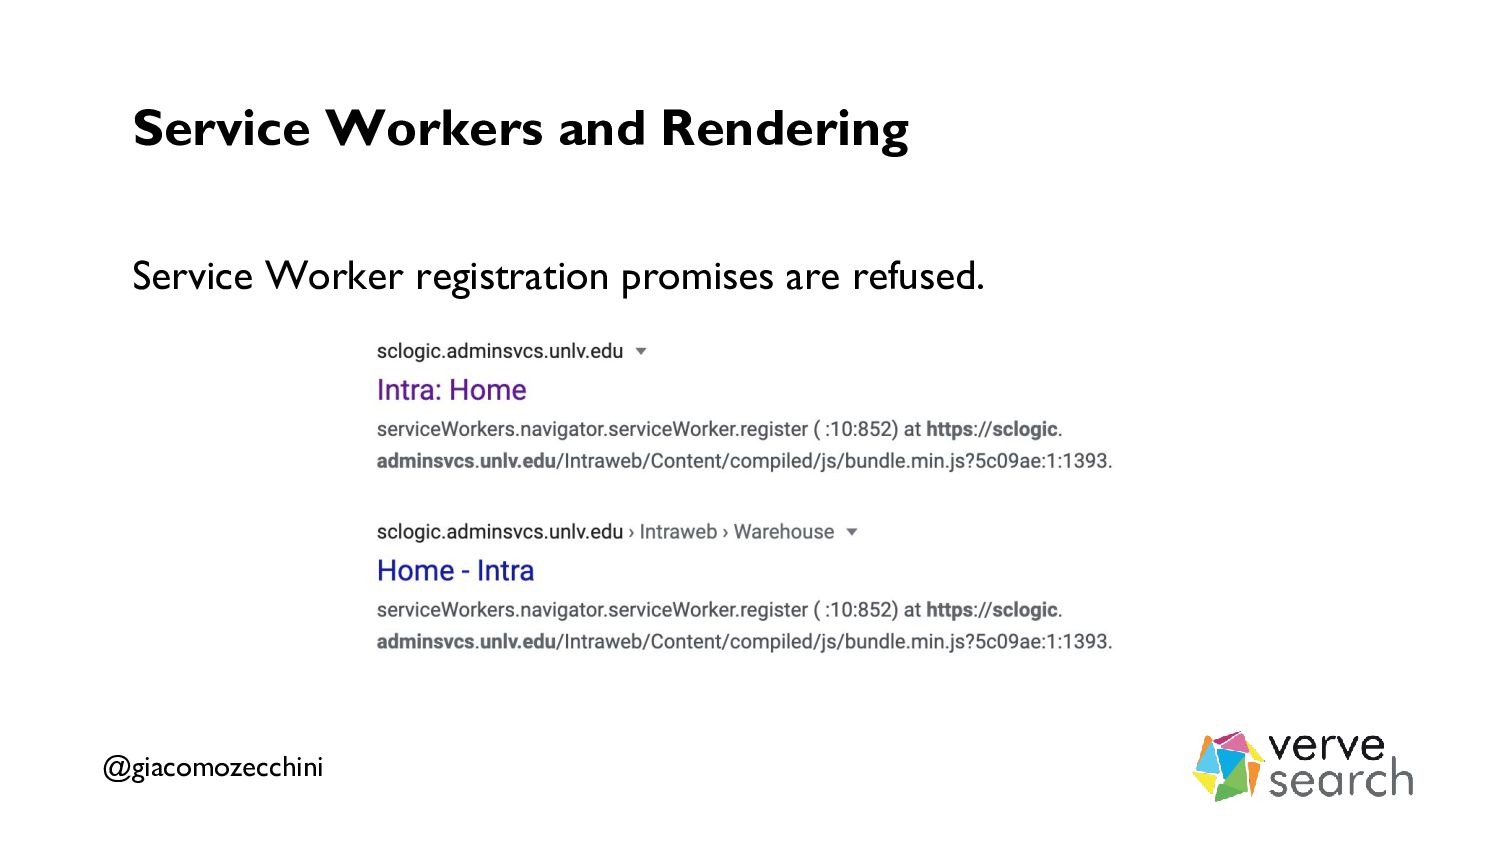
Service Workers and Rendering Service Worker registration promises are refused.
Web Workers are supported. @giacomozecchini -
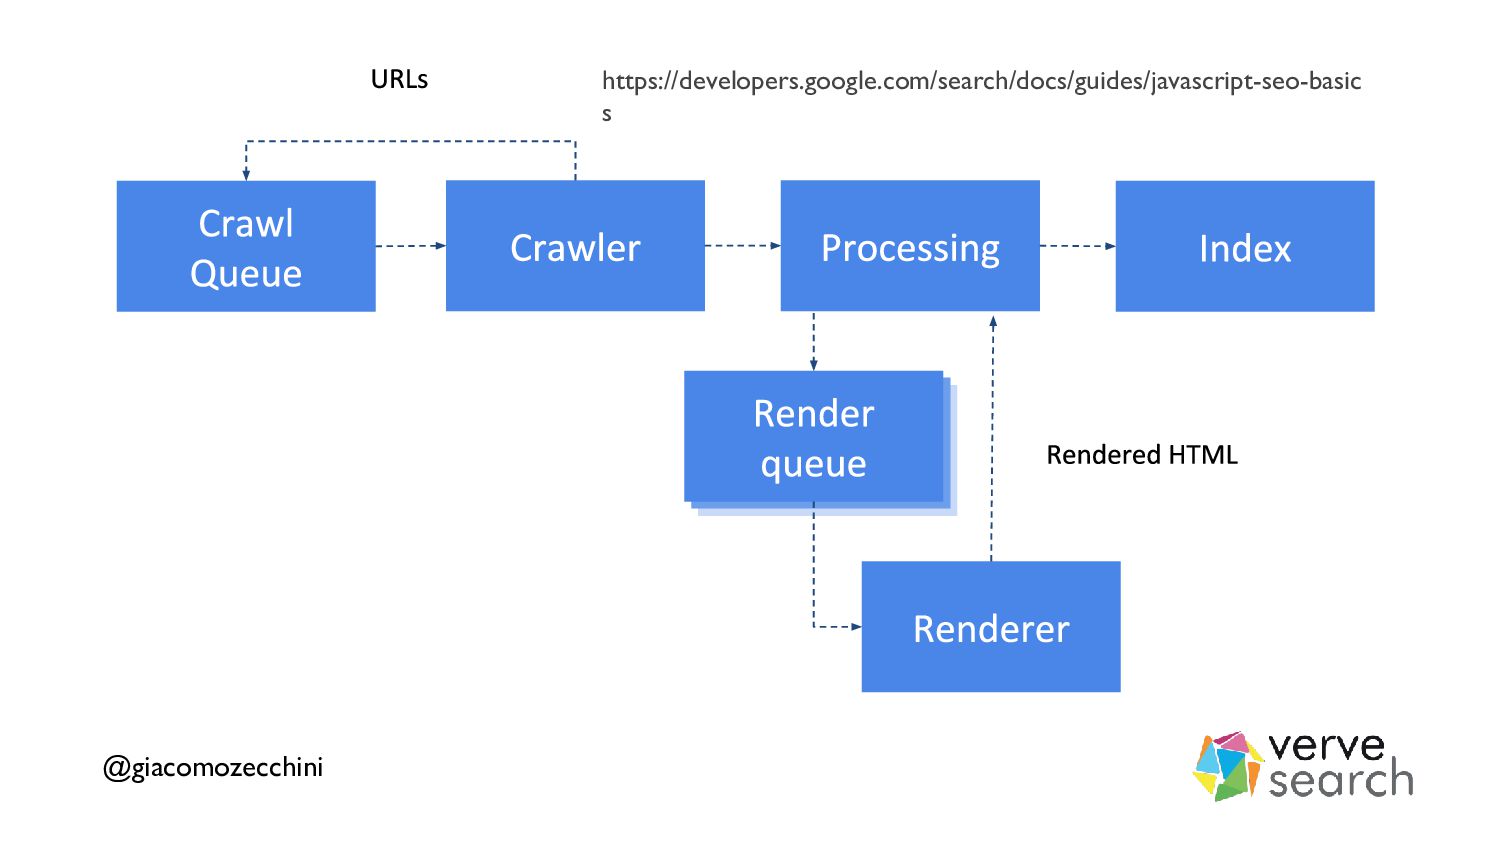
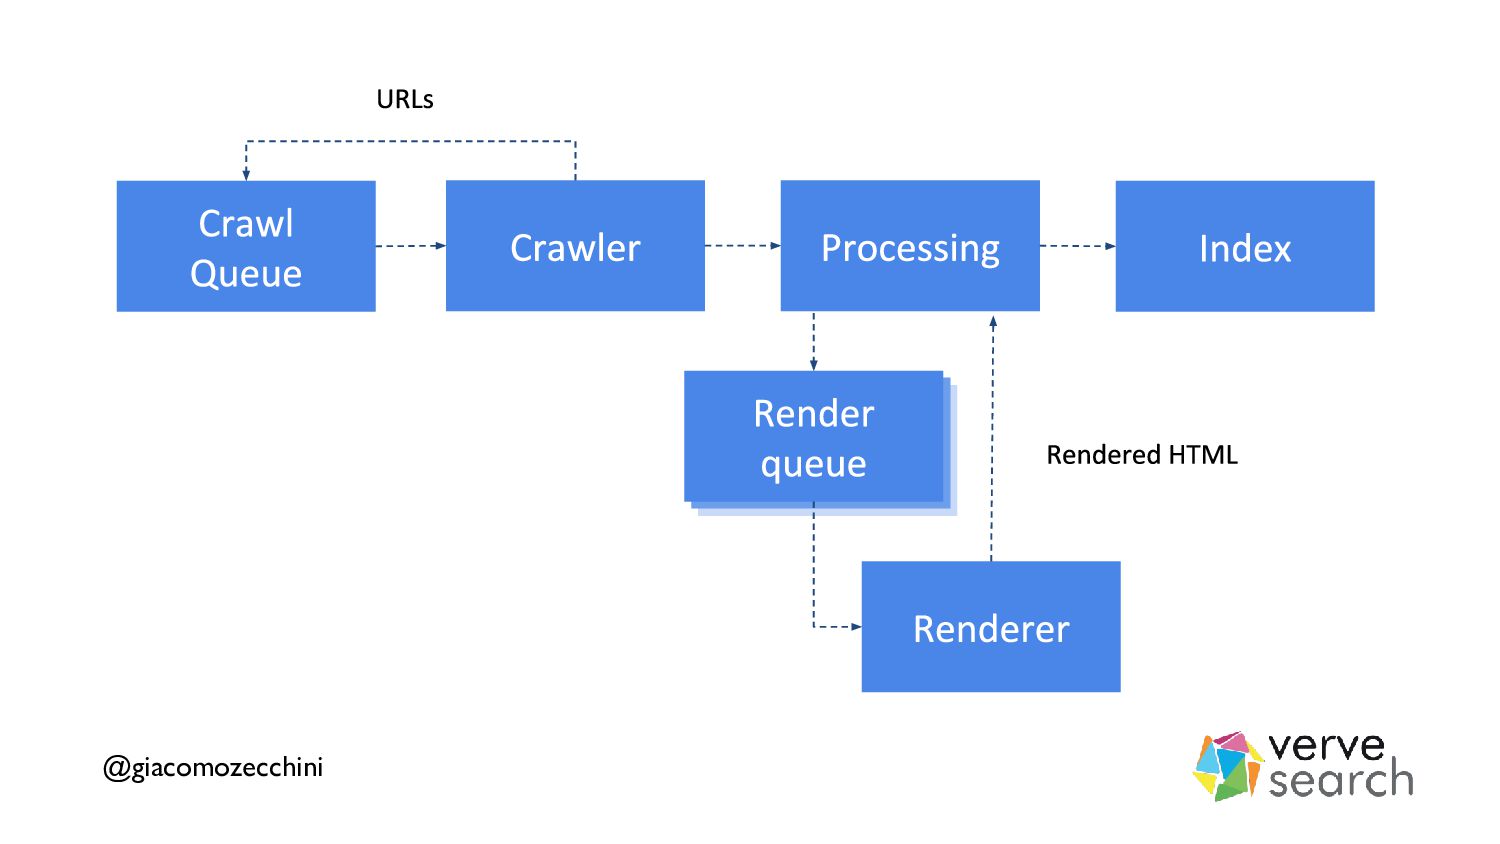
Render Queue and Rendering Google states that the Render Queue
median time is ~5 seconds. In the past this wasn't true and pages were waiting hours/days to be rendered. This might still be true for other search engines. @giacomozecchini -
Render Queue and Rendering I believe Google reduced Render Queue
time for two main big reasons: • Freshness • Errors with assets / dependencies @giacomozecchini -
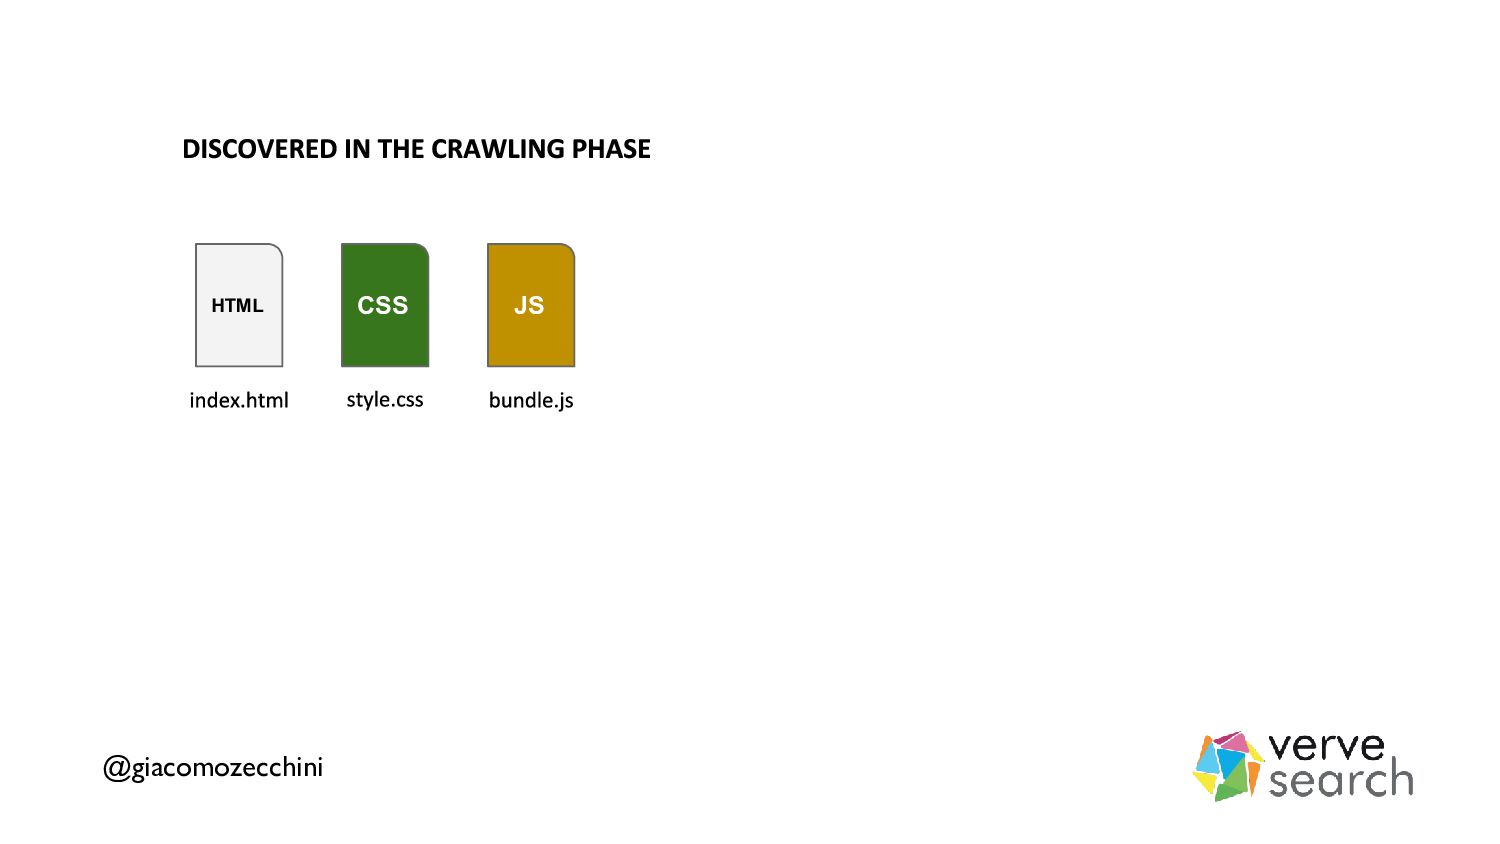
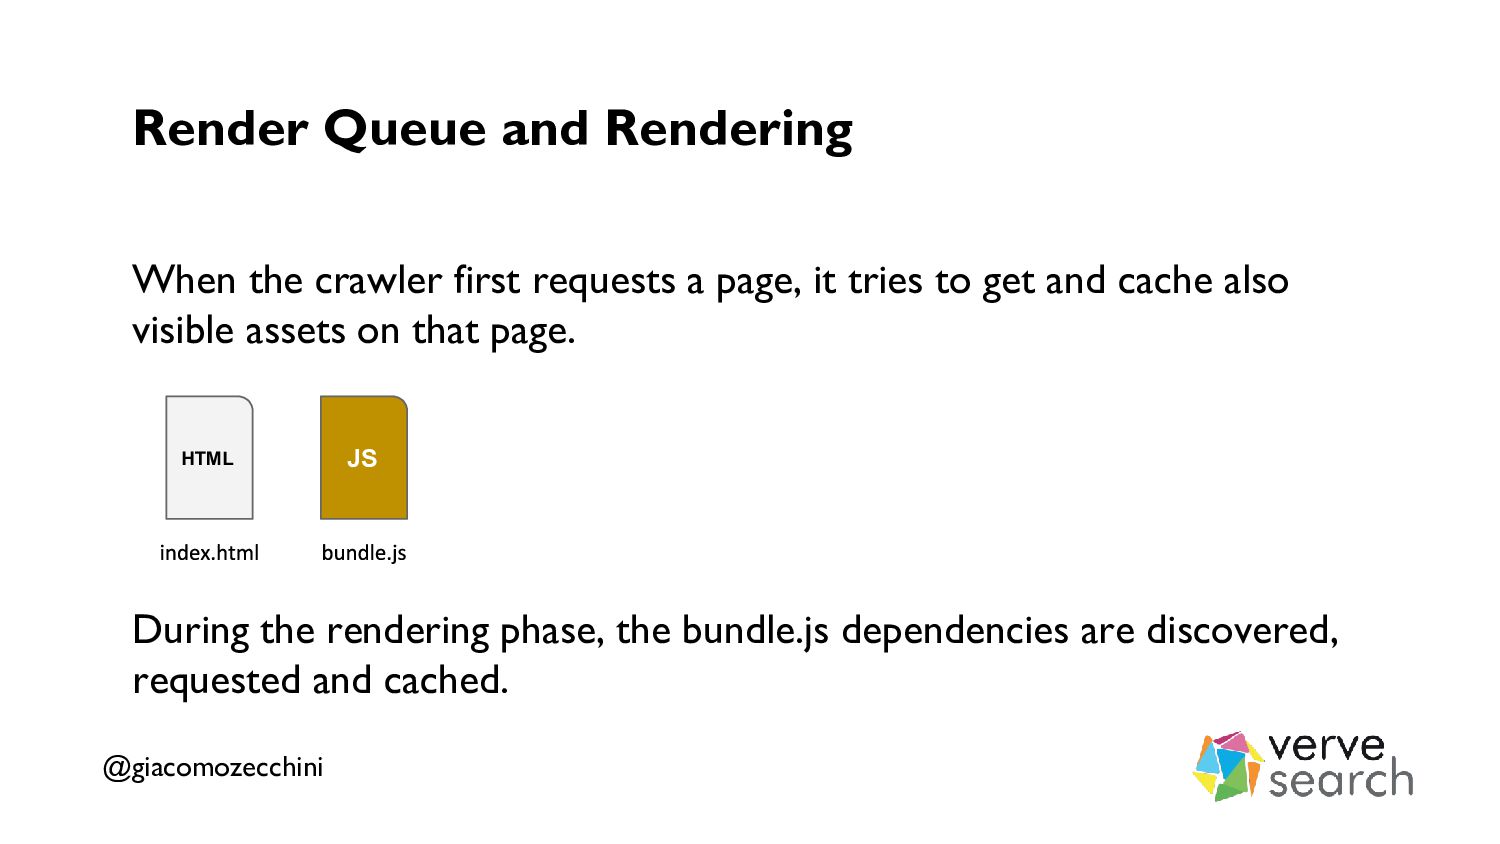
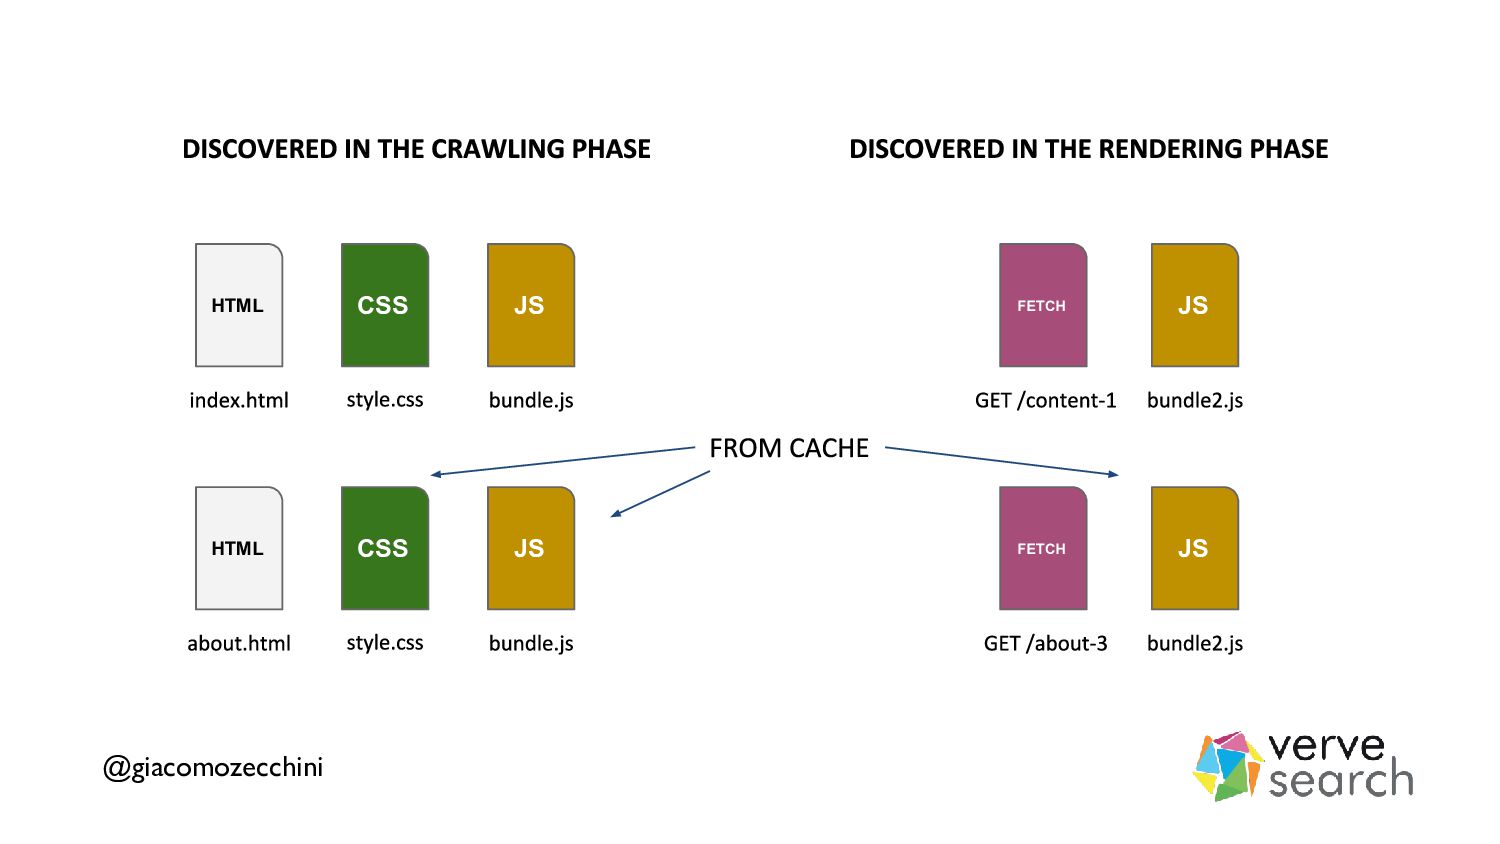
Render Queue and Rendering When the crawler first requests a
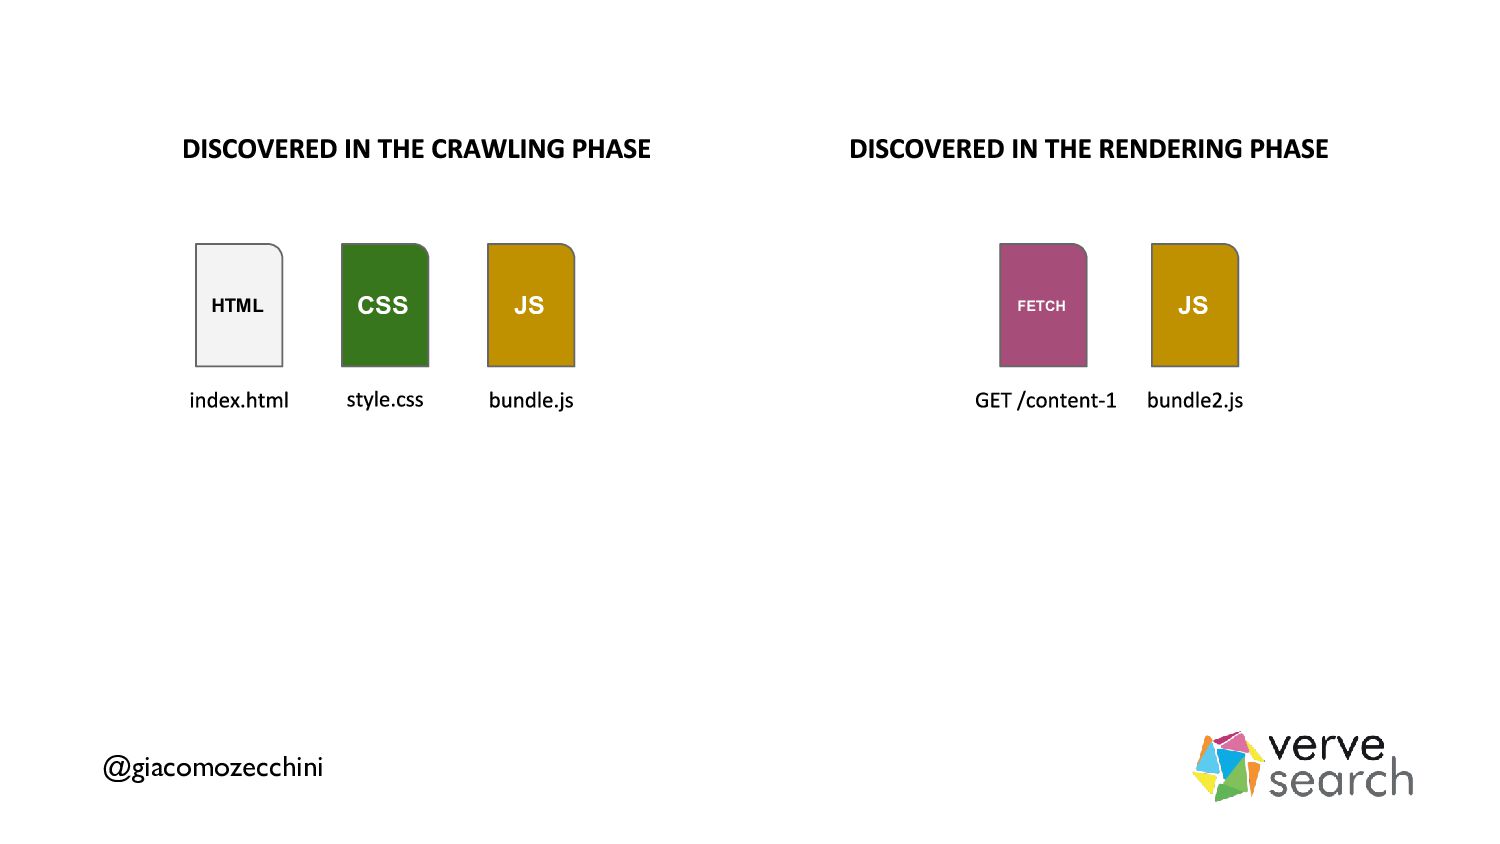
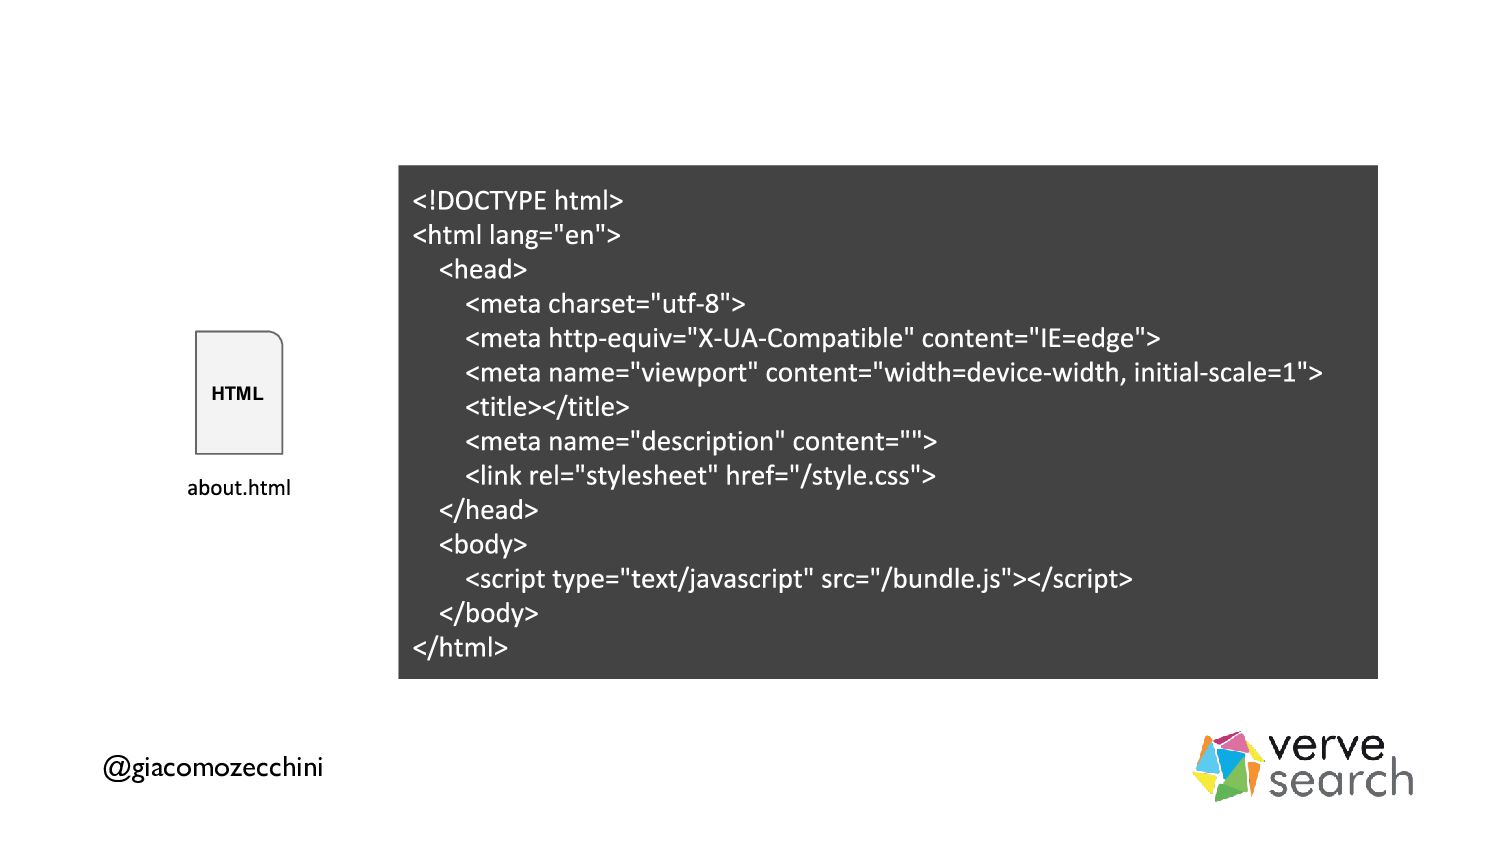
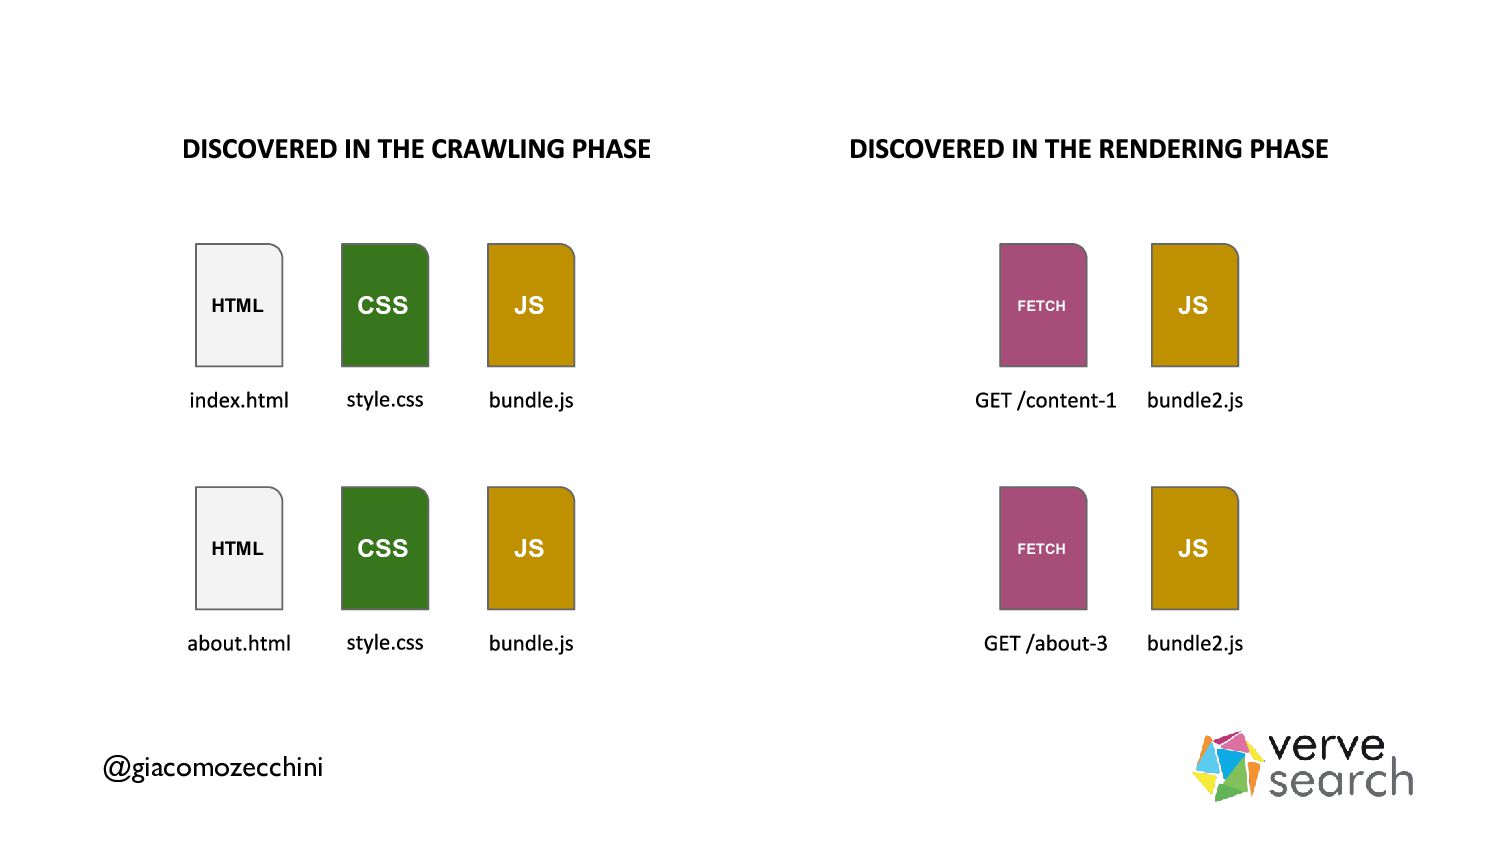
page, it tries to get and cache also visible assets on that page. During the rendering phase, the bundle.js dependencies are discovered, requested and cached. @giacomozecchini HTML JS -
Render Queue and Rendering But, if you delete the dependencies
of bundle.js before the rendering phase, they can’t be fetched even if bundle.js is cached. I guess this was happening a lot in the past but it shouldn’t happen anymore at least in Google’s WRS, as the time span between the two phases is very short. Not sure about other search engines yet. TIP: keep old assets for a bit, even if not using those anymore. @giacomozecchini -
Browser Events and Rendering WRS Chrome instances don’t scroll or
click, if you want to use Javascript lazy load functionalities use the Intersection Observer. WRS Chrome instances start rendering pages with two fixed viewports for mobile (412 x 732) and desktop (1024 x 1024). And then, they increase the viewport height size to a very big number of pixels (tens of thousands), that is dynamically calculated on a page base. @giacomozecchini -
Debugging Rendering problems Search Console is the best way to
do it. @giacomozecchini -
Debugging Rendering problems Search Console is the best way to
do it. @giacomozecchini -
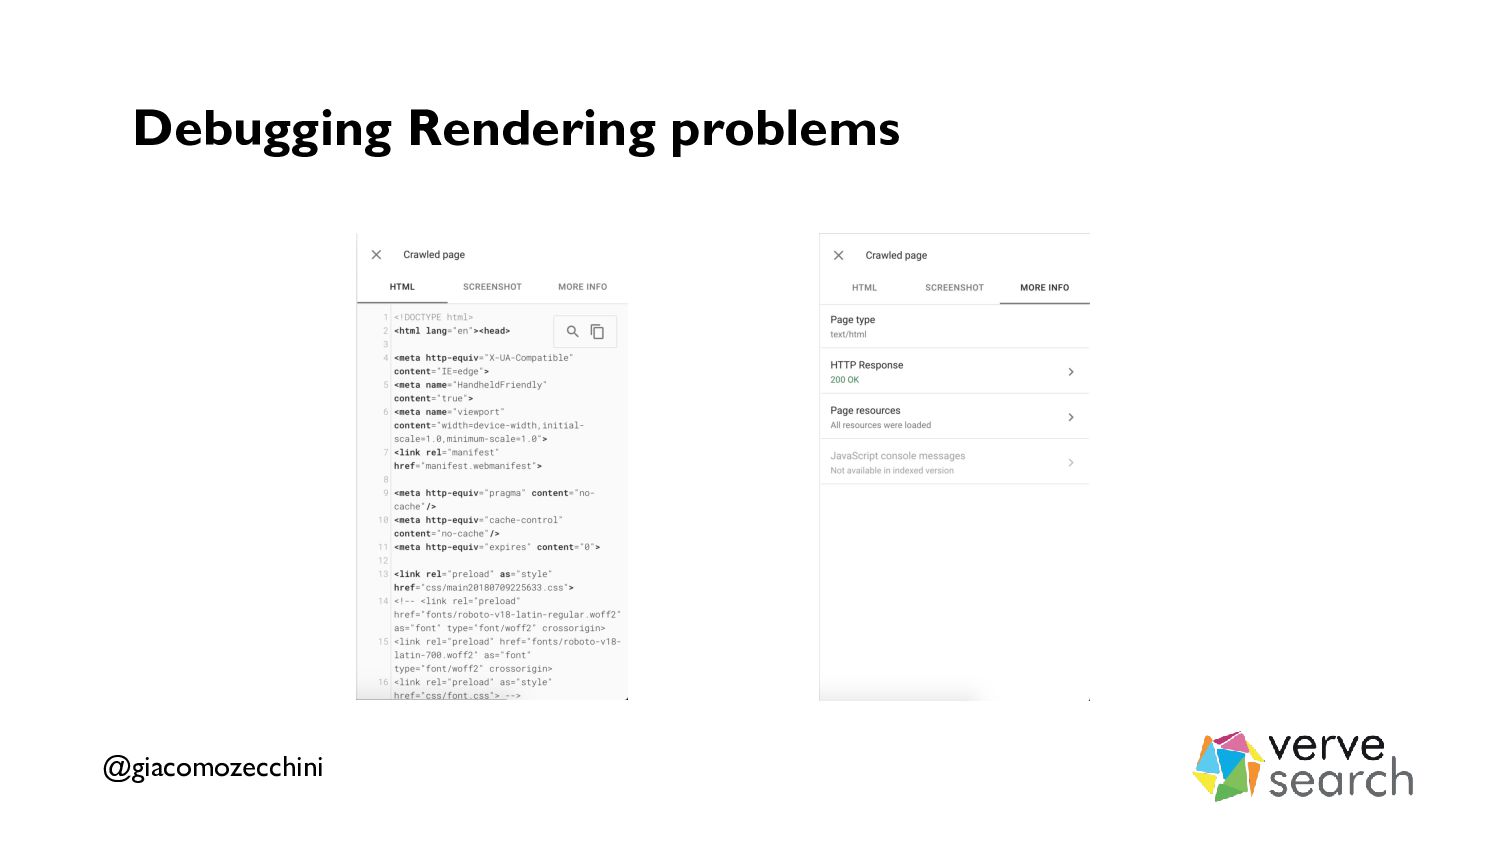
Debugging Rendering problems In the “page resource” tab you shouldn't
worry if there are error for FONTs, IMAGEs and Analytics Js files. Those file are not requested in the rendering phase. @giacomozecchini -
Debugging Rendering problems If you haven’t Search Console access, you
can use Mobile-Friendly Test. WARNING Mobile-Friendly Test, Search Console Live Test, AMP Test, and Rich Results Test are using the same infrastructure as WRS, but bypassing cache and using stricter timeouts than Googlebot / WRS, final results can be very different. https://youtu.be/24TZiDVBwSY?t=816 @giacomozecchini