Share
Validating Session Isolation for Web Crawling to Provide Data Integrity
Deep dive into session isolation and why search engines render pages in isolated rendering sessions to avoid having the rendering of one web page affect the functionality or the content of another.
Web crawling tools aim to replicate search engines' crawling and rendering behaviours by implementing and using web rendering systems. This offers insights into what search engines might see when they are crawling and rendering web pages.
While there is no defined standard for an automated rendering process, search engines (e.g. Google, Bing, Yandex) render pages in isolated rendering sessions. This way, they avoid having the rendering of one web page affect the functionality or the content of another. Isolated rendering sessions should have isolated storage and avoid cross-tab talking.
Giacomo Zecchini
Transcript
82 slides
-
• Web Rendering, Search Engines, and Web Crawlers • Research
context • What is Session Isolation? • Session Isolation in the wild • Solving Session Isolation • Tests • Conclusion Table of contents @giacomozecchini -
We are not in the 90s anymore As new web
rendering patterns got traction on the web, we moved from static HTML pages to more complex ways of rendering content. @giacomozecchini https://www.patterns.dev/posts/rendering-introduction/ -
New rendering patterns emerged With the massive use of rendering
patterns such as Client-Side Rendering and Progressive Hydration, search engines were somehow forced to start rendering web pages and retrieve almost as much content as the users would get with their browsers. @giacomozecchini https://developers.google.com/search/docs/crawling-indexing/javascript/javascript-seo-basics -
Web Rendering Systems to save the day Search Engines have
developed their own web rendering systems (or web rendering services). These are a piece of software that is able to render a large number of web pages by using automated browsers. @giacomozecchini “Googlebot & JavaScript: A Closer Look at the WRS” by Martin Splitt: https://www.youtube.com/watch?v=Qxd_d9m9vzo -
Web Crawler tools followed Search Engines Web crawling tools also
started to build rendering systems to keep up with the evolution of the web and mimic search engines' capabilities. @giacomozecchini -
But rendering is hard! There is no industry standard for
rendering pages, which means that not even leading search engines such as Google are doing it in the “correct” way. Each web rendering system is built to serve specific use cases, which results in inevitable tradeoffs. @giacomozecchini -
At Merj we’ve been happy users of many web crawling
tools and during the years we probably used all of them at least once. We’ve been using web crawling tools for years @giacomozecchini -
We’ve been building custom WRS solutions For use cases such
as custom data sources in complex data pipelines for enterprises, we have been building our own web crawling systems . @giacomozecchini -
Data integrity assurances The starting point of this research was
a recent project that required us to provide assurances to a legal and compliance team about the data quality and integrity of a data source (rendered pages). These were to be ingested into a machine learning model. @giacomozecchini -
Data validation process In addition to other checks present in
our data integrity validation process, we tested the output of multiple web crawling tools. We found some unexpected values which varied across tools. @giacomozecchini -
What is Session Isolation? While rendering a page in an
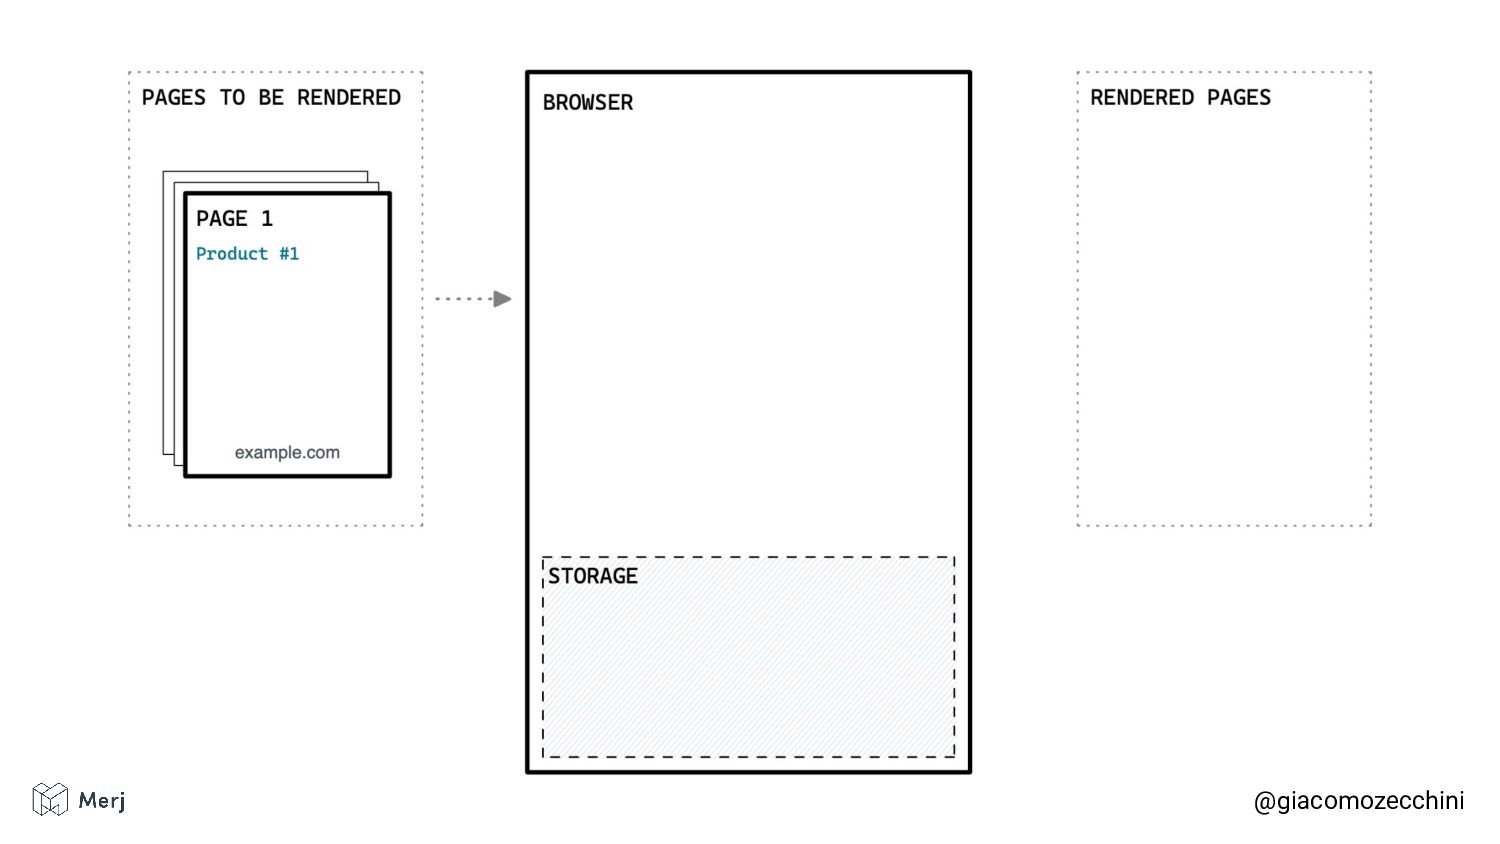
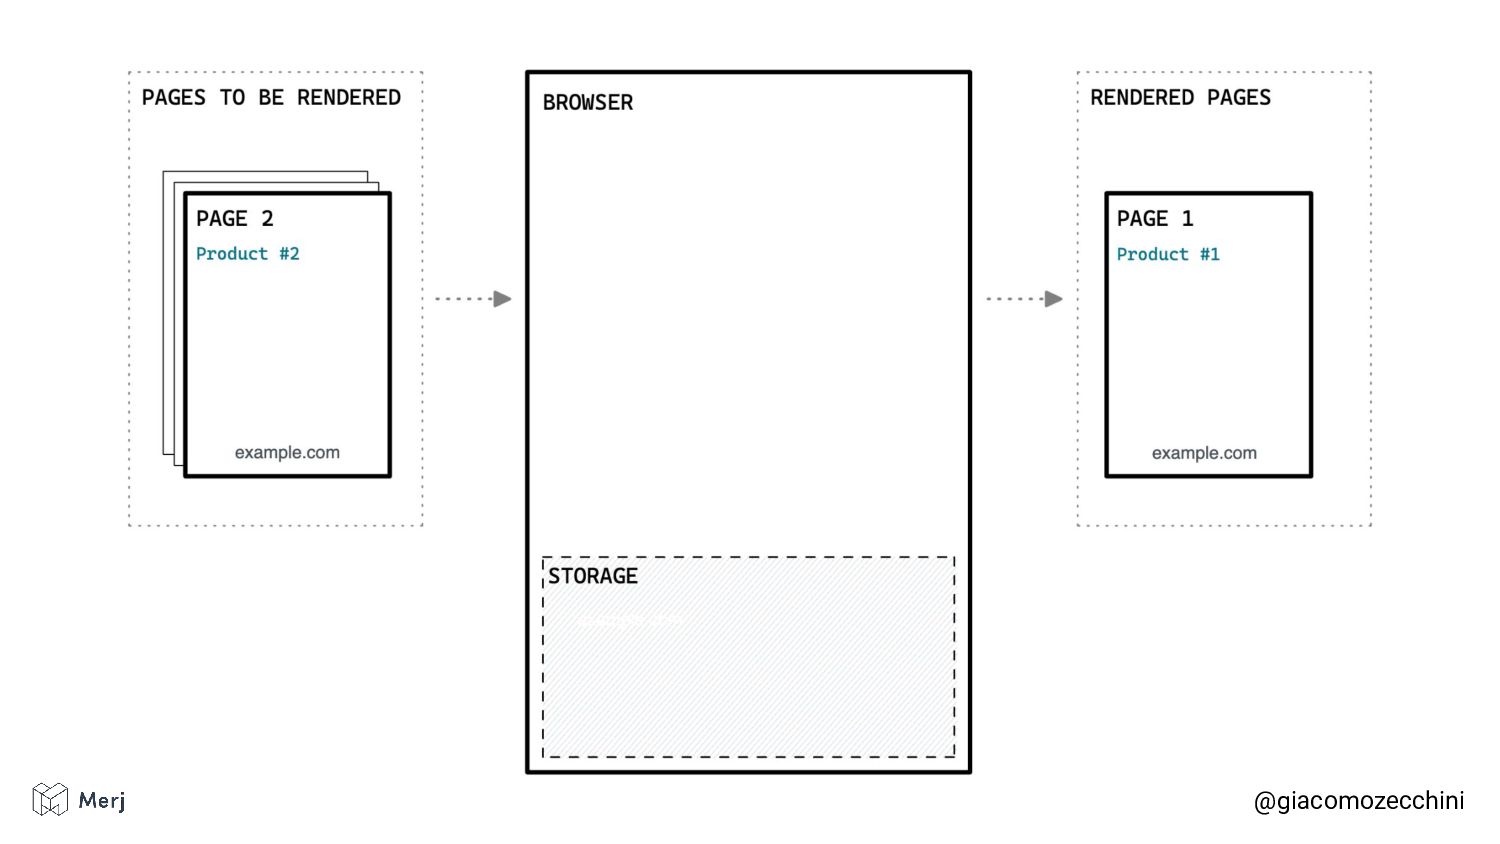
isolated rendering session, the page must not be able to get any data from previous rendering sessions and be influenced by other pages' renderings. @giacomozecchini -
Stateless is a similar concept This is similar to the
concept of “stateless” as used for web crawlers, where all fetches are completed without reusing cookies and without keeping in memory any specific data. @giacomozecchini -
Content customisations based on navigation Session isolation real world problems
can be found by observing the rendering of pages that have content customisations based on user navigation. @giacomozecchini -
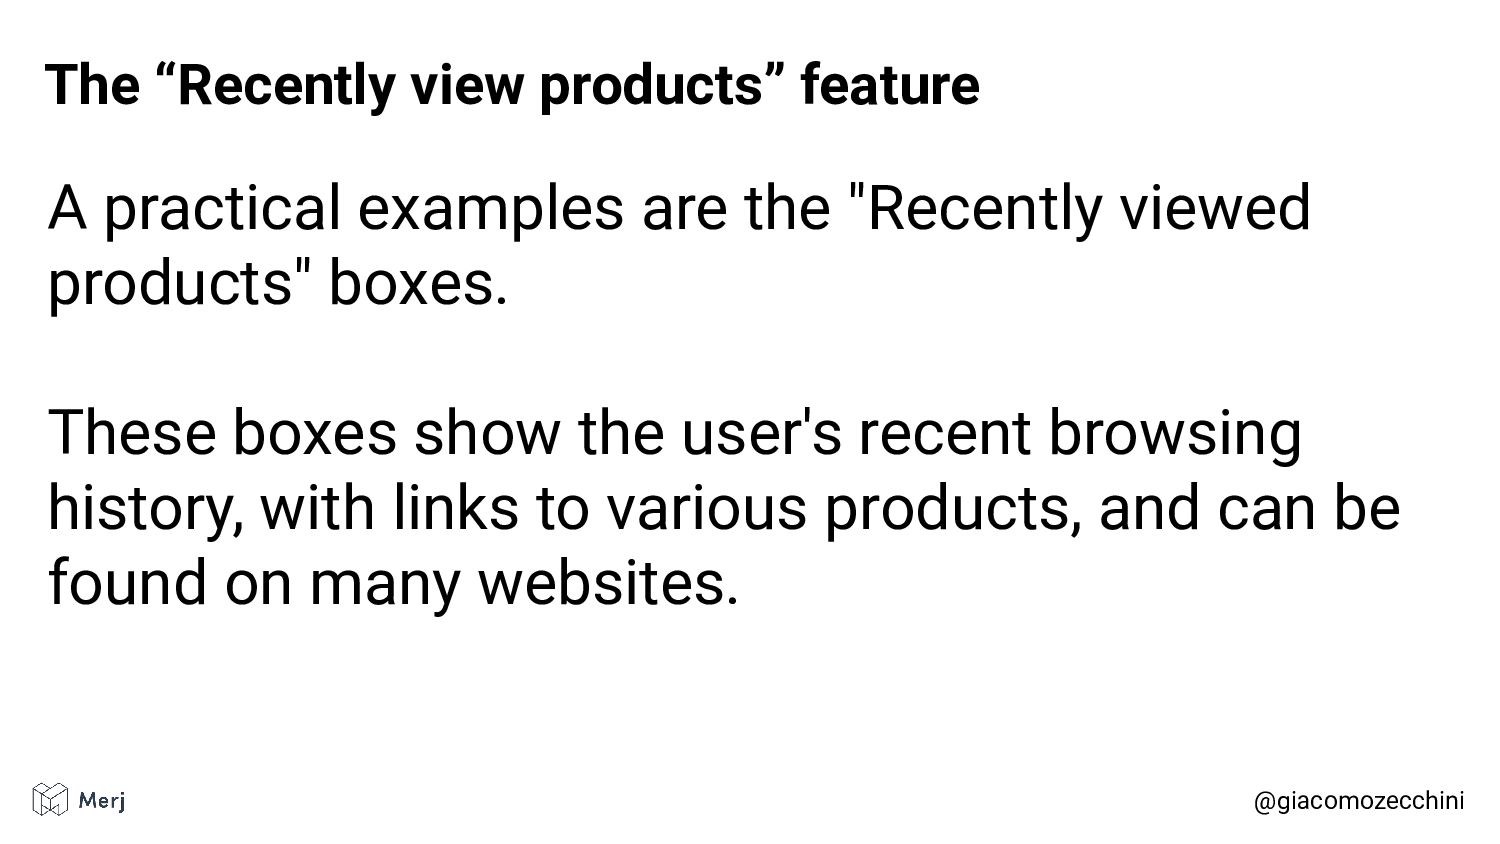
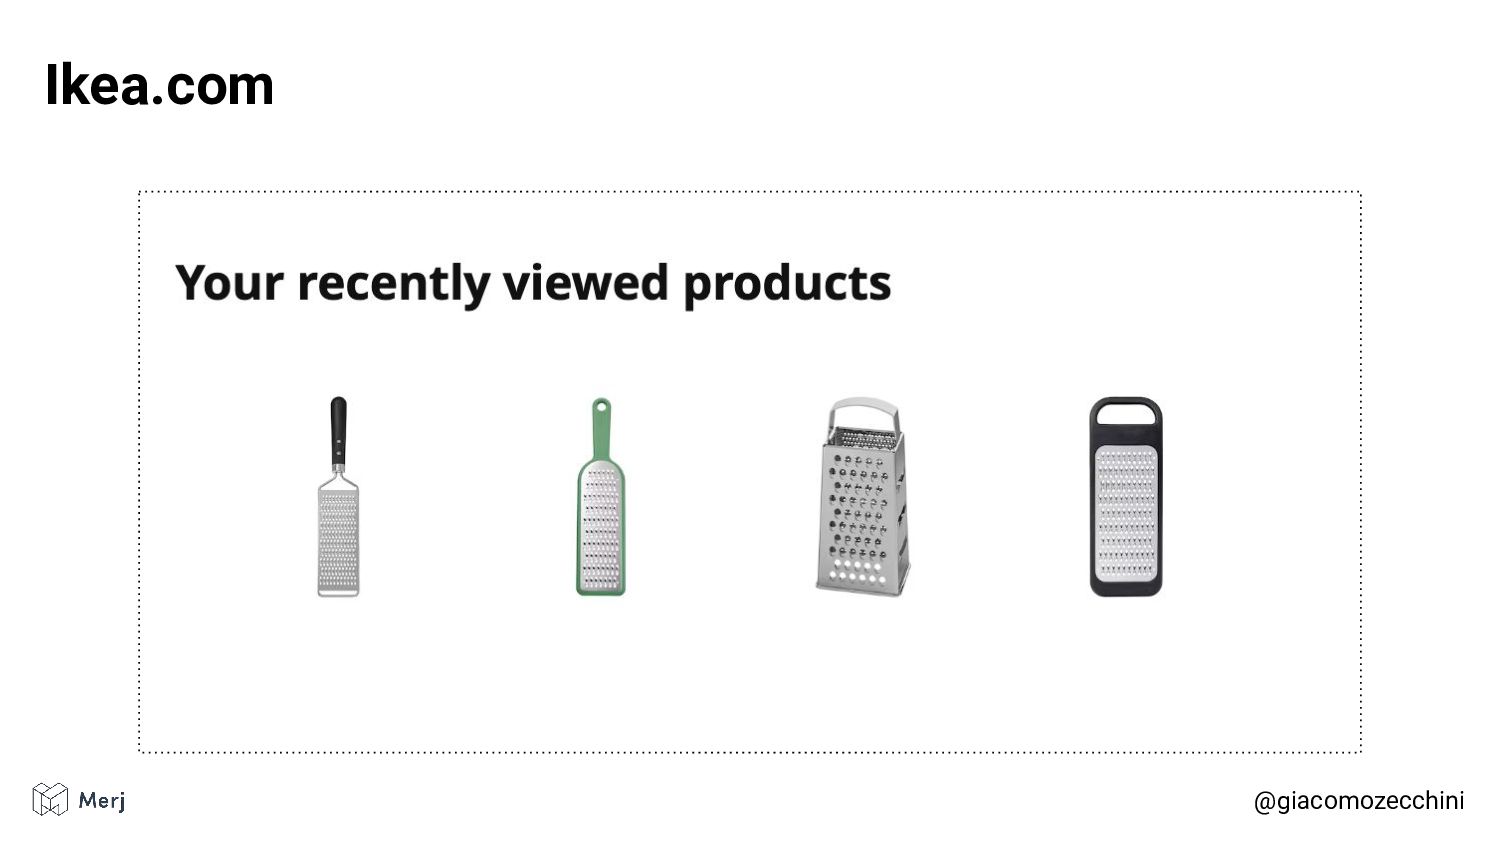
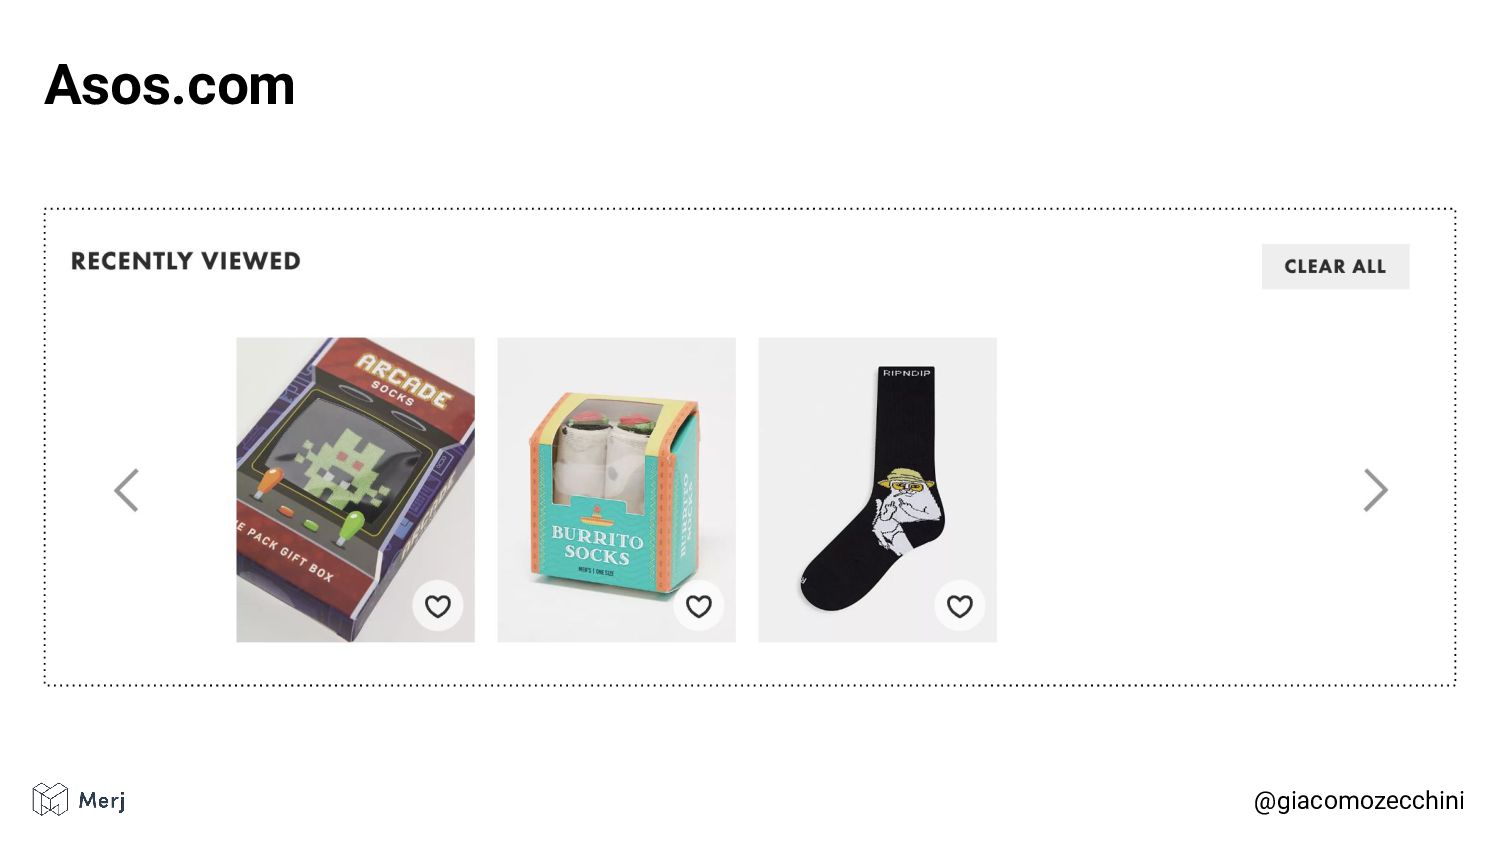
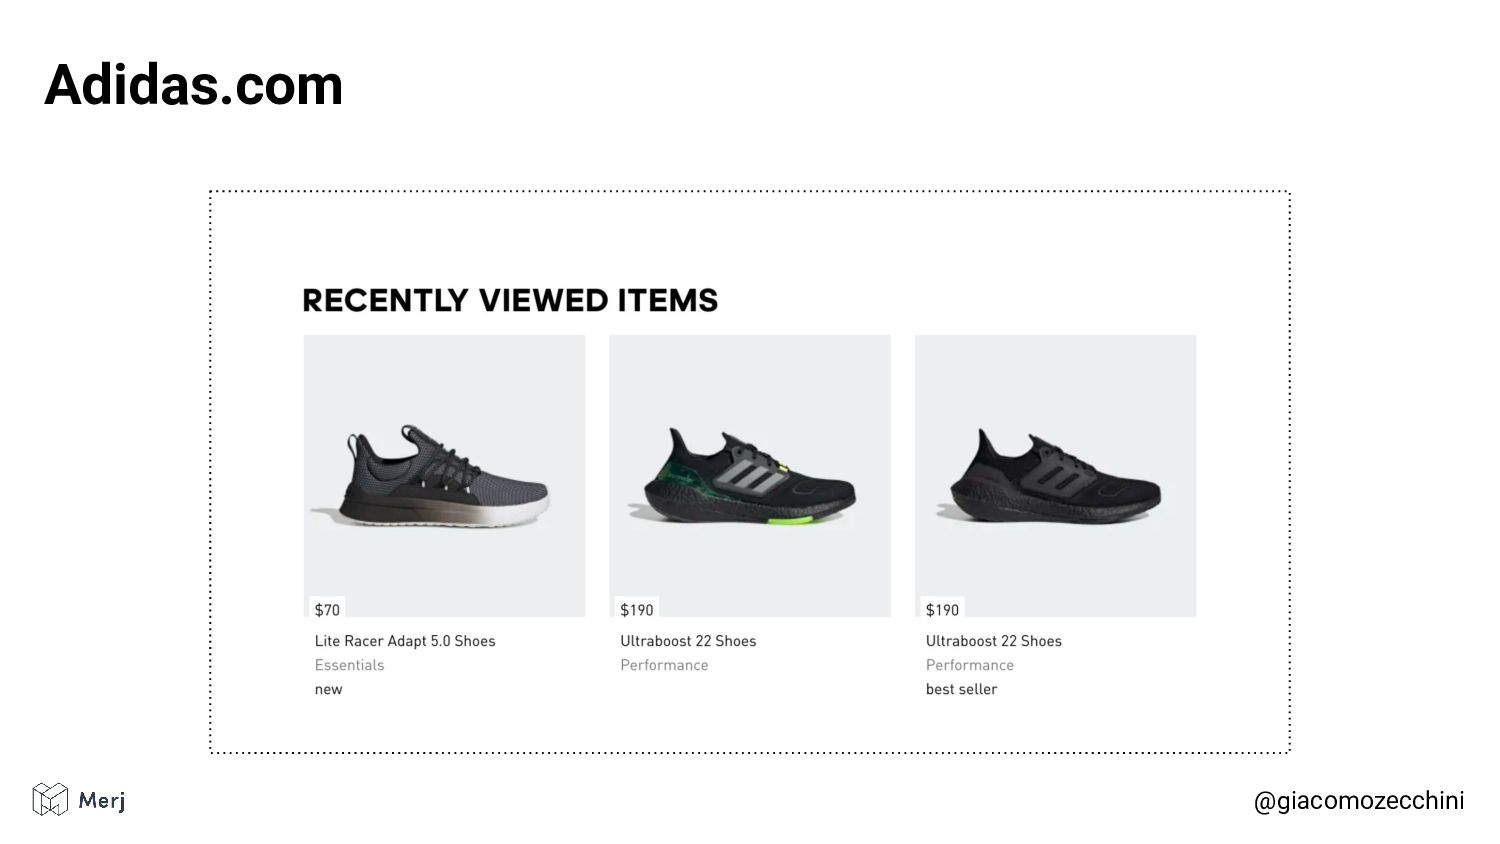
The “Recently view products” feature A practical examples are the
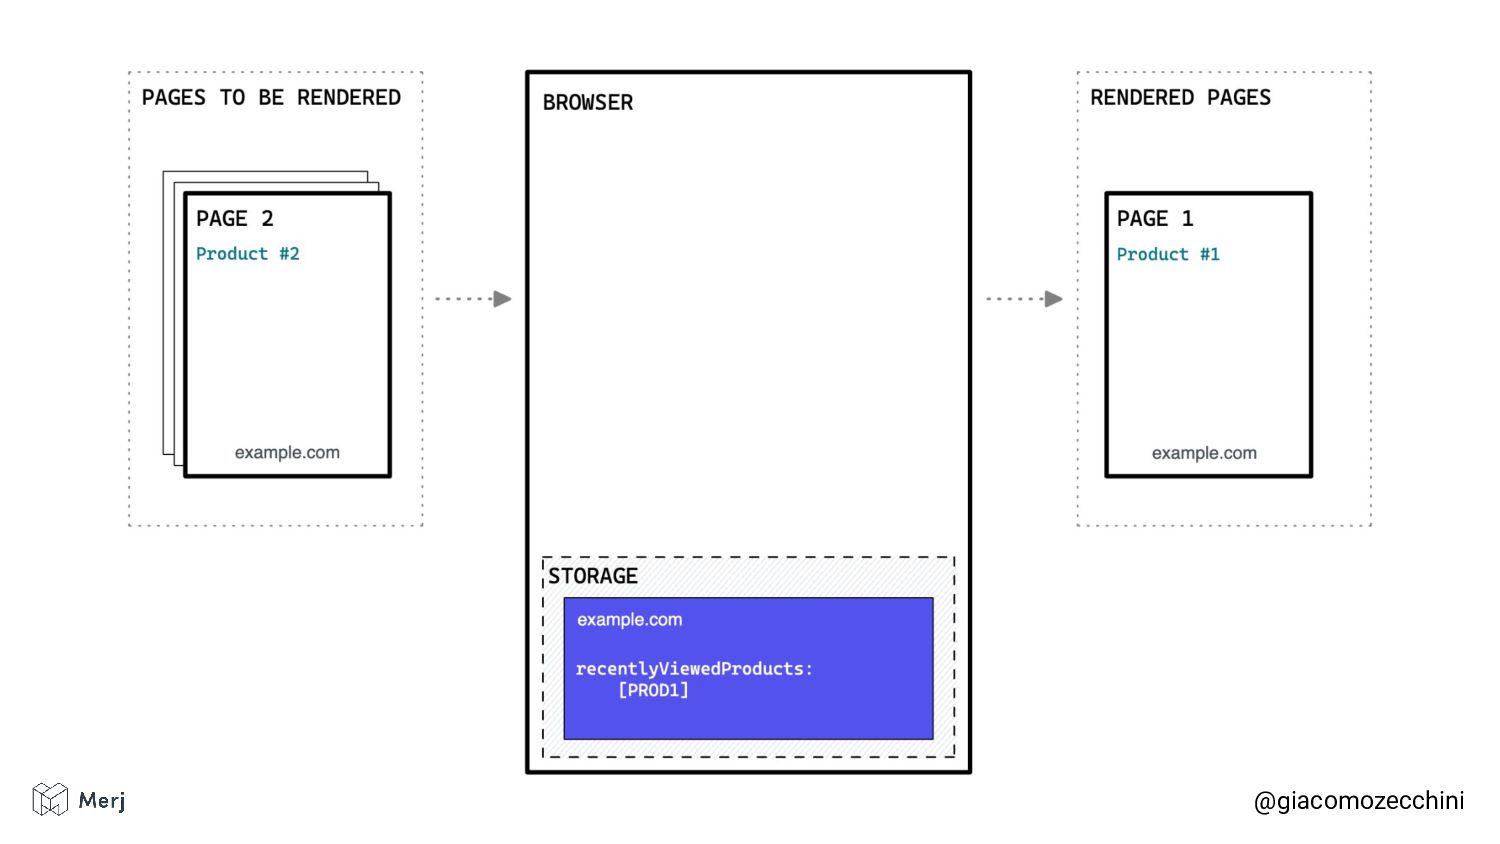
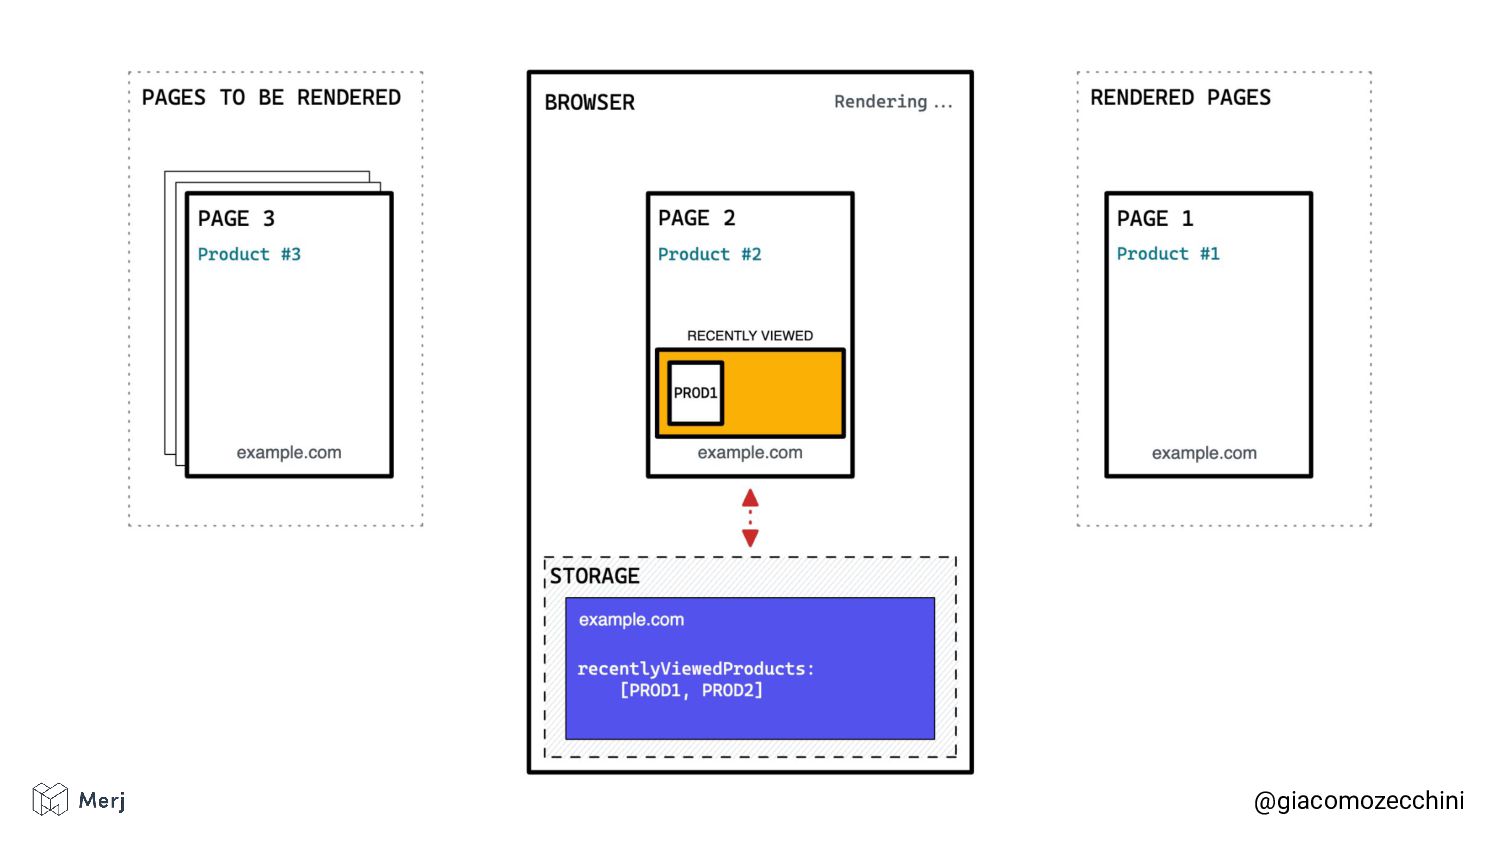
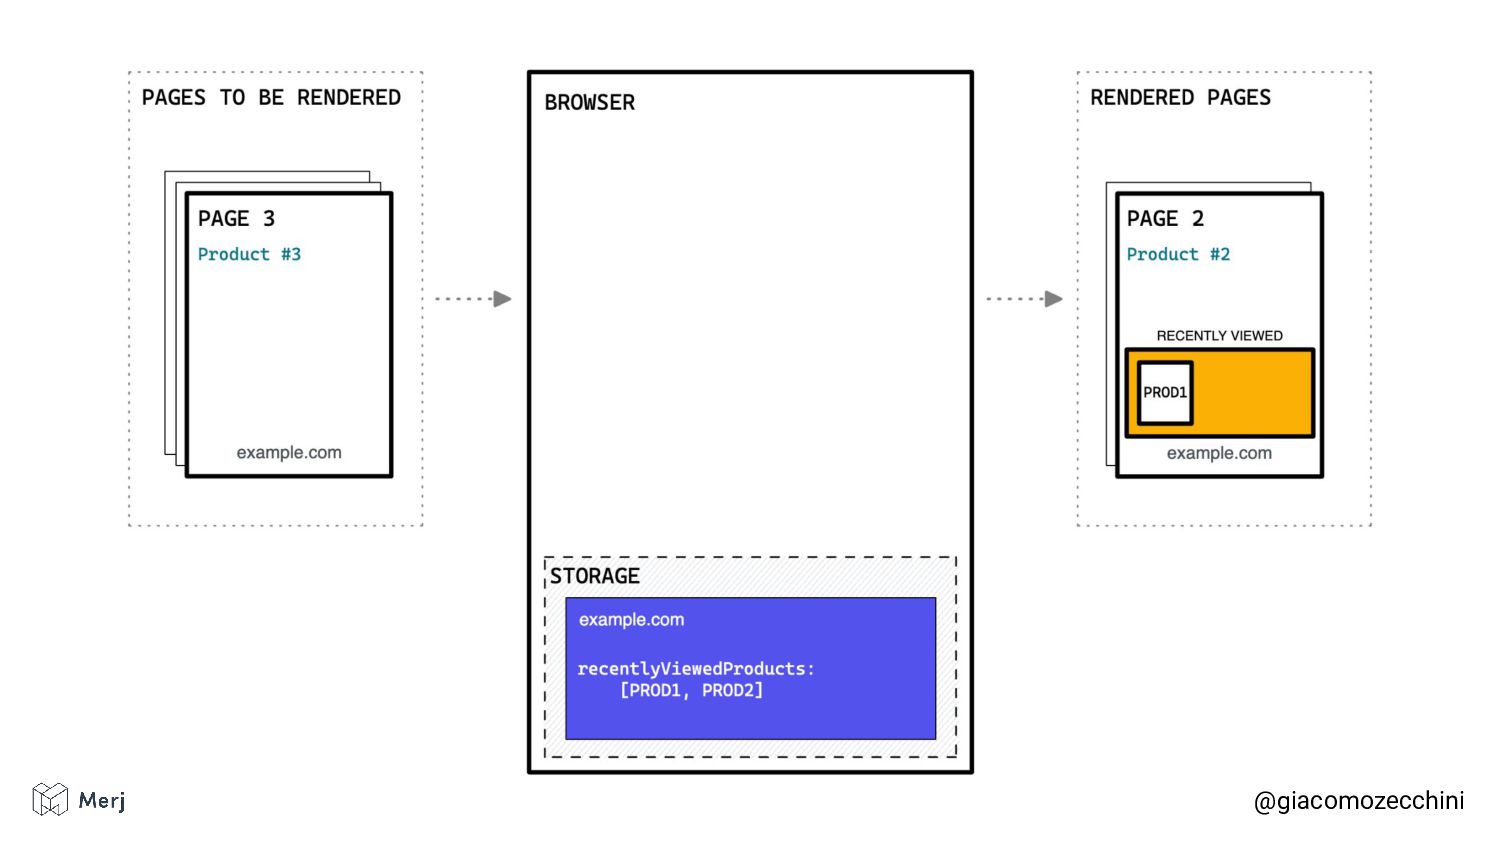
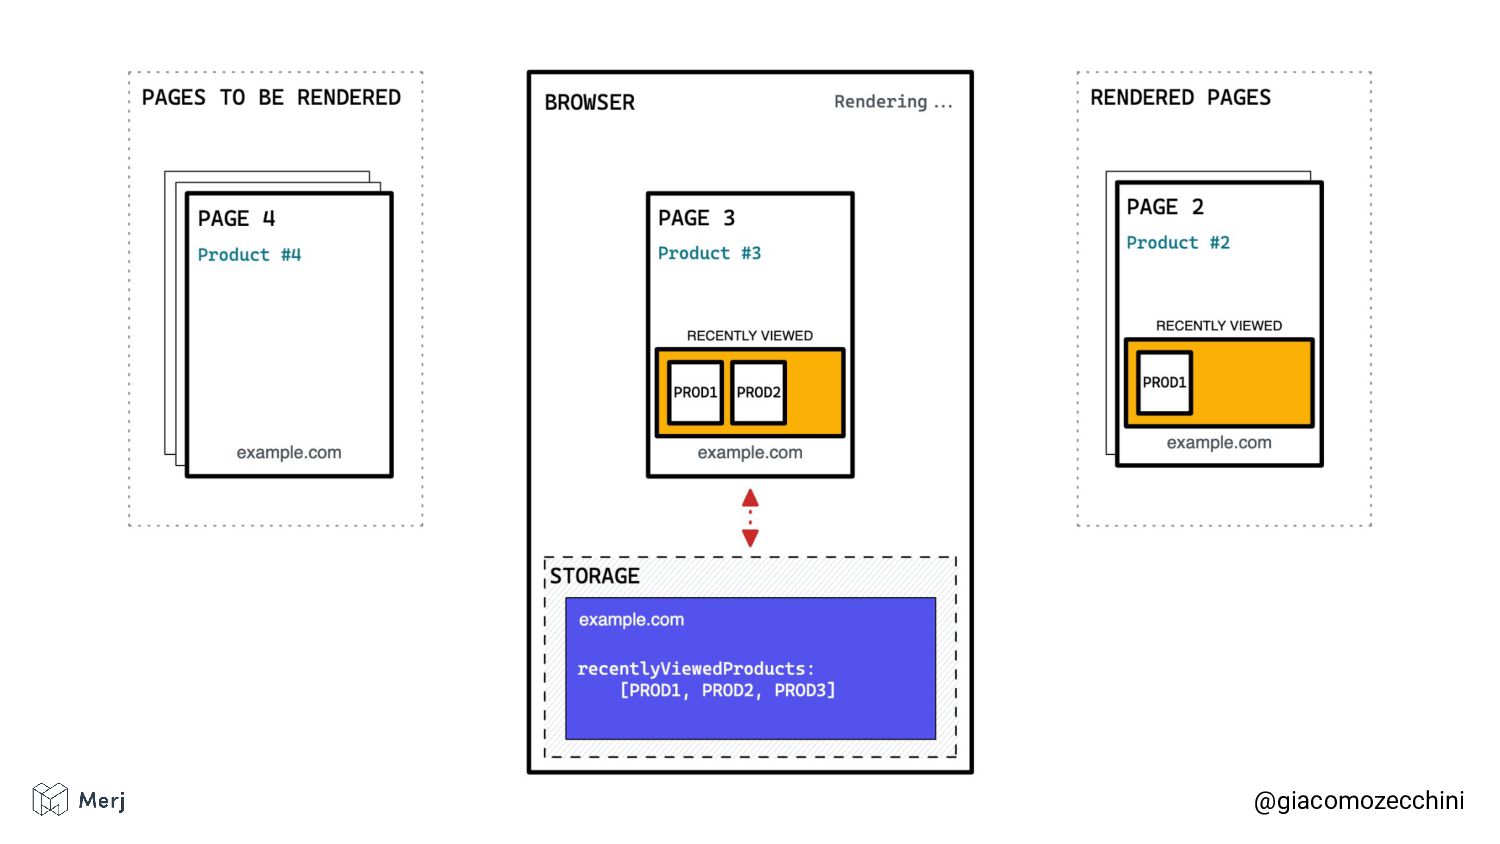
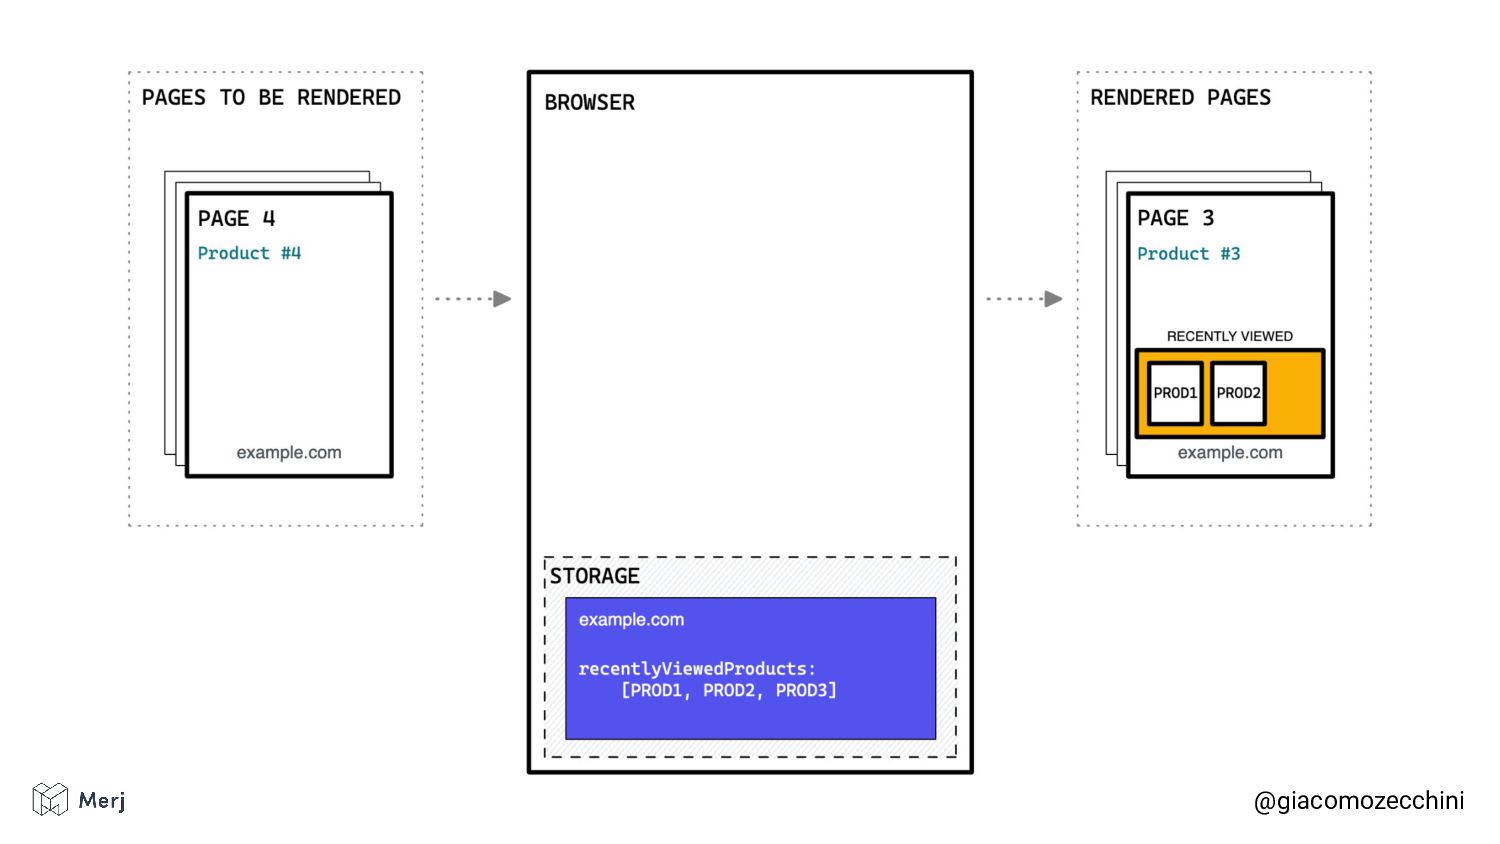
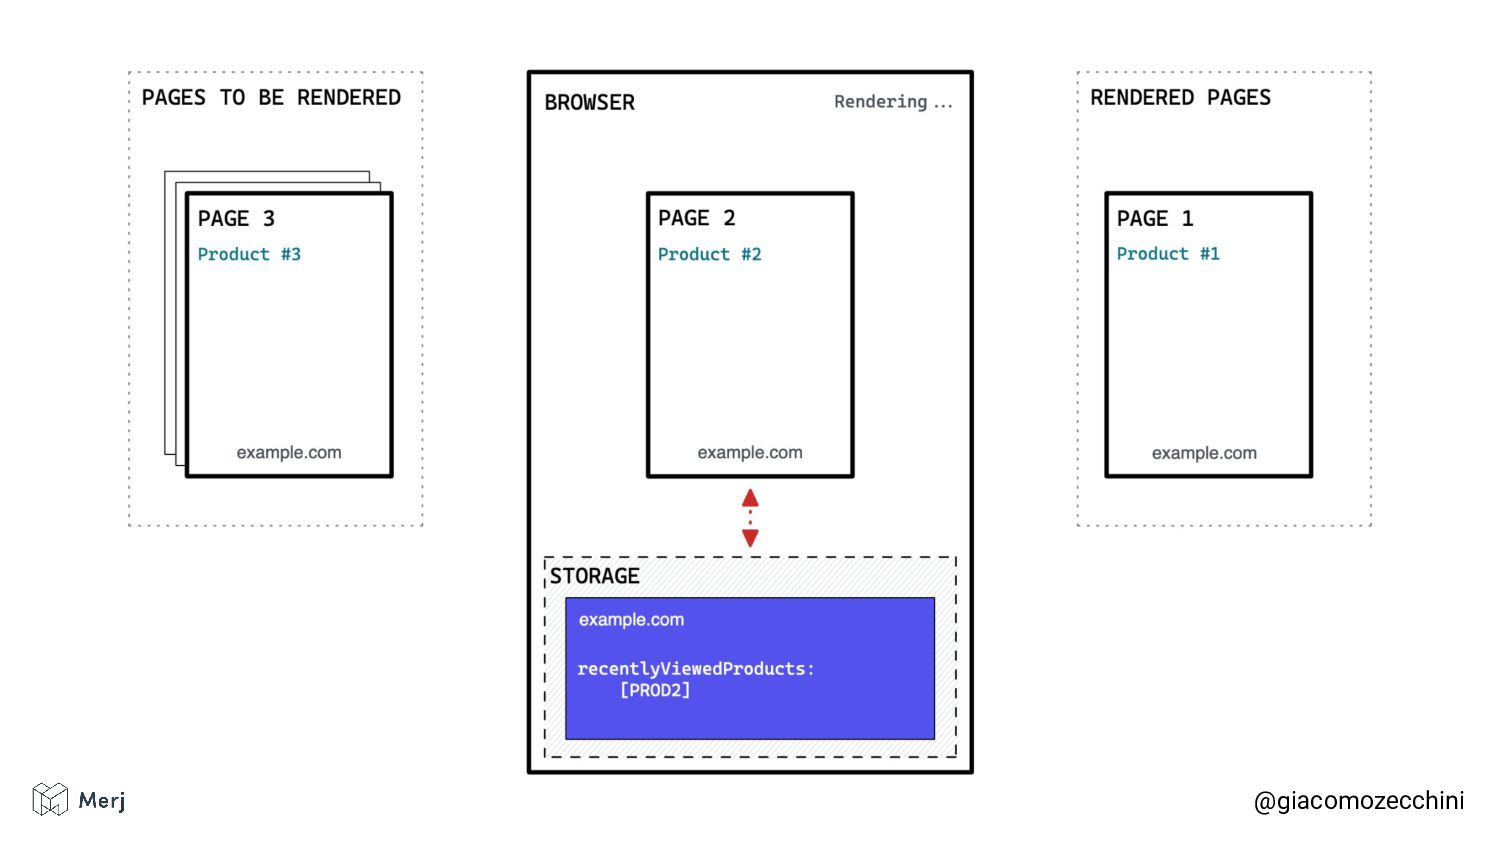
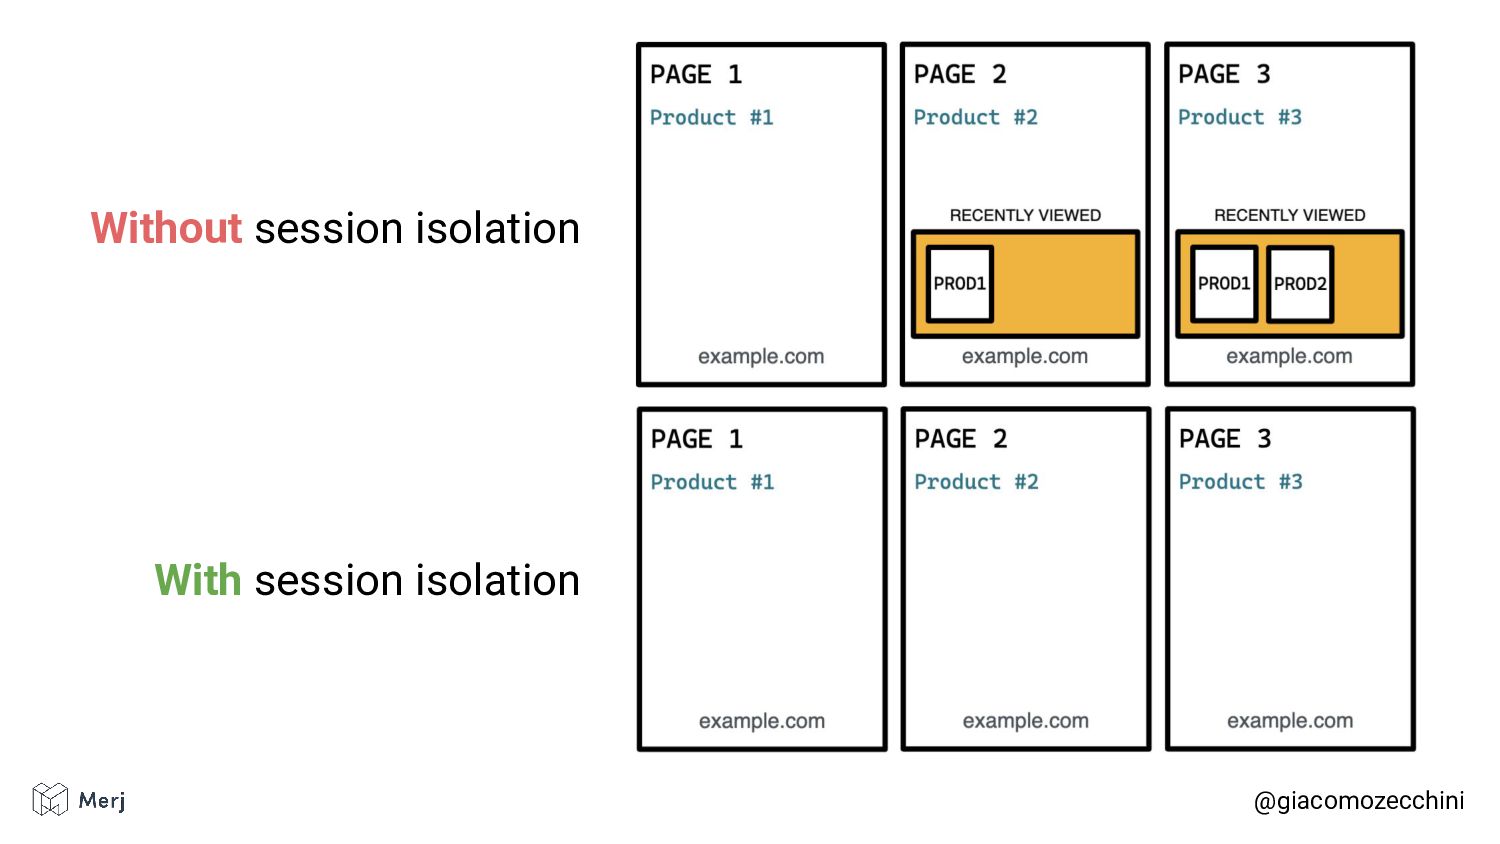
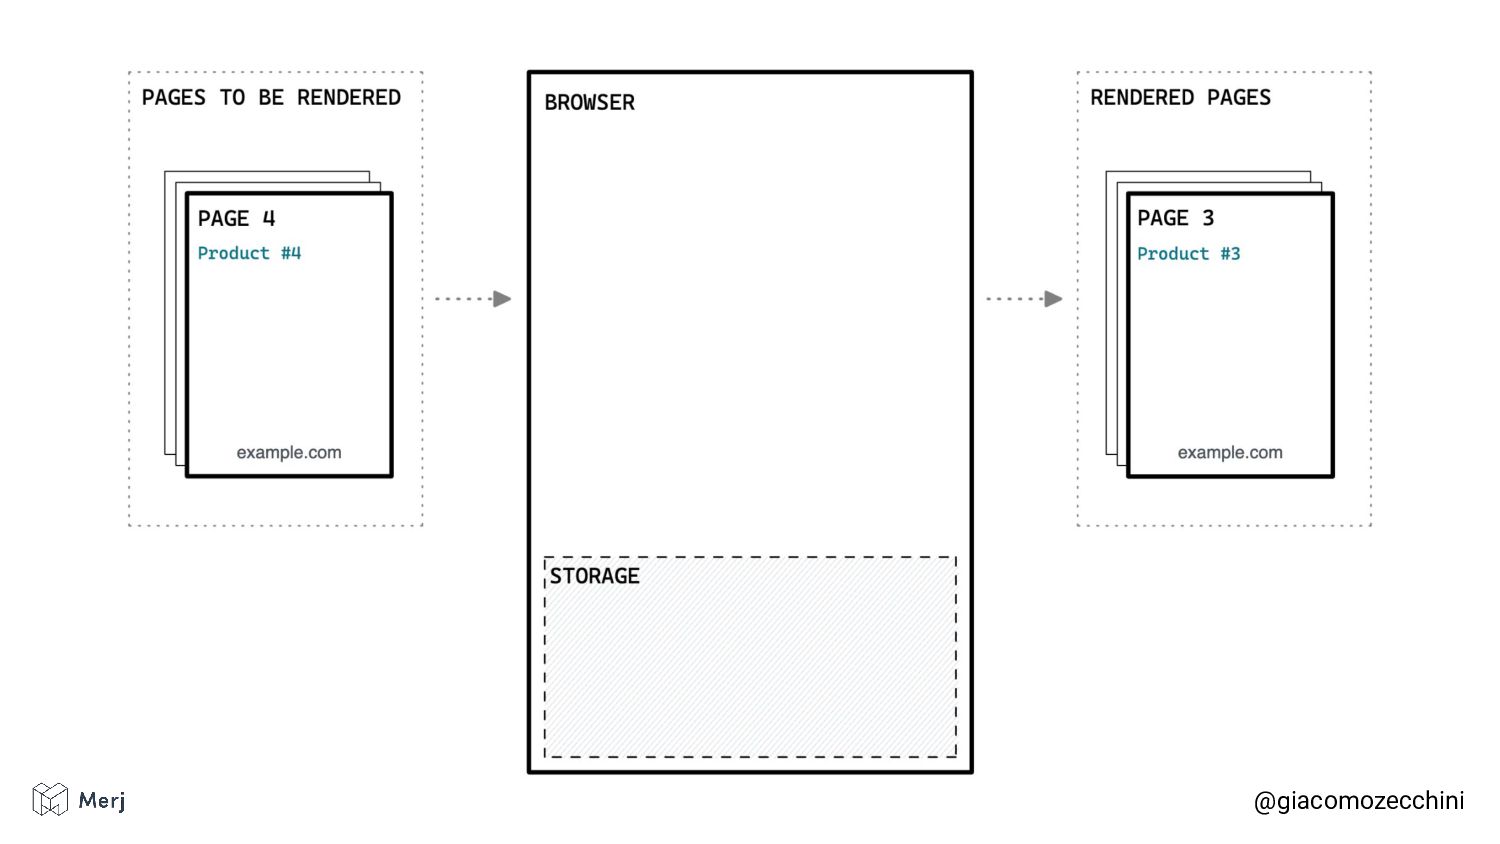
"Recently viewed products" boxes. These boxes show the user's recent browsing history, with links to various products, and can be found on many websites. @giacomozecchini -
Visited pages are saved in memory For all three of
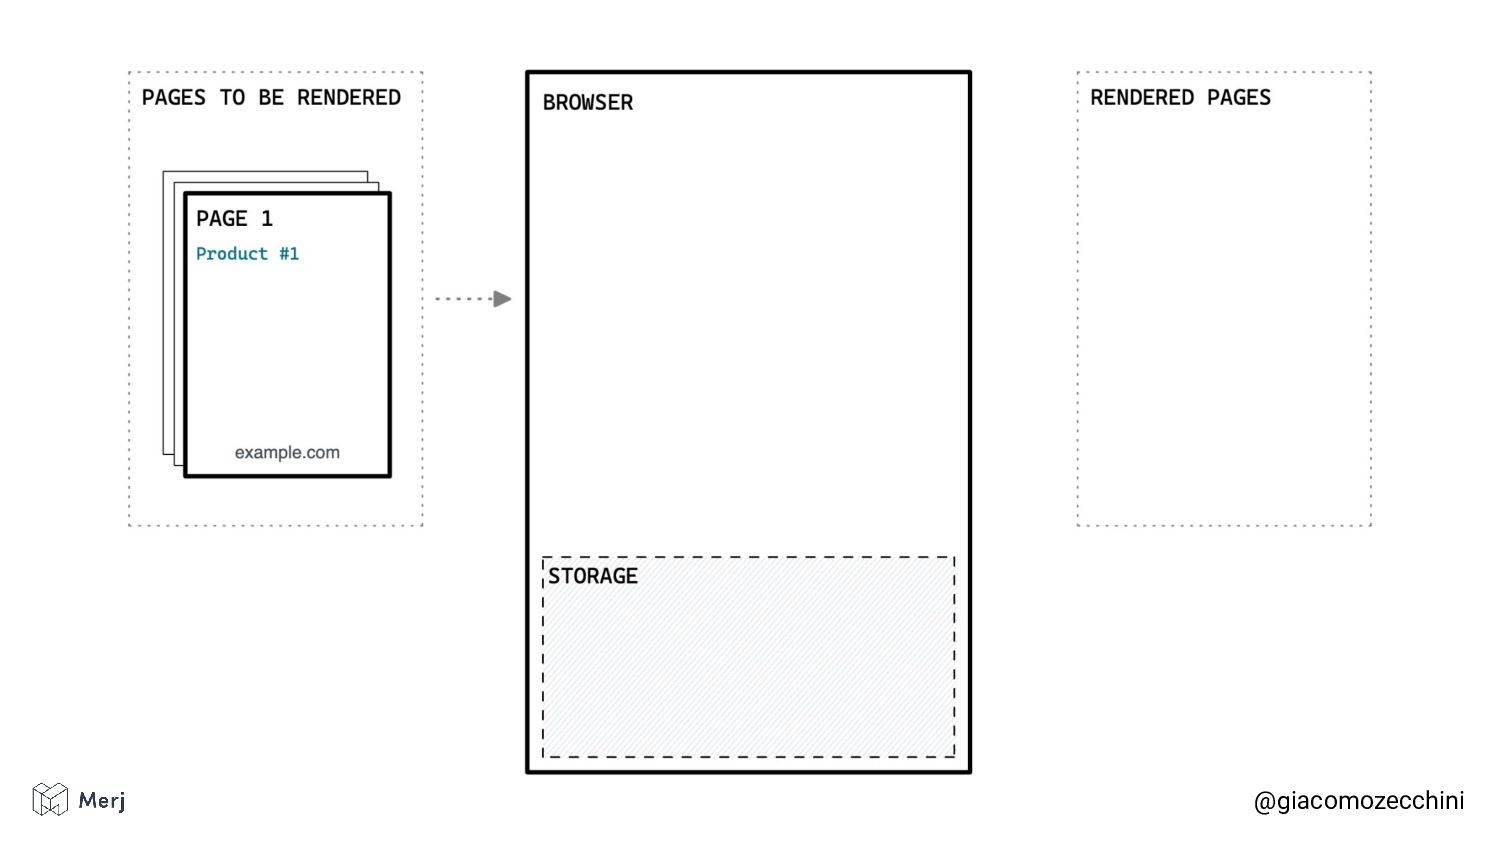
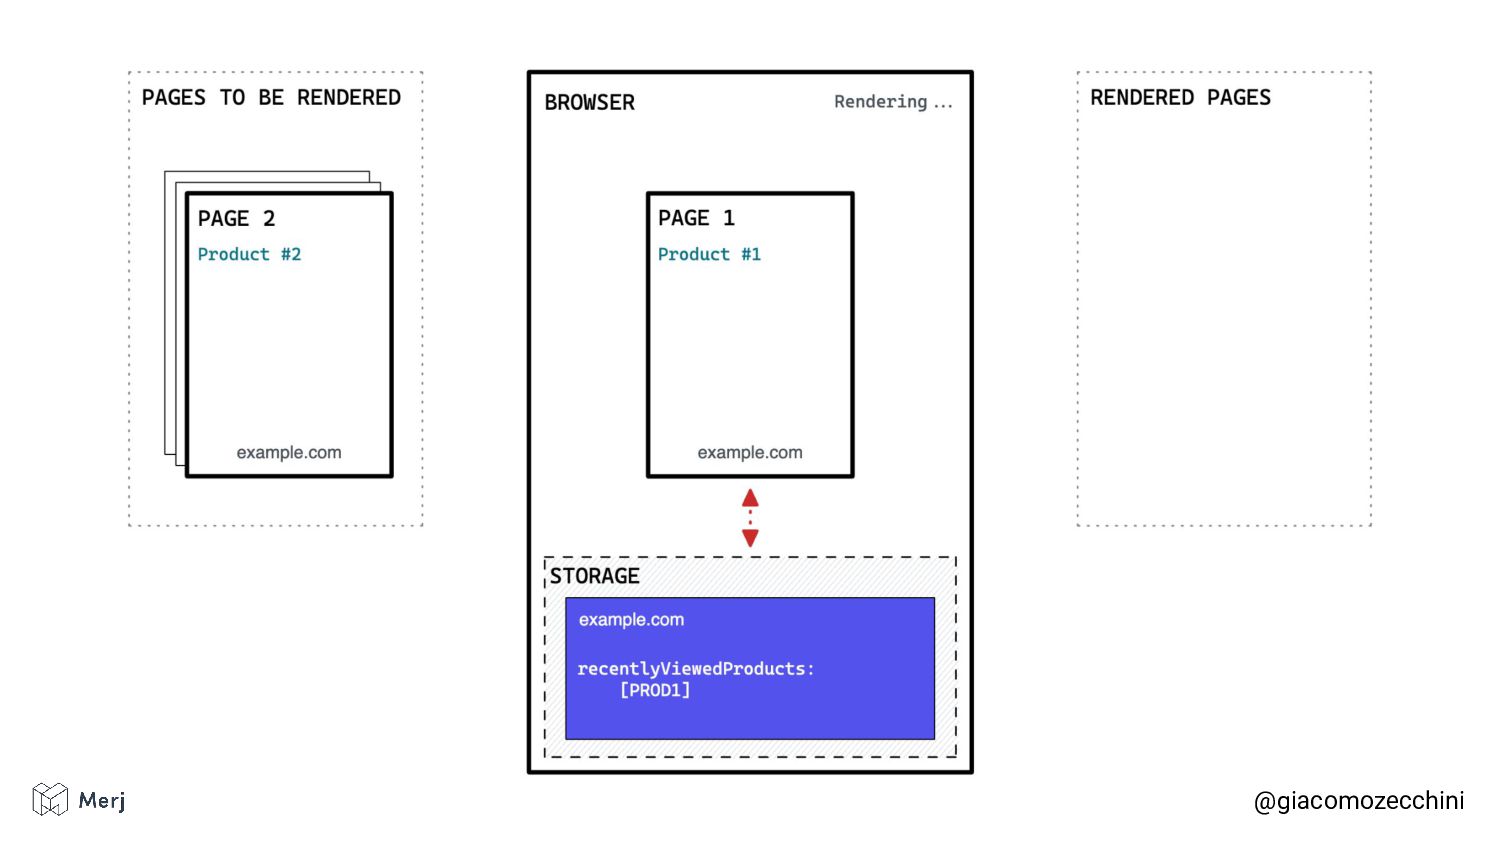
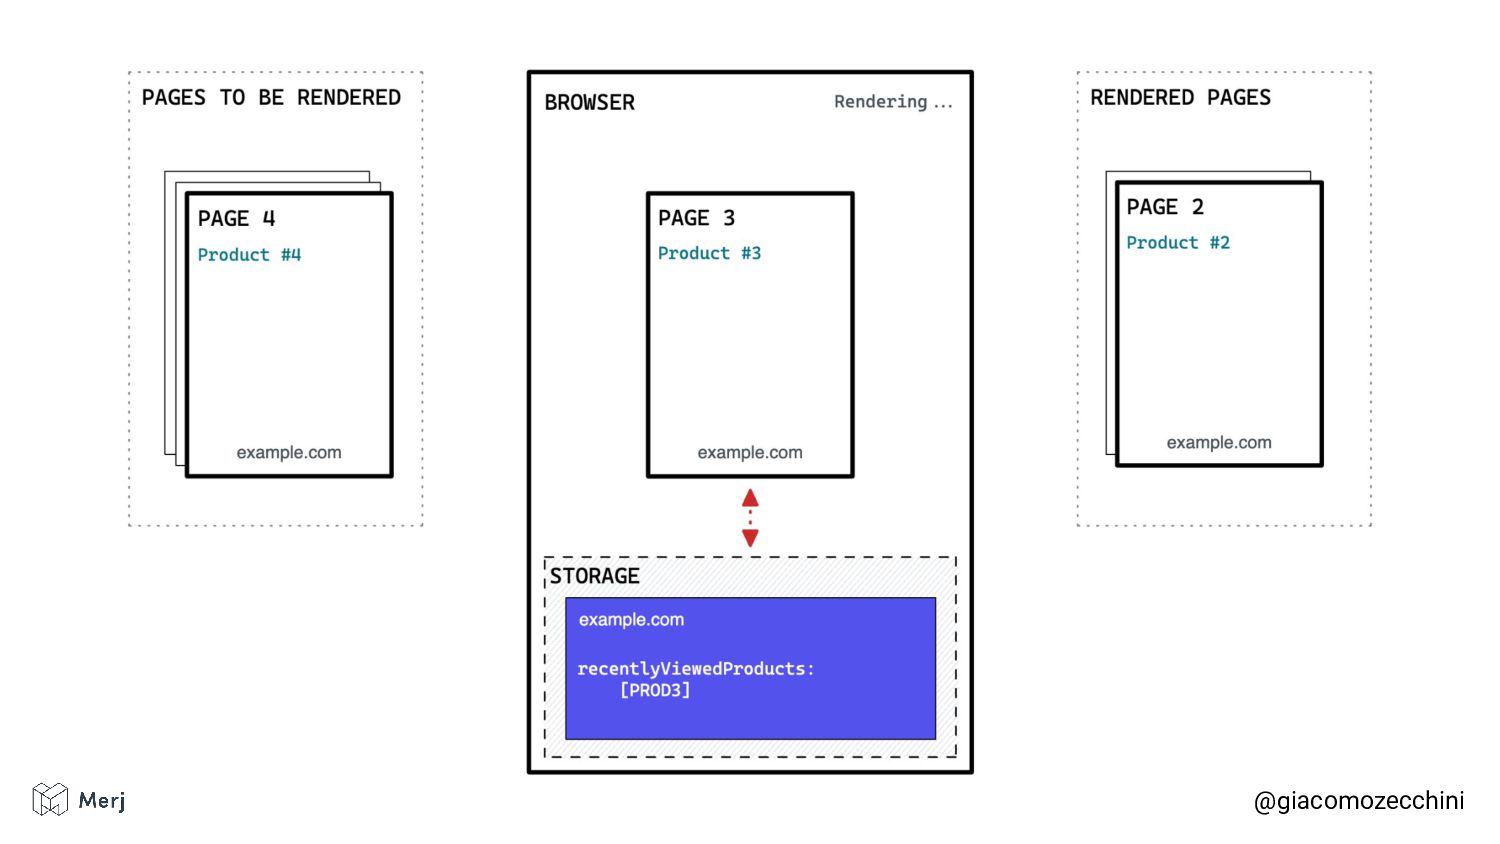
the previous examples, the "Recently viewed products" box is implemented by saving the pages visited by the user in the browser memory. @giacomozecchini -
Saved data may affect rendering For those web crawlers that
render web pages without isolating the rendering sessions, the data saved in the browser's memory may affect the rendering of other web pages of the same website. @giacomozecchini -
Tools with session isolation behave differently The result is different
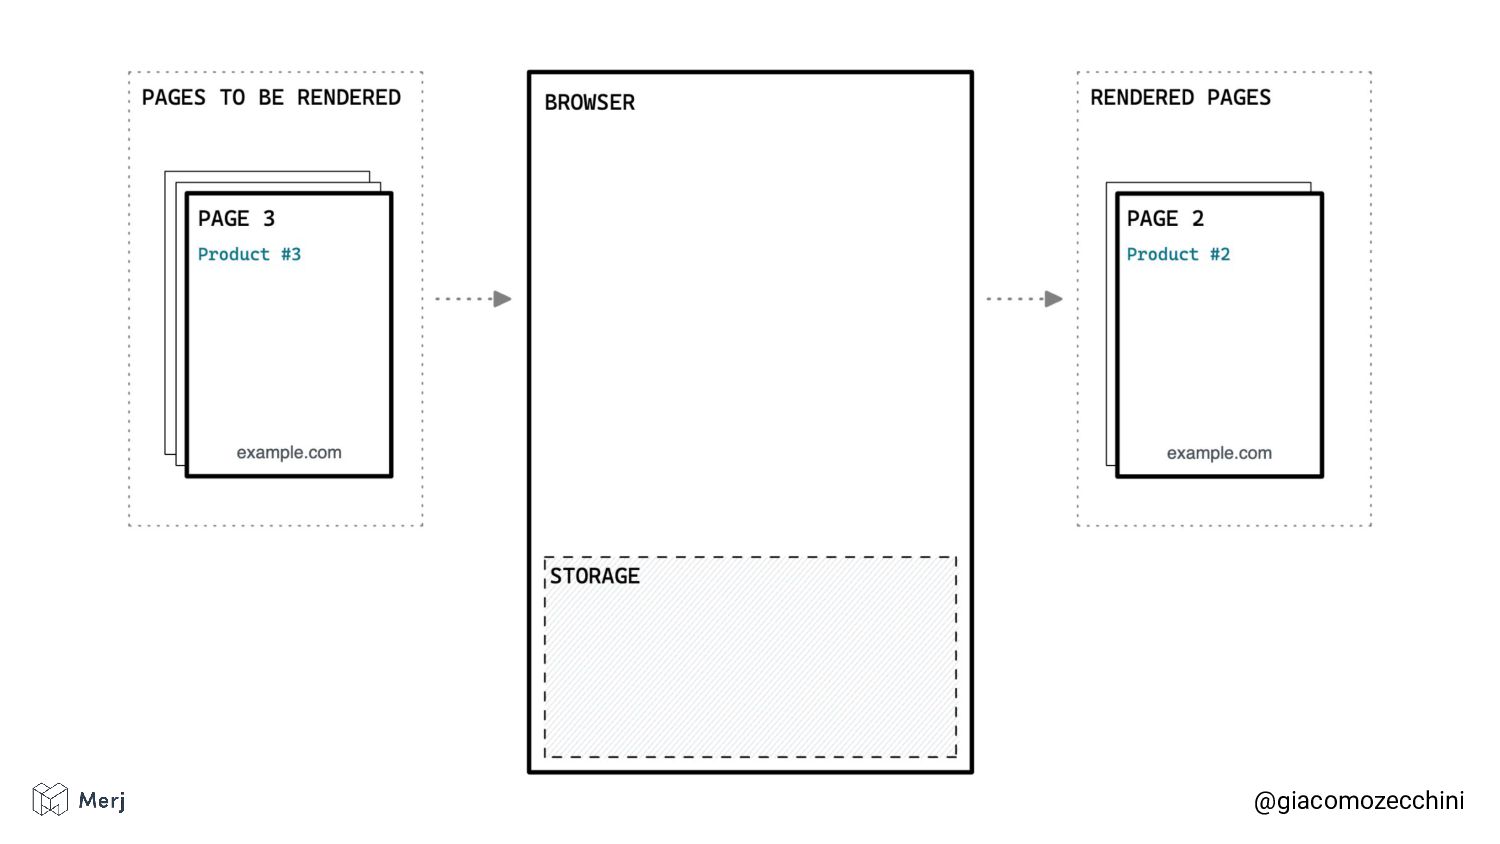
if we look at how Search Engines or Web Crawlers that implement correct session isolation are rendering pages. @giacomozecchini -
Additional content and “ghost links” These different ways of rendering
pages will produce additional content and a considerable percentage of “ghost links”, only visible by web crawlers affected by session isolation issues. @giacomozecchini -
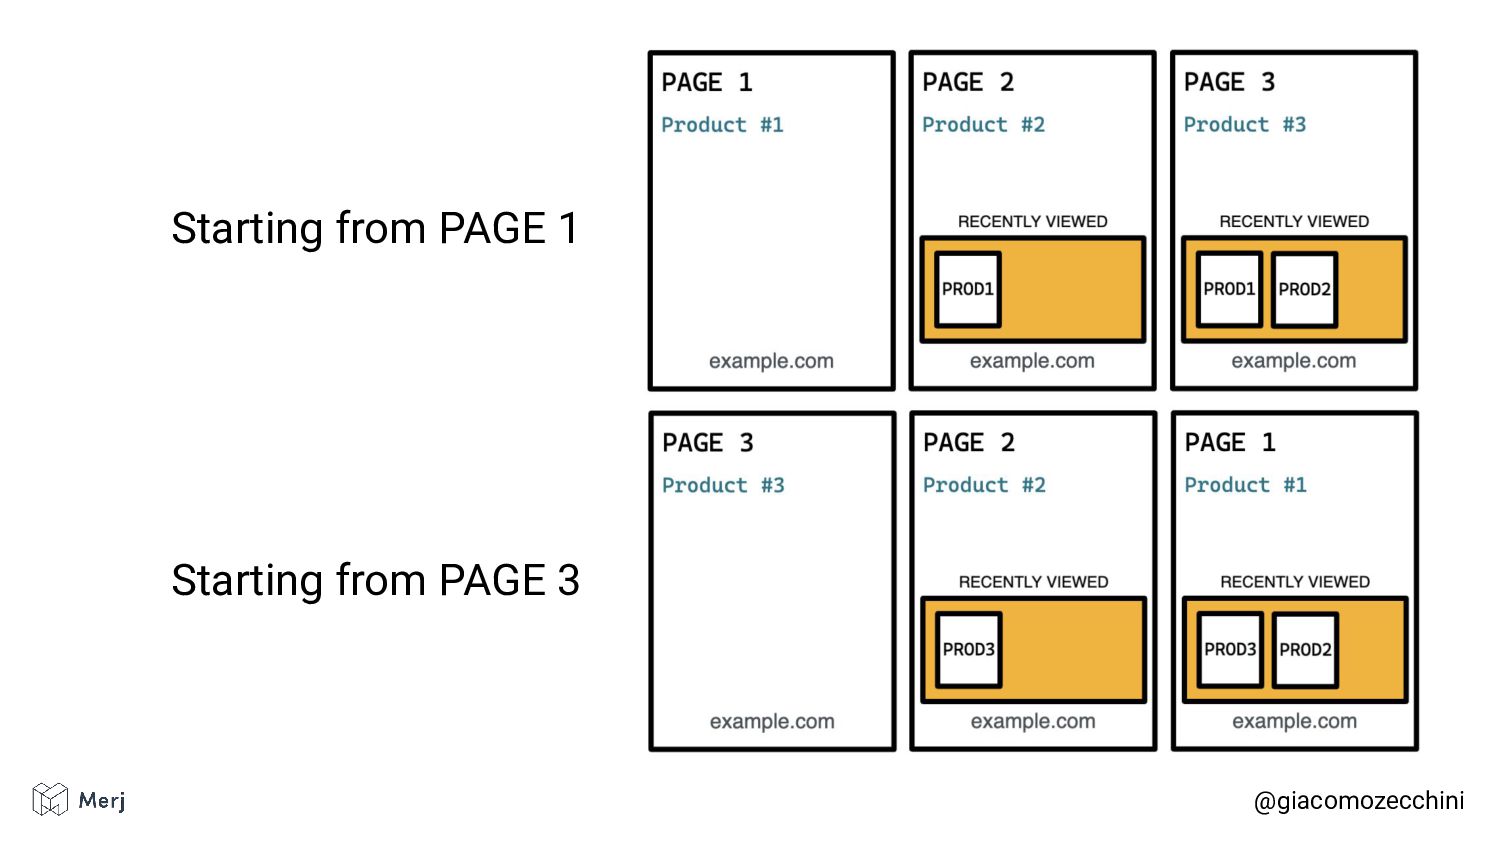
Crawling/rendering order matters Depending on the crawling/rendering order, a web
crawling tool with session isolation issues may create arbitrary HTML content that changes every time. @giacomozecchini -
Three main implications • Lack of data integrity • The
rendered pages are not an accurate representation of what search engines will render and use • Developers may waste time (and money) investigating issues which are not present @giacomozecchini -
Analyses are based on wrong data, for example: • Content
Analysis with additional content • Internal linking analysis with X% arbitrary links * those additional content and links are not visible to Google & Co Effects on SEOs’ day-to-day @giacomozecchini -
These wrong analyses often translate into: • Waste of time
& money • Wrong choices Effects on SEOs’ day-to-day @giacomozecchini -
Session isolation isn’t limited to web crawlers All systems that
use browser-based functionalities might be affected such as dynamic rendering services, web performance analysis tools, and CI/CD pipeline tests. @giacomozecchini -
If it’s an option, it should be clear There are
some cases where you need to keep data for specific tests, but that option should be really clear and intended, not a side effect of a hidden problem. @giacomozecchini -
Partial or incorrect solutions There are many partial or incorrect
ways of tackling session isolation for web crawling purposes, let’s have a look at some of them. @giacomozecchini -
Partial or incorrect solution #1 Clearing cookies manually after the
rendering of a page. The problem here is that Cookies are not the only Web API that can store data. @giacomozecchini -
Partial or incorrect solution #2 Opening and closing the browser
for each page you want to render, manually deleting the folders where the browser stores data. This option is not efficient at all. @giacomozecchini -
Partial or incorrect solution #3 Using the incognito profile hides
some possible pitfalls as well. Within an incognito profile the rendered pages might share storage and cross-tab communication is possible. This option would solve our problem only if, again, we don’t render pages in parallel and we start/stop the browser for each page. @giacomozecchini -
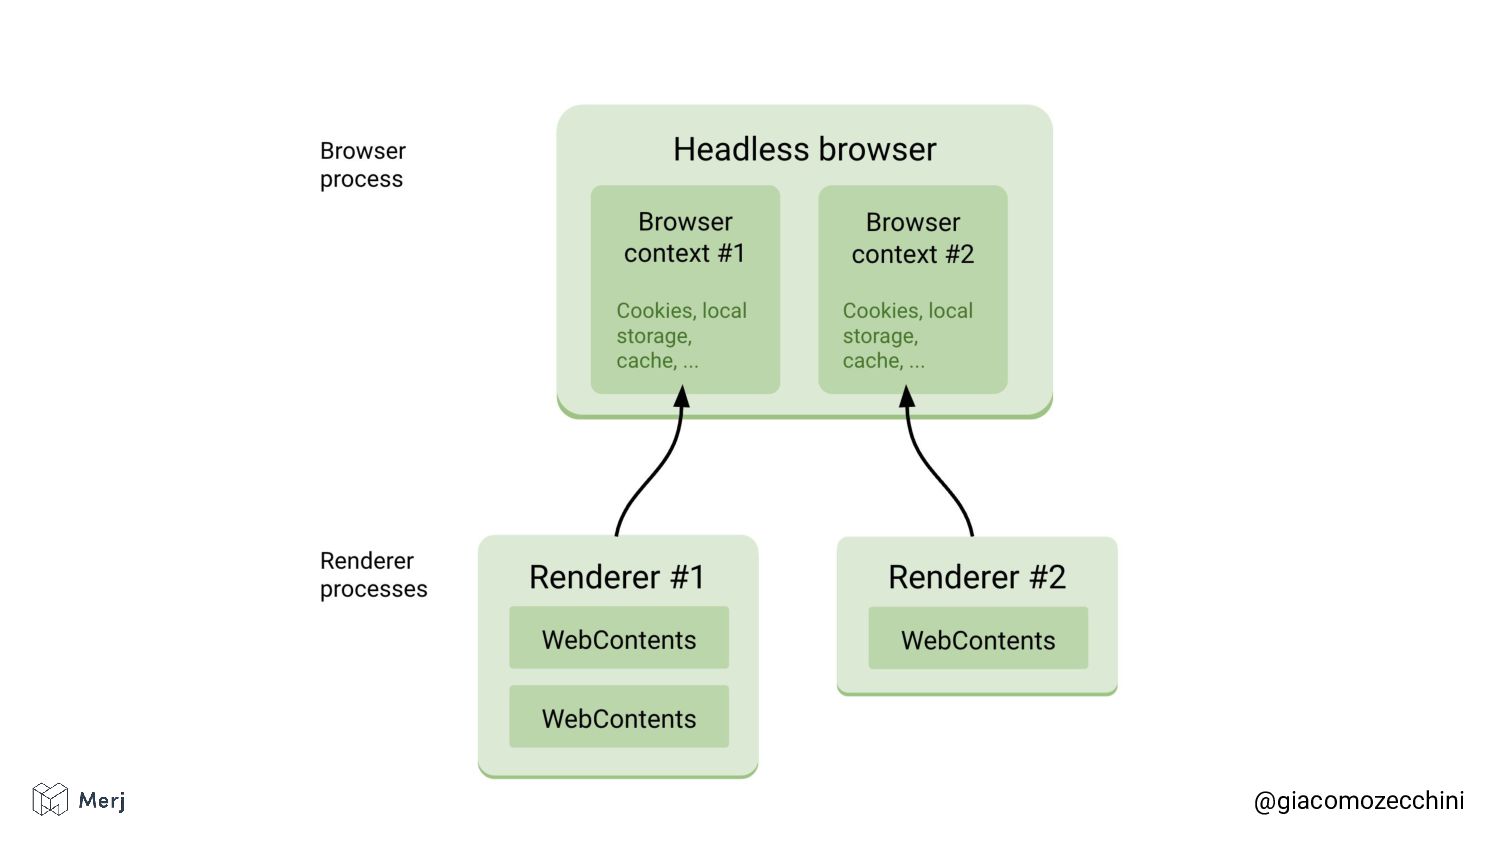
The optimal solution Introduced at BlinkOn 6, Browser Context is
an efficient way to have correct session isolation. Every Browser Context session runs in a separate renderer process, isolating the storage (cookies, cache, local storage, etc.) and preventing cross-tab communication. @giacomozecchini -
How to use Browser Context effectively Rendering a single page
per Browser Context, closing it at the end of the rendering, and then opening a new Browser Context for the next page will guarantee isolated rendering sessions without the need to restart the browser every time. @giacomozecchini -
Data integrity > Performance Using this solution will have a
minimal effect on the web crawlers' performance. In most real-world cases, the majority of web crawling tools users would not compromise data integrity caused by session isolation for an overall performance difference of a few seconds. @giacomozecchini -
Documentation and example Additional documentation and examples on the use
of Browser Context can be found here: • https://chromedevtools.github.io/devtools-protocol/tot/ Target/#method-createBrowserContext • https://pptr.dev/next/api/puppeteer.browser.createinco gnitobrowsercontext • https://playwright.dev/docs/api/class-browsercontext @giacomozecchini -
Methodology We set up a testing environment with 1,000 pages
that try to communicate with each other using the storage and cross-tab communication. @giacomozecchini -
Avoiding false negatives Rendering 1,000 pages will increase the chances
of having two or more pages rendered at the same time in parallel or by the same browser, using fewer pages may cause false negatives if the tested web rendering system uses a high number of machines in parallel. @giacomozecchini -
Storage isolation tests Storage isolation tests are focused on Web
APIs that save or access data from the browser's memory. The goal of each test is to find race conditions in accessing data saved from previous or parallel page renderings. @giacomozecchini -
Test #1 - Cookies Cookies don’t need presentation. The Cookie
interface lets you read and write small pieces of information in the browser storage. Test explanation: When the rendering starts the page creates and saves a Cookie, then reads if there are cookies saved from other pages. Fail criterion: if there are cookies other than the ones created for the rendered page, the test fails. @giacomozecchini -
Test #2 - IndexedDB IndexedDB is a transactional database system
that lets you store and retrieve objects from Browser memory. Test explanation: When the rendering starts the page, it creates or connects to an IndexedDB database. Then, it creates and saves a record in the database to eventually start reading if there are records saved from other pages. Fail criterion: If there are records other than the ones created for the rendered page, the test fails. @giacomozecchini -
Test #3 - LocalStorage LocalStorage is a mechanism that uses
the Web Storage API by which browsers can store key/value pairs. Data persists when the browser is closed and reopened. Test explanation: When the rendering starts, the page creates or saves a data item in the Local Storage, and then it reads if there are data items saved from other pages. Fail criterion: If there are data items other than the ones created for the rendered page, the test fails. @giacomozecchini -
Test #4 - SessionStorage SessionStorage is a mechanism that uses
the Web Storage API by which browsers can store key/value pairs. Data lasts as long as the tab or the browser is open and survives over page reloads and restores. Test explanation: When the rendering service starts the page, creates, or saves a data item in the Session Storage, and then it reads if there are data items saved from other pages. Fail criterion: If there are data items other than the ones created for the rendered page, the test fails. @giacomozecchini -
Cross-tab communication tests Cross-tab communication tests are focused on Web
APIs that send or receive data. The goal of each test is to find if during rendering a page can receive messages from other pages rendered in parallel. @giacomozecchini -
Test #5 - Broadcast Channel The Broadcast Channel API allows
communication between windows, tabs, frames, iframes, and workers of the same origin. Test explanation: When the rendering starts the page connects to the channel and then starts sending its page title as a message to the channel. If there are other pages connected that are sending messages through the channel the page gets and saves them. Fail criterion: If the rendered page gets even a single message from the Broadcast Channel sent by other pages, the test fails. @giacomozecchini -
Test #6 - Shared Worker The Shared Worker is a
Worker that allows communication between windows, tabs, frames, iframes, and workers on the same origin. Test explanation: When the rendering starts the page connects to the Shared Worker, then it starts sending messages to the Worker and eventually starts listening for messages from other pages sent through the worker. Fail criterion: If the rendered page gets even a single message from the Shared Worker sent by other pages, the test fails. @giacomozecchini -
71% of web crawlers failed at least one test @giacomozecchini
Test Results Cookie 29% of web crawlers failed this test IndexedDB 64% of web crawlers failed this test LocalStorage 71% of web crawlers failed this test SessionStorage 21% of web crawlers failed this test Broadcast Channel 14% of web crawlers failed this test Shared Worker 14% of web crawlers failed this test -
Source Code on GitHub Replicate the testing environment using the
following code. https://github.com/merj/test- crawl-session-isolation @giacomozecchini -
Cause of storage isolation problems It’s complex to predict what’s
causing the storage isolation issue. The implementation may drastically vary and we can only speculating on the cause. @giacomozecchini -
Cause of cross-tab communication problems A possible cause for failing
the cross-tab communication tests (Broadcast Channel and Shared Worker) is having the same browser used to render pages in parallel using multiple windows and/or tabs. @giacomozecchini -
Don’t clean it manually! Web crawlers might pass all tests
included in this research by manually cleaning every single storage at the end of every page rendering session, but this approach is not a secure and viable solution to guarantee data integrity. @giacomozecchini -
Workarounds are not future proof solutions Web APIs and browser
interfaces included in the research aren't the only ones that might have access to browser memory/cache and trying to keep up with the development of all new standards and web features is a complex and time-consuming process. @giacomozecchini -
Our goal is to improve web crawling! Not all web
crawlers have been able to fix the session isolation issues yet while they investigate further. The Docker crawling test framework was able to support those who have fixed the session isolation and might be included in their future release checks. Some web crawlers included us through the entire remediation process. @giacomozecchini -
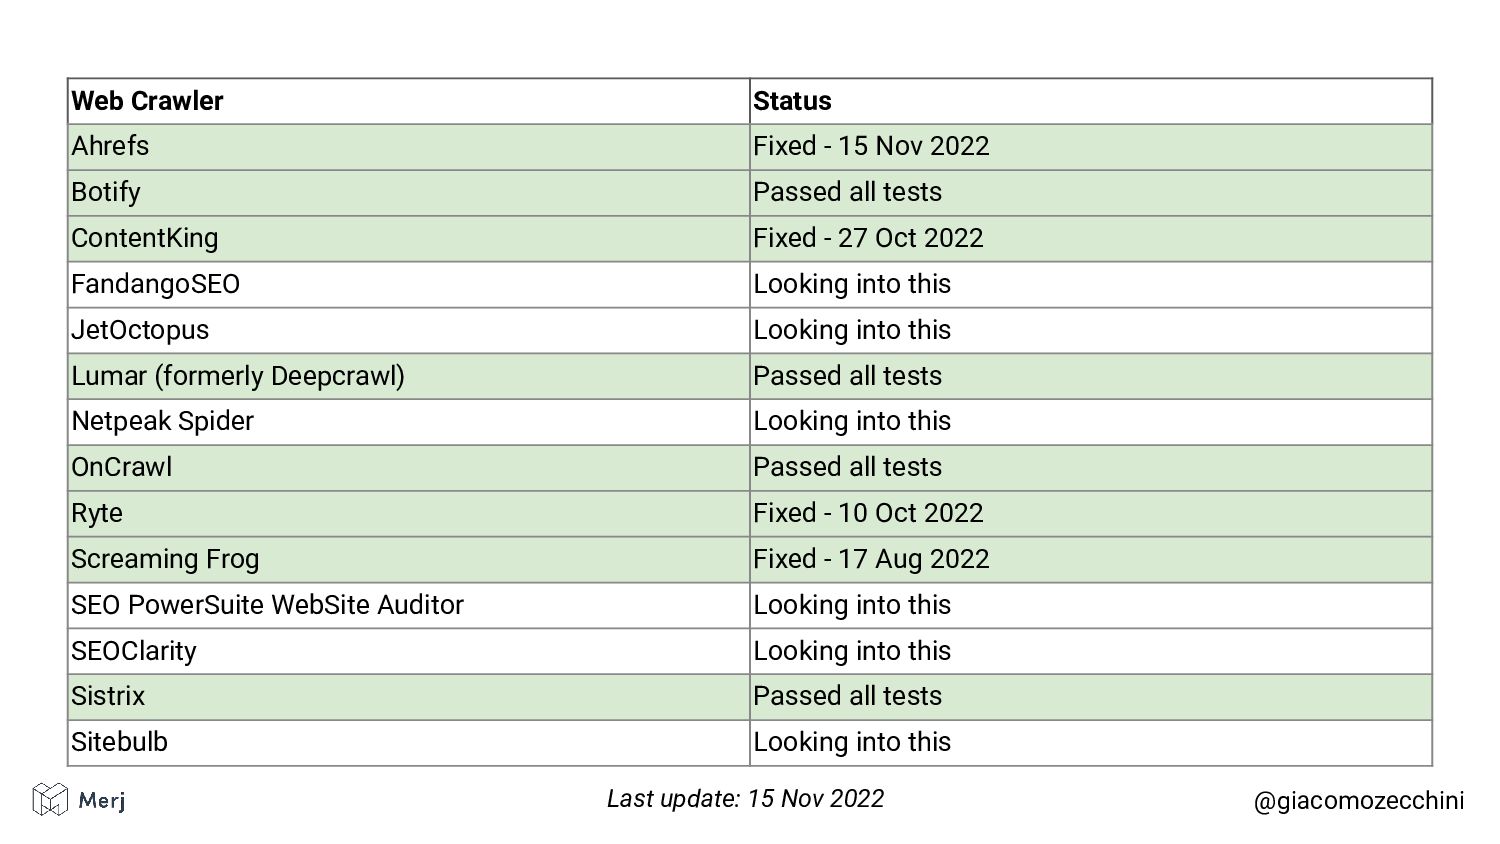
@giacomozecchini Web Crawler Status Ahrefs Fixed - 15 Nov 2022
Botify Passed all tests ContentKing Fixed - 27 Oct 2022 FandangoSEO Looking into this JetOctopus Looking into this Lumar (formerly Deepcrawl) Passed all tests Netpeak Spider Looking into this OnCrawl Passed all tests Ryte Fixed - 10 Oct 2022 Screaming Frog Fixed - 17 Aug 2022 SEO PowerSuite WebSite Auditor Looking into this SEOClarity Looking into this Sistrix Passed all tests Sitebulb Looking into this Last update: 15 Nov 2022 -
Final thoughts • Rendering is hard, we hope that in
the future there will be an industry standard • Make sure you validate your data @giacomozecchini -
Blog We published the research on our blog: https://merj.com/blog/validat ing-session-isolation-for-web-
crawling-to-provide-data-integ rity @giacomozecchini -
Thank you for your time! @GiacomoZecchini on Twitter, Slideshare &
Speakerdeck We work with enterprise clients to support them with SEO Innovation, Research, & Development. Want to work with us? [email protected] +44 (0) 203 322 2660 7 Pancras Square London, N1C 4AG