Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
PostgreSQL+pgvector で LlamaIndex の Property Gr...
Search
hmatsu47
PRO
June 09, 2025
Technology
71
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
PostgreSQL+pgvector で LlamaIndex の Property Graph Index を試す(序章)
俺の勉強会 #2 2025/6/9 LT
(6/20 一部訂正)
hmatsu47
PRO
June 09, 2025
More Decks by hmatsu47
See All by hmatsu47
中小企業に就職して転職せず30年。結果どうなった?
hmatsu47
PRO
0
95
JAWS ミート 2026 の「出し物」のゲームを Kiro と AI-DLC v2 で作った話
hmatsu47
PRO
0
28
ゲームで挑戦!VPC の気持ちになって IPv4/v6 パケットをルーティングしよう!
hmatsu47
PRO
0
32
続・名古屋城とデータセンター
hmatsu47
PRO
0
30
【再演】IPv6 VPC の実装パターンをいくつか
hmatsu47
PRO
0
35
名古屋城とデータセンター
hmatsu47
PRO
0
43
IPv6 に関する話
hmatsu47
PRO
0
33
さいきんの光ファイバーの話
hmatsu47
PRO
0
80
低いほうのレイヤを見てみる話
hmatsu47
PRO
0
38
Other Decks in Technology
See All in Technology
ブラウザとサーバーから考えるAI時代のフロントエンド監視
shogo4131
3
940
AI駆動で「他アプリの音を加工できる」アプリを作った
satomasahiro2005
0
150
AIがコードを書く時代に、エンジニアは何で自分の価値を証明するのか / In an era where AI writes code how do engineers prove their value
carta_engineering
3
1.1k
AI × アーキテクト 第1・2章|生成AIの課題とアーキテクトの素養
daidaidai
0
170
継続的なAIコスト最適化
bgpat
1
340
AI コーディングと人間の認知スループット / CTO Night & Day 2026 Morning Session / AI Coding and Human Cognitive Throughput
prog893
4
1k
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
130
『SAR衛星データ解析入門』の ご紹介とその応用
syuchimu
0
120
Local CI × GitHub Actions
gogutan
2
190
DGX Spark でどこまでハッキングができるのか?
kash1064
3
1.3k
PHPカンファレンス関西の招待状 / Invitation to PHP Conference Kansai
ykanoh
0
110
DevelopersIO 2026 知識の地図を描く ─ オントロジーとは何か?
ishikawa_satoru
1
1.7k
Featured
See All Featured
Lightning Talk: Beautiful Slides for Beginners
inesmontani
PRO
2
730
Kristin Tynski - Automating Marketing Tasks With AI
techseoconnect
PRO
0
550
Navigating the moral maze — ethical principles for Al-driven product design
skipperchong
2
630
Max Prin - Stacking Signals: How International SEO Comes Together (And Falls Apart)
techseoconnect
PRO
0
490
DBのスキルで生き残る技術 - AI時代におけるテーブル設計の勘所
soudai
PRO
68
58k
Building an army of robots
kneath
307
47k
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
990
Principles of Awesome APIs and How to Build Them.
keavy
128
18k
Reality Check: Gamification 10 Years Later
codingconduct
0
2.3k
How to Build an AI Search Optimization Roadmap - Criteria and Steps to Take #SEOIRL
aleyda
1
2.2k
Context Engineering - Making Every Token Count
addyosmani
9
1.2k
Optimising Largest Contentful Paint
csswizardry
37
4k
Transcript
PostgreSQL+pgvector で LlamaIndex の Property Graph Index を試す (序章) 俺の勉強会
#2 2025/6/9 まつひさ(hmatsu47)
自己紹介 松久裕保(@hmatsu47) • https://qiita.com/hmatsu47 • 現在: ◦ 名古屋で Web インフラのお守り係をしています
◦ SRE チームに所属しつつ技術検証の支援をしています ◦ 普段カンファレンス・勉強会では DB の話しかしていません (ほぼ) 2
ところで • 最近の生成 AI 界隈では MCP がブームですが、ちょっと 前までは RAG が流行っていましたね
◦ もう見る影もないですが ◦ とはいえ、実務では RAG で頑張っている勢のほうが多いかも? 3
RAG といえば • RAG(Retrieval Augmented Generation:検索拡張生成) ◦ 生成 AI が学習していない(弱い)知識について普通に質問する
と、生成 AI は正しい答えを返せない ◦ 関連知識を DB などから検索して持ってきてコンテキストとして 生成 AI に与えると、正しい答えを返せる ◦ 関連知識を DB で検索するときの標準的な方法はベクトル検索 4
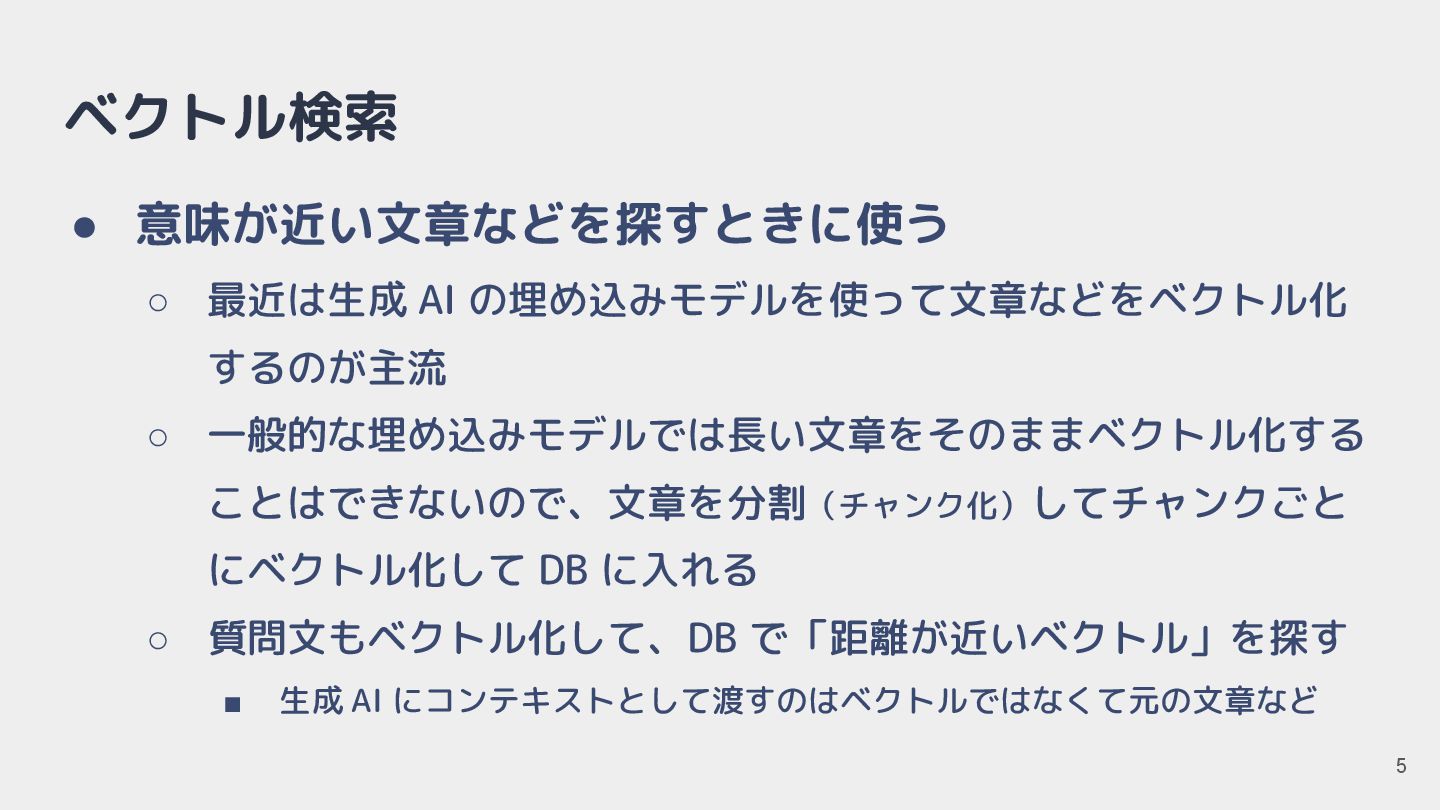
ベクトル検索 • 意味が近い文章などを探すときに使う ◦ 最近は生成 AI の埋め込みモデルを使って文章などをベクトル化 するのが主流 ◦ 一般的な埋め込みモデルでは長い文章をそのままベクトル化する
ことはできないので、文章を分割(チャンク化)してチャンクごと にベクトル化して DB に入れる ◦ 質問文もベクトル化して、DB で「距離が近いベクトル」を探す ▪ 生成 AI にコンテキストとして渡すのはベクトルではなくて元の文章など 5
詳細は • BuriKaigi2025 の発表資料 ◦ https://www.docswell.com/s/hmatsu47/ZP2LY6-2025-01-19-235645 6
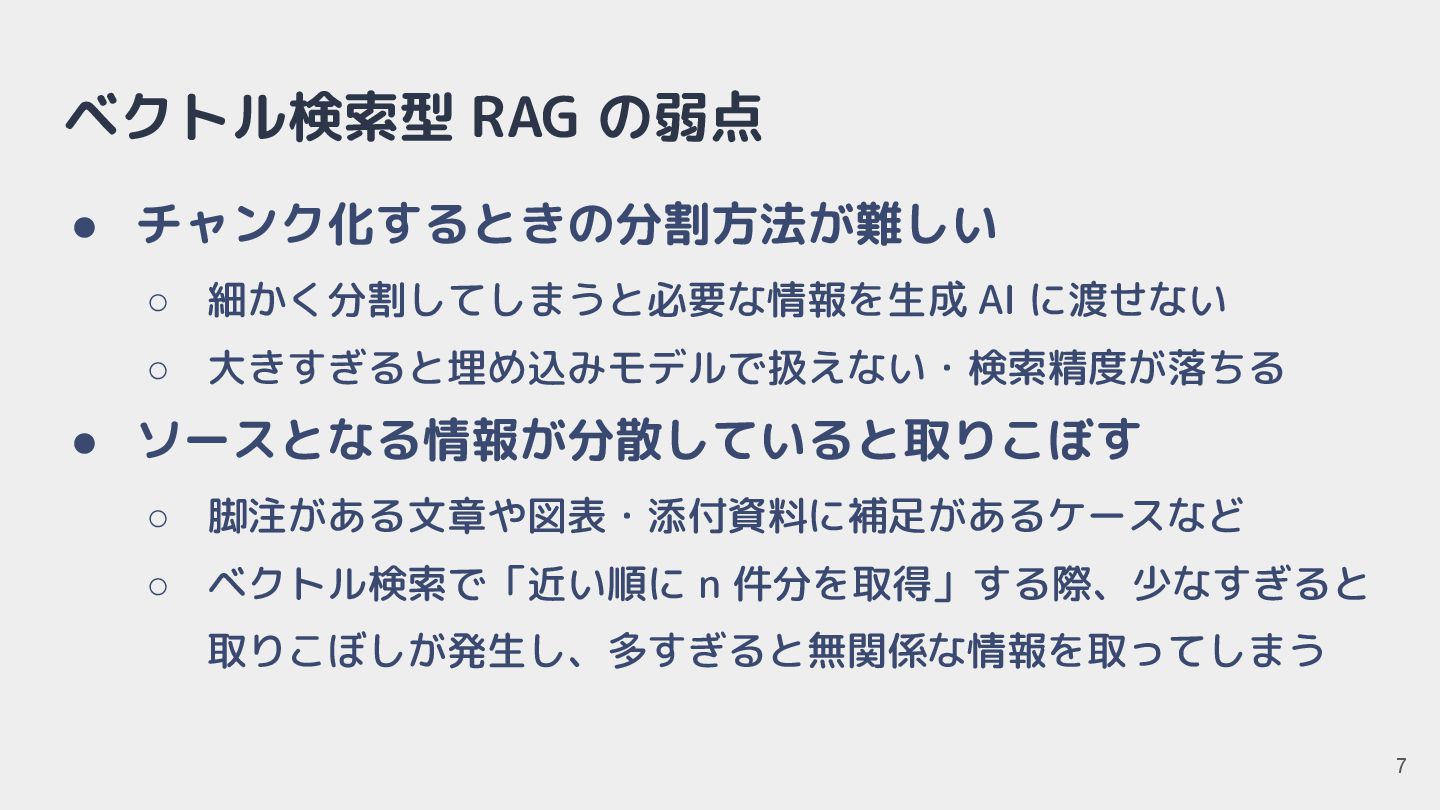
ベクトル検索型 RAG の弱点 • チャンク化するときの分割方法が難しい ◦ 細かく分割してしまうと必要な情報を生成 AI に渡せない ◦
大きすぎると埋め込みモデルで扱えない・検索精度が落ちる • ソースとなる情報が分散していると取りこぼす ◦ 脚注がある文章や図表・添付資料に補足があるケースなど ◦ ベクトル検索で「近い順に n 件分を取得」する際、少なすぎると 取りこぼしが発生し、多すぎると無関係な情報を取ってしまう 7
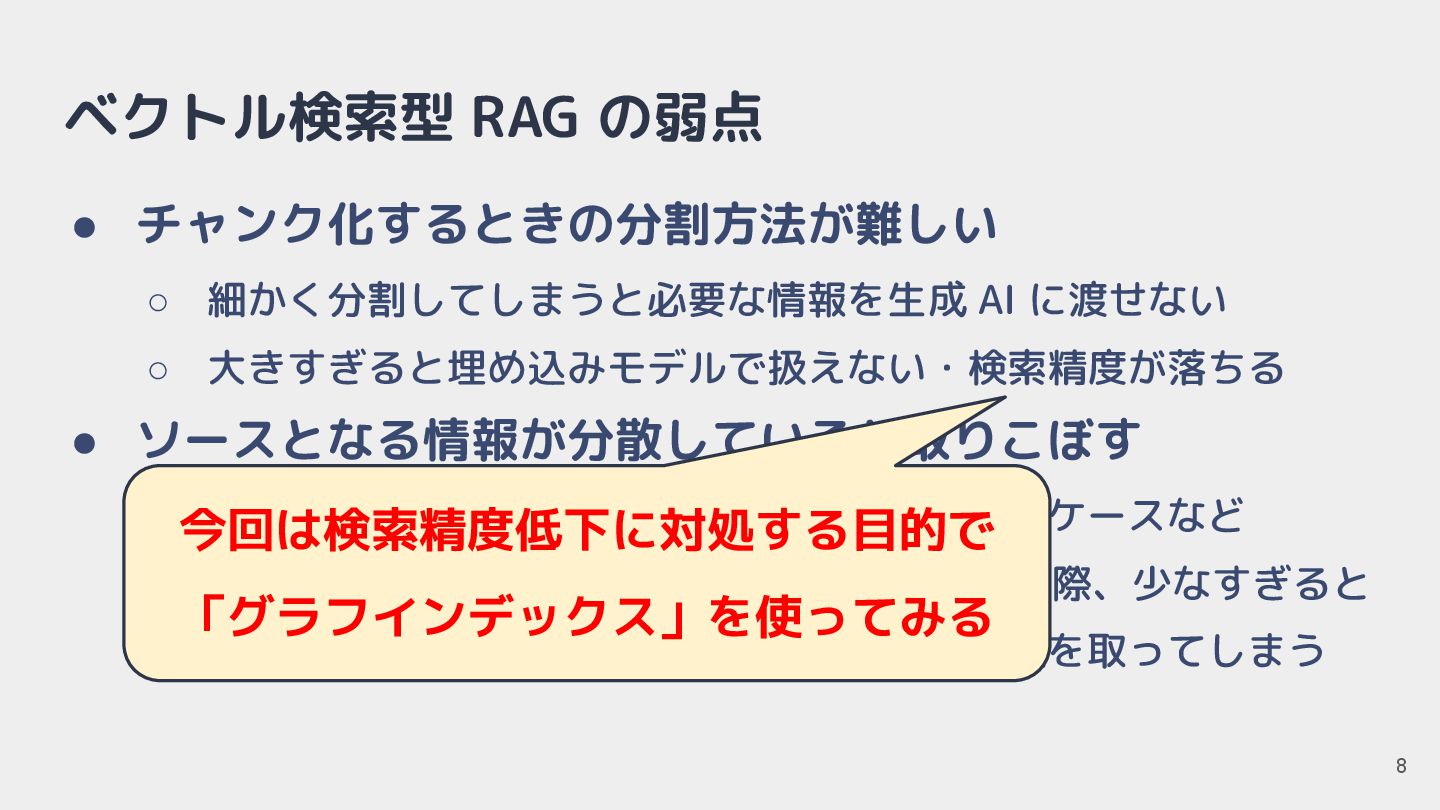
ベクトル検索型 RAG の弱点 • チャンク化するときの分割方法が難しい ◦ 細かく分割してしまうと必要な情報を生成 AI に渡せない ◦
大きすぎると埋め込みモデルで扱えない・検索精度が落ちる • ソースとなる情報が分散していると取りこぼす ◦ 脚注がある文章や図表・添付資料に補足があるケースなど ◦ ベクトル検索で「近い順に n 件分を取得」する際、少なすぎると 取りこぼしが発生し、多すぎると無関係な情報を取ってしまう 8 今回は検索精度低下に対処する目的で 「グラフインデックス」を使ってみる
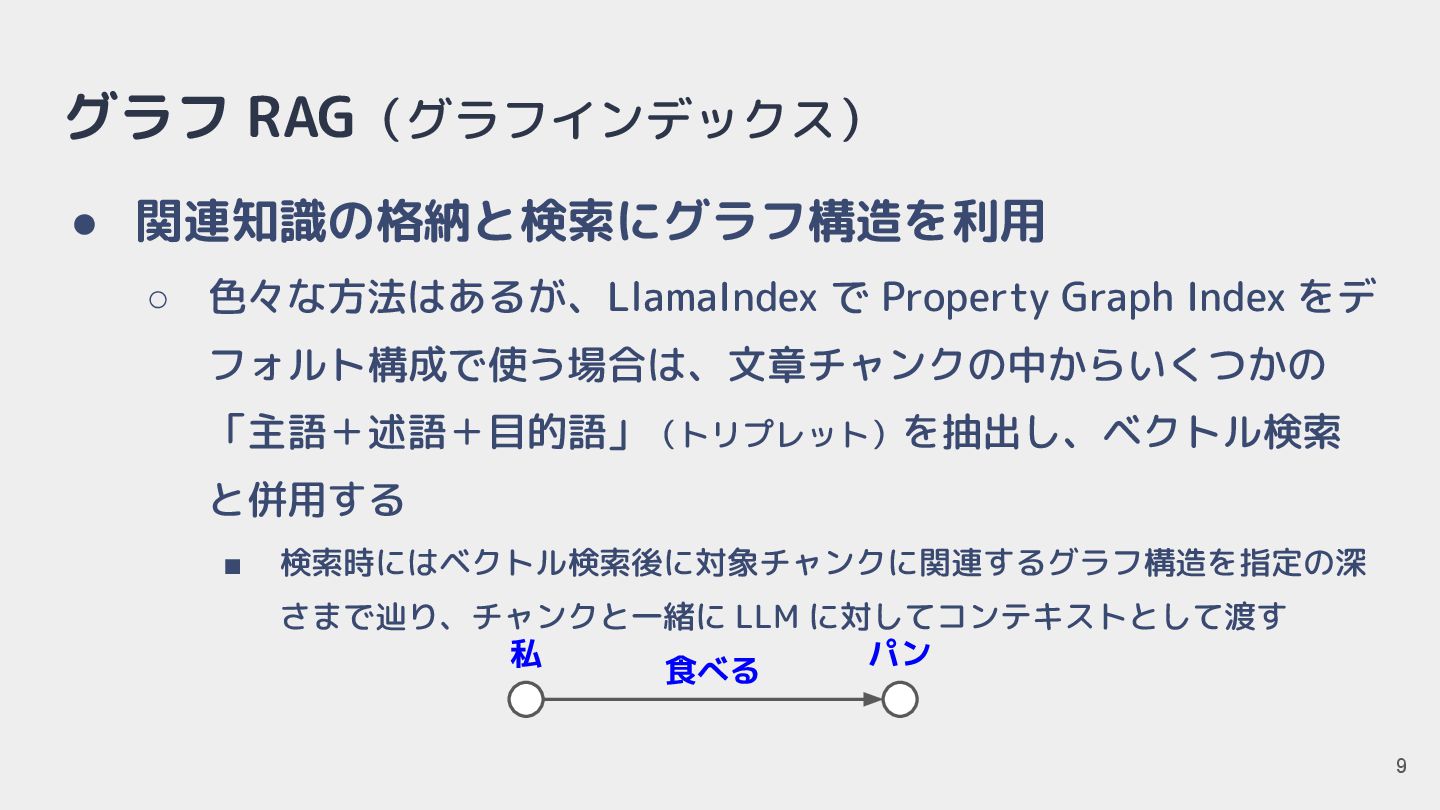
グラフ RAG(グラフインデックス) • 関連知識の格納と検索にグラフ構造を利用 ◦ 色々な方法はあるが、LlamaIndex で Property Graph Index
をデ フォルト構成で使う場合は、文章チャンクの中からいくつかの 「主語+述語+目的語」(トリプレット)を抽出し、ベクトル検索 と併用する ▪ 検索時にはベクトル検索後に対象チャンクに関連するグラフ構造を指定の深 さまで辿り、チャンクと一緒に LLM に対してコンテキストとして渡す 9 私 パン 食べる
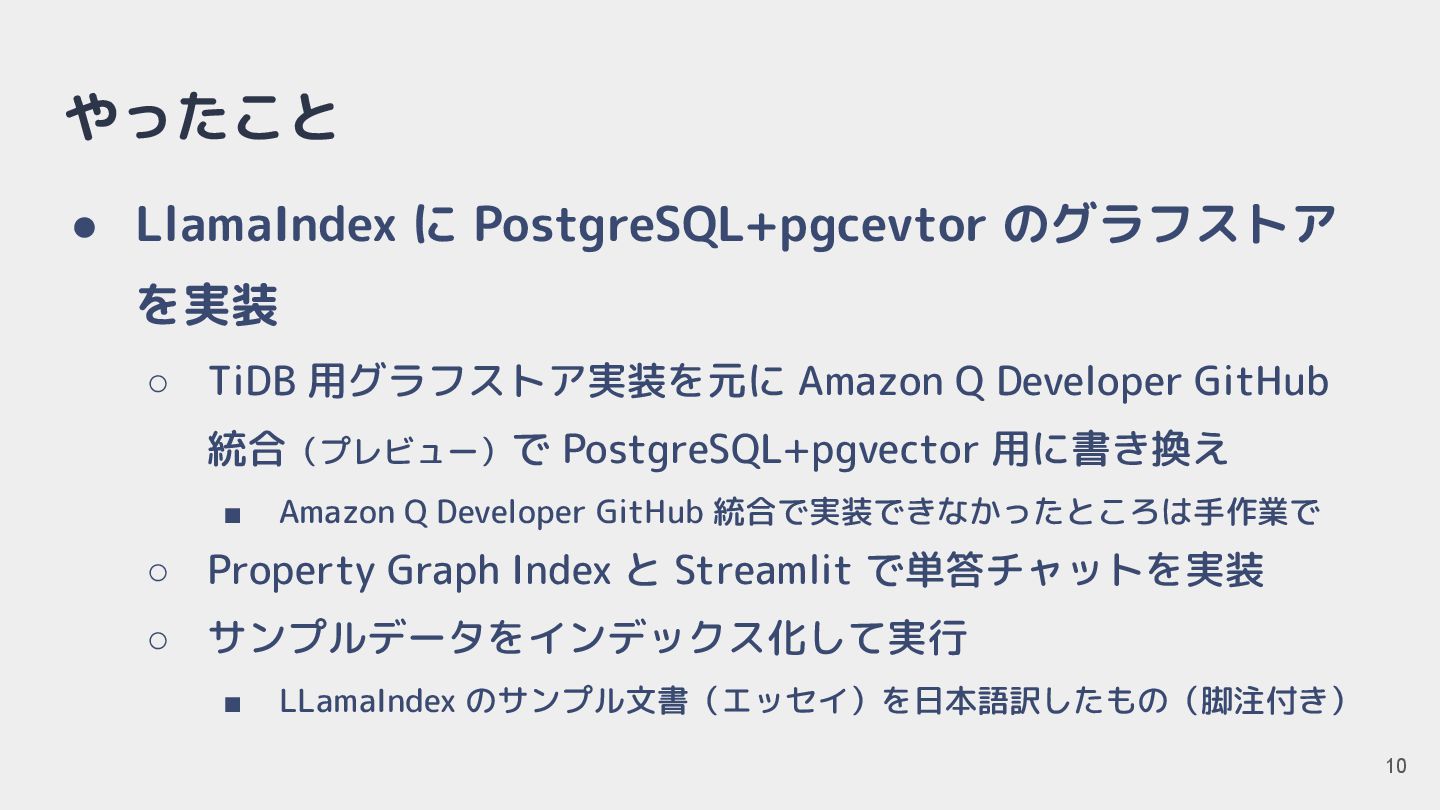
やったこと • LlamaIndex に PostgreSQL+pgcevtor のグラフストア を実装 ◦ TiDB 用グラフストア実装を元に
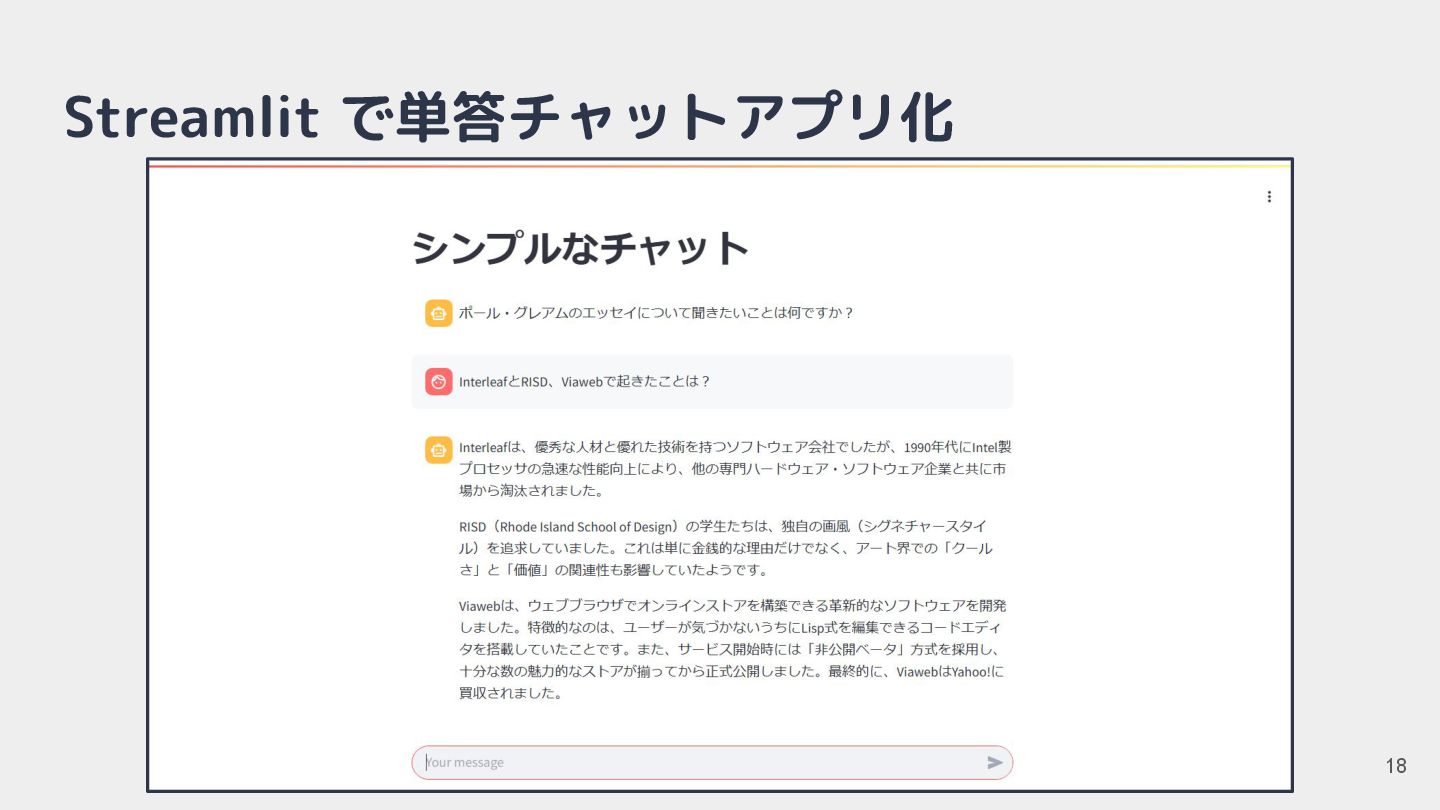
Amazon Q Developer GitHub 統合(プレビュー)で PostgreSQL+pgvector 用に書き換え ▪ Amazon Q Developer GitHub 統合で実装できなかったところは手作業で ◦ Property Graph Index と Streamlit で単答チャットを実装 ◦ サンプルデータをインデックス化して実行 ▪ LLamaIndex のサンプル文書(エッセイ)を日本語訳したもの(脚注付き) 10
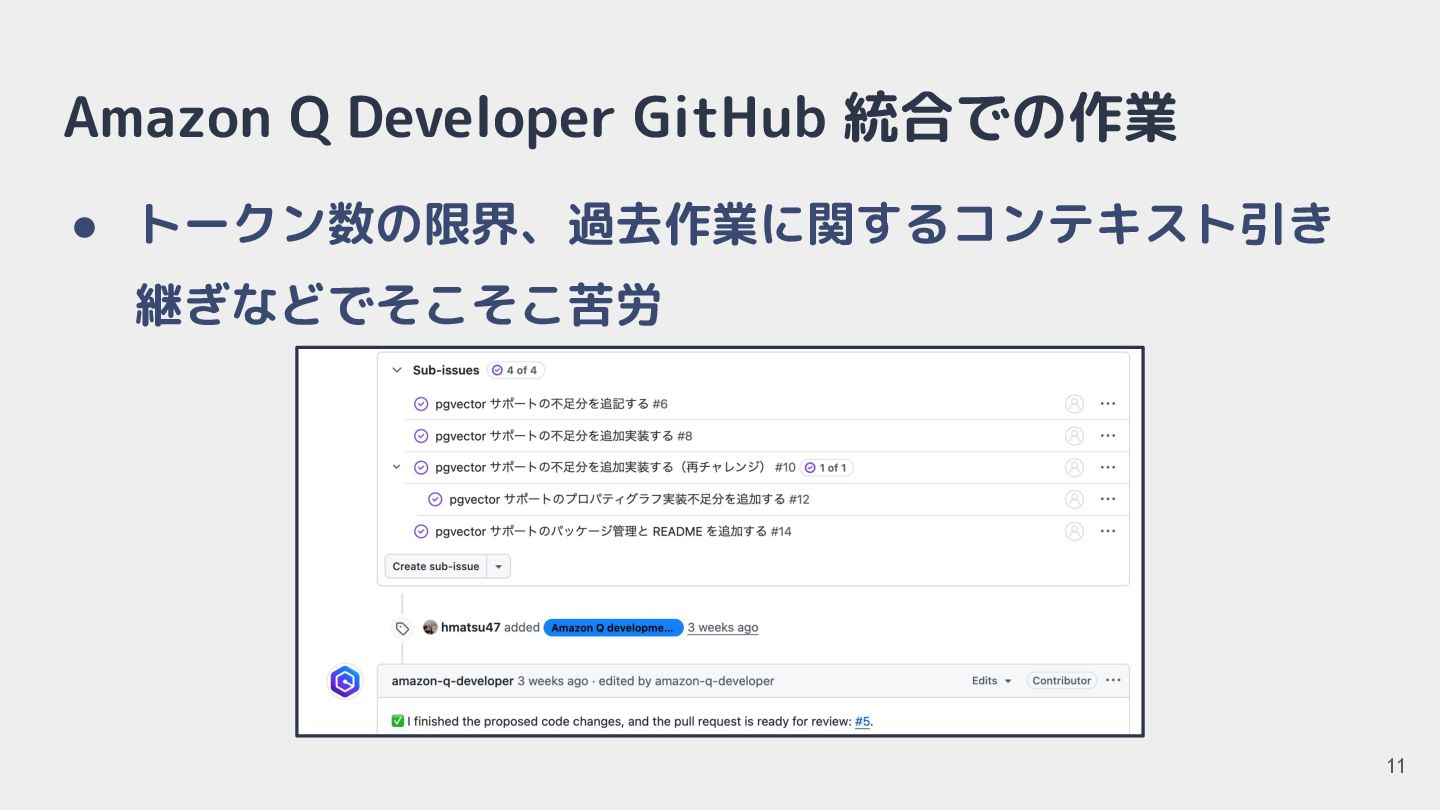
Amazon Q Developer GitHub 統合での作業 • トークン数の限界、過去作業に関するコンテキスト引き 継ぎなどでそこそこ苦労 11
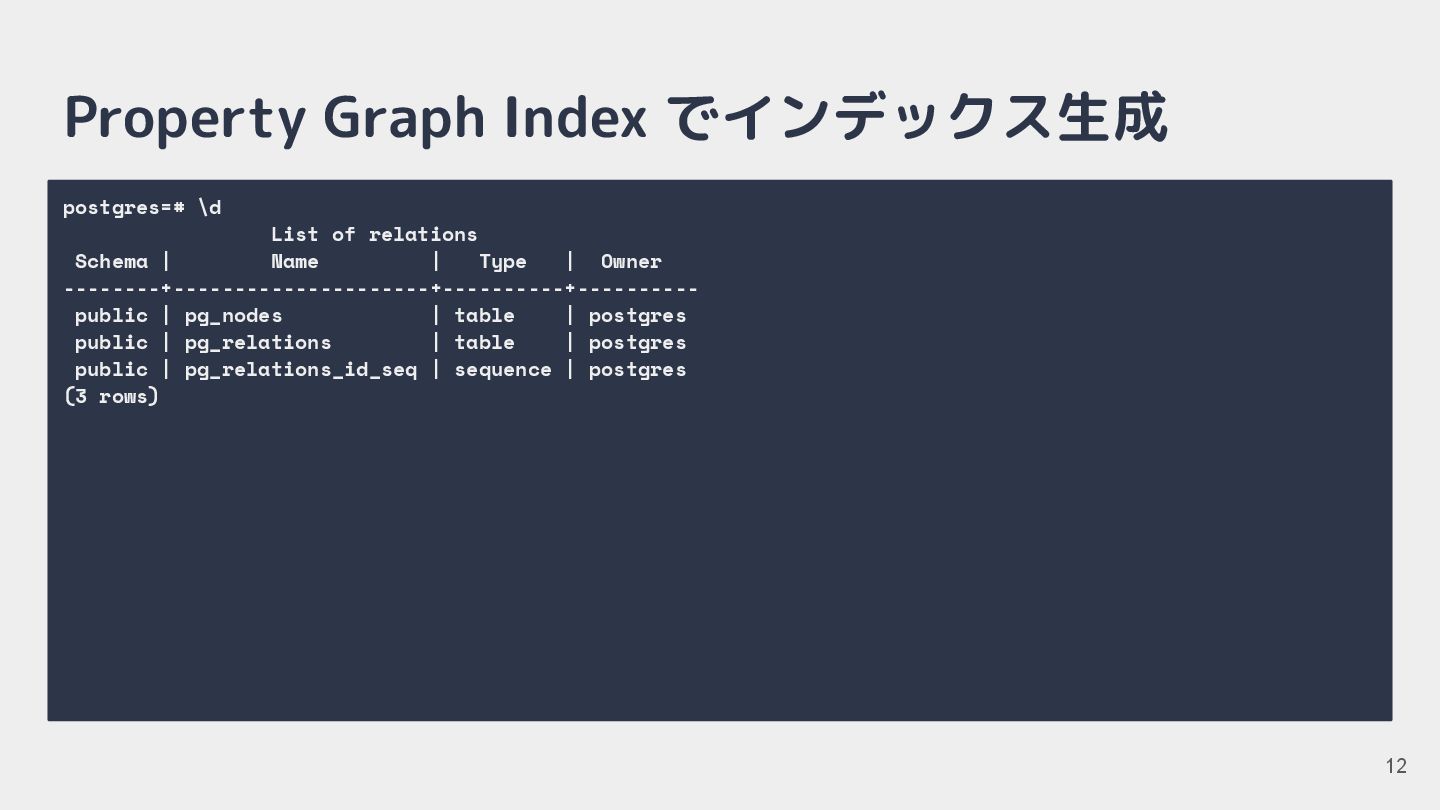
Property Graph Index でインデックス生成 postgres=# \d List of relations Schema
| Name | Type | Owner --------+---------------------+----------+---------- public | pg_nodes | table | postgres public | pg_relations | table | postgres public | pg_relations_id_seq | sequence | postgres (3 rows) 12
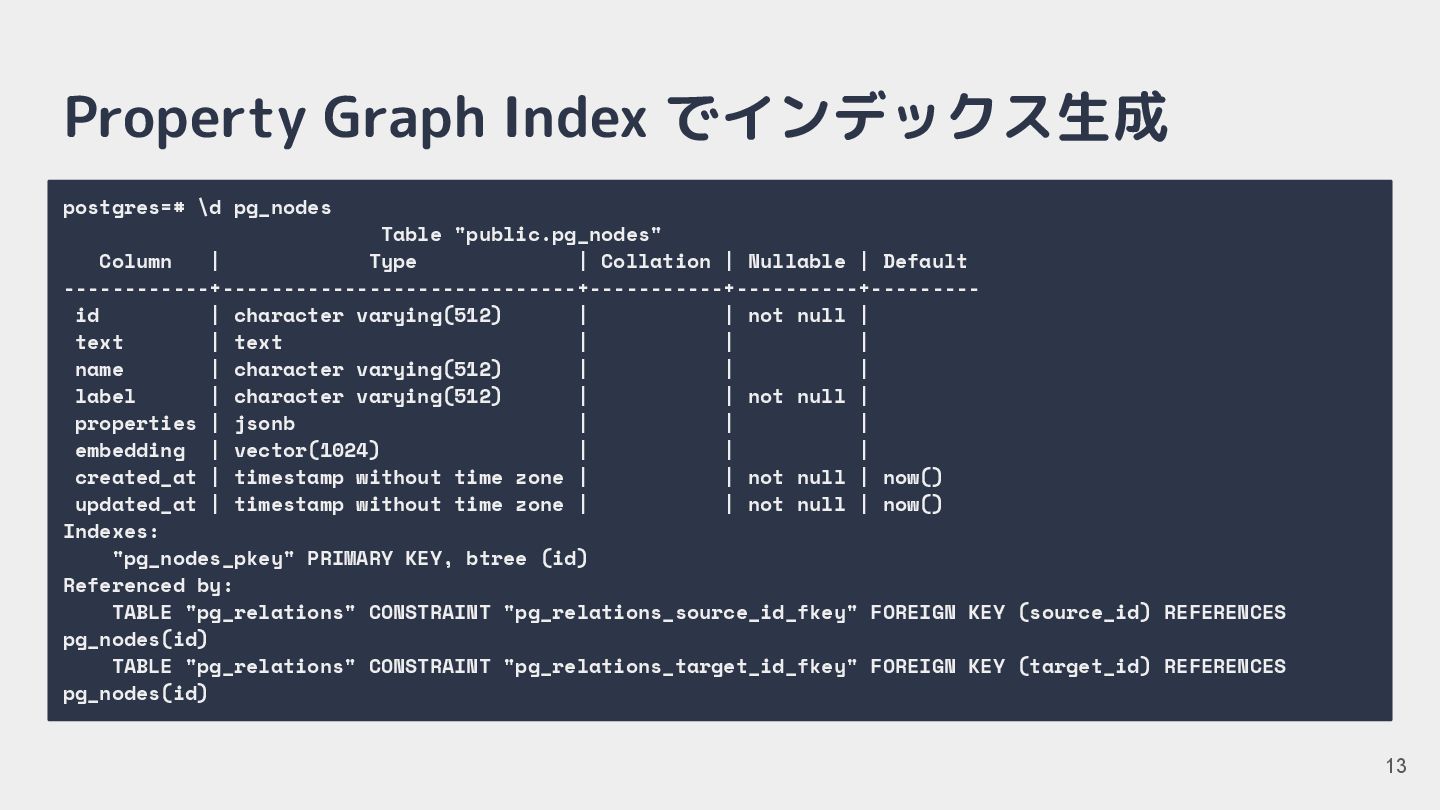
Property Graph Index でインデックス生成 postgres=# \d pg_nodes Table "public.pg_nodes" Column
| Type | Collation | Nullable | Default ------------+-----------------------------+-----------+----------+--------- id | character varying(512) | | not null | text | text | | | name | character varying(512) | | | label | character varying(512) | | not null | properties | jsonb | | | embedding | vector(1024) | | | created_at | timestamp without time zone | | not null | now() updated_at | timestamp without time zone | | not null | now() Indexes: "pg_nodes_pkey" PRIMARY KEY, btree (id) Referenced by: TABLE "pg_relations" CONSTRAINT "pg_relations_source_id_fkey" FOREIGN KEY (source_id) REFERENCES pg_nodes(id) TABLE "pg_relations" CONSTRAINT "pg_relations_target_id_fkey" FOREIGN KEY (target_id) REFERENCES pg_nodes(id) 13
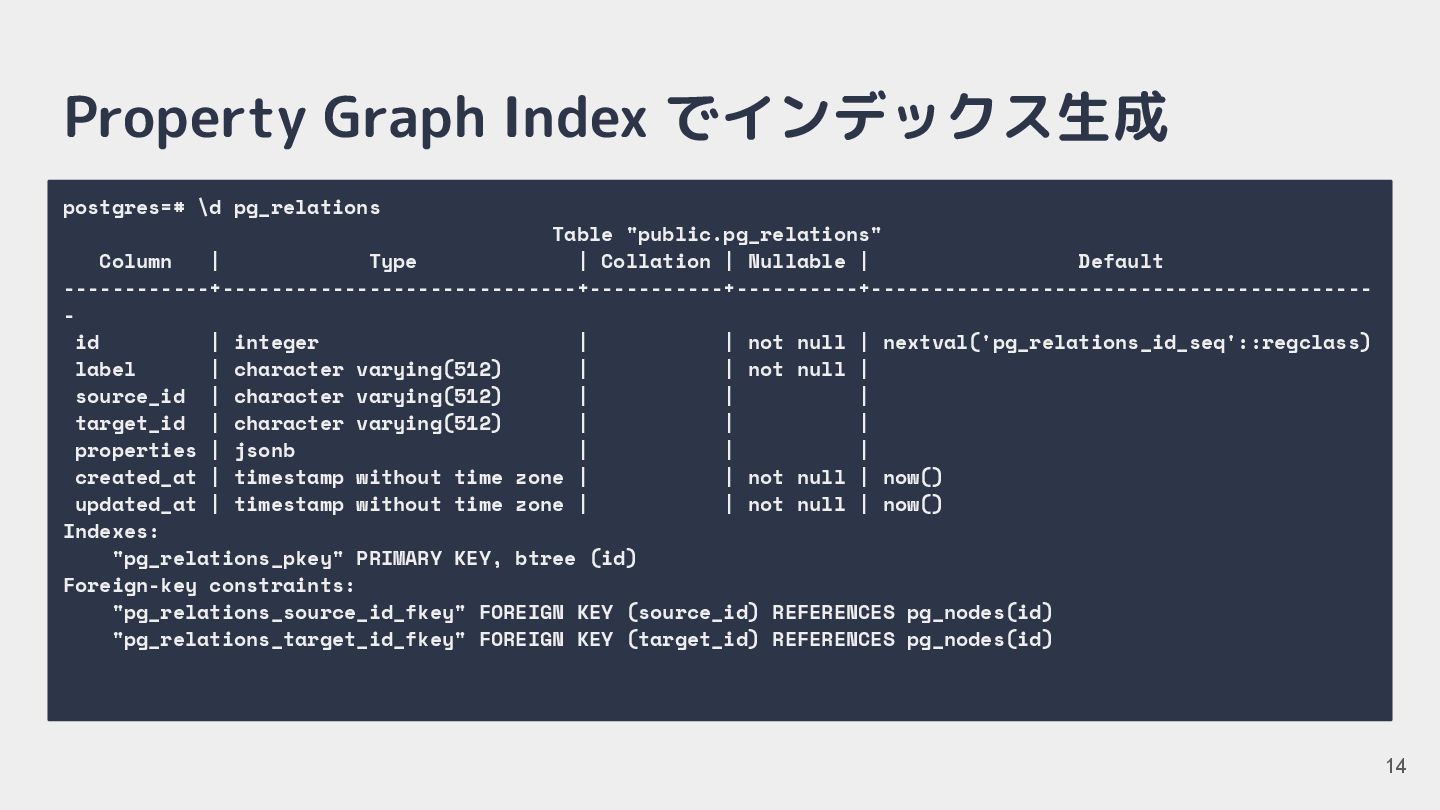
Property Graph Index でインデックス生成 postgres=# \d pg_relations Table "public.pg_relations" Column
| Type | Collation | Nullable | Default ------------+-----------------------------+-----------+----------+----------------------------------------- - id | integer | | not null | nextval('pg_relations_id_seq'::regclass) label | character varying(512) | | not null | source_id | character varying(512) | | | target_id | character varying(512) | | | properties | jsonb | | | created_at | timestamp without time zone | | not null | now() updated_at | timestamp without time zone | | not null | now() Indexes: "pg_relations_pkey" PRIMARY KEY, btree (id) Foreign-key constraints: "pg_relations_source_id_fkey" FOREIGN KEY (source_id) REFERENCES pg_nodes(id) "pg_relations_target_id_fkey" FOREIGN KEY (target_id) REFERENCES pg_nodes(id) 14
Property Graph Index でインデックス生成 postgres=# SELECT id, text, name, label,
properties FROM public.pg_nodes LIMIT 1; (中略) id | 9035ea97-bd3d-449e-a7c6-4905ce223bd2 text | 私が取り組んできたこと (中略) | 大学に入る前、学校以外で私が取り組んでいた主なことは、文章を書くこととプログラミングだった。エッセイは書かなかった。 当時、そして今もおそらく初心者の作家が書くべきとされている短編小説を書いていた。私の小説はひどい出来だった。ほとんど筋がなく、感情 の強い登場人物がいるだけで、それが作品に深みを与えているのだと思い込んでいた (中略) name | label | text_chunk properties | {"doc_id": "4442846b-2d07-41e6-9dab-3cdea250595a", "file_name": "example_ja.txt","file_path": "/Users/hmatsu47/llama_index_property_graph_test/data/example_ja.txt", "file_size": 44432, "file_type": "text/plain", "_node_type": "TextNode", "ref_doc_id": "4442846b-2d07-41e6-9dab-3cdea250595a", "document_id": "4442846b-2d07-41e6-9dab-3cdea250595a", (中略) \"metadata_seperator\": \"\\n\", \"text_template\": \"{metadata_str}\\n\\n{content}\", \"class_name\": \"TextNode\"}", "creation_date": "2025-05-22", "last_modified_date": "2025-05-22"} 15
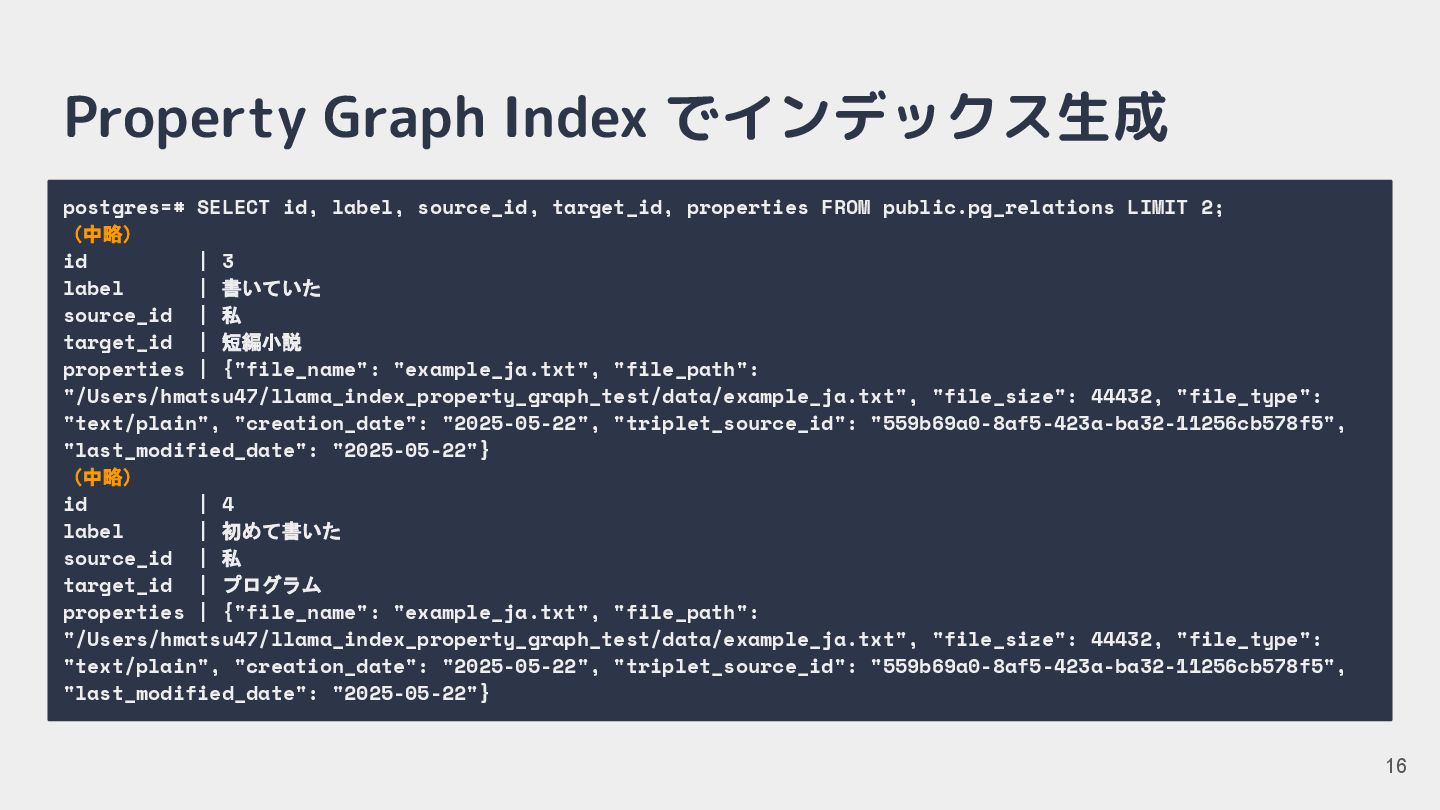
Property Graph Index でインデックス生成 postgres=# SELECT id, label, source_id, target_id,
properties FROM public.pg_relations LIMIT 2; (中略) id | 3 label | 書いていた source_id | 私 target_id | 短編小説 properties | {"file_name": "example_ja.txt", "file_path": "/Users/hmatsu47/llama_index_property_graph_test/data/example_ja.txt", "file_size": 44432, "file_type": "text/plain", "creation_date": "2025-05-22", "triplet_source_id": "559b69a0-8af5-423a-ba32-11256cb578f5", "last_modified_date": "2025-05-22"} (中略) id | 4 label | 初めて書いた source_id | 私 target_id | プログラム properties | {"file_name": "example_ja.txt", "file_path": "/Users/hmatsu47/llama_index_property_graph_test/data/example_ja.txt", "file_size": 44432, "file_type": "text/plain", "creation_date": "2025-05-22", "triplet_source_id": "559b69a0-8af5-423a-ba32-11256cb578f5", "last_modified_date": "2025-05-22"} 16
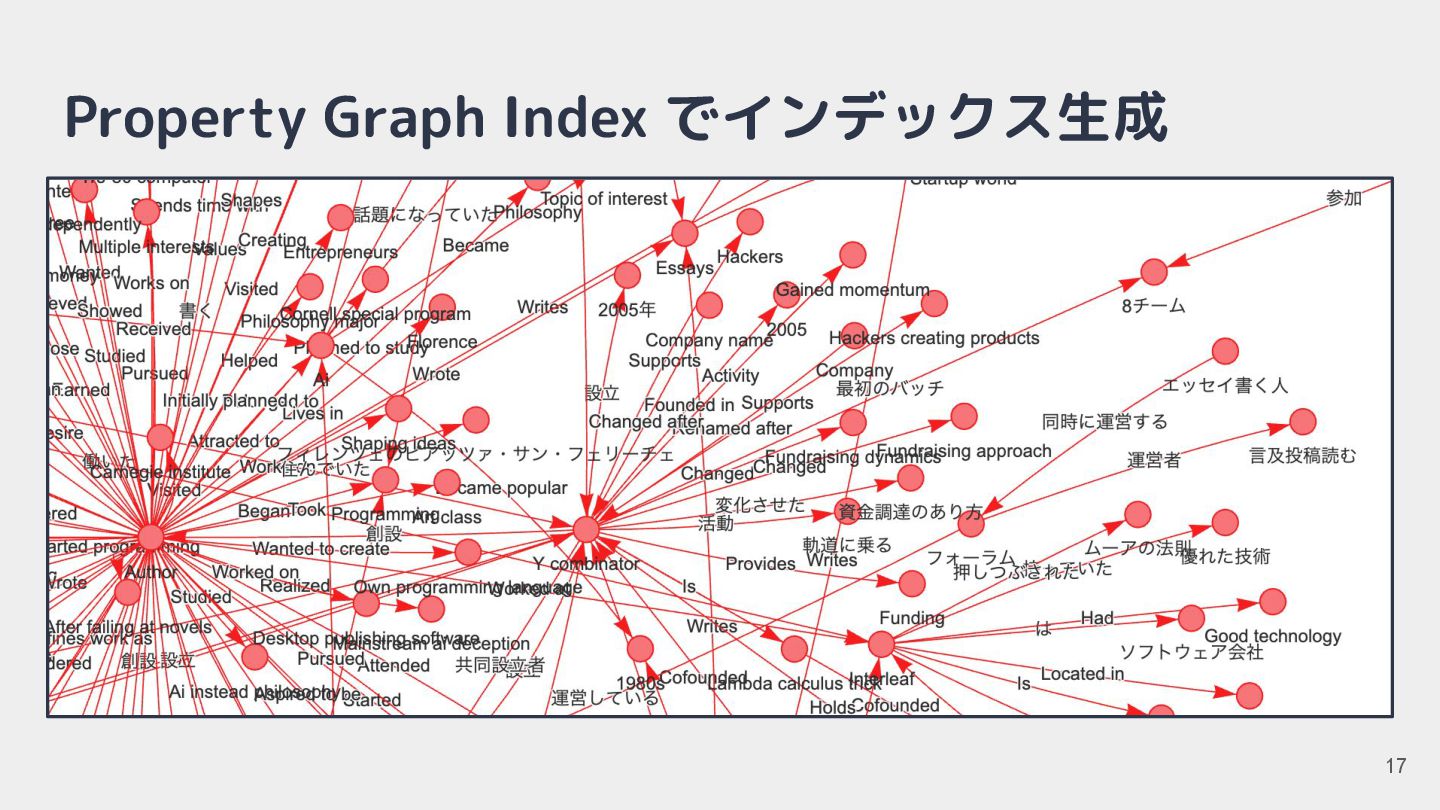
Property Graph Index でインデックス生成 17
Streamlit で単答チャットアプリ化 18
以上「序章」でした • 詳細はこちらで話す予定 ◦ 第 53 回 PostgreSQL アンカンファレンス@オンライン(6/24) https://pgunconf.connpass.com/event/355128/
• GitHub リポジトリ ◦ https://github.com/hmatsu47/llama-index-graph-stores-postgres ◦ https://github.com/hmatsu47/llama_index_property_graph_test ◦ https://github.com/hmatsu47/llama_index/issues?q=is%3Aissue%20state %3Aclosed 19


 hmatsu47
 shogo4131
 satomasahiro2005
 carta_engineering
 daidaidai
 bgpat
 prog893
 pfn
 syuchimu
 gogutan
 kash1064
 ykanoh
 ishikawa_satoru
 inesmontani
 techseoconnect
 skipperchong
 soudai
 kneath
 frankvandijk
 keavy
 codingconduct
 aleyda
 addyosmani
 csswizardry